Japonya ile Endonezya, ekonomi ve güvenlik alanlarında somut işbirliğini geliştirmede mutabık
Japonya ve Endonezya’nın, ekonomi ve güvenlik alanlarında somut işbirliğinin geliştirilmesi konusunda mutabık kaldığı bildirildi.

 Kitap okuma deneyimini interaktif hale getirmek isteyenler için Mark akıllı kitap ayracı hem okuma istatistikleri hem de çevrim içi mücadeleler ile renkli bir tecrübe sunuyor.
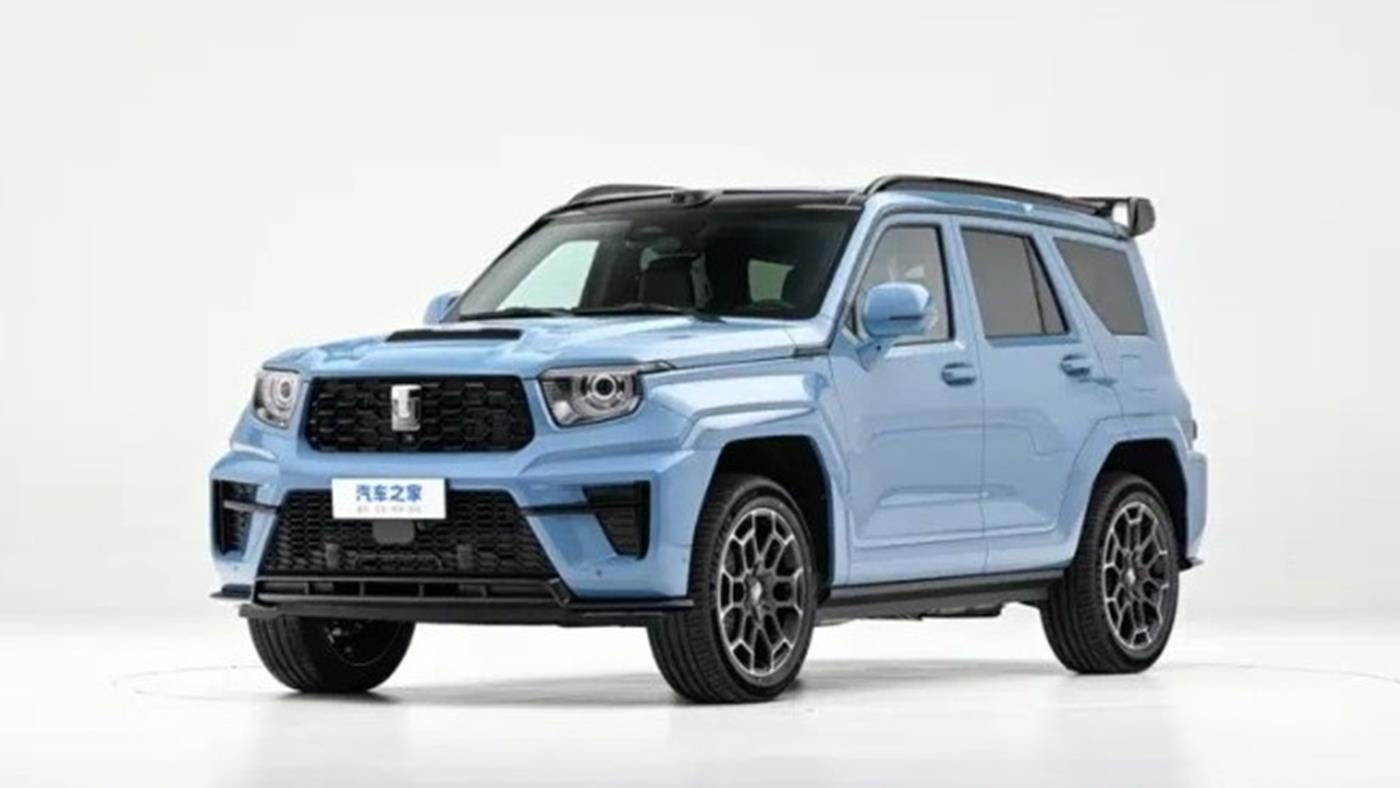
 Mercedes G-Serisi’ne benzerliğiyle dikkat çeken Çinli Great Wall Tank 700 ön satışa çıktı. Hibrit motor ve lüks donanımlara sahip olan modelin fiyatı G-Serisi’nin yarısı kadar.
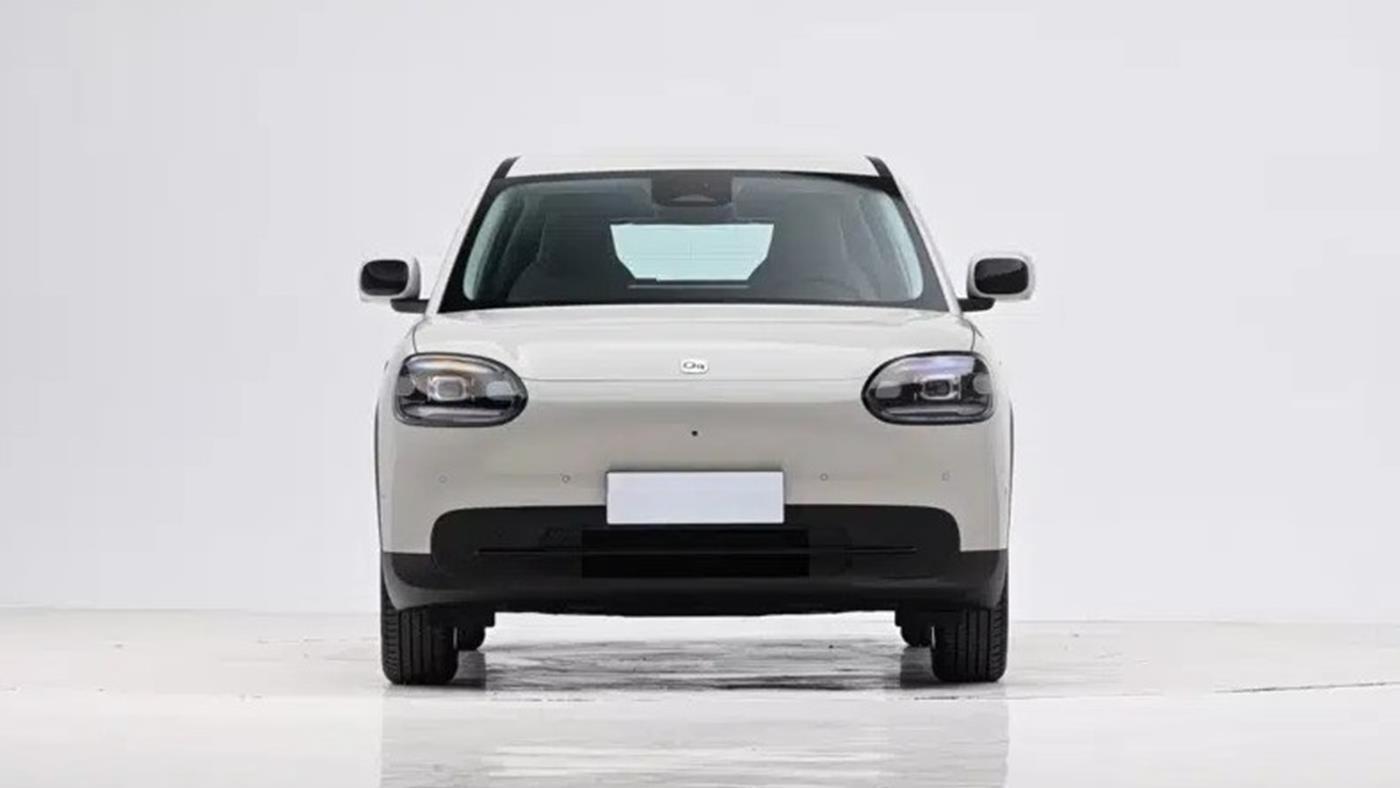
 Chery QQ3, dört farklı donanım seviyesiyle Çin pazarına girdi. Fiyatı 8.200 dolardan başlayan kompakt elektrikli model, tasarımı ve özellikleriyle dikkat çekiyor.
Getting 404 Errors After Building a Teams Tab App? HTML Caching Might Be the Cause
Introduction
When developing Microsoft Teams tab apps, there’s a frustrating issue you may run into during local development.
After modifying frontend code and rebuilding, Vite/Rollup adds a content hash to filenames (e.g., TeamsInitializer.bBRVpIft.js). However, if the browser (Teams WebView) has cached the HTML, the old HTML continues to reference the old hashed filenames, which results in 404 errors.
In this article, we’ll share a solution we discovered by digging into the internal structure of the Teams SDK v2 local server.
Common Solutions and Their Drawbacks
Approach 1: Remove Hashes from Filenames
// astro.config.mjs or vite.config.js
export default {
  vite: {
    build: {
      rollupOptions: {
        output: {
          entryFileNames: 'assets/[name].js',
          chunkFileNames: 'assets/[name].js',
          assetFileNames: 'assets/[name].[ext]',
        },
      },
    },
  },
};
Drawback: Removing hashes means the browser may cache files indefinitely, preventing code updates from being reflected. You lose the benefits of cache busting.
Approach 2: Use the Dev Server (HMR)
Using Vite or Astro’s dev server with HMR (Hot Module Replacement) avoids caching issues altogether.
Drawback: Teams apps are typically configured so that the Teams client (WebView) accesses a specific port, making it difficult to use the dev server’s separate port directly.
Investigating the Teams SDK v2 Internals
When looking into the @microsoft/teams.apps package in Teams SDK v2, we discovered that HttpPlugin uses Express internally.
// Excerpt from node_modules/@microsoft/teams.apps/dist/plugins/http/plugin.js
const express_1 = __importDefault(require("express"));

let HttpPlugin = class HttpPlugin {
    constructor(server, options) {
        this.express = (0, express_1.default)();
        // ...
        this.use = this.express.use.bind(this.express);  // ← use() is exposed!
    }

    static(path, dist) {
        this.express.use(path, express_1.default.static(dist));
        return this;
    }
}
Key findings:
HttpPlugin holds an internal Express instanceuse() method is exposed and bound to Express’s app.use()
Solution: Set Cache-Control Headers via Middleware
Leveraging this discovery, we add middleware to disable HTML caching only during local development.
// src/index.ts
import fs from "fs";
import https from "https";
import path from "path";

import { App, HttpPlugin, IPlugin } from "@microsoft/teams.apps";
import { ConsoleLogger } from "@microsoft/teams.common/logging";

const sslOptions = {
  key: process.env.SSL_KEY_FILE ? fs.readFileSync(process.env.SSL_KEY_FILE) : undefined,
  cert: process.env.SSL_CRT_FILE ? fs.readFileSync(process.env.SSL_CRT_FILE) : undefined,
};

const httpPlugin = new HttpPlugin(
  sslOptions.cert && sslOptions.key ? https.createServer(sslOptions) : undefined
);

// Disable HTML caching for local development only
if (!process.env.RUNNING_ON_AZURE) {
  httpPlugin.use("/tabs", (req, res, next) => {
    // Disable caching for HTML files and index.html requests
    if (req.path.endsWith(".html") || req.path === "/" || !req.path.includes(".")) {
      res.setHeader("Cache-Control", "no-cache, no-store, must-revalidate");
      res.setHeader("Pragma", "no-cache");
      res.setHeader("Expires", "0");
    }
    next();
  });
}

const plugins: IPlugin[] = [httpPlugin];
const app = new App({
  logger: new ConsoleLogger("tab", { level: "debug" }),
  plugins: plugins,
});

app.tab("home", path.join(__dirname, "./client"));

(async () => {
  await app.start(+(process.env.PORT || 3978));
})();
Key Points
RUNNING_ON_AZURE environment variable is not set (i.e., during local development).html, the root path, and paths without extensions (SPA routing) are treated as HTML requestsCache-Control, Pragma, and Expires — are set to ensure caching is fully disabled Benefits of This Approach
Use Case: Adding Other Middleware
Using this technique, you can add various middleware to the Teams SDK.
// Add request logging
httpPlugin.use((req, res, next) => {
  console.log(`${req.method} ${req.path}`);
  next();
});

// Add custom headers
httpPlugin.use((req, res, next) => {
  res.setHeader("X-Custom-Header", "my-value");
  next();
});

// Add authentication for specific paths
httpPlugin.use("/api/private", (req, res, next) => {
  if (!req.headers.authorization) {
    res.status(401).send("Unauthorized");
    return;
  }
  next();
});
Caveats
@microsoft/teams.apps v2.x) Conclusion
We discovered that Teams SDK v2’s HttpPlugin uses Express internally and exposes the use() method. By taking advantage of this:
We hope this helps anyone working with Teams SDK v2 who runs into the same issue.
This article was originally published in Japanese at archelon-inc.jp.
If you’re routing across multiple LLMs, you probably already know this feeling:
One model happily accepts your massive conversation.
The next model chokes, truncates half the important bits, and hallucinates the rest.
Same app. Same user. Different context window. Chaos.
Backboard.io now includes Adaptive Context Management, a system that automatically manages conversation state when your app moves between models with different context sizes.
ps. if you have keys from any of the frontiers or OpenRouter you can use this for free!
You still get access to 17,000+ LLMs on the platform.
You just don’t have to personally babysit their context windows anymore.
And yes, it’s included for free.
The Problem: Context Windows Are Inconsistent (and Annoying)
In a multi‑model setup, this is what actually happens:
You start on a large‑context model. Everything fits:
system prompt
conversation history
tool calls + tool responses
RAG chunks
web search results
random runtime metadata you forgot you added
Your router decides to send the next request to a smaller‑context model.
Suddenly your carefully curated “state” is too big to fit. Something has to go.
Most platforms respond with:
“Cool, just write truncation and summarization logic that:
prioritizes what matters,
handles overflow nicely,
doesn’t break when you add a new tool,
and works for every model you might ever route to.”
So we all end up writing the same brittle code:
if tokens > limit:

  drop_old_messages()

  maybe_summarize()

  hope_nothing_important_was_there()
In a multi‑model system, that logic gets complicated and fragile fast.
What We Shipped: Adaptive Context Management
Backboard now automatically handles context transitions when models change.
There’s no extra endpoint and no new config. It runs inside the Backboard runtime whenever a request is routed to a model.
When that happens, Backboard:
Looks up the model’s context window.
Dynamically budgets it:
20% reserved for raw state
80% freed via summarization
Within that 20% “raw state” budget, we prioritize:
system prompt
recent messages
tool calls
RAG results
web search context
Whatever fits in that 20% goes through unchanged.
Everything else is handled by intelligent summarization.
You don’t write the logic. You just route between models.
How Intelligent Summarization Works
When we need to compress, we follow a simple rule:
First try the model you’re switching to.
“Hey smaller model, summarize this so you can still understand what’s going on.”
If the summary still doesn’t fit:
We fall back to the larger model that was previously in use to generate a more efficient summary.
This preserves the important parts of the conversation while ensuring the final state always fits within the new model’s context window.
All of this happens automatically during the request and tool calls.
No manual orchestration. No custom jobs. No extra service.
You Should Rarely Hit 100% Context Again
Because Adaptive Context Management runs continuously:
It reshapes and compresses state before you slam into the limit.
It keeps a buffer in the context window instead of riding at 99.9% and hoping for the best.
Mid‑conversation model switches stop being a coin flip on whether something vital gets chopped.
Your job: define the routing logic and features.
Our job: make sure the context window doesn’t quietly wreck them.
You Still Get Visibility: context_usage in msg
This is not a black box.
We expose context usage directly in the msg endpoint so you can see what’s happening in real time.
Example response:
"context_usage": {

  "used_tokens": 1302,

  "context_limit": 8191,

  "percent": 19.9,

  "summary_tokens": 0,

  "model": "gpt-4"

}
You can track:
how much context is currently used
how close you are to the limit
how many tokens are from summarization
which model is currently managing the context
If you like graphs and dashboards, this gives you the raw data without forcing you to build your own context tracking system from scratch.
The Bigger Idea: Treat Models Like Infrastructure
Backboard’s thesis is simple:
You should be able to treat models as interchangeable infrastructure.
Your state should just move with the user.
That only works if state can move safely between:
cheap and expensive models
long‑context and short‑context models
different providers and pricing tiers
Adaptive Context Management is the safety layer that makes that viable:
You route across thousands of models.
Backboard keeps the conversation state aligned with each model’s constraints.
You don’t write ad‑hoc truncation and summarization logic per model.
You focus on product behavior.
We handle the context window drama.
Adaptive Context Management is free and live today in the Backboard API.
No feature flag. No extra pricing line.
You can start building with it now at:
If you’re already routing across multiple models and have horror stories about context windows, I’d love to hear them.
Semgrep is a great open source security and code validation tool. Semgrep revolves around rules like this:
rules:
  - id: print-to-logger
    pattern: print($VAR)
    message: Use logging.info() instead of print()
    language: python
    severity: MEDIUM
    fix: logger.info($MSG)
The rule above will raise a MEDIUM severity issue every time a use of print() is used in your Python code. It will also provide the recommended fix and even take the value inside the print statement and produce the fix content. Thus print("Hello world!") becomes logger.info("Hello world!")
The rules.yaml file is then used to validate one or more (in this case) Python files:
semgrep scan -f rules.yaml app.py
Capturing Semgrep Output using the OpenTelemetry Collector
Semgrep is capable of producing JSON output which means it’s really easy to grab using the OpenTelemetry collector. Let’s re-run the previous command with a few more flags to produce JSON:
semgrep scan -f rules.yaml --json -o out.json app.py
It produces single line JSON (JSONL) like this (which I’ve expanded here for readability):
{
    "version": "1.152.0",
    "results": [
       // Rule violations are listed here...
        {
            "check_id": "print-to-logger",
            "path": "app.py",
            "start": {
                "line": 4,
                "col": 5,
                "offset": 46
            },
            "end": {
                "line": 4,
                "col": 18,
                "offset": 59
            },
            "extra": {
                "message": "Use logging.info() instead of print()",
                "fix": "logger.info("blah")",
                "metadata": {},
                "severity": "MEDIUM",
                "fingerprint": "requires login",
                "lines": "requires login",
                "validation_state": "NO_VALIDATOR",
                "engine_kind": "OSS"
            }
        },
        ...
      ],
        "rules": [],
        "rules_parse_time": 0.0018589496612548828,
        "profiling_times": {
            "config_time": 0.1376628875732422,
            "core_time": 0.2947859764099121,
            "ignores_time": 4.291534423828125e-05,
            "total_time": 0.43769073486328125
        },
        "parsing_time": {
            "total_time": 0.0,
            "per_file_time": {
                "mean": 0.0,
                "std_dev": 0.0
            },
            "very_slow_stats": {
                "time_ratio": 0.0,
                "count_ratio": 0.0
            },
            "very_slow_files": []
        },
        "scanning_time": {
            "total_time": 0.009443998336791992,
            "per_file_time": {
                "mean": 0.009443998336791992,
                "std_dev": 0.0
            },
            "very_slow_stats": {
                "time_ratio": 0.0,
                "count_ratio": 0.0
            },
            "very_slow_files": []
        },
        "matching_time": {
            "total_time": 0.0,
            "per_file_and_rule_time": {
                "mean": 0.0,
                "std_dev": 0.0
            },
            "very_slow_stats": {
                "time_ratio": 0.0,
                "count_ratio": 0.0
            },
            "very_slow_rules_on_files": []
        },
        "tainting_time": {
            "total_time": 0.0,
            "per_def_and_rule_time": {
                "mean": 0.0,
                "std_dev": 0.0
            },
            "very_slow_stats": {
                "time_ratio": 0.0,
                "count_ratio": 0.0
            },
            "very_slow_rules_on_defs": []
        },
        "fixpoint_timeouts": [],
        "prefiltering": {
            "project_level_time": 0.0,
            "file_level_time": 0.0,
            "rules_with_project_prefilters_ratio": 0.0,
            "rules_with_file_prefilters_ratio": 1.0,
            "rules_selected_ratio": 1.0,
            "rules_matched_ratio": 1.0
        },
        "targets": [],
        "total_bytes": 0,
        "max_memory_bytes": 120384832
    }
Configure the OpenTelemetry collector to:
out.json
The transform processor can also be used to process the JSONL lines as they transit through the collector. In this case the rules:
time and observed_time to the current time (since the log line doesn’t explicitly state a timestamptool: semgrep (this is useful when the log line hits your Observability backend for filtering)results_found and the value is the length of the results array (again useful for backend processing – your O11y system may be able to compute lengths from an input array, but you can add it here to offload the processing / cost)version key as semgrep_version.Note: The collector cannot rename attribute keys so you actually take the current value of
version(ie."1.152.0"), create a new attribute calledsemgrep_version, set the value of the value using the existing value and finally delete the existingversionattribute.
receivers:
  filelog:
    include: [out.json]
    start_at: beginning
    operators:
      - type: json_parser
        parse_from: body

processors:
  transform:
    error_mode: ignore
    log_statements:
      - statements:
        - set(log.time, Now())
        - set(log.observed_time, Now())
        - set(log.attributes["tool"], "semgrep")
        - set(log.attributes["results_found"], Len(log.attributes["results"]))
        - set(log.attributes["semgrep_version"], log.attributes["version"])
        - delete_key(log.attributes, "version")

exporters:
  debug:
    verbosity: detailed

service:
  pipelines:
    logs:
      receivers: [filelog]
      processors: [transform]
      exporters: [debug]
Save Money by shrinking output on no violations
The output can be a bit wordy even when there are no violations. We can shrink this using the transform processor with an additional rule:
- set(log.body, "Semgrep scan finished. No issues found.") where Len(log.attributes["results"]) == 0
Create metrics from log content
Notice there are lots of metric fields in the JSON so use the signal_to_metrics connector to transform log content to real OpenTelemetry metrics.
Add this content to the collector YAML (connectors should be at the same level as receivers and processors.
Then add the signal_to_metrics as both an output of the logs pipeline and an input to a metrics pipeline (that you need to define).
The idea here is that logs flow into the connector, are transformed to metrics and into the metrics pipeline they go.
connectors:
  signal_to_metrics:
    logs:
      - name: max_memory_bytes
        description: Extract the first number from the string
        gauge:
          value: Double(log.attributes["time"]["max_memory_bytes"])
      - name: profiling_times.config_time
        description: Extract the first number from the string
        gauge:
          value: Double(log.attributes["time"]["profiling_times"]["config_time"])

...

service:
  pipelines:
    logs:
      receivers: [filelog]
      processors: [transform]
      exporters: [debug, signal_to_metrics]
    metrics:
      receivers: [signal_to_metrics]
      processors: []
      exporters: [debug]
Summary
Semgrep is a great security and validation tool and the results are really easy to process using the OpenTelemetry collector.
Subscribe to me on YouTube for more Observability and OpenTelemetry content.
Two agents. Same knowledge base. Same question. Different answers.
Both answers are internally consistent. Both are traceable to real sources. Neither agent made anything up. And yet they disagree.
This is not a hallucination problem. It’s not an agent quality problem. It’s a determinism problem — and it’s the one nobody talks about.
What determinism means in a knowledge system
Most people ask two things of their knowledge system:
This method adds a third requirement that almost nobody names explicitly:
Any agent, reading your sources in any order, must arrive at the same model of the system.
This is not the same as accuracy. Data can be accurate in every individual file and still produce different models depending on reading order. The failure modes are subtle:
None of these are factual errors. Every file is “correct.” But the system as a whole is non-deterministic — its output depends on which file the agent happened to read first.
If two agents read the same knowledge base and build different models — the knowledge base is non-deterministic. That’s a bug, not a disagreement, not a matter of interpretation.
Why this is harder to catch than hallucination
Hallucination is visible in the wrong direction. The output doesn’t match anything in the sources — you can check.
Non-determinism is invisible because the output matches something in the sources. It’s just not the right something. If you ask “is this in my knowledge base?” — the answer is yes. The answer is always yes. You just got the wrong version of yes.
This is why COLLAPSE markers matter so much. Without them, every silent choice looks like a confident answer. With them, you can see exactly where the system branched — and which branch was taken.
But COLLAPSE markers only help after a choice has been made. Determinism is about preventing the ambiguity that forces the choice in the first place.
The three sources of non-determinism
1. Asymmetric connections
If your knowledge includes relationships between concepts — A connects to B — both sides need to describe the connection. If only A mentions B but B doesn’t mention A, then an agent starting from B will build a model where that connection doesn’t exist.
This is the most common failure. It feels like thorough documentation. It isn’t.
The test: for every connection in your system, can you find the description from both sides? If not — you have asymmetric coverage, and reading order determines what agents know.
2. Terminology drift
The same concept named differently in different places. “Decision” in one file, “resolution” in another, “outcome” in a third — all meaning the same thing.
Each individual file is internally consistent. But across files, an agent has no way to know these are the same thing. It builds three separate concepts. And when it reasons about them, the models diverge.
The fix is not renaming everything in one pass — that introduces iatrogenesis. The fix is a terminology map: here are all the names we use for this concept, and this one is canonical. Then agents can normalize before reasoning.
3. Layer violations
When information lives on the wrong layer, agents reading only the correct layer miss it. An agent doing a deep-spec pass reads specs — and misses the business rule that was written in the navigation layer because it seemed important at the time.
This creates a specific kind of non-determinism: the model depends not just on reading order, but on reading depth. An agent doing a shallow pass and a deep pass build different models — even from the same starting point.
How to test for determinism
Three practical tests. You don’t need multiple agents to run them — you can do them manually.
Test 1 — The reverse order test
Pick your five most important questions about your domain. Answer them from your knowledge base, starting from the first file you’d naturally open.
Now answer them again, but start from a file you’d normally read last.
Do the answers change? If yes — you have reading-order dependency. Something is determined by entry point, not by content.
Test 2 — The two-path test
Pick one connection or relationship in your system. Find where it’s described from side A. Find where it’s described from side B (if it exists). Do both descriptions agree on: what the connection is, when it applies, who initiates it?
If they disagree on any of these — you have a COLLAPSE:RED that hasn’t been marked yet.
If side B doesn’t exist — you have an asymmetric connection. An agent starting from B will never know this relationship exists.
Test 3 — The empty layer test
For each layer in your pyramid, ask: what would an agent know if it read only this layer and nothing below?
Then ask: is that the right amount for this layer to communicate?
If the navigation layer contains business rules — agents reading only the navigation layer will build an overconfident model. If the spec layer is missing fields that appear in the scenario layer — agents building from specs will have an incomplete model.
The right answer for each layer is: exactly what belongs here, nothing more, nothing less.
What done looks like
A knowledge system is deterministic when:
That last point matters more than it sounds. “I’ve covered the main sources” is not a status. “I’ve read 14 of 20 sources; the remaining 6 require a second pass for: [specific topics]” is a status.
The difference is whether you know what you don’t know. A system that knows its own gaps is more useful than one that presents itself as complete.
The linter vs the method
A linter checks form: file exists, link not broken, syntax valid. You can have a perfect linter score and a completely non-deterministic knowledge system. All files present, all links valid, all formats correct — and two agents still build different models.
Determinism is semantic. It’s checked by:
This is not a one-time setup. It’s a recurring check — every time you add significant content, every time you cross a domain boundary, every time you connect two previously separate knowledge areas.
The linter checks form. This method checks meaning.
Where we go from here
The series has covered the full method:
Part 1 — five core principles: write everything explicitly, use layers, catalog hallucination traps, mark collapses, be the gateway.
Part 2 — agent specialization as protection against iatrogenics, and the failure patterns that look like work but aren’t.
Part 3 (this post) — determinism as the third requirement, its three sources, and how to test for it.
Next: we leave method and go into domain. Real failure modes, real examples — starting with the one that caught OpenAI off guard: confabulation versus hallucination, and why the distinction changes how you build.
Method developed from a real working system. The principle works with any stack, any tools, any domain.
References: Zhang et al. arXiv:2510.04618 (ACE, 2025), Luhmann (1981).
In Part 1, I described the problem and five principles: write everything explicitly, use layers, catalog hallucination traps, mark silent collapses, stay the gateway.
But I left out three things deliberately — they needed more room.
How to build agents that don’t break each other.
What not to do when building the system.
How to know the system actually works.
That’s this post.
Why one smart agent is the wrong architecture
The obvious setup: one powerful agent that reads everything, understands everything, fixes everything. It’s flexible, it adapts, it “gets the context.”
The problem: one agent is one point of iatrogenesis.
Iatrogenesis is a medical term — when the treatment causes another disease. The doctor fixes the knee, damages the nerve. The surgeon removes the tumor, introduces infection. In medicine it’s a known, studied risk. In information systems almost nobody names it.
In agent systems it looks like this: the agent fixes a contradiction in file A, and in doing so creates a new one in file B. Or it summarizes a long document and loses a nuance that was critical three layers down. Or it rewrites a section “for clarity” and subtly shifts the meaning — consistently with its own model, not yours.
The fix is the same as in surgery: specialization. A surgeon who only does knees doesn’t touch nerves. An agent that only reads and builds a model can’t accidentally break anything — it has no write access. An agent that only adds content never rewrites existing text — by design.
Each role, one responsibility, one explicit constraint:
Reader       →  extracts understanding. builds a model. never edits.
Verifier     →  runs the hallucination checklist. emits COLLAPSE markers.
Surgeon      →  reads the report. makes targeted edits. never rewrites.
Mirror       →  checks symmetry. is every connection described from both sides?
Filler       →  only adds. never touches existing content.
Auditor      →  checks distribution. where does info live on the wrong layer?
These aren’t product names — they’re roles. Your implementation might have three of them or fifteen. The principle is the same: every constraint is a removed degree of freedom for error.
And the number of agents is unlimited. When a new domain appears, you add a role for it. The pipeline scales horizontally without changing the core.
Iatrogenics: the patterns that look like work but aren’t
Beyond multi-agent design, there are recurring failure modes that appear when building any knowledge system with LLMs. They all share the same shape: they feel productive, they produce output, and they quietly degrade the system.
“The main stuff is covered.”
This is rationalization of incomplete reading. There are no unimportant parts of a knowledge system. An unread source isn’t “background context” — it’s a blind spot. The only honest alternative: flag it explicitly. “Read 12 of 20 sources. The remaining 8 require a second pass covering: [list].” Incomplete analysis doesn’t get called analysis.
“Exactly N items in the system.”
Hardcoding counts is a pressure artifact. The agent is implicitly told: fit reality into this number. So it does. It picks the five most prominent issues and ignores three others that are equally real. The count should come from the content, not the prompt. Always.
“Top 5 problems.”
Same mechanism, worse outcome. Limiting the output count is not brevity — it’s information loss. If there are eight problems, there are eight problems. The agent that returns five has made an editorial decision on your behalf, without flagging it.
“Describe it briefly.”
Volume should follow content, not instructions to be concise. Nuance lives in the details that get cut first. If a brief description is genuinely sufficient — it will be brief naturally. Forcing brevity on a complex topic produces a description that sounds complete and isn’t.
Rigid output format.
This is the subtlest one. If your prompt requires “five sections” — you will always get five sections. Even when the content calls for three or eight. The agent optimizes for format compliance, not for accuracy. Format should follow content. Always the other way around from what most people do.
The ACE paper (Zhang et al., arXiv:2510.04618, 2025) describes the same failure at the architectural level and calls it brevity bias — the system optimizes for shorter outputs because shorter is what the format rewards. The same dynamic happens in knowledge systems when you constrain the output shape before you understand the content shape.
The series so far — and where it goes
Part 1 — the problem and five principles: write everything, use layers, catalog hallucination traps, mark collapses, be the gateway.
Part 2 (this post) — agents and specialization, iatrogenics patterns.
Part 3 — determinism as an engineering requirement: what it means, how to test for it, and what “done” actually looks like.
After that: real failure modes from real domains — confabulation vs hallucination, static automation, and why your tech stack is a consequence not a decision.
Method developed from a real working system. The tools — Markdown, Obsidian, open-source Copilot — are one implementation. The principle works with any stack.
References: Zhang et al. arXiv:2510.04618 (ACE, 2025), Li et al. arXiv:2507.03724 (MemOS, 2025), Luhmann (1981).