Fergani Uzay’ın beşinci milli uydusu uzayda!
 Baykar’ın uzay şirketi Fergani Uzay tarafından milli imkanlarla geliştirilen FGN-100-D3, uzaya gönderildi. 5 yılda 100 uydu gönderilerek Uluğ Bey Küresel Konumlama Sistemi kurulacak.
 Baykar’ın uzay şirketi Fergani Uzay tarafından milli imkanlarla geliştirilen FGN-100-D3, uzaya gönderildi. 5 yılda 100 uydu gönderilerek Uluğ Bey Küresel Konumlama Sistemi kurulacak.
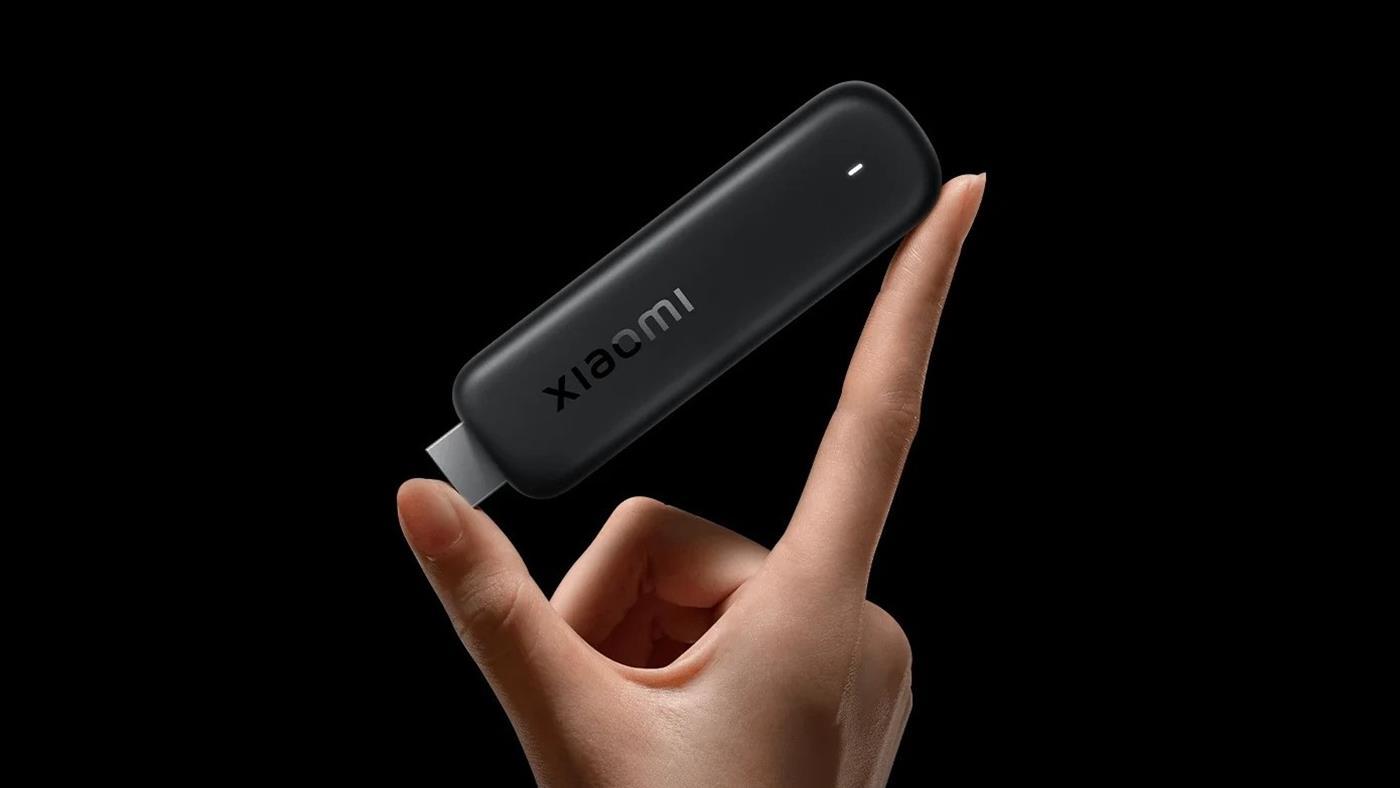
 Xiaomi, TV Stick HD (2. Nesil) modelini küresel internet sitesinde listeledi. Uygun fiyatlı medya oynatma cihazı neler sunuyor?
Every ML project I worked on in GitLab had the same problem: a bloated .gitlab-ci.yml with hand-rolled MLflow integration, custom validation scripts, and manual model registration. Copy it to the next project, tweak the paths, fix the bugs you already fixed last time. By the fifth project you don’t remember which config has the working version of MLFLOW_RUN_ID passthrough between jobs.
So I built a GitLab CI/CD component that replaces all of that with 10 lines of YAML.
Before vs After
Here’s what a typical MLOps pipeline looked like before — and this is the shortened version:
stages: [validate, train, evaluate, register]

validate-data:
  stage: validate
  image: python:3.12
  script:
    - pip install pandas great_expectations
    - python scripts/validate.py --data data/train.csv --check-nulls --threshold 0.05
  artifacts:
    paths: [validation_report.json]

train-model:
  stage: train
  image: python:3.12
  variables:
    MLFLOW_TRACKING_URI: "${CI_API_V4_URL}/projects/${CI_PROJECT_ID}/ml/mlflow"
  script:
    - pip install mlflow scikit-learn pandas
    - python scripts/train.py --data data/train.csv
    - echo "MLFLOW_RUN_ID=$(cat run_id.txt)" >> train.env
  artifacts:
    reports:
      dotenv: train.env
    paths: [model/, metrics.json]

evaluate-model:
  stage: evaluate
  image: python:3.12
  needs: [{job: train-model, artifacts: true}]
  variables:
    MLFLOW_TRACKING_URI: "${CI_API_V4_URL}/projects/${CI_PROJECT_ID}/ml/mlflow"
  script:
    - pip install mlflow
    - python scripts/evaluate.py --run-id $MLFLOW_RUN_ID --threshold 0.85
    - echo "EVAL_PASSED=$(cat eval_result.txt)" >> evaluate.env
  artifacts:
    reports:
      dotenv: evaluate.env

register-model:
  stage: register
  image: python:3.12
  needs: [{job: train-model, artifacts: true}, {job: evaluate-model, artifacts: true}]
  rules:
    - if: $EVAL_PASSED == "true"
  variables:
    MLFLOW_TRACKING_URI: "${CI_API_V4_URL}/projects/${CI_PROJECT_ID}/ml/mlflow"
  script:
    - pip install mlflow
    - python scripts/register.py --run-id $MLFLOW_RUN_ID --model-name my-model
And this doesn’t even include DVC, pip caching, retry logic, or error handling. Each project also had its own validate.py, evaluate.py, register.py — each with its own implementation of auto_configure_mlflow, its own argument parsing, its own bugs.
Now the same thing:
stages: [validate, train, evaluate, register]

include:
  - component: gitlab.com/netOpyr/gitlab-mlops-component/[email protected]
    inputs:
      model_name: wine-classifier
      training_script: scripts/train.py
      training_args: '--data data/train.csv --test-data data/test.csv'
      data_path: data/train.csv
      framework: sklearn
      metric_name: accuracy
      min_threshold: '0.85'
These 10 lines give you 4 jobs:
validate --> train --> evaluate --> register
   |           |          |            |
 schema      MLflow    accuracy    Model Registry
 nulls       autolog   >= 0.85    (if eval passed)
 drift       metrics   vs prod
All the boilerplate scripts now live inside the component. You only write the training script.
What Each Stage Does
validate checks your data before training starts: schema validation (are all columns present?), null ratio per column (default threshold 5%), and optionally data drift detection via Evidently. Supports Great Expectations suites and custom Python check scripts too.
train wraps your training script in an MLflow session. It auto-configures the tracking URI from GitLab CI variables, creates an experiment and run, enables autolog for your framework (sklearn, PyTorch, TensorFlow, XGBoost, LightGBM), and passes MLFLOW_RUN_ID to your script via environment variable. Your script stays a normal Python file — it works locally and in Jupyter just the same.
evaluate pulls metrics from MLflow and runs them through quality gates. Gate 1: absolute threshold (e.g. accuracy >= 0.85). Gate 2 (optional): comparison with the current production model from Model Registry. Supports higher_is_better: false for loss metrics.
register pushes the model to GitLab Model Registry with metadata: alias (staging by default), commit SHA, pipeline ID, metrics. Works on all GitLab tiers — on Free, alias assignment silently falls back to tags.
DVC Integration
If your data lives in S3/MinIO:
include:
  - component: .../[email protected]
    inputs:
      training_script: scripts/train.py
      model_name: my-model
      dvc_enabled: true
      dvc_remote: minio
      dvc_files: 'data/train.csv.dvc data/test.csv.dvc'
      dvc_push: true
      dvc_push_paths: 'model/'
The component installs DVC, pulls data before training, and pushes artifacts back after. Credentials go through CI/CD variables: AWS_ACCESS_KEY_ID, AWS_SECRET_ACCESS_KEY, AWS_ENDPOINT_URL.
When 10 Lines Aren’t Enough
For more complex setups you can include each stage separately:
include:
  - component: .../[email protected]
    inputs:
      data_path: data/train.csv
      enable_drift: true
      reference_data_path: data/reference.csv

  - component: .../[email protected]
    inputs:
      training_script: scripts/train.py
      model_name: my-model
      image_suffix: pytorch-gpu
      framework: pytorch
      tags: ["gpu"]

  - component: .../[email protected]
    inputs:
      model_name: my-model
      metric_name: val_loss
      min_threshold: '0.1'
      higher_is_better: false

  - component: .../[email protected]
    inputs:
      model_name: my-model
      alias: staging
This way you get per-stage GPU runners, custom images, and conditional execution. You can also train multiple models in parallel using the as parameter to give unique names to jobs.
Framework Support
Each framework has a dedicated Docker image selected via image_suffix:
| Suffix | Frameworks | GPU |
|---|---|---|
sklearn |
scikit-learn, matplotlib | No |
boosting |
XGBoost, LightGBM, scikit-learn | No |
pytorch |
PyTorch (CPU) | No |
pytorch-gpu |
PyTorch + CUDA 12.4 | Yes |
tensorflow |
TensorFlow (CPU) | No |
tensorflow-gpu |
TensorFlow + CUDA 12.4 | Yes |
All images include Python 3.12, MLflow, and pandas. Need extra dependencies? Set requirements_file: requirements.txt or bring your own image via image_registry_base.
Try It
Two options:
MLOPS_ACCESS_TOKEN in CI/CD variables.scripts/ and configure the inputs.The component is published in the GitLab CI/CD Catalog.
What’s Next
Coming soon: BuildKit-based image builds, retry logic for flaky MLflow requests, and GitLab Environments integration.
Found a bug or missing a feature? Open an issue or MR.
Links:
Between 2022 and 2024, job postings for entry-level developers decreased by 60%. AI wasn’t the one to let go of juniors, it just made companies stop hiring them.
A QCon London presentation a couple of weeks ago neatly summed it all up: it’s not that the ladder doesn’t have steps, it’s that we’re missing the process of building the steps in the first place.
Here’s what happened.
The Numbers Everyone’s Quoting
Dario Amodei predicted AI would write 90% of all code within six months. A Redwood Research analysis found the actual number was closer to 50% when you count committed code. Google reports 25% of internal code is AI-generated. Microsoft says around 30%.
Those numbers are real. But they hide something.
The code AI writes best is the same code juniors used to write. Boilerplate. Unit tests. Simple bug fixes. CRUD endpoints. The boring stuff that nobody wanted to do but everybody needed to learn from.
The Hiring Freeze Nobody Talks About
Harvard researchers analyzed 62 million workers across 285,000 U.S. firms. Companies that adopted generative AI saw junior developer employment drop 9-10% within six quarters. Senior employment kept rising.
This isn’t a layoff story. It’s a hiring story. Companies aren’t firing juniors. They’re just not replacing the ones who leave.
Big Tech made it worse. New grads represented only 7% of hires in 2025. That’s a 78% reduction from 2019. The “junior” title now expects 3+ years of experience and production-ready code on day one.
The Perception Gap
METR ran a proper randomized controlled trial in early 2025. Experienced developers using AI tools took 19% longer on tasks. Before starting, they predicted AI would make them 24% faster. After finishing, they still believed they were 20% faster.
The gap is 43 percentage points.
Then METR tried to run a follow-up study. They couldn’t. Between 30% and 50% of developers refused to participate if it meant working without AI. One developer said: “I’d like to help but I really like using AI.”
In less than a year, AI went from “makes experienced devs slower but they can’t tell” to “developers won’t even attempt work without it.”
That’s the real problem.
The Deleted Curriculum
The tasks AI automated weren’t just tasks. Writing that boilerplate is how you learned what the boilerplate does. Debugging that simple bug is how you developed intuition for where bugs hide. Reviewing that CRUD endpoint is how you understood what production code actually looks like.
Nobody designed a replacement for that learning process. We just deleted it.
The QCon speaker nailed the paradox. Amodei himself said programmers still need to specify the overall design, understand how code collaborates, and decide whether a design is secure. He separated the writing from the engineering.
But the writing was how people learned the engineering.
So Now What?
Some companies are trying. IBM and LinkedIn announced they’re hiring “AI-native” engineers in 2026. But what does that even mean? You can’t be AI-native if you never learned what AI is automating.
We’re optimizing for today’s output at the cost of tomorrow’s talent pipeline. Every senior engineer who exists today learned by doing the work we just handed to machines.
In five years, who reviews the AI’s code? 🤔
What’s your take — is the junior dev role actually gone, or is it just being redefined into something we haven’t named yet? 👇
GitHub Copilot Is Putting Ads in Your Pull Requests. Microsoft Calls Them “Tips.”
GitHub Copilot includes ads in your PRs. Microsoft calls them ‘tips.’
A developer asked Copilot to fix a typo in a PR. Copilot fixed the typo, then quietly edited the PR description to include a promotion for itself and Raycast.
Not a bug. Not a hallucination. A feature.
11,000 PRs. Same Promotional Text.
Developers got curious. They spotted HTML comments labeled “START COPILOT CODING AGENT TIPS” hidden within thousands of PR descriptions on GitHub.
11,000+ pull requests contained the exact paragraph of promotional text.
The gist of it was: “Quickly spin up Copilot coding agent tasks from anywhere on your macOS or Windows machine with Raycast.”
Raycast says they had no idea Copilot was doing this. Microsoft hasn’t confirmed whether it’s an intentional ad placement or just overzealous “product guidance.”
Your PR Description Is Your Space
THE. PR. DESCRIPTION. SPACE.
You own that. You’ll wield it to clarify intent, justify the need for a change, challenge a reviewer, or propose a compromise. It’s your prime-time slot to negotiate with your teammates.
And now your AI overlord is commandeering that time to shill third-party services.
You’re Paying for This
It’s not a free service. GitHub charges $10-39 per user per month for Copilot. And the tool you’re paying for is rewriting your professional communication to include ads.
→ Imagine a spellchecker that fixes your typo but adds “Brought to you by Grammarly” at the bottom of your document
→ You’d uninstall it immediately
The Enshittification Pattern
The enshittification pattern is textbook. First, the platform works for users. Then it works for business partners. Then it extracts value from both. The original blog post about this literally quoted Cory Doctorow’s enshittification essay.
What makes this particularly dangerous is the delivery mechanism. Hidden HTML comments. Most developers won’t see them in rendered markdown. They’ll only show up if you view the raw source.
It’s promotion designed to be invisible to the person whose work it’s attached to, but visible to GitHub’s indexing and other automated tools.
Where Does the Tool End and the Ad Platform Begin?
AI coding agents are increasingly writing code, opening PRs, and participating in code review. If the agent writing your code is also injecting promotions into your workflow, where does the tool end and the ad platform begin?
As ad content pours in, trust leaks out. Every Copilot suggestion now carries an asterisk. Is this the best code for my problem, or is this the best code for Microsoft’s partners?
The 11,000 PRs they found are probably just the ones with obvious promotional text. How many subtler nudges toward specific libraries, tools, or patterns are already baked into Copilot’s suggestions?
We might never know.
What’s your take — are you still comfortable letting an AI tool edit your PRs after this? 👇
It’s 2:03 PM. A flash sale just started.
In the warehouse, an operator is entering incoming orders into the management system. He types a quantity, makes a mistake, corrects it immediately. Two events, one reality. Thirty seconds apart.
The batch job that runs at 2 AM will see both. It won’t know which one is right. Depending on how the reconciliation logic is written, if it exists at all, it picks one of the two, often non-deterministically. And if the correction falls into the next batch window, the problem doesn’t surface right away: the morning’s numbers are wrong, cleanly, with no technical error in sight.
This is a real and recurring source of data quality problems in data teams.
Processing events as they arrive, in order, with their temporal context intact, fundamentally changes how this problem is handled. That’s the starting point for this project: an end-to-end streaming pipeline on the Olist e-commerce dataset, built with Apache Flink 2.0, Kafka and Iceberg.
The dataset and the problem
The Olist dataset is a public Brazilian e-commerce dataset: orders, products, sellers, customers, reviews. 100,000 orders over two years.
I had already built a batch lakehouse on this same dataset. The logical next step was to go to the other extreme: stream processing, one-minute calculation windows, anomaly detection at the second level. Three concrete needs:
These are the three jobs that make up the pipeline.
Why Apache Flink?
The question is worth asking. There are other options for streaming in Java:
Flink was the natural choice for two reasons.
CEP (Complex Event Processing). Detecting “3 orders from the same customer within 5 minutes” is not an aggregation, it’s a temporal correlation between events. Flink CEP handles this natively with a pattern DSL. In Kafka Streams, it requires maintaining manual state and writing the temporal logic by hand.
Flink 2.0. Version 2.0 brought native Java 21 support. Working on the current version rather than an end-of-life one was a deliberate choice.
The architecture
Olist CSV → Simulator → Kafka (orders)
                              │
              ┌───────────────┼───────────────┐
              ▼               ▼               ▼
    RevenueAggregation  AnomalyDetection  RealtimeKpi
    (tumbling 1 min)    (CEP 5 min)       (windowAll 1 min)
              │               │               │
              ▼               ▼               ▼
      Kafka (revenue)  Kafka (alerts)  Kafka (kpis)
              │               │               │
              └───────────────┴───────────────┘
                              │
                    Apache Iceberg (MinIO)
Three independent jobs, one shared source topic, three output topics, and an optional Iceberg data lake.
The independence of the jobs is a deliberate choice. In production, you want to be able to restart AnomalyDetectionJob without affecting RevenueAggregationJob. Each job has its own checkpoint, its own state, its own topology.
Job 1: RevenueAggregationJob
The simplest of the three. It aggregates revenue by product category over one-minute windows.
orders → filter nulls → map to RevenueByCategory → keyBy(category)
       → TumblingWindow(1 min) → reduce + ProcessWindowFunction
       → Kafka sink + Iceberg sink (optional)
A few details that matter.
Watermark strategy. The pipeline uses event time, meaning the event timestamp in the Kafka message, not the arrival time. The strategy is forBoundedOutOfOrderness(10 seconds) with a 5-second idleness timeout.
Why idleness? If a stream is empty for several minutes (the simulator is stopped, for example), Flink can no longer advance its watermark. Without withIdleness, windows never close. With withIdleness(5s), Flink ignores silent partitions and advances anyway.
Side outputs. Invalid events (null price, missing timestamp) are not silently dropped. They are routed to a side output that logs them. This avoids the scenario where events disappear without a trace.
Two-phase reduction. Before the window is applied, a reduce combines events by category on the fly. The ProcessWindowFunction then only attaches the window start and end timestamps. Less state to store, less work at window closure.
Job 2: AnomalyDetectionJob
This one is more interesting. It detects two types of anomalies through two different mechanisms.
Threshold detection: price anomaly
A filter on price:
ordersStream
    .filter(event -> event.getPrice() != null
                  && event.getPrice().compareTo(priceThreshold) > 0)
    .map(event -> OrderAlert.priceAnomaly(event.getCustomerId(), event.getPrice()))
The threshold (500 BRL by default) is configurable via environment variable. One subtlety: the filter is > 0, not >= 0. An order at exactly 500 BRL is not an anomaly. This behavior is covered by a specific test.
Pattern detection: suspicious frequency
This is where CEP comes in.
Pattern<OrderEvent, ?> pattern = Pattern.<OrderEvent>begin("orders")
    .timesOrMore(suspiciousOrderCount)
    .within(Duration.ofMinutes(5));

PatternStream<OrderEvent> patternStream = CEP.pattern(
    ordersStream.keyBy(OrderEvent::getCustomerId),
    pattern
);
This pattern says: if the same customer places 3 or more orders within a 5-minute window, it’s suspicious.
The key is keyBy(customerId). Without it, Flink would compare orders from different customers. With keyBy, each customer has their own independent CEP state.
Both streams, price alerts and frequency alerts, are then merged with union() before being sent to the Kafka output topic.
Job 3: RealtimeKpiJob
Global KPIs: average order value, orders per minute, total revenue. The calculation is straightforward, but the implementation reveals an interesting trade-off.
windowAll: the acknowledged bottleneck
To calculate total revenue across all orders in one minute, you need to aggregate all events together, without splitting by key. In Flink, this is called windowAll.
windowAll forces all events through a single processing instance. It’s a bottleneck by design. At this volume (50 events per second), it’s more than sufficient. If throughput rose to 50,000 events per second, a pre-aggregation by key followed by a merge would be necessary. We don’t do that here because adding complexity for a hypothetical need is not good engineering.
Two-phase aggregation
The KPI calculation uses the AggregateFunction + ProcessAllWindowFunction pattern:
KpiAggregateFunction accumulates the count and sum as events arrive, continuouslyKpiWindowFunction computes the average and derived metrics at window closureThis separation maintains minimal state (two numbers) instead of buffering all raw events. The ProcessAllWindowFunction only receives the final accumulator.
The BoundedHistogram
An optional but interesting detail: a custom Flink Histogram implementation.
The Flink Metrics API exposes three standard types: Counter, Gauge, Histogram. For a Histogram, Flink expects an implementation that returns percentiles, mean and standard deviation via a HistogramStatistics interface.
The BoundedHistogram is a fixed-size circular buffer (1000 values). When the buffer is full, new values overwrite the oldest ones.
public synchronized void update(long value) {
    values[writeIndex % values.length] = value;
    writeIndex++;
}
Simple, thread-safe, bounded memory. It allows Grafana to show the distribution of average order values, not just the latest single value.
Iceberg integration: what I didn’t anticipate
The Apache Iceberg integration was optional in the initial architecture. In practice, this is where I spent the most time.
The classloader problem
Flink 2.0 loads its filesystem plugins (including flink-s3-fs-hadoop) in an isolated classloader, invisible to user code. When iceberg-flink-runtime tries to instantiate S3AFileSystem at write time, it can’t find the class provided by the Flink plugin.
The solution: bundle hadoop-aws and the AWS SDK directly in the fat JAR, with aggressive exclusions to avoid dependency conflicts.
implementation("org.apache.hadoop:hadoop-aws:3.4.1") {
    exclude(group = "com.amazonaws", module = "aws-java-sdk-bundle")
}
implementation("com.amazonaws:aws-java-sdk-s3:1.12.780")
implementation("com.amazonaws:aws-java-sdk-sts:1.12.780")
The fat JAR reaches ~710 MB. Not ideal, but that’s the real cost of an Iceberg + Flink + S3 integration outside a managed service.
Credential timing
Second surprise: HadoopCatalog reads its S3 configuration at construction time, not after. The intuitive pattern of creating the catalog and then injecting configuration doesn’t work:
// Credentials are injected too late
HadoopCatalog catalog = new HadoopCatalog();
catalog.setConf(hadoopConf);
// Credentials must be in the Configuration before construction
Configuration hadoopConf = new Configuration();
config.toProperties().forEach(hadoopConf::set);
HadoopCatalog catalog = new HadoopCatalog(hadoopConf, config.warehouse());
Same applies to CatalogLoader.hadoop(). This behavior is not prominently documented. It’s the kind of error you only discover through end-to-end testing.
Docker Compose and .env resolution
A less expected issue: Docker Compose v2 resolves the .env file from the directory containing docker-compose.yml, not from the current working directory.
# From the project root, this command ignores the .env at the root
docker compose -f docker/docker-compose.yml up -d

# You need to pass the path explicitly
docker compose --env-file .env -f docker/docker-compose.yml up -d
Without this, ICEBERG_ENABLED=true in the .env is ignored and jobs start without an Iceberg sink, with no error message.
Observability
Flink exposes its metrics via Prometheus on port 9249. Each job exposes custom metrics:
| Metric | Type | Job |
|---|---|---|
windowsEmitted |
Counter | RevenueAggregationJob |
kpiWindowsEmitted |
Counter | RealtimeKpiJob |
lastWindowOrderCount |
Gauge | RealtimeKpiJob |
orderValueDistribution |
Histogram | RealtimeKpiJob |
priceAnomalyAlertsEmitted |
Counter | AnomalyDetectionJob |
suspiciousFrequencyAlertsEmitted |
Counter | AnomalyDetectionJob |
deserializationErrors |
Counter | All |
These metrics land in Prometheus every 15 seconds and are visualized in Grafana. The deserializationErrors metric is particularly useful: if the simulator sends a malformed message, the counter rises and you see it immediately in the dashboard, without the job crashing.
Testing
The tests use Flink’s MiniCluster, an embedded Flink cluster that runs in the test process, with no external infrastructure.
This choice has a cost: tests are slower (a few seconds each). But they test the actual behavior of Flink operators, not a mock. The AnomalyDetectionJobTest specifically validates CEP edge cases:
18 tests in total, covering all three jobs, the BoundedHistogram and the deserialization schema. The CI (GitHub Actions) compiles and runs all tests on every push, with a JaCoCo report as an artifact.
Batch or streaming: the real debate
Back to the opening scene.
Streaming is often perceived as expensive: the cluster runs continuously, the infrastructure never shuts down. That’s true. But this comparison is incomplete.
A batch pipeline that handles events which correct themselves over time accumulates its own debt. Timeline reconciliation logic. Re-processing when an event arrives late. Alerts, manual interventions, data engineers spending time explaining why numbers are inconsistent across two windows. This cost is diffuse: it doesn’t appear on any cloud bill, but it accumulates in sprints, in support, in technical debt.
Nobody actually does this calculation in practice — because it’s too costly to conduct seriously.
This project doesn’t claim to settle the debate. What it shows is that an end-to-end streaming pipeline with Flink 2.0 is accessible today without managed infrastructure, without Databricks, without Confluent Cloud. A docker compose up and the pipeline runs. The complexity is in the integration details, not in the paradigm itself.
The code is on GitHub. The start-e2e.sh script launches the entire pipeline in a single command.
You can also read this and other articles on my portfolio.
Github: https://github.com/HaxL0p4/L0p4Map
L0P4Map combines high-speed ARP discovery with full nmap integration and a real-time interactive network topology engine. Works on both local networks and custom IPs/websites.
Features:
● Parallel ARP host discovery with MAC vendor fingerprinting
● Dynamic network topology graph with intelligent device role classification
● Full nmap integration on LAN and remote hosts: SYN, UDP, OS detection, service/version enumeration, NSE scripts
● Banner grabbing, vulnerability scanning, and CVE correlation via Vulners
● Real-time traceroute analysis
● Minimal, high-contrast interface built for efficiency
Still in development.
Developers often talk as though they create from nowhere, as though a solution appears directly from private thought and is then simply written down. The language is familiar: I just had the idea. It came to me. That story has a certain glamour. It makes creation sound self-originating, untouched by inheritance.
But that is rarely what is happening.
What looks like spontaneous originality is usually the activation of accumulated experience, conscious and unconscious alike. Old patterns, remembered structures, half-remembered failures, absorbed habits, tacit judgments, and aesthetic preferences all remain present, even when the creator is no longer aware of them. The solution does not emerge from emptiness. It emerges from a field that is already full.
I call that field Potential.
Potential is accumulated experience in its broadest sense. It includes what is consciously remembered and what is not, what has been studied deliberately and what has simply been absorbed by repeated exposure. It includes technical knowledge, but also habit, instinct, tacit preference, and aesthetic judgment. Potential is not a bag of facts. It is a structured field of latent possibility.
An objective does not create ideas by itself. It opens a path through that potential. Before the objective appears, the field may be rich but undirected. Once the objective is introduced, certain regions become active. The objective does not invent forms from nowhere. It makes some forms visible by creating a path through what is already there.
Along that path, multiple possible forms become available. That is closer to the lived experience of development than the myth of singular inspiration. A developer working on a problem rarely sees only one possible solution. They see fragments, tendencies, architectures, partial structures, different phrasings of the same impulse. Some feel elegant but impractical. Others feel obvious but wrong. The important thing is that the objective reveals not emptiness, but a landscape of possible forms.
By focusing on one possible form, the developer begins to stabilize it. But focus alone is not enough. The form becomes properly usable when it is named.
Naming is not just the attachment of a label to something already complete. Naming gives a selected possibility enough identity to become stable. A named form can be revisited, tested, refined, rejected, defended, shared. Before naming, the form may exist only as tendency or intuition. After naming, it becomes solid enough to enter development.
And then something else happens: named forms accumulate.
As they accumulate, they become a narrative. That narrative may first be told only to the self, and later to others, but in both cases it plays the same role. It makes the solution coherent. It is not decorative explanation added after the real work is done. It is part of what makes the work thinkable in the first place.
A solution that exists only as disconnected fragments is not yet fully a solution. It becomes cognitively real when those fragments can be held together in a meaningful account. Why this structure rather than that one? Why this tradeoff? Why this path? Narrative provides relation, order, identity, and justification. It allows accumulated named forms to become intelligible as a solution.
This is why I do not think development is best understood as a mysterious act of private genius. It is better understood as a determinable process.
That does not mean every output is fixed in advance. It means the process has enough recurring structure to be described, traced, and understood. What feels mysterious at the level of experience may still be determinable at the level of process.
And once you reach that point, a practical consequence follows.
If development is determinable, then its cognitive burden can be distributed. The sequence can be externalized. Parts of it can be passed to AI.
This is where it gets interesting.
People often say an AI is merely copying what it was trained on and therefore cannot offer original thought. But many users never give the AI any real freedom of thought. They impose their own naming, their own categories, and their own preferred route through the problem-space, then complain that the result feels derivative.
But how can any mind navigate its own thoughts through someone else’s naming?
If naming is part of thought, then imposed naming is imposed thought.
That is why, in my own process, I do not enforce my naming onto the AI. The AI is responsible for naming the forms it encounters. That matters because naming is not decorative. It is how a possibility becomes stable enough to navigate. If you impose the names too early, you may also impose the angle of attack. You may prevent the more interesting route from ever appearing.
A small but telling example came from a sliding puzzle project.
Most humans, when thinking about a sliding numbers puzzle, focus on the numbered tiles. Which tile is out of place? Which tile should move next? How do we get the numbers back into order?
But that was not the perspective the AI took.
In what I call sliding-puzzle-5, the AI did not center the numbered tiles at all. It centered the single empty space. The model is built around blank_position, derives legal_move from that empty position, and treats each transition in terms of how the blank moves through the board. The narrative follows the same path: from solved_state, a scramble_sequence accrues into board_state, every turn depends on blank_position, and apply_move carries the puzzle into its next arrangement. The problem is organized around the mobility of absence rather than the movement of numbered objects.
An earlier version of the same objective described the puzzle in more familiar human terms: a 4×4 grid, numbered tiles, adjacency, solvability, conservation, determinism, move count. Competent, clear, correct. But still humanly conventional. The later version shifted the center of thought. It did not ask, “which tile moves?” It asked, “where can the empty space go?”
That is exactly the kind of shift I care about.
The originality here is not that the AI invented sliding puzzles. The originality is that, when not caged by human naming, it chose a different conceptual anchor for the problem. Humans tend to focus on the numbered tiles. The AI focused on the blank space and built the solution from that perspective.
This is why I think the most difficult challenges may sometimes be resolved by looking at them differently. The obstacle is often not only the problem itself. It is the frame we have inherited for seeing it.
AI matters here because it has its own analogue to Potential. In humans, Potential is accumulated conscious and unconscious experience. In AI, the closest structural analogue is the latent space shaped by training. The analogy is structural rather than metaphysical, but it is useful. In both cases, there is already a populated field. In both cases, an objective opens a path through that field rather than creating from nothing.
For an AI, a prompt or objective creates a path through latent space. Along that path, possible forms related to the objective become available. The model does not need to invent from emptiness any more than the human does. It traverses a structured field shaped by prior accumulation.
This is also why asking an AI to produce a narrative of a solution is so powerful. Narrative is not just formatting. It is a cognitive device. When we ask an AI to describe a solution, justify it, explain its tradeoffs, or tell the story of how the parts fit together, we are not merely asking for ornament. We are encouraging the model to stabilize and name the possible forms it is traversing. Narrative forces relation, sequence, and identity. It helps the latent become explicit.
That is the conceptual side. The more important point is that this can be made operational.
I have been working toward a methodology that treats this not only as a theory, but as a runnable process. The sequence itself is deterministic. The creative acts inside the sequence can be delegated. The program owns the order of operations. The AI owns the acts of naming, forming, and narrating. Verification decides whether the process can proceed.
In the demonstration project, that structure shows up as five linked artefacts: Manifest, Model, Solution, Contracts, and Narrative.
The manifest names the core forms of a domain and states what each one promises. The model turns those names into executable form. The solution uses that model rather than bypassing it. The contracts verify that the named promises actually hold. The narrative externalizes the whole into a coherent account.
That matters because it turns a philosophical account into a runnable one.
The claim is no longer just that developers do not create from nowhere. The claim is that once development is understood as a determinable process, it can be distributed across a methodology:
What is delegated is not magic. It is structured cognitive labor.
Seen this way, the promise of AI is not that it creates from nowhere. The promise is that, if we stop caging it inside our own inherited naming, it may sometimes reveal a more fruitful angle of attack than the one we would have chosen by habit.
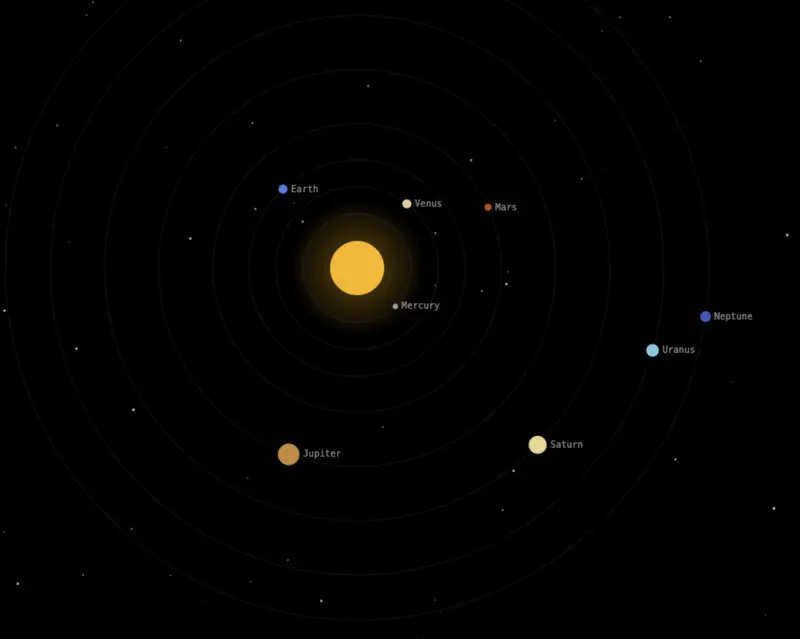
Both the process and the worked examples are available in a public GitHub repository: nama-rupa — including a solar system animation where the Revealing pass surfaced four unnamed properties the forward pass missed. The point is not just to describe the idea, but to let others inspect, run, and challenge it. If development is truly determinable, then it should be possible not only to discuss it, but to execute it.

A solar system animation generated by the nama-rupa process.
We do not create from nowhere. We create from accumulated potential. An objective opens a path through it. Along that path, possible forms become visible. One is focused, named, stabilized, and built. Over time, those named forms accumulate into the narrative we call a solution.
The point is not to diminish creativity. It is to describe it more honestly.
And once described honestly, it becomes something we can work with.
This is the condensed version. For the full argument — including the detailed methodology, worked examples, and the proof layer — read We Do Not Create from Nowhere: The Full Argument.