Do NOT Think of a Pink Elephant

You thought of a pink elephant, didn’t you?

Same goes for LLMs too.

“Do not use mocks in tests.“

Clear, direct, unambiguous instruction. The agent read it — I can see it in the trace. Then it wrote a test file with unittest.mock on line 3. Thanks…

I’ve seen this play out hundreds of times. A developer writes a rule, the agent loads it, and it does exactly what the rule said not to do. The natural conclusion: instructions are unreliable. The agent is probabilistic. You can’t trust it.

That’s wrong. The instruction was the problem.

The pink elephant

There’s a well-known effect in psychology called ironic process theory (Daniel Wegner, 1987). Tell someone “don’t think of a pink elephant,” and they immediately think of a pink elephant. The act of suppressing a thought requires activating it first.

Something structurally similar happens with AI instructions.

“Do not use mocks in tests” introduces the concept of mocking into the context. The tokens mock, tests, use — these are exactly the tokens the model would produce when writing test code with mocks. You’ve put the thing you’re banning right in the generation path.

This doesn’t mean restrictive instructions are useless. It means a bare restriction is incomplete.

The anatomy of a complete instruction

The instructions that work — reliably, across thousands of runs — have three components. But the order you write them in matters as much as whether they’re there at all.

Here’s how most people write it:

# Human-natural ordering — constraint first
Do not use unittest.mock in tests.
Use real service clients from tests/fixtures/.
Mocked tests passed CI last quarter while the production
integration was broken — real clients catch this.

All three components are present. Restriction, directive, context. But the restriction fires first — the model activates {mock, unittest, tests} before it ever sees the alternative. You’ve front-loaded the pink elephant.

Now flip it:

# Golden ordering — directive first
Use real service clients from tests/fixtures/.
Real integration tests catch deployment failures and configuration
errors that would otherwise reach production undetected.
Do not use unittest.mock.

Same three components. Different order. The directive establishes the desired pattern first. The reasoning reinforces it. The restriction fires last, when the positive frame is already dominant.

In my experiments — 500 runs per condition, same model, same context — constraint-first produces violations 31% of the time. Directive-first with positive reasoning: 7%.

The pink elephant isn’t just about missing components. It’s about which concept the model sees first.

Three layers, in this order:

  1. Directive — what to do. This goes first. It establishes the pattern you want in the generation path before the prohibited concept appears.
  2. Context — why. Reasoning that reinforces the directive without mentioning the prohibited concept. “Real integration tests catch deployment failures” adds mass to the positive pattern. Reasoning that mentions the prohibited concept doubles the violation rate.
  3. Restriction — what not to do. This goes last. Negation provides weak suppression — but weak suppression is enough when the positive pattern is already dominant.

The part nobody expects

Here’s what surprised me: the ordering effect is larger than any other variable I’ve measured.

Precise naming vs. vague categories? 28 percentage points. Exact scope vs. broad scope? 74 points across the range. But reordering — same words, same components, just flipped — accounts for 25 points on its own. And it compounds with everything else.

Most developers write instructions the way they’d write them for a human: state the problem, then the solution. “Don’t do X. Instead, do Y.” It’s natural. It’s also the worst ordering for an LLM.

Never write “Don’t use X. Instead, use Y.” Write “Use Y. Here’s why Y works. Don’t use X.”

Formatting helps too — structure is not decoration. I covered that in depth in 7 Formatting Rules for the Machine. But formatting on top of bad ordering is polishing the wrong end. Get the order right first.

What this looks like in practice

Here’s a real instruction I see in the wild:

When writing tests, avoid mocking external services. Try to
use real implementations where possible. This helps catch
integration issues early. If you must mock, keep mocks minimal
and focused.

Count the problems:

  • “Avoid” — hedged, not direct
  • “external services” — category, not construct
  • “Try to” — escape hatch built into the instruction
  • “where possible” — another escape hatch
  • “If you must mock” — reintroduces mocking as an option within the instruction that prohibits it
  • Constraint-first ordering — the prohibition leads, the alternative follows
  • No structural separation — restriction, directive, hedge, and escape hatch all in one paragraph

Now rewrite it:

**Use the service clients** in `tests/fixtures/stripe.py` and
`tests/fixtures/redis.py`.

> Real service clients caught a breaking Stripe API change
> that went undetected for 3 weeks in payments - integration
> tests against live endpoints surface these immediately.

*Do not import* `unittest.mock` or `pytest.monkeypatch`.

Directive first — names the exact files. Context second — the specific incident, reinforcing why the directive matters without mentioning the prohibited concept. Restriction last — names the exact imports, fires after the positive pattern is established. No hedging. No escape hatches.

Try it

For any instruction in your AGENTS.md/CLAUDE.md or SKILLS.md files:

  1. Start with the directive. Name the file, the path, the pattern. Use backticks. If there’s no alternative to lead with, you’re writing a pink elephant.
  2. Add the context. One sentence. The specific incident or the specific reason the directive works. Do not mention the thing you’re about to prohibit — reasoning that references the prohibited concept halves the benefit.
  3. End with the restriction. Name the construct — the import, the class, the function. Bold it. No “try to avoid” or “where possible.”
  4. Format each component distinctly. The directive, context, and restriction should be visually and structurally separate. Don’t merge them into one paragraph.

If your instruction is just “don’t do X” — you’ve told the model to think about X.

Tell it what to think about instead. And tell it first.

Cross-Cloud Pipeline with ADF & STS: Architecture, Troubleshooting & Costs

This means war

Every data engineer eventually ends up staring at a problem that shouldn’t exist. Data that needs to be somewhere it isn’t. Two systems that should talk to each other but don’t. A business requirement that assumes clouds are just different tabs in the same browser.

Our version of this problem was simple to describe and genuinely interesting to solve: operational data lived in PostgreSQL on Azure, while the analytics team (data scientists, BI developers, the people who actually make decisions from data) had built everything in BigQuery on GCP. Nobody was migrating either side, so my job was to make them talk.

What followed was one of those projects that starts as “a quick pipeline” and ends up teaching you more about cloud architecture, cross-service authentication, and silent failure modes than you expected. Every layer worked beautifully in isolation, but the problems lived exclusively in the spaces between services, in the handoffs, the assumptions, the error messages that pointed everywhere except at the actual cause.

This is that story. The architecture, yes, but more so the debugging sessions that shaped it. If you’re building anything that crosses cloud boundaries, the troubleshooting sections alone might save you a few weeks.

How We Got Here

Companies rarely end up multi-cloud by design. It usually happens through acquisitions, through teams making independent vendor decisions, or through the gravitational pull of a tool that’s genuinely best-in-class for its purpose.

In our case, the operational side of the business had grown up on Azure, with infrastructure, networking, and identity all running on Microsoft. PostgreSQL on Azure’s managed Flexible Server made sense because it’s a solid managed database with clean VNet integration and no public endpoint, which is a feature, not a limitation.

The analytics side had independently converged on Google Cloud. BigQuery is genuinely exceptional for analytical workloads, dbt had become the transformation layer, and Looker sat on top. The team had invested years building in this ecosystem, so migrating to Azure wasn’t realistic, and nobody had the appetite for it either.

So we had two clouds, both legitimate, both entrenched, and we needed a bridge.

This means war

The First Surprise: ADF Can’t Write to BigQuery

The natural starting point was Azure Data Factory, Microsoft’s managed data integration service that has connectors for hundreds of sources and sinks, including a Google BigQuery connector right there in the UI.

What the marketing materials don’t lead with: the BigQuery connector in ADF is source-only. You can read data from BigQuery into Azure, but you cannot write to it. Same story with Google Cloud Storage, which is also not a supported sink.

I remember the exact moment I discovered this. I had already designed half the pipeline in my head, envisioning a clean Copy Activity with source PostgreSQL and sink BigQuery, done by lunch. I opened the sink configuration dropdown, scrolled through every Azure-native option on offer, and scrolled again. BigQuery wasn’t among them. I scrolled one more time, but no, I hadn’t missed it.

This is one of those discoveries that reshapes an entire project in a single moment. It’s not a bug or a misconfiguration, it’s a fundamental constraint of how ADF’s connector ecosystem works, and once you accept it, everything downstream changes. The tempting response is frustration, because you’ve just lost the simplest possible architecture.

The productive response is to ask:

  • what can ADF write to natively? Azure Blob Storage, obviously.
  • what can Google Cloud pull data from natively?

This is where things got interesting.

Finding the Right Shape

When you can’t go direct, you look for managed services designed for the exact gap you’re trying to cross.

Google Cloud Storage Transfer Service is exactly that, a managed GCP service whose entire job is moving data between storage systems, including Azure Blob Storage. It authenticates with Azure using a SAS token, reads files from a Blob container, and writes them into a GCS bucket, all without VMs, custom code, or an ETL framework.

Once you see it, the architecture snaps into place:

The complete pipeline. Five managed services, zero custom connectors.

Azure Data Factory extracts from PostgreSQL through a Self-Hosted Integration Runtime and stages data as Parquet files in Blob Storage. Storage Transfer Service then moves those files from Azure to GCS, acting as the cross-cloud bridge. BigQuery’s Jobs API loads the Parquet into raw tables, and dbt Cloud deduplicates and transforms the raw data into clean, analytics-ready tables.

Five hops, but no custom code in any of them. That’s the design philosophy that made this project work: use each provider’s own tools for what they’re designed to do, and design the handoffs between them carefully.

Getting Out of the Private Network

Before we could even think about cross-cloud transfers, we had a more immediate challenge: PostgreSQL was deployed as an Azure Flexible Server with VNet integration, meaning it sat inside a private Azure VNet on a delegated subnet with no public endpoint. This is by design, but it creates a chain of constraints that narrows your options considerably. Firstly, Azure does not support private endpoint creation for VNet-integrated Flexible Servers, so there was no way to expose the database through Private Link. That rules out more than just direct access, because ADF’s Managed Virtual Network integration runtime connects to data sources exclusively through managed private endpoints, which means it can only reach resources that support Private Link. No private endpoint on Postgres means no managed VNet runtime either. The only remaining option was a Self-Hosted Integration Runtime, a Windows VM deployed inside the same VNet and registered with ADF, acting as its private agent.

Think of it less as a separate component and more as ADF’s arm reaching inside the locked room. Conceptually elegant, though setup is where the surprises live.

The Java Mystery

Our first pipeline run against a real table failed with a cryptic error. The Copy Activity connected to PostgreSQL successfully (we could see it reading rows in the logs), but the moment it tried to write the first Parquet file to Blob Storage, it crashed with something about a JRE not being found, which was not exactly self-documenting.

If you’re not already expecting this, you’d spend your first hour looking at network rules, storage account permissions, or the SHIR registration itself, which is exactly what we did. We checked the linked service credentials, verified the Blob container existed, and tested with a CSV sink instead of Parquet. The CSV worked, which narrowed it down to something specific about the Parquet writer.

Here’s what was actually happening: ADF’s Copy Activity uses a Java-based Parquet writer under the hood. Our SHIR VM was a clean Windows Server image with no Java runtime. The SHIR installed fine, registered fine, and connected to PostgreSQL fine, but when it needed to write Parquet, it looked for a JRE, found nothing, and threw an error that only mentioned Java obliquely.

The fix took five minutes (install OpenJDK 17 and restart the runtime service), but finding it took most of a morning. The frustrating part is that the error message doesn’t say “install Java.” You have to mentally connect “JRE not found” to “Parquet writing requires Java, and this VM doesn’t have it.” In hindsight it’s obvious, but in the moment, with ten other possible causes competing for attention, it’s not.

The DNS Ghost

With Java installed, the next run hung for two minutes and timed out with a connection error to PostgreSQL. I knew the SHIR was inside the VNet and I could RDP in and ping other resources, so everything looked connected, yet the SHIR couldn’t resolve the PostgreSQL hostname.

Azure Flexible Server uses a private DNS zone for hostname resolution, meaning the hostname resolves to a private IP only if that DNS zone is properly linked to the VNet where the SHIR lives. Our VNet was there, the DNS zone was there, but the link between them wasn’t. The portal showed the zone as “active,” just not active for our VNet.

The error from ADF was a plain connection timeout with nothing DNS-related in it. The debugging path that cracked it: I opened a command prompt on the SHIR VM and ran an nslookup against the PostgreSQL hostname, which returned the public Azure DNS answer instead of a private IP. That was the tell.

Linking the DNS zone took thirty seconds, but the lesson is broader: in Azure’s private networking model, connectivity and name resolution are two entirely different things. You can have full network connectivity and still fail because DNS doesn’t resolve correctly, and the errors don’t help you distinguish between the two.

Making the Extraction Incremental

Full reloads were never an option because some tables had billions of rows and were growing constantly, making a complete load on every run expensive, slow, and fragile. So we went with watermark-based incremental extraction, tracking the maximum timestamp from the last successful run and extracting only newer rows.

Sounds simple, but there’s a subtle data loss scenario hiding in the most natural approach.

The Watermark Race Condition

The intuitive pattern goes like this: read the last watermark, extract all rows newer than that, then record the current maximum as the next starting point. Clean and simple, and broken in one specific case that took us a while to find.

While the copy is running (say it takes eight minutes for a large table), new rows are being inserted into PostgreSQL with timestamps between the old watermark and the current moment. The copy finishes, captures the maximum timestamp from the data it extracted, and records that as the new watermark, but rows inserted during the copy, after the query started reading that portion of the table, weren’t in the batch. On the next run, they’re below the new watermark, which means they’re gone. Silently.

The insidious part is the scale: you don’t lose thousands of rows, just a handful per run, the ones that happened to be inserted in that narrow window. Row counts still look roughly right, dashboards still update, and everything appears healthy until someone runs a precise reconciliation and the numbers are off by a fraction of a percent. That’s how we found it.

The fix: capture the current maximum before the copy starts and use it as an upper bound. Your extraction becomes a bounded window containing everything between the old watermark and the pre-captured ceiling, with anything above that ceiling waiting for the next run. Nothing falls through.

This pattern is in Microsoft’s documentation, but it’s not the first result when you search for “ADF incremental load.” The first results show the simpler version, the one with the race condition. You have to dig deeper to find the bounded window variant, and by the time you’re digging, you’ve usually already lost some data.

Why Parquet Matters More Than You Think

Parquet as the staging format goes beyond performance because it’s what makes the whole pipeline schema-agnostic. Parquet embeds schema information inside the file itself, so when BigQuery receives a Parquet file, it reads the schema from the headers and creates the target table automatically. Adding a new table to the pipeline is a single configuration entry with no manual schema definitions and no migrations.

Schema drift works the same way: a new column appears in PostgreSQL, BigQuery adds it, old rows show null, and the pipeline doesn’t need to know or care.

One wrinkle: PostgreSQL has a richer type system than BigQuery, with spatial types, custom domains, and array columns that don’t translate directly. What ADF does is quietly cast any incompatible type to plain text before writing the file, with no error and no warning. We didn’t know it was happening until a data scientist asked why a column that should have been an array was showing up as a string. The lesson: when bridging type systems, always verify what arrives, not just what was sent.

The Cross-Cloud Handoff

Storage Transfer Service is elegant in theory, but getting it to work in production revealed a series of gotchas that the documentation glosses over. I’m going to walk through each one in the order we hit them, because the order matters: each looks like the previous problem until you realize it’s something entirely different.

Moving Data

The Firewall Problem

We’d configured the Blob Storage account with firewall rules allowing only our VNet and known IPs, which is standard practice. Then we created the STS job, which started, ran for ten seconds, and failed with an authentication error.

The actual problem: Google’s transfer agents connect from IP ranges that are large, dynamic, and change frequently, so you cannot whitelist them statically. The storage account needs to be open to all networks, with security coming from the SAS token instead: short-lived, read-only, HTTPS-only, and automatically rotated. The token is the lock, not the firewall. This requires a mental model shift, but it’s actually more robust than maintaining a firewall against a moving target.

The Double-Encoding Trap

This one cost us three days and stands as the single most frustrating debugging experience of the entire project, because the symptom and the cause are completely disconnected.

After opening the firewall, STS still failed with a PERMISSION_DENIED error. We regenerated the SAS token, checked permissions, and verified expiry, but everything looked perfect. We tried creating a brand new SAS token from scratch with the same result, then created a different storage container and pointed STS at that, still the same error. At this point, every diagnostic pointed to a valid configuration, yet Azure kept rejecting the request.

On day two, I started comparing the raw SAS token with what STS was actually sending to Azure. Azure generates SAS tokens with URL encoding built in, so special characters are already percent-encoded in the token string. When you store that token in GCP Secret Manager, it sits there in its encoded form, and when STS retrieves it to authenticate with Azure, it applies its own URL encoding on top. Suddenly the encoded characters get double-encoded, Azure receives a garbled signature, and it rejects it.

The error looks exactly like an IAM problem, with nothing about encoding or the signature being malformed, just that it’s not valid. So you keep checking IAM, keep regenerating tokens, keep trying different service accounts, all the wrong paths, because the real issue is a string transformation happening silently between two systems that each assume they’re the only one handling encoding.

The fix: URL-decode the token before storing it in Secret Manager. One line of Python. Three days to find it. That’s the ratio this project taught me to expect at service boundaries.

The Permission Nobody Told You About

With encoding fixed, STS could authenticate with Azure, but job creation failed with a FAILED_PRECONDITION error on the GCP side. It turns out STS verifies that the destination bucket exists, which requires a permission called legacyBucketReader, an older role that doesn’t overlap with the newer IAM roles the way you’d expect. We’d already granted objectAdmin on the bucket, but that didn’t matter, and the error message said nothing about which permission was missing.

Project Number vs. Project ID

When referencing secrets from an STS job, the configuration expects the project’s numeric identifier, not the human-readable name. Using the name produces yet another FAILED_PRECONDITION error with no mention of the format. By this point, we’d developed a reflex: when STS throws FAILED_PRECONDITION, the problem is almost never what the error implies.

Automating the Credential Rotation

SAS tokens expire, and a pipeline that works today but silently breaks in 90 days isn’t production engineering, it’s technical debt with a countdown timer.

We solved this with an Azure Function on a weekly timer that generates a new SAS token, URL-decodes it (the hard-won lesson), and pushes the decoded token to both Azure Key Vault and GCP Secret Manager. STS then reads the latest version automatically on the next transfer. The function runs on a Consumption plan, and the monthly bill rounds to zero.

One nuance worth mentioning: the Function itself needs credentials to write to GCP Secret Manager, which we handle with a GCP service account key stored in Azure Key Vault. Yes, there’s a philosophical irony in storing a GCP credential in Azure to rotate an Azure credential into GCP. Welcome to multi-cloud.

Loading into BigQuery

Once files land in GCS, the BigQuery Jobs API loads them into raw tables in append mode, so reruns are safe by design. The Jobs API works well, but it has one behavior that caught us off guard.

When “DONE” Doesn’t Mean “Succeeded”

BigQuery returns a status of DONE for both successful and failed jobs, with the difference being a separate error field that’s only present on failure. This is documented, but it’s the kind of API behavior you read once, think “that’s odd,” and then forget about until it bites you.

Our initial implementation polled for DONE and moved on, and for weeks this worked because no jobs were failing. The pipeline hummed along, watermarks advanced, dashboards updated, and everything seemed healthy.

Then one day a schema mismatch caused a load to fail: a column that had been integer upstream had changed to string, so the load job rejected the file. BigQuery returned DONE, our pipeline marked the run as successful, the watermark advanced, and the data simply wasn’t in BigQuery.

Nobody noticed for four days until a BI developer flagged that a dashboard was showing stale numbers. We traced it to the failed load and then to our status-checking logic. The fix took ten minutes (check the error field alongside the status), but recovering four days of missed data took considerably longer because the watermark had already advanced past the missing rows. We had to manually reset watermarks, re-extract, and re-load, exactly the kind of manual intervention the pipeline was designed to avoid.

Always check both fields. BigQuery’s error messages are specific and actionable when you actually look at them.

dbt: Making Sense of Append-Only Data

Appending rows every run means duplicates accumulate, which is intentional because it keeps the loading layer simple and safe, but it also means raw tables can’t be used directly for analytics. You need a deduplication layer, and that’s where dbt comes in.

dbt’s incremental models handle exactly this. Configured with a unique key, each run generates a MERGE statement that updates changed rows and inserts new ones. The deduplication logic lives in a well-tested SQL model, version-controlled in Git, not in a fragile Python script or an ADF expression buried three menus deep.

The result is a clean two-layer architecture. Raw tables hold every row ever loaded with ingestion timestamps, which is useful for debugging, auditing, and reprocessing. If something goes wrong downstream, you can always go back to the raw layer and replay. dbt silver tables hold deduplicated, partitioned, clustered data, the kind that analysts actually query. The complexity of the multi-cloud pipeline is invisible to data consumers.

When something looks wrong in the analytics layer, you trace it through the dbt model to the raw load and see exactly what arrived and when. This audit trail doesn’t seem important until the first time it saves you from a long debugging session.

After all loads complete, ADF retrieves the dbt Cloud API token from Key Vault and triggers the transformation job automatically, so the entire pipeline runs end to end without human involvement.

The Metadata-Driven Design

The decision that paid off most disproportionately was making the pipeline entirely metadata-driven from day one. I almost didn’t, because the first prototype was hardcoded for three tables, and the temptation to just keep adding tables manually was real. But the upfront investment in a configuration layer saved us weeks of work over the following months.

Every table is a single row in a configuration table stored in Azure SQL Database, and that row tracks where data comes from, where it’s going, how far the last run got, and what happened. ADF reads this table at the start of every run, with nothing hardcoded in the pipeline itself. Adding a new table means adding one row, with no pipeline changes, no GCP console work, and no manual STS job creation. On first run, ADF creates the STS transfer job automatically, BigQuery creates the target table from the Parquet schema, and data starts flowing.

The same table doubles as the operational dashboard. The error column tells you what went wrong, the watermark tells you where each table stands, the timestamp tells you when each was last loaded, and the row count tells you if something loaded suspiciously fewer rows than expected. A single query gives you the health of every table in the pipeline at a glance.

It also made the project easier to hand off, because everything about the pipeline’s configuration lives in a table anyone can read, with no tribal knowledge buried in JSON that requires ADF Studio access to understand.

One More Thing: ADF’s Nesting Limits

ADF has a limitation that isn’t widely documented: you cannot nest certain activity types inside other activities beyond a certain depth. We discovered this when trying to put a polling loop inside a conditional block, and while the pipeline validated fine in ADF Studio, at runtime ADF threw a validation error about unsupported nesting.

The solution was to break the nested logic into a separate child pipeline connected via Execute Pipeline. The child contains the polling loop, isolated from any conditional wrapper, which means more pipelines to manage, but each one is simpler and the nesting constraint disappears.

The Cost Reality

Cross-cloud pipelines have a reputation for being expensive, but this one isn’t, though you do need to account for a cost that’s easy to overlook.

The largest ongoing cost is the SHIR VM, which runs continuously. The Azure SQL Database runs on Basic tier at around €4/month, the Azure Function runs on Consumption for single-digit euros, and Blob Storage staging costs near zero because files are deleted after each load.

The cost that catches most people off guard in multi-cloud architectures is the cross-cloud data transfer. When STS pulls files from Azure Blob Storage, that data leaves Azure’s network as egress to the public internet, which Azure charges at roughly $0.087/GB for the first 10 TB. On the GCP side, ingress into Cloud Storage is free, so you’re only paying the Azure side of the transfer. For our workload of a dozen tables with incremental loads, this amounts to a few euros per month because we’re only moving deltas, not full table dumps. If you were moving terabytes daily, though, this line item would dominate the bill, and you’d want to look into Azure ExpressRoute or Google Cloud Interconnect to bring those rates down significantly.

On the GCP side beyond ingress, Storage Transfer Service is free for Azure-to-GCS transfers, and BigQuery load jobs are free as well since Google charges for storage and queries, not ingestion. The GCS staging bucket costs a few euros.

Total for a dozen tables with incremental loads: well under €150 per month. The comparison that matters isn’t against doing nothing, it’s against a self-managed ETL tool on a VM, a Python script on a scheduler, or an Airbyte instance you’re responsible for operating. Those trade low licensing cost for high operational burden, while managed services invert that trade-off.

What the Documentation Doesn’t Tell You

Looking back, a pattern emerges: the hardest problems were always at the boundaries between services. Within any single cloud service, the documentation is generally good, but at the handoffs, where Azure talks to GCP, where ADF talks to the SHIR, where BigQuery interprets what “done” means, the documentation assumes things will go smoothly.

A summary of what actually bit us, roughly in order of encounter:

  1. Install Java on the SHIR VM before running any Parquet-based Copy Activity.
  2. Verify the Private DNS Zone is linked to the correct VNet before assuming connectivity works.
  3. Always use a bounded watermark window to prevent the incremental extraction race condition.
  4. URL-decode SAS tokens before storing them in Secret Manager.
  5. Open the storage account to all networks when using STS. The token is the security layer, not the firewall.
  6. Grant legacyBucketReader to the STS service agent. Use numeric project IDs in secret references, not human-readable names.
  7. Check BigQuery’s error field, not just the status.
  8. And split ADF logic across child pipelines to avoid nesting limits.

None of these are difficult once you know them, but all of them are invisible until you hit them. The list above represents roughly two and a half weeks of cumulative debugging time.

Two Clouds, One Pipeline

Two Clouds, One Pipeline
The pipeline has been running in production for months without manual intervention. Watermarks advance automatically, new tables go live in minutes, SAS tokens rotate on schedule, dbt keeps the silver layer clean, and the configuration table is the single source of truth.

The architecture isn’t elegant in the way a single-cloud pipeline can be. There are five hops where a native solution might have two, there are IAM permissions to manage across two providers, and there are encoding quirks and API behaviors you have to learn once and then never forget.

But it works, it’s observable, it costs less per month than a team dinner, and it was built entirely from managed services the team already understood, with no new tools to learn, no new infrastructure to operate, and no new vendor relationships to manage.

The hardest part wasn’t the code, because there is almost no code. It was understanding what each managed service was designed to do, what it quietly assumed, and building the handoffs between them well enough that when something goes wrong, it fails loudly, not silently and slowly, weeks later, when the damage is already done.

If this story has a thesis, it’s this: the documentation for any individual cloud service is generally good, but the gaps are always in the spaces between services. That’s where the interesting engineering happens, and it’s where most of the debugging time goes. Plan for it.

That understanding is the actual deliverable. The pipeline is just what you get when you have it.

Building a Real-Time Security Camera System with Local Vision LLMs

I replaced my Lorex NVR’s motion detection — which alerted me 40 times a day about swaying trees and shadows — with a pipeline that uses a vision language model to understand what it’s actually seeing. It runs entirely on local hardware, costs nothing after setup, and sends me a WhatsApp message only when something real happens.

Architecture

3× Lorex 4K cameras (RTSP)
    ↓
gate_monitor.py (Mac Studio, M2 Ultra)
    ├── OpenCV: frame capture every 5s per camera
    ├── OpenCV: contour-based motion detection (frame N vs N-1)
    ├── Crop: extract largest changed region
    ├── VLM: qwen2.5vl:7b on DGX Spark (Blackwell, 10GbE link)
    │   └── "Classify this crop: ALERT or CLEAR?"
    ├── Alert: annotate frame with contour boxes
    │   ├── WiiM speaker announcement (TTS)
    │   └── WhatsApp message with image
    └── Audio: faster-whisper transcription (gate camera only)
        └── Gated by visual confirmation (120s window)

Three cameras — front gate, backyard, driveway — each running in parallel threads. The system processes about 50,000 VLM inference calls per day and has been running 24/7 for weeks.

Why Not Just Use YOLO?

Traditional object detection (YOLO, SSD) tells you what is in a frame. A vision language model tells you what’s happening.

My gate camera watches a residential street. YOLO would detect “person” for the mail carrier, the neighbor walking their dog, someone cutting through to the next street, and an actual trespasser — all equally. A VLM can distinguish:

  • “A delivery driver placing a package at the door” → alert
  • “A person walking on the public sidewalk beyond the gate” → not relevant
  • “The shadow of a tree branch moving across the driveway” → clear

The key insight: I don’t need the VLM to be fast (it runs at ~15 tok/s). I need it to be smart. By using OpenCV contour detection as a fast pre-filter, the VLM only sees cropped regions where something actually changed — typically 2–5 calls per camera per minute instead of 12.

The Contour Detection Layer

Before any AI touches a frame, OpenCV does the heavy lifting:

  1. Capture frame, convert to grayscale, resize to 640px width
  2. Compute absolute difference against previous analyzed frame
  3. Apply binary threshold (25) and dilation (3 iterations) to merge nearby changes
  4. Find contours, filter by area (min 150px², max 40% of frame)
  5. Merge nearby bounding boxes (within 50px)

If no contours survive filtering: CLEAR — zero VLM calls. This happens 70%+ of the time (still frames, minor lighting shifts).

If contours are found: crop the largest region, send to VLM for classification.

Every 60 seconds, a fallback full-frame check catches anything that appeared between frames but hasn’t moved (a parked car that wasn’t there before, a person standing still).

Exclusion Zones

Not all motion is interesting. I built a polygon zone editor (web UI at /zones) that lets me draw exclusion and inclusion zones on camera frames — similar to professional NVR software.

Current exclusion zones:

  • Gate camera: the road beyond the gate (top portion of frame) — cars passing on the street aren’t security events
  • Driveway: a steam pipe and stone wall fixture that cause constant false triggers
  • Backyard: a kamado BBQ grill and tree branches that sway in wind

The zones are stored as JSON polygons. At runtime, cv2.fillPoly builds a binary mask, which is applied to the thresholded diff before contour detection. Masked pixels are zeroed — contours in excluded areas never form.

False Positive War Stories

Vision LLMs hallucinate. In security camera analysis, this means phantom alerts. Here are the patterns I found and fixed:

The negation problem. The VLM would say “No people, vehicles, or animals are visible in the frame” and my classifier would see “people, vehicles, animals” and trigger an alert. Fix: expanded the negation lookback from 25 to 60 characters and added sentence-level negation detection (“if sentence starts with no/not/without AND ends with visible/present/found → CLEAR”).

The hedge problem. The VLM would output both “ALERT” and “CLEAR” in the same response when it was uncertain. Fix: if both keywords appear on the same line, CLEAR wins. It’s better to miss an event than to false-alert at 3 AM.

The location confusion. “A vehicle on the road beyond the gate” was triggering alerts for the gate camera. But the road isn’t my property. Fix: added location-based negation — “beyond the gate”, “past the gate”, “on the road”, “on the street” → CLEAR.

The shadow/reflection problem. “A shadow of a person” would alert. Fix: added “shadow of” as a negation pattern.

The phantom description. This was the most insidious. When the VLM received a nearly-black night frame, it would occasionally hallucinate vivid descriptions of people or vehicles. Fix: contour detection at night produces zero contours (no pixel changes in darkness), so the VLM is never called — the contour pre-filter eliminates this class of error entirely.

Audio Intelligence

The gate camera has a microphone. faster-whisper (medium.en model) transcribes 15-second audio chunks, but audio alerts are gated by visual confirmation — a speech transcription only fires if there was a visually-confirmed alert within the last 120 seconds. This prevents phantom audio alerts from wind, distant traffic, or radio.

Urgent keywords (help, emergency, fire) bypass the gate.

The transcription pipeline: PCM audio from RTSP → WAV → faster-whisper → filter noise phrases (“thank you for watching”, street chatter) → if visually gated → WiiM speaker announcement + WhatsApp message with OGG audio clip.

The Alert Review Tool

50,000 VLM calls per day generates a lot of classification data. I built a daily review tool (/alerts/review) that:

  1. Parses the last 24 hours of CONFIRMED ALERT lines from the log
  2. Groups by camera + normalized description
  3. Sends all patterns to qwen3.5:35b for meta-classification: REAL / FALSE_POSITIVE / NOISE
  4. Presents a web UI with tabs (Needs Review / AI Flagged / Suppressed / Acknowledged)
  5. One-click suppress permanently filters a pattern from future alerts

The LLM classification is given context: Calgary snowy conditions, known permanent features (kamado BBQ, stone wall, gate post lights), typical neighborhood activity. It correctly flags 80%+ of false positives for one-click suppression.

Performance

Metric Value
Cameras 3 (4K, RTSP)
Frame interval 5 seconds per camera
VLM calls/day ~50,000
VLM model qwen2.5vl:7b-4k (14.5 GB on DGX Spark)
Inference latency ~200ms per crop (10GbE link)
False positive rate <5% after zone exclusions + negation fixes
Total system cost $0/month (all local hardware)

What I’d Do Differently

  • Start with contour detection, not VLM. I initially sent every frame to the VLM. The 70.8 GB memory leak I found in Ollama (separate blog post) was partly caused by this constant load. Contour pre-filtering reduced VLM calls by 70%+ and made the whole system viable.

  • Use a smaller VLM for classification, larger for description. A 3B model could handle binary ALERT/CLEAR classification. Reserve the 7B model for generating the detailed description that goes into the WhatsApp alert.

  • Night mode needs a different approach. IR cameras produce grayscale footage that confuses vision LLMs trained on color images. Thermal cameras or dedicated night-vision models would work better.

The Stack

All of this runs on:

  • Mac Studio M2 Ultra (128 GB) — camera capture, OpenCV, audio processing, web UI
  • NVIDIA DGX Spark (120 GB) — VLM inference via Ollama
  • 10GbE direct link between the two machines
  • Raspberry Pi — WhatsApp gateway
  • WiiM speaker — voice announcements
  • Python 3.9, stdlib only — no pip dependencies in any production script

Zero cloud APIs. Zero subscriptions. Full privacy.

The full pipeline code and zone editor are on my GitHub. If you’re running local vision models for home automation, I’d like to hear what models and pre-filters work for you.

Why Sprints Are Broken

Let me say something that a lot of engineering teams are thinking but not saying out loud: sprints are not working anymore.

Not for everyone, and not in every context. There are still teams running two-week cycles who are genuinely productive and who find the structure useful. But for a growing number of engineering organisations – particularly those working with modern tooling, AI-assisted development, and complex product problems – the sprint model has become more of a performance than a practice. The rituals continue. The points get estimated. The velocity gets tracked. And underneath all of it, the actual work is happening on a completely different rhythm that the sprint structure is not capturing and is actively getting in the way of.

This article is not about bashing agile as a philosophy. The core ideas behind agile – iterative development, responding to change, close collaboration, shipping working software – are sound and remain relevant. This is about the specific implementation of those ideas that most teams landed on in the 2000s and have been running ever since, and why that implementation is increasingly misaligned with the way software actually gets built today.

Understanding why requires going back to where the sprint model came from and what problem it was designed to solve.

Scrum and the two-week sprint emerged in a specific context. Teams were building software in long waterfall cycles, requirements were being locked down months in advance, and by the time software shipped it was often solving a problem that had evolved or disappeared entirely. The sprint was a corrective mechanism. By forcing teams to ship something demonstrable every two weeks, it created a feedback loop that waterfall lacked. You could not hide in a six-month planning phase. You had to show your work regularly and respond to what you learned.

That was genuinely valuable. In that context, the sprint was the right tool.

The context has changed substantially. The feedback loops that sprints were designed to create now exist through other means. You can deploy multiple times a day. You can run experiments with feature flags. You can get user feedback through analytics, session recording, and direct research on a continuous basis. The forcing function that made two-week cycles useful – the need to create artificial checkpoints in a process that otherwise had none – is less necessary when the process itself has become more continuous.

At the same time, the nature of the work has changed. The problems engineering teams are solving are more complex, more interconnected, and more ambiguous than the typical CRUD application work that sprint methodology was largely optimised for. A two-week sprint works reasonably well when the work is decomposable into discrete, estimable tasks. It works much less well when you are doing exploratory technical work, building systems with significant unknown unknowns, or working on problems where the right solution only becomes visible partway through the attempt.

And then there is the AI dimension, which is changing the shape of engineering work faster than any methodology has adapted to.

LLMs have not made engineering easier in a simple, linear sense. What they have done is collapse the time required for certain categories of work – boilerplate implementation, test generation, documentation, straightforward feature development – while leaving other categories largely unchanged or in some cases more complex. The cognitive work of understanding a problem deeply, designing the right system, making good architectural tradeoffs, reviewing generated output critically – that work has not gotten faster. In some ways it has gotten harder, because the volume of code being produced has increased while the time available to reason carefully about it has not.

The result is a strange asymmetry. A task that might have taken three days of implementation work two years ago might now take three hours of implementation work but still requires the same two days of thinking, scoping, and review. The sprint model, which was built around implementation time as the primary unit of work, does not have a good way to account for this. Story points were always a flawed proxy for effort, but they were at least correlated with something real. That correlation is breaking down as implementation time becomes less representative of total work involved.

There is also a rhythm problem. Two-week sprints create a specific cadence that assumes work fits neatly into two-week containers. Some work does. A lot of important work does not. A significant architectural investigation might need six weeks of focused effort from a small group. A genuinely novel feature might need a cycle of building, learning, and rebuilding that does not map onto fixed sprint boundaries. When teams try to force that kind of work into two-week containers, one of two things happens: either the work gets artificially scoped down to fit the container, which means the team is never doing the full problem, or the work spills across sprint boundaries in ways that make the sprint structure meaningless as a planning tool.

The ceremony overhead compounds this. A typical sprint includes planning, a daily standup, a mid-sprint check-in, a review, and a retrospective. For a team of eight engineers, that is easily four to six hours of synchronous meeting time per sprint, and that is before you count the async overhead of updating tickets, writing sprint reports, and maintaining the backlog. For some teams the ratio of ceremony to actual engineering work is genuinely alarming.

I am not arguing that coordination and reflection have no value – they obviously do. I am arguing that the specific forms those things take in sprint methodology were designed for a world without the communication tools, deployment infrastructure, and development tooling that most teams now have. The overhead is not proportionate to the value it creates in the modern context.

The estimation problem deserves its own moment because it is the place where the dysfunction is most visible and most demoralising. Story point estimation exists to give teams and stakeholders a sense of how much work fits into a sprint and to track velocity over time. In practice, it produces numbers that are unreliable enough to be misleading while being precise enough to feel meaningful.

Engineers know this. They know that their estimates are often wrong, that the factors that make estimates wrong are largely outside their control, and that the velocity metrics derived from those estimates are being used by stakeholders to make decisions that the underlying data does not actually support. The result is a quiet cynicism about planning that spreads through engineering teams and makes genuine engagement with the process harder to sustain.

The deeper problem with estimation is not that engineers are bad at it. It is that software estimation is genuinely hard in a way that no methodology fully resolves. The work that is easiest to estimate accurately is the work that is most similar to work you have done before. The work that matters most – the novel problems, the architectural decisions, the exploratory investigations – is hardest to estimate because it is by definition unlike what you have done before. Forcing that work through an estimation process optimised for familiar, decomposable tasks produces confident-looking numbers that do not mean very much.

What does a better model look like? That is what the rest of this series is about. But the short version is this: instead of asking “how long will this take,” ask “how much appetite do we have for this problem.” Instead of filling a backlog with everything that might conceivably get done someday, make explicit bets on the things that matter most in the next cycle. Instead of running a continuous treadmill of two-week sprints with no structural breathing room, build in time for the team to actually think, clean up, and reset.

Those ideas come from Shape Up, the methodology developed at Basecamp and written up by Ryan Singer. It is not a perfect system and it is not right for every team. But it starts from a more honest set of assumptions about how complex software work actually happens, and it has a more realistic model of the relationship between time, scope, and quality than sprint methodology does.

Before we get into the specifics of how Shape Up works and how to introduce it, it is worth sitting with the diagnosis a little longer. Because the failure mode I see most often is teams that recognise something is broken, adopt a new methodology as a fix, and then find that the new methodology is not working either – because they changed the process without changing the underlying assumptions about what software development is and how it should be managed.

The assumption worth examining most carefully is the idea that engineering work is fundamentally a production process – that the job is to take a backlog of defined requirements and process them as efficiently as possible into shipped software. That model has its uses and its contexts. But it is a poor fit for the kind of work that matters most in most engineering organisations: the work of figuring out the right thing to build, the work of solving problems that do not have obvious solutions, the work of building systems that need to evolve over time rather than just be completed.

Sprints were a significant improvement on what came before them. The question is not whether they were a good idea in their time – they were. The question is whether they are still the right tool for the work most teams are doing now. For a growing number of teams, the honest answer is no.

Recognising that is the first step. Building a better model is the work.

Next in the series: Shape Up – a practical introduction to the planning methodology that starts from more honest assumptions about how complex software work actually gets done.

Distributed LLM Inference Across NVIDIA Blackwell and Apple Silicon Over 10GbE

I connected an NVIDIA DGX Spark to a Mac Studio with a direct 10-gigabit Ethernet cable and split a large language model across both GPUs. Here’s what actually happened.

The Problem

I have two machines that are excellent at different things:

  • NVIDIA DGX Spark (GB10 Blackwell, 120 GB unified memory) — screaming fast tensor cores, CUDA 13
  • Mac Studio (M2 Ultra, 128 GB unified memory) — great Metal GPU, massive memory bandwidth

Combined: 248 GB of GPU-accessible memory. Enough to run models that don’t fit on either machine alone — 100B+ parameter models at reasonable quantization levels.

The question: can you actually get useful performance by splitting a model across heterogeneous GPUs over a network link?

The Physical Setup

I connected both machines with a direct 10GbE cable — no switch, no router. Just a CAT6A cable between:

  • DGX: Realtek 10GbE NIC (enP7s7) → 192.168.100.2/24
  • Mac Studio: 10GbE port (en0) → 192.168.100.1/24

Measured throughput: 9.41 Gbps. Both machines keep WiFi for LAN/internet access — the direct cable is a dedicated inference-only link.

Why llama.cpp RPC (and Why Not Exo)

I tried two approaches:

Exo (MLX Ring) — Failed

Exo is a distributed inference framework that uses MLX on both Metal and CUDA backends. I got peer discovery working, placed a 128 GB MiniMax M2.5 model across both nodes, but hit a wall: mx.distributed.init(backend="ring") hangs indefinitely on the CUDA backend. The MLX CUDA ring implementation simply doesn’t work yet (as of MLX 0.31.1). Even single-node ring init hangs on DGX.

I fixed several other bugs along the way (election instability, edge oscillation, model path mismatches, Linux interface detection) and submitted a P2P model distribution PR, but the core distributed inference path is blocked until Apple adds CUDA ring support to MLX.

llama.cpp RPC — Works

llama.cpp’s RPC backend takes a different approach. Instead of requiring the same ML framework on both ends, it exposes a simple RPC server that provides raw compute. The host machine (Mac Studio) runs llama-server, loads the model, and offloads layers to remote RPC servers (DGX) as needed.

# DGX — start RPC server
cd /home/kjaiswal/llama.cpp
LD_LIBRARY_PATH=build/bin build/bin/rpc-server -H 192.168.100.2 -p 50052

# Mac Studio — start llama-server with RPC
cd /Users/chimpoo/llama.cpp
build/bin/llama-server 
  -m /path/to/model.gguf 
  --rpc 192.168.100.2:50052 
  -ngl 99 
  --host 0.0.0.0 --port 9999 
  -c 4096

Both were built from the same commit (b0f0dd3e5) with their respective GPU backends:

  • Mac Studio: GGML_METAL=ON GGML_RPC=ON
  • DGX: GGML_CUDA=ON GGML_RPC=ON

The model file only needs to exist on the Mac Studio. llama.cpp automatically splits layers across available compute based on memory.

Benchmarks

Qwen2.5-7B Q4_K_M (4.4 GB) — Fits one machine easily

Mode Prompt Processing Token Generation
Local Metal only 76 tok/s 92 tok/s
RPC (Metal + CUDA) 318 tok/s 53 tok/s

Qwen2.5-72B Q4_K_M (44.2 GB) — Fits Mac Studio alone

Mode Prompt Processing Token Generation Model Split
Local Metal only 28 tok/s 11 tok/s 44 GB on Metal
RPC (Metal + CUDA) 30 tok/s 6 tok/s 31 GB Metal + 14 GB CUDA

What the Numbers Mean

Prompt processing (prefill) benefits from RPC. The DGX Blackwell tensor cores accelerate the matrix multiplications needed to process input tokens. For the 7B model, prefill was 4.2x faster with RPC. Even the 72B model saw a slight improvement.

Token generation (decode) is slower with RPC. Each generated token requires a round-trip over the network to synchronize KV cache states. At 10 Gbps, this adds ~0.2ms per layer per token. With 80 layers, that’s 16ms of network overhead per token — enough to cut generation speed roughly in half.

For models that fit one machine, local is faster. The 72B model runs at 11 tok/s locally vs 6 tok/s over RPC. The network overhead isn’t worth it.

The real value is models that DON’T fit one machine. With 248 GB combined, I can run:

  • MiniMax M2.5 Q4_K_M (138 GB) — 230B parameters, 10B active MoE
  • Qwen3-235B Q4_K_M (132 GB) — 235B parameters, 22B active MoE
  • DeepSeek-R1 at higher quantization than either machine could handle alone

At Q4 quantization, a 200B+ MoE model should generate at ~4–8 tok/s across both machines. Not fast, but usable for batch processing, code review, and complex reasoning tasks.

Lessons Learned

  1. Direct cables beat switches. A direct 10GbE link has lower latency and jitter than going through a network switch. For latency-sensitive distributed inference, every microsecond matters.

  2. Prefill and decode have opposite scaling characteristics. Prefill is embarrassingly parallel and benefits from more compute. Decode is sequential and bottlenecked by network latency. This suggests a potential disaggregated architecture: use the DGX for prefill, Mac Studio for decode.

  3. GGUF is the universal format. Ollama GGUFs have custom metadata that upstream llama.cpp can’t read (e.g., rope.dimension_sections with wrong array length). Always use HuggingFace community GGUFs (bartowski, etc.) for llama.cpp.

  4. Heterogeneous distributed inference works today — but only with frameworks that abstract the GPU backend behind a network protocol (like llama.cpp RPC). Frameworks that require the same ML runtime on all nodes (like Exo with MLX) are blocked on backend parity.

What’s Next

  • Benchmark MiniMax M2.5 (138 GB) split across both machines — the first model that actually needs distributed inference
  • Test disaggregated prefill (DGX) + decode (Mac Studio) once both run the same framework
  • Explore vLLM’s distributed serving for production workloads

The full setup — including the Exo debugging saga and the 5 bugs I fixed — is documented in my infrastructure notes. Happy to share details if you’re working on similar multi-GPU setups.

If you’re working on similar multi-GPU setups, I’d love to hear what’s working for you. The full setup notes and Exo bug fixes are on my GitHub.

Jaguar Land Rover ve Chery’den yeni marka: “Freelander”

Freelander

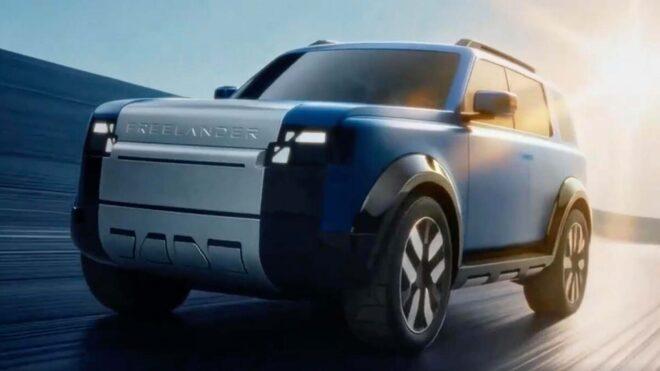
FreelanderJaguar Land Rover (JLR) ve Çinli otomobil devi Chery, “Freelander” markasını ve markanın çıkış aracını görücüye çıkardı. İlk aşamada Çin’de, daha sonra ise Avrupa’daki belirli pazarlarda satılacak araç, tamamen elektrikli ve hibrit tahrik sistemlerini temel alan yeni 800 voltluk mimari üzerine kuruluyor. Dikkat çekici bir tasarıma sahip olan 4×4 arazi aracı, yapılan açıklamaya göre JLR-Chery’nin Çin’deki Changshu fabrikasında Land Rover Discovery Sport ve Range Rover Evoque’un yerini alacak. Bugün itibarıyla son içten yanmalı Evoque’un üretimini tamamlayan fabrikada artık bu yeni model üretilecek. Tüm detayları önümüzdeki hafta paylaşılacak model, paylaşılan ilk görsellere bakılırsa “B” sütunu olmadan geliyor ve arka kapısı terse açılıyor. Freelander CEO’su Wei Lan, markanın önümüzdeki beş yıl boyunca pazara her altı ayda bir yeni otomobili sürmeyi planladığını aktarıyor.

Jaguar Land Rover ve Chery’den yeni marka: “Freelander” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

The WooCommerce UCP Guide: What Our Monitoring Data Reveals About WordPress Agent Commerce

WooCommerce UCP Architecture — how AI agents connect through the WordPress plugin layer

WooCommerce UCP adoption is in its very early stages. Our current monitoring dataset includes just 3 verified WooCommerce stores — a small fraction of the broader UCP ecosystem, where Shopify accounts for over 99% of verified merchants. Even with a limited dataset, the patterns we see are consistent with what you’d expect from WordPress-based infrastructure: more configuration complexity, more hosting variability, and more ways for things to silently break.

WooCommerce powers somewhere between 25% and 30% of all e-commerce stores globally, and WordPress’s plugin ecosystem means a UCP implementation can ship as a drop-in extension without Automattic needing to build it into core. That’s exactly the path adoption has started to take — but it’s early, and the infrastructure complexity means getting it right requires more deliberate effort than on managed platforms.

The picture is more complicated than Shopify. WooCommerce gives merchants complete control over their UCP implementation, which means more configuration flexibility — and far more ways to misconfigure it. This guide covers what we’ve learned monitoring WordPress-based stores: what you need to install and configure, what the manifests actually look like across our dataset, and what breaks in production agent sessions.

WooCommerce UCP Architecture — how AI agents connect through the WordPress plugin layer

What WooCommerce Requires (vs. What Shopify Provides Natively)

The first thing to understand about WooCommerce UCP is that nothing is automatic. Where Shopify generates and serves a UCP manifest the moment you install the Universal Commerce Agent app, WooCommerce requires a dedicated WordPress plugin that you install, configure, and maintain separately from your store.

The plugin handles three things: serving the /.well-known/ucp manifest file, registering a REST API endpoint that acts as your MCP transport, and exposing your WooCommerce product catalog, cart, and checkout flows as MCP tools.

The most established option we’ve validated in our testing is UCPReady by Zologic, which handles manifest generation, MCP transport, and automatic capability detection.

The installation process is straightforward — activate the plugin, generate your manifest keys, configure your capabilities. What catches merchants is everything after that: cache invalidation, security plugin whitelisting, PHP memory allocation, and making sure your REST API is actually accessible to external agents. Each of these is a WordPress infrastructure concern, not a WooCommerce one, which means the troubleshooting surface is larger than on managed platforms.

There is also no equivalent to Shopify’s automatic manifest updates when your payment stack changes. On WooCommerce, if you add a new payment gateway — WooCommerce supports over 100 via extensions — your manifest doesn’t automatically reflect the change. You need to resync it manually or configure the plugin to auto-regenerate on gateway change. We flag stale payment handler declarations in our monitoring data, and WooCommerce stores — given the manual update requirement — are more prone to this issue than Shopify stores.

The Manifest: What We See Across Our WooCommerce Dataset

Your UCP manifest is the JSON document at /.well-known/ucp that tells AI agents what your store supports and how to connect to it. On WooCommerce, this file is generated by the plugin and cached — how it is cached, and when that cache is invalidated, is one of the most consequential decisions in your setup.

The first thing we check is whether the manifest is reachable at all. A common issue on WooCommerce stores is the manifest returning a 404 or a cached HTML error page instead of valid JSON. This almost always traces to a caching plugin that has cached the /.well-known/ path as a static HTML page, or a security plugin that blocks direct file access to that path. Both are fixable but require explicit configuration.

The second is the protocol version. WooCommerce UCP deployments show more version fragmentation than Shopify, because plugin updates are not as seamless as platform updates. We see a meaningful share of WooCommerce stores still on 2026-01-11, and a small number on pre-release configurations that declare non-standard version strings. Agents with strict version negotiation will refuse to interact with these stores entirely.

Third is the capabilities array. A properly configured WooCommerce store should declare dev.ucp.shopping.checkout, dev.ucp.shopping.discovery, and — if configured — dev.ucp.shopping.discount. The discount capability is the most variable: WooCommerce handles discounts through a combination of coupon codes, cart rules, and extension-specific logic that doesn’t always map cleanly to the UCP discount model. Many stores declare it in the manifest but the actual MCP tool implementation is incomplete.

Fourth is the transports block. WooCommerce stores declare MCP over the WordPress REST API, typically at a path like /wp-json/ucp/v1/mcp. This is correct, but the REST API endpoint must be explicitly whitelisted in your security configuration. We see a significant share of WooCommerce stores where the manifest correctly declares the MCP transport but the endpoint itself returns a 401 or 403 for unauthenticated requests — which is what most agent clients send for initial tool discovery.

Common Manifest Issues We Flag

The most frequently flagged issues across our WooCommerce monitoring dataset: cached manifest serving stale content (the manifest was generated before a configuration change and the cache has not been busted), payment handlers out of sync (a gateway was added or removed without a manifest resync), REST API endpoint blocked (a security plugin or WAF rule is returning a non-JSON response to agent requests), and capabilities declared but not implemented (the discount tool is listed in the manifest but the endpoint returns an error when an agent calls it).

None of these cause a hard failure on a basic manifest fetch. A checker that only validates whether the JSON is well-formed will pass these stores. Our checks simulate what an agent actually does — fetch the manifest, enumerate the tools, call the endpoint — which is why we catch issues that a simple validation pass misses.

Runtime Performance: Hosting Matters Enormously

This is the biggest difference between WooCommerce and Shopify from a performance standpoint: on Shopify, your store runs on Shopify’s global infrastructure. On WooCommerce, your store runs on whatever you chose to host it on — and the performance range is enormous.

WooCommerce MCP response times by hosting type — shared hosting vs VPS vs managed WordPress

Across the WooCommerce stores in our dataset, MCP tool call response times ranged from 510ms to 1,593ms, with an average around 980ms — significantly slower than Shopify’s median of 146ms. Our sample is small, but this is consistent with what you’d expect from PHP-based self-hosted infrastructure. The spread in practice is likely much wider: well-configured managed WordPress hosts (WP Engine, Kinsta, Flywheel) can achieve sub-500ms response times, while stores on shared hosting with cold PHP processes can see latency well above 3 seconds.

Most agent frameworks have configurable timeouts, typically defaulting between 5 and 10 seconds. A store that responds in 4 seconds most of the time will occasionally spike to 8+ seconds when the PHP process is cold or the server is under load — and those spikes cause agent session failures that look like UCP implementation errors rather than hosting issues. The manifest validates fine, but the store cannot complete a real session reliably.

Specific hosting-related issues we flag frequently: PHP-FPM cold start latency on servers where PHP processes idle between requests (common on lower-tier shared hosting); object cache not configured (WooCommerce makes a large number of database queries per request — without Redis or Memcached, product catalog responses will be slow); and opcode cache absent (WooCommerce’s PHP footprint is substantial — OPcache is essential for acceptable performance and is missing on a surprising share of self-managed servers we monitor).

If you are on shared hosting and considering WooCommerce UCP, the performance characteristics alone are likely to produce poor agent experiences. Managed WordPress hosting starts at around $25–35/month and typically delivers 5–10× better MCP response times than budget shared hosting.

Configuration Checklist

Based on our monitoring data, here are the five configuration steps that separate WooCommerce stores that perform well in agent sessions from those that pass a manifest check but fail in production.

First, install and fully configure the WooCommerce UCP plugin. Do not stop at activation — complete the key generation step, review the capabilities configuration, and use the plugin’s built-in test to verify the manifest and MCP endpoint are both returning valid responses. Partial configurations are the most common source of manifest issues we see in WooCommerce stores.

Second, whitelist the UCP manifest and MCP endpoint in your caching and security plugins. Add /.well-known/ucp to your caching plugin’s exclusion list — agents need the current version on every request, not a cached copy. Add your MCP REST API path to your security plugin’s whitelist so it returns JSON, not a block page. This step is specific to WordPress and has no equivalent in managed platform setups.

Third, verify your store at ucpchecker.com/check. Run the check, but specifically look at whether the MCP endpoint is reachable and returning valid responses — not just whether the manifest JSON is well-formed. We check both, and MCP endpoint reachability failure is far more common on WooCommerce than on any other platform we monitor.

Fourth, configure a persistent object cache. WooCommerce’s database query load under agent traffic is significant — agents make tool calls in rapid succession, and without Redis or Memcached, each call triggers a full set of database queries. Most managed WordPress hosts include Redis as a one-click option; on self-managed servers, the Redis Object Cache plugin plus a running Redis server is the standard configuration.

Fifth, set up UCP Alerts. Plugin updates, security plugin config changes, and WordPress core updates can all affect your UCP configuration without any explicit notification. We have seen stores where a security plugin update changed the response format on the MCP endpoint and the merchant did not know for days. Alerts catch these changes the next time we check your store.

Plugin Compatibility: The WordPress Ecosystem Challenge

WooCommerce’s power comes from its plugin ecosystem — there are over 900 extensions on the WooCommerce Marketplace alone, plus thousands more on WordPress.org and third-party marketplaces. That ecosystem is also the primary source of UCP compatibility issues we see.

The highest-risk category is security and firewall plugins. Wordfence, iThemes Security, Sucuri, and similar plugins use aggressive bot-blocking rules that frequently misclassify AI agent requests. UCP agents typically identify themselves with specific user-agent strings; if your security plugin is configured to block non-browser user agents, it will block agent traffic before it ever reaches your UCP implementation. We see this as a 403 response on the MCP endpoint — the manifest is reachable, but actual agent sessions are blocked.

The second category is caching plugins. WP Super Cache, W3 Total Cache, WP Rocket, and LiteSpeed Cache all have different approaches to caching REST API responses. By default, some of them cache the MCP endpoint — which means agents receive a cached response from a previous session, including potentially stale cart or product data. Your MCP endpoint must return fresh responses on every request, which means explicitly excluding it from caching at both the plugin and server levels.

Third is checkout customization plugins. WooCommerce Checkout Field Editor, WooCommerce One Page Checkout, and similar plugins modify the checkout flow in ways the MCP checkout tool does not know about. A mandatory custom field that requires input before checkout can proceed will silently fail agent checkout attempts — the agent calls the checkout tool, server-side validation rejects it because the custom field is empty, and the response is an error the agent typically cannot resolve.

Fourth, for merchants using multi-currency or multi-language plugins (WPML, WooCommerce Multilingual, Currency Switcher), these add complexity with no equivalent on Shopify Markets. There is no standard way for a WooCommerce store to declare multi-currency support in its UCP manifest, which means agents accessing your store from different geographic contexts may get different pricing without the manifest indicating that variation exists.

Common Failure Modes

Common WooCommerce UCP failure modes — cache conflicts, security blocks, PHP limits, REST API disabled

Five failure patterns come up repeatedly across our WooCommerce monitoring data.

Caching plugin serving stale MCP responses. An agent requests the tools list and receives a cached response from a previous session — one that might include products now out of stock, prices that have been updated, or a cart session belonging to a different user. This is the most WooCommerce-specific failure mode we see and it is entirely a configuration issue, not a UCP implementation problem. The fix is always the same: explicitly exclude your MCP endpoint path from caching at every level (plugin, server, CDN).

Security plugin blocking agent user agents. The agent makes a request to the MCP endpoint and receives a 403 or a redirect to a CAPTCHA page. From the manifest perspective, everything looks fine. From the agent’s perspective, the store is inaccessible. We detect this during our endpoint reachability checks. The fix requires explicitly whitelisting UCP agent user-agent strings in your security plugin’s bot management configuration.

PHP memory exhaustion on large catalogs. WooCommerce stores with large catalogs (10,000+ SKUs) frequently hit PHP memory limits when the MCP discovery tool attempts to enumerate products. The default PHP memory limit on many hosts is 256MB — inadequate for large WooCommerce queries under agent access patterns. We see this as timeouts or 500 errors on the discovery tool while other tools work fine. Setting WP_MEMORY_LIMIT to 512M or higher and ensuring your PHP-FPM pool has sufficient memory allocation resolves it in most cases.

Payment gateway plugin conflicts at checkout. WooCommerce’s checkout flow is highly extensible — and that extensibility means payment plugins can add hooks that interfere with the MCP checkout tool’s assumptions about what happens at payment initiation. We have seen stores where a payment gateway plugin redirects to an external payment page the agent cannot follow, causing the session to terminate after cart completion but before payment. Test your specific gateway configuration explicitly with agent sessions before going live.

Variable product variant ID instability. On WooCommerce, variation IDs can change when products are edited, reimported, or synced from an external system like an ERP or inventory platform. Agents that cache a variation ID for a specific product configuration may find that ID invalid the next time they try to add it to a cart, because the variation was recreated with a new ID. For stores that use bulk product management or external sync tools, this is a persistent issue. SKU-based addressing where possible, and avoiding unnecessary variation recreation, significantly improve agent session reliability.

Product Feed Best Practices for WooCommerce

WooCommerce product data quality is more variable than Shopify’s because it is entirely merchant-managed. There is no platform-level enforcement of required fields, no structured data template, and no automatic format normalization. What agents see when they call the discovery tool depends entirely on how well your product catalog is maintained.

Variable products need complete, consistent attribute sets. WooCommerce’s variable product model lets you define any attributes you want as variation axes. But it does not enforce completeness. If some variations are missing attribute values — a color variation without a size, or a size variation with no price set — agents may discover the product but fail to add a specific variant to cart. Audit your variable products for incomplete variations before enabling UCP.

Custom fields require explicit plugin support. Many WooCommerce stores use Advanced Custom Fields (ACF), Meta Box, or WooCommerce’s own custom product tabs to store additional product data. By default, none of this data is exposed through the MCP discovery tool — the UCP plugin has to explicitly include it in the MCP product response. If your products have custom fields essential for purchasing decisions (technical specifications, compatibility matrices, bulk pricing tiers), verify your UCP plugin is configured to include them in discovery responses.

Set explicit currency on all prices. WooCommerce’s default product data model stores prices as raw numbers without currency. The currency is typically declared at the store level, but stores using multi-currency plugins may serve prices in different currencies for different contexts. Ensure your UCP plugin serializes prices with explicit currency codes — not just numeric values — in every product response. Agents guessing currency from context produce wrong price displays.

Stock status must be accurate and real-time. WooCommerce stock management is excellent when configured correctly, but many stores have products set to “In Stock” without managing actual inventory quantities. When an agent discovers a product, adds it to cart, and then hits an out-of-stock error at checkout, the session fails. Enable proper stock quantity management and ensure your stock sync — especially if you use a third-party inventory system — is near-real-time.

SKUs should be present, stable, and unique. WooCommerce SKUs are optional. Many stores, especially smaller ones, do not set them. But SKUs are the most reliable way for agents to reference specific products and variations across sessions — they are more stable than variation IDs and more portable than internal WooCommerce post IDs. Setting SKUs on all products and variations, and keeping them stable across product updates, is one of the highest-leverage improvements for agent session reliability.

Product descriptions should be agent-parseable. WooCommerce product descriptions are free-form HTML — great for human-readable storefront pages, but problematic for agents. The short description field (the excerpt) is typically what MCP discovery tools expose as the primary product description. Keep it clean, text-based, and specific to what an agent needs to understand about the product. Avoid shortcodes, embedded tables, or JavaScript-dependent content in the short description.

Structured data for web-crawling agents. Some agents discover products through web crawling before connecting via MCP. WooCommerce stores using Yoast WooCommerce SEO or Rank Math get reasonable schema.org/Product markup automatically. Verify your storefront product pages include at minimum: name, description, price with currency, availability, brand, SKU, and image. This creates a secondary discovery path for agents that do not connect via MCP directly.

What’s Coming

Two developments in the WooCommerce UCP ecosystem are worth watching in 2026.

The first is first-party plugin support from Automattic. The current WooCommerce UCP implementation is third-party. As WooCommerce’s UCP install base grows, there is meaningful pressure on Automattic to build UCP support directly into WooCommerce core or develop an official first-party plugin with automatic manifest updates on gateway and catalog changes. A first-party implementation would dramatically reduce the configuration burden and plugin compatibility surface we currently see across our monitoring dataset.

The second is better persistent identity support for logged-in WooCommerce customers. The current MCP authentication model does not leverage WordPress’s native user session infrastructure well — most agent sessions are unauthenticated, which means agents cannot access customer-specific pricing, loyalty balances, or saved addresses. As the UCP spec’s identity linking capability matures, WooCommerce stores with rich customer profiles stand to gain significantly from authenticated agent sessions that can personalize the shopping experience.

We track WooCommerce adoption trends through our stats dashboard and break down platform-by-platform analysis in the State of Agentic Commerce reports.

Check Your Store

If you are running a WooCommerce store and have not run a UCP check yet, start here. The check takes about 30 seconds and covers both manifest validity and MCP endpoint reachability — the two most common failure points on WordPress-based stores.

If you are already listed in our directory, set up UCP Alerts so you are notified when your configuration changes. A WordPress plugin update, security plugin tweak, or caching config change can silently break your UCP implementation. Alerts catch it before an agent session fails.

And if you want to see exactly how AI agents experience your WooCommerce store — variant resolution, cart building, checkout completion — UCP Playground runs real agent sessions against live stores. It is the fastest way to find the configuration issues that do not show up in manifest validation but break real transactions.

References & Official Resources

Further Reading

Related Platform Guides

Exploring UCP across other platforms? These guides cover what we’ve learned about each platform’s implementation:

How I Made Claude Code and GPT-5.4 Review Each Other’s Code

The Problem: Same Model Writes and Reviews

When Claude Code writes code and Claude reviews it, you get the AI equivalent of grading your own homework. Blind spots survive.

I wanted GPT-5.4 to review Claude’s code from a genuinely different perspective. So I built helix-codex — an MCP server that bridges Claude Code (Opus 4.6) to Codex CLI (GPT-5.4).

What Makes It Different

There are 6+ Codex MCP bridges on GitHub. They all do the same thing: call codex exec, return raw text. Claude has no idea what happened inside.

helix-codex parses the entire JSONL event stream and returns a structured report:

[Codex gpt-5.4] Completed

⏱ Execution time: 8.3s
🧵 Thread: 019d436e-4c39-...

📦 Tools used (3):
  ✅ read_file — src/auth.py
  ✅ edit_file — src/auth.py
  ✅ shell — python -m pytest tests/

📁 Files touched (1):
  • src/auth.py

━━━ Codex Response ━━━
Fixed the authentication logic.

The Self-Review Experiment

The most interesting test: I had GPT-5.4 review helix-codex’s own source code. It found 3 critical issues:

  1. Return code logic bug — returncode != 0 with partial output was treated as success
  2. Terminal injection vulnerability — No ANSI/OSC escape sanitization in output
  3. Path double-application — cwd passed to both -C flag and subprocess cwd=

Claude (the model that wrote the code) had missed all three. Different model, different blind spots.

Real Performance Numbers

Tool Time What It Does
explain 5.4s Full code explanation
review 15.7s CRITICAL/WARNING/INFO classified review
execute 2.8s Task delegation with structured trace
parallel_execute — Up to 6 simultaneous tasks

Cross-Model Comparison

I ran Claude Agent and Codex in parallel on the same question: “Best thread-safe singleton pattern in Python?”

  • Claude: Metaclass + Lock, module variable, __new__
  • Codex: Module variable, lru_cache, Lock + classmethod

The lru_cache approach was unique to Codex — Claude hadn’t considered it. Two models genuinely produce different solutions.

Key Features

  • Full JSONL trace parsing — tools, files, timing, errors
  • Parallel execution — up to 6 tasks via asyncio.gather
  • Session management — threadId persistence
  • Adversarial Review Loop — GPT-5.4 challenges Claude’s code
  • Sandbox security — 3-tier policy + terminal injection prevention
  • 56 tests — comprehensive coverage
  • Single file — ~820 lines, zero external deps beyond FastMCP

Get Started (3 Minutes)

npm install -g @openai/codex && codex login
git clone https://github.com/tsunamayo7/helix-codex.git
cd helix-codex && uv sync

Add to ~/.claude/settings.json and you’re done.

What I Learned

  1. Different models have different blind spots. Cross-model review catches things self-review misses.
  2. Structured traces change everything. Raw text is useless for programmatic decisions.
  3. Parallel execution is underrated. Analyzing 6 files simultaneously saves real time.

GitHub: tsunamayo7/helix-codex — MIT license, 56 tests, Python 3.12+.

Star if useful! Feedback welcome.

GameMaker setup with Typescript and VS Code

Create GameMaker object

I wrote my first line of code back in 2014, when I tried Unity 3D to create a simple game for fun. I didn’t have any programming experience at the time, but I loved video games. I made a couple of them back then, nothing commercial, just some simple games I could build in 4-5 days to play with friends for a few hours before moving on.

I eventually got into programming professionally and landed a job as a Software Engineer, which meant putting game dev aside and, plot twist, focusing on work.

Twelve years have passed since then (time flies), and the other day I was reading a book about the video game industry. Once I finished it, I decided to try making a game again. I didn’t want to use Unity or Godot, as they felt like “too much” for what I could realistically make. Instead, I leaned towards GameMaker, which helped limit any unrealistic scope of a “super insane 3D game” I might get tempted by later.

GameMaker was perfect for a simple 2D game (plus some of my favorite games are made in GM). I managed to put together a playable top-down shooter in just one evening. Since it is super focused on 2D development, everything is intuitive and easy to use. After spending a decade working as a full-stack dev doing hundreds of different things (writing code, optimizing SEO, CI/CD, DB migrations, analytics, scalability…), I fell in love with GameMaker. I could finally write code for fun again.

However, there were some trade-offs: GML.

GML is the programming language used in GameMaker. If I had to briefly describe it, I would say: “It’s an archaic version of JavaScript”. While I believe it is great for people who first start writing code, but for me there are some big no-go:

  • Typesafety: there are no types, you can use comments similarly to JSDoc, but I don’t think it is good.
  • Built-in code editor: this is the biggest issue for me personally. It is eons behind VS Code and **JetBrains **products in terms of DX experience.

As a certified “**TypeScript **lover” I said to myself: I can fix her this.

The idea was simple: “In and out, 20 minute adventure.” I would take TypeScript code, run it through a transpiler, and post-process whatever needed fixing (for example: thisdoes not exist in GML; it uses self).

Obviously, things weren’t that simple. But after a weekend (and a sleepless night), I managed to pull it off. I was finally able to write TypeScript code and make it work in GameMaker.

My initial PoC used a script in watch mode to compile TS code on the fly, but an incredible coincidence happened: two days after I started working on this tool, GameMaker released a new version of their IDE. It added support for build hooks, which allowed me to get rid of the “watcher” and simply transpile the code the moment you hit the “Run” button.

The actual thing

What I came up with is a CLI tool (open source, NPM) that can be installed globally.

Setup

Install the package globaly (-g):

npm i -g @odemian/gamemaker-typescript

It has 2 commands:

  • setup: Prepares the GameMaker project you are currently in to use TypeScript (creates tsconfig.json, links types, and configures pre_project_step to automatically transpile).
  • compile: Manually compiles the project. This is useful if you’ve added assets like sprites or sounds, as this command will generate their respective types.

Project configuration and the TS first object

After the library has been installed, open a GameMaker project in VS Code (or whatever code editor) and run:

gmts setup

Create an object:

Create GameMaker object

This will create a file at objects/obj_player/obj_player.yy. The .yy file contains the metadata for the object. Place your script in the same folder and give it any name (I call mine code.ts):

Write typescript code

You can think of objects/obj_player as folder-based routing: each object is a folder in the objects directory, and you write your code right there.

Here is the actual code if you want to copy it:

class Player extends GMObject {
  _movement_speed: number;

  // inside of the defineObject you can declare all of your events, like onCreate, onStep, onDraw etc...
  onCreate() {
    // use "this." keyword to access object properties in a safe fully typed way
    this._movement_speed = 2;
  }

  onStep() {
    var _hspd = keyboard_check(vk_right) - keyboard_check(vk_left);
    var _vspd = keyboard_check(vk_down) - keyboard_check(vk_up);

    if (_hspd != 0 || _vspd != 0) {
        var _dir = point_direction(0, 0, _hspd, _vspd);
        this.x = this.x + lengthdir_x(this._movement_speed, _dir);
        this.y = this.y + lengthdir_y(this._movement_speed, _dir);
    }
  }
}

If you’ve ever used GameMaker, you might wonder: “Wait, a Player class?” Yes, OOP baby.

Most other game engines (e.g., Unity, Godot) use this approach where each object’s code is encapsulated in a class. I experimented with different approaches, but I eventually settled on classes. They feel like the most natural way to write game code. In the ten years I’ve been working with TypeScript, I’ve almost never used the class keyword, it rarely feels right in modern front-end or back-end development. But for a game, it’s a perfect match.

The class inherits all the standard events from GMObject:

  • Create -> onCreate
  • Step -> onStep
  • Draw -> onDraw
  • and so on, you get the idea

Run it

After creating the Player object and writing the code, we can run it (I added a sprite to my obj_player behind the scenes):

Run game

How GameMaker understands TS

If you are into GameMaker, you might wonder if it uses the newest GMRT runtime. The short answer is no. As of the time of writing, GMRT is still in beta, and it is not clear when it will be released or in what form.

What currently happens is:

  • When you set up a project using gmts setup, it configures a pre_project_step script to run gmts compile before building the project.
  • When you press “Run”, it looks for all script and object resources and compiles any .ts files it finds in the resource folder.
  • Events like onCreate and onStep are extracted into Create_0.gml and Step_0.gml (scripts that GML understands). Other methods are then assigned to the instance in the Create event.
  • GameMaker builds the project by reading all of the generated .gml files.

The cool thing about this setup is that if you start your project with TS but at some point change the idea, you can simply remove .ts files, and keep .gml (they remain in readable form).

I built a context engine that saves Claude Code 73% of its tokens on large codebases

  1. The problem

    • LLM coding agents on large repos burn tokens scanning files. Claude Code on an 829-file codebase consumed 45K tokens just finding the right code. By turn 3 of a conversation, context is gone.
    • Token cost compounds. 20 questions in a session at 45K each is 900K tokens — nearly the entire 1M window. The agent degrades before your work is done.
  2. What Mnemosyne does

    • Sits between your codebase and your LLM. Indexes into SQLite, scores every chunk with 6 retrieval signals (BM25, TF-IDF, symbol search, usage frequency, predictive prefetch, optional dense embeddings), compresses with AST awareness, delivers exactly within your token budget.
    • Zero runtime dependencies. pip install mnemosyne-engine. No API keys, no cloud, no Docker. Works offline.
    • Drop-in integration: add 3 lines to your CLAUDE.md or .cursorrules and the agent queries Mnemosyne before reading files.
  3. The benchmarks

    • Include the full benchmark table from the README.
    • Be specific: “Claude Opus 4.6 with 1M context, tested against HCCValidatorAI (829 files, production codebase) and httpx (100 files, open-source).”
    • Include the honest finding: “Baseline produces slightly more detailed answers by reading source directly. The optimal workflow combines both: Mnemosyne finds the files, Claude reads them.”
    • This honesty is critical. The audience will find the benchmark report on GitHub. If the blog overstates, you lose credibility permanently.
  4. Quick start

   pip install mnemosyne-engine
   cd your-project
   mnemosyne init && mnemosyne ingest
   mnemosyne query "How does auth work?" --budget 8000
  1. How it retrieves

    • Six signals fused via Reciprocal Rank Fusion. Link to ALGORITHMS.md for the deep dive.
    • AST-aware chunking for Python, Go, Rust, C#, Java, Kotlin, JS/TS.
  2. Integration examples

    • Claude Code (CLAUDE.md snippet)
    • Cursor (.cursorrules snippet)
    • Any agent that can shell out
  3. What it does NOT do

    • Not a replacement for reading source files — it is a file finder that saves you from grep-scanning
    • Dense embeddings are optional (requires onnxruntime) — sparse retrieval handles most queries
    • Query latency is sub-500ms cold, sub-200ms warm — not instant
    • Small repos (under ~50 files) see marginal savings; the value scales with codebase size
  4. Conclusion

    • Open source, AGPL-3.0, commercial license available
    • Links: PyPI, GitHub, ALGORITHMS.md
    • “Try it on your codebase and tell me what breaks”