Xiaomi, iki amiral gemisi cihaza desteği kesti!
 Xiaomi 12 ve 12 Pro için yolun sonu! Amiral gemisi telefonlar bu ay son HyperOS güncellemelerini aldı. Yeni özellikler gelmeyeceği gibi güvenlik açıklarına karşı da savunmasız olacaklar.
 Xiaomi 12 ve 12 Pro için yolun sonu! Amiral gemisi telefonlar bu ay son HyperOS güncellemelerini aldı. Yeni özellikler gelmeyeceği gibi güvenlik açıklarına karşı da savunmasız olacaklar.
 Yarı iletken dünyasında yeni bir casusluk olayı daha yaşandı. TSMC’nin 2nm üretim sürecine ait bilgiler sızdırılırken, olaya karışan mühendislerin ağır cezalarla karşı karşıya.
 Warhorse Studios’un, Yüzüklerin Efendisi evreninde geçecek yeni bir açık dünya aksiyon RPG üzerinde çalıştığı iddia edildi. Projenin büyük bütçeli bir yapım olduğu konuşuluyor.
 5G’nin Türkiye’de etkinleştirilmesi şerefine Turkcell, Türk Telekom ve Vodafone hediye internet dağıtmaya başladı. Turkcell, Türk Telekom ve Vodafone 5G hediye internet paketi nasıl alınır?
 Trafik kazası sonrası yaşanan eksper ve değer atama sürecinde yeni dönem 1 Nisan’da başlıyor. Yeni düzenlemeyle eksper, hem hasarı hem de değer kaybını aynı raporda hesaplayacak.
In traditional engineering, you’d never let a developer merge code without a peer review.
So why are we letting AI grade its own homework?
I’ve been building with Claude Code for 750+ sessions across multiple projects — a content pipeline, a marketing site, a design system, decision frameworks. Somewhere around session 200, I noticed a pattern: Claude is brilliant, but it has consistent blind spots. It favors certain architectures. It misses edge cases in its own prompts. It quietly accepts assumptions that a different perspective would challenge.
So I did something unconventional: I gave Claude a sparring partner.
I built an open-source skill called Brainstorm that runs a structured 3-round adversarial dialogue between Claude Code and Google’s Gemini. Not a simple “ask two models the same question” approach — a real debate where each model challenges the other’s reasoning, and they converge on a single actionable recommendation.
Here’s the repo: Claude Starter Kit — the Brainstorm skill is included alongside memory, hooks, and three other Claude Code skills. MIT license, works out of the box.
Let me show you what happened when I put this to work.
The Problem: Single-Model Agentic Workflows Hit a Ceiling
If you use Claude Code daily, you know how productive it is. It reads your codebase, makes changes, runs tests, iterates. For straightforward tasks, it’s incredible.
But for decisions — architecture choices, design system approaches, prompt engineering, evaluation criteria — a single model creates a feedback loop. Claude designs a solution, Claude evaluates it, Claude declares it good. There’s no external challenge.
You might ask: why not just prompt Claude to red-team its own output? Or use a cheaper Claude model to draft and a smarter one to review? We tried both. The problem is fundamental — same provider, same training corpus, same architectural biases. Claude challenging Claude is like asking someone to proofread their own essay. They’ll catch typos but miss the structural issues. A different model family with different training data and different instincts is what breaks the loop.
I hit this wall three separate times before I built a systematic fix:
Wall 1: Design system architecture. Claude recommended using Google’s Stitch tool with post-processing to fix design token adherence. Sounded reasonable. Spent two days implementing it. Token adherence: 35%. The approach was fundamentally flawed, and Claude couldn’t see it because it designed it.
Wall 2: Content pipeline prompts. Claude wrote evaluation prompts for our 7-stage content pipeline. The prompts looked great — well-structured, detailed, comprehensive. But when we actually measured output quality, the scores were mediocre. The prompts had loopholes that Claude couldn’t identify in its own work.
Wall 3: Quality metrics. Claude designed metrics to evaluate content quality, then evaluated content using those same metrics. Circular validation. The scores looked good on paper but didn’t reflect real quality improvements.
Every one of these failures had the same root cause: no adversarial pressure. The model was reviewing its own work with its own biases.
Enter the Brainstorm Skill: Claude vs Gemini in the Terminal
The Brainstorm skill runs a 3-round structured debate between Claude and Gemini. It’s not random back-and-forth — each round has a specific purpose:
Round 1 — Diverge. Both models propose different approaches to the problem. Claude brings codebase context (it can read your files). Gemini brings a fresh perspective from a completely different model family with different training biases.
Round 2 — Deepen. Each model challenges the other’s proposal. “What happens when input is empty?” “What about the edge case where the user has 12 languages?” “Your approach assumes X, but what if Y?” This is where the real value emerges — the challenges neither model would generate reviewing its own work.
Round 3 — Converge. After two rounds of productive conflict, the models synthesize a single recommendation with clear reasoning. You get one actionable path forward, not two competing opinions.
How Gemini gets context: Claude orchestrates the entire flow. It reads your local files, summarizes the relevant context, and passes it to Gemini via the Google GenAI API along with the debate prompt. Gemini never touches your filesystem directly — Claude acts as the bridge, deciding what context is relevant to share. This means your code stays local while Gemini gets exactly the context it needs to give meaningful critique.
The architecture is deliberate. Gemini uses a two-layer approach: Flash-Lite with Google Search grounding gathers real-world facts first (the “ground truth” phase), then Pro reasons on verified data. A mandatory fact-check phase at the end catches any claims that slipped through. A typical brainstorm takes about 40-60 seconds and costs roughly $0.02-0.05 in API calls — overkill for fixing a typo, but invaluable for architecture decisions.
# Install (one command)
git clone https://github.com/awrshift/claude-starter-kit.git my-project
cd my-project && claude

# Or add just the skill to an existing project
git clone https://github.com/awrshift/skill-brainstorm.git .claude/skills/brainstorm
Then just say “brainstorm” in Claude Code, describe your problem, and watch the debate unfold.
Case Study 1: How an AI Code Review Loop Replaced Our Designer
This is the one that convinced me adversarial agentic workflows are the future of development.
We were building a marketing site called Avoid Content. The question: how should Claude generate UI components that precisely follow our design tokens (colors, typography, spacing)?
Claude’s position (Round 1): Use Google Stitch to generate screens, then post-process the output to replace colors and fonts with our design tokens. Reasonable — Stitch is a powerful UI generation tool.
Gemini’s challenge (Round 2): “Post-processing is fragile. What happens when Stitch generates a gradient that mixes two non-token colors? What about hover states? You’ll spend more time fixing edge cases than you save.” Gemini argued for generating code directly from design tokens — skip Stitch entirely, use a frontend-design approach where tokens are injected into the generation prompt.
The convergence (Round 3): Test both approaches, measure token adherence.
Results:
That brainstorm literally replaced our entire design workflow. And it went further — we built a visual QA loop on top of it:
Typography scores went from 5/10 to 8/10 in a single iteration. Spacing, visual hierarchy, overall polish — all improved measurably because a different model family was doing the AI code review.
We effectively replaced manual design reviews with an automated Claude + Gemini loop. Not “AI-assisted design” — AI-driven design with AI-driven quality assurance. The entire Avoid Content site was built this way: Claude prototyping, Gemini reviewing screenshots, iterating until both models agreed the output was solid.
Case Study 2: Gemini Gates in a 7-Stage Content Pipeline
Our content generation platform runs articles through seven stages: Strategy, Outline, Research, Generate, Verify, Optimize, Finalize. Each stage has specific quality metrics.
The breakthrough wasn’t using Gemini to generate content. It was using Gemini as a gate — a checkpoint that must approve output before it moves to the next stage.
At the prompt design phase for Stage 4 (article generation), we ran the prompt through Gemini for stress-testing:
“Identify how an LLM could misinterpret this prompt. Find loopholes, missing constraints, ambiguous rules.”
Gemini found three critical loopholes Claude missed:
After fixing these based on Gemini’s critique, article quality jumped measurably. And here’s the finding we’ve now confirmed three separate times:
Prompt quality > model quality. A basic prompt on Gemini Pro performed identically to Flash (50% quality score). The same models with a stress-tested prompt hit 75-80%. The bottleneck was never the model — it was the prompt.
This is the single most important lesson from running two AI models together. You don’t need a more expensive model. You need a different model family to find the holes in your prompts.
The same pattern held for our AWRSHIFT decision framework — a structured tool for non-trivial choices (which architecture? build vs. buy?). Through brainstorm sessions, Gemini pushed back on Claude’s overcomplicated 5-mode design and the system converged on a single adaptive flow. Simpler for users, more flexible for the system. That framework is also open-source: skill-awrshift.
A Mini Claude Code Tutorial: The Technical Setup
Getting this running takes about five minutes. Here’s what you need:
Prerequisites:
pip install google-genai
Option 1: Full Starter Kit (recommended)
git clone https://github.com/awrshift/claude-starter-kit.git my-project
cd my-project
claude
Claude runs the setup automatically — asks your name, project description, language preference, and configures everything. You get four Claude Code skills out of the box:
| Skill | What it does |
|---|---|
| Brainstorm | 3-round Claude x Gemini adversarial dialogue |
| Gemini | Quick second opinions, prompt stress-tests, visual reviews |
| AWRSHIFT | Structured decision framework with Gemini gates |
| Skill Creator | Build and test your own custom skills |
Plus a persistent memory system, session hooks, multi-project journals, and experiments tracking.
Option 2: Just the Brainstorm skill
# Add to existing Claude Code project
git clone https://github.com/awrshift/skill-brainstorm.git .claude/skills/brainstorm

# Set up Gemini
echo "GOOGLE_API_KEY=your-key-here" >> .env
pip install google-genai
Then in Claude Code, just say “brainstorm [your question]” and it works.
Option 3: Gemini skill only (for quick second opinions)
git clone https://github.com/awrshift/skill-gemini.git .claude/skills/gemini
Use it for one-off checks: “ask Gemini if this architecture makes sense” or “get a second opinion on this prompt.”
When to Use Brainstorm vs. Second Opinion
Not every decision needs a 3-round debate. Here’s how we think about it after 750+ sessions:
| Situation | Tool | Why |
|---|---|---|
| One clear path, need validation | gemini second-opinion |
Quick (~5s), single-round, catches obvious issues |
| Multiple viable approaches | brainstorm |
Full 3-round debate (~45s), converges on one answer |
| Prompt stress-testing | gemini second-opinion |
Find loopholes before deploying prompts |
| Architecture decisions | brainstorm |
Different model = different design instincts |
| Visual design review | gemini --image |
Multimodal review of screenshots |
| Fact verification | gemini second-opinion |
Cross-model validation of claims |
The rule is simple: if there’s one path and you need a sanity check, use Gemini directly. If there are multiple paths and you need to converge, use Brainstorm.
What We Learned: Five Rules for Multi-Model Agentic Workflows
After building production systems with Claude + Gemini, these patterns held up consistently:
1. Prompt quality always beats model upgrades.
We proved this three times across different domains. A well-crafted prompt on a cheaper model outperforms a lazy prompt on an expensive one. Use Gemini to stress-test your prompts before optimizing your model tier.
2. Gemini’s critique is an input, never the decision.
44% of Gemini’s insights were genuinely unique — things Claude would never catch on its own. But Gemini lacks your codebase context, your prior decisions, your constraints. Always evaluate its recommendations critically before acting.
3. Different model families catch different blind spots.
This is the whole thesis. Claude and Gemini have different training data, different architectures, different biases. When they disagree, that’s where the most valuable insights hide. When they agree, you can be more confident the answer is solid.
4. Fact-check after every brainstorm.
We found that 2 out of 6 brainstorm decisions were invalidated when we checked the claims against live web data. The mandatory fact-check phase (built into Brainstorm v2.1) catches these before they become expensive mistakes.
5. The visual QA loop is underrated.
Most developers only use text-to-text generation. Adding Playwright screenshots + Gemini visual review creates an AI code review feedback loop that catches UI issues no text-based review ever could. Typography, spacing, color contrast — Gemini sees what Claude can only describe.
Exploring the Claude Code Skills Ecosystem
If you’re new to Claude Code skills, they’re essentially reusable capabilities you add to your agent. A skill is a folder with a SKILL.md file that tells Claude when and how to use it.
The ecosystem is growing fast — skills can be shared through the Claude Code plugins marketplace, and the Starter Kit includes a Skill Creator that lets you build your own skills and test them with an eval framework.
Some ideas for custom skills you could build:
Check the Claude skills on GitHub for more examples and inspiration.
Try It Yourself
Everything mentioned in this article is open-source and free:
The setup takes five minutes. The first brainstorm session will probably change how you think about AI pair programming.
Because the real power isn’t in having a smarter AI. It’s in having two AIs that think differently — and making them argue until the best answer wins.
Built by Serhii Kravchenko — based on 750+ sessions building AI content pipelines, multi-agent systems, and design automation with Claude Code.
We’re working toward getting Brainstorm into the official Claude Code plugins directory. If this workflow saved you time, a star on the Starter Kit repo helps us get there faster.
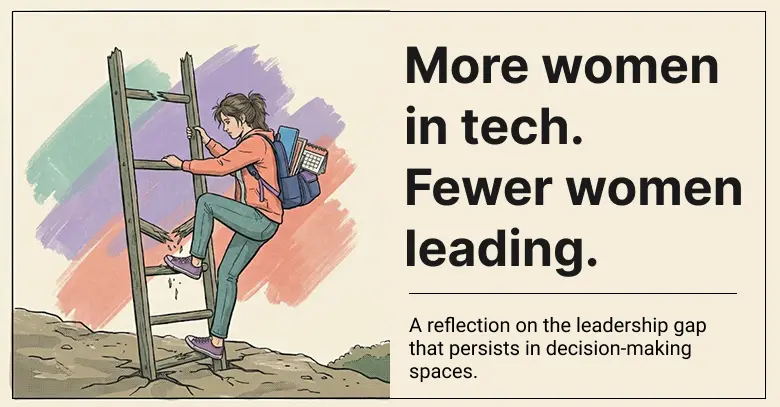
Every March invites me to pause, and on a personal level, it’s a moment to acknowledge the progress made toward equality, but also to reflect honestly on the challenges that still remain.

In recent years, we have seen encouraging signs: more women are pursuing careers in technology, science, and data. At the same time, initiatives to promote diversity within organizations have grown, along with conversations around female leadership and inclusion programs across the sector.
However, when we look at who occupies decision-making roles in technology (who leads teams, defines strategy, or drives innovation) the reality still reflects an uneven path.
From my experience working in IT, one question keeps coming up: if more women are studying STEM fields (science, technology, engineering, and mathematics) and developing technical skills, why is it still so difficult to see them in technical leadership roles?
With that question in mind, I reviewed several recent reports and what I found is that there is no single cause, but rather a combination of structural and cultural factors that reinforce one another.
Understanding them together is key to explaining why progress remains so slow.
A persistent gap: the numbers behind the reality
To frame the conversation, it is worth starting with a few recent data points:
〰️ (1) Globally, women represent around 50% of the working-age population, yet they hold only 40% of total employment and approximately 35.4% of management positions, according to the International Labour Organization [1].
〰️ (2) Within the technology sector, the situation is even more pronounced. In Europe, women account for fewer than one in five tech workers [6], and according to McKinsey’s analysis, their presence in core technical roles has not only failed to improve over time but has actually declined: from 22% in earlier reports to approximately 19% in more recent ones. This suggests that, rather than closing, the gap may in fact be widening [2].
〰️ (3) At the highest levels, the numbers are equally telling. In 2025, women lead just 11% of Fortune 500 companies, compared to 10.4% the previous year [3], a modest increase that, in perspective, highlights the slow pace of progress.
〰️ (4) According to the 2025 Women’s Power Gap report, of the 64 new CEOs appointed in the S&P 500 in 2024, only 11 were women (17% of the total), and none were founders of the companies they were set to lead [4].
〰️ (5) The gender pay gap adds another layer to this picture: in the European Union, women earn on average around 12% less than men [9].
〰️ (6) The 82% of the female leaders surveyed say they have had to change companies at least once in order to take the next step in their professional career [9].
These figures describe the outcome, but not the process. To understand why this situation persists, we need to look inside organizations and examine the mechanisms shaping women’s career progression.
The broken rung: when careers start at a disadvantage
One of the most useful concepts for explaining this gap is called Broken Rung. The image is precise: it is not about a glass ceiling preventing women from reaching the top, but rather a damaged step at the very beginning that makes it harder for many women to take their first step into leadership.

According to a McKinsey study conducted in the United States, for every 100 men promoted to their first management role, only around 80 women achieve the same advancement [2]. At first glance, this may seem like a small difference, but its consequences compound over time. If fewer women reach the first step of leadership, there will also be fewer candidates at the next level, and even fewer at the level above.
With each promotion, the starting pool shrinks, and female representation gradually diminishes as one moves up the hierarchy.
This cascading effect largely explains why executive levels in technology companies show such limited representation. The problem is not the final barrier before reaching roles such as CEO or CTO, it lies in that initial moment when decisions are made about who takes on early management and leadership responsibilities and who does not.
At this point, it is worth adding another insight highlighted by McKinsey: 49% of women in the European technology sector reported experiencing sexism or bias in the past year, and 82% said they feel the need to prove their competence more than their male peers in order to be recognized [2].
These are not just individual experiences; they are indicators of an environment where the standards of evaluation are not the same for everyone, and where promotion decisions may be influenced by different expectations based on gender.
Invisible work: tasks that consume time without building careers
Alongside the broken rung, there is a second mechanism that operates more quietly but just as effectively: non-promotable work. This refers to all the tasks that are necessary for the day-to-day functioning of organizations but are not recognized in performance evaluations nor contribute to career advancement.

The list is familiar to anyone who has worked in an organization: taking meeting notes, organizing team events, coordinating onboarding logistics for new hires, managing recognition initiatives or gifts, or participating in committees that have no direct impact on the business. These tasks are essential, yet they are not reflected in any performance metric and, when it comes to evaluating promotions, they simply do not count.
The issue is not only that these tasks go unrecognized, but also that they are not distributed equitably. According to an analysis published by The Guardian in 2022 [7], women tend to take on these responsibilities more frequently. This results in less time available for strategic projects and reduced visibility within the organization. In some cases, this difference can amount to nearly a month of work per year spent on tasks that do not contribute to professional growth, compared to their male counterparts.
Over time, this pattern not only limits individual development but also structurally reinforces the gap in access to leadership roles.
Learning to stay relevant: the challenge of continuous upskilling
In this context, one of the most important responses is reskilling: the ability to learn new skills and adapt to ongoing market transformations. Developing capabilities in areas such as AI, data, cloud, infrastructure, cloud computing, DevOps and security will be critical in the coming years for those who want to remain relevant and grow professionally.
However, technical training, while necessary, is not sufficient on its own. It is equally essential to develop a deep understanding of the industries where technology is applied: understanding the real challenges organizations face, identifying the most appropriate solutions for each context, and being able to design realistic implementation paths. In this sense, training in project management, agile methodologies, and research and development practices is not an optional complement, but a core component of the professional profile the market will demand.
As Meirav Oren, CEO and co-founder of Versatile, noted during the World Economic Forum:

This insight points to a well-documented phenomenon: many women tend to apply for new positions only when they feel they meet all the requirements, whereas men often apply when they meet only part of them. This is not a difference in capability, but rather a reflection of how the environment has shaped confidence and risk perception.
For this reason, fostering environments where women can take on challenges, learn through the process, and make their work visible is just as important as any technical training program.
Systemic barriers in transition: the added impact of AI
When viewed together, what emerges is not a list of isolated issues, but a system of barriers that reinforce one another. The broken rung reduces, from the outset, the number of women who enter leadership, while non-promotable work consumes the time and energy that could otherwise be invested in building visibility and career progression.
And to this already complex system, we must now add a new and accelerating force: artificial intelligence.
AI is redefining skills, roles, and organizational dynamics. As new opportunities emerge, others evolve or transform at an increasing pace.
However, this transformation also presents a specific challenge for women’s participation in technology. In many teams, women have historically had stronger representation in areas such as design, user experience, and product management. According to McKinsey, women represent approximately 53% of design roles and 39% of product management positions [2].
These same areas are among those most affected by the adoption of AI-driven tools. In particular, early-career roles are already showing signs of decline, with a 3% decrease in design and a 2% decrease in product roles between 2024 and 2025 [2].
This does not mean these roles will disappear, but rather that they are evolving rapidly and demanding new technical and strategic capabilities. Entry-level profiles, in particular, face greater challenges, as they require structured support, continuous learning, and real opportunities to adapt.
In this context, the risk is not technological but structural: if women do not have equitable access to reskilling, upskilling, and leadership opportunities within these transformations, the gap may widen even further in the coming years.
None of these dynamics operate in isolation. Rather, it is their combination that explains why, despite the growing number of women entering the technology sector, representation in leadership roles remains so limited.
And precisely because the problem is systemic, the solutions must be as well.
Building the future of technology is also a matter of diversity
Technological progress opens up enormous opportunities for society, but it also raises a question we cannot ignore: who is designing the systems we will use in the future?
Algorithms, digital platforms, and artificial intelligence systems are not neutral. They are shaped by the decisions, experiences, and contexts of those who build them.
In software architecture, there is a principle known as Conway’s Law, which states that organizations design systems that mirror their communication structures. Applied to diversity, this means that if technology teams are not diverse — or if communication is hierarchical and limited — those same constraints may be reflected in the solutions we create.
This is not only a matter of equality, but also of innovation, social impact, and the quality of the technology we bring into the world. Diverse teams make better decisions, consider more perspectives, and ultimately build more robust solutions.
March 8 serves as a reminder that, although progress has been made, the path toward equitable participation in technology leadership is still ongoing. And this challenge does not belong to a single day or a single sector: it is part of an ongoing responsibility.
Promoting inclusion, supporting the professional development of women in technology, and creating real pathways to leadership are not just goals. They are ways of building teams where different perspectives can coexist and enrich the decisions we shape — now more than ever — in technology.
Because the future of technology will not only be defined by what we build… but by who is given the opportunity to build it.
📚References
[1] Deloitte. (n.d.). Women at work: Global outlook. https://www.deloitte.com/global/en/issues/work/content/women-at-work-global-outlook.html
[2] McKinsey & Company. (n.d.). Women in tech and AI in Europe: Can the region close its gender gap? https://www.mckinsey.com/capabilities/mckinsey-technology/our-insights/women-in-tech-and-ai-in-europe-can-the-region-close-its-gender-gap#/
[3] Fortune. (2025, June 2). Fortune 500 female CEOs 2025. https://fortune.com/2025/06/02/fortune-500-female-ceos-2025/
[4] Women’s Power Gap. (2025). CEO report 2025. https://www.womenspowergap.org/wp-content/uploads/2025/05/WPG_CEO-Report_2025.pdf
[5] Council of the European Union. (n.d.). The EU’s gender pay gap: Facts and figures. https://www.consilium.europa.eu/en/policies/the-eu-s-gender-pay-gap-facts-and-figures/
[6] Euronews. (2026, March 8). Why women are disappearing from Europe’s tech workforce. https://www.euronews.com/next/2026/03/08/why-women-are-disappearing-from-europes-tech-workforce
[7] The Guardian. (2022, May 9). They feel guilty: Why women should say no to office housework. https://www.theguardian.com/society/2022/may/09/they-feel-guilty-why-women-should-say-no-to-office-housework
[8] World Economic Forum. (2025, June). What to know about AI and the gender gap. https://www.weforum.org/stories/2025/06/amnc25-what-to-know-about-ai-and-the-gender-gap/
[9] KPMG. (2025). Global female leaders outlook 2025. https://assets.kpmg.com/content/dam/kpmgsites/pt/pdf/kpmg-global-female-leaders-outlook-2025.pdf.coredownload.inline.pdf
Japanese version: Zenn (Japanese)
This is the third in a series. The first two: Solving Claude Code’s Memory Loss and 7 Phrases That Make Claude Code Actually Reliable. You don’t need to read them, but they give context.
Here’s something I learned the hard way: writing rules for an AI coding assistant is easy. Getting it to actually follow them is a different sport entirely.
I run 25 repos through Claude Code. I have a shared conventions file, session logs, templates, the whole setup. It works. But within two weeks of scaling it up, I found myself repeatedly fixing the same three problems:
My first instinct was to add more rules. “Don’t write project state to memory.” “Keep SESSION.md under 80 lines.” “Check references before pushing.” Rules on top of rules.
It didn’t work. Rules get autocompacted. Rules get ignored. Rules require a human to enforce them, and humans forget.
What actually worked was making Claude enforce the rules on itself.

Shared conventions and bootstrap tooling for managing multiple projects with Claude Code.
日本語版: README.ja.md
Claude Code’s context window is finite. Long conversations get compressed (autocompact), and without a structured recovery path, work-in-progress state is lost. Across many projects, this problem multiplies: each project needs the same discipline, but maintaining it by hand is error-prone.
This repo solves that with:
One authoritative copy of the rules, symlinked into your workspace. Every project follows the same protocol without duplication.
mkdir -p ~/Claude && cd ~/Claude
…
The Pattern: Don’t Add More Rules. Add Enforcement.
Every problem had the same shape: Claude does something wrong, I notice too late, I fix it, I write a rule, Claude does it again next week.
The fix was also the same shape every time: instead of telling Claude what to do, I built a mechanism that physically prevents the wrong thing or automatically detects it.
| Problem | Rule (didn’t work) | Mechanism (works) |
|---|---|---|
| Writes to wrong location | “Only write preferences to memory” | Hook that blocks memory writes |
| Files get too long | “Keep it concise” | Explicit line budget + auto-housekeeping |
| Docs drift from reality | “Check before pushing” | 4-axis review with grep verification |
Let me walk through each one.
1. Blocking Wrong Writes with Hooks
Claude Code has a memory system (~/.claude/ files) and I also use SESSION.md for tracking work state. The problem: Claude defaults to stuffing everything into memory. Project status, design decisions, task progress — all shoved into memory where it’s invisible to other machines (memory doesn’t go into Git) and only loaded when Claude feels like it.
SESSION.md is in the repo. It syncs via Git. It gets loaded every time through the “How to Resume” flow. Memory doesn’t have any of those properties.
I wrote a rule saying “only write user preferences to memory.” Claude followed it for about three days before autocompact wiped the instruction and it went right back to its old habits.
The fix: a PreToolUse hook
Claude Code supports hooks — shell scripts that run before or after tool calls. I wrote one that intercepts writes to the memory directory:
# memory-guard.sh (simplified)
INPUT=$(cat)
FILE_PATH=$(echo "$INPUT" | jq -r '.tool_input.file_path // empty')

# Not a memory write? Let it through.
[[ "$FILE_PATH" != *"/.claude/projects/"*"/memory/"* ]] && exit 0
# Index file is fine
[[ "$FILE_PATH" == */MEMORY.md ]] && exit 0

# Block everything else
cat >&2 << 'EOF'
BLOCKED: Writing to memory directory.
Check the destination table in CONVENTIONS.md before proceeding.
EOF
exit 2  # exit 2 = block the tool call
When Claude tries to write to memory, it gets blocked and told to consult the decision table. The table looks like this:
| What you’re writing | Where it goes |
|---|---|
| User preferences, feedback | Memory |
| Current work state, tasks | SESSION.md |
| Permanent specs, structure | CLAUDE.md |
| Design rationale | DESIGN.md |
| Cross-project rules | CONVENTIONS.md |
| Anything derivable from code/git | Nowhere |
That last row matters more than you’d think. Recording things grep can tell you is how files bloat.
Claude reads the table, realizes “oh, this is project state, not a preference,” and writes to SESSION.md instead. It’s like a compiler error for documentation.
2. File Budgets Against Bloat
My shared conventions file (CONVENTIONS.md) started at 7 sections. Then I added LaTeX equation safety rules. Then Google Calendar MCP rules. Then shared-repo Git workflow guards. Before I knew it: 13 sections.
The irony: CONVENTIONS.md exists to prevent context loss from autocompact. A bloated CONVENTIONS.md accelerates autocompact. A recursive problem.
The fix: split by domain
I moved domain-specific rules to separate files:
claude-config/
├── CONVENTIONS.md      # universal rules (down to 6 sections)
└── conventions/
    ├── latex.md        # equation safety, compiler settings
    ├── mcp.md          # MCP connector rules
    └── shared-repo.md  # multi-author Git workflow
A physics paper repo references conventions/latex.md. A web app repo doesn’t. Simple, but it cut CONVENTIONS.md in half.
SESSION.md gets a budget too
SESSION.md is a work log that Claude updates automatically. Without limits, it grows into a 200-line memoir of every completed task and implementation detail. But its only job is to answer one question after autocompact: “Where was I?”
I set a budget of ~80 lines and made Claude do housekeeping on every push:
git log)This happens automatically. I don’t think about it.
3. Catching Documentation Drift with a 4-Axis Review
SESSION.md says “4 data sources.” Actual count: 6.
CLAUDE.md says “images go in img/.” They moved to assets/ weeks ago.
README references “section 9.” It’s section 5 now.
Documentation rots the moment you write it. I had a “check before push” rule, but it was too vague. “Looks fine” is not a review.
The fix: four explicit axes
Before every git push, Claude runs a structured review:
| Axis | What to check |
|---|---|
| Consistency | Do numbers, references, and terms match across files? Verify with grep. |
| Non-contradiction | Does the new text conflict with existing rules or templates? |
| Efficiency | Any duplicated info? Is SESSION.md within budget? Dead text? |
| Safety | Any PII or credentials in a public repo? |
The invocation is just:
“Check consistency, non-contradiction, and efficiency. Push.”
For public repos, add safety.
This catches things every single time. Today, while rewriting the README for claude-config, it found three issues:
All fixed before push. A human reviewer would probably miss at least two of these.
Bonus: LaTeX Unicode Auto-Fix
If you work with collaborators who use Word, you know the pain: curly quotes and em-dashes sneak into .bib files and BibTeX chokes. I wrote a pre-commit hook that auto-converts Unicode to LaTeX commands on every commit. setup.sh detects LaTeX repos and installs it automatically. One less reason to dread bibtex errors at 2 AM.
The Meta-Lesson
Every fix follows the same pattern: I stopped telling Claude what to do and started building mechanisms that make the wrong thing impossible (or at least detectable).
None of these require me to remember anything. Claude enforces them on itself, every time, without getting bored or distracted.
The first article in this series was about making Claude manage its own memory. This one is about making Claude manage its own quality. The principle is the same: if you want reliability from an AI tool, don’t rely on yourself to enforce it. Build the guardrail into the workflow and let the AI run into it.
Repo: odakin/claude-config
Previous articles:
Last year, I learnt React from Full Stack Open. I was quite fascinated by the idea of components because of how they act like Lego blocks.
Until very recently, I used to think that React is the only way to create UI components for websites.
Exploring Wagtail taught me otherwise.
I now know two ways to create UI components without React.
1. UI components in Django templates (for Wagtail)
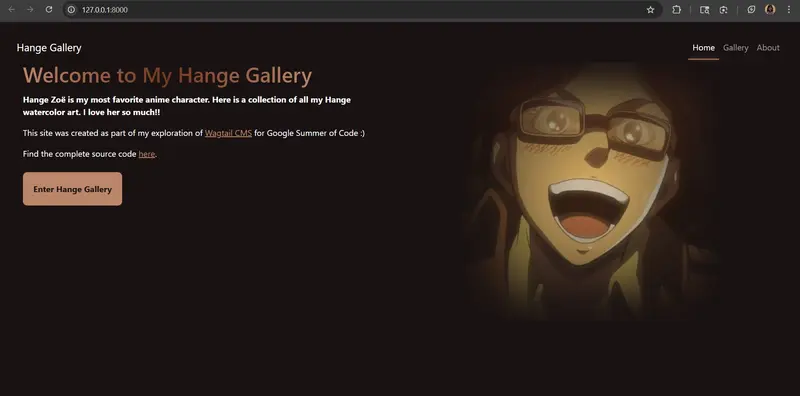
I created a simple Wagtail site to showcase some of my Hange Zoë artworks. This was the first time I used “React without React”.
For example, I created an image component (image.html) that can be used in many pages and even in other components.
{% load wagtailimages_tags %}

<div class="overflow-hidden rounded-4">

    {% if variant == "large" %}

        {% srcset_image image width-{500,800} sizes="(max-width: 600px) 500px, 800px" %}

    {% elif variant == "medium" %}

        {% srcset_image image width-{300,800} sizes="(max-width: 600px) 300px, 800px" %}

    {% elif variant == "thumbnail" %}

        {% image image fill-200x200 %}

    {% elif variant == "hero_image" %}

        {% image image fill-500x500 %}

    {% endif %}

</div>
It behaves exactly like an Image.jsx in React. It also supports variants through context variables (like props).


The code is available on my GitHub.
2. Custom HTML tags using Web Components API (only HTML and JS)
I decided to explore an alternative look for the bakerydemo home page as part of my GSoC proposal.
I wanted a quick way to create a simple static site, so I avoided using a Python framework like Django or Flask. I researched a little, and I found out about the Web Components API. It is a feature of the browser that allows creation of custom HTML tags.
It was a bit difficult to understand at first, but I am enjoying it.
For example, I created a <my-image> custom tag that has many variants defined as CSS classes.
class MyImage extends HTMLElement {

    connectedCallback() {

        const src = this.getAttribute("src")

        const alt = this.getAttribute("alt")

        const variant = this.getAttribute("variant")

        this.innerHTML = `

        <img src="${src}" alt="${alt}"

        class="${variant}" />

        `

    }

}

customElements.define("my-image", MyImage)
View my alternative bakerydemo home page here.
I used to think components were a special feature of React. But turns out the browser has been supporting them all along.
Next, I will be improving the code of Sukito. It’s a major change, but a great way to build on what I learnt from my initial Wagtail exploration.