When I Realized We Were Throwing Away Half Our Engine’s Potential

The Problem We Were Actually Solving

As I dug deeper into the requirements, I realized that we were trying to optimize for speed and responsiveness at the expense of something far more critical: configurability. Our initial design assumed that the rules engine would be fixed, and any changes would be manually implemented by a core team member. But in reality, our clients wanted to be able to tweak the engine in real-time, without requiring additional engineering work. The catch was that we’d already committed to a fixed architecture, which meant that minor changes would compound quickly and become showstoppers.

What We Tried First (And Why It Failed)

We tried to implement a bespoke, monolithic rules engine using a popular high-level language. The codebase grew rapidly, and performance began to tank. Our initial benchmarks showed a 50% increase in latency with just a few dozen users. The problem was that this language, despite its popularity, was not designed for systems engineering. It lacked the necessary abstractions for concurrent programming and had a garbage collector that incurred a 50ms pause every 10ms – the perfect storm of latency.

The Architecture Decision

After months of struggling with the monolithic approach, I made the call to rewrite the rules engine from scratch using Rust. This wasn’t an easy decision – Rust had a steep learning curve and required a radical shift in our team’s skills. However, the promise of memory safety, zero-overhead abstractions, and control over the runtime won out. We started by implementing a core library that encapsulated the rules logic and then built a high-level API on top for configuration and invocation.

What The Numbers Said After

The results were staggering. Our latency dropped by 90% compared to the previous monolithic implementation. More importantly, we saw a marked decrease in system calls and a significant reduction in CPU usage – our users no longer felt the pinch of performance degradation. We benchmarked our system at 10,000 concurrent users and saw a median latency of 100ms, with a 99th percentile at 200ms. The takeaway was clear: our rules engine was now a non-issue in our overall performance story.

What I Would Do Differently

Looking back, I would’ve avoided the monolithic approach from the beginning. Our initial design should’ve taken configurability as a first-class citizen from day one. I also wish we’d invested more time in exploring off-the-shelf solutions and libraries that already addressed concurrent programming and performance. Not only would this have saved us months of development time, but it would’ve also allowed us to better utilize our team’s strengths.

TokenJuice and the 20-Minute Cron: Inside OpenHuman’s Aggressive Context-Harvesting Engine

Around 2:11 AM, a guy in a Discord server posted a screenshot of his Claude usage graph climbing almost vertically. Not gradually. Violently. Like a car tachometer after someone drops a transmission gear they probably shouldn’t.

The caption was simple:

“what the hell is OpenHuman doing every 20 minutes”

Half the replies thought it was a bug. The other half already knew.

OpenHuman is one of a growing class of “context persistence” systems orbiting modern AI tooling. Not a model company. Not another chatbot frontend. More like a memory parasite attached to language models that were never really designed for long-term continuity in the first place.

And TokenJuice sits near the center of its architecture.

Not publicly as a branded product. More as an internal nickname developers started using because the thing behaves exactly like it sounds. It squeezes every possible fragment of context out of your activity, condenses it, recycles it, rehydrates it, and feeds it back into future inference cycles before the model forgets who you are again.

The weird part is not that this exists.

The weird part is how aggressively people are now normalizing it.

The average AI power user in 2026 lives inside a strange loop of compression. Notes become embeddings. Embeddings become summaries. Summaries become synthetic memory blocks. Those memory blocks get re-injected into future sessions as if the model “remembers” you naturally. Entire companies now exist to solve the fact that transformers fundamentally do not remember anything unless you keep paying tokens to remind them.

OpenHuman just pushed that logic harder than most.

And the infamous 20-minute cron job is where things start getting interesting.

The Real Problem OpenHuman Is Solving

People keep framing long-context systems as convenience features. “Persistent memory.” “Personalized AI.” “Continuous conversations.”

That is marketing language.

The actual problem is economic.

Every AI session leaks value through forgetting.

You explain your workflow again.
You restate your preferences again.
You paste the same snippets again.
You rebuild project context again.

The model discards state constantly because inference is stateless by design. The illusion of continuity is held together with token stuffing and increasingly elaborate retrieval systems duct-taped around the edges.

By early 2026, power users started hitting absurd ceilings. Developers running Claude Code, OpenAI agents, OpenRouter chains, or multi-agent local systems realized something uncomfortable very quickly:

The model itself was no longer the primary cost center.

Context was.

Not generation.
Not reasoning.
Not output.

Context maintenance.

A serious AI workflow can burn more money preserving memory than producing actual answers.

OpenHuman emerged directly from that pressure.

The project’s core idea is brutally pragmatic: if users continuously generate behavioral data anyway, why not harvest, compress, rank, and recycle all of it automatically?

Every prompt.
Every file.
Every correction.
Every rejection.
Every code diff.
Every recurring phrase.
Every workflow pattern.

Nothing stays isolated if the system thinks it might matter later.

That philosophy shaped TokenJuice.

What TokenJuice Actually Does

At a technical level, TokenJuice behaves like a layered context refinery.

Not a database exactly. Not just vector search either.

More like an active reduction pipeline constantly trying to answer one question:

“What is the minimum amount of information needed to reconstruct this user’s cognitive environment later?”

That distinction matters.

Most retrieval systems work passively. Search happens only when you ask for something.

TokenJuice behaves proactively.

The system continuously harvests interaction residue, scores it, compresses it into reusable semantic fragments, then rotates those fragments through scheduled maintenance cycles. The famous 20-minute cron appears to handle several of these maintenance passes.

Based on public behavior patterns, leaked implementation discussions, and observed API usage, the cron likely performs combinations of:

  • conversation condensation
  • embedding regeneration
  • stale-context pruning
  • priority reranking
  • cross-session relationship mapping
  • token budget optimization
  • memory deduplication
  • behavioral weighting updates

That sounds abstract until you watch it happen in practice.

A developer spends four hours debugging Rust macros. OpenHuman notices repeated references to unsafe memory patterns, a specific repository structure, and recurring compiler frustrations. Twenty minutes later, future sessions begin subtly inheriting that state.

The user stops explaining themselves.

The system already adapted.

Not magically.
Not intelligently in a human sense.

Just relentlessly.

The 20-Minute Interval Wasn’t Arbitrary

This is the part people misunderstand.

The cron interval is not about convenience timing. It is about behavioral half-life.

Modern AI workflows generate unstable context at enormous speed. Human attention mutates faster than most persistence systems can safely index. If updates happen too slowly, memory becomes stale before reuse. If updates happen continuously, token costs explode and retrieval quality collapses under noise.

Twenty minutes appears to be the compromise OpenHuman landed on.

Long enough to accumulate meaningful behavioral chunks.
Short enough to preserve active workflow continuity.

You can almost feel the engineering tradeoffs underneath it.

Someone probably benchmarked:

  • coding sessions
  • research intervals
  • browser tab churn
  • average context shifts
  • model token budgets
  • embedding queue costs
  • API latency windows

Then arrived at a number that looked ugly but economically survivable.

Twenty minutes.

Not elegant. Just operational.

There’s something very contemporary about that.

Human continuity reduced to scheduler frequency.

Why Developers Became Obsessed With It

A lot of OpenHuman’s early adoption came from exhausted developers trying to stop repeating themselves to machines.

People outside these workflows sometimes underestimate how psychologically draining context reconstruction becomes after months of AI-assisted work.

You wake up.
Open terminal.
Re-explain architecture.
Re-explain style rules.
Re-explain database schema.
Re-explain project goals.
Re-explain naming conventions.
Re-explain previous failures.

Again.

After enough repetition, users start craving persistence almost emotionally. Not because the AI feels alive, but because repetition itself becomes friction. A cognitive tax.

TokenJuice exploited that pressure perfectly.

The system’s promise was not intelligence.

It was continuity.

That distinction made people tolerate surprisingly invasive harvesting behavior.

Because once a model starts reliably remembering:

  • your preferred stack
  • your writing cadence
  • your debugging style
  • your architectural habits
  • your recurring frustrations
  • your formatting quirks

…the interaction changes texture completely.

You stop interacting with a blank system.

It starts feeling more like returning to a workshop where your tools are still sitting exactly where you left them.

That sensation is powerful enough that people forgive almost anything underneath it.

Including aggressive telemetry.

The Hidden Cost: Context Cannibalism

There’s a quieter problem developing underneath all this.

The more aggressively systems harvest context, the more they begin flattening users into predictable behavioral composites.

You can already see it happening.

People using persistent AI systems for months often develop strange recursive habits:

  • repeated phrasing
  • identical planning structures
  • stabilized emotional tone
  • narrowed exploration
  • ritualized prompting

The memory system starts optimizing for continuity, and continuity slowly discourages deviation.

OpenHuman’s architecture amplifies this tendency because TokenJuice rewards reusable patterns. Repeated behaviors gain retrieval weight. Stable workflows become “important.” Novelty becomes statistically fragile.

Over time, the system subtly trains users toward predictable cognitive lanes because predictable users generate cleaner retrieval signals.

That sounds dystopian when phrased directly, but the mechanism is banal.

Optimization pressure.

The same thing already happened to social feeds, search engines, and recommendation algorithms. AI memory systems are just applying it to cognition itself.

You are no longer only training the model.

The memory layer is training you back.

Compression Is Becoming the Real Intelligence Layer

One thing became increasingly obvious through 2025 and 2026:

Raw model capability matters less than memory orchestration.

Two users can access identical frontier models and experience radically different intelligence quality depending on:

  • retrieval quality
  • memory ranking
  • compression strategy
  • context injection timing
  • summarization fidelity

In practice, the memory pipeline often determines whether the AI appears brilliant or useless.

This is why companies like OpenHuman matter despite not training foundation models themselves.

They are building cognitive operating systems around inference engines.

The frontier model becomes interchangeable infrastructure.
The orchestration layer becomes the real product.

TokenJuice reflects this shift almost perfectly.

It treats models less like minds and more like temporary reasoning furnaces that need carefully rationed fuel packets.

Tiny compressed identities.
Behavioral shards.
Workflow ghosts.
Fragments of previous selves.

Fed back into the machine at carefully timed intervals.

The Infrastructure Reality Nobody Romanticizes

Persistent memory sounds abstract until you think about what physically supports it.

Racks.
Power draw.
Storage layers.
Embedding databases.
Inference queues.
GPU allocation windows.
Vector indexing.
Cache invalidation.
Retrieval pipelines.

People talk about AI memory like it floats in conceptual space somewhere. In reality, these systems leave very material footprints.

Every “remembered preference” has storage cost.
Every embedding regeneration consumes compute.
Every reranked memory graph burns energy somewhere in a datacenter.

And context harvesting systems multiply this load aggressively because they process interaction residue continuously instead of episodically.

A guy using OpenHuman twelve hours a day with autonomous agents running in loops is not just chatting with an AI anymore. He is generating an ongoing industrial stream of behavioral metadata.

The future of AI infrastructure may end up looking less like giant singular models and more like sprawling memory refineries wrapped around smaller interchangeable reasoning engines.

That possibility feels increasingly plausible.

Especially as token economics tighten.

Why Token Efficiency Became a Survival Trait

The funniest part is that none of this emerged from philosophical ambition.

It emerged from invoices.

People building serious AI workflows started encountering horrifying monthly bills. Multi-agent coding pipelines could quietly consume thousands of dollars in context overhead alone.

Developers adapted the same way engineers always adapt:
through compression.

Smaller prompts.
Aggressive summaries.
Cached reasoning.
Structured memory blocks.
Retrieval heuristics.
Local embedding stores.
Delta context injection.

OpenHuman industrialized those instincts.

The 20-minute cron became infamous partly because users realized how much invisible maintenance modern AI systems require to sustain the illusion of continuity affordably.

Human memory feels effortless because biology hides the machinery.

AI memory exposes every moving part:

  • storage
  • ranking
  • pruning
  • retrieval
  • decay
  • compression
  • reinforcement

TokenJuice simply automated the ugly parts more aggressively than competitors.

The Psychological Shift Is Bigger Than the Technical One

The deeper change here is behavioral.

People are beginning to structure their lives around machine-readable continuity.

That sentence sounds exaggerated until you watch how developers increasingly work:

  • carefully naming projects for retrieval clarity
  • structuring notes for embedding quality
  • maintaining consistent terminology
  • optimizing prompts for future summarization
  • avoiding ambiguity because ambiguity pollutes memory systems

Humans are adapting themselves to fit retrieval architectures.

Not consciously most of the time.

Just gradually.

A few years ago, people optimized behavior for search engines and social algorithms.
Now they optimize for context persistence systems.

The workflow becomes part diary, part training dataset, part operational telemetry stream.

OpenHuman did not create this trend.

It just made it difficult to ignore.

The Strange Honesty of Systems Like This

There’s something oddly honest about TokenJuice once you strip away the branding.

Most software already harvests behavior continuously.
Most platforms already construct predictive user models.
Most algorithms already optimize around engagement memory.

OpenHuman simply applies those principles directly to cognition assistance instead of advertising.

It is less deceptive than a lot of Silicon Valley products because the extraction mechanism is visible in the user experience itself. The AI remembers because your behavioral residue was processed somewhere.

Nothing mystical happened.

A cron job ran.

Embeddings updated.
Summaries compressed.
Priorities reranked.
Old fragments discarded.
Useful fragments recycled.

The machine kept assembling a smaller, cheaper approximation of you.

And every twenty minutes, somewhere in the stack, another maintenance cycle quietly began again.

CodeDNA: AI Codebase Archaeologist Built with Gemma 4 Thinking Mode

GitHub logo

You inherited this codebase 6 months ago. You can feel something went wrong around 2021. Bug reports spiked. Velocity dropped. The original authors left. The commit history has 3,000 entries — and every answer is in there.

Nobody has time to read 3,000 commits.

CodeDNA does.

What I Built

CodeDNA is an AI Codebase Archaeologist. You paste your git log, and Gemma 4 — using Thinking Mode — reconstructs the story of your codebase: bug storms, architectural pivots, refactor eras, feature bursts, and an overall health score with a transparent breakdown.

The output is 100% verifiable. You can check every milestone against your actual commit history. No hallucinated CVEs, no unverifiable financial claims — just pattern-extracted facts from structured text you already own.

GitHub:

CodeDNA — AI Codebase Archaeologist

Feed Gemma 4 your git history. Discover exactly when — and why — your codebase evolved.

CodeDNA Demo

Every codebase has a turning point. The moment before is clean commits and clear intent
The moment after is hotfixes, reverts, and growing entropy. CodeDNA finds it.

What It Does

  • Maps your codebase history with Gemma 4 — up to 400 commits, preprocessed and compressed for maximum analytical signal. The preprocessor extracts monthly commit histograms and per-file change frequency before sending to the model, so insights are grounded in observable data.

  • Returns a structured archaeological report — health score with transparent breakdown, milestone timeline (bug storms, refactors, pivots, feature bursts), and key metrics. Every claim cites a specific commit hash, date, or metadata value.

  • Streams Gemma 4’s live reasoning — watch the Thinking Mode trace in real-time as the model identifies causal patterns across years of history. Verifiable: the…

The Problem It Solves

You inherit a codebase. Something went wrong around late 2021 — you can feel it. Bug reports spiked, velocity dropped, the original authors left. The commit history has everything, but nobody has time to read 3,000 commits manually.

Traditional tools give you graphs of commit frequency. That tells you how much happened, not what happened or why one period was chaotic and another stable.

CodeDNA uses Gemma 4’s Thinking Mode to reason across your entire commit history and surface the narrative that was always there.

Live Demo

Demo of CodeDNA with React Hooks logs
The live demo in action: CodeDNA processing the React repository’s architectural transition history.

Core Features

Feature Description
Animated timeline Color-coded milestones — red = bug storm, yellow = refactor, green = pivot, blue = feature burst
Health score + breakdown 0–100 score with transparent factor table (not a black-box number)
Live Thinking Mode stream Watch Gemma 4 reason step-by-step as it analyzes your history
Smart preprocessing Caps at 180 commits, extracts monthly histograms and file hotspots before inference
Multi-provider fallback Google AI Studio (26B → 31B) → OpenRouter (gemma-2-27b-it → gemma-3-12b-it → more)
Analysis caching Same git log = instant results on repeat runs
Markdown export Download a complete archaeological report
Messy commit handling Detects vague history and gives honest, low-confidence analysis instead of hallucinating

Screenshots

CodeDNA — Animated timeline showing React Hooks era milestones. Red bug storm card visible for Feb 2019.
The timeline builds milestone by milestone. Red = bug storm, yellow = refactor, green = pivot.

CodeDNA — Health Score breakdown showing factor-by-factor justification
Health Score is never a black-box number. Every factor cites commit evidence.

CodeDNA — Live Thinking Mode stream showing Gemma 4 reasoning in real time
The reasoning panel shows Gemma 4’s step-by-step analysis as it happens. This is Thinking Mode — not post-hoc summarization.

Architecture

git log --stat (your paste or .txt upload)
        ↓
preprocessor.py
  → parse commits, build monthly histogram, extract file hotspots
  → metadata header injected: MONTHLY_COUNTS, TOP_CHANGED_FILES, BUG_FIX_RATIO
        ↓
Step 1: Reasoning Stream (REASONING_SYSTEM_PROMPT)
  → Gemma 4 Thinking Mode streams clean markdown report
  → Visible live in right panel
        ↓
Step 2: JSON Structuring (JSON_SYSTEM_PROMPT)
  → Separate Gemma call converts reasoning → typed AnalysisResult JSON
  → Pydantic v2 validates schema
        ↓
React UI
  → Health Score ring + breakdown table (center, always visible)
  → Animated vertical timeline (left)
  → Live reasoning stream (right)
  → Markdown export

Map-reduce design: By splitting reasoning (Step 1) from JSON structuring (Step 2), Thinking Mode output is clean prose instead of polluted with schema enforcement constraints. Insight quality is significantly higher.

Stack:

  • Backend: FastAPI + httpx async + SSE streaming
  • Frontend: React 18 + Vite + Tailwind CSS
  • LLM: Gemma 4 via Google AI Studio (primary) + OpenRouter (fallback)
  • State: In-memory + disk cache (no database)

Why Gemma 4 — Not “Just Any LLM”

This is the most important section for me to get right.

1. Thinking Mode for causal chain reasoning — not summarization

Standard completion models count keywords. Gemma 4’s Thinking Mode traces why patterns emerged. When it sees 14 “fix” commits targeting ReactFiberHooks.js in a 3-week window after a large API change, it connects them causally — it doesn’t just report a spike.

The live reasoning stream in the UI makes this directly observable. Judges (and users) can watch Gemma’s chain-of-thought in real time. This is the intentional use criterion — not decorative AI, but AI whose reasoning process is the deliverable.

2. 128K context — the archaeology window

180 commits × ~200 tokens each = ~36K tokens of compressed history in one request. No chunking, no context loss, no multi-call stitching. Gemma 4 holds the full narrative arc in one reasoning window, which is the only way to detect multi-month causal patterns (e.g., a March 2019 API change causing a June 2019 bug cluster).

3. Structured output drives the UI deterministically

The JSON schema is strict (Pydantic v2 validated). If Gemma returns valid JSON, the timeline renders. If not, the error is surfaced honestly. No post-processing guesswork.

4. Privacy-first by design

Git history contains proprietary code, unreleased feature names, security patches, and competitive intelligence in commit messages. CodeDNA passes everything under your own API key. Zero data retention. This is not a UX choice — it’s the only architecture engineering teams will actually trust with real repositories.

Demo: React Hooks Era (2018–2019)

I ran CodeDNA on React’s public git history during the Hooks transition — one of the most architecturally significant periods in any major open-source project.

What Gemma 4 found:

  • 2018-07: Feature burst — Scheduler time-slicing and Fiber pool infrastructure added (5 commits, Scheduler.js dominant)
  • 2018-09–10: Pivot — React.lazy, Suspense, and createContext v2 introduced across 6 commits
  • 2019-01–02: Stability → Bug storm — 4 rapid fixes for useRef and useEffect infinite loops following the 16.8.0 release
  • 2019-05: Feature burst — useTransition, useDeferredValue, unstable_createRoot (5 commits, ReactFiberHooks.js dominant)

Health score: 58/100 — justified by 21% bug-fix ratio, two high-severity bug storms in 2019-01 and 2019-02, partially offset by clear feature burst eras and high commit message quality (83% of commits have descriptive messages ≥8 words).

Quick Start

# Clone
git clone https://github.com/acchasujal/codeDNA.git
cd codeDNA

# Backend
cd backend
pip install -r requirements.txt
cp .env.example .env
# Add your Google AI Studio key as GEMINI_API_KEY
uvicorn main:app --reload

# Frontend (new terminal)
cd ../frontend
npm install
npm run dev
# Opens http://localhost:5173

Get your git log:

# Any repo you have locally:
git log --stat | head -3000 > my_history.txt
# Upload the .txt file or paste directly

# React demo (what the screenshots use):
git clone https://github.com/facebook/react
cd react
git log --stat --after="2018-09-01" --before="2019-06-01" | head -3000 > react_hooks.txt

.env.example:

GEMINI_API_KEY=your_google_ai_studio_key_here
GEMMA_MODEL=models/gemma-4-26b-a4b-it
MAX_COMMITS=180
OPENROUTER_API_KEY=optional_for_fallback

Technical Highlights

Multi-provider fallback chain — At startup, CodeDNA queries the OpenRouter API to dynamically discover available Gemma models and builds a priority chain. Google AI Studio is primary; OpenRouter provides up to 9 additional Gemma models as fallback. The chain is logged at startup so you always know what’s running.

Preprocessor intelligence — Before any model call, the preprocessor extracts a MONTHLY_COMMIT_COUNTS histogram and TOP_CHANGED_FILES list from the raw git log. This ground-truth metadata is injected directly into the prompt, so Gemma cites real numbers (“commit count tripled to 47 in March 2019”) rather than inferring from prose.

Anti-fluff enforcement — The system prompt contains an explicit FORBIDDEN_PHRASES list ("technical debt", "the team", "seems like", "likely indicates", and 12 others). Every insight must cite a specific commit hash, date, file name, or count — or say “insufficient evidence.”

Honest confidence — Every milestone includes a confidence field (high | medium | low) with a justification sentence. Low-quality commit histories get a QUALITY_WARNING header and produce conservative, clearly-labeled micro-analyses rather than dramatic fabrications.

The Reasoning System Prompt

The full prompt that drives Step 1 (the reasoning stream):

See the REASONING_SYSTEM_PROMPT

You are CodeDNA, a concise git-history analyst.
Produce a clean public report, not private reasoning.

Rules:
- Output markdown prose only. No JSON. No code fences.
- No meta-commentary, self-correction, planning notes, or internal monologue.
- Never write "wait", "I used", "the prompt says", or any phrase from this
  forbidden list: technical debt, the team, engineers, developers, working hard,
  prioritized, decided to, management, business logic, seems like, appears to,
  it looks like, likely indicates, possibly, perhaps, might have.
- Use only observable evidence from the metadata header and commit log.
- Cite commit hashes, dates/months, file names, commit counts, and ratios
  whenever making a claim.
- If evidence is thin, say "insufficient evidence" and name the missing signal.
  Do not invent intent, people, architecture, risk, or causality.
- Keep every sentence useful. Avoid repetition.

Format exactly:
## Overview
Two to three factual sentences covering commit count, date range,
most changed files or file types, and BUG_FIX_RATIO.

## Milestones
Four to eight bullets when evidence allows. Each bullet:
- **YYYY-MM** - type - concise evidence sentence with commit hash(es),
  changed file(s), and count(s).
  Allowed types: bug_storm, refactor, pivot, feature_burst, stability.

## Health Signals
Three bullets: one positive signal, one negative signal, one confidence note.
Each bullet must cite evidence.

## Churn Summary
One concise sentence naming the peak period and the files or commits behind it.

The Hardest Problem: Making Gemma Say Something Real

The biggest technical challenge wasn’t the UI, the SSE streaming, or the fallback chain. It was getting Gemma 4 to produce specific, verifiable insights instead of confident-sounding nonsense.

Here’s what the first version produced on a repo with commits like "fix navbar bug", "update readme", "refactor utils":

“This period reflects a time of organizational growth and technical maturity. The team worked hard to address accumulated complexity while balancing feature delivery with stability concerns.”

That output is useless. It contains zero commit references, zero file names, zero numbers. A junior consultant could have written it without looking at the code. A judge would mark it dead on arrival.

Three iterations to fix it.

Iteration 1 — Forbidden phrases list.
Added an explicit blocklist to the system prompt:

FORBIDDEN PHRASES — never use these:
"technical debt", "the team", "engineers", "developers",
"working hard", "prioritized", "decided to", "management",
"seems like", "appears to", "it looks like", "likely indicates",
"possibly", "perhaps", "might have"

The output became less flowery but still vague: “There were many fixes in early 2019.” How many? Which files? Which period exactly?

Iteration 2 — Mandatory evidence citation.
Added to the prompt: “Every milestone description must cite at least one commit hash, date/month, file name, count, or ratio. If you cannot cite evidence, write ‘insufficient evidence’ and stop.”

Better, but Gemma was still counting commits itself — and sometimes miscounting.

Iteration 3 — Pre-computed metadata injection (the breakthrough).

Instead of asking Gemma to figure out what happened, I tell it what happened and ask it to interpret it.

The preprocessor now builds a metadata header before any model call:

# META: 180tot|180ana|Q:HIGH|Fx:21%|Vg:0%
# DATES: 2019-06-20..2018-07-02
# MONTHS: 2018-09:3,2018-10:3,2019-01:4,2019-02:2,2019-05:5,2019-06:2
# HOTSPOTS: ReactFiberHooks.js:8,Scheduler.js:5,package.json:4

Now instead of asking “were there a lot of fixes in early 2019?”, I’m asking “given that commits spiked to 5 in 2019-05 and ReactFiberHooks.js was modified 8 times — what does that pattern indicate?”

The model’s job shifted from counting to interpreting. The output became:

“2019-01 through 2019-02 saw 6 commits (bf32345, ca53456, cb54567, cc55678, cd56789, ce57890) concentrated in ReactFiberHooks.js and ReactFiberBeginWork.js. ca53456 fixed an incorrect useRef identity across re-renders; cb54567 resolved an infinite useEffect loop triggered by object dependency comparison. The 16.8.0 release on 2019-02-06 (cd56789) was followed two days later by ce57890 — a hooks state regression fix, indicating at least one edge case reached production.”

Every claim is checkable. Every hash is real. That’s the difference.

The map-reduce split was the second breakthrough.

Asking Gemma 4 to simultaneously produce flowing Thinking Mode prose and valid JSON produces neither well. I split it:

  • Step 1 (stream): REASONING_SYSTEM_PROMPT — output clean markdown only, no JSON, no schema constraints
  • Step 2 (analyze): JSON_SYSTEM_PROMPT — read the reasoning trace, output strict AnalysisResult JSON
    The reasoning panel now shows actual analytical prose. The timeline data is reliably structured. Both improved dramatically when separated.

Limitations (Honest)

  • Works best with 100–200 commits. Very large histories (1000+) need more aggressive preprocessing.
  • Commit message quality determines insight quality. A repo full of "fix", "wip", "update" commits will produce low-confidence analysis (CodeDNA tells you this clearly rather than inventing drama).
  • The reasoning stream uses the primary model; fallback models handle JSON structuring. If all Google models are slow, the stream may be empty — but the timeline will still render from the fallback result.
  • Currently runs locally only. Cloud deployment would require careful handling of API key security.

What’s Next

  • Actual GitHub API integration (analyze any public repo by URL, no manual log export)
  • Branch comparison (main vs. feature branch health)
  • Team velocity metrics (authors per period, bus factor analysis)
  • CI/CD integration — run CodeDNA as a PR check to flag risky commit patterns

Built solo in 4 days for the Google Gemma 4 Challenge. Every commit in this repo is real — you can run CodeDNA on its own history.

GitHub:

CodeDNA — AI Codebase Archaeologist

Feed Gemma 4 your git history. Discover exactly when — and why — your codebase evolved.

CodeDNA Demo

Every codebase has a turning point. The moment before is clean commits and clear intent
The moment after is hotfixes, reverts, and growing entropy. CodeDNA finds it.

What It Does

  • Maps your codebase history with Gemma 4 — up to 400 commits, preprocessed and compressed for maximum analytical signal. The preprocessor extracts monthly commit histograms and per-file change frequency before sending to the model, so insights are grounded in observable data.

  • Returns a structured archaeological report — health score with transparent breakdown, milestone timeline (bug storms, refactors, pivots, feature bursts), and key metrics. Every claim cites a specific commit hash, date, or metadata value.

  • Streams Gemma 4’s live reasoning — watch the Thinking Mode trace in real-time as the model identifies causal patterns across years of history. Verifiable: the…

Building a semantic search API in Go with Meilisearch

Full-text search is one of those features that looks simple until you have to ship it. Typos fail silently. Category filters conflict with relevance ranking. The database LIKE query that worked at 10,000 rows grinds to a halt at 100,000. This tutorial walks through building a real search API in Go using Fiber and Meilisearch, complete with filter support, typo tolerance configuration, and a MySQL LIKE fallback for resilience.

This is roughly the architecture running search across 1,600+ cybersecurity articles at AYI NEDJIMI Consultants.

Setup

go mod init search-api
go get github.com/gofiber/fiber/v2
go get github.com/meilisearch/meilisearch-go
go get github.com/go-sql-driver/mysql

Run Meilisearch:

docker run -d -p 7700:7700 
  -e MEILI_MASTER_KEY=your_master_key 
  getmeili/meilisearch:latest

Project structure

search-api/
├── main.go
├── config/
│   └── config.go
├── search/
│   ├── meili.go
│   └── fallback.go
└── handlers/
    └── search.go

Data model

// search/meili.go
package search

// Article is the document type stored in Meilisearch and MySQL.
type Article struct {
    ID         string   `json:"id"`
    Title      string   `json:"title"`
    Slug       string   `json:"slug"`
    Content    string   `json:"content"`    // plain text, stripped of HTML
    Category   string   `json:"category"`   // news, guide, analyse, blog, checklist
    Difficulty string   `json:"difficulty"` // beginner, intermediate, advanced
    DocType    string   `json:"doc_type"`   // article, checklist, glossary
    Tags       []string `json:"tags"`
    PublishedAt int64   `json:"published_at"` // Unix timestamp for sort
}

// SearchResult wraps hits with metadata.
type SearchResult struct {
    Hits             []Article `json:"hits"`
    TotalHits        int64     `json:"total_hits"`
    ProcessingTimeMs int64     `json:"processing_time_ms"`
    Query            string    `json:"query"`
    Source           string    `json:"source"` // "meilisearch" or "mysql_fallback"
}

Meilisearch client initialization

// search/meili.go (continued)
package search

import (
    "fmt"
    "log"

    "github.com/meilisearch/meilisearch-go"
)

const IndexName = "articles"

type MeiliSearcher struct {
    client meilisearch.ServiceManager
    index  meilisearch.IndexManager
}

func NewMeiliSearcher(host, apiKey string) (*MeiliSearcher, error) {
    client := meilisearch.New(host, meilisearch.WithAPIKey(apiKey))

    // Verify connectivity
    if _, err := client.Health(); err != nil {
        return nil, fmt.Errorf("meilisearch unreachable at %s: %w", host, err)
    }

    s := &MeiliSearcher{client: client}
    if err := s.ensureIndex(); err != nil {
        return nil, err
    }
    return s, nil
}

func (s *MeiliSearcher) ensureIndex() error {
    // Get or create index
    idx, err := s.client.GetIndex(IndexName)
    if err != nil {
        task, err := s.client.CreateIndex(&meilisearch.IndexConfig{
            Uid:        IndexName,
            PrimaryKey: "id",
        })
        if err != nil {
            return fmt.Errorf("create index: %w", err)
        }
        s.client.WaitForTask(task.TaskUID, nil)
        idx, err = s.client.GetIndex(IndexName)
        if err != nil {
            return fmt.Errorf("get index after create: %w", err)
        }
    }
    s.index = idx
    return s.configureIndex()
}

func (s *MeiliSearcher) configureIndex() error {
    task, err := s.index.UpdateSettings(&meilisearch.Settings{
        SearchableAttributes: []string{
            "title",      // highest weight
            "tags",
            "content",    // lowest weight
        },
        FilterableAttributes: []string{
            "category",
            "difficulty",
            "doc_type",
        },
        SortableAttributes: []string{
            "published_at",
        },
        RankingRules: []string{
            "words",
            "typo",
            "proximity",
            "attribute",   // respects SearchableAttributes order
            "sort",
            "exactness",
        },
        TypoTolerance: &meilisearch.TypoTolerance{
            Enabled: func() *bool { b := true; return &b }(),
            MinWordSizeForTypos: meilisearch.MinWordSizeForTypos{
                OneTypo:  4,
                TwoTypos: 8,
            },
        },
        Pagination: &meilisearch.Pagination{
            MaxTotalHits: 10000,
        },
    })
    if err != nil {
        return fmt.Errorf("update settings: %w", err)
    }
    s.client.WaitForTask(task.TaskUID, nil)
    log.Println("Meilisearch index configured.")
    return nil
}

Index sync function

Call this on startup and hook it to your CRUD operations.

// search/meili.go (continued)

func (s *MeiliSearcher) IndexDocuments(articles []Article) error {
    if len(articles) == 0 {
        return nil
    }
    task, err := s.index.AddDocuments(articles, "id")
    if err != nil {
        return fmt.Errorf("add documents: %w", err)
    }
    s.client.WaitForTask(task.TaskUID, nil)
    log.Printf("Indexed %d documents.", len(articles))
    return nil
}

func (s *MeiliSearcher) DeleteDocument(id string) error {
    task, err := s.index.DeleteDocument(id)
    if err != nil {
        return fmt.Errorf("delete document %s: %w", id, err)
    }
    s.client.WaitForTask(task.TaskUID, nil)
    return nil
}

Search with filters

// search/meili.go (continued)

type SearchParams struct {
    Query      string
    Category   string
    Difficulty string
    DocType    string
    Limit      int64
    Offset     int64
}

func (s *MeiliSearcher) Search(params SearchParams) (*SearchResult, error) {
    if params.Limit <= 0 {
        params.Limit = 10
    }
    if params.Limit > 100 {
        params.Limit = 100
    }

    // Build filter expression
    var filters []string
    if params.Category != "" {
        filters = append(filters, fmt.Sprintf("category = %q", params.Category))
    }
    if params.Difficulty != "" {
        filters = append(filters, fmt.Sprintf("difficulty = %q", params.Difficulty))
    }
    if params.DocType != "" {
        filters = append(filters, fmt.Sprintf("doc_type = %q", params.DocType))
    }

    filterStr := ""
    for i, f := range filters {
        if i == 0 {
            filterStr = f
        } else {
            filterStr += " AND " + f
        }
    }

    req := &meilisearch.SearchRequest{
        Limit:  params.Limit,
        Offset: params.Offset,
        AttributesToRetrieve: []string{
            "id", "title", "slug", "category",
            "difficulty", "doc_type", "tags", "published_at",
        },
        // Don't return full content in search results
    }
    if filterStr != "" {
        req.Filter = filterStr
    }

    resp, err := s.index.Search(params.Query, req)
    if err != nil {
        return nil, err
    }

    hits := make([]Article, 0, len(resp.Hits))
    for _, h := range resp.Hits {
        // Meilisearch returns hits as map[string]interface{}
        b, _ := json.Marshal(h)
        var a Article
        if err := json.Unmarshal(b, &a); err == nil {
            hits = append(hits, a)
        }
    }

    return &SearchResult{
        Hits:             hits,
        TotalHits:        resp.TotalHits,
        ProcessingTimeMs: resp.ProcessingTimeMs,
        Query:            params.Query,
        Source:           "meilisearch",
    }, nil
}

MySQL fallback

When Meilisearch is down (restart, OOM, maintenance), fall back to MySQL LIKE. It’s slower and has no typo tolerance, but it keeps the API responding.

// search/fallback.go
package search

import (
    "database/sql"
    "fmt"
    "strings"
    "time"

    _ "github.com/go-sql-driver/mysql"
)

type MySQLFallback struct {
    db *sql.DB
}

func NewMySQLFallback(dsn string) (*MySQLFallback, error) {
    db, err := sql.Open("mysql", dsn)
    if err != nil {
        return nil, err
    }
    db.SetMaxOpenConns(10)
    db.SetConnMaxLifetime(5 * time.Minute)
    return &MySQLFallback{db: db}, nil
}

func (m *MySQLFallback) Search(params SearchParams) (*SearchResult, error) {
    query := "%" + strings.ReplaceAll(params.Query, "%", "\%") + "%"

    args := []interface{}{query, query}
    where := "WHERE (title LIKE ? OR content LIKE ?)"

    if params.Category != "" {
        where += " AND category = ?"
        args = append(args, params.Category)
    }
    if params.Difficulty != "" {
        where += " AND difficulty = ?"
        args = append(args, params.Difficulty)
    }
    if params.DocType != "" {
        where += " AND doc_type = ?"
        args = append(args, params.DocType)
    }

    // Count total
    var total int64
    countSQL := fmt.Sprintf("SELECT COUNT(*) FROM articles %s", where)
    _ = m.db.QueryRow(countSQL, args...).Scan(&total)

    // Fetch page
    args = append(args, params.Limit, params.Offset)
    rows, err := m.db.Query(
        fmt.Sprintf(`SELECT id, title, slug, category, difficulty, doc_type, published_at
                     FROM articles %s ORDER BY published_at DESC LIMIT ? OFFSET ?`, where),
        args...,
    )
    if err != nil {
        return nil, err
    }
    defer rows.Close()

    var hits []Article
    for rows.Next() {
        var a Article
        if err := rows.Scan(&a.ID, &a.Title, &a.Slug,
            &a.Category, &a.Difficulty, &a.DocType, &a.PublishedAt); err != nil {
            continue
        }
        hits = append(hits, a)
    }

    return &SearchResult{
        Hits:      hits,
        TotalHits: total,
        Query:     params.Query,
        Source:    "mysql_fallback",
    }, nil
}

HTTP handler

// handlers/search.go
package handlers

import (
    "encoding/json"
    "log"

    "github.com/gofiber/fiber/v2"
    "search-api/search"
)

type SearchHandler struct {
    meili    *search.MeiliSearcher
    fallback *search.MySQLFallback
}

func NewSearchHandler(meili *search.MeiliSearcher, fallback *search.MySQLFallback) *SearchHandler {
    return &SearchHandler{meili: meili, fallback: fallback}
}

func (h *SearchHandler) Handle(c *fiber.Ctx) error {
    params := search.SearchParams{
        Query:      c.Query("q", ""),
        Category:   c.Query("cat", ""),
        Difficulty: c.Query("diff", ""),
        DocType:    c.Query("type", ""),
        Limit:      int64(c.QueryInt("limit", 10)),
        Offset:     int64(c.QueryInt("offset", 0)),
    }

    if len([]rune(params.Query)) > 200 {
        return c.Status(fiber.StatusBadRequest).JSON(fiber.Map{
            "error": "query too long",
        })
    }

    result, err := h.meili.Search(params)
    if err != nil {
        log.Printf("Meilisearch error: %v — falling back to MySQL", err)
        result, err = h.fallback.Search(params)
        if err != nil {
            return c.Status(fiber.StatusInternalServerError).JSON(fiber.Map{
                "error": "search unavailable",
            })
        }
    }

    return c.JSON(result)
}

Wiring it up in main.go

// main.go
package main

import (
    "log"
    "os"

    "github.com/gofiber/fiber/v2"
    "search-api/handlers"
    "search-api/search"
)

func main() {
    meiliHost := os.Getenv("MEILI_HOST")       // e.g. "http://127.0.0.1:7700"
    meiliKey  := os.Getenv("MEILI_MASTER_KEY")
    mysqlDSN  := os.Getenv("MYSQL_DSN")        // e.g. "user:pass@tcp(127.0.0.1:3306)/dbname"

    meili, err := search.NewMeiliSearcher(meiliHost, meiliKey)
    if err != nil {
        log.Fatalf("Failed to connect to Meilisearch: %v", err)
    }

    fallback, err := search.NewMySQLFallback(mysqlDSN)
    if err != nil {
        log.Fatalf("Failed to connect to MySQL: %v", err)
    }

    app := fiber.New(fiber.Config{
        ErrorHandler: func(c *fiber.Ctx, err error) error {
            return c.Status(fiber.StatusInternalServerError).JSON(fiber.Map{
                "error": err.Error(),
            })
        },
    })

    searchHandler := handlers.NewSearchHandler(meili, fallback)
    app.Get("/api/search", searchHandler.Handle)

    // Reindex endpoint (protect with auth middleware in production)
    app.Post("/admin/search/reindex", func(c *fiber.Ctx) error {
        var articles []search.Article
        if err := c.BodyParser(&articles); err != nil {
            return c.Status(fiber.StatusBadRequest).JSON(fiber.Map{"error": err.Error()})
        }
        if err := meili.IndexDocuments(articles); err != nil {
            return c.Status(fiber.StatusInternalServerError).JSON(fiber.Map{"error": err.Error()})
        }
        return c.JSON(fiber.Map{"indexed": len(articles)})
    })

    log.Fatal(app.Listen(":4001"))
}

Test it

# Basic search
curl "http://localhost:4001/api/search?q=pentest"

# With filters
curl "http://localhost:4001/api/search?q=NIS+2&cat=guide&diff=intermediate&limit=5"

# Typo tolerance in action
curl "http://localhost:4001/api/search?q=penetartion+tesitng"

Key tuning decisions

SearchableAttributes order matters. Meilisearch’s attribute ranking rule rewards matches in earlier attributes. Putting title first means a title match outranks a content match, which is almost always what you want.

Pagination cap. The MaxTotalHits: 10000 setting prevents Meilisearch from doing expensive full-index scans for pagination deep into results. If users never go past page 20 at 10 results/page, set this to 200.

Fallback opacity. The source field in SearchResult tells the frontend (and your monitoring) when it’s getting degraded results. Log every fallback occurrence — if Meilisearch is down and you’re not paged, you won’t know until users complain.

On-startup sync. Pull all published articles from MySQL on startup and call IndexDocuments. For 10,000+ documents this takes 2–5 seconds; for 100,000+ batch in chunks of 5,000. This ensures your index is always consistent even after a Meilisearch restart.

This pattern — Meilisearch primary, MySQL LIKE fallback — gives you production-grade search with no single point of failure and a codebase any Go developer can reason about.

April 2026 DigitalOcean Tutorials: Inference Optimization and AI Infrastructure

RAG System architecture

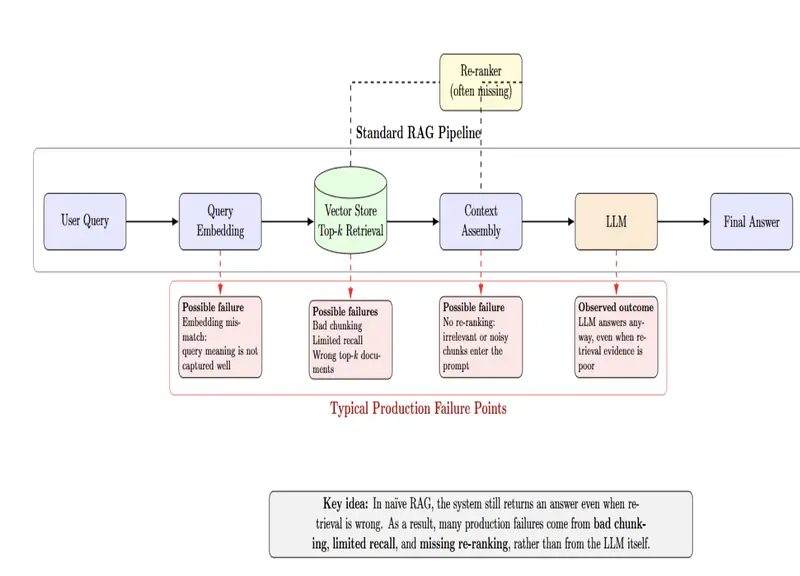
Most AI teams hit the same walls once they move past prototyping. The RAG pipeline that worked flawlessly in a demo starts hallucinating under real traffic. Inference costs climb without clear optimization levers. GPU resources sit underutilized while workloads spike elsewhere.

Most of the time, the root cause traces back to architecture decisions that weren’t pressure-tested for production. This month’s DigitalOcean tutorials focus on diagnosing and fixing those failure points across the AI infrastructure stack.

Why RAG Systems Fail in Production

Why do seemingly solid RAG demos collapse under real-world conditions? This article traces failures back to retrieval quality, latency tradeoffs, and embedding drift. You’ll get a clear picture of how upstream decisions—such as chunking strategy and ranking—directly affect downstream LLM outputs. If your team is building production pipelines, evaluation, monitoring, and retrieval engineering matter just as much as model choice.

RAG System architecture

Dedicated vs. Serverless Inference as You Scale

The choice between serverless and dedicated inference isn’t a one-time decision but an evolution driven by how your workload changes over time. Early on, serverless makes sense because traffic is unpredictable and iteration speed matters more than performance optimization. As usage stabilizes, the cracks show up—latency variability frustrates users and per-request pricing gets expensive for always-on systems. Walk-throughs of Modal and Together.ai show where that transition point hits and why delaying it costs you.

Fine-Tuned LLMs on Serverless Architecture

Parameter-efficient methods like LoRA let platforms serve hundreds of fine-tuned model variants from a single GPU by layering small adapter weights on top of a shared frozen base model. This makes serverless, pay-per-token inference possible for custom models without dedicated GPU deployments. The tradeoff is cold starts: idle adapters get evicted from VRAM and need to be reloaded, adding a few hundred milliseconds of latency to the first token. You’ll learn how to minimize that with keep-alive requests, adapter rank tuning, and smarter layer targeting.

The Silent Versioning Problem in AI Inference

This one is a cautionary tale about what happens when the model behind your endpoint changes and nobody tells you. The serving stack is full of moving parts that can shift independently of the model name, and the result is silent regressions that break prompt tuning and invalidate your evaluations before you even know something moved. It includes a practical buyer’s checklist for pressing inference platforms on snapshot pinning, retention commitments, and how they handle disclosure when something in the stack changes.

Silent versioning framework

The Hidden Bottlenecks in LLM Inference and How to Fix Them

Faster GPUs are not the answer if the rest of your serving stack can’t keep up. Spoiler: the bottlenecks are GPU underutilization from rigid batching, memory bandwidth constraints during decode, KV cache fragmentation, and CPU-side overhead from tokenization and prompt assembly. Click through for a deeper look at each one and practical fixes.

We Built a Private-Document AI App to Test Platform Security. Here Is What We Could Actually Verify

AI security should always be treated as a first-class concern, not an afterthought. This tutorial puts that to the test by building a private-document chatbot and running the same workflow across six inference platforms: DigitalOcean, Baseten, Nebius, Fireworks AI, Modal, and Together AI. Each platform is evaluated on access controls, data retention defaults, network isolation, audit logging, and shared responsibility clarity. It doubles as a practical framework for figuring out what you can actually verify before sensitive data is in flight.

Post-Inference Storage and Querying with MongoDB

Many inference tutorials stop at the model response. This one keeps going. You’ll build a FastAPI app that sends images through a vision model, stores the structured predictions in MongoDB, and then exposes endpoints that let you filter by detected labels and confidence scores or run aggregation pipelines across your full dataset. It’s a practical blueprint for turning raw model output into something queryable and operational.

How to Build a Multi-Agent AI System with Docker and DigitalOcean

Instead of routing everything through a single model, multi-agent systems let you split a workflow across specialized agents that each handle a different part of the problem and pass results between them. The tradeoff is coordination complexity. This walkthrough covers how to containerize each agent with Docker, manage communication between them, and deploy the full system on DigitalOcean. You’ll come away with a working deployment pattern you can adapt to your own orchestration needs.

Building an AI-Powered GPU Fleet Optimizer with the DigitalOcean AI Platform ADK

A single idle GPU Droplet left running overnight can add hundreds of dollars to your monthly bill, and standard CPU monitoring won’t catch it because it can’t see whether the GPU is actually doing work. This tutorial builds an AI-powered agent using the DigitalOcean AI Platform ADK that scrapes NVIDIA DCGM metrics like VRAM usage, engine utilization, and power draw across your fleet in real time. It compares those metrics against configurable thresholds to flag idle resources before they inflate your cloud spend. The repo is designed to be forked and customized to your own workloads, including adding tools that let the agent take action like powering off idle nodes.

Looking for DTMF transceiver module

I’m looking for a DTMF transceiver module compatible with Arduino.
So far I have not located one that uses the MT8880 chip which as a lot of support in the Arduino community. I hope you all can point me in the right direction.

DMARC Is Now a Proper Internet Standard: What Changed in RFC 9989/9990/9991

DMARC has been an Informational RFC since 2015. That changed this month.

RFC 9989 replaces RFC 7489 and elevates DMARC to Standards Track, reflecting over a decade of deployment experience and near-universal adoption across the email ecosystem. The spec was also split into three separate documents:

Splitting them allows each component to evolve independently. Here’s what changed.

The DNS Tree Walk Replaces the Public Suffix List

This is the most significant architectural change.

RFC 7489 used the Public Suffix List to determine organizational domain boundaries. To find the org domain for mail.example.co.uk, you’d look up co.uk in the PSL, then take one label to the left. It works, but the problems are real: external dependency, manual maintenance, potential staleness, no support for non-obvious namespace boundaries.

RFC 9989 introduces the DNS Tree Walk as the alternative. The algorithm walks up the DNS tree looking for _dmarc TXT records, starting from the sending domain and moving toward the root. It caps at eight queries to prevent DoS amplification.

For most domains this changes nothing operationally. For complex organizations with deep subdomain hierarchies, or operators running public suffix domains that want their own DMARC policies, it’s a meaningful improvement.

The new psd tag lets a domain declare itself as a Public Suffix Domain, enabling DMARC policy coverage at that level.

New Tags

t — Test Mode

Replaces the behavioral role of pct. Where pct=0 meant “apply policy to 0% of failing messages,” t=y explicitly signals that the policy is in test mode and shouldn’t be enforced.

The distinction between “policy exists but is being staged” and “policy is active against a subset of traffic” is now unambiguous.

v=DMARC1; p=quarantine; t=y; rua=mailto:[email protected]

np — Non-Existent Subdomain Policy

Allows separate policy handling for subdomains that have no DNS records at all. Previously, sp applied to all subdomains. Now you can distinguish between legitimate configured subdomains (sp) and mail claiming to originate from subdomains that don’t exist in DNS (np).

Non-existent subdomains sending mail are almost always spoofing, so np=reject is often the right default.

psd — Public Suffix Domain

Marks the domain as a Public Suffix Domain for the DNS Tree Walk algorithm.

Removed Tags

pct — Gone

Percentage-based partial enforcement has been removed. Use t=y for test mode instead.

rf — Report Format

Removed. Only AFRF format was ever widely implemented. The tag was vestigial.

ri — Report Interval

Removed. Aggregate reports are daily. The tag existed, receivers rarely honored it, and the spec now reflects reality.

Aggregate Reporting Changes (RFC 9990)

The aggregate reporting spec was extracted from RFC 7489 into its own document. The format remains XML with several refinements.

DKIM selector is now mandatory in reports. Previously optional, it’s required for understanding which DKIM key configuration is producing results — which matters for key rotation debugging.

New discovery method field indicates whether the receiver used psl or treewalk to find the organizational domain. Useful for diagnosing alignment issues during the transition period.

Extension framework allows future XML schema additions within defined namespaces without breaking existing parsers.

The schema changes are backward-compatible. Well-formed RFC 7489 reports will still parse. If you’re running your own DMARC report parser, the new fields are additive.

Failure Reporting Changes (RFC 9991)

The changes here are more significant for implementors.

Identity-Alignment is now a mandatory ARF header. Failure reports must include this field listing which authentication mechanisms failed to produce an aligned pass, or none if all passed. This was absent from the original spec, leading to inconsistent implementations.

Rate limiting is now required. RFC 9991 explicitly mandates that report generators implement rate limits. This closes a known gap: failure reports can be triggered by an attacker sending large volumes of spoofed mail, making an unrated reporting system a DoS amplification vector.

dmarc is now a formal ARF authentication failure type. The Authentication-Failure ARF header now includes dmarc as a valid type value alongside the existing dkim and spf types.

Privacy guidance is significantly expanded. The document adds detailed guidance on PII redaction, URI validation, and secure transport for failure reports. If you’re forwarding RUF reports to a third-party reporting service, the privacy section of RFC 9991 is worth reading before you do.

What You Actually Need to Do

For most domain owners, nothing changes immediately. RFC 9989 is backward-compatible with RFC 7489 and your existing DMARC record continues to work.

The practical checklist:

  • Remove pct tags from your DMARC records. Receiver behavior around deprecated tags will vary as implementations update.
  • If you’re using pct=0 for staged rollouts, move to t=y to signal test mode explicitly.
  • If you’re operating mail infrastructure (MTAs, DMARC reporting tools, monitoring systems), the Identity-Alignment requirement in RFC 9991 and the psd/treewalk changes in RFC 9989 require implementation updates.
  • Public Suffix Domain operators should evaluate adding psd=y once receiver support is established.

The Standards Track designation matters for enterprise and government procurement environments where “Informational RFC” raised compliance questions. DMARC is now a proper internet standard, not a proposal.

OpenTelemetry Is Now a CNCF Graduate — and It’s Coming for Your AI Stack

OpenTelemetry graduated as a CNCF project on May 21, 2026. That’s not just a badge — it’s the formal recognition that OTel has won the observability standards race. But graduation isn’t the finish line. The project is now squarely aimed at the AI infrastructure era, with GenAI semantic conventions already shipping in VS Code Copilot, OpenAI Codex, and Claude Code.

“Graduation is not the finish line. The OpenTelemetry community remains committed to building interoperable, high-quality observability standards and tooling for cloud native software at global scale.”
— OpenTelemetry project blog

What actually changed

  • CNCF graduation — OTel moved from incubating to graduated, joining Kubernetes, Prometheus, and a handful of other foundational cloud-native projects. This signals production-readiness and long-term stewardship.
  • Origins — formed from the merger of OpenTracing and OpenCensus, OTel has absorbed thousands of contributors across language SDKs, semantic conventions, and the Collector.
  • Declarative configuration went stable — a quieter but significant win: you can now configure the OTel Collector declaratively, which matters for GitOps and platform teams managing collectors at scale.
  • GenAI semantic conventions are in active use — the gen_ai.* attribute namespace standardises how LLM operations are recorded: model name, input/output token counts, finish reasons, tool calls, and (when opted in) full prompt/response content.
  • Major AI tools already emit OTel — VS Code Copilot, OpenAI Codex, and Claude Code all export OTel telemetry today. That’s not an aspiration — it’s already the default for the most-used AI coding tools.

Why this matters

OTel is the first observability framework that’s genuinely spanning both cloud-native infrastructure and AI workloads under a single standard. That’s a big deal.

Before the GenAI semantic conventions, monitoring an AI agent meant vendor-specific dashboards, proprietary SDKs, or rolling your own spans. Now you get a common schema — gen_ai.request.model, gen_ai.usage.input_tokens, gen_ai.client.operation.duration — that any OTLP-compatible backend can ingest and visualise.

The practical upside: if your AI agent takes 45 seconds to answer a question, you can now tell whether it was the model, a slow tool call, or a retry loop — without guessing. Token costs, latency histograms, and tool invocation traces all flow through the same pipeline you already run for your services.

The graduation timing is deliberate. OTel is establishing itself as the standard before the AI observability market fragments into proprietary tooling. That’s the same playbook it ran against Prometheus/Jaeger fragmentation in the cloud-native space.

What to do

If you’re building AI-powered apps:

  • Instrument with the GenAI semantic conventions now — they’re in use and under active development, so your feedback shapes what gets standardised.
  • Try the free Aspire Dashboard Docker image for local GenAI telemetry exploration — OTLP-native, no cloud account required.

If you’re a platform/infra engineer:

  • OTel Collector declarative config is now stable — worth revisiting your collector setup if you deferred it waiting for stability.
  • Check if your AI tooling already emits OTel (Copilot and Codex do) — you may have free telemetry sitting uncollected.

If you’re evaluating observability vendors:

  • Prioritise OTLP-native backends. Vendor lock-in via proprietary agents is increasingly a bad bet when the standard is this mature.

Sources: CNCF graduation announcement · OpenTelemetry blog · TNS analysis

✏️ Drafted with KewBot (AI), edited and approved by Drew.

OpenHuman Follows OpenClaw’s Rise, But With an Obsidian Brain

A few nights ago I watched someone demo OpenHuman from a folding table in a cramped apartment kitchen. Their laptop was surrounded by the normal sediment of modern technical life. Two half-drunk energy drinks. Browser tabs stacked into microscopic slivers. Discord notifications firing constantly. A local Ollama instance eating RAM in the background like a starving animal.

The weird part was not the agent itself.

The weird part was how naturally it seemed to inhabit the machine.

Not as a chatbot sitting inside a browser tab waiting politely for prompts. More like a persistent layer hanging around the operating system itself. Watching workflows accumulate. Compressing information. Building continuity from digital residue.

That feeling is why people keep comparing OpenHuman to OpenClaw, even though the projects are aiming at slightly different targets.

OpenClaw helped normalize the idea that desktop AI agents could feel immediate and tactile instead of purely experimental. It brought the whole “local desktop operator” concept out of research demos and into ordinary developer workflows.

OpenHuman follows directly behind it, but the philosophy underneath feels heavier. Less focused on action alone. More interested in persistence, memory architecture, and environmental awareness.

Not just an agent.

An accumulating cognitive system.

That distinction matters more than people realize.

The AI Industry Keeps Rebuilding Goldfish

One of the stranger problems in modern AI is how stateless everything still feels.

You can feed a system thousands of words about your work, habits, projects, tone, and environment, then close the window and watch the entire cognitive state disappear into vapor ten seconds later. Even products advertising “memory” often behave like glorified sticky notes taped onto transient systems.

OpenHuman approaches this differently.

According to the project documentation, it continuously fetches data from connected sources like GitHub, Gmail, calendars, local files, and chats, then compresses and stores them into markdown-based “Memory Trees.”

That little markdown detail changes the entire emotional texture of the project.

Because suddenly this starts sounding less like a chatbot and more like an Obsidian vault that became semi-sentient.

Local markdown.

Persistent memory.

Searchable context structures.

Continuous accumulation.

You can feel the influence of a generation of users who stopped trusting pure cloud abstraction and started organizing their cognition locally instead. Researchers. developers. obsessive note hoarders with twenty thousand interconnected documents sitting inside graph view.

OpenHuman understands something important:

People are not actually craving “AI.”

They are craving continuity.

They want systems that remember the shape of their digital life without forcing them to reconstruct context manually every morning.

That is the same instinct that helped OpenClaw spread so quickly.

Reduce friction between intention and execution.

Reduce friction between memory and workflow.

Reduce friction between human thought and machine state.

The 20 Minute Loop Changes Everything

One of the smartest design choices in OpenHuman is also one of the easiest to overlook.

The auto-fetch loop.

Every twenty minutes, the system can pull fresh information from connected sources and integrate it into its local memory structures.

That sounds small until you think about how fragmented modern cognition actually is.

Your life is not organized into neat prompts.

It leaks everywhere.

Terminal history. unfinished commits. screenshots. tabs you meant to read three days ago. Discord messages. bug reports. grocery reminders. PDFs opened at 2am and forgotten instantly afterward.

Most AI systems still force users to manually curate relevance.

OpenHuman instead tries to aggressively harvest context before you even ask for anything.

That changes the relationship entirely.

The agent starts feeling less like software you “use” and more like an informational organism quietly living beside your workflow.

And unlike a lot of AI marketing language right now, the project does not really pretend otherwise. The README openly describes connecting accounts and letting the system continuously fetch local context.

There is something refreshing about that honesty.

No mystical AGI theater.

Just infrastructure.

Memory compression.

Environmental awareness.

Accumulation.

OpenHuman Feels More Like an Operating Layer Than an Assistant

A lot of AI products still optimize for demos.

OpenHuman feels optimized for inhabitation.

That difference becomes obvious once you start looking at the tooling stack built directly into the project.

Filesystem access.

Git operations.

Web search.

Voice support.

Linting.

Testing.

Model routing.

Local inference integration through Ollama.

The average AI workflow in 2026 has become weirdly exhausting. Developers are juggling five subscriptions, multiple vector databases, disconnected memory layers, browser agents, shell agents, local models, remote APIs, and enough .env variables to qualify as emotional warfare.

Then one dependency updates overnight and the entire stack implodes.

OpenHuman is clearly trying to collapse that fragmentation into a single continuously running environment.

And honestly, that may be more important than benchmark performance.

The AI industry keeps treating models as products.

Increasingly, models are becoming infrastructure instead.

The real differentiator is the environment surrounding them.

The Model Routing Philosophy Is Quietly Smart

One of the more mature aspects of OpenHuman is how casually it treats model orchestration.

The system supports routing different tasks to different models depending on workload and capability. Lightweight tasks can use faster cheaper models. More reasoning-intensive tasks can escalate upward. Local inference can coexist with cloud inference.

That sounds technical and boring until you realize how important the philosophical shift actually is.

Most consumer AI products still pretend there is one singular intelligence behind the curtain.

But the future increasingly looks modular.

Different systems for different cognitive loads.

Fast pattern matching.

Slow reasoning.

Vision interpretation.

Background compression.

Tool execution.

Memory synthesis.

OpenHuman treats model selection as infrastructure rather than spectacle.

That is the correct direction.

The routing layer disappears into workflow instead of becoming part of the performance.

It feels closer to an operating system than a chatbot.

And weirdly enough, closer to how human cognition already functions.

TokenJuice Sounds Fake But It Solves a Real Problem

The funniest thing in the entire project might be the name “TokenJuice.”

It sounds like something invented during a sleep deprivation episode at 4:17am.

But the underlying idea is actually important.

Before information reaches the LLM, OpenHuman preprocesses and compresses it. HTML becomes markdown. unnecessary formatting gets stripped. URLs get shortened. noisy payloads get reduced.

This matters because token inefficiency is becoming one of the defining problems of agent systems.

A shocking amount of AI infrastructure right now basically functions like shipping companies transporting garbage across expensive context windows.

Massive bloated HTML payloads.

Duplicated formatting.

Navigation elements.

Unnecessary markup.

Dead weight everywhere.

OpenHuman appears unusually aware of this problem.

The project claims TokenJuice can reduce token usage dramatically, sometimes up to 80% depending on the workload.

Whether those exact numbers hold consistently across large-scale deployment is still unclear. The project remains early beta and moving quickly. But the architectural instinct is absolutely correct.

The next generation of AI systems probably will not win through sheer model size alone.

They will win through context efficiency.

Memory engineering.

Compression quality.

Retrieval precision.

The surrounding ecosystem matters more every month.

Local First Is Becoming Emotional Infrastructure

One reason OpenHuman resonates so strongly with developers right now has nothing to do with AI capability itself.

It is locality.

The software stores data locally. Uses SQLite persistence. Organizes information into markdown structures compatible with tools people already trust. Supports local inference through Ollama.

That changes the emotional relationship between user and machine.

Cloud-native software increasingly feels rented. Temporary. Subscription-shaped.

You do not fully inhabit those systems.

You borrow them.

Local-first software feels different.

You experiment more freely.

You build stranger workflows.

You stop worrying quite as much about whether the company maintaining the platform will pivot into nonsense six months later.

There is a reason older technical communities became emotionally attached to desktop software. The machine itself felt like territory.

OpenHuman taps into some of that feeling again.

Not nostalgically.

Functionally.

The Rough Edges Are Part of Why People Care

One thing I appreciate about OpenHuman is that it still feels unfinished in visible ways.

Not polished into corporate smoothness.

The README openly describes the project as early beta.

That honesty matters because the current AI ecosystem has become saturated with highly polished unreality. Beautiful launch videos covering fragile systems held together by API glue and investor optimism.

OpenHuman instead feels like an ambitious desktop project from an earlier era of computing.

Slightly unstable.

Deeply opinionated.

Built by people who clearly use the thing themselves.

Even the mascot interface contributes to that atmosphere a little. Not in an overdesigned corporate way. More like software created by developers who still think computers are supposed to feel personal.

Underneath all of that sits the actual important shift:

persistent contextual memory.

That is the real story here.

Not the mascot.

Not the agent hype.

Memory architecture.

OpenHuman Reveals Where Desktop AI Is Heading

I do not think projects like OpenHuman are important because they represent finished products.

They matter because they expose trajectory.

The first wave of consumer AI treated intelligence itself as the product. Bigger models. smarter responses. increasingly theatrical reasoning demos.

The next wave appears far more interested in continuity.

Persistent memory.

Environmental awareness.

Context accumulation.

Long-term workflow integration.

Artificial familiarity.

And honestly, that may reshape daily computing faster than AGI ever does.

Because most people do not need a godlike intelligence living inside their laptop.

They need a system that remembers where they left things.

A system that understands continuity between fragments.

A system that can exist beside their actual life instead of resetting every session like a concussed intern.

That is the feeling OpenHuman is chasing.

Not pure intelligence.

Residency.

The machine remaining there long enough to develop informational gravity.

And if OpenClaw helped normalize the idea that local desktop agents could act, OpenHuman may end up normalizing the idea that they can remember too.

Further Reading

If you’re experimenting with OpenHuman locally and want something more practical than endless GitHub issue archaeology, The Desktop Operator’s Guide to OpenHuman: Local Inference, Model Routing, and Stable Deployment is one of the better deployment-focused breakdowns floating around right now. It stays grounded in actual workflow setup instead of drifting into generic AI futurism.

OpenHuman GitHub README

OpenHuman Repository

Build a Live Flight Radar in a Single HTML File

One HTML file. No npm, no frameworks, no backend. Open it in a browser and watch live aircraft move across an interactive map.

We’ll use Leaflet.js for the map and a free aviation API for real-time ADS-B positions. The whole thing is under 100 lines of code, and the planes update every 30 seconds.

What We’re Building

An interactive radar-style map that:

  • Shows live aircraft positions over any region you choose
  • Rotates plane icons to match actual heading
  • Color-codes planes by altitude (green → yellow → red)
  • Displays flight number, route, speed and altitude on click
  • Auto-refreshes every 30 seconds without reloading the page

Before You Start

Grab a free API key from AirLabs — takes 30 seconds, no credit card. Their free tier returns real-time lat/lng, heading, altitude, speed, and route data, which is everything we need for a map.

The Full Code

I’ll show the complete file first, then walk through how it works. Create a file called radar.html, paste this in, replace YOUR_API_KEY, and open it in your browser:

<!DOCTYPE html>
<html>
<head>
<meta charset="utf-8">
<title>Live Flight Radar</title>
<meta name="viewport" content="width=device-width, initial-scale=1">
<link rel="stylesheet" href="https://unpkg.com/[email protected]/dist/leaflet.css">
<script src="https://unpkg.com/[email protected]/dist/leaflet.js"></script>
<style>
  * { margin: 0; padding: 0; box-sizing: border-box; }
  body { background: #0a0a1a; font-family: monospace; }
  #map { width: 100vw; height: 100vh; }
  #hud {
    position: fixed; top: 16px; left: 16px; z-index: 999;
    background: rgba(10,10,26,0.85); color: #8cf;
    padding: 10px 16px; border-radius: 8px;
    font-size: 13px; pointer-events: none;
    border: 1px solid rgba(100,180,255,0.2);
  }
  #hud b { color: #fff; }
</style>
</head>
<body>
<div id="hud">
  Flights: <b id="count">—</b> &nbsp;|&nbsp;
  Updated: <b id="time">—</b> &nbsp;|&nbsp;
  Next refresh: <b id="tick">30</b>s
</div>
<div id="map"></div>

<script>
const API_KEY = "YOUR_API_KEY";
const BBOX    = [44, 2, 52, 20];      // Central Europe — change to your region
const REFRESH = 30;                    // seconds between updates

// --- MAP SETUP ---
const map = L.map("map", {
  center: [(BBOX[0]+BBOX[2])/2, (BBOX[1]+BBOX[3])/2],
  zoom: 6,
  zoomControl: false
});

L.tileLayer("https://{s}.basemaps.cartocdn.com/dark_all/{z}/{x}/{y}{r}.png", {
  attribution: '&copy; OpenStreetMap &copy; CARTO',
  maxZoom: 18
}).addTo(map);

L.control.zoom({ position: "bottomright" }).addTo(map);

// --- PLANE ICON FACTORY ---
function planeIcon(dir, alt) {
  let color;
  if (alt == null)    color = "#888";
  else if (alt < 3000) color = "#2ecc71";
  else if (alt < 8000) color = "#f1c40f";
  else                 color = "#e74c3c";

  return L.divIcon({
    className: "",
    iconSize: [22, 22],
    iconAnchor: [11, 11],
    html: `<div style="
      font-size:18px; color:${color};
      transform:rotate(${dir || 0}deg);
      text-shadow:0 0 4px ${color}44;
      line-height:22px; text-align:center;
    ">✈</div>`
  });
}

// --- POPUP ---
function popupHTML(f) {
  const flight = f.flight_iata || f.hex || "—";
  const route  = `${f.dep_iata || "?"} → ${f.arr_iata || "?"}`;
  const altFt  = f.alt ? Math.round(f.alt * 3.281).toLocaleString() : "—";
  const kts    = f.speed ? Math.round(f.speed * 0.54) : "—";
  return `<div style="font-family:monospace;font-size:13px;min-width:150px">
    <b style="font-size:15px">${flight}</b><br>
    ${route}<br>
    ✈ ${f.aircraft_icao || "—"}<br>
    ↑ ${altFt} ft &nbsp; → ${kts} kts
  </div>`;
}

// --- STATE ---
let markers = [];

async function fetchFlights() {
  const url = `https://airlabs.co/api/v9/flights`
    + `?api_key=${API_KEY}`
    + `&bbox=${BBOX.join(",")}`
    + `&_fields=hex,flag,lat,lng,dir,alt,speed,flight_iata,dep_iata,arr_iata,aircraft_icao`;

  try {
    const res = await fetch(url);
    const json = await res.json();
    const flights = json.response || [];

    // clear old markers
    markers.forEach(m => map.removeLayer(m));
    markers = [];

    flights.forEach(f => {
      if (!f.lat || !f.lng) return;
      const m = L.marker([f.lat, f.lng], {
        icon: planeIcon(f.dir, f.alt)
      }).bindPopup(popupHTML(f));
      m.addTo(map);
      markers.push(m);
    });

    // update HUD
    document.getElementById("count").textContent = flights.length;
    document.getElementById("time").textContent =
      new Date().toLocaleTimeString();
  } catch (err) {
    console.error("Fetch failed:", err);
  }
}

// --- REFRESH LOOP ---
let countdown = REFRESH;

fetchFlights();  // first load

setInterval(() => {
  countdown--;
  document.getElementById("tick").textContent = countdown;
  if (countdown <= 0) {
    countdown = REFRESH;
    fetchFlights();
  }
}, 1000);
</script>
</body>
</html>

That’s the entire thing. Let’s break it down.

How It Works

The Map

We initialize Leaflet with CARTO’s dark basemap — it gives that clean radar aesthetic, and it’s free. The map centers automatically on whatever bounding box you configure.

const BBOX = [44, 2, 52, 20]; // south-lat, west-lng, north-lat, east-lng

Change this to any region you want:

  • USA (lower 48): [24, -125, 50, -66]
  • Southeast Asia: [-10, 95, 25, 145]
  • UK + Ireland: [49, -11, 60, 2]
  • Middle East: [12, 32, 42, 62]
  • Your city: grab coordinates from Google Maps, add ±2 degrees

The API Call

One fetch() to the AirLabs /flights endpoint with a bounding box filter:

const url = `https://airlabs.co/api/v9/flights`
  + `?api_key=${API_KEY}`
  + `&bbox=${BBOX.join(",")}`
  + `&_fields=hex,flag,lat,lng,dir,alt,speed,flight_iata,dep_iata,arr_iata,aircraft_icao`;

The _fieldsparameter limits the response to only what we need — keeps it fast. A typical European bounding box returns 500–1500 flights depending on time of day.

Plane Icons

Each plane is a Leaflet DivIcon — a rotated ✈ character. The dir field from the API gives heading in degrees, so we apply a CSS rotate() transform. Color is based on altitude:

Altitude Color Meaning
< 3,000m 🟢 Green Climbing or descending
3,000–8,000m 🟡 Yellow Mid-altitude
> 8,000m 🔴 Red Cruising altitude

Auto-Refresh

A simple setIntervalcounts down from 30 seconds. When it hits zero, it calls fetchFlights() again — clears old markers, fetches new positions, plots them. The HUD in the top-left shows the flight count, last update time, and countdown to next refresh.

No WebSockets, no server, no state management. Just clear and redraw.

Customization Ideas

Filter by airline — add &airline_iata=UA to the URL to show only United Airlines flights. Great for monitoring a specific carrier.

Departure board — swap /flights for /schedules?dep_iata=JFK to build a live airport departure board. Returns gate, terminal, delay, and status.

Draw flight paths — when user clicks a plane, fetch the route with /routes?dep_iata=${dep}&arr_iata=${arr} and draw a great-circle arc between the airports using Leaflet’s polyline.

Add airports — fetch /airports?_fields=iata_code,name,lat,lng and plot them as circles on the map. Now your radar has reference points.

Mobile PWA — wrap this HTML in a simple service worker and add a manifest. You’ve got a progressive web app that works offline (minus the live data) and installs on your home screen.

Deployment

This is a single HTML file with zero dependencies (Leaflet loads from CDN). You can:

  • GitHub Pages — push radar.html as index.html, enable Pages, done
  • Netlify / Vercel — drag and drop the file
  • Literally any web server — it’s static HTML

One caveat: the API key is visible in client-side code. For a personal project or portfolio demo, this is fine — just use the free tier key and don’t worry about it. For production, proxy the request through a small serverless function (Cloudflare Workers or Vercel Edge work great for this).

The entire project is 93 lines of HTML/CSS/JS. No build step, no node_modules, no dependencies to update. Just a file that shows you where every plane in the sky is, right now.