Dronla bozayıları sürüden uzaklaştırdı

Erzincan’ın Refahiye ilçesinde hayvancılıkla uğraşan Baki Kaya, sürüsüne yaklaşan 3 bozayıyı dron kullanarak bölgeden uzaklaştırdı. Teknolojinin hayvancılıkta güvenlik amaçlı kullanımına örnek olan olayda ayılar doğal yaşam alanına döndü.

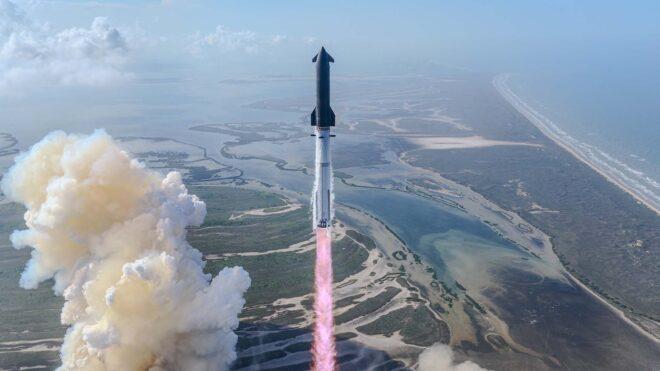
SpaceX, “Starship V3” denemesinden harika videolar paylaştı

SpaceX, Starship V3 denemesinden harika videolar paylaştı

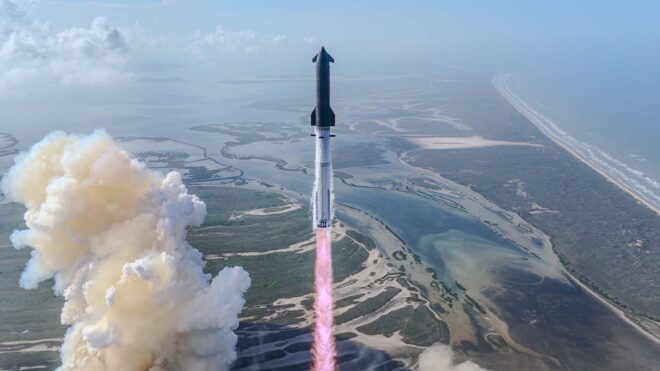
SpaceX, Starship V3 denemesinden harika videolar paylaştıElon Musk’ın başarılı özel uzay şirketi SpaceX, bu sefer geçtiğimiz saatlerde gerçekleştirilen Starship V3 denemesiyle dikkat çekti. Dünyanın en güçlü roketinin son sürümü için yapılan ilk denemeyi, uzaydan internet sunan Starlink’ten güç alınan altyapıyla kayıt altına alan SpaceX, resmi X hesabından hem dışta hem de roketin üstünde çekilen nefes kesici videolar paylaştı. Deneme kapsamında yörüngeye test amaçlı Starlink uyduları bırakan şirket, Starship’i gerçek ticari görevlere hazırlamaya devam ediyor. Liftoff of Starship! pic.twitter.com/LQLdjK5V6K — SpaceX (@SpaceX) May 22, 2026 Starship’s Raptor engines ignite during hot-staging separation pic.twitter.com/oNdU0Z4FQI — SpaceX (@SpaceX) May 22, 2026 Live views brought to you by @Starlink pic.twitter.com/Rpn6XtHckU — SpaceX (@SpaceX) May 22, 2026 Starship is executing a banking maneuver that mimics the final approach it would take while returning to Starbase for a catch on a future mission pic.twitter.com/3YQr8LKAaj — SpaceX (@SpaceX) May 22, 2026 Splashdown confirmed! Congratulations to the entire SpaceX team on the twelfth flight […]
SpaceX, “Starship V3” denemesinden harika videolar paylaştı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

I’m a Front End Web Developer Learning Machine Learning From Scratch

Hey,

I’m a web developer – building UIs with React, TypeScript, Tailwind, and modern web tools. A few months ago, I decided to step into Machine Learning.
No prior ML background. Just curiosity and basic Python knowledge.I started Andrew Ng’s Machine Learning Specialization and created my own study plan. Here’s what the first 30 days looked like — the concepts that clicked, the mistakes I made, and what surprised me most.

Week 1: Building the Math Foundation
I started with prerequisites because they’re essential:

  • Linear Algebra (vectors, matrices, eigenvalues)
  • Calculus (derivatives, partial derivatives, gradients)
  • Probability & Statistics

Concept: Why Gradients Matter
Gradient descent is the engine behind almost all modern ML.
Imagine you’re trying to reach the bottom of a valley in the dark. The gradient tells you the direction and steepness of the slope. You take a small step downhill.

(w = w - learning_rate * gradient)

Repeat until you reach the minimum.
This simple idea powers neural networks, linear regression, and more.

Weeks 2–3: Supervised Learning (The Real Fun Begins)
I dove into regression and classification:

  • Linear & multiple linear regression
  • Logistic regression for classification
  • Cost functions, gradient descent, regularization, feature scaling, softmax

I built small projects in Colab:

  • House price predictor (linear regression)
  • Spam email classifier (logistic regression)

Concept: Regularization
Regularization is like putting guardrails on your model. Without it, the model can memorize noise in the training data (overfitting). With L2 regularization, we penalize large weights, helping the model generalize better.

Weeks 4–5: Neural Networks & Tree Ensembles
This is where things got exciting:

  • Built my first neural networks in TensorFlow (forward propagation + backpropagation)
  • Learned decision trees, Random Forests, and XGBoost

Concept: Backpropagation
Forward propagation makes a prediction.
Backpropagation figures out why the prediction was wrong and updates every weight accordingly using the chain rule. It’s like tracing a bug through a chain of React components — but for thousands of parameters.

What Surprised Me Most

  1. The math finally made sense when I saw it used in real models.
  2. Building small projects > passive watching.
  3. ML and web development are a powerful combination — I can already imagine turning these models into real web features.

What’s Next?
I’m continuing the plan:

  • More neural network practice
  • Full mini-projects
  • Course 3 (Unsupervised learning)

I’ll be sharing regular updates here — code, lessons, and notebooks. If you’re also learning ML as a web developer, drop a comment. I’d love to hear your journey too!

Laravel Waiting Request

The Problem

You are processing some data through background job. But before the processing is done, another request had been made to read the related data.

In this case you are either providing a historic data or serving wrong information.

Solution

Holding the request until the job is executed, could be the simplest solution.
I am not saying it is the only solution, but the simplest one.

Some Scenarios

Lets discuss about some possible scenarios.

Booking Job

When a user request to book a resource between two specifics dates. Let’s assume that it is done by a job. So it might take some time in production load.
In the meantime if another request is asking for that specific users booking data.

File Importing Job

User uploads a file like CSV or XML, you have accepted the file but it also needs processing, which should be done in by a job.
If the user ask for the status of the CSV resource in another request.

The Package

aihimel/laravel-waiting-request is a small Laravel package that solves exactly this — it lets one request park until another piece of work (a job, a sync, a long-running controller action) signals that the resource is ready to read.

Install

composer require aihimel/laravel-waiting-request

Optionally publish the config:

php artisan vendor:publish --tag="waiting-request-config"

How it works

The package exposes a tiny API around four ideas: block, wait, check, resolve. Under the hood it is backed by your Laravel cache — no extra infrastructure, no queue plumbing.

A blocker is identified by a class path and a resource id. That pair becomes a unique cache key, so blockers are per-resource (booking 42 does not interfere with booking 43).

use AihimelLaravelWaitingRequestFacadesLWRequest;

// 1. Block — call this where the background work *starts*
LWRequest::addBlocker(Booking::class, $booking->id);

// 2. Wait — call this in the request that wants to read the resource
$resolved = LWRequest::whenResolved(Booking::class, $booking->id);

if ($resolved) {
    return BookingResource::make($booking->fresh());
}

return response()->json(['message' => 'Still processing, try again'], 202);

// 3. Resolve — call this when the background work finishes
LWRequest::resolveBlocker(Booking::class, $booking->id);

You can also peek without waiting:

if (LWRequest::isBlocked(Booking::class, $booking->id)) {
    // resource is mid-flight
}

Applying it to the scenarios

Booking job. The controller that accepts the booking calls addBlocker(Booking::class, $id) and dispatches the job. The job calls resolveBlocker(...) in its handle() (or in a finally block). Any reader that hits GET /bookings/{id} in the meantime calls whenResolved(...) first and only reads the model once the writer is done.

File importing job. Same shape: addBlocker(Import::class, $import->id) when the upload is accepted, resolveBlocker(...) when the parser finishes (success or failure — both should release). The status endpoint calls whenResolved(...) so the client gets a settled answer instead of a half-imported snapshot.

Sensible defaults you can tune

Every knob lives in config/waiting-request.php and is overridable via env:

Config Env Default What it does
cache_prefix LW_REQUEST_CACHE_PREFIX lw_request_ Namespace for cache keys
timeout LW_REQUEST_MAX_WAITING_TIME 5 How long whenResolved() waits before giving up (seconds)
check_interval LW_REQUEST_CHECK_INTERVAL 250 Poll interval inside whenResolved() (milliseconds)
max_blocking_time LW_REQUEST_MAX_BLOCKING_TIME 10 Max lifetime of a blocker before it auto-expires (seconds)

addBlocker() takes an optional third argument so you can bump the TTL per call when you know a particular job runs longer:

LWRequest::addBlocker(Import::class, $import->id, 120); // 2 minutes

Why the blocker has a lifetime

If a job crashes before calling resolveBlocker(), you do not want readers to wait forever. From v2.x every blocker carries a Unix expiry timestamp. The next isBlocked() / whenResolved() call after that timestamp will:

  1. Forget the cache entry, and
  2. Emit Log::warning('Waiting-request blocker expired without being resolved', [...])

So even if your job dies, traffic recovers on its own and you get a log line telling you it happened.

Do’s and Don’ts

Do

  • Do release the blocker in finally. Wrap your job body so a thrown exception still hits resolveBlocker(). Auto-expiry is a backstop, not a happy path.
  • Do set max_blocking_time to comfortably exceed your worst-case job duration. If your import averages 8s and worst-cases at 25s, a 10s default will auto-release while the job is still running — defeating the lock.
  • Do tune timeout to match your UX budget. If a client is willing to wait 2s for a synchronous response, set timeout=2; do not let whenResolved() hold an HTTP worker for 30s.
  • Do flush the cache when upgrading from 1.x to 2.x. Pre-upgrade values stored as true will be read as 1, treated as already-expired, and produce a one-time burst of warning logs.
  • Do treat a false return from whenResolved() as “still pending”. Respond with 202 Accepted (or similar) and let the client poll — do not pretend the data is ready.

Don’t

  • Don’t put isBlocked() on a hot, read-only path you expect to be side-effect-free. It evicts expired entries and writes a log line. That is intentional, but worth knowing.
  • Don’t use it as a distributed mutex for writes. This package is for readers waiting on writers on a best-effort basis. If two writers race, Cache::add() will reject the second addBlocker() (it returns false), but the package does not give you queueing, fairness, or strict mutual exclusion.
  • Don’t share a single blocker across unrelated resources. Key it by the real resource (Booking::class + $id), not by something coarse like the user id, or you will block requests that have nothing to do with each other.
  • Don’t forget the cache driver matters. array or file drivers will not work across processes. In production, use redis / memcached so the worker that resolves the blocker and the web process that is waiting actually share the same cache.
  • Don’t lean on whenResolved() from a queue worker. Polling inside a worker burns a worker slot. Workers should resolve blockers, not wait on them.

That’s the whole package — a couple of facade calls, a cache key per resource, and a sane expiry so nothing wedges. If you’ve ever shipped a ?retry=true hack or a sleep-and-pray in a controller, this is the cleaner version of that.

Source & issues: github.com/aihimel/laravel-waiting-request

Samsung Galaxy Z Fold8 Wide için yeni paylaşımlar geldi

Samsung Galaxy Z Fold8 Wide için yeni paylaşımlar geldi

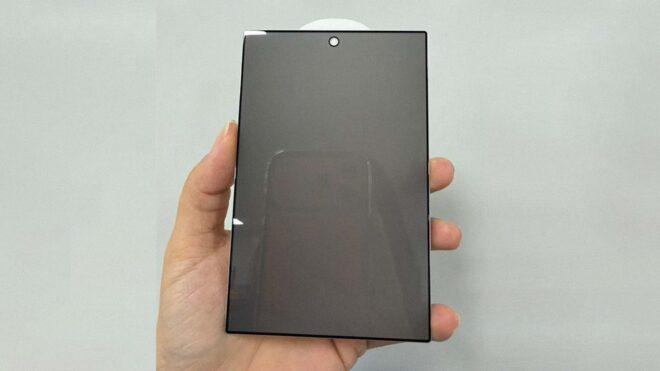
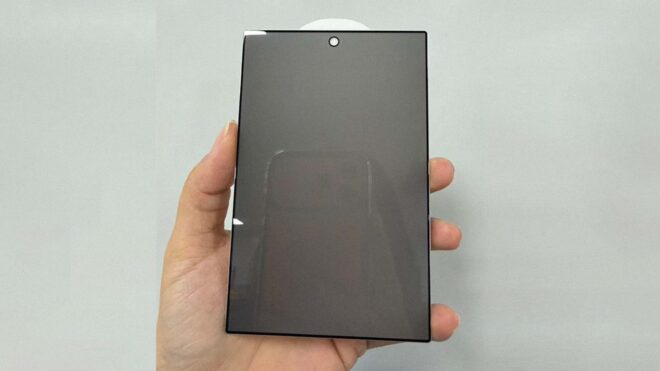
Samsung Galaxy Z Fold8 Wide için yeni paylaşımlar geldiGeniş yapısıyla fark yaratacak katlanabilir telefon modeli Samsung Galaxy Z Fold8 Wide (ismi farklı olabilir) için yeni paylaşımlar yapıldı. Ice Universe’ten gelen bu paylaşımlarda cihazın ekranını koruyacak cam karşımıza çıkıyor. Telefonun kapalı formdaki boyutunu ve elde duruşunu gözler önüne seren cam, Huawei Pura X Max’te kullanılan camla da yan yana getiriliyor. TechManiacs tarafından aktarılan bilgilere göre Galaxy Z Fold8 Wide modeli 45W şarj destekli 4.800 mAh batarya, 7,6 inç boyutunda katlanabilir iç ekran, 5,4 inç boyutunda dış ekran, Snapdragon 8 Elite Gen 5 işlemci, 200 gram gövde ağırlığı, 50 megapiksel geniş açı + 50 megapiksel ultra geniş açı taşıyan arka kamera sistemi ve iki farklı 10 megapiksellik selfie kamerası gibi teknik detaylarla geliyor. If we add a screen to this tempered glass protector for the Samsung Galaxy Z Fold8 Wide, its cover screen would basically look like the image on the right. Of course, the real device will not have […]

Samsung Galaxy Z Fold8 Wide için yeni paylaşımlar geldi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Why Google Can’t See Your React Breadcrumbs (And the 4-Line Fix)

I wasted an entire afternoon wondering why Google Search Console kept showing zero rich results for my React app. The breadcrumbs looked perfect in the browser. Users could see them. But Google? Completely blind. The problem wasn’t my breadcrumb component it was that I’d never told Google what those breadcrumbs actually were. Structured data. Four lines of JSON-LD. That was it. Here’s everything I learned, so you don’t lose the same afternoon.

Why React Breadcrumbs Are Invisible to Google

React apps render in the browser. Google’s crawler is getting better at parsing JavaScript, but structured data embedded in client-rendered markup is still unreliable for rich results. The gold standard for breadcrumb rich results in Google Search is JSON-LD schema markup injected into <head> not your visible DOM breadcrumb trail.

The two things are completely separate:

  • Your breadcrumb UI component what users see
  • Breadcrumb Schema markup what search engines read

Most tutorials show you how to build the UI. Almost none explain the schema side. That’s why your breadcrumbs look fine to you but don’t show up as rich results in Google.

Here’s what a valid BreadcrumbList schema looks like, per Schema.org:

{
  "@context": "https://schema.org",
  "@type": "BreadcrumbList",
  "itemListElement": [
    {
      "@type": "ListItem",
      "position": 1,
      "name": "Home",
      "item": "https://example.com"
    },
    {
      "@type": "ListItem",
      "position": 2,
      "name": "Blog",
      "item": "https://example.com/blog"
    },
    {
      "@type": "ListItem",
      "position": 3,
      "name": "My Article",
      "item": "https://example.com/blog/my-article"
    }
  ]
}

Your job is to get exactly this into a <script type="application/ld+json"> tag in <head> on every page that has breadcrumbs.

The Manual Approach: A Custom React Hook

If you’re not using any SEO library, here’s a clean, copy-paste hook that builds and injects breadcrumb schema based on your current route.

// hooks/useBreadcrumbSchema.js
import { useEffect } from "react";

export function useBreadcrumbSchema(crumbs) {
  useEffect(() => {
    const schema = {
      "@context": "https://schema.org",
      "@type": "BreadcrumbList",
      itemListElement: crumbs.map((crumb, index) => ({
        "@type": "ListItem",
        position: index + 1,
        name: crumb.label,
        item: crumb.url,
      })),
    };

    const script = document.createElement("script");
    script.type = "application/ld+json";
    script.id = "breadcrumb-schema";
    script.textContent = JSON.stringify(schema);

    // Remove any existing breadcrumb schema before inserting
    document.getElementById("breadcrumb-schema")?.remove();
    document.head.appendChild(script);

    return () => {
      document.getElementById("breadcrumb-schema")?.remove();
    };
  }, [crumbs]);
}

Then in your page component:

// pages/BlogPost.jsx
import { useBreadcrumbSchema } from "../hooks/useBreadcrumbSchema";

export default function BlogPost({ post }) {
  useBreadcrumbSchema([
    { label: "Home", url: "https://example.com" },
    { label: "Blog", url: "https://example.com/blog" },
    { label: post.title, url: `https://example.com/blog/${post.slug}` },
  ]);

  return <article>{/* your content */}</article>;
}

Result: Every time the component mounts, the correct JSON-LD block is injected into <head> and cleaned up on unmount. Paste it into Google’s Rich Results Test and you’ll see a green checkmark.

One caveat: if you’re using SSR (Next.js, Remix, etc.), this useEffect approach only runs client-side. For SSR, you need to render the script tag server-side which brings us to the next section.

The SSR Problem: Getting Schema Into <head> at Build Time

With Next.js, you can’t rely on useEffect for schema that needs to be in the initial HTML response. The fix is rendering a <script> tag directly in your component using next/head or the App Router’s <Head>:

// app/blog/[slug]/page.jsx (Next.js App Router)
import Head from "next/head";

function buildBreadcrumbSchema(crumbs) {
  return {
    "@context": "https://schema.org",
    "@type": "BreadcrumbList",
    itemListElement: crumbs.map((crumb, i) => ({
      "@type": "ListItem",
      position: i + 1,
      name: crumb.label,
      item: crumb.url,
    })),
  };
}

export default function BlogPost({ params }) {
  const crumbs = [
    { label: "Home", url: "https://example.com" },
    { label: "Blog", url: "https://example.com/blog" },
    { label: "My Post", url: `https://example.com/blog/${params.slug}` },
  ];

  const schema = buildBreadcrumbSchema(crumbs);

  return (
    <>
      <Head>
        <script
          type="application/ld+json"
          dangerouslySetInnerHTML={{ __html: JSON.stringify(schema) }}
        />
      </Head>
      <article>{/* your content */}</article>
    </>
  );
}

Now the schema is part of the server-rendered HTML Google sees it immediately, no JavaScript execution required.

Using a Library: When Manual Gets Tedious

The manual approach is fine for one or two page types. But if your app has ten different page templates (product pages, category pages, blog posts, docs), you’ll end up copy-pasting and slightly mangling that schema builder everywhere. That’s where a dedicated library helps.

I tried a few options and ended up using @power-seo because it handles breadcrumb schema, OpenGraph, and canonical tags from a single config object which matched how I was already thinking about per-page SEO.

npm install @power-seo
import { SEO } from "@power-seo";

export default function BlogPost({ post }) {
  return (
    <>
      <SEO
        breadcrumbs={[
          { label: "Home", url: "https://example.com" },
          { label: "Blog", url: "https://example.com/blog" },
          { label: post.title, url: `https://example.com/blog/${post.slug}` },
        ]}
        title={post.title}
        canonical={`https://example.com/blog/${post.slug}`}
      />
      <article>{/* your content */}</article>
    </>
  );
}

It generates the same JSON-LD output as the manual approach no magic, just less repetition. Whether that’s worth a dependency is your call. For small projects, the hook above is plenty.

What I Learned

  • Your visible breadcrumb UI and your breadcrumb schema are two separate things. One is for users, one is for search engines. Both need to exist.
  • useEffect-injected schema works for CSR apps, but for SSR/SSG (Next.js, Remix), render the <script> tag server-side inside <head> to guarantee it’s in the initial HTML.
  • Always validate with Google’s Rich Results Test (search.google.com/test/rich-results) before assuming it works. It’ll show you exactly what schema Google can parse.
  • Keep your schema in sync with your actual URLs. Stale or mismatched item values in your schema are a silent SEO killer Google will ignore the breadcrumb entirely if the URLs don’t resolve.

If you want to see how the full implementation looks in a real Next.js blog (including dynamic route handling), here’s a detailed walkthrough: https://ccbd.dev/blog/how-to-implement-breadcrumb-schema-in-react-using-power-seo

What’s your setup?

Are you handling structured data manually, using a library, or just skipping it entirely and hoping for the best? I’m curious how other React devs are solving this especially on large apps with lots of page templates. Drop your approach in the comments. If you’ve found a cleaner pattern than what I’ve shown here, I genuinely want to know.