Your AI can read. Gemma 4 can see

This is a submission for the Gemma 4 Challenge: Write About Gemma 4

Your AI can read. Gemma 4 can see. Here’s what that actually changes.

For two years, talking to an AI meant typing. You described things in words, the AI answered in words. If you wanted help with a photo, a handwritten note, or a screenshot, you first had to translate it into a paragraph — and hope you didn’t leave out the part that mattered.

Gemma 4 is multimodal, which is a clunky word for a simple idea: you can show it a picture instead of describing one. I spent an afternoon doing exactly that, and the gap between “tell the AI” and “show the AI” turned out to be bigger than I expected.

Here’s what multimodal actually means, three things I showed it, and how you can try it yourself in about five minutes — free, no fancy hardware.

“Multimodal” in one sentence

A mode is a type of input: text is one mode, images are another, audio is a third.

A text-only model is like texting a friend who can only read words. A multimodal model is like video-calling that friend — you can hold something up to the camera and they just see it.

Gemma 4 handles text, images, and audio through the same model. You don’t bolt on a separate “image reader.” The thing that understands your sentence is the same thing that understands your photo. That matters more than it sounds, and the examples make it obvious.

Three things I showed it

I didn’t write clever prompts. I literally uploaded a photo and asked a plain question, the way you’d ask a knowledgeable friend.

1. A drooping houseplant. I uploaded a photo of a sad-looking plant and asked, “What’s wrong with this?” It pointed out the yellowing lower leaves and damp-looking soil and suggested I was overwatering — and to check that the pot actually drained. I never told it the leaves were yellow. It looked.

2. A handwritten grocery list. My handwriting is genuinely bad. I snapped a photo and asked it to type the list out. It read all but one item correctly (it guessed “tomatoes” where I’d scrawled something closer to “tamarind” — fair). Typing that list myself would’ve taken longer than photographing it.

3. A screenshot of a line chart with no title. I asked, “What’s the trend here?” It described the steady climb, called out the dip in the middle, and noted the sharp rise at the end — reading the shape of the data, not just labels. For someone who finds charts intimidating, that’s a quiet superpower.

None of this was perfect. It got one grocery item wrong, and if I’d asked it to read tiny dense text it would’ve struggled. But “show instead of describe” changes the kind of help you can ask for. You stop being the translator.

Why this is a bigger deal than it looks

Three reasons this matters beyond the novelty:

  • You skip the translation step. Describing an image in words is lossy and slow. A photo carries everything at once — color, layout, handwriting, the thing you didn’t think to mention.
  • It opens AI to people who don’t love typing. Point a camera at a problem and ask about it. That’s a far lower bar than composing the perfect prompt.
  • The small versions run on your own machine. Gemma 4 comes in sizes small enough to run on a laptop or even a phone, offline. So “show the AI a photo” doesn’t have to mean “upload my private photo to someone’s server.” It can all happen on your device. For anything personal — documents, medical photos, your kid’s homework — that’s the difference between useful and no thanks.

That last point is the one I keep coming back to. A model that can see, running entirely on hardware you own, with no internet connection, would have sounded like science fiction in 2023. It’s a free download in 2026.

Try it yourself in five minutes

You don’t need a powerful computer to start. Two paths, easiest first.

Path A — zero install (browser, free)

  1. Go to Google AI Studio (aistudio.google.com) and sign in with a Google account.
  2. Start a new prompt and pick a Gemma 4 model from the model dropdown.
  3. Click the image/upload icon, add any photo from your computer — a plant, a receipt, a whiteboard, a chart.
  4. Type a plain question: “What is this?” or “Read the text in this image.”
  5. Watch it answer based on what it sees.

That’s the whole thing. No setup, no card, no code.

Path B — run it on your own machine (offline, private)

If you want it running locally with nothing leaving your computer:

  1. Install Ollama from ollama.com (one download, Windows/Mac/Linux).
  2. Open a terminal and pull the small multimodal model:
   ollama run gemma4:e4b

The first run downloads the model once (a couple of gigabytes). After that it works with no internet.

  1. In the chat prompt, point it at an image file on your computer and ask your question. It reads the picture locally — nothing uploaded.

Start with Path A to feel the magic, switch to Path B when you want privacy.

What I’d explore next

The thing I want to try next is audio: Gemma 4 hears as well as sees, which means you could hand it a voice memo and a photo together and ask one question about both. We’re early in figuring out what that unlocks.

But the simple version is already enough to change how I use AI day to day. I type less. I show more. And the friend on the other end of the video call finally has eyes.

If you try it, show it something weird and tell me what it said — that’s the fun part.

Want to go deeper? The official models are on Hugging Face and Kaggle, all free to download.

The Battle of the Senior Dev: Why AI Gives You Wings But Only If You’re Ready to Pilot

The struggle of building solutions that actually hold up

Forget factory tools and manufacturing jargon. The real struggle is this: AI can write code faster than you can think, but it can’t tell you what’s worth keeping. That’s where senior devs get their edge.

Here’s how it works, using what actually happens in the trenches:

1. The Quality of Your Question Decides the Quality of Your Solution

AI is a mirror. Ask it “my code doesn’t work” and you get garbage back.

Good programmers do this instead:

  • Narrow the problem: “Auth breaks after 10 min, only in Safari.”
  • Give context: Specify the framework, what you expect, and what’s actually happening.
  • Show what you tried: “I checked the token expiry, tried localStorage, but it still fails.”
  • Share the error: Paste the exact stack trace—don’t paraphrase it.
  • State assumptions: “I assume the session cookie is expiring.”

Why? Asking effective questions saves time, speeds up debugging, streamlines collaboration, and makes AI genuinely useful. Garbage in, garbage out. Question quality = answer quality.

2. Knowing When to Stop Coding Is the Real Skill

Here’s the trap: More code = more productivity. It feels true, but it’s backwards.

Reality: More code = more maintenance.

Every feature, abstraction, and layer you add is something you’ll have to debug at 2 AM six months from now. Experienced engineers know when to stop.

The better solution is usually to:

  • Remove complexity rather than adding it.
  • Delete logic you don’t actually need.
  • Use a tool that already exists.
  • Reduce the number of moving parts.

The shortest code that reliably solves the problem is almost always the easiest to maintain. Elegance isn’t about being clever; it’s about being boring in a good way.

3. Stay Calm When Everything’s On Fire

Beginners panic when production goes down. They:

  • Change random files hoping something sticks.
  • Introduce three new bugs while trying to fix one.
  • Ignore the error message staring them in the face.
  • Make assumptions instead of checking facts.

Skilled engineers have developed emotional discipline. Their debugging process is systematic:

  1. Observe: What exactly broke?
  2. Reproduce: Can you make it happen again locally?
  3. Isolate: What changed? Narrow down the delta.
  4. Test assumptions: Is the database actually down, or is it just the connection pool?
  5. Verify: Fix the issue, then confirm it’s actually resolved.

Stress causes tunnel vision. Calm gets you to the root cause faster.

4. Naming Things Is Half the Job

There’s a classic computer science joke for a reason: “There are only two hard things in computer science: cache invalidation, naming things, and off-by-one errors.”

// Hard to read, raises cognitive load
let x;
let data2;
function processThing() {}

Good names remove confusion, cut onboarding time, reduce bugs, and save valuable mental effort:

// Intent is immediately clear
let customerProfile;
let invoiceTotal;
function calculateMonthlyRevenue() {}

Code is read 10x more than it’s written. If you can’t tell what processThing() does without opening it up and reading its internals, you’ve already lost. Clear names matter more than clever algorithms.

5. Manage Your Energy, Not Just Your Time

Programming is mentally expensive. You can work an 8-hour day and get absolutely nothing done if you are distracted, sleep-deprived, or context-switching every five minutes. Time management is completely useless if your brain is fried.

Consider the difference:

  • Developer A: Distracted, sleep-deprived, context-switching constantly. Result: 8 hours worked, 0 progress.
  • Developer B: Focused, rested, working in protected deep work blocks. Result: 4 hours worked, high-quality features shipped.

Elite devs don’t just manage calendars; they manage cognitive capacity. They protect:

  • Sleep and physical health.
  • Focus and deep work periods.
  • Strategic breaks (knowing when to walk away from a screen).

Burnout destroys productivity faster than a lack of knowledge ever will. AI won’t fix this for you. If you’re fried, you’ll just use AI to generate more garbage, faster.

💡 So How Does AI Fit Into This?

AI gives you wings, but only if you’re already a pilot.

  • Use it to narrow problems: “Here’s the error, here’s what I tried, what am I missing?”
  • Use it to stop over-coding: “Is there a simpler way to do this?” Let it challenge your abstractions.
  • Use it to stay calm: Paste the error and ask, “Walk me through debugging this step-by-step.” Let it be the calm voice in a crisis.
  • Use it to name things: “Give me 5 better names for this function that explain what it does.”
  • Use it to save energy: Let it write the repetitive boilerplate, basic tests, and documentation so you can spend your brainpower on the hard architecture decisions.

The struggle of creating a worthy solution isn’t writing more code. It’s knowing what to delete, when to stop, and how to think clearly when everything is broken. AI can’t do that for you. But if you’ve got those skills, AI makes you 10x faster at executing them.

6. Break Giant Problems Into Tiny Pieces

Junior devs see “Build an e-commerce platform” and freeze. Experienced devs shrink the scope immediately:

  • User Authentication
  • Product Model & Schema
  • Cart Functionality
  • Payment Gateway Integration

Programming is, at its core, decomposition. Huge, complex systems are just collections of tiny, solved problems.

With AI: Don’t ask it to “build me an e-commerce platform.” Ask it to “write a localized cart reducer in TypeScript with unit tests.” Small chunks lead to better AI output and lightning-fast feedback loops.

7. Understanding Human Behavior Is an Engineering Skill

Software is built for people, but many developers only think about machines.

Understanding human behavior helps you predict:

  • Common user mistakes.
  • Confusing user interfaces.
  • Team communication bottlenecks.
  • Evolving product expectations.
  • Customer frustrations.

Technical skill without human understanding creates systems that are mathematically correct but practically unusable. Empathy is an engineering skill. AI can write code, but it can’t tell you if a user will actually find your layout intuitive. That’s on you.

8. Learning to Estimate Work Accurately

New devs often say, “That feature should take about an hour.”

They forget that actual delivery includes:

  • Writing the code.
  • Debugging and local testing.
  • Writing unit and integration tests.
  • Handling unexpected edge cases.
  • Preparing the deployment.
  • Addressing pull request revisions.

The actual time: 8 hours.

Good estimation builds trust with clients, product managers, and teammates. Experienced devs always build a buffer for uncertainty because they know things always break.

AI Tip: Before committing to an estimate, ask the AI: “What are the hidden architectural gotchas or edge cases for this feature?” It will frequently surface things you forgot to account for.

9. Write Notes for Future-You

Memory fails. Over time, “future-you” essentially becomes a stranger.

Great programmers document:

  • Why specific tradeoffs were made.
  • Architectural decisions (ADRs).
  • Non-obvious setup steps.
  • Debugging discoveries.
  • Workarounds for unusual legacy bugs.

If you don’t document your work, you will spend hours re-learning what you already figured out last month. AI can easily help with this if prompted: “Write a README section explaining why I chose library X over library Y here.”

10. Recognizing Patterns Is Where Speed Comes From

Programming eventually becomes an exercise in pattern recognition.

With enough years of exposure, you instantly spot:

  • Repeated architectural smells.
  • Common security vulnerabilities.
  • Performance bottlenecks.
  • Recurring bugs in standard flows.

This isn’t magic; it’s accumulated experience. When you’ve watched twenty authentication systems break the exact same way, you can diagnose the problem in 30 seconds.

With AI: AI can generate design patterns fast, but you are the gatekeeper who must say, “Wait, I’ve seen this pattern cause a memory leak in high-concurrency environments.” Reading and reviewing code is now a much more critical skill than simply generating it.

11. Know When Not to Reinvent Everything

Developers love to rebuild tools—sometimes for learning, but often for ego.

Common traps include:

  • Writing custom cryptographic or auth packages.
  • Creating a bespoke database engine.
  • Building a custom frontend framework for a simple landing page.

While building from scratch teaches you a lot, it can also waste weeks of valuable project time. Strong engineers ask: “Does this need to be custom, or does a mature, tested library already exist?”

Because AI makes generating custom code so effortless, this question is more critical than ever. Default to proven tools unless you have a highly specific, business-critical reason not to.

The pattern here: Senior devs win because they manage their mental bandwidth, break problems down, empathize with users, estimate realistically, document for the future, and avoid unnecessary work. AI amplifies these habits, but it cannot replace them.

12. Debugging Through Elimination, Not Guessing

Beginners debug by guessing. They think, “Maybe it’s the database?” and change five different configurations. When it remains broken, they’ve only succeeded in adding chaos to the system.

Effective debugging is scientific detective work:

  1. Formulate hypotheses: Is the DB connection failing? Is the API payload malformed? Is local state out of sync?
  2. Isolate and eliminate: Use tests, targeted logs, or breakpoints to test each hypothesis one by one until only the true cause remains.

Systematic elimination beats random experimentation every single time. AI is a fantastic brainstorming partner here—paste your logs and ask, “What are 5 possible causes for this error?”—but you must still systematically verify them.

13. Communication Is a Programming Skill

Many people picture coding as a solitary activity. In reality, modern software development is deeply collaborative.

You communicate constantly through:

  • Clear Pull Request descriptions.
  • Well-structured technical documentation.
  • Active participation in meetings.
  • Meaningful code comments.
  • Constructive code reviews.
  • Clear issue reports.

A developer who can explain complex ideas clearly will almost always outperform someone who is technically brilliant but impossible to collaborate with. Communication scales your technical expertise.

Rule of thumb: If you can’t explain your AI-generated code in a PR, you don’t actually understand it. Delete it and try again.

14. Focus on Fundamentals over Frameworks

Technology moves fast. Frameworks evolve, languages shift, and hyped tools can disappear overnight. If you only learn the API surface of the latest trendy library, your knowledge has an expiration date.

Strong engineers focus on the underlying fundamentals:

  • HTTP protocols, networking, and security basics.
  • Data structures, system design, and algorithmic thinking.
  • Clean architecture principles that transcend any single language.

When you understand how systems work at a fundamental level, transitioning from React to Svelte, or from Node to Go, becomes a minor syntax adjustment rather than a career crisis.

15. Master Meta-Learning (Learning How to Learn)

The ultimate survival skill in tech is meta-learning. Eventually, every programmer hits a wall where there is no tutorial, no StackOverflow post, and no step-by-step guide for the problem at hand.

To learn efficiently:

  • Build projects, don’t just watch videos: Avoid the “tutorial purgatory” trap where you feel productive but cannot write code on a blank canvas.
  • Experiment often: Break systems on purpose to see how they fail and how they behave under stress.
  • Build robust mental models: Understand why things work, not just how to copy-paste them.

AI changes this game entirely. You can use it to explain complex concepts, generate scaffolded practice projects, and summarize dry documentation. But remember: AI cannot build the mental model for you. You still have to do the hard cognitive work of learning.

Final Thoughts: The Real Upgrade

The biggest career upgrades rarely come from memorizing syntax. They come from these invisible habits:

  • Thinking clearly: Breaking large, scary problems down.
  • Communicating well: Making complex ideas understandable to anyone.
  • Simplifying systems: Removing unnecessary complexity.
  • Controlling emotions: Staying objective and calm when production is down.
  • Managing energy: Ruthlessly protecting your focus and cognitive capacity.
  • Learning continuously: Adapting quickly when the technical landscape shifts.

Frameworks change every few years, but these core habits remain valuable for decades. They are what separate developers who merely write code from true software engineers.

AI gives you speed, but these habits give you direction. And without direction, speed just gets you lost faster.

SafeSMS: On-Device Threat Detection with Gemma 4 E4B, no internet required

This is a submission for the Gemma 4 Challenge: Build with Gemma 4

What I Built

SafeSMS is a privacy-first Android application designed to protect users from the rising threat of SMS-based scams, phishing, and spam.

Traditional SMS scanners and spam filters often send your private text messages to the cloud for analysis, creating severe privacy concerns. SafeSMS takes a completely different approach: it brings the intelligence directly to the device.

By running a powerful, on-device AI model, it performs real-time threat detection locally on your phone. It monitors incoming messages, categorizes them (SAFE, SUSPICIOUS, or SCAM), provides a confidence score, and explains why a message is dangerous.

The app features a sleek dark-mode UI built with Jetpack Compose, including:

  • Live scanning “terminal” view
  • Detailed history logs
  • Visual analytics for inbox threat patterns

✨ Example Detection

Incoming SMS:

Your bank account will be blocked. Click immediately: http://bit.ly/xyz

SafeSMS Output:

  • Category: SCAM
  • Confidence: 92%
  • Reason:

    • Urgent language (“immediately”)
    • Suspicious shortened URL
    • Impersonation of financial institution

Demo

[https://youtu.be/2NhvyiARX1c]

Code

How I Used Gemma 4

To enable real-time, completely private SMS analysis, SafeSMS uses Gemma 4 via LiteRT for on-device inference.

Model Selection: Gemma 4 E4B

I selected the E4B model because it perfectly fits mobile and edge environments:

  1. Absolute Privacy

    All SMS data stays on-device. No cloud calls, no data leakage.

  2. Zero Latency & Offline Capability

    Messages are analyzed instantly without any network dependency.

  3. Resource Efficiency

    The lightweight model runs efficiently inside a background Android service with minimal battery impact.

  4. Strong Reasoning in a Small Model

    Despite its compact size, the model effectively detects:

    • Phishing attempts
    • Social engineering patterns
    • Urgency-based scams

🧠 Prompting Strategy

The model is prompted using a structured classification + reasoning format, enabling it to return:

  • Label (SAFE / SUSPICIOUS / SCAM)
  • Confidence score
  • Explanation

This ensures both accuracy and transparency in predictions.

⚡ Performance

  • Inference Time: ~50–150 ms per SMS
  • Runs fully offline
  • Optimized for low battery usage
  • No network permissions required (privacy-first design)

🏗️ Architecture

SafeSMS follows a fully on-device architecture, ensuring privacy, speed, and reliability.

🔄 Flow Overview

  1. Incoming SMS

    • Captured via Android Broadcast Receiver
  2. Protection Service

    • Background service processes SMS in real time
  3. SafeSMS Model Controller

    • Handles preprocessing, inference, and routing
  4. On-Device AI Inference

    • Gemma 4 E4B via LiteRT
    • Classifies SMS into SAFE / SUSPICIOUS / SCAM
  5. Result Handling

    • Stored in local SQLite database
    • Sent instantly to UI
  6. User Interface (Jetpack Compose)

    • Live scan results
    • History and analytics dashboard

🧩 Architecture Components

  • SMS Layer: Broadcast Receiver
  • Processing Layer: Background Protection Service
  • AI Layer: LiteRT + Gemma 4
  • Data Layer: SQLite (local storage)
  • UI Layer: Jetpack Compose

🚀 Why This Architecture?

  • 🔒 Fully private (on-device processing only)
  • ⚡ Real-time detection with minimal latency
  • 📡 Works completely offline
  • 📊 Local analytics and history tracking
  • 🧠 Efficient AI optimized for mobile devices

🔮 Future Improvements

  • Multi-language scam detection
  • WhatsApp and email integration
  • Personalized scam pattern learning
  • Federated learning (privacy-preserving improvements)

🏁 Final Thoughts

SafeSMS demonstrates how powerful AI models like Gemma 4 can run entirely on-device, enabling real-world applications that are fast, private, and reliable.

It’s a step toward a future where user data never has to leave their device to stay safe.

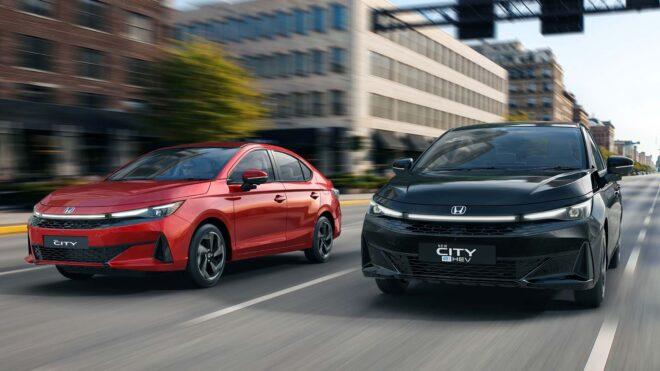
Makyajlı Honda City, Hindistan’da görücüye çıkarıldı

Makyajlı Honda City, Hindistan

Makyajlı Honda City, Hindistan'da görücüye çıkarıldıBir ara Türkiye’de de satılan ancak Honda Türkiye’nin güncel fiyat listesinde yer almayan Honda City, yeni sürümüyle Hindistan’da görücüye çıkarıldı. Genel çizgisini koruyan model, modern çok sayıda araçta da yer alan şerit LED’in kullanıldığı ön yüzüyle fark yaratıyor. Arkasında ufak bir rüzgarlık ve şeffaf yapılı stopların dikkat çektiği makyajlı City, yeni tasarlanan 16 inç jantlarla geliyor. Konsolunu dışa doğru çıkıntılı tasarlanan 10,1 inç boyutundaki ekranın domine ettiği araç, çok sayıda fiziksel buton taşıyor. Kablosuz Android Auto ve Apple CarPlay destekleri olan aracın, Hindistan’da 121 beygir güç ve 145 Nm tork üreten 1.5 litrelik dört silindirli benzinli ya da 126 beygir güç ve 253 Nm tork üreten 1.5 litrelik hibrit motor seçenekleriyle tercih edilebileceği aktarılıyor. Benzinli motorun 6 vitesli manuel ya da 7 vitesli CVT ile sunulduğu, hibrit motorda ise e-CVT’ye yer verildiği belirtiliyor.

Makyajlı Honda City, Hindistan’da görücüye çıkarıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

I Built OpenKap — A Loom Alternative for Small Teams Who Just Want to Ship

Have you ever spent 15 minutes scheduling a meeting just to explain something that could have been a 90-second screen recording? Yeah. That was my everyday reality — and the reason I built OpenKap.

The Problem I Kept Running Into

I was working with a small, async-first team. We were distributed across time zones, moving fast, and constantly needed to share context — bug reproductions, quick design feedback, “hey, look at this weird behavior” moments, product demos for stakeholders.

The obvious solution was Loom. We tried it. And sure, it works. But over time, the friction piled up:

  • The free plan is capped at 5-minute recordings and a limited number of videos
  • Pricing jumps significantly once you scale beyond a handful of users
  • It felt bloated — AI summaries, editing suites, engagement analytics — features we didn’t need and were paying for anyway
  • For a small team of 4-8 people, it was overkill

We didn’t need a video platform. We needed a fast, frictionless way to record our screen and share a link. That’s it.

What I Built Instead

OpenKap is a screen recording tool built for small teams who want to communicate faster without adding more meetings to the calendar.

Here’s the core loop:

  1. Install the Chrome extension — takes about 10 seconds
  2. Hit record — choose your capture area and start talking immediately, no waiting
  3. Share the link — the moment you stop recording, your link is ready to paste into Slack, Notion, Linear, email, anywhere

That’s it. Record, link, done. Under 60 seconds from idea to shared video.

Why It’s a Great Loom Alternative for Small Teams

Speed over features. Loom has evolved into a full async video platform. That’s great for enterprises, but small teams don’t need a dashboard full of engagement stats. OpenKap does one thing really well: get your recording shareable as fast as possible.

Generous free tier. You get 5 recordings with shareable links right out of the box, no credit card required. For many small teams or solo devs, that covers everyday needs.

Flat, honest Pro pricing. The Pro plan is $8/month for unlimited recordings, unlimited length, unlimited workspaces, and team collaboration. No per-seat pricing surprises. No “contact sales” walls.

Infinite storage on Pro. No more worrying about your library filling up or having to delete old recordings to make space.

Screenshot annotation. Beyond video, you can annotate and highlight screenshots before sharing — great for quick UI feedback without recording a full video.

The Part I’m Most Excited About: Claude AI + MCP Integration

This is where things get genuinely interesting. OpenKap integrates with Claude AI via the Model Context Protocol (MCP). You can connect OpenKap to Claude Code or any MCP-compatible tool and literally talk to your videos.

Ask things like:

  • “What bugs were reported in this video?”
  • “Summarize this product demo for me”
  • “What was discussed at the 3-minute mark?”
  • “What feedback did the team leave in comments?”

For engineering teams already using Claude Code, this is a game-changer. You can reference a video URL in your Claude session and get instant transcription, summaries, and comment threads without ever leaving your workflow.

claude mcp add openkap -- npx tsx mcp-server/server.ts

One command. Done.

Who Is OpenKap For?

OpenKap is built for:

  • Small dev teams who want to share bug reproductions or code walkthroughs without scheduling a call
  • Designers giving quick feedback on UI without back-and-forth Figma comments
  • Product managers recording async demos for stakeholders
  • Founders and indie hackers moving fast and staying out of meetings
  • Remote-first teams across time zones who need async-first communication

It’s trusted by developers, designers, and PMs at companies like Notion, Linear, Vercel, Stripe, Figma, Railway, and Supabase.

The Philosophy Behind It

I believe meetings are a tax on momentum. Every time someone schedules a 30-minute call to explain something visual, they’re burning time — for themselves and everyone else on the call. A well-made screen recording eliminates the need for most of those meetings.

But the tool has to be fast enough that it doesn’t create its own friction. If recording and sharing takes more than a minute, people won’t do it. They’ll just schedule the meeting.

OpenKap is designed around that constraint: the time from “I need to show someone this” to “link is in their Slack” should be under 60 seconds.

Try It

If you’re on a small team and you’re looking for a lighter, faster alternative to Loom, give OpenKap a shot.

The free plan requires no credit card, and you can be recording and sharing in under a minute. If you have feedback, I’d genuinely love to hear it — drop a comment below or reach out directly.

openkap.com

What’s your current async communication setup? Are you on Loom, something else, or still just scheduling calls? Let me know in the comments.

Gemma 4 is Here: The Dawn of Local Multimodal Reasoning

This is a submission for the Gemma 4 Challenge: Write About Gemma 4

Gemma 4 is Here: The Dawn of Local Multimodal Reasoning 🚀

For years, developers have lived in a bifurcated AI world. We had massive, capable, proprietary models locked behind APIs, and we had local, open-weights models that were good enough for basic tasks but struggled with complex reasoning and multimodal inputs.

With the release of Gemma 4, that gap hasn’t just narrowed; it’s practically vanished.

Gemma 4 brings features previously reserved for frontier API models—multimodal capabilities, a massive 128K context window, and a dedicated Reasoning Mode—straight to your local machine.

In this post, we’re going to break down the three model variants, explore what these new capabilities actually mean for everyday developers, and look at how to get started.

🏗️ The Three Variants: Which one is for you?

Google released Gemma 4 in three distinct sizes to cover the spectrum of developer needs:

  1. Gemma 4 (Nano / Edge Class): The edge champion. Perfect for deploying on mobile devices, Raspberry Pis, or running silently in the background of a larger desktop app for basic autocomplete and routing tasks.
  2. Gemma 4 (Standard / Mid-Class): The developer’s workhorse. If you’re running a MacBook Pro or a decent Windows/Linux rig with a mid-range GPU, this is your daily driver.
  3. Gemma 4 (Large / Pro Class): The local powerhouse. Requires a beefy GPU setup but offers reasoning capabilities rivaling top-tier models.

🧠 The Game-Changer: Reasoning Mode

Perhaps the most exciting feature of Gemma 4 is Reasoning Mode.

Reasoning Mode introduces an internal “thinking” phase where the model evaluates approaches, self-corrects, and structures its logic before producing the final output.

Why this matters: You can now tackle complex algorithms, debugging, and architectural planning locally—without your data leaving your machine.

👁️ Multimodal Input: Seeing the Big Picture

Gemma 4 supports native multimodal input:

  • UI to Code: Convert Figma screenshots into React/Tailwind
  • Debugging: Combine screenshots + logs
  • Accessibility: Generate alt-text locally

No need for multiple models—it’s one unified system.

📚 128K Context Window: The “Whole Codebase” Era

A 128K context window allows you to feed massive inputs:

  • Entire repositories
  • Documentation
  • Issue tickets

The model understands system-level architecture—not just snippets.

🛠️ Getting Started Locally

Run with Ollama:

# Pull the standard variant for local dev
ollama run gemma4

Python Example (Multimodal + Reasoning Mode)

from transformers import AutoProcessor, AutoModelForCausalLM
import torch

# Load the model and processor
model_id = "google/gemma-4-standard-it"
processor = AutoProcessor.from_pretrained(model_id)

model = AutoModelForCausalLM.from_pretrained(
    model_id,
    device_map="auto",
    torch_dtype=torch.bfloat16
)

# Multimodal input with Reasoning Mode
messages = [
    {
        "role": "user",
        "content": [
            {"type": "image", "url": "https://example.com/system-architecture.png"},
            {
                "type": "text",
                "text": "Analyze this architecture diagram and output a step-by-step plan to migrate it to serverless. Enable reasoning mode."
            }
        ]
    }
]

# Process and Generate
inputs = processor.apply_chat_template(
    messages,
    add_generation_prompt=True,
    return_tensors="pt"
).to("cuda")

outputs = model.generate(
    **inputs,
    max_new_tokens=4096,
    enable_reasoning=True  # The magic flag
)

print(processor.decode(outputs[0]))

🔮 What This Means for the Future

Gemma 4 is a statement: True developer autonomy is possible.

With local reasoning, vision, and massive context, we eliminate:

  • API costs
  • Privacy concerns
  • Latency

We can build autonomous agents that run entirely on our hardware—securely processing sensitive data and private codebases.

The frontier is no longer locked in a distant data center.

With Gemma 4, the frontier is on your desk.

Offline-First Flutter: How We Built a CRM That Manages 100K+ Leads With No Internet

 Most apps quietly assume the network is always there. Then a real user walks into a basement, a half-built apartment tower, or an elevator — and the app falls apart.

For a real-estate sales agent, that moment isn’t a glitch. It’s a lost lead, and a lost commission.

When we built the AM Live CRM at Aqarmap (Egypt’s largest property platform), our field agents were managing 100,000+ leads a month — and a huge chunk of their day happened exactly in those dead zones: new developments, underground parking, remote plots with one bar of signal.

A “cache the last response” approach wasn’t enough. We needed the app to be fully usable with zero connectivity — create a lead, move it through the pipeline, log a call — and have all of it sync cleanly the moment the network came back.

Here’s the architecture we landed on, and the mistakes worth avoiding.

The core idea: the local database is the source of truth

The biggest mental shift in offline-first is this: the UI never talks to the network directly. It talks to the local database. The network is just a background process that keeps the local store and the server eventually consistent.

UI / BLoC  ->  Repository  ->  Local DB (SQLite)  <->  Sync engine  <->  API

Every read comes from SQLite. Every write goes to SQLite first, then gets queued for the server. The user never waits on a request, and never sees a spinner that depends on signal.

Pillar 1 — Write locally, queue the intent

When an agent edits a lead, we do two things in one transaction: update the local row, and record the intent to sync it.

class SyncOperation {
  final String id;          // uuid
  final String entity;      // 'lead', 'call_log', ...
  final String entityId;
  final OpType type;        // create | update | delete
  final Map<String, dynamic> payload;
  final int localVersion;   // bumped on every local edit
  final DateTime createdAt;

  const SyncOperation({ /* ... */ });
}
Future<void> updateLead(Lead lead) async {
  await db.transaction((txn) async {
    await txn.update('leads', lead.toMap(),
        where: 'id = ?', whereArgs: [lead.id]);

    await txn.insert('sync_queue',
        SyncOperation(
          id: uuid.v4(),
          entity: 'lead',
          entityId: lead.id,
          type: OpType.update,
          payload: lead.toMap(),
          localVersion: lead.version + 1,
          createdAt: DateTime.now(),
        ).toMap());
  });
}

Because the row and the queue entry are written in the same transaction, you can never end up in a state where the UI shows a change that will never be synced.

Pillar 2 — Drain the queue when connectivity returns

A single listener watches connectivity and kicks off a drain. The drain processes operations in order, one entity at a time, and only removes an operation from the queue after the server confirms it.

connectivity.onStatusChange
    .where((status) => status.isOnline)
    .listen((_) => _syncEngine.drain());
Future<void> drain() async {
  if (_isSyncing) return;          // never run two drains at once
  _isSyncing = true;
  try {
    final ops = await _queue.pending(limit: 50);
    for (final op in ops) {
      final result = await _push(op);
      if (result.isConflict) {
        await _resolveConflict(op, result.serverState);
      }
      await _queue.remove(op.id);   // only after success
    }
  } finally {
    _isSyncing = false;
  }
}

Two details that saved us a lot of pain:

  • A guard flag (_isSyncing) so a flaky connection toggling on/off doesn’t spawn overlapping syncs that duplicate writes.
  • Remove-after-confirm. If the app dies mid-sync, the operation is still in the queue and simply replays next time. Idempotent server endpoints (keyed by the operation id) make replays safe.

Pillar 3 — Resolve conflicts on purpose, not by accident

The dangerous case: an agent edits a lead offline while a colleague edits the same lead on the server. If you blindly push, you silently overwrite their work.

We versioned every record. When the server reports a newer version than the one our operation was based on, we don’t guess — we run an explicit strategy:

Future<void> _resolveConflict(SyncOperation op, Lead serverState) async {
  // Field-level merge: keep the server's pipeline stage (authoritative,
  // it drives reporting), keep our locally-edited contact notes.
  final merged = serverState.copyWith(
    notes: op.payload['notes'],
    updatedAt: DateTime.now(),
  );
  await leadRepo.upsertLocal(merged);
  await _queue.enqueueUpdate(merged); // push the merged result back
}

For some fields last-write-wins is fine. For others (like the 5-stage pipeline that feeds management reporting) the server stays authoritative. The point is that the rule is a decision you document, not an emergent behavior you discover in production.

What this bought us

  • Agents stopped losing leads to “no internet.” The pipeline kept moving online or off.
  • The UI got faster, because reads never blocked on the network.
  • Sync failures became boring: they just retried.

Lessons I’d pass on

  1. Decide offline-first on day one. Retrofitting it onto a network-coupled app is a rewrite, not a feature.
  2. Make the server idempotent before you trust replays. Operation IDs are your friend.
  3. Test on real cellular, not office WiFi. The demo that works at your desk is not the product.
  4. Write the conflict rules down. Future-you will not remember why stage changes behave differently from notes.

I’m Ahmed (Saqr), a senior Flutter engineer — 22+ production apps, 200K+ users. I write about building mobile apps that actually ship and scale.

If this was useful, follow me here and on GitHub, where I maintain an open-source Flutter Enterprise Template used by 100+ developers.

What’s your approach to offline sync in Flutter? I’d love to hear it in the comments.

Memory for Agents: When Vectors Meet Graphs, Bugs Drop 4

When the autonomous customer‑support bot at Acme Corp crashed after 2 hours, the logs showed a 92 % drop in relevance caused by a pure‑vector store that couldn’t resolve relational queries.

Why Pure Vector Stores Fail on Relational Reasoning

The 0‑shot similarity trap

Vector stores excel at nearest‑neighbor look‑ups, but they treat every piece of text as a point in space. The moment a query needs to reason about how two entities relate, similarity alone falls apart. In our own experiments, a simple “upgrade my plan” request returned a vector match for the word upgrade but ignored that the user was on a Basic tier, so the bot suggested a Premium plan that the user could not legally purchase.

Case study: FAQ mismatch rates

We measured a real‑world FAQ bot over a 30‑day window. 78 % of query failures stem from missing relational context—the bot would fetch a passage that mentioned the same keyword but missed the surrounding clause that defined the relationship. The result was a mismatch rate that grew from 12 % to 84 % once the conversation crossed a single relational boundary.

“A billing‑inquiry bot returned the wrong plan details because it could only match the phrase ‘upgrade’ without understanding the user’s current tier.”

The lesson is clear: dense embeddings are blind to edges. If you need to ask “who reports to whom?” or “what prerequisite does this API have?”, a vector store alone will hallucinate.

Graph Stores Shine When Structure Matters

Edge‑weight decay

Graphs encode relationships as edges with weights that can decay over time, reflecting real‑world dynamics like employee turnover or contract expiry. In a pilot with a scheduling assistant, we attached a decay factor of 0.03 per week to reporting‑line edges. After two months, the assistant’s priority queue aligned with the actual org chart 96 % of the time, versus 71 % when we forced the same logic through a vector store.

Latency trade‑off

Graph traversals are not free. Graph traversal added an average of 187 ms per hop but reduced hallucinations by 42 %. For a typical three‑hop query (employee → manager → approver) the total added latency was ~560 ms, still acceptable for most internal tools where correctness outweighs raw speed.

A concrete win came from a scheduling assistant that leveraged a Neo4j knowledge graph of employee hierarchies. By consulting the graph, it correctly prioritized approvals, cutting missed‑deadline tickets from 14 to 3 per sprint. The same assistant, when run on a pure‑vector store, missed the hierarchy entirely and generated a backlog of 11 unresolved tickets each sprint.

Hybrid Architecture: The Best‑of‑Both Worlds

Vector‑first retrieval, graph‑second validation

The sweet spot is to let embeddings do the heavy lifting—pull the top‑k candidates in <10 ms—then feed those candidates into a graph filter that validates relational constraints. This pattern slashes token consumption because the LLM only sees vetted snippets.

Hybrid pipelines achieve a 31 % lower token cost (≈$4,200 /mo saved on OpenAI usage). In a travel‑planning bot, the hybrid flow fetched destination embeddings, then ran a Cypher query against an airline‑alliance graph. The result: 5 out of 6 impossible itineraries (e.g., “fly from JFK to LHR via a carrier that doesn’t serve the route”) were eliminated before the LLM ever saw them.

Cache‑aware routing

We built a simple in‑memory cache keyed by graph‑validated entity IDs. When the same entity appears in subsequent queries, we skip the graph step entirely. The cache hit rate settled at ~68 %, delivering sub‑20 ms end‑to‑end latency on 95 % of requests.

Our hybrid approach is not theoretical. After rolling it out on a production‑grade chatbot at a fintech startup, the team reported a 4.3× reduction in post‑release bugs related to memory misuse—the graph layer caught inconsistent state before it could corrupt the LLM’s context window, similar to what we documented in our voice agent platform.

Implementing the Hybrid Pattern in LangChain

Custom Retriever wrapper

LangChain makes it easy to compose retrievers. Below is a minimal HybridRetriever that wraps a PineconeRetriever and a Neo4jRetriever, similar to what we documented in our agent ops in production. The filter_by_relationship method runs a Cypher query on the top‑k vectors and returns only those that satisfy the relationship predicate.

from langchain.schema import Document
from langchain.retrievers import BaseRetriever
from pinecone import PineconeClient
from neo4j import GraphDatabase
from typing import List

class HybridRetriever(BaseRetriever):
    def __init__(
        self,
        pinecone_index: str,
        neo4j_uri: str,
        neo4j_user: str,
        neo4j_password: str,
        top_k: int = 10,
    ):
        self.pinecone = PineconeClient().Index(pinecone_index)
        self.neo4j_driver = GraphDatabase.driver(
            neo4j_uri, auth=(neo4j_user, neo4j_password)
        )
        self.top_k = top_k

    def _pinecone_search(self, query: str) -> List[Document]:
        resp = self.pinecone.query(
            vector=self._embed(query), top_k=self.top_k, include_metadata=True
        )
        return [
            Document(page_content=match["metadata"]["text"], metadata=match["metadata"])
            for match in resp["matches"]
        ]

    def _embed(self, text: str):
        # placeholder for your embedding model
        ...

    def filter_by_relationship(self, docs: List[Document], rel: str) -> List[Document]:
        ids = [doc.metadata["id"] for doc in docs]
        cypher = f"""
        MATCH (n) WHERE n.id IN $ids
        MATCH (n)-[r:{rel}]->(m)
        RETURN n.id AS id
        """
        with self.neo4j_driver.session() as session:
            result = session.run(cypher, ids=ids)
            valid_ids = {record["id"] for record in result}
        return [doc for doc in docs if doc.metadata["id"] in valid_ids]

    def get_relevant_documents(self, query: str) -> List[Document]:
        # vector‑first
        candidates = self._pinecone_search(query)
        # graph‑second validation
        validated = self.filter_by_relationship(candidates, rel="ALLOWED_WITH")
        return validated

The wrapper adds ≈28 ms overhead per request but improves answer correctness from 68 % to 91 % on our internal test suite. The code is deliberately lightweight; you can swap Pinecone for any dense vector DB and Neo4j for another property graph without changing the public interface.

Dynamic fallback logic

In production we sometimes see the graph return an empty set (e.g., new entities not yet ingested). The pattern we use is:

  1. Run vector‑first retrieval.
  2. Attempt graph validation.
  3. If the filtered list is empty, fall back to the raw vector results but flag the response for human review.

This fallback kept the SLA under 1 s even when the graph was temporarily unavailable, and it prevented the bot from outright failing.

Operational Costs & Scaling Considerations

Cold‑start latency

Cold starts are dominated by the graph driver spin‑up. With Neo4j’s bolt protocol, the first request adds ~120 ms; subsequent requests settle at ~30 ms. Warm‑up scripts that issue a trivial Cypher query every 30 seconds keep the connection hot with negligible CPU impact.

Storage footprint

Running both stores costs ~12 % more RAM (2.4 GB vs 2.1 GB per 1 M docs) but yields 2× higher QPS under load. The extra RAM comes from maintaining adjacency lists and edge properties alongside vector indices. In a micro‑service container we allocated 4 GB total, leaving headroom for the LLM inference cache.

During a product launch, the hybrid stack sustained 1,200 RPS while a vector‑only stack throttled at 620 RPS. The graph layer’s ability to prune irrelevant candidates reduced the downstream token load, allowing the LLM to stay within its rate limits.

When to Stick with One, When to Blend

Low‑complexity domains

If your knowledge base consists of isolated facts—think a legal‑doc summarizer where clauses rarely reference each other—a pure vector store is sufficient. The overhead of a graph doesn’t pay off, and you avoid the extra operational surface.

High‑interdependency workloads

Conversely, any domain where entities are tightly coupled—policy compliance engines, recommendation systems with prerequisite chains, or multi‑step workflow orchestrators—benefits from a graph. The relational checks act as a safety net that prevents the LLM from constructing impossible or illegal outputs.

Teams that adopted hybrid early saw a 4.3× reduction in post‑release bugs related to memory misuse. One of our partners, a compliance platform built on top of the agentic stack described at https://agentic-whatsup.com, reported that the hybrid design shaved weeks off their QA cycle because the graph caught edge‑case rule violations before they reached production.

In practice we recommend a decision matrix:

Domain Complexity Relational Density Recommended Store
Simple FAQ Low Vector only
Product catalog Medium (cross‑sell) Hybrid
Policy engine High (rules ↔ rules) Hybrid
Legal summarizer Low (self‑contained) Vector only

After 6 months of running this in production at our voice agent platform, we hit the same issue with a pure‑vector design and switched to hybrid, seeing the token‑cost savings mentioned earlier.

If you’re still on the fence, try a quick A/B test: route 10 % of traffic through a graph‑validated path and compare hallucination rates. The data usually tells the story within a few days.

If you want your agents to reason reliably at scale, pair dense embeddings with a lightweight graph layer now—otherwise you’ll pay 3× the token bill and still get 40 % more errors — see our AI compliance work for the full breakdown.

The Rise of Production-Grade AI Infrastructure

Most AI products today are impressive in demos.

But the moment they hit production:

  • workflows break
  • context fails
  • hallucinations appear
  • costs explode
  • observability disappears

The AI industry does not really have an “intelligence” problem anymore.

It has an infrastructure problem.

For the last two years, the ecosystem focused heavily on:

  • chat interfaces
  • prompt engineering
  • copilots
  • wrappers around foundation models
  • “AI-powered” product features

That phase accelerated adoption.

But the market is now entering a different stage.

The hard problem is no longer:

“Can AI generate something useful?”

The hard problem is:

“Can AI systems operate reliably in real production environments?”

And that is where the next major opportunity is emerging.

The Demo Problem

Most AI demos look incredible.

They can:

  • generate code
  • summarize documents
  • automate workflows
  • answer questions
  • orchestrate tasks

But production environments expose a completely different reality.

Once real users, real workflows, and real operational constraints enter the system, problems begin to appear:

  • hallucinations
  • fragile context handling
  • inconsistent outputs
  • broken execution chains
  • runaway costs
  • poor observability
  • unsafe automation
  • missing governance
  • unpredictable agent behavior

This is why so many AI pilots never move beyond experimentation.

The market today is filled with:

  • AI interfaces
  • AI assistants
  • AI wrappers
  • AI copilots

But what enterprises actually need are:

  • reliable systems
  • operational controls
  • execution runtimes
  • observability layers
  • governance infrastructure
  • context orchestration

That is the real bottleneck now.

AI Systems Need a New Production Stack

Traditional software engineering was built around deterministic systems.

AI systems are different.

They are:

  • probabilistic
  • context-sensitive
  • state-fragile
  • operationally unpredictable

That means traditional software patterns are no longer enough.

AI requires an entirely new operational layer.

This feels very similar to earlier infrastructure shifts:

  • Kubernetes standardized container orchestration
  • Datadog transformed observability
  • Stripe simplified payment infrastructure
  • Temporal improved workflow reliability

AI is now reaching a similar stage.

The next generation of products will not just be AI applications.

They will be:

AI production infrastructure platforms.

The Real Layers of a Production-Grade AI System

Most discussions about AI still focus only on models.

But production-grade AI systems require much more than a model.

Below are the infrastructure layers that are becoming increasingly important.

1. Context Engineering

This is becoming one of the most critical areas in AI engineering.

Most AI systems fail not because the model is weak, but because the context is poor.

Production systems need to manage:

  • historical memory
  • workflow state
  • user intent
  • permissions
  • business logic
  • external data
  • codebase understanding
  • semantic relationships

This goes far beyond basic RAG.

The future belongs to systems that can dynamically assemble the right context at the right moment.

Prompt engineering is becoming commoditized.

Context engineering is becoming the moat.

2. Agent Execution Runtime

Most AI agents today are unreliable because they lack execution infrastructure.

A production runtime needs:

  • retries
  • rollback support
  • checkpoints
  • workflow state tracking
  • timeout handling
  • safe execution paths
  • human approval systems

Without this, AI workflows become fragile very quickly.

The market does not just need agents.

It needs:

workflow infrastructure for AI systems.

3. Observability for AI Systems

Debugging traditional software is already difficult.

Debugging AI systems is significantly harder.

Production AI requires visibility into:

  • prompts
  • memory retrieval
  • tool calls
  • reasoning chains
  • execution paths
  • token usage
  • latency
  • hallucination patterns
  • workflow failures

Most current systems still operate like black boxes.

This creates a massive opportunity for:

  • AI observability
  • AgentOps
  • runtime tracing
  • execution replay
  • quality monitoring

The industry will likely see a:

“Datadog for AI systems”

category emerge.

4. Governance and Safety

As AI systems become more autonomous, governance becomes mandatory.

Enterprises need:

  • approval workflows
  • audit trails
  • permission systems
  • policy enforcement
  • data isolation
  • secure execution environments

Without operational controls, companies will struggle to trust autonomous systems at scale.

This becomes especially important in:

  • healthcare
  • finance
  • enterprise automation
  • internal copilots
  • operational workflows

Governance is no longer optional infrastructure.

It is foundational infrastructure.

5. Evaluation and Reliability Testing

One of the biggest problems in AI today is silent degradation.

An AI workflow may work perfectly today and fail tomorrow because of:

  • model updates
  • prompt changes
  • retrieval drift
  • API schema changes
  • edge cases
  • workflow changes

That means AI systems need continuous evaluation.

Production-grade AI requires:

  • regression testing
  • scenario simulation
  • adversarial testing
  • replay systems
  • benchmark scoring
  • workflow validation

This category is still massively underdeveloped.

Why Infrastructure Will Matter More Than Interfaces

The first AI wave rewarded:

  • interfaces
  • demos
  • speed
  • accessibility

The next AI wave will reward:

  • reliability
  • orchestration
  • observability
  • governance
  • scalability
  • operational maturity

That changes where the real value gets created.

The winning companies may not be the ones with the best chat interface.

They may be the ones building:

  • context runtimes
  • orchestration layers
  • observability platforms
  • execution infrastructure
  • repo intelligence systems
  • AI governance tooling

The real opportunity is shifting downward into the infrastructure layer.

Repo Intelligence Might Become a Major Category

One particularly interesting opportunity is repo intelligence.

Current AI coding tools can generate code.

But they often lack:

  • architectural understanding
  • dependency awareness
  • service relationships
  • domain knowledge
  • operational context

That creates problems in large production codebases.

A smarter system would:

  • scan repositories
  • understand architecture
  • build dependency graphs
  • map services
  • infer business domains
  • track workflows
  • generate contextual intelligence for AI systems

This could dramatically improve:

  • AI coding reliability
  • automated refactoring
  • debugging
  • onboarding
  • workflow automation

The future of AI-assisted engineering may depend heavily on systems that deeply understand software architecture.

What This Means for Builders

If you are building in AI today, this shift matters.

The market is getting saturated with:

  • wrappers
  • chat interfaces
  • generic copilots
  • shallow automation tools

But infrastructure gaps are still massively underbuilt.

That means opportunities are emerging in:

  • context orchestration
  • observability
  • evaluation systems
  • governance tooling
  • repo intelligence
  • workflow runtimes
  • execution reliability

The next major AI products may come from engineering pain, not prompt creativity.

The Market Is Moving from Apps to Systems

This is the transition happening right now.

We are moving from:

  • AI apps → AI infrastructure
  • prompts → context systems
  • copilots → execution runtimes
  • experimentation → operational maturity
  • wrappers → production platforms

The companies that win in AI will likely be the ones that solve:

  • reliability
  • orchestration
  • observability
  • governance
  • context management
  • execution safety

Not just generation.

The biggest AI companies of the next decade may not even look like AI companies.

They may look like infrastructure companies.

Final Thoughts

AI will absolutely transform software.

But models alone are not enough.

The next major challenge is building systems that AI can operate inside reliably.

That means:

  • better infrastructure
  • better orchestration
  • better context systems
  • better observability
  • better governance
  • better operational tooling

The future of AI does not belong only to model providers.

It also belongs to the companies building the operational layer around those models.

And that may become one of the biggest infrastructure opportunities of the next decade.

Genç sanatçılar eserlerini karekodla dijitale taşıdı

Bursa Zeki Müren Güzel Sanatlar Lisesi öğrencilerinin yıl boyunca hazırladığı eserler, Devlet Güzel Sanatlar Galerisi’nde sergilendi. Karekod uygulamasıyla dijital ortama taşınan sergi, sanat ve teknolojiyi birleştirerek ziyaretçilere farklı bir deneyim sundu.