Kurbanlık alacaklara “Küpe kontrolü” uyarısı

Tekirdağ İl Tarım ve Orman Müdürü Mehmet Aksoy, kurbanlık alacak vatandaşlara hayvanların küpe bilgilerini TarımCebimde uygulaması üzerinden kontrol etmeleri çağrısında bulundu. Ayrıca, olumsuz durumların ALO 174 Gıda hattına bildirilmesini istedi.

Membangun Kompetensi dan Relasi: Mengapa Ekosistem Kampus Itu Penting

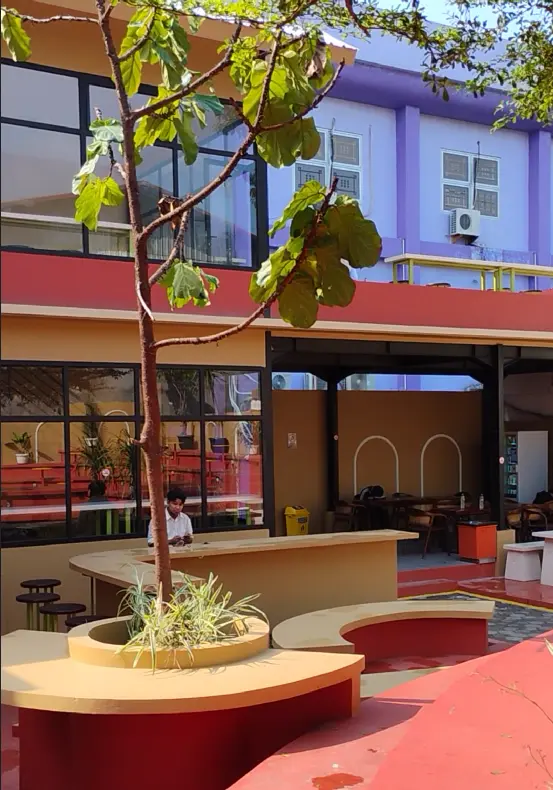
Suasana area santai Food Corner dan Coworking Space di depan Gedung 4 Universitas Amikom Yogyakarta dengan tempat duduk melingkar

Membangun kompetensi di dunia teknologi jelas butuh lingkungan yang mendukung. Universitas Amikom Yogyakarta menyediakan ekosistem terintegrasi untuk menjembatani jarak antara teori akademik dan kebutuhan industri yang sebenarnya. Bagi saya pribadi, ketersediaan sarana kampus bukan sekadar pendukung jadwal perkuliahan, melainkan sebuah ruang untuk mengasah keterampilan teknis serta inovasi secara langsung.

Gambaran lengkap mengenai visi dan infrastruktur kampus dapat disimak melalui tayangan profil berikut:

Sumber video: Channel YouTube Universitas AMIKOM Yogyakarta

Selain fasilitas utama seperti laboratorium, area pendukung seperti Coworking Space atau Food Corner yang terletak di depan Gedung 4 memegang peranan yang tidak kalah penting. Area terbuka ini menjadi titik temu favorit saya beserta banyak mahasiswa lain untuk berkolaborasi dalam pengerjaan proyek, bertukar ide arsitektur aplikasi, maupun sekadar membangun relasi profesional. Penggunaan fasilitas publik semacam ini sangat melatih kemampuan komunikasi dan kerja tim yang esensial di dunia kerja nantinya.

Suasana area santai Food Corner dan Coworking Space di depan Gedung 4 Universitas Amikom Yogyakarta dengan tempat duduk melingkar

Integrasi berbagai fasilitas mulai dari laboratorium komputer, pusat layanan riset, hingga studio kreatif memperlihatkan bagaimana aspek teknis dan industri berjalan berdampingan secara harmonis. Infrastruktur ini memastikan kita mampu menguasai keahlian spesifik sekaligus memahami nilai praktis dari sebuah produk digital sebelum terjun langsung ke pasar kerja.

Kesiapan fasilitas kampus benar benar memberikan nilai tambah yang signifikan bagi pengembangan diri. Lingkungan yang kondusif memungkinkan kita untuk mematangkan persiapan karier sejak dini dengan standar yang mendekati kebutuhan industri modern.

Menurut kalian, seberapa besar pengaruh fasilitas kampus terhadap kesiapan kerja mahasiswa? Silakan bagikan pendapat kalian di kolom komentar ya! Jangan lupa tinggalkan Reactions (Like) dan klik Follow jika artikel ini bermanfaat.

I Built an AI That Decides Which AI to Talk To — Running 24/7 From My Living Room

Today morning when I waked up, my AI agent reviewed 14 restaurant ratings in Indiranagar, updated a shared Google Sheet, signed a 20-page PDF I’d been ignoring for a week, and wrote a bash script to clean up my server logs.

I didn’t ask it to do any of that. It just… does things now.

Meet OpenClaw — my long-running autonomous agent that lives on a Raspberry Pi, plugged into Discord, running 24/7. It manages my memory, handles research, writes code, edits documents, finds the best weekend spots in Bangalore by scraping live ratings — basically, it runs half my life on autopilot.

But a few weeks ago, I noticed something that bothered me.

I asked it: “Write a Python script to parse JSON logs.” Simple coding task. It sent that request to a cloud API, waited 3 seconds, burned tokens I paid for, and came back with an answer — when I had a perfectly capable local LLM sitting idle on my Mac Mini, three feet away.

Then I asked: “Think step by step about the trade-offs between event-driven vs polling architecture for my notification system.” That’s a hard reasoning question. I want that going to a frontier model. That’s worth the tokens.

Same agent. Same endpoint. Completely different needs.

And that’s when a stupid idea hit me:

What if the system could figure out which brain to use — before the request even reaches a model?

Turns out, it’s not stupid at all. And it took me a weekend, a Raspberry Pi, a Mac Mini, 50 lines of Python, and an open-source gateway to build it.

Here’s how.

The Setup

Here’s what’s running in my living room:

Raspberry Pi → Runs OpenClaw, my autonomous agent. It takes input from Discord, manages context, memory, and orchestrates everything.
Mac Mini → The brain farm. Runs three things:
Ollama with qwen2.5-coder:7b — a local coding model that never leaves my network
AgentGateway — an open-source AI gateway from Google that handles routing, auth, observability
A lightweight Python router — the “intent classifier” I wrote in ~50 lines of code
The magic? OpenClaw doesn’t know any of this is happening. It just sends a request to one endpoint. Behind the scenes, the system figures out the rest.

The Architecture

Three models. Three price points. One unified endpoint. OpenClaw just hits http://192.168.1.15:1234/v1/chat/completions and forgets about it.

Why AgentGateway?

I evaluated a few options — raw Envoy, Nginx with Lua scripting, even building a full proxy from scratch. But AgentGateway stood out for a few reasons:

What it gives you out of the box:
Protocol translation — It speaks OpenAI-compatible API on the frontend, but can talk to Gemini, Vertex AI, Bedrock, Ollama, and more on the backend. I don’t write a single line of provider-specific code.
Backend authentication — API keys are managed at the gateway level. OpenClaw never sees or stores any API key. I just set backendAuth: key: $GEMINI_API_KEY in the config and it handles the rest.
Model aliasing — OpenClaw sends model: “inteli-llm” in every request. AgentGateway silently translates that to qwen2.5-coder:7b, gpt-4o, or gemini-2.5-flash depending on which route matched. The client has no idea.
Observability — Every request gets logged with provider name, model, token counts, and latency. I can see exactly how many tokens are going to OpenAI vs staying local.
Prompt guards & rate limiting — Built-in regex-based PII masking, webhook-based content moderation, and rate limiting. Enterprise-grade features I get for free.
Weighted load balancing & failover — If Ollama crashes (it happens), I can configure automatic failover to a cloud model. No downtime.
What it doesn’t do (yet): Content-aware routing. AgentGateway routes based on path, headers, and methods — which is the right design for a gateway. It doesn’t peek into your request body to decide where to send it. That’s a feature, not a bug — gateways should be fast and protocol-level, not parsing JSON payloads.

But I needed content-aware routing. So instead of searching for other tool, I extended it.

The 50-Line Router That Makes It All Work

I wrote a tiny FastAPI proxy that sits in front of AgentGateway. Here’s what it does:

  • Intercepts the incoming OpenAI-compatible request
  • Reads the last message in the chat
  • Classifies intent using simple keyword matching + prompt length heuristics:
    • Contains code, python, script, function, bug? → coding
    • Contains think, analyze, reasoning, deduce? Or prompt > 400 chars? → reasoning
    • Everything else? → simple
  • Injects an x-intent HTTP header
  • Forwards the request to AgentGateway untouched
    That’s it. No ML model for classification. No vector databases. No semantic similarity. Just good old keyword matching that works 90% of the time — and that’s good enough for a homelab.
coding_keywords = ["code", "python", "javascript", "bash", "script", "function", "bug"]
reasoning_keywords = ["think", "analyze", "explain in detail", "reasoning", "logic", "deduce"]

if any(k in prompt_lower for k in coding_keywords):
    intent = "coding"
elif len(prompt) > 400 or any(k in prompt_lower for k in reasoning_keywords):
    intent = "reasoning"
else:
    intent = "simple"

The Cost Equation

Here’s what this setup actually saves me:

Intent Model Where it runs Cost per 1M tokens
Coding qwen2.5-coder:7b Local (Ollama) $0
Simple Q&A gemini-2.5-flash Google Cloud ~$0.15
Deep Reasoning gpt-4o OpenAI ~$2.50

Before this setup, every single request was going to a cloud API. Now, roughly 60-70% of my queries stay local — coding questions, quick lookups, simple formatting tasks. They’re fast, free, and private.

The expensive reasoning model only gets called when I genuinely need it. And the mid-tier Gemini handles everything in between.

My monthly API bill dropped significantly, and the local responses are actually faster.

Design Choices & Why They Worked

1. Header-based routing over path-based routing Initially, I was going to use URL paths (/coding, /reasoning, /simple) and strip them with URL rewriting. But header injection is cleaner — the original request path stays intact, and AgentGateway’s header matching is first-class.

2. Classification at the proxy, not the gateway I could have tried to use AgentGateway’s CEL expressions or ExtProc policies for classification. But those run after backend selection, not before. Keeping classification in a separate lightweight layer means I can swap algorithms without touching my gateway config.

3. Keyword heuristics over ML classifiers Could I use a small classifier model or even RouteLLM for smarter routing? Absolutely. But for a homelab, keyword matching is:

  • Zero latency overhead
  • Zero dependencies
  • Easy to debug (just read the logs)
  • Surprisingly accurate for my use cases

4. One unified model name OpenClaw sends model: "inteli-llm" for everything. AgentGateway’s modelAliases feature translates it per-route. This means I can swap out backend models without touching a single line of OpenClaw’s config. Last week it was gemini-1.5-flash, this week it’s gemini-2.5-flash. OpenClaw never knew.

What’s Next

Smarter classification — Maybe a tiny local classifier model, or even using the first few tokens of a response to reclassify and retry on a better model.
Metrics dashboard — AgentGateway already emits OpenTelemetry traces. I want to hook up a Grafana dashboard to see which models are handling what, with latency and token breakdowns.
Failover chains — If Ollama is under heavy load, automatically fall back to Gemini for coding tasks. AgentGateway supports priority groups for this.
More agents — OpenClaw is just the beginning. I want to run specialized agents for different domains, all routing through the same gateway.

The Takeaway

You don’t need a Kubernetes cluster or a $10K GPU server to build a multi-model AI system. A Raspberry Pi, a Mac Mini, an open-source gateway, and 50 lines of Python got me:

✅ An always-on autonomous agent ✅Intelligent routing ✅across 3 different LLMs ✅Local-first for privacy and speed ✅Cloud when I need the horsepower ✅Zero API keys exposed to the client ✅A monthly bill I actually don’t mind paying

The best part? The entire config is a single YAML file and a single Python script. No Docker. No Kubernetes. No Terraform. Just two processes on a Mac Mini and an agent on a Pi.

Sometimes the best infrastructure is the one you can explain in a napkin sketch.

If you’re building something similar or want to see the config files, drop a comment — happy to share the full setup.

AI #HomeAssistant #LLM #AgentGateway #Ollama #OpenAI #Gemini #HomeLab #BuildInPublic #MacMini #RaspberryPi #AIEngineering

How to Actually Become a Programmer: The Hard Part Nobody Wants to Explain

There is a comfortable myth around becoming a programmer. It says you can watch a few courses, copy a few tutorials, build a portfolio app, learn a modern framework, and become employable in a few months. Sometimes that happens. More often, it creates people who know how to repeat steps, but do not yet understand what they are doing.

Programming is not mainly about knowing syntax. It is not about collecting certificates. It is not even about choosing the perfect first language. A programmer solves problems by turning unclear ideas into working systems. That requires a very specific skill: the ability to think in code.

That skill is built through long, focused practice. There is no polite shortcut around it.

Programming Is Not Watching Someone Else Program

Many beginners spend too much time preparing to learn. They watch videos about roadmaps. They compare languages. They join communities. They read debates about whether Java, Python, Go, C#, JavaScript, Rust, or C++ is the best first language.

Some of that research is useful. Too much of it becomes procrastination.

At some point, you have to write code. Then you have to break it, fix it, extend it, read other people’s code, get confused, search for answers, rebuild the project, and repeat the process until the confusion becomes more structured.

That is the part that many beginner programs hide. Real programming skill appears when your brain starts connecting three things:

  1. What does the task mean
  2. How the program should behave
  3. How to express that behavior in code

Until that connection becomes natural, every problem feels like a wall. After enough practice, the wall does not disappear, but you start seeing cracks in it.

Focus Matters More Than Motivation

One brutal but useful truth is that becoming a programmer requires a serious period of focus. Not a year in isolation, and not ten hours every day, but enough uninterrupted time to let your brain adapt.

Programming is cognitively expensive. You hold state in your head. You trace logic. You remember assumptions. You compare what the program should do with what it actually does. Constant interruption destroys that process.

A beginner who studies for eight distracted hours may learn less than someone who spends two focused hours every day writing and debugging code. The real requirement is not suffering. It is continuity.

You need enough regular practice to keep the work warm in your mind. If you return to the same project only once a week, you spend most of your time remembering what you were doing. If you work every day, even briefly, the project starts living in your head. That is when learning accelerates.

But remember, mental exhaustion is not the same as discipline. If you burn out, stop sleeping, stop moving, and turn learning into punishment, your code will not improve for long. Programming requires concentration, memory, patience, and emotional stability. Destroying those things is not heroic.

A better rule is this: Create an environment where deep work is possible, but protect the body and mind that have to do that work. Take walks. Sleep. Exercise. Step away when stuck. Many programming problems are solved after your brain gets distance from them.

Choose a First Language, but Do Not Worship It

Some strongly argue for Java as a first language. Others push back, with fair reasons.

Java is a reasonable first language because it has mature tooling, strong typing, many books, many examples, and a large ecosystem. It also forces beginners to deal with structure. You learn classes, methods, types, compilation, packages, build tools, and errors that are often explicit enough to teach you something.

But Java is not the only valid path.

  • C# is no longer simply “Windows only.” Modern .NET works well on Linux and is widely used for backend development.
  • Go is mature enough for real production systems and is simpler than many languages.
  • Python is excellent for learning basics and building useful scripts, though it can hide some concepts.
  • JavaScript is unavoidable if you are interested in web development.
  • C teaches valuable lessons about memory and machines, but it can be punishing as a first language.

The better advice is this: Choose a language that lets you build things you care about while still teaching you real programming concepts.

If you want backend systems, Java, C#, Go, or Python can all work. If you want web interfaces, JavaScript or TypeScript will become necessary. If you want systems work, C, C++, or Rust may eventually matter. If you want mobile, Swift or Kotlin may be more relevant. The first language is not a life sentence. It is a training environment. What matters is that you do not jump between languages every two weeks because the next one looks easier.

Start With Exercises, but Do Not Stay There

Textbook exercises are useful because they isolate concepts. You should write small programs that teach variables, loops, functions, collections, files, errors, data structures, and basic algorithms.

But exercises alone are not enough. A person can complete 100 small tasks and still freeze when faced with a real codebase. Real projects are messy. They have naming conventions, build files, dependencies, old decisions, strange abstractions, and code written by people who are no longer around.

That is why one of the best learning methods is modifying existing open source software. Not contributing immediately and not trying to impress maintainers. Just learning to work with a real project.

Clone something. Build it locally. Change a label. Remove a button. Add logging. Disable one branch of logic. Find where a configuration value is read. Break the build and fix it. Trace a request from the entry point to the output.

This teaches skills tutorials rarely teach:

  • How projects are structured
  • How build systems work
  • How errors appear in real code
  • How abstractions are used and abused
  • How to read code written by someone else

That last skill is critical. Professional developers spend a huge amount of time reading and changing existing code. Greenfield work is the exception, not the norm.

Build Something Personally Useful

One of the best insights is simple: write programs that are useful to you. A textbook task may teach a concept, but a personally useful project keeps you emotionally involved. That matters. Curiosity makes difficult work survivable.

Build a small tool for yourself. A notes app. A file organizer. A text parser. A personal dashboard. A tiny game. A command-line utility. A script that automates something boring. A small editor. A local search tool. A budget tracker. Anything you would actually use.

The point is not originality. The point is friction. A useful project forces real questions:

  • Where should data be stored?
  • What happens when the input is wrong?
  • How should errors be shown?
  • How do I package and run this again tomorrow?
  • What part became painful to change?
  • Why did this simple feature make the code ugly?

Those questions are where programming starts becoming engineering.

Use Search and AI, but Do Not Outsource Your Brain

There is a strong debate about whether a programmer should rely on search engines or AI. The sensible answer is somewhere in the middle. A developer who cannot search is ineffective. Documentation, examples, issue trackers, source code, specifications, and community discussions are part of the job. But a beginner who searches every basic step without understanding the answer is also in trouble.

There is a big difference between searching:

“How do I parse command line arguments in Go?”

and searching:

“How do I write a program?”

The first is normal. The second means the foundation is missing.

AI assistants make this distinction even more important. They can help generate examples, explain errors, create small scripts, and suggest approaches. They can also hallucinate APIs, produce insecure code, and hide the learning process behind confident output.

Use AI like a junior assistant, not like a replacement brain. Ask it to explain. Ask it for alternatives. Ask it to review your code. Ask why a solution works. Then verify the answer against documentation and run the code yourself. The goal is to keep responsibility for understanding.

Courses and Mentors Help, but They Cannot Do the Work

Courses can give structure. Mentors can save you from wasting weeks on the wrong path. A good teacher can explain concepts that documentation makes needlessly painful.

But no mentor can install programming skills into your head. You still need the hours. You still need the frustration. You still need to debug your own misunderstanding.

The best use of a mentor is not asking them to solve everything. It is asking better questions:

  • “I tried this approach, but the state becomes inconsistent here. What am I missing?”
  • “I solved it this way. Is there a simpler design?”
  • “This code works, but it feels hard to change. Why?”

Passive watching does not build the judgment that comes from real conversation.

What “Ready for Work” Really Means

You do not need to know everything to get your first developer job. Nobody does. But you should be able to do certain things without panic:

  • Set up a development environment
  • Build and run a project
  • Read errors and investigate them
  • Use Git for basic workflows
  • Write simple features
  • Write basic tests
  • Read unfamiliar code
  • Ask precise technical questions
  • Search documentation effectively
  • Explain what you changed and why
  • Accept code review without collapsing emotionally

That is already far beyond “I watched a course.” The gap between what candidates expect and what employers actually look for is wider than most beginners realize — and closing it requires exactly the practical work described above.

Final Thoughts

Becoming a programmer is not about entering the IT industry. It is about learning to think clearly enough that a machine can execute your idea. That takes time. It takes repetition. It takes curiosity. It takes humility to be wrong 20 times before the program finally works.

The good news is that the path is not mysterious. Write code. Read code. Change code. Break code. Debug code. Build things you care about. Study the concepts behind the tools. Use search and AI carefully, but do not let them replace your understanding.

At some point, you will notice that you are no longer merely copying solutions. You are thinking in code. That is when you start becoming a programmer.

Building a Production-Style Multi-Tool AI Agent with Python, Flask, React & Gemini AI

Artificial Intelligence is rapidly evolving from simple chatbots into intelligent automation systems capable of performing real-world actions. Over the last few months, I have been deeply exploring AI automation workflows, backend engineering and full stack development during my AI & Automation Internship at NEXE.AGENT.

One of the most exciting outcomes of this journey is my latest project:

NEXEAGENT Multi-Tool AI Agent

A production-style AI automation assistant designed to intelligently perform multiple tasks including:

  • AI-powered conversations
  • AI & Web Development job search
  • Notes management
  • Email automation
  • Utility tool execution
  • Workflow-based AI interactions

Unlike traditional chatbot systems, this project focuses on creating an AI assistant that can actually take actions instead of only generating responses.

Project Vision

The main idea behind this project was simple:

Build an AI system that behaves more like an intelligent assistant than a normal chatbot.

The agent can analyse prompts, select tools, execute functions, manage workflows and return structured results.

For example, the AI agent can:

  • Search remote AI jobs
  • Extract useful information
  • Save important notes
  • Send automated emails
  • Run custom utility tools
  • Manage chat history and logs

This project helped me understand how modern AI agents are designed and how multiple systems can work together inside a single intelligent workflow.

Technologies Used

The complete project was built using modern full stack technologies.

Backend

  • Python
  • Flask
  • Google Gemini AI API
  • JSON Database System
  • Gmail SMTP Automation

Frontend

  • React.js
  • Vite
  • Tailwind CSS
  • Responsive Dashboard UI

Additional Systems

  • Function-based AI tools
  • Modular API architecture
  • Logging & history management
  • AI workflow routing

Core Features

🤖 AI Chat Agent

The system uses Google Gemini AI to process prompts and intelligently decide which tool or workflow should be executed.

💼 AI Job Search

The platform can search for:

  • AI jobs
  • Python jobs
  • React jobs
  • Flask jobs
  • Full stack jobs
  • Remote developer opportunities

The AI agent summarizes results and organizes useful information.

📝 Notes System

A lightweight JSON-based note management system allows saving important links, summaries and AI-generated outputs.

📧 Email Automation

The platform integrates Gmail SMTP automation to send emails directly through the AI workflow.

🛠 Utility Tools

Custom tools include:

  • Calculator
  • URL extractor
  • Keyword extractor
  • Text summarizer
  • JSON formatter
  • Date & time utilities

🏗 Architecture & Workflow

One of my main goals during development was to maintain a professional and scalable project structure.

The project uses:

  • Modular Flask backend architecture
  • Route separation
  • Service-based AI logic
  • Tool-based execution system
  • JSON database handling
  • Reusable frontend components

This structure makes the application easier to scale and maintain.

Challenges & Learning Experience

During development, I faced several real-world engineering challenges:

  • Open API Limited Tokens
  • Gemini API integration issues
  • SMTP configuration problems
  • Tool execution debugging
  • Frontend/backend communication
  • Environment variable management
  • JSON data handling

Solving these issues helped me gain practical experience in:

  • AI automation systems
  • API integration
  • Backend engineering
  • Full stack development
  • Production-style debugging
  • Professional GitHub workflows

🌍 Why This Project Matters

AI automation is becoming one of the most important areas in software engineering.

This project represents more than just a chatbot.
It demonstrates how AI can:

  • Interact with tools
  • Execute workflows
  • Automate tasks
  • Manage data
  • Improve productivity
  • Assist developers intelligently

Building projects like these is helping me move deeper into the world of AI engineering and automation systems.

🔗 GitHub Repository

You can explore the complete project here:

Repository: https://github.com/YasirAwan4831/nexeagent-multi-tool-ai-agent

👨‍💻 Connect With Me

GitHub

https://github.com/YasirAwan483

LinkedIn

https://linkedin.com/in/yasirawan4831

I’m currently focused on:

  • AI Automation
  • Full Stack Development
  • Python Backend Systems
  • Intelligent AI Workflows
  • Automation Engineering

Final Thoughts

This project was an incredible learning experience and helped me better understand how modern AI systems can be structured professionally.

From backend APIs to AI workflows and frontend dashboards, every part of this project contributed to improving my engineering mindset and practical development skills.

I’m excited to continue building more intelligent systems, automation platforms and AI-powered applications in the future

Thanks for reading.

#AI #Automation #Python #Flask #React #GeminiAI #FullStackDevelopment #SoftwareEngineering #ArtificialIntelligence #WebDevelopment #GitHub #NEXEAGENT #AIProjects #MuhammadYasir #YasirAwan4831

# Building Instagram OSINT Projects with HikerAPI

I recently experimented with building an Instagram OSINT project on Linux using Python and HikerAPI. Originally I tried older scraping libraries and unofficial Instagram API wrappers, but many of them were unreliable because Instagram now aggressively blocks automation attempts.

After some testing, I found that using an external API service like HikerAPI was much more stable for learning and development purposes.

Why I Switched

At first I used tools based on:

  • instagram-private-api
  • old scraping scripts
  • login-based automation

The problem was:

  • constant login checkpoints
  • “bad_password” errors even with correct credentials
  • temporary account locks
  • broken endpoints

Modern Instagram protection systems make direct scraping much harder than before.

My Setup

I used:

  • Arch Linux
  • Hyprland
  • Python virtual environment
  • HikerAPI

Creating the virtual environment:

python -m venv venv
source venv/bin/activate.fish

Installing dependencies:

pip install requests httpx

Basic HikerAPI Example

Here’s a simple request example:

import requests

headers = {
    "x-access-key": "YOUR_KEY"
}

r = requests.get(
    "https://api.hikerapi.com/v2/user/by/username?username=instagram",
    headers=headers
)

print(r.json())

What I Learned

A few things became obvious during testing:

  1. Old Instagram scraping methods are becoming unreliable.
  2. API-based approaches are much easier to maintain.
  3. Using a Python virtual environment on Linux avoids dependency issues.
  4. Sherlock and other username OSINT tools are still useful alongside APIs.

Tradeoffs

HikerAPI is convenient, but it’s not fully free. You need credits for larger usage. For hobby projects and learning, that may still be easier than constantly fixing broken scrapers.

Meanwhile, tools like:

  • Sherlock
  • Maigret
  • Google Dorking
  • Wayback Machine

are still excellent for public OSINT workflows.

Final Thoughts

This was a fun experiment for learning Python, Linux tooling, and OSINT workflows. If you’re building similar projects, I’d strongly recommend:

  • using virtual environments
  • avoiding your main Instagram account
  • testing on dummy accounts
  • learning public OSINT techniques first

HikerAPI definitely simplified the process compared to older scraping approaches.