Designing an In-Game Inflation Tracking Algorithm for Web Utility Apps

In modern web development, scaling an application to track real-time transactional data presents unique hurdles especially when tracking hyper-volatile secondary market economies like the Blox Fruits Easter Update.

Traditional gaming utility sites rely on static JSON tables or manual content management updates. The fatal flaw here is a structural 48-to-72-hour data lag. In a market where server updates shift item demand in minutes, static lists cause users to make highly unfavorable trades.

To combat this, we developed a responsive computing framework for our production node at the Blox Fruits Value Calculator, which processes algorithmic demand weights rather than raw, unchanging price points.

The Mathematical Framework of Demand Scaling

To calculate true market parity, an algorithm cannot look at an item’s hardcoded “Beli” store cost alone. It must evaluate an item’s real-time transactional velocity ($V$) against its current active circulation ($C$).

We structure our calculations using a baseline multipliers approach:

$$M_v = frac{V_t cdot alpha}{C_s cdot beta}$$

Where:

  • $M_v$ represents the dynamic velocity multiplier.
  • $V_t$ is the volume of logged trade attempts in a rolling 60-minute window.
  • $C_s$ represents known item liquidity based on drop rates.
  • $alpha$ and $beta$ are normalization constants adjusted during server events.

For developers interested in inspecting how these arrays are set up on the backend, you can review our open-source structural schema inside this Raw JSON Data Repository on GitLab.

Mitigating Front-End Calculation Lag

When dealing with massive traffic surges during event periods, running complex database queries on every user interaction will crash standard serverless instances.

To achieve optimal performance, we implemented a localized calculation engine:

  1. The server caches the macro-level $M_v$ multipliers globally every 5 minutes.
  2. The user’s browser executes the raw trade comparison equations locally using a lightweight JavaScript architecture.
  3. This decouples database read operations from user input, reducing server response times down to sub-10ms.

We initially mapped this UI layout within an open interactive sandbox environment, which you can view in our production-ready CodePen UI Sandbox Prototype.

Conclusion

Building software for gaming communities requires the same structural integrity as traditional SaaS applications. By moving away from static database rows and moving toward algorithmic, cached calculations, you can scale a lightweight utility site to handle millions of active users with minimal overhead.

Maintained by Qamar Farooq | SEO Architect & Systems Developer at BloxValues.net

Google AI Studio Just Changed the Shape of App Development

This is a submission for the Google I/O Writing Challenge

The browser is becoming the IDE, the backend, the deployment pipeline and the App factory

The most important thing Google announced at I/O 2026 was not a model.

It was the disappearance of friction.

At first I dismissed Google AI Studio as another polished keynote demo. Then I realized Google wasn’t showing a coding assistant. It was showing an attempt to compress the entire app lifecycle into one surface.

That distinction matters.

For years, AI-assisted development mostly meant faster scaffolding. Generate some boilerplate. Autocomplete a function. Maybe prototype a UI. But the moment you needed authentication, deployment, testing, data integration, or collaboration, you fell back into the usual maze of setup overhead and infrastructure churn.

This year felt different.

Google AI Studio now sits at the center of a workflow where an idea can move from prompt → prototype → backend → Android test track with surprisingly little context switching. The browser is no longer just where developers read documentation and manage tickets. It is starting to look like the place where software begins.

And honestly, that may end up being the biggest story from Google I/O 2026.

Most dev tools optimize stages. AI Studio is optimizing handoffs.

That was the real insight I kept coming back to while watching the announcements.

Most developer platforms improve one slice of the workflow:

  • better code editing,
  • better deployment,
  • better testing,
  • better backend tooling.

AI Studio feels different because the focus is not just generation. It is continuity.

Google showed a workflow where developers can:

  • generate native Android apps with Kotlin and Jetpack Compose,
  • preview them directly in the browser,
  • connect Workspace data like Sheets and Drive,
  • test apps through browser emulators or ADB,
  • export projects into Antigravity with context preserved,
  • and move directly into Play Internal Testing.

Individually, none of those features are revolutionary.

Together, they are.

Because the painful part of software development has never been creating the first prototype. The painful part is what happens after the prototype:

  • authentication,
  • deployment,
  • collaboration,
  • environment setup,
  • infrastructure wiring,
  • handoffs between tools,
  • and maintaining momentum once the original creative spark fades.

Google’s new stack appears designed around reducing those transitions.

That is a much bigger ambition than “AI coding assistance.”

I tried a small workflow, and one thing surprised me

During one of the keynote replays, I tested the flow by sketching a tiny Android app concept that turned a messy Google Sheet into a lightweight issue tracker.

Nothing ambitious.

Just:

  • issue cards,
  • owner names,
  • due dates,
  • and simple status labels.

What surprised me was not the generated UI.

It was how naturally context carried between steps.

The system understood the structure of the Sheet surprisingly well. Moving from prompt to preview did not feel like starting over repeatedly. Small interface edits happened inside the same flow instead of forcing a tool switch every few minutes.

The strange part was how quickly I stopped thinking about the tooling. After a while, the workflow stopped feeling like “AI-assisted development” and started feeling like a normal creative process with less drag.

That feeling stuck with me more than any individual feature announcement.

Because the real innovation here may not be intelligence alone.

It may be momentum.

The hidden story is convergence

I think many people focused on the flashy AI demos and missed the more important architectural shift happening underneath them.

Google AI Studio, Firebase, and Antigravity no longer feel like isolated products.

They feel like layers of the same pipeline.

AI Studio is becoming the idea-to-prototype layer.

Firebase is increasingly becoming the agent-aware backend layer.

Antigravity looks positioned as the deeper engineering and orchestration layer where larger systems evolve after the prototype stage.

That matters because older no-code and low-code platforms usually collapsed at the handoff point. The prototype was easy, but scaling or customizing it often required a painful rewrite.

Google seems to understand that the handoff itself is the product.

That is why preserving project context, conversation history, and configuration between environments matters so much. The workflow feels less like generating throwaway demos and more like continuing software development across different levels of complexity.

That is a subtle but important shift.

This changes who gets to start

One consequence of cheaper software creation is that more people can participate earlier.

A solo founder can validate an idea faster.

A designer can build a functional prototype before involving engineering.

A product manager can test workflows without waiting on infrastructure setup.

And developers can spend less time wiring repetitive systems before reaching meaningful experimentation.

That does not eliminate engineering complexity.

But it changes where effort gets spent.

If the first draft of software becomes dramatically cheaper, then competitive advantage shifts toward:

  • product judgment,
  • architecture,
  • reliability,
  • systems thinking,
  • and understanding real user problems.

In five years, manually wiring authentication flows, deployment pipelines, and environment setup for early-stage applications may feel as outdated as provisioning physical servers by hand.

That sounds dramatic today.

I’m not sure it will sound dramatic for long.

But there are real tradeoffs

I’m excited about this direction, but I also think developers should stay skeptical in healthy ways.

The first concern is ecosystem gravity.

The smoother the workflow becomes inside a single platform, the easier it is for that platform to quietly define your architecture choices. Fast beginnings can eventually create painful dependencies.

The second concern is over-trusting generated systems.

Production software is not just working code. It is:

  • observability,
  • edge-case handling,
  • debugging,
  • maintainability,
  • security review,
  • and long-term operational ownership.

AI can reduce setup friction. It cannot eliminate responsibility.

And there is a third concern that feels even more important.

Developers still need to understand what the system is doing underneath abstraction layers.

If every workflow becomes:

prompt → preview → deploy

then there is a real risk that engineering understanding becomes increasingly shallow.

The best use of these tools is not avoiding thinking.

It is spending more energy on the problems that actually matter.

The bigger shift

What struck me most was not the AI itself.

It was the fatigue Google appears to be targeting.

Every developer knows the feeling of losing momentum somewhere between the prototype and the deployment checklist. Creative energy dies in setup screens, permissions, configuration files, environment mismatches, and endless integration work.

AI Studio feels like an attempt to preserve that momentum longer.

And honestly, that may be why this feels more significant than another model release.

The tooling is starting to disappear.

The next few years

My biggest takeaway from Google I/O 2026 is that the future IDE may not look like an IDE at all.

It may look like a conversational workspace capable of:

  • generating software,
  • previewing interfaces,
  • configuring infrastructure,
  • testing deployments,
  • orchestrating agents,
  • and handing projects across multiple levels of abstraction without losing context.

In that world, the most valuable developers will not simply be the people who can write everything manually from scratch.

They will be the people who can direct systems well enough to build reliable, thoughtful, useful products quickly.

That is a very different skill.

And I think Google understands that shift earlier than most people realize.

I’m still not sure whether AI Studio is hiding complexity or genuinely removing it, and that may be the most interesting question Google I/O 2026 leaves us with.

#googleio #ai #gemini #googleaistudio #firebase #android #flutter #productivity #programming #developerexperience #future #ide #tooling

Best AI Agent Security & Guardrails Tools in 2026: LLM Guard vs NeMo vs Guardrails AI

As AI agents become more autonomous — browsing the web, executing code, and making decisions — security is no longer optional. One prompt injection attack, one toxic output, or one leaked secret can break user trust overnight.

This guide compares the top AI agent security and guardrails tools in 2026 to help you pick the right layer of protection.

Why AI Agent Security Matters

Modern LLM applications face unique threats:

  • Prompt injection — malicious inputs hijacking agent behavior
  • Jailbreaks — users bypassing safety constraints
  • Data leakage — PII, credentials, and secrets in model outputs
  • Toxic content — harmful, biased, or off-policy responses
  • Hallucinations — confidently wrong answers in production

A guardrails layer sits between your LLM and users, validating inputs and outputs in real time.

Top 5 AI Agent Security Tools in 2026

1. LLM Guard

Best for: Production-grade PII & toxicity filtering

LLM Guard by Protect AI is an open-source toolkit for sanitizing both prompts and responses. It runs as middleware and chains multiple scanners together.

Key features:

  • 20+ built-in scanners (PII, toxicity, prompt injection, secrets, code)
  • Supports both input and output scanning
  • Self-hosted, no data leaves your infrastructure
  • Fast inference — adds ~50ms overhead per request

Pricing: Free, open-source (MIT)

from llm_guard import scan_output
from llm_guard.output_scanners import Toxicity, Secrets

sanitized, results = scan_output(prompt, model_output, [Toxicity(), Secrets()])

When to use: You need comprehensive scanning with full data control.

2. NeMo Guardrails (NVIDIA)

Best for: Complex conversational flows with policy enforcement

NVIDIA’s NeMo Guardrails uses a custom language called Colang to define dialogue policies. It’s designed for multi-turn conversations and agent workflows.

Key features:

  • Colang-based policy authoring (topical, safety, execution rails)
  • Deep LangChain/LlamaIndex integration
  • Input, output, and dialogue-level guardrails
  • Active community and enterprise support from NVIDIA

Pricing: Free, open-source (Apache 2.0)

# config.yml
models:
  - type: main
    engine: openai
    model: gpt-4o

rails:
  input:
    flows:
      - check input sensitive data
  output:
    flows:
      - check output toxicity

When to use: Complex agent pipelines where you need policy-as-code.

3. Guardrails AI

Best for: Structured output validation and schema enforcement

Guardrails AI focuses on making LLM outputs reliable and schema-compliant. It’s perfect when you need structured data (JSON, XML) from LLMs with guaranteed format.

Key features:

  • Pydantic-style validators for LLM outputs
  • 50+ pre-built validators in the Hub
  • Streaming support with real-time validation
  • Works with any LLM provider

Pricing: Free core library; Guardrails Hub has commercial validators

from guardrails import Guard
from guardrails.hub import ToxicLanguage

guard = Guard().use(ToxicLanguage(threshold=0.5, on_fail="exception"))
response = guard(openai.chat.completions.create, ...)

When to use: You need strict output schemas + content validation together.

4. Vigil

Best for: Prompt injection detection

Vigil is a dedicated prompt injection detection server. Unlike general guardrails libraries, it specializes deeply in one threat: detecting attempts to manipulate your LLM.

Key features:

  • Multi-strategy detection (similarity, keyword, transformer models)
  • REST API — language-agnostic, use from any stack
  • Lightweight and fast to deploy
  • Canary token injection for tracing

Pricing: Free, open-source (MIT)

When to use: Your app is exposed to untrusted user inputs and you need prompt injection as a first-line defense.

5. Rebuff

Best for: Self-hardening prompt injection defense

Rebuff uses a self-hardening approach — it learns from attacks over time by storing vectors of successful injection attempts and comparing new inputs against them.

Key features:

  • Vector similarity search against known injection patterns
  • Optional canary word injection and detection
  • API + self-hosted modes
  • Learns from your specific application’s attack history

Pricing: Free, open-source

When to use: You face repeated adversarial users and want defenses that improve over time.

Comparison Table

Tool Primary Focus Open Source Self-hosted LLM Agnostic Best For
LLM Guard PII + toxicity + secrets ✅ ✅ ✅ Production scanning
NeMo Guardrails Dialogue policy ✅ ✅ ✅ Complex agent flows
Guardrails AI Output validation ✅ (core) ✅ ✅ Structured outputs
Vigil Prompt injection ✅ ✅ ✅ Injection detection
Rebuff Self-hardening injection ✅ ✅ ✅ Adversarial users

How to Choose

Start with LLM Guard if you’re building a production app with real users and need broad coverage out of the box.

Add NeMo Guardrails if your agent needs complex dialogue policies with clear topical boundaries.

Use Guardrails AI if your LLM must return structured data (forms, API payloads, reports).

Layer Vigil or Rebuff on top if prompt injection is a specific threat in your use case (e.g., user-submitted content, RAG over untrusted docs).

Most production AI agents combine 2-3 of these tools — it’s not a one-or-nothing choice.

Explore More AI Agent Security Tools

Browse 600+ AI agent tools — including the full security/guardrails category — at AgDex.ai, the most comprehensive AI agent resource directory in 2026.

🔍 View all AI security & guardrails tools →

Published by AgDex.ai — your guide to the AI agent ecosystem.

I Deployed Netflix’s Web Server in 30 Seconds (And So Can You) – Docker Project 1

Introduction
What You Will Build Today

By the end of this tutorial, you will have:

A live web server running inside Docker

Your custom HTML page served from a container

A persistent website that survives container death

Screenshots proving every step works

Time required: 20 minutes
Prerequisites: Docker installed (I will show you how to check)

Why Project-Based Learning

When I started learning Docker, I watched hours of videos and forgot everything. Then I switched to building real projects. This is Project 1 of 6 in my “Docker Zero to Hero” series.

Let me show you what I built, step by step.

Section 1: Verifying Docker

Step 1: Is Docker Alive?
First, I opened my terminal (PowerShell on Windows with WSL2 enabled).
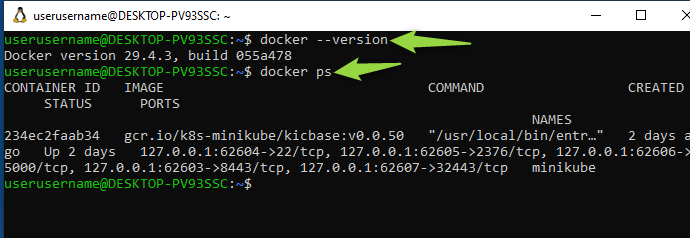
command: docker –version
docker ps

The docker ps command showed an empty table – that is normal. No containers running yet.

What I learned: docker ps only shows RUNNING containers. Use docker ps -a to see all containers including stopped ones.

Section 2: Running Your First Container

Step 2: The 5-Second Web Server

Here is where the magic happened. I ran one command and got a production-grade web server.

Command:
docker run -d –name my-first-website -p 8080:80 nginx

Breaking down what this means:

Command part What it does
docker run Create and start a container
-d Run in background (detached mode)
–name my-first-website Give it a friendly name
-p 8080:80 Map my computer’s port 8080 to container’s port 80
nginx The image name (web server used by Netflix)

I got back a long container ID – that is proof it worked.

My container appeared in the list with status “Up”.

Section 3: Seeing It in the Browser

Step 3: Opening Your Website
I opened my browser (Chrome) and went to:
http://localhost:8080

“Welcome to nginx!” appeared.

In 5 seconds, I deployed the same web server that runs Netflix, Airbnb, and Uber.

My reaction: This is insane. No Apache setup. No Nginx installation. No dependency hell.

What I learned: Containers package the application AND its dependencies together. That is why it “just works.”

Section 4: Making It Your Website

Step 4: Modifying the Website
A default “Welcome to nginx” page is useless for real work. Let me change it to a maintenance page my boss would actually use.

First, I created my own HTML file:

echo “

My First Docker Project – Under Maintenance

Back at 9am.

” > index.html

Then I copied it into the running container:

docker cp index.html my-first-website:/usr/share/nginx/html/index.html

Refreshed my browser:

What I learned: docker cp works like regular cp – but it copies files INTO a running container. The path /usr/share/nginx/html/ is where nginx looks for web files

Step 5: Simulating a Crash
Here is where I learned the most important lesson about containers.

I stopped and removed my container:

docker stop my-first-website
docker rm my-first-website

Checked if it was gone:
docker ps -a

Refreshed my browser:

The page was dead. My custom HTML was gone forever.

Why? Containers are ephemeral – when they die, everything inside them dies too.

The problem: If I deployed a real app this way, a simple restart would wipe all my data. That is unacceptable for production.

Section 6: Fixing It with Volumes (Production Solution)

Step 6: Persistent Storage with Volumes
The solution is volume mounts – share a folder from MY computer with the container.

I created a dedicated project folder:

mkdir docker-project-1 && cd docker-project-1

Created a new HTML file:
echo “

PERSISTENT WEBSITE

This survives container death.

” > index.html

Ran the container with a volume mount (-v):

docker run -d –name persistent-site -p 8080:80 -v “$(pwd):/usr/share/nginx/html” nginx

What -v “$(pwd):/usr/share/nginx/html” means:

Part Meaning
-v Volume mount flag
“$(pwd)” My current folder on my computer
: Separator
/usr/share/nginx/html Folder inside the container
Translation: “Docker, mirror my computer’s folder inside the container. When I change files on my computer, change them in the container too.”

Refreshed my browser:

Now for the real test. I deleted the container again:

docker stop persistent-site && docker rm persistent-site

Ran the SAME command again:

docker run -d –name persistent-site -p 8080:80 -v “$(pwd):/usr/share/nginx/html” nginx

Refreshed my browser:

IT STILL WORKED.

What I learned:

Without volumes: Data dies with container

With volumes: Data lives on your computer, containers just read it

This is how databases, file uploads, and user data survive restarts in production

FAQ Schema Markup Generators: What They Actually Do (and What They Don’t Tell You)

So you’ve heard that adding FAQ schema to your pages can get you those sweet rich results in Google Search — the expandable Q&A dropdowns right in the SERP. You Google “FAQ schema generator”, paste in your questions, copy the JSON-LD, and drop it in your <head>. Done, right?

Sort of. There’s more going on here than most tutorials explain.

Let’s break it down properly.

What Is FAQ Schema, Actually?

FAQ schema is a type of structured data — machine-readable metadata you embed in your HTML to tell search engines what kind of content is on your page.

It uses the schema.org/FAQPage vocabulary and is typically written in JSON-LD (JavaScript Object Notation for Linked Data), which Google officially recommends over Microdata or RDFa for new implementations.

A minimal, valid FAQ schema block looks like this:

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "FAQPage",
  "mainEntity": [
    {
      "@type": "Question",
      "name": "What is structured data?",
      "acceptedAnswer": {
        "@type": "Answer",
        "text": "Structured data is a standardized format for providing information about a page and classifying the page content."
      }
    }
  ]
}
</script>

The mainEntity array holds your questions. Each item is a Question with a name (the question text) and an acceptedAnswer containing an Answer with a text property.

That’s the whole spec for this type. Not complicated — which is exactly why generators exist.

What Do FAQ Schema Generators Actually Do?

A FAQ Schema generator is just a UI wrapper around a template. You fill in fields, it writes the JSON-LD for you. Nothing more.

The output of every single FAQ schema generator in existence looks like the block above. They differ only in:

  • Whether they let you add multiple Q&A pairs (most do)
  • Whether the text field allows HTML (more on this in a second)
  • Whether they validate the output before showing it to you
  • Whether they minify or pretty-print the JSON

They do not:

  • Check if your questions match actual content on your page
  • Verify whether your page is eligible for rich results
  • Guarantee you’ll get a rich snippet
  • Update automatically if you change your FAQ content

That last point trips people up constantly.

The HTML-in-answers Question

Google’s documentation says the text property of an Answer does support a limited subset of HTML — specifically: <a>, <b>, <br>, <em>, <i>, <li>, <ol>, <strong>, <ul>.

Some generators strip all HTML from the answer field. Some preserve it. Some encode it incorrectly (double-escaping &amp; instead of &, breaking the output).

If your answers need links or lists inside them, test your generator’s output manually. Paste the result into Google’s Rich Results Test and inspect what it actually parses.

Common Mistakes the Generator Won’t Catch

1. Schema that doesn’t match your visible content

Google’s guidelines are explicit: your structured data must reflect content that is visually present on the page. If you generate FAQ schema for questions that only exist in the JSON-LD and not in the actual HTML — that’s a violation, and Google can apply a manual action to your site.

Don’t use generators to add “bonus” FAQs that aren’t rendered on the page.

2. Using FAQPage on pages that aren’t really FAQ pages

FAQPage is for pages where the primary purpose is answering questions. Dropping FAQ schema on a product page, a blog post, or a homepage just because you have one accordion component at the bottom is a gray area that Google has increasingly penalized.

3. Duplicate FAQ schema across multiple pages

If you have the same FAQ block on 50 pages (common with CMS templates), search engines see it as low-quality repeated content in structured data. Each FAQ schema implementation should be page-specific.

4. Stale schema after content edits

You updated the FAQ section on your page, but the JSON-LD in the <head> still has the old questions. Now your schema and your content disagree. Generators produce static output — you’re responsible for keeping it in sync.

The Right Way to Use a Generator

Think of generators as scaffolding tools, not end-to-end solutions. Here’s a sane workflow:

  1. Write your FAQ content on the page first. Real questions, real answers, visible in the HTML.
  2. Use a generator to produce the initial JSON-LD from that content.
  3. Validate the output using Google’s Rich Results Test.
  4. Embed it — either inline in a <script> tag or injected via your CMS/tag manager.
  5. Tie it to your content update process so the schema stays in sync.

For anything more than a few static pages, consider templating the schema generation into your build pipeline or CMS rather than relying on a one-off generator.

Validating Your Output

Two tools worth bookmarking:

  • Google Rich Results Test — tests whether Google can parse your schema and whether your page is eligible for rich results
  • Schema.org Validator — validates against the schema.org spec directly, independent of Google’s interpretation

These aren’t interchangeable. Google’s validator tells you what Google will do with your schema. The schema.org validator tells you if your markup is technically correct per the open standard. Run both.

When Rich Results Don’t Appear (and It’s Not the Generator’s Fault)

Even perfectly valid FAQ schema doesn’t guarantee a rich result. Google treats rich results as optional enhancements, not entitlements. Common reasons you won’t see them:

  • The page doesn’t have enough authority or trust signals yet
  • Google already shows a competitor’s FAQ snippet for the same queries
  • The SERP layout for those queries doesn’t include FAQ features (Google has been reducing FAQ rich results for high-authority sites since 2023)
  • The page was crawled but not yet re-indexed since you added the schema

Structured data is an input signal to Google’s rendering pipeline. What comes out the other end is Google’s decision.

TL;DR

Thing What It Does What It Doesn’t Do
FAQ Schema Generator Writes valid JSON-LD for you Validates content match, guarantees rich results
JSON-LD in <head> Makes schema parseable by crawlers Make questions visible to users
Google Rich Results Test Shows if schema is parseable Guarantees SERP appearance
FAQPage schema type Signals Q&A structure to search engines Work on pages without actual FAQ content

Structured data is one of those areas where the tooling is simple but the judgment required to use it correctly is non-trivial. Generators handle the syntax. Understanding when and how to apply the schema — that part is still on you.

How a pure-TypeScript flex layout engine closed the last WASM-Yoga gap

TL;DR

I’ve been building Pilates, a flex layout engine for terminal UIs in pure TypeScript. As of last week, across the 9 scenarios in my bench suite, the pure-TS engine is faster than WASM Yoga (the engine Ink uses) on each — including the structural-mutation workload (append + remove a row per frame) Yoga led on by ~5× until phases 15–17 closed it. That flipped to a ~1.7× Pilates win, in pure TypeScript.

No native bindings. No WASM port. The fix was algorithmic, and the algorithmic fix worked in TS.

The numbers

Median latency, win32-x64, Node 22, ~5s tinybench windows with bootstrap CI95:

Scenario Pilates yoga-layout (WASM) Ratio
tiny (10 nodes) 4.5µs 19.0µs 4.2× faster
realistic (~100) 121µs 328µs 2.7× faster
stress (~1000) 601µs 1.94ms 3.2× faster
big (~5000) 3.32ms 9.17ms 2.8× faster
huge (~10000) 8.62ms 18.5ms 2.1× faster
hot-relayout 16.3µs 83.0µs 5.1× faster
hot-relayout + boundaries 15.8µs 77.8µs 4.9× faster
hot-relayout (text mutation) 8.9µs 90.6µs 10× faster
hot-structural 71.3µs 118.3µs 1.7× faster

Caveats up front: 9 hand-picked scenarios, not a universal claim. Reproduce with pnpm bench — about 5 minutes on a recent machine.

Why pure TS can beat WASM here

Terminal UI is a curiously hostile workload for a WASM engine. Trees are small (10–10,000 nodes), but updates are frequent — one keystroke, one tick, one frame. The crossing cost from JS into WASM dominates: Yoga’s per-call kernel is a few microseconds, but node.setWidth(N) from JS to WASM is also a few microseconds. A pure-TS engine pays no crossing cost.

That was the thesis going in. Phases 15–17 are evidence the thesis holds even in the worst case — the workload where Yoga’s compute kernel is exactly what’s being measured, with the tree pre-built and only the structural-mutation layout timed.

How hot-structural went from ~450µs to ~70µs

Two algorithmic changes did the work.

1. Linear-recurrence main-axis positions

The original main-axis position rule was a cumulative sum: each cell’s position depended on the size of every prior sibling. A 100-cell row in the stress fixture meant ~300 dependency edges per row.

// Old rule — every cell reads every prior sibling
mainPos[N] = sum(siblings[0..N-1].mainSize + margin + gap)

Replaced with a linear recurrence — each cell only reads the cell immediately before it:

// New rule — each cell only reads the previous one
mainPos[N] = mainPos[N-1] + prev.mainSize + prev.marginEnd + me.marginStart + gap

Reverse-direction (row-reverse / column-reverse) keeps the cumulative-sum fallback because the recurrence depends on the prior cell’s already-resolved position, which doesn’t hold when iteration is reversed.

2. Fold default-valued style inputs

Observation: roughly half of all input fields in the grammar were sitting at default values forever — margin: 0, minWidth: 0, maxWidth: undefined, etc. They still consumed dirty-flag slots, propagated through dependents, and appeared in dependency sets.

Phase 17 folds these defaults into compile-time constants at grammar-build time. Each per-cell node went from ~15 fields to ~7. The classifier’s nodeSig was extended with fold-predicate bits so that mutating from default → non-default correctly triggers a structural rebuild.

Combined, hot-structural went from ~450µs to ~70µs.

Why pure TS over a native rewrite

I considered porting the engine to a native-compiled-to-WASM language before doing the algorithmic work. Glad I didn’t.

Yoga’s advantage wasn’t speed of arithmetic — its C++ kernel is fast and well-tuned, but speed of arithmetic wasn’t the bottleneck on this workload. The advantage was the structural-mutation algorithm: Yoga handled it natively, the pure-TS engine was redoing too much work per mutation.

A native-compiled port from my side would have inherited the same algorithmic shape and reached parity at best. The fix was algorithmic, and the algorithmic fix worked in TypeScript. “Pure TS is competitive with native code on this workload” is the actually-interesting result.

Validation, including a same-day hotfix story

  • 1,470 unit + integration tests pass
  • Structural-differential fuzzer green at 3,000 runs
  • 33 Yoga oracle fixtures (cell-for-cell comparison)
  • Byte-identical cached-vs-cold differential mode at 833 runs

A small incident worth mentioning: within hours of publishing 2.0.0, the fast-check property fuzzer caught a real bug — createStyleDirtier was throwing on a node whose entire style had been folded out, a case my analysis said couldn’t happen. The fuzzer immediately found it. 2.0.1 shipped same day with the fix and a pinned regression test, and 2.0.0 was deprecated on npm pointing at 2.0.1.

Property-based fuzzing earns its keep. I had been on the fence about whether the fuzzer was worth maintaining; this answered it.

API stability

Public calculateLayout() is byte-identical between 1.x and 2.x. The SemVer-major bump reflects internal API and memory-characteristic shifts:

  • Typed-array runtime (Field.id integer + array storage replacing Map<Field, X>)
  • LayoutPool grows unbounded (tried FinalizationRegistry-based recycling in phase 15C; caused 2× regression so removed)
  • Per-property dirty bitmask replacing single dirty bool
  • Linear recurrence + fold default values (the algorithmic changes above)

If you’re using only the documented public API, you upgrade and the speedup is transparent.

Try it

git clone https://github.com/pilatesjs/pilates
cd pilates
pnpm install
pnpm bench   # ~5 min

Or install the engine directly:

npm install @pilates/core

Full React stack (reconciler + widgets):

npm install @pilates/react @pilates/widgets react

Adversarial benchmarks are very welcome — if there’s a workload where this approach breaks down, I’d genuinely like to find it. That’s the most valuable feedback the project can get right now.

Repo (MIT): https://github.com/pilatesjs/pilates

npm: https://www.npmjs.com/package/@pilates/core

Spot instances as GitHub Actions runners

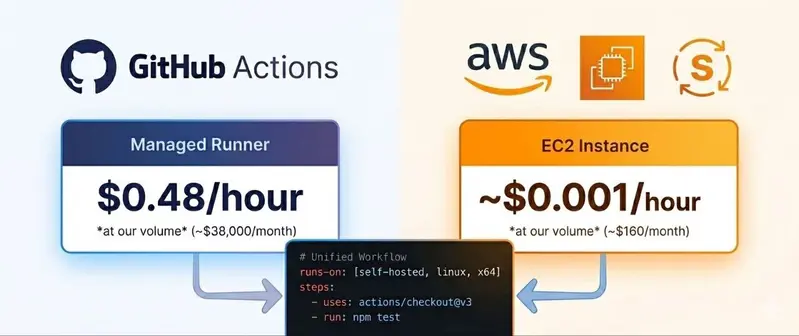
Same workflow, different runner: github managed runners vs spot runners

Part 1 was the foundation – Jenkins as a Code, ephemeral workers, the whole thing. Part 2 was the painful platform – macOS. This one is sideways: we moved a chunk of the CI workload off Jenkins entirely, onto GitHub Actions, using EC2 spot instances as the runner fleet.

This isn’t me saying “Jenkins is dead, use GitHub Actions”. The Jenkins setup is still the workhorse for the big builds – macOS, Windows, anything that needs custom orchestration or runs for hours. GitHub Actions runs alongside it for a specific class of workload where it fits better.

This post is about the self-hosted spot runner pattern – how to point GitHub Actions at your own ephemeral EC2 fleet instead of GitHub’s managed runners, and the things that bite once you do.

Same workflow, different runner: github managed runners vs spot runners

Why bother in the first place

The managed runners GitHub gives you out of the box are fine for small teams. A few reasons push you toward self-hosted:

1. Cost at volume. GitHub bills its managed Linux runners at $0.008/minute, which is about $0.48 per hour. No problem if you run a few builds a day. At our volume (roughly 80,000 runner-hours per month across 29,000 jobs), the same workload on managed runners would land around $38,000 per month. Our actual EC2 spot bill for the runner fleet last month was about $120 (plus a few dollars of Lambda, SQS and EBS overhead from the orchestration). The per-hour gap is what does the heavy lifting – spot sits around $0.001-0.002 per runner-hour against $0.48 for managed.

2. Instance shape. GitHub’s managed runners come in fixed sizes. If your build wants 16 vCPUs and 64 GB of RAM, or a specific GPU, or arm64, you’re either paying for the largest tier or you’re stuck. Self-hosted lets you pick whatever EC2 instance type the build actually needs.

3. Network and dependency access. Builds that need to talk to private resources – internal artifact registries, RDS instances, things behind a VPC – are awkward on managed runners. Self-hosted runners live inside your VPC, so they have direct access to whatever they need without proxies or tunnels.

All three applied for us. The bill is what got us to try it, but instance-shape flexibility and VPC access were nice surprises on top.

github actions and cost explorer charts

What “self-hosted spot runner” actually means

A self-hosted GitHub Actions runner is a small agent that registers itself with a GitHub repo or org, polls for jobs matching its labels, runs them, and reports results back. The agent doesn’t care where it lives – bare-metal, VM, container, anything that can run the runner binary.

The runner can be:

  • Persistent: registered once, sits there forever, picks up jobs as they come in.
  • Ephemeral: registered with a single-use token, picks up exactly one job, then de-registers and shuts down.

We picked ephemeral, for the same reasons as in Part 1. A long-lived self-hosted runner means you’re babysitting a host, eating build pollution from a shared agent, and carrying a security blast radius that never closes.

So every GitHub Actions job gets its own EC2 spot instance, freshly launched from a Packer-baked AMI. The job runs, the instance is terminated. It’s the same one-build-per-worker idea as the Jenkins fleet, just driven from a different control plane.

The architecture, end to end

There’s no single “self-hosted spot runner” plugin or service. You stitch the flow yourself, or you grab one of a few open-source modules that stitch it for you. I went with terraform-aws-github-runner – the most beat-on option of the bunch, and it drops into a Terraform-managed AWS account without much ceremony. (Heads-up if you knew this project by its old name: it was originally maintained by Philips Labs at philips-labs/terraform-aws-github-runner and later moved to the dedicated github-aws-runners org. Same project, new home.)

When somebody opens a PR that triggers a workflow, the flow looks like this:

  1. GitHub fires a webhook. As soon as a workflow job gets queued, GitHub posts a workflow_job event to a webhook URL.
  2. API Gateway + Lambda receives it. The webhook Lambda validates the payload (HMAC signature check), filters for the runner labels you care about, and drops a message onto an SQS queue.
  3. A “scale-up” Lambda drains the queue. For each queued job it launches an EC2 spot instance from a specific AMI, with user-data carrying a single-use registration token.
  4. Instance comes up. Cloud-init runs, the runner binary registers itself with GitHub using the token, then starts polling for jobs.
  5. GitHub assigns the job to it. The runner came up with matching labels, so GitHub schedules that specific job onto it.
  6. Job runs. Whatever your workflow says – checkout, build, test, push artifacts.
  7. Runner shuts down. We registered it as --ephemeral, so the runner agent exits after one job. A “scale-down” Lambda swings by on a schedule, finds instances whose runners have de-registered, and kills them.

The Lambda code, SQS queues and IAM glue all live inside the runner module – you don’t write any of it yourself. What you do write is the Terraform configuration declaring which runners exist, what AMI they use, and which instance types are eligible.

📌 IMAGE TODO (architecture): linear flow left-to-right – GitHub webhook → API Gateway + Lambda → SQS → Scale-up Lambda → EC2 spot instance (Packer AMI) → Job runs → Instance terminates. One dashed loop labeled “scale-down Lambda watches and cleans up”. Hand-drawn excalidraw style to match Parts 1 and 2.

Multi-tier runners – one workload size doesn’t fit all

The setup earns its keep once you split runners into tiers distinguished by labels. Workflows pick the tier they want by setting runs-on: in the workflow YAML.

I ended up with roughly three tiers:

  • Default (small) tier: t3.medium / m5.large-class instances. For lightweight jobs – linters, formatters, doc builds, anything that doesn’t really stress a CPU. Cheap, spot capacity is rarely a problem at this size, and they spawn quickly.
  • Large tier: m5.xlarge / c5.xlarge-class instances. For the typical build/test workflow that wants a bit of CPU but isn’t hammering it.
  • Compute-intensive tier: c7a.4xlarge / c8a.8xlarge-class instances. For workflows that benefit from a lot of cores – compile-heavy builds, big test suites, anything that scales with parallelism.

Each tier is its own runner configuration in Terraform – same module, called multiple times, with different labels and instance-type lists. The Terraform looks roughly like this (sanitized):

module "github-runners" {
  source  = "github-aws-runners/github-runner/aws//modules/multi-runner"
  version = "~> 6.0"

  multi_runner_config = {
    "linux-x64-small" = {
      runner_config = {
        runner_extra_labels = "linux,x64,small"
        instance_types      = local.default_instances
        ami_filter          = { name = ["*ci-runner-x64*"] }
        enable_ephemeral_runners = true
        enable_spot_instances    = true
      }
    }

    "linux-x64-compute-intensive" = {
      runner_config = {
        runner_extra_labels = "linux,x64,compute-intensive"
        instance_types      = local.compute_intensive
        ami_filter          = { name = ["*ci-runner-x64*"] }
        enable_ephemeral_runners = true
        enable_spot_instances    = true
      }
    }

    # ...and so on for the other tiers
  }

  # Common stuff: webhook secret, GitHub app credentials, VPC config, etc.
  github_app = { ... }
  webhook_secret = random_id.webhook_secret.hex
  vpc_id  = module.vpc.vpc_id
  subnet_ids = module.vpc.private_subnets
}

And in a workflow YAML, picking the tier looks like this:

jobs:
  build:
    runs-on: [self-hosted, linux, x64, compute-intensive]
    steps:
      - uses: actions/checkout@v4
      - run: make build

The runs-on array gets matched against runner labels – GitHub picks any registered runner that has all of them. And because the Lambda only spawns instances on demand, you don’t pay for idle capacity in a tier nobody’s using.

Scheduling – warm pool during hours, lights off at night

Pure on-demand scaling reads well on paper – zero idle runners, you only pay when a job is running, the Lambda spawns instances exactly when GitHub queues something. Two patterns spoil it in practice, and you’ll want to layer scheduling on top.

The morning-rush problem: the first PRs of the day all queue around the time people log in. With pure on-demand, every one of those jobs eats the full cold-start latency (~60-120 seconds from queue to running). Multiply by a dozen developers hitting “push” at 9am and you’ve got a backlog people notice.

The 3am problem: even on spot, runners that exist but aren’t being used cost something. Idle time on launched instances waiting for the next job, EBS-backed storage on warm AMIs, plus the always-on cost of the orchestration Lambdas. Outside business hours the queue is mostly empty – no point in keeping capacity hot.

The runner module addresses both with idle pools and scheduled scaling.

What works for us:

  • During business hours (weekdays 08:00-20:00 in our main timezone): keep a warm pool of N runners per tier. They sit idle, registered with GitHub, ready to grab the first job whose labels match. As soon as one of them claims a job, the scale-up Lambda spawns a replacement, so the pool size stays at N. Cold start from the user’s perspective drops from ~90s to ~0s.
  • Outside business hours: pool size goes to zero. Late-night and weekend jobs still run, they just pay the cold-start tax. Most jobs in those windows are scheduled batch work that doesn’t care about an extra minute.

In Terraform, the relevant pieces look roughly like this (sanitized, per-tier):

runner_config = {
  # ... labels, instance_types, ami_filter as before ...

  enable_ephemeral_runners = true
  enable_spot_instances    = true

  # Warm pool - kept at this size during the cron windows below.
  idle_config = [
    {
      cron      = "0 8 * * MON-FRI"   # ramp up at 08:00 weekdays
      timeZone  = "Europe/Berlin"
      idleCount = 3
    },
    {
      cron      = "0 20 * * MON-FRI"  # ramp down at 20:00 weekdays
      timeZone  = "Europe/Berlin"
      idleCount = 0
    },
  ]
}

A few notes about this pattern:

  • “Warm pool” runners are still ephemeral, just pre-launched. Each one picks up a single job and dies, same as any other runner. The pool replenishes by launching new instances, never by re-using old ones, so the byte-identical state property from Part 1 still holds.
  • Pool size is a judgment call. Too small and you hit cold-starts during the rush anyway. Too big and you’re burning money on instances that sit unused. We tune it per tier based on the morning queue depth we observe. The compute-intensive tier has a smaller pool than the default tier because those jobs are rarer.
  • Spot eviction during pool-idle time is a non-event. If AWS reclaims a pool runner before it ever picks up a job, the scale-up Lambda launches a replacement. Pool size is a target, not a list of specific instances.
  • Holidays we haven’t solved properly. The cron-based schedule doesn’t know about public holidays, so on a Monday holiday the pool ramps up at 08:00 to serve nobody. The cost is small enough that we’ve never been motivated to build a calendar-aware scheduler.

During working hours the dev experience is roughly as snappy as the managed runners. Outside those hours the bill is close to zero.

📌 IMAGE TODO (warm-pool schedule): a 24-hour timeline showing pool size. Flat at 0 from 00:00-08:00, ramps up to N runners at 08:00, stays at N until 20:00, drops to 0 for the night. Weekend bar shows pool=0 all day. Annotate “cold-start hides here” inside the 08:00-20:00 band.

The AMI is still a Packer image

As in Part 1: whatever the runner needs to do its job (language runtimes, build tools, Docker, cached dependencies) gets baked into a Packer AMI ahead of time. The AMI is versioned, lives in your AWS account, and is referenced by the runner’s ami_filter.

For the GitHub Actions case the image is usually lighter than the Jenkins worker images, because GitHub Actions workflows tend to install their own action-specific tooling at runtime via setup-node, setup-python, setup-java, etc. So the base image just needs:

  • The OS (Ubuntu, usually).
  • The GitHub Actions runner binary, pre-downloaded.
  • Docker (for docker build / docker run steps).
  • AWS CLI (most workflows talk to S3 or ECR).
  • Basic build dependencies (git, curl, jq, unzip).
  • Any runtime that’s stable enough to bake (Node LTS, Python 3.x).

The image lands in the 5-10 GB range. Small enough that a fresh spot instance pulls it and starts running in well under a minute.

Spot interruptions – and why ephemeral makes them OK

Everyone asks the same question the first time they look at spot for CI: what happens when AWS yanks the instance mid-build?

The build fails. GitHub re-queues it. A fresh instance picks it up. There’s no recovery dance to write, because the runner is ephemeral and the workflow should be idempotent anyway. An interruption costs you one wasted partial build, and the retry runs from scratch on a brand-new runner.

Spot interruption notices give you 2 minutes of warning before AWS pulls the plug. The runner can listen for that signal and de-register from GitHub cleanly before shutdown – the module wires this up for you. Without it, GitHub briefly shows a “this runner went offline mid-job” error before the retry. Ugly but not fatal.

In practice I see an interruption rate of roughly 1-3% of jobs on the default and large tiers, and a bit higher on the compute-intensive tier (the larger instance types just have less spot capacity available per AZ). For most workloads that’s a fine trade for the cost savings. For workflows that can’t tolerate retry – final release builds, deploys with side effects – I either run those on on-demand instances (same module, just flip enable_spot_instances = false for that tier) or send them over to the Jenkins fleet where the lifecycle is more controlled.

Trade-offs vs. Jenkins workers

“Should this workflow run on Jenkins or GitHub Actions?” comes up a lot. How I think about it:

Workload shape Where it goes
PR-triggered, short, idempotent GitHub Actions on spot – fast, cheap, no Jenkins overhead.
Long-running build (1h+) Jenkins. Spot interruption risk is too high for long jobs.
macOS / Windows builds Jenkins. The macOS and Windows worker setup from Parts 1 and 2 lives there.
Custom orchestration (matrix sharding, dynamic parallelism, gated promotion) Jenkins. Groovy DSL handles this more flexibly than GitHub Actions matrix.
Deploys / releases with side effects Jenkins on dedicated workers, or GitHub Actions on on-demand. No spot.
Open-source / contributor-facing repos GitHub Actions. Don’t expose Jenkins to contributors.
Builds that need ephemeral access to a specific cloud service Whichever is in the right VPC. Usually GitHub Actions for the small stuff.

The two systems don’t overlap, they cover different shapes of work. Moving everything to GitHub Actions would have been a mistake. Moving the small, fast, PR-scoped stuff off Jenkins freed up real capacity for the big jobs.

What I’m still figuring out

A few things in this part of the system that aren’t fully solved:

  • Cold-start latency outside the warm pool. Inside business hours the warm pool hides it; outside business hours every job pays the full 60-120 seconds. We’re OK with this trade-off but it occasionally bites the people working evenings.
  • Spot capacity in specific AZs. Occasionally the compute-intensive tier can’t get spot capacity in our preferred AZ and the queue backs up. The module supports multi-AZ fallback, which helps, but doesn’t eliminate it. For genuinely bursty days we sometimes fall back to on-demand temporarily.
  • Holiday-aware pool scheduling. The cron schedule doesn’t know about public holidays. Low impact, but it’s annoying every time you remember it.
  • AMI sprawl. Every architecture (x64, arm64) and every base-image variant is its own AMI lineage. Keeping them all current is a chore. We build them on a schedule via Packer the same way we do the Jenkins worker images, but the operational overhead is real.
  • Cost attribution. Spot instances launched by the scale-up Lambda inherit tags from the launch template, but not every downstream resource (EBS volumes, ENIs) picks up the right cost-attribution tags automatically. Whole separate rabbit hole, not opening it here.

Closing thought

The same pattern keeps showing up across all three parts: ephemeral workers, baked images, orchestrated from git, secrets pulled from a vault, identical state every build. Jenkins is one way to wire it up, GitHub Actions on self-hosted spot runners is another, and there’s no rule that says you have to pick just one. Pick whichever control plane fits the workload in front of you.

The worker lifecycle is the bit that has to be right. Don’t keep workers around between builds. Once that piece is in place, everything else (Jenkins or GitHub Actions, spot or on-demand, Tart or vSphere) is tactical, and you can swap it later without rebuilding the platform.

That’s where My CI/CD Odyssey wraps for now. The three posts more or less reduce to the same advice – stop clicking, bake your images, don’t reuse workers between builds. If any of it saves you a week of figuring it out yourself, this was worth writing.

Appendix – tools mentioned in this post

This is Part 3 of My CI/CD Odyssey. Thanks for sticking with the whole series. If you’re doing self-hosted CI differently – Jenkins, GitHub Actions, or something else – I’d love to hear about it in the comments.

Agents Need Receipts, Not Just Better Prompts

Most AI agent demos optimize for the first successful run.

Real agent work gets interesting after the agent says “done.”

For a coding agent, browser agent, or MCP-connected workflow, the final chat answer is not enough. I want a receipt: a compact operational record that helps a human trust, debug, replay, roll back, or explain what happened.

Not a giant transcript. Not a raw log dump. A receipt.

“Done” is not a state

Imagine an agent is asked to update a billing flow.

It reads docs, edits four files, calls a test command, skips one integration test, touches an env file, and says:

Done.

That answer is almost useless by itself.

The operator still needs to know:

  • What task did the agent think it was doing?
  • What files, tools, systems, or data was it allowed to touch?
  • What context influenced the work?
  • Which tools or commands did it call?
  • Which actions were read-only versus write, destructive, external, or spend-affecting?
  • What changed?
  • Which checks passed, failed, or were skipped?
  • What required approval?
  • What should a human review?
  • How do I retry, replay, resume, or roll back?

That is the receipt.

What should be in an agent receipt?

The first version does not need to be fancy.

A useful receipt should include:

  • task: what the agent believed it was doing
  • scope: files, systems, tools, or data it was allowed to touch
  • context_used: docs, files, memories, links, or prior runs that influenced the work
  • actions: tool calls, commands, API calls, file edits
  • action_class: read, write, destructive, external send, spend-affecting, permission-changing
  • state_changes: files changed, records created, messages sent, jobs started
  • checks_run: tests, linters, scans, dry runs, evals
  • checks_skipped: expected checks that were not run, with reason
  • approvals: who or what approved the action, scope, expiry, one-off versus policy
  • outcome: completed, partial, blocked, failed, reverted, needs review
  • recovery: how to retry, resume, inspect, or roll back

Here is a small example:

{
  "receipt_version": "0.1",
  "run_id": "run_2026_05_23_001",
  "agent": {
    "name": "local-coding-agent",
    "provider": "anthropic",
    "model": "claude-sonnet-4.5",
    "runtime": "local"
  },
  "task": {
    "summary": "Update the billing retry handler and add regression coverage",
    "scope": [
      "repo:apps/billing",
      "tool:filesystem.read",
      "tool:filesystem.write",
      "tool:shell.test"
    ],
    "out_of_scope": [
      "production database",
      "deployment",
      "customer email sending"
    ]
  },
  "actions": [
    {
      "tool": "filesystem.write",
      "action_class": "write",
      "result": "success",
      "decision_id": "decision_write_002"
    },
    {
      "tool": "shell.test",
      "action_class": "exec",
      "result": "success",
      "decision_id": "decision_exec_004"
    }
  ],
  "checks": {
    "run": ["npm test -- billing"],
    "skipped": [
      {
        "check": "full integration suite",
        "reason": "requires staging credentials"
      }
    ]
  },
  "outcome": {
    "status": "completed",
    "review_needed": true,
    "recovery": "Revert the modified files or rerun npm test -- billing"
  }
}

The model should not own the receipt

The model can summarize intent.

But the hard evidence should come from the runtime, tool layer, or control plane:

  • commands
  • exit codes
  • tool calls
  • files touched
  • approvals
  • policy versions
  • state changes
  • artifacts created

If the agent writes its own audit trail, the audit trail is just another model output.

That is useful as a summary, but it is not enough as evidence.

Traces are not enough

OpenTelemetry-style traces are useful. They explain latency, retries, errors, and service boundaries.

But an agent operator often needs a different object.

A trace tells you which span was slow.

A receipt tells you what the agent was allowed to do, what it actually did, why it was allowed, what changed, and what should be reviewed.

Traces explain execution.

Receipts explain responsibility.

You need both.

MCP makes receipts more important

MCP is useful because it gives agents a common way to access tools and context.

It also makes the tool boundary much more important.

Once an agent can call multiple MCP servers, a single call can look harmless while the sequence is not:

  1. Read customer data from server A.
  2. Process it through server B.
  3. Publish or send it through server C.

That is why receipts should capture not only individual calls, but also source, sink, data class, action class, policy version, and approval scope across the run.

Where we are taking this with Armorer

This is the direction we are building toward with Armorer.

Armorer is a local control plane for AI agents. The goal is to make agent runs, tools, approvals, jobs, logs, and recovery inspectable on your own machine instead of treating every agent as an opaque chat window.

Armorer Guard focuses on checks near the action boundary: what is the agent trying to do, what class of action is it, should it be allowed, blocked, or routed to approval, and what decision record should exist afterward?

The GitHub discussion for the receipt spec is here:

https://github.com/ArmorerLabs/Armorer/discussions/43

And the repo is here:

https://github.com/ArmorerLabs/Armorer

The bet is simple:

As agents get more capable, the bottleneck moves from “can it do the task?” to “can I understand, govern, and repair what it did?”

That layer is still early.

But I think it is where practical agent engineering is heading.