Spec sheets aren’t capabilities: a Day-1 Gemma 4 eval on Telugu vision

This is a submission for the Gemma 4 Challenge: Write About Gemma 4

I was building Maatru, a Telugu literacy app for kids whose parents can’t comfortably teach the script. The original design had photo-feedback as the core interaction. A kid writes a letter on paper, takes a picture, the app compares the writing to the target and gives feedback. The mechanic felt right. Paper-and-pencil is how kids actually learn handwriting. And Gemma 4’s multimodal capability was one of the strongest things in the announcement.

Before I built anything, I tested whether the capability held up for my use case. It didn’t. Gemma 4 confidently misread typed Telugu characters as completely different characters. These were clean Unicode glyphs on white backgrounds, the easy case. Across 20 test samples spanning four difficulty tiers, the cloud variant (Gemma 4 31B Dense) got 4 right. The local variant (Gemma 4 E4B) got 1.

The interesting part of this story isn’t that the capability failed. It’s that I knew within a day, not three weeks into the build. This essay is about the evaluation discipline that produced that knowledge. And why I think anyone planning to build a non-trivial product on Gemma 4 (or any model) should run capability gates before architectural commitment.

To be clear, this isn’t a Gemma 4 criticism. The model does many things well. The multilingual generation and function calling ended up powering Maatru’s curriculum content and agentic planner. What I learned is that model spec sheets are claims to be tested. The cost of testing those claims early is much smaller than the cost of building on a capability that doesn’t deliver.

How I structured the evaluation

A capability gate is an evaluation that answers one question. Does this model capability hold up for my use case, at a quality bar that makes my product viable? For Maatru’s photo-feedback, the question was concrete. Can Gemma 4 reliably identify Telugu characters from images that look like what a kid actually produces?

I built the eval around four difficulty tiers. The typed tier was the easy case: five Telugu characters in a clean Unicode font, black on white, no noise. The adult-handwriting tier was five samples I wrote by hand. The child-handwriting tier was samples produced by a kid I knew, with shaky strokes and uneven spacing. The similar-looking tier was characters that share visual structure, the Telugu confusables set that kids commonly mix up. These test whether the model actually distinguishes between similar shapes or just pattern-matches loosely. Five samples per tier, twenty total. Small enough to run in an afternoon, large enough to surface real failure patterns.

I ran the eval against both Gemma 4 variants I had access to. E4B running locally through Ollama on an M4 MacBook Air with 16GB of RAM, and 31B Dense through OpenRouter’s free tier. Testing both variants matters because Gemma 4 spec claims apply to the family. Specific variants may perform differently due to parameter count, distillation, or fine-tuning. My acceptance threshold, decided before running: typed+adult tiers ≥80% combined, child tier ≥60%. If the model couldn’t reliably read clean reference glyphs and adult handwriting, the kid-handwriting case was hopeless. Defining the threshold before I saw results was important. Otherwise it’s too easy to convince yourself that bad numbers are “actually pretty good.”

What the data showed

The scorecard came back well below threshold. Cloud variant: 1 of 5 typed, 1 of 5 adult handwriting, 0 of 5 child handwriting, 2 of 5 similar-looking. Total 4 of 20, or 20%. Local variant: 1 of 5 typed, 0 of 5 adult, 0 of 5 child, 0 of 5 similar. Total 1 of 20, or 5%. The threshold required 80% on typed+adult combined. The cloud variant gave me 20% on that combined tier.

The failure mode mattered more than the aggregate number. I’d expected child-handwriting to be hard. Kids’ strokes are messy, spacing is unpredictable, letter shapes drift from the canonical form. What I didn’t expect was that the typed reference tier would also fail. The clearest example: Gemma 4 confidently misread అ, a basic Telugu vowel rendered cleanly on a white background, as ౦ (a Telugu numeral) on the cloud variant, and as ని (a different consonant-vowel combination) on the local variant. Same input image, two completely different wrong outputs from two independent inference paths. And neither model hedged. Both committed to wrong answers with no caveats.

That confidence without hedging is what made the failure mode dangerous for the product I was planning. A model that says “I think this might be అ but I’m uncertain” is a model you can build around. You handle the uncertainty in the UX. A model that says “this is ని” when it’s actually అ ships a bug straight into a literacy tool for kids. Different wrong answers on different runs across independent inference paths tells you you’re looking at a model knowledge gap on a specific subdomain. Telugu script recognition in Gemma 4’s vision training distribution. Not a fixable engineering bug.

Ruling out the alternatives

Before accepting “the model can’t reliably do this” as the explanation, I worked through the alternatives. The first candidate was image encoding. Maybe the test images weren’t reaching the model correctly. I ruled this out because the cloud variant got 4 of 20 right, including 2 of the similar-looking pairs. That means the model was receiving and processing visual input correctly. An encoding bug would produce uniform failure across all 20 samples, not the spread of failures I actually saw.

The second candidate was API throttling or silent quality degradation. Maybe OpenRouter’s free tier downgrades model output under load. I ruled this out because cloud providers don’t quietly serve degraded outputs. They return errors. They don’t return lower-quality answers silently. Also, the local E4B variant runs entirely on-device with no external dependency, and it produced even worse results than cloud. If both an unthrottled local run and a potentially-throttled cloud run produce the same failure pattern, throttling isn’t the cause.

Cold-start effects were the third candidate. Maybe the model needed warm-up calls before producing reliable output. I’d added warm-up calls to the runner before the timed loop. Latencies stabilized after warm-up. But the accuracy problem persisted across all 20 samples. Cold-start affects latency, not accuracy.

What remained was the conclusion the data supported. Gemma 4’s vision capability does not currently read Telugu script reliably enough to be the foundation of a literacy product. This is a model training-data limitation, not a fixable engineering bug. Indic scripts are likely underrepresented in the visual training corpus relative to Latin scripts. That isn’t specific to Gemma 4. Most big models have the same gap with non-English visual recognition. But it does mean any product built on Gemma 4 vision for Indic scripts (or other underrepresented visual writing systems) inherits this limitation.

What I’d tell another developer

The discipline that made this story end in a one-day pivot instead of a three-week wasted build is what I think of as capability-gate-first engineering. Before you commit to an architecture that depends on a specific model capability working at a specific quality bar, build the smallest possible evaluation that tests that exact capability under conditions that approximate your actual use case. Set the threshold before you see results. Run it on day one, not week three. If the model passes, you’ve validated a key assumption. If it fails, you’ve saved yourself weeks of building on something that won’t hold up.

For developers planning to build with Gemma 4 on non-English use cases: don’t trust the spec sheet’s “multimodal” or “multilingual” claims as proxies for your specific language or script. Test the exact capability you need on the exact data shape you’ll see in production. For my use case that meant 20 Telugu samples across 4 difficulty tiers. For yours it might be 50 Arabic OCR samples, or 30 medical-image inferences, or 100 Hindi-handwriting captures. The shape of the eval depends on the use case. The discipline of running it before architectural commitment doesn’t. Maatru shipped because the day-one capability gate told me to redesign around what Gemma 4 actually does well, multilingual text generation and agentic reasoning, rather than what the announcement promised. Honestly, that one day of testing saved the project.
Design a Clean Form with Floating Labels in Bootstrap 5

Bootstrap 5 comes with built-in floating labels, but the default inputs can feel a bit too tall for compact forms.

Here’s a cleaner version with a more balanced height and a simple card layout.

The HTML structure:

<link
  href="https://cdn.jsdelivr.net/npm/[email protected]/dist/css/bootstrap.min.css"
  rel="stylesheet"
/>

<div class="container py-4">
  <div class="row justify-content-center">
    <div class="col-md-6">
      <div class="card bg-white shadow-sm">
        <div class="card-header h6 py-3 fw-bold">
          Register
        </div>

        <div class="card-body">
          <form method="#" autocomplete="off">
            <div class="row">
              <div class="col-md-6">
                <div class="form-floating mb-3">
                  <input type="text" class="form-control" id="first_name" name="first_name" placeholder="First name">
                  <label for="first_name">First name</label>
                </div>
              </div>

              <div class="col-md-6">
                <div class="form-floating mb-3">
                  <input type="text" class="form-control" id="last_name" name="last_name" placeholder="Last name">
                  <label for="last_name">Last name</label>
                </div>
              </div>
            </div>

            <div class="form-floating mb-3">
              <input type="email" class="form-control" id="email" name="email" placeholder="Email address">
              <label for="email">Email address</label>
            </div>

            <div class="form-floating mb-3">
              <input type="password" class="form-control" id="password" name="password" placeholder="Password">
              <label for="password">Password</label>
            </div>

            <div class="form-floating mb-3">
              <input type="password" class="form-control" id="password_confirmation" name="password_confirmation" placeholder="Confirm Password">
              <label for="password_confirmation">Confirm Password</label>
            </div>

            <button type="submit" class="btn btn-primary w-100">
              Register
            </button>
          </form>
        </div>
      </div>
    </div>
  </div>
</div>

We need just a little bit of custom CSS:

.form-floating > .form-control {
    height: 48px;
    min-height: 48px;
    padding: 1rem 0.75rem 0.25rem;
  }

  .form-floating > label {
    padding: 0.75rem;
  }

  .form-control:focus {
    box-shadow: none;
  }

And here’s our nice form! 😊

Your MCP Server Is Probably Overprivileged – Here’s a Scanner For It

MCP servers expose tools to LLMs, but most configs grant tools broader permissions than they need, ship without auth, and leak prompt-injection surface in tool descriptions. This scanner finds it before your model does.

Most MCP servers I’ve audited in the last few months had the same three issues:

  1. A shell or fs tool was scoped to the entire filesystem when the use case needed exactly one directory.
  2. The transport ran without auth because the local-dev SSE config got promoted to prod.
  3. Tool descriptions echoed verbatim into prompts with no sanitization — a perfect injection surface.

@hailbytes/mcp-security-scanner is what I wish I’d had on day one of building MCP servers. It’s a static + dynamic scanner for MCP configs and live endpoints that flags these patterns.

CLI

# Scan a local config
npx @hailbytes/mcp-security-scanner ./mcp-config.json

# Scan a live endpoint
npx @hailbytes/mcp-security-scanner https://my-mcp-server.example.com

# SARIF output + fail the build
npx @hailbytes/mcp-security-scanner ./config.json --output=sarif --exit-code

Programmatic

import { scan } from "@hailbytes/mcp-security-scanner";

const report = await scan({ configPath: "./mcp-config.json" });

if (!report.passed) {
  console.error(report.findings);
  process.exit(1);
}

What it checks

  • Overprivileged tools — broader permissions than the declared function needs (filesystem scope, shell access, network egress)
  • Missing or weak authentication — unauthenticated transports, missing token validation, plaintext secrets in config
  • Prompt injection surface — tool descriptions and output paths that pass through to model context without sanitization
  • Unsafe defaults — insecure transport defaults, verbose error exposure, CORS wildcards

The SARIF output drops straight into GitHub Code Scanning, so findings show up as alerts on PRs — same place your SAST results live.

npm install -g @hailbytes/mcp-security-scanner

Source: github.com/hailbytes/mcp-security-scanner — MIT licensed. Pairs nicely with @hailbytes/mcp-server-template if you want a scaffold that comes up secure by default.

Maatru: An agentic Telugu literacy app for kids, built with Gemma 4

This is a submission for the Gemma 4 Challenge: Build with Gemma 4

What I Built

I’m from Hyderabad, India. My wife and I both grew up speaking Telugu — it’s our mother tongue. We have two daughters, three and one and a half. They’re at a daycare where the teachers cover English letters and rhymes, sometimes Hindi, but not Telugu. And here’s the part that’s harder to admit: my wife and I haven’t read or written Telugu in any real way for years. We can speak it fluently, but we lost the script somewhere along the way. When I mentioned this to colleagues at work, several of them said the same thing about their own kids. This is what Maatru is for.

Maatru is a small app for parents like me who can’t comfortably teach the script themselves. A kid taps Start and hears a Telugu letter spoken aloud. Four letter buttons appear on screen and they tap the one that matches the sound. After five letters the session ends and they see a “Great job” card. Later, a parent can open a separate dashboard — gated by a PIN — and read a short English paragraph about what their kid practiced that day, which letters they got right, and which ones they’re still working on.

My first design had the kid write the letter on paper and photograph it; Gemma 4 would compare it to the target and give feedback. I tested that capability on Day 1 before building anything around it. The moment I knew was when Gemma 4 confidently misread అ — a clean, typed vowel on a white background — as completely different characters: ౦ on cloud, ని locally. It got 1 of 20 right on Gemma 4 E4B running locally and 4 of 20 on the 31B variant via OpenRouter — both models failed even on typed reference, which should have been the easy case. The vision capability wasn’t there yet for Indic scripts, at least not reliably enough to be the foundation of a literacy tool.

What I ended up with uses Gemma 4 for the two things it does reliably for Telugu — generating curriculum content in plain text, and making pedagogical decisions about what a specific kid should practice next. The kid loop itself doesn’t call the model. The parent dashboard does, once per visit. I’ll walk through both in the ‘How I Used Gemma 4’ section below.

Demo

Code

GitHub logo

ai-with-avinash
/
maatru

Telugu literacy app for kids. Built with an agentic Gemma 4 planner that adapts to each child’s progress.

Maatru

A Telugu literacy companion for kids whose parents can speak the language but lost the script.

What this is

Maatru is a small web app for parents like me — Telugu speakers raising kids in English-medium schools, who can’t comfortably teach the Telugu writing system because we’ve lost it ourselves. A kid taps Start, hears a Telugu letter spoken aloud, and taps the matching letter from four options. After five letters they see a “Great job” card. A separate parent dashboard (PIN-gated) shows what the kid practiced — in English — alongside the AI’s pedagogical reasoning for why those letters were chosen.

Built for the dev.to Gemma 4 Challenge: Build with Gemma 4.

Architecture at a glance

Two layers, deliberately separated:

  • Layer 1 (kid loop): Deterministic, zero Gemma 4 calls during a session. Renders from a cached SessionPlan. Sub-second response on every tap.
  • Layer 2 (planner): One agentic…

How I Used Gemma 4

I shipped on Gemma 4 31B Dense, accessed via OpenRouter’s free tier (model string: google/gemma-4-31b-it:free). I’d tested the E4B variant locally first — running through Ollama on an M4 MacBook Air with 16GB of RAM — and the latency wasn’t workable for a kid-facing flow. E4B took 8 to 46 seconds on generation prompts, with two hard timeouts at 60s. The 31B Dense via OpenRouter wasn’t fast either (median 5.3s, p95 15.4s in a 50-request stress test), but its function-calling reliability is what made the rest of the architecture buildable: in a smoke test, it produced valid tool calls on 8 out of 8 invocations across two runs. The free tier comes with constraints — 20 requests per minute hard cap and roughly 36% upstream 502s from Google AI Studio — and the architecture was designed around them from day one.

Gemma 4 runs in exactly two places. When a parent opens the dashboard, one call generates an English-language summary of what their kid did that day — practiced letters, where they were confident, where they struggled, what to expect next. When a kid taps Start, one agentic call decides what the session will contain: which letters to target, what distractors to pair them with, what feedback strings to show on correct and wrong taps, and a short paragraph explaining the pedagogical reasoning. The kid loop itself, between session start and end-card, makes zero calls to Gemma 4.

The architectural decision that shapes everything else is bundling. The naive design would have called Gemma 4 once per kid interaction — one call to generate three distractors when a letter appears, another to produce feedback when the kid taps. For a 5-letter session that’s roughly fourteen Gemma 4 calls, each taking 5-15 seconds on the free tier and any of which could fail with a 502. Instead, the planner makes one agentic call at session start and returns a SessionPlan that bundles everything the kid loop needs for the whole session: per-step distractors, per-step feedback variants, the session-level reasoning. The kid loop then runs deterministically from the cached plan, and Gemma 4 stays out of the critical path entirely. Roughly fourteen calls becomes one.

The planner is given three read-only SQLite tools — get_recent_sessions, get_letter_accuracy, get_curriculum — and Gemma 4 calls them via function calling before proposing a plan. The output is a SessionPlan that bundles the kid loop’s content and a short paragraph of reasoning that explains the pedagogical choice. That reasoning is visible to the parent on the dashboard. After session 1 (a cold start: “starting with the first five foundational vowels”), session 2 read the history and adapted on its own: “The child did well in the first session but struggled slightly with ఇ. We are reinforcing the first five vowels with medium difficulty and introducing ఊ to expand their knowledge.” That second paragraph wasn’t templated — it was Gemma 4 reading two sessions of attempts and making a teaching call.

The planner call is wrapped in a retry-with-backoff (1s, 3s, 9s; three attempts) that handles 429s, 502s, timeouts, and malformed tool calls. If retries exhaust or the model returns something unparseable, the planner falls back to a deterministic curriculum heuristic — same SessionPlan shape, hand-written letter selection logic, no AI involved. The dashboard knows the difference: planner-driven sessions show their reasoning paragraph; fallback sessions hide it. A 45-second server-side timeout caps the whole thing so the kid never waits more than ~46 seconds from tapping Start. During verification, the fallback path fires often enough — sometimes 25-40% of the time under heavy upstream instability — that I treat it as a normal operating mode, not an exception.

devchallenge #gemmachallenge #gemma

Gemma 4 Is Not Just Another Open Model — It Changes What Developers Can Build Locally

This is a submission for the Gemma 4 Challenge: Write About Gemma 4

Most posts about new models focus on benchmarks, setup commands, or a fast comparison table. Gemma 4 deserves a better kind of explanation because it is not just another model release to skim and forget.

It feels more like a practical local AI stack for developers who care about privacy, multimodal workflows, long-context reasoning, and real software integration. That is what makes it worth writing about in a broader way.

This post covers the full picture: what Gemma 4 is, how its variants differ, how to choose between them, what makes its multimodal and long-context capabilities important, how to start locally, where it fits in real projects, and why it matters beyond one release cycle.

Why Gemma 4 matters

Gemma 4 is one of the most important open model releases in the Gemma line because it pushes the conversation beyond raw intelligence alone. The bigger shift is that useful AI is moving closer to the user.

Instead of assuming every serious workflow must depend on a remote API, Gemma 4 strengthens the case for local-first intelligence. That changes how developers think about deployment, privacy, latency, resilience, and product design.

For builders, this means the model is not only something to chat with. It is something that can sit inside assistants, mobile experiences, research tools, coding systems, document workflows, and structured automation pipelines.

The four Gemma 4 variants

The most useful way to understand Gemma 4 is to treat it as a family, not as one model with different download sizes. Each variant is clearly more suitable for a different hardware level and product style.

Model Best for Main idea
Gemma 4 E2B Edge devices, mobile tasks, offline use Lightweight local intelligence with multimodal support
Gemma 4 E4B Stronger on-device assistants and practical local apps More capable while still efficient for local deployment
Gemma 4 26B MoE Fast workstation reasoning, coding, tool use Mixture-of-experts design that balances quality and efficiency
Gemma 4 31B Dense Highest-quality local reasoning and advanced fine-tuning Best fit when output quality matters more than speed

This is where the model family becomes genuinely useful. Developers are not forced into one giant default choice.

A small model can power private mobile or offline experiences, while a much stronger model can serve as a serious local reasoning engine on a workstation. That range is one of Gemma 4’s biggest strengths.

How to choose the right one

If the goal is mobile, privacy-first, or offline assistance, E2B and E4B are the most natural choices. These are the kinds of models that fit translation helpers, field assistants, classroom tools, note summarizers, accessibility experiences, and on-device productivity features.

If the goal is a desktop copilot, coding assistant, or tool-using workflow, the 26B MoE model becomes especially interesting. It is a good match when strong reasoning is needed but latency still matters.

If the goal is maximum reasoning quality, deeper analysis, or future fine-tuning for a specialized domain, the 31B Dense model is the stronger fit. That is the version to think about for advanced writing systems, repository understanding, domain copilots, and heavier internal tools.

What makes Gemma 4 technically exciting

A lot of open model launches sound impressive in the same generic way. Gemma 4 stands out because several important capabilities come together in a way that directly changes product design.

Multimodal input

Gemma 4 is not limited to plain text. It supports multimodal understanding, including image and video, while some edge-oriented variants also support audio input.

That matters because real-world software workflows are rarely text only. Users work with screenshots, scanned pages, diagrams, voice notes, charts, camera input, and mixed technical material.

A model that can handle those naturally creates much better product possibilities. A local assistant that reads a UI screenshot, understands a spoken complaint, and returns a structured bug summary is far more useful than a chatbot waiting for perfectly typed prompts.

Long context

The long context window is another major reason Gemma 4 matters. It makes it much easier to work with long code files, documentation sets, multi-document packets, transcripts, and research material in a single session.

This changes what local AI can do in practice. Instead of building complicated chunking systems too early, developers can first explore richer direct workflows like repository explanation, multi-file debugging, policy review, academic summarization, and large-context planning.

That shift is subtle but important. When the model can keep more of the task in view, the developer spends less time fighting orchestration and more time shaping the actual user experience.

Structured output and tool use

Gemma 4 also becomes more valuable when looked at as part of a workflow, not just as a chatbot. Function calling, structured output, and agent-style behavior are what make models usable inside real systems.

The difference between a fun AI demo and a reliable product usually appears when the model needs to pass clean JSON, call tools, classify information, or route decisions into code. That is why this part matters so much.

A model that can reason and still return predictable machine-readable output is far easier to integrate into production software.

A better way to teach readers about Gemma 4

Most model articles explain from the inside out. They start with parameters, move to benchmarks, and then end with a few generic use cases.

A more useful approach is to explain Gemma 4 from the outside in. Start with the product constraint.

If the constraint is privacy, choose a smaller local model. If the constraint is latency, use the model that stays responsive on available hardware. If the constraint is output quality for difficult reasoning or future adaptation, move to the stronger dense model.

This framing helps readers immediately connect the model to actual decisions. It turns Gemma 4 from “another release” into “a design choice.”

A hands-on local starting point

A strong educational post should leave readers with something they can try immediately. One easy path is to run Gemma 4 locally with a runtime such as Ollama.

ollama pull gemma4
ollama run gemma4

That is enough to begin testing prompts and checking local performance. But a better experiment is to give the model a project README, an issue report, and a screenshot, then ask for a JSON response with fields like problem_summary, possible_root_cause, files_to_check, and recommended_next_step.

That single exercise teaches more than a generic chat prompt. It shows how Gemma 4 can reason across mixed inputs and produce output that software can directly act on.

A creative application readers will remember

The best way to stand out in a challenge like this is not to repeat what everyone already knows. It is to show a fresh product pattern.

One standout idea is a local digital investigator. The system takes screenshots, logs, voice notes, and long technical documents, then produces a structured incident brief, highlights anomalies, suggests next actions, and keeps the workflow private on the device or workstation.

That concept works especially well because it fits cybersecurity, debugging, compliance, education, support engineering, and technical operations. It also shows off what Gemma 4 is actually good at instead of forcing it into a generic chatbot role.

What local Gemma 4 means for the future

The biggest idea behind Gemma 4 is not only that open models are improving. It is that local models are becoming strong enough to be serious building blocks.

That changes who can build, where systems can run, and what kinds of users can be served safely. A student with weak internet, a startup with tight cost limits, a privacy-sensitive organization, or an independent builder working on a laptop can all benefit from that shift.

When capable models run across phones, laptops, desktops, and cloud-connected workflows, developers gain freedom. They can design around user needs instead of designing around permanent dependence on one hosted endpoint.

Licensing and practical caution

A trustworthy post should also mention responsible usage. Developers should always check the official Gemma 4 model pages, supported runtimes, license terms, and deployment documentation before shipping or redistributing anything.

It is completely fine to explain how to run the model, compare variants, and discuss supported tooling. It is not a good idea to imply permissions or guarantees beyond what the official release materials actually state.

That small caution makes technical content more credible.

Why Gemma 4 is worth writing about

Gemma 4 sits at the intersection of several important trends. It is open, practical, multimodal, long-context capable, and deployable across very different hardware tiers.

That combination makes it useful not only for researchers, but for actual product builders. The most exciting Gemma 4 projects will probably not look like flashy AI demos at all.

They will look like better apps, faster workflows, smarter local assistants, safer enterprise tools, and more inclusive software that continues working even when connectivity is weak. That is what makes Gemma 4 more than a release.

It is a signal that local AI is becoming real infrastructure for developers.

Helpful Links

https://www.youtube.com/watch?v=iB5POKmXfWY
https://developer.android.com/blog/posts/android-studio-supports-gemma-4-our-most-capable-local-model-for-agentic-coding
https://www.youtube.com/watch?v=7LEvSOiTWZk

OpenVibe: An Open-Source AI Coding IDE That Works With Any Model

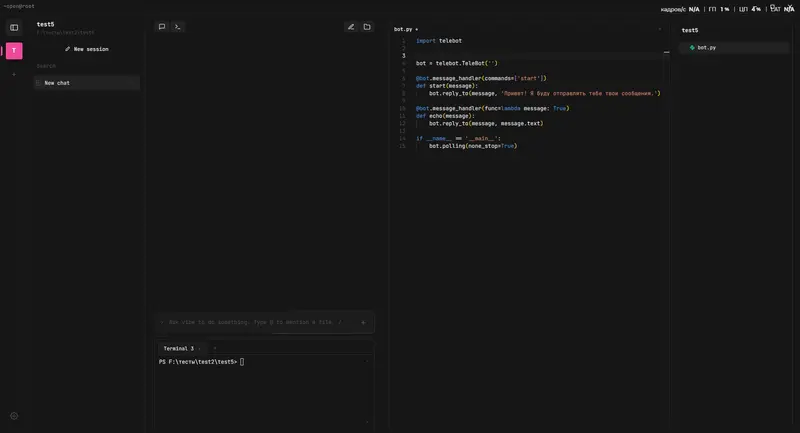
openvibe is an open-source desktop IDE with a built-in AI coding agent. The agent has direct access to your file system, terminal, and web search, so you can describe a task and it executes the full workflow — reading code, writing new files, editing existing ones, running commands.

Unlike Cursor or Claude Code, openvibe doesn’t lock you to a single AI provider. It works with any OpenAI-compatible API: OpenAI, Anthropic Claude, Google Gemini, Groq, DeepSeek, OpenRouter, and local models via Ollama, LM Studio, or vLLM. Switch providers in two clicks. No subscription, no account, no telemetry.

Core capabilities:

  • Agentic AI — autonomous file operations, command execution, web search
  • MCP support — connect external tools (GitHub, databases, browsers) via Model Context Protocol
  • Project-specific rules — drop a .vibe/rules.md in your project to teach the AI your conventions; it reads them at session start and follows them strictly
  • Real-time Monaco editor — see AI code changes live as they happen
  • Integrated PowerShell/bash terminal with multiple tabs
  • Multi-project workspace with isolated chat history per project
  • Project templates for React, Next.js, Express, Flask, Electron, Telegram Bot, Vue
  • Project snapshots — one-click zip backup
  • Markdown and LaTeX rendering with diff view for AI edits
  • Works fully offline with local models

License: MIT. No tracking, no required account, no cloud dependencies.

GitHub: https://github.com/muradtedeev0912-maker/openvibe
Website: https://openvibe-beta.vercel.app/

Looking for feedback from developers who use AI coding tools daily — what’s missing, what works, what’s broken.

I Inspected the System Program and It Looked Just Like My Wallet

The Challenge

Day 25 of 100 Days of Solana: inspect system program accounts. Your wallet, the System Program, native programs, sysvar accounts. Use the CLI and Explorer. Understand how they differ and how they’re the same.

I’d been hearing “everything is an account” for 25 days. This was the day I actually verified it.

Starting With My Wallet

solana account <MY_ADDRESS> --url devnet

Output:
Balance: 1.247 SOL
Owner: 11111111111111111111111111111111
Executable: false
Rent Epoch: 0

The owner field jumped out: 11111111111111111111111111111111. The System Program. My wallet isn’t a special type of thing — it’s an account that the System Program owns and manages. Every SOL transfer I’ve ever made was the System Program modifying this row.

Inspecting the System Program Itself

solana account 11111111111111111111111111111111 --url devnet

Output:
Balance: 1 SOL
Owner: NativeLoader1111111111111111111111111111111
Executable: true
Data Length: 14 bytes

The System Program the program that underlies every wallet on Solana, that has processed billions of transactions is an account with 14 bytes of data and a 1 SOL balance. The executable: true flag is the only thing that distinguishes it from my wallet structurally. Same schema. One boolean different.

The 14 bytes confused me at first. After some digging: native programs have their code compiled directly into the validator binary. The account is essentially a registry entry a marker that says “this address is the System Program.”

The BPF Loader

solana account BPFLoaderUpgradeab1e11111111111111111111111 --url devnet

Executable: true
Owner: NativeLoader
Data Length: 36 bytes

The ownership chain: NativeLoader → BPF Loader → my future programs. Three levels, all expressed as account ownership fields.

Sysvar Accounts

solana account SysvarC1ock11111111111111111111111111111111 --url devnet

The Clock sysvar holds the current slot, epoch, and unix timestamp. Updated every slot by the runtime. Programs that need time-based logic read this account.

What surprised me: it’s just an account. executable: false, owned by the Sysvar program, 40 bytes of encoded data. The same structure as everything else.

The Mental Model I Built

Every account sits on a spectrum from “pure data” to “pure code,” determined entirely by two fields:

  • executable is this account code or data?
  • owner which program has authority over this account?
Account type executable owner
Wallets false System Program
Regular programs true BPF Loader
Native programs true NativeLoader
Sysvar accounts false Sysvar program
Your data accounts false your program

No special types. No separate registries. One table, differentiated entirely by field values.

The CLI Commands Worth Bookmarking

solana account 11111111111111111111111111111111              # System Program
solana account BPFLoaderUpgradeab1e11111111111111111111111  # BPF Loader
solana account SysvarC1ock11111111111111111111111111111111  # Clock sysvar
solana account SysvarRent111111111111111111111111111111111  # Rent sysvar

One command. Any account. The entire network is readable.