Nintendo’da yüzler gülüyor: Switch 2 hedefi 20 milyona çıktı
 Nintendo, Switch 2 fiyatlarına gelen zamma rağmen talebin güçlü kalacağını düşünüyor. Şirketin üretim hedefini 20 milyon adede çıkardığı ortaya çıktı. İşte detaylar…
 Nintendo, Switch 2 fiyatlarına gelen zamma rağmen talebin güçlü kalacağını düşünüyor. Şirketin üretim hedefini 20 milyon adede çıkardığı ortaya çıktı. İşte detaylar…
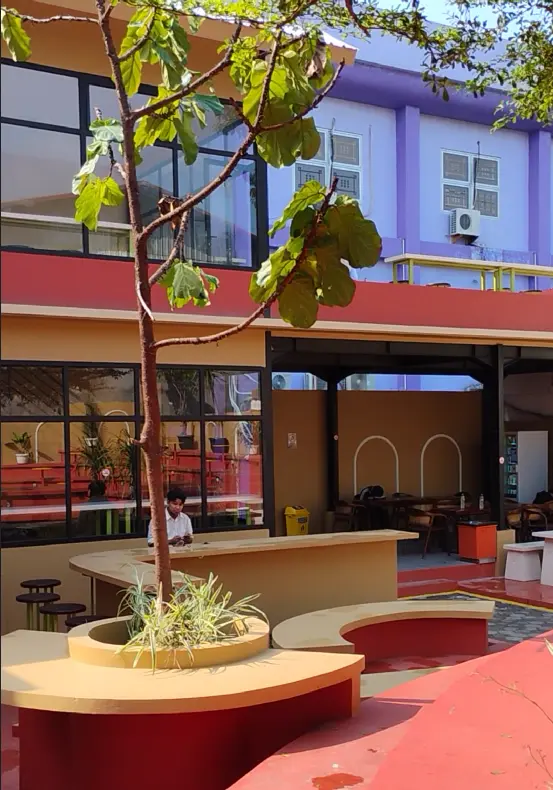
Membangun kompetensi di dunia teknologi jelas butuh lingkungan yang mendukung. Universitas Amikom Yogyakarta menyediakan ekosistem terintegrasi untuk menjembatani jarak antara teori akademik dan kebutuhan industri yang sebenarnya. Bagi saya pribadi, ketersediaan sarana kampus bukan sekadar pendukung jadwal perkuliahan, melainkan sebuah ruang untuk mengasah keterampilan teknis serta inovasi secara langsung.
Gambaran lengkap mengenai visi dan infrastruktur kampus dapat disimak melalui tayangan profil berikut:
Sumber video: Channel YouTube Universitas AMIKOM Yogyakarta
Selain fasilitas utama seperti laboratorium, area pendukung seperti Coworking Space atau Food Corner yang terletak di depan Gedung 4 memegang peranan yang tidak kalah penting. Area terbuka ini menjadi titik temu favorit saya beserta banyak mahasiswa lain untuk berkolaborasi dalam pengerjaan proyek, bertukar ide arsitektur aplikasi, maupun sekadar membangun relasi profesional. Penggunaan fasilitas publik semacam ini sangat melatih kemampuan komunikasi dan kerja tim yang esensial di dunia kerja nantinya.

Integrasi berbagai fasilitas mulai dari laboratorium komputer, pusat layanan riset, hingga studio kreatif memperlihatkan bagaimana aspek teknis dan industri berjalan berdampingan secara harmonis. Infrastruktur ini memastikan kita mampu menguasai keahlian spesifik sekaligus memahami nilai praktis dari sebuah produk digital sebelum terjun langsung ke pasar kerja.
Kesiapan fasilitas kampus benar benar memberikan nilai tambah yang signifikan bagi pengembangan diri. Lingkungan yang kondusif memungkinkan kita untuk mematangkan persiapan karier sejak dini dengan standar yang mendekati kebutuhan industri modern.
Menurut kalian, seberapa besar pengaruh fasilitas kampus terhadap kesiapan kerja mahasiswa? Silakan bagikan pendapat kalian di kolom komentar ya! Jangan lupa tinggalkan Reactions (Like) dan klik Follow jika artikel ini bermanfaat.

Today morning when I waked up, my AI agent reviewed 14 restaurant ratings in Indiranagar, updated a shared Google Sheet, signed a 20-page PDF I’d been ignoring for a week, and wrote a bash script to clean up my server logs.
I didn’t ask it to do any of that. It just… does things now.
Meet OpenClaw — my long-running autonomous agent that lives on a Raspberry Pi, plugged into Discord, running 24/7. It manages my memory, handles research, writes code, edits documents, finds the best weekend spots in Bangalore by scraping live ratings — basically, it runs half my life on autopilot.
But a few weeks ago, I noticed something that bothered me.
I asked it: “Write a Python script to parse JSON logs.” Simple coding task. It sent that request to a cloud API, waited 3 seconds, burned tokens I paid for, and came back with an answer — when I had a perfectly capable local LLM sitting idle on my Mac Mini, three feet away.
Then I asked: “Think step by step about the trade-offs between event-driven vs polling architecture for my notification system.” That’s a hard reasoning question. I want that going to a frontier model. That’s worth the tokens.
Same agent. Same endpoint. Completely different needs.
And that’s when a stupid idea hit me:
What if the system could figure out which brain to use — before the request even reaches a model?
Turns out, it’s not stupid at all. And it took me a weekend, a Raspberry Pi, a Mac Mini, 50 lines of Python, and an open-source gateway to build it.
Here’s how.
The Setup

Here’s what’s running in my living room:
Raspberry Pi → Runs OpenClaw, my autonomous agent. It takes input from Discord, manages context, memory, and orchestrates everything.
Mac Mini → The brain farm. Runs three things:
Ollama with qwen2.5-coder:7b — a local coding model that never leaves my network
AgentGateway — an open-source AI gateway from Google that handles routing, auth, observability
A lightweight Python router — the “intent classifier” I wrote in ~50 lines of code
The magic? OpenClaw doesn’t know any of this is happening. It just sends a request to one endpoint. Behind the scenes, the system figures out the rest.
The Architecture

Three models. Three price points. One unified endpoint. OpenClaw just hits http://192.168.1.15:1234/v1/chat/completions and forgets about it.
Why AgentGateway?
I evaluated a few options — raw Envoy, Nginx with Lua scripting, even building a full proxy from scratch. But AgentGateway stood out for a few reasons:
What it gives you out of the box:
Protocol translation — It speaks OpenAI-compatible API on the frontend, but can talk to Gemini, Vertex AI, Bedrock, Ollama, and more on the backend. I don’t write a single line of provider-specific code.
Backend authentication — API keys are managed at the gateway level. OpenClaw never sees or stores any API key. I just set backendAuth: key: $GEMINI_API_KEY in the config and it handles the rest.
Model aliasing — OpenClaw sends model: “inteli-llm” in every request. AgentGateway silently translates that to qwen2.5-coder:7b, gpt-4o, or gemini-2.5-flash depending on which route matched. The client has no idea.
Observability — Every request gets logged with provider name, model, token counts, and latency. I can see exactly how many tokens are going to OpenAI vs staying local.
Prompt guards & rate limiting — Built-in regex-based PII masking, webhook-based content moderation, and rate limiting. Enterprise-grade features I get for free.
Weighted load balancing & failover — If Ollama crashes (it happens), I can configure automatic failover to a cloud model. No downtime.
What it doesn’t do (yet): Content-aware routing. AgentGateway routes based on path, headers, and methods — which is the right design for a gateway. It doesn’t peek into your request body to decide where to send it. That’s a feature, not a bug — gateways should be fast and protocol-level, not parsing JSON payloads.
But I needed content-aware routing. So instead of searching for other tool, I extended it.
The 50-Line Router That Makes It All Work
I wrote a tiny FastAPI proxy that sits in front of AgentGateway. Here’s what it does:
code, python, script, function, bug? → codingthink, analyze, reasoning, deduce? Or prompt > 400 chars? → reasoningcoding_keywords = ["code", "python", "javascript", "bash", "script", "function", "bug"]
reasoning_keywords = ["think", "analyze", "explain in detail", "reasoning", "logic", "deduce"]
if any(k in prompt_lower for k in coding_keywords):
intent = "coding"
elif len(prompt) > 400 or any(k in prompt_lower for k in reasoning_keywords):
intent = "reasoning"
else:
intent = "simple"
The Cost Equation
Here’s what this setup actually saves me:
| Intent | Model | Where it runs | Cost per 1M tokens |
|---|---|---|---|
| Coding | qwen2.5-coder:7b | Local (Ollama) | $0 |
| Simple Q&A | gemini-2.5-flash | Google Cloud | ~$0.15 |
| Deep Reasoning | gpt-4o | OpenAI | ~$2.50 |
Before this setup, every single request was going to a cloud API. Now, roughly 60-70% of my queries stay local — coding questions, quick lookups, simple formatting tasks. They’re fast, free, and private.
The expensive reasoning model only gets called when I genuinely need it. And the mid-tier Gemini handles everything in between.
My monthly API bill dropped significantly, and the local responses are actually faster.
Design Choices & Why They Worked
1. Header-based routing over path-based routing Initially, I was going to use URL paths (/coding, /reasoning, /simple) and strip them with URL rewriting. But header injection is cleaner — the original request path stays intact, and AgentGateway’s header matching is first-class.
2. Classification at the proxy, not the gateway I could have tried to use AgentGateway’s CEL expressions or ExtProc policies for classification. But those run after backend selection, not before. Keeping classification in a separate lightweight layer means I can swap algorithms without touching my gateway config.
3. Keyword heuristics over ML classifiers Could I use a small classifier model or even RouteLLM for smarter routing? Absolutely. But for a homelab, keyword matching is:
4. One unified model name OpenClaw sends model: "inteli-llm" for everything. AgentGateway’s modelAliases feature translates it per-route. This means I can swap out backend models without touching a single line of OpenClaw’s config. Last week it was gemini-1.5-flash, this week it’s gemini-2.5-flash. OpenClaw never knew.
What’s Next
Smarter classification — Maybe a tiny local classifier model, or even using the first few tokens of a response to reclassify and retry on a better model.
Metrics dashboard — AgentGateway already emits OpenTelemetry traces. I want to hook up a Grafana dashboard to see which models are handling what, with latency and token breakdowns.
Failover chains — If Ollama is under heavy load, automatically fall back to Gemini for coding tasks. AgentGateway supports priority groups for this.
More agents — OpenClaw is just the beginning. I want to run specialized agents for different domains, all routing through the same gateway.
The Takeaway
You don’t need a Kubernetes cluster or a $10K GPU server to build a multi-model AI system. A Raspberry Pi, a Mac Mini, an open-source gateway, and 50 lines of Python got me:
✅ An always-on autonomous agent ✅Intelligent routing ✅across 3 different LLMs ✅Local-first for privacy and speed ✅Cloud when I need the horsepower ✅Zero API keys exposed to the client ✅A monthly bill I actually don’t mind paying
The best part? The entire config is a single YAML file and a single Python script. No Docker. No Kubernetes. No Terraform. Just two processes on a Mac Mini and an agent on a Pi.
Sometimes the best infrastructure is the one you can explain in a napkin sketch.
If you’re building something similar or want to see the config files, drop a comment — happy to share the full setup.

AI #HomeAssistant #LLM #AgentGateway #Ollama #OpenAI #Gemini #HomeLab #BuildInPublic #MacMini #RaspberryPi #AIEngineering
There is a comfortable myth around becoming a programmer. It says you can watch a few courses, copy a few tutorials, build a portfolio app, learn a modern framework, and become employable in a few months. Sometimes that happens. More often, it creates people who know how to repeat steps, but do not yet understand what they are doing.
Programming is not mainly about knowing syntax. It is not about collecting certificates. It is not even about choosing the perfect first language. A programmer solves problems by turning unclear ideas into working systems. That requires a very specific skill: the ability to think in code.
That skill is built through long, focused practice. There is no polite shortcut around it.
Programming Is Not Watching Someone Else Program
Many beginners spend too much time preparing to learn. They watch videos about roadmaps. They compare languages. They join communities. They read debates about whether Java, Python, Go, C#, JavaScript, Rust, or C++ is the best first language.
Some of that research is useful. Too much of it becomes procrastination.
At some point, you have to write code. Then you have to break it, fix it, extend it, read other people’s code, get confused, search for answers, rebuild the project, and repeat the process until the confusion becomes more structured.
That is the part that many beginner programs hide. Real programming skill appears when your brain starts connecting three things:
Until that connection becomes natural, every problem feels like a wall. After enough practice, the wall does not disappear, but you start seeing cracks in it.
Focus Matters More Than Motivation
One brutal but useful truth is that becoming a programmer requires a serious period of focus. Not a year in isolation, and not ten hours every day, but enough uninterrupted time to let your brain adapt.
Programming is cognitively expensive. You hold state in your head. You trace logic. You remember assumptions. You compare what the program should do with what it actually does. Constant interruption destroys that process.
A beginner who studies for eight distracted hours may learn less than someone who spends two focused hours every day writing and debugging code. The real requirement is not suffering. It is continuity.
You need enough regular practice to keep the work warm in your mind. If you return to the same project only once a week, you spend most of your time remembering what you were doing. If you work every day, even briefly, the project starts living in your head. That is when learning accelerates.
But remember, mental exhaustion is not the same as discipline. If you burn out, stop sleeping, stop moving, and turn learning into punishment, your code will not improve for long. Programming requires concentration, memory, patience, and emotional stability. Destroying those things is not heroic.
A better rule is this: Create an environment where deep work is possible, but protect the body and mind that have to do that work. Take walks. Sleep. Exercise. Step away when stuck. Many programming problems are solved after your brain gets distance from them.
Choose a First Language, but Do Not Worship It
Some strongly argue for Java as a first language. Others push back, with fair reasons.
Java is a reasonable first language because it has mature tooling, strong typing, many books, many examples, and a large ecosystem. It also forces beginners to deal with structure. You learn classes, methods, types, compilation, packages, build tools, and errors that are often explicit enough to teach you something.
But Java is not the only valid path.
The better advice is this: Choose a language that lets you build things you care about while still teaching you real programming concepts.
If you want backend systems, Java, C#, Go, or Python can all work. If you want web interfaces, JavaScript or TypeScript will become necessary. If you want systems work, C, C++, or Rust may eventually matter. If you want mobile, Swift or Kotlin may be more relevant. The first language is not a life sentence. It is a training environment. What matters is that you do not jump between languages every two weeks because the next one looks easier.
Start With Exercises, but Do Not Stay There
Textbook exercises are useful because they isolate concepts. You should write small programs that teach variables, loops, functions, collections, files, errors, data structures, and basic algorithms.
But exercises alone are not enough. A person can complete 100 small tasks and still freeze when faced with a real codebase. Real projects are messy. They have naming conventions, build files, dependencies, old decisions, strange abstractions, and code written by people who are no longer around.
That is why one of the best learning methods is modifying existing open source software. Not contributing immediately and not trying to impress maintainers. Just learning to work with a real project.
Clone something. Build it locally. Change a label. Remove a button. Add logging. Disable one branch of logic. Find where a configuration value is read. Break the build and fix it. Trace a request from the entry point to the output.
This teaches skills tutorials rarely teach:
That last skill is critical. Professional developers spend a huge amount of time reading and changing existing code. Greenfield work is the exception, not the norm.
Build Something Personally Useful
One of the best insights is simple: write programs that are useful to you. A textbook task may teach a concept, but a personally useful project keeps you emotionally involved. That matters. Curiosity makes difficult work survivable.
Build a small tool for yourself. A notes app. A file organizer. A text parser. A personal dashboard. A tiny game. A command-line utility. A script that automates something boring. A small editor. A local search tool. A budget tracker. Anything you would actually use.
The point is not originality. The point is friction. A useful project forces real questions:
Those questions are where programming starts becoming engineering.
Use Search and AI, but Do Not Outsource Your Brain
There is a strong debate about whether a programmer should rely on search engines or AI. The sensible answer is somewhere in the middle. A developer who cannot search is ineffective. Documentation, examples, issue trackers, source code, specifications, and community discussions are part of the job. But a beginner who searches every basic step without understanding the answer is also in trouble.
There is a big difference between searching:
“How do I parse command line arguments in Go?”
and searching:
“How do I write a program?”
The first is normal. The second means the foundation is missing.
AI assistants make this distinction even more important. They can help generate examples, explain errors, create small scripts, and suggest approaches. They can also hallucinate APIs, produce insecure code, and hide the learning process behind confident output.
Use AI like a junior assistant, not like a replacement brain. Ask it to explain. Ask it for alternatives. Ask it to review your code. Ask why a solution works. Then verify the answer against documentation and run the code yourself. The goal is to keep responsibility for understanding.
Courses and Mentors Help, but They Cannot Do the Work
Courses can give structure. Mentors can save you from wasting weeks on the wrong path. A good teacher can explain concepts that documentation makes needlessly painful.
But no mentor can install programming skills into your head. You still need the hours. You still need the frustration. You still need to debug your own misunderstanding.
The best use of a mentor is not asking them to solve everything. It is asking better questions:
Passive watching does not build the judgment that comes from real conversation.
What “Ready for Work” Really Means
You do not need to know everything to get your first developer job. Nobody does. But you should be able to do certain things without panic:
That is already far beyond “I watched a course.” The gap between what candidates expect and what employers actually look for is wider than most beginners realize — and closing it requires exactly the practical work described above.
Final Thoughts
Becoming a programmer is not about entering the IT industry. It is about learning to think clearly enough that a machine can execute your idea. That takes time. It takes repetition. It takes curiosity. It takes humility to be wrong 20 times before the program finally works.
The good news is that the path is not mysterious. Write code. Read code. Change code. Break code. Debug code. Build things you care about. Study the concepts behind the tools. Use search and AI carefully, but do not let them replace your understanding.
At some point, you will notice that you are no longer merely copying solutions. You are thinking in code. That is when you start becoming a programmer.
Artificial Intelligence is rapidly evolving from simple chatbots into intelligent automation systems capable of performing real-world actions. Over the last few months, I have been deeply exploring AI automation workflows, backend engineering and full stack development during my AI & Automation Internship at NEXE.AGENT.
One of the most exciting outcomes of this journey is my latest project:
NEXEAGENT Multi-Tool AI Agent
A production-style AI automation assistant designed to intelligently perform multiple tasks including:
Unlike traditional chatbot systems, this project focuses on creating an AI assistant that can actually take actions instead of only generating responses.
Project Vision
The main idea behind this project was simple:
Build an AI system that behaves more like an intelligent assistant than a normal chatbot.
The agent can analyse prompts, select tools, execute functions, manage workflows and return structured results.
For example, the AI agent can:
This project helped me understand how modern AI agents are designed and how multiple systems can work together inside a single intelligent workflow.
Technologies Used
The complete project was built using modern full stack technologies.
Backend
Frontend
Additional Systems
Core Features
🤖 AI Chat Agent
The system uses Google Gemini AI to process prompts and intelligently decide which tool or workflow should be executed.
💼 AI Job Search
The platform can search for:
The AI agent summarizes results and organizes useful information.
📝 Notes System
A lightweight JSON-based note management system allows saving important links, summaries and AI-generated outputs.
📧 Email Automation
The platform integrates Gmail SMTP automation to send emails directly through the AI workflow.
🛠 Utility Tools
Custom tools include:
🏗 Architecture & Workflow
One of my main goals during development was to maintain a professional and scalable project structure.
The project uses:
This structure makes the application easier to scale and maintain.
Challenges & Learning Experience
During development, I faced several real-world engineering challenges:
Solving these issues helped me gain practical experience in:
🌍 Why This Project Matters
AI automation is becoming one of the most important areas in software engineering.
This project represents more than just a chatbot.
It demonstrates how AI can:
Building projects like these is helping me move deeper into the world of AI engineering and automation systems.
🔗 GitHub Repository
You can explore the complete project here:
Repository: https://github.com/YasirAwan4831/nexeagent-multi-tool-ai-agent
👨💻 Connect With Me
GitHub
https://github.com/YasirAwan483
LinkedIn
https://linkedin.com/in/yasirawan4831
I’m currently focused on:
Final Thoughts
This project was an incredible learning experience and helped me better understand how modern AI systems can be structured professionally.
From backend APIs to AI workflows and frontend dashboards, every part of this project contributed to improving my engineering mindset and practical development skills.
I’m excited to continue building more intelligent systems, automation platforms and AI-powered applications in the future
Thanks for reading.
#AI #Automation #Python #Flask #React #GeminiAI #FullStackDevelopment #SoftwareEngineering #ArtificialIntelligence #WebDevelopment #GitHub #NEXEAGENT #AIProjects #MuhammadYasir #YasirAwan4831
I recently experimented with building an Instagram OSINT project on Linux using Python and HikerAPI. Originally I tried older scraping libraries and unofficial Instagram API wrappers, but many of them were unreliable because Instagram now aggressively blocks automation attempts.
After some testing, I found that using an external API service like HikerAPI was much more stable for learning and development purposes.
Why I Switched
At first I used tools based on:
The problem was:
Modern Instagram protection systems make direct scraping much harder than before.
My Setup
I used:
Creating the virtual environment:
python -m venv venv
source venv/bin/activate.fish
Installing dependencies:
pip install requests httpx
Basic HikerAPI Example
Here’s a simple request example:
import requests

headers = {
    "x-access-key": "YOUR_KEY"
}

r = requests.get(
    "https://api.hikerapi.com/v2/user/by/username?username=instagram",
    headers=headers
)

print(r.json())
What I Learned
A few things became obvious during testing:
Tradeoffs
HikerAPI is convenient, but it’s not fully free. You need credits for larger usage. For hobby projects and learning, that may still be easier than constantly fixing broken scrapers.
Meanwhile, tools like:
are still excellent for public OSINT workflows.
Final Thoughts
This was a fun experiment for learning Python, Linux tooling, and OSINT workflows. If you’re building similar projects, I’d strongly recommend:
HikerAPI definitely simplified the process compared to older scraping approaches.
This is a submission for the Gemma 4 Challenge: Write About Gemma 4
Your AI can read. Gemma 4 can see. Here’s what that actually changes.
For two years, talking to an AI meant typing. You described things in words, the AI answered in words. If you wanted help with a photo, a handwritten note, or a screenshot, you first had to translate it into a paragraph — and hope you didn’t leave out the part that mattered.
Gemma 4 is multimodal, which is a clunky word for a simple idea: you can show it a picture instead of describing one. I spent an afternoon doing exactly that, and the gap between “tell the AI” and “show the AI” turned out to be bigger than I expected.
Here’s what multimodal actually means, three things I showed it, and how you can try it yourself in about five minutes — free, no fancy hardware.
“Multimodal” in one sentence
A mode is a type of input: text is one mode, images are another, audio is a third.
A text-only model is like texting a friend who can only read words. A multimodal model is like video-calling that friend — you can hold something up to the camera and they just see it.
Gemma 4 handles text, images, and audio through the same model. You don’t bolt on a separate “image reader.” The thing that understands your sentence is the same thing that understands your photo. That matters more than it sounds, and the examples make it obvious.
Three things I showed it
I didn’t write clever prompts. I literally uploaded a photo and asked a plain question, the way you’d ask a knowledgeable friend.
1. A drooping houseplant. I uploaded a photo of a sad-looking plant and asked, “What’s wrong with this?” It pointed out the yellowing lower leaves and damp-looking soil and suggested I was overwatering — and to check that the pot actually drained. I never told it the leaves were yellow. It looked.
2. A handwritten grocery list. My handwriting is genuinely bad. I snapped a photo and asked it to type the list out. It read all but one item correctly (it guessed “tomatoes” where I’d scrawled something closer to “tamarind” — fair). Typing that list myself would’ve taken longer than photographing it.
3. A screenshot of a line chart with no title. I asked, “What’s the trend here?” It described the steady climb, called out the dip in the middle, and noted the sharp rise at the end — reading the shape of the data, not just labels. For someone who finds charts intimidating, that’s a quiet superpower.
None of this was perfect. It got one grocery item wrong, and if I’d asked it to read tiny dense text it would’ve struggled. But “show instead of describe” changes the kind of help you can ask for. You stop being the translator.
Why this is a bigger deal than it looks
Three reasons this matters beyond the novelty:
That last point is the one I keep coming back to. A model that can see, running entirely on hardware you own, with no internet connection, would have sounded like science fiction in 2023. It’s a free download in 2026.
Try it yourself in five minutes
You don’t need a powerful computer to start. Two paths, easiest first.
Path A — zero install (browser, free)
That’s the whole thing. No setup, no card, no code.
Path B — run it on your own machine (offline, private)
If you want it running locally with nothing leaving your computer:
ollama run gemma4:e4b
The first run downloads the model once (a couple of gigabytes). After that it works with no internet.
Start with Path A to feel the magic, switch to Path B when you want privacy.
What I’d explore next
The thing I want to try next is audio: Gemma 4 hears as well as sees, which means you could hand it a voice memo and a photo together and ask one question about both. We’re early in figuring out what that unlocks.
But the simple version is already enough to change how I use AI day to day. I type less. I show more. And the friend on the other end of the video call finally has eyes.
If you try it, show it something weird and tell me what it said — that’s the fun part.
Want to go deeper? The official models are on Hugging Face and Kaggle, all free to download.
The struggle of building solutions that actually hold up
Forget factory tools and manufacturing jargon. The real struggle is this: AI can write code faster than you can think, but it can’t tell you what’s worth keeping. That’s where senior devs get their edge.
Here’s how it works, using what actually happens in the trenches:
1. The Quality of Your Question Decides the Quality of Your Solution
AI is a mirror. Ask it “my code doesn’t work” and you get garbage back.
Good programmers do this instead:
localStorage, but it still fails.”Why? Asking effective questions saves time, speeds up debugging, streamlines collaboration, and makes AI genuinely useful. Garbage in, garbage out. Question quality = answer quality.
2. Knowing When to Stop Coding Is the Real Skill
Here’s the trap: More code = more productivity. It feels true, but it’s backwards.
Reality: More code = more maintenance.
Every feature, abstraction, and layer you add is something you’ll have to debug at 2 AM six months from now. Experienced engineers know when to stop.
The better solution is usually to:
The shortest code that reliably solves the problem is almost always the easiest to maintain. Elegance isn’t about being clever; it’s about being boring in a good way.
3. Stay Calm When Everything’s On Fire
Beginners panic when production goes down. They:
Skilled engineers have developed emotional discipline. Their debugging process is systematic:
Stress causes tunnel vision. Calm gets you to the root cause faster.
4. Naming Things Is Half the Job
There’s a classic computer science joke for a reason: “There are only two hard things in computer science: cache invalidation, naming things, and off-by-one errors.”
// Hard to read, raises cognitive load
let x;
let data2;
function processThing() {}
Good names remove confusion, cut onboarding time, reduce bugs, and save valuable mental effort:
// Intent is immediately clear
let customerProfile;
let invoiceTotal;
function calculateMonthlyRevenue() {}
Code is read 10x more than it’s written. If you can’t tell what processThing() does without opening it up and reading its internals, you’ve already lost. Clear names matter more than clever algorithms.
5. Manage Your Energy, Not Just Your Time
Programming is mentally expensive. You can work an 8-hour day and get absolutely nothing done if you are distracted, sleep-deprived, or context-switching every five minutes. Time management is completely useless if your brain is fried.
Consider the difference:
Elite devs don’t just manage calendars; they manage cognitive capacity. They protect:
Burnout destroys productivity faster than a lack of knowledge ever will. AI won’t fix this for you. If you’re fried, you’ll just use AI to generate more garbage, faster.
💡 So How Does AI Fit Into This?
AI gives you wings, but only if you’re already a pilot.
The struggle of creating a worthy solution isn’t writing more code. It’s knowing what to delete, when to stop, and how to think clearly when everything is broken. AI can’t do that for you. But if you’ve got those skills, AI makes you 10x faster at executing them.
6. Break Giant Problems Into Tiny Pieces
Junior devs see “Build an e-commerce platform” and freeze. Experienced devs shrink the scope immediately:
Programming is, at its core, decomposition. Huge, complex systems are just collections of tiny, solved problems.
With AI: Don’t ask it to “build me an e-commerce platform.” Ask it to “write a localized cart reducer in TypeScript with unit tests.” Small chunks lead to better AI output and lightning-fast feedback loops.
7. Understanding Human Behavior Is an Engineering Skill
Software is built for people, but many developers only think about machines.
Understanding human behavior helps you predict:
Technical skill without human understanding creates systems that are mathematically correct but practically unusable. Empathy is an engineering skill. AI can write code, but it can’t tell you if a user will actually find your layout intuitive. That’s on you.
8. Learning to Estimate Work Accurately
New devs often say, “That feature should take about an hour.”
They forget that actual delivery includes:
The actual time: 8 hours.
Good estimation builds trust with clients, product managers, and teammates. Experienced devs always build a buffer for uncertainty because they know things always break.
AI Tip: Before committing to an estimate, ask the AI: “What are the hidden architectural gotchas or edge cases for this feature?” It will frequently surface things you forgot to account for.
9. Write Notes for Future-You
Memory fails. Over time, “future-you” essentially becomes a stranger.
Great programmers document:
If you don’t document your work, you will spend hours re-learning what you already figured out last month. AI can easily help with this if prompted: “Write a README section explaining why I chose library X over library Y here.”
10. Recognizing Patterns Is Where Speed Comes From
Programming eventually becomes an exercise in pattern recognition.
With enough years of exposure, you instantly spot:
This isn’t magic; it’s accumulated experience. When you’ve watched twenty authentication systems break the exact same way, you can diagnose the problem in 30 seconds.
With AI: AI can generate design patterns fast, but you are the gatekeeper who must say, “Wait, I’ve seen this pattern cause a memory leak in high-concurrency environments.” Reading and reviewing code is now a much more critical skill than simply generating it.
11. Know When Not to Reinvent Everything
Developers love to rebuild tools—sometimes for learning, but often for ego.
Common traps include:
While building from scratch teaches you a lot, it can also waste weeks of valuable project time. Strong engineers ask: “Does this need to be custom, or does a mature, tested library already exist?”
Because AI makes generating custom code so effortless, this question is more critical than ever. Default to proven tools unless you have a highly specific, business-critical reason not to.
The pattern here: Senior devs win because they manage their mental bandwidth, break problems down, empathize with users, estimate realistically, document for the future, and avoid unnecessary work. AI amplifies these habits, but it cannot replace them.
12. Debugging Through Elimination, Not Guessing
Beginners debug by guessing. They think, “Maybe it’s the database?” and change five different configurations. When it remains broken, they’ve only succeeded in adding chaos to the system.
Effective debugging is scientific detective work:
Systematic elimination beats random experimentation every single time. AI is a fantastic brainstorming partner here—paste your logs and ask, “What are 5 possible causes for this error?”—but you must still systematically verify them.
13. Communication Is a Programming Skill
Many people picture coding as a solitary activity. In reality, modern software development is deeply collaborative.
You communicate constantly through:
A developer who can explain complex ideas clearly will almost always outperform someone who is technically brilliant but impossible to collaborate with. Communication scales your technical expertise.
Rule of thumb: If you can’t explain your AI-generated code in a PR, you don’t actually understand it. Delete it and try again.
14. Focus on Fundamentals over Frameworks
Technology moves fast. Frameworks evolve, languages shift, and hyped tools can disappear overnight. If you only learn the API surface of the latest trendy library, your knowledge has an expiration date.
Strong engineers focus on the underlying fundamentals:
When you understand how systems work at a fundamental level, transitioning from React to Svelte, or from Node to Go, becomes a minor syntax adjustment rather than a career crisis.
15. Master Meta-Learning (Learning How to Learn)
The ultimate survival skill in tech is meta-learning. Eventually, every programmer hits a wall where there is no tutorial, no StackOverflow post, and no step-by-step guide for the problem at hand.
To learn efficiently:
AI changes this game entirely. You can use it to explain complex concepts, generate scaffolded practice projects, and summarize dry documentation. But remember: AI cannot build the mental model for you. You still have to do the hard cognitive work of learning.
Final Thoughts: The Real Upgrade
The biggest career upgrades rarely come from memorizing syntax. They come from these invisible habits:
Frameworks change every few years, but these core habits remain valuable for decades. They are what separate developers who merely write code from true software engineers.
AI gives you speed, but these habits give you direction. And without direction, speed just gets you lost faster.
This is a submission for the Gemma 4 Challenge: Build with Gemma 4
What I Built
SafeSMS is a privacy-first Android application designed to protect users from the rising threat of SMS-based scams, phishing, and spam.
Traditional SMS scanners and spam filters often send your private text messages to the cloud for analysis, creating severe privacy concerns. SafeSMS takes a completely different approach: it brings the intelligence directly to the device.
By running a powerful, on-device AI model, it performs real-time threat detection locally on your phone. It monitors incoming messages, categorizes them (SAFE, SUSPICIOUS, or SCAM), provides a confidence score, and explains why a message is dangerous.
The app features a sleek dark-mode UI built with Jetpack Compose, including:
✨ Example Detection
Incoming SMS:
Your bank account will be blocked. Click immediately: http://bit.ly/xyz
SafeSMS Output:
Demo
[https://youtu.be/2NhvyiARX1c]
Code
How I Used Gemma 4
To enable real-time, completely private SMS analysis, SafeSMS uses Gemma 4 via LiteRT for on-device inference.
Model Selection: Gemma 4 E4B
I selected the E4B model because it perfectly fits mobile and edge environments:
Absolute Privacy
All SMS data stays on-device. No cloud calls, no data leakage.
Zero Latency & Offline Capability
Messages are analyzed instantly without any network dependency.
Resource Efficiency
The lightweight model runs efficiently inside a background Android service with minimal battery impact.
Strong Reasoning in a Small Model
Despite its compact size, the model effectively detects:
🧠 Prompting Strategy
The model is prompted using a structured classification + reasoning format, enabling it to return:
This ensures both accuracy and transparency in predictions.
⚡ Performance
🏗️ Architecture
SafeSMS follows a fully on-device architecture, ensuring privacy, speed, and reliability.
🔄 Flow Overview
Incoming SMS
Protection Service
SafeSMS Model Controller
On-Device AI Inference
Result Handling
User Interface (Jetpack Compose)
🧩 Architecture Components
🚀 Why This Architecture?
🔮 Future Improvements
🏁 Final Thoughts
SafeSMS demonstrates how powerful AI models like Gemma 4 can run entirely on-device, enabling real-world applications that are fast, private, and reliable.
It’s a step toward a future where user data never has to leave their device to stay safe.
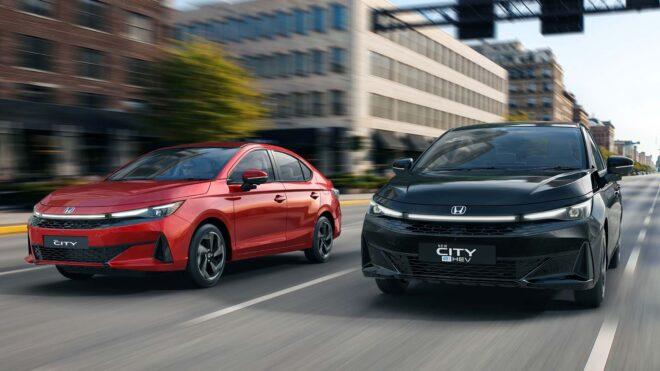
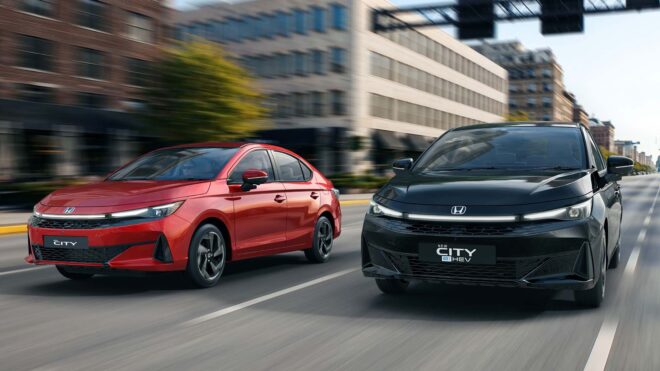 Bir ara Türkiye’de de satılan ancak Honda Türkiye’nin güncel fiyat listesinde yer almayan Honda City, yeni sürümüyle Hindistan’da görücüye çıkarıldı. Genel çizgisini koruyan model, modern çok sayıda araçta da yer alan şerit LED’in kullanıldığı ön yüzüyle fark yaratıyor. Arkasında ufak bir rüzgarlık ve şeffaf yapılı stopların dikkat çektiği makyajlı City, yeni tasarlanan 16 inç jantlarla geliyor. Konsolunu dışa doğru çıkıntılı tasarlanan 10,1 inç boyutundaki ekranın domine ettiği araç, çok sayıda fiziksel buton taşıyor. Kablosuz Android Auto ve Apple CarPlay destekleri olan aracın, Hindistan’da 121 beygir güç ve 145 Nm tork üreten 1.5 litrelik dört silindirli benzinli ya da 126 beygir güç ve 253 Nm tork üreten 1.5 litrelik hibrit motor seçenekleriyle tercih edilebileceği aktarılıyor. Benzinli motorun 6 vitesli manuel ya da 7 vitesli CVT ile sunulduğu, hibrit motorda ise e-CVT’ye yer verildiği belirtiliyor.
Makyajlı Honda City, Hindistan’da görücüye çıkarıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.