Yeni Freelander SUV önümüzdeki hafta tanıtılacak
 Chery ve Jaguar Land Rover iş birliğinde marka olarak hayata dönen Freelander, ilk etapta Çin’de ve ardından küresel pazarda boy gösteren bir SUV markası olacak.
 Chery ve Jaguar Land Rover iş birliğinde marka olarak hayata dönen Freelander, ilk etapta Çin’de ve ardından küresel pazarda boy gösteren bir SUV markası olacak.
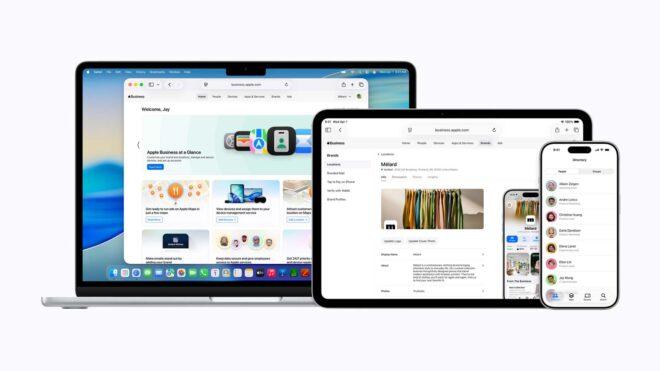
 Apple bugün şirketlerin aygıtlarını zahmetsizce yönetmek, ekip üyelerini gerekli uygulama ve araçlarla donatmak ve uzmanlardan destek almak için ihtiyaç duydukları tüm temel hizmetleri içeren, hepsi bir arada bir platform olan yeni Apple Business’ı duyurdu. Platform hakkında yapılan resmi açıklamada, “Business sayesinde şirketler işlerini verimli ve güvenli şekilde yürütüp büyütebilecek. Apple Business, yerleşik mobil aygıt yönetimi sayesinde işletmelere çalışan gruplarını, aygıt ayarlarını, güvenliği ve uygulamaları kolayca yapılandırma konularında yardımcı olacak ve Blueprint’lerle işe hızlıca koyulmalarını sağlayacak. Buna ek olarak, müşteriler kesintisiz ve gelişmiş iletişim ve iş birliği için artık kendi alan adlarıyla iş mail’i, takvim ve dizin hizmetlerini yapılandırabilecek. Üstelik Apple Business, milyonlarca şirketin Apple Harita, Mail, Cüzdan ve Siri gibi birçok uygulama üzerinden daha geniş kitlelere ulaşmasına ve yerel müşterilerle bağlantı kurmasına da yardımcı olacak. Apple Business, 14 Nisan Salı günü itibarıyla 200’den fazla ülkede ve bölgede kullanıma sunulacak” ifadelerine yer verildi. “Farklı büyüklükteki şirketlerin Apple ürün ve hizmetlerinin gücünden yararlanarak […]
Apple Business platformu tanıtıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Every application has secrets: API keys, database credentials, OAuth tokens, encryption keys. How you manage them determines whether those secrets stay secret — and whether your team can actually work with them without emailing each other .env files.
This guide covers the real options in 2025, from basic .env files to production-grade secrets managers.
The Core Problem
Environment variable management has three distinct challenges:
Most teams solve #1 poorly, #2 not at all, and #3 acceptably. This guide covers doing all three well.
The Bad Practice (That Everyone Uses)
The .env file committed to git.
Don’t do this. Secrets in git history are compromised secrets, even if you delete the file later. If your repo is ever public, ever leaked, or ever shared with a contractor — those secrets are exposed forever.
What people do instead (but shouldn’t):
.env files to new team membersAll of these fail in different ways. Here’s how to actually do it.
Option 1: Basic .env With dotenv (Fine for Solo Projects)
The dotenv package loads a .env file into process.env at runtime. It’s simple and universally understood.
Setup:
npm install dotenv
// At the top of your entry file
require('dotenv').config()

// Or with ES modules
import 'dotenv/config'
# .env (NEVER commit this)
DATABASE_URL=postgresql://user:pass@localhost:5432/myapp
API_KEY=sk-abc123
REDIS_URL=redis://localhost:6379

# .env.example (DO commit this)
DATABASE_URL=postgresql://user:pass@localhost:5432/myapp
API_KEY=your-api-key-here
REDIS_URL=redis://localhost:6379
Rules:
.env in .gitignore — always.env.example committed with placeholder values — always.env.example to .env and fill in real valuesLimitations:
Best for: Solo projects, learning, prototypes.
Option 2: dotenvx — Encrypted .env Files
dotenvx is an open-source tool from the creator of the original dotenv. It adds encryption to .env files so you can actually commit them safely.
How it works:
# Install
npm install -g @dotenvx/dotenvx

# Encrypt your .env file
dotenvx encrypt

# .env is now encrypted — safe to commit
# .env.keys contains your private key — DO NOT COMMIT THIS
Your .env file becomes:
#/-------------------[DOTENV_PUBLIC_KEY]--------------------/
#/            public-key encryption for .env files          /
#/       [how it works](https://dotenvx.com/encryption)     /
#/----------------------------------------------------------/
DOTENV_PUBLIC_KEY="025a54c5d04b..."

# .env
DATABASE_URL="encrypted:BGYE53..."
API_KEY="encrypted:BH8f2..."
The encrypted .env can be committed. The .env.keys file (private key) goes in .gitignore and is shared through a separate, secure channel.
Running your app:
# Development (using .env.keys)
dotenvx run -- node server.js

# Production (inject DOTENV_PRIVATE_KEY as env var)
DOTENV_PRIVATE_KEY="your-key" dotenvx run -- node server.js
Why this is good:
Limitations:
Best for: Small teams that want encryption without a full secrets service.
Option 3: Infisical — Open-Source Secrets Manager
Infisical is the most popular open-source secrets management platform. It offers a Vault-like experience with a developer-friendly interface, and you can self-host or use their cloud.
Key features:
CLI usage:
# Install
brew install infisical/get-infisical/infisical

# Login
infisical login

# Initialize project
infisical init

# Run with secrets injected
infisical run -- npm run dev

# Pull secrets to a .env file (for tools that need it)
infisical export --format dotenv > .env
SDK usage (Node.js):
npm install @infisical/sdk
import { InfisicalClient } from "@infisical/sdk"

const client = new InfisicalClient({
  clientId: process.env.INFISICAL_CLIENT_ID,
  clientSecret: process.env.INFISICAL_CLIENT_SECRET,
})

const { secretValue } = await client.getSecret({
  secretName: "DATABASE_URL",
  projectId: "your-project-id",
  environment: "production",
})
Pricing:
Best for: Teams that want open-source but need a full secrets management platform.
Option 4: Doppler — Commercial Secrets Manager with Great DX
Doppler is a commercial secrets management platform focused on developer experience. It’s particularly popular with teams using Vercel, Railway, or similar platforms.
Key features:
CLI usage:
# Install
brew install dopplerhq/cli/doppler

# Login
doppler login

# Configure project
doppler setup

# Run with secrets
doppler run -- npm run dev

# Pull to .env
doppler secrets download --no-file --format env > .env
Vercel integration:
# Sync Doppler secrets to Vercel
doppler secrets download --no-file --format env |
  vercel env add --environment production
Or use the native Vercel ↔ Doppler integration that auto-syncs.
Pricing:
Best for: Small-to-medium teams that want polished tooling and native integration with deployment platforms.
Option 5: AWS Secrets Manager / GCP Secret Manager / Azure Key Vault
For teams already on a cloud provider, using their native secrets service is often the right choice — especially for production workloads.
AWS Secrets Manager:
import { SecretsManagerClient, GetSecretValueCommand } from "@aws-sdk/client-secrets-manager"

const client = new SecretsManagerClient({ region: "us-east-1" })

const response = await client.send(
  new GetSecretValueCommand({ SecretId: "myapp/production/database" })
)

const { DATABASE_URL } = JSON.parse(response.SecretString)
Pros:
Cons:
Best for: Teams with significant AWS workloads that want secrets close to their infrastructure.
Recommended Setup by Team Size
Solo developer / small project
dotenv for local development.env.example committed to repo Small team (2-10 people)
Medium team (10-50 people)
Enterprise / cloud-native
Best Practices Regardless of Tool
Never commit secrets to git. Check your .gitignore includes .env, .env.local, .env.*.local, *.pem, *.key.
Separate by environment. Development secrets should never have production access. Different services, different credentials.
Rotate after exposure. Any secret that was exposed (leaked repo, terminated employee, tool breach) must be rotated immediately — not “eventually.”
Principle of least privilege. Each service should only have access to the secrets it needs. Your API server doesn’t need your database admin credentials.
Audit access. Know who can see which secrets. This matters for both security and compliance.
Don’t log secrets. Audit your logging for accidental secret exposure. Environment variables are particularly easy to accidentally log in error messages.
Quick Comparison
| Tool | Self-hosted | Sync | UI | CI Integration | Cost |
|---|---|---|---|---|---|
| dotenv | Yes | No | No | Manual | Free |
| dotenvx | Yes | Via git | No | Good | Free |
| Infisical | Yes/Cloud | Yes | Yes | Excellent | Free/Paid |
| Doppler | Cloud | Yes | Yes | Excellent | Free tier |
| AWS Secrets Manager | AWS | Yes | AWS Console | Good | ~$0.40/secret/month |
More free tools for developers at DevPlaybook.cc — including JSON Formatter, Base64 Encoder, and 15+ utilities for daily development work.
Level Up Your Dev Workflow
Found this useful? Explore DevPlaybook — cheat sheets, tool comparisons, and hands-on guides for modern developers.
🛒 Get the DevToolkit Starter Kit on Gumroad — 40+ browser-based dev tools, source code + deployment guide included.
Best Free Code Formatters and Linters 2025: The Complete Guide
Code formatting is one of those things teams argue about endlessly until they stop arguing about it entirely — because a formatter has taken the decision off the table. Linting is what catches the bugs that a formatter can’t see. Together, they’re the lowest-effort, highest-ROI investment in code quality a team can make.
This guide covers the best free tools in 2025 across languages, how to configure them, how to integrate them into VS Code and CI, and how to share configs across a team.
Why Formatting and Linting Matter
Formatting is about consistency: tabs vs. spaces, single vs. double quotes, trailing commas, line length. None of these choices matter — what matters is that the whole codebase makes the same choice consistently. When every developer’s editor formats code differently, every pull request has noise from formatting changes mixed in with actual logic changes.
Linting goes further: it catches potential bugs, enforces best practices, and flags patterns that are technically valid but commonly lead to mistakes. A linter won’t catch every bug, but it catches the ones that are always wrong — and it does it in milliseconds.
The compounding benefits:
The question isn’t whether to use formatters and linters. The question is which ones.
Prettier: The Opinionated Formatter
Prettier is the dominant code formatter for JavaScript, TypeScript, CSS, HTML, JSON, Markdown, and more. Its defining characteristic is that it’s opinionated — it has minimal configuration, and it overrides your choices with its own. This is a feature, not a bug. The whole point is to end formatting debates by removing the decision entirely.
Installation
npm install --save-dev prettier
Basic Config
Create .prettierrc in your project root:
{
  "semi": true,
  "singleQuote": true,
  "tabWidth": 2,
  "trailingComma": "es5",
  "printWidth": 100,
  "arrowParens": "avoid"
}
Create .prettierignore:
node_modules
dist
build
coverage
*.min.js
Running Prettier
# Check files without modifying (useful for CI)
npx prettier --check .

# Format all files in place
npx prettier --write .

# Format a specific file
npx prettier --write src/app.js
VS Code Integration
Install the Prettier – Code formatter extension (esbenp.prettier-vscode). Then add to your VS Code settings (settings.json):
{
  "editor.defaultFormatter": "esbenp.prettier-vscode",
  "editor.formatOnSave": true,
  "[javascript]": {
    "editor.defaultFormatter": "esbenp.prettier-vscode"
  },
  "[typescript]": {
    "editor.defaultFormatter": "esbenp.prettier-vscode"
  }
}
With formatOnSave: true, every file is formatted the moment you hit save. No manual formatting steps.
ESLint: Catching Bugs Before Runtime
ESLint is the linting standard for JavaScript and TypeScript. Unlike Prettier, it’s not opinionated — it’s highly configurable. You choose which rules to enable, what severity level to apply, and which plugins to use.
Installation and Setup
npm install --save-dev eslint
npx eslint --init
The --init wizard walks you through setup and creates your config. For TypeScript support:
npm install --save-dev @typescript-eslint/parser @typescript-eslint/eslint-plugin
Modern Flat Config (ESLint v9+)
ESLint v9 introduced a new “flat config” format using eslint.config.js (replacing .eslintrc). The new format is cleaner and more explicit:
// eslint.config.js
import js from '@eslint/js';
import tseslint from 'typescript-eslint';

export default [
  js.configs.recommended,
  ...tseslint.configs.recommended,
  {
    rules: {
      'no-unused-vars': 'warn',
      'no-console': 'warn',
      'prefer-const': 'error',
      'no-var': 'error',
      '@typescript-eslint/no-explicit-any': 'warn',
    }
  }
];
Severity Levels
"error" — fails the lint check, blocks CI"warn" — shows a warning but doesn’t fail"off" — disables the rule Key Plugins Worth Installing
| Plugin | Purpose |
|---|---|
eslint-plugin-react |
React-specific rules |
eslint-plugin-react-hooks |
Rules of Hooks enforcement |
eslint-plugin-jsx-a11y |
Accessibility rules for JSX |
eslint-plugin-import |
Import/export validation |
eslint-plugin-security |
Catches common security patterns |
eslint-plugin-unicorn |
Enforces modern JavaScript best practices |
Integrating ESLint with Prettier
ESLint and Prettier can conflict — both may have opinions about the same code. The solution is eslint-config-prettier, which disables all ESLint rules that might conflict with Prettier:
npm install --save-dev eslint-config-prettier
Add "prettier" as the last item in your extends array:
// eslint.config.js
import prettier from 'eslint-config-prettier';

export default [
  js.configs.recommended,
  ...tseslint.configs.recommended,
  prettier,  // Must be last — disables conflicting rules
  {
    rules: {
      // Your custom rules here (non-formatting only)
    }
  }
];
Rule of thumb: Prettier handles formatting, ESLint handles code quality. Don’t overlap.
Biome: The All-in-One Newcomer
Biome is the new challenger that combines formatting and linting into a single tool. It’s written in Rust, which makes it dramatically faster than both Prettier and ESLint. For large codebases, this matters.
Why Biome Is Worth Watching
biome.json replaces .prettierrc + .eslintrc
Installation
npm install --save-dev --save-exact @biomejs/biome
npx biome init
Configuration (biome.json)
{
  "$schema": "https://biomejs.dev/schemas/1.6.0/schema.json",
  "organizeImports": {
    "enabled": true
  },
  "linter": {
    "enabled": true,
    "rules": {
      "recommended": true,
      "suspicious": {
        "noExplicitAny": "warn"
      }
    }
  },
  "formatter": {
    "enabled": true,
    "indentStyle": "space",
    "indentWidth": 2,
    "lineWidth": 100
  },
  "javascript": {
    "formatter": {
      "quoteStyle": "single",
      "trailingCommas": "es5",
      "semicolons": "always"
    }
  }
}
Running Biome
npx biome check .          # Lint + format check (no writes)
npx biome check --apply .  # Lint + format and apply safe fixes
npx biome format --write . # Format only, apply writes
When to use Biome vs. Prettier + ESLint:
Biome doesn’t yet have the full plugin ecosystem of ESLint, but it covers the most important rules out of the box.
Language-Specific Tools
Python: Black + Ruff
Black is Python’s answer to Prettier — opinionated, fast, and uncompromising. It formats your Python code with almost no configuration.
pip install black
black .                    # Format all Python files
black --check .            # Check without modifying (CI)
black --diff .             # Show what would change
Black’s only meaningful config option is line length (default 88):
# pyproject.toml
[tool.black]
line-length = 88
target-version = ['py311']
Ruff is the linter equivalent — extremely fast (written in Rust), replaces Flake8, isort, and many other Python tools:
pip install ruff
ruff check .
ruff check --fix .
# pyproject.toml
[tool.ruff]
line-length = 88
select = ["E", "F", "I", "N", "UP"]
ignore = ["E501"]
Go: gofmt and golangci-lint
Go ships with gofmt built in — no installation required, no configuration. Run it and your code is formatted to the Go standard. There is no debate about Go formatting.
gofmt -w .                 # Format all .go files in place
gofmt -d .                 # Show diff without modifying
For linting, golangci-lint aggregates many Go linters into one fast runner:
go install github.com/golangci/golangci-lint/cmd/golangci-lint@latest
golangci-lint run
Rust: rustfmt and Clippy
Rust ships with both formatters and linters as part of the official toolchain:
rustup component add rustfmt clippy

cargo fmt              # Format all Rust code
cargo fmt --check      # Check only (CI)
cargo clippy           # Run the Clippy linter
cargo clippy -- -D warnings   # Treat warnings as errors (strict CI)
rustfmt is configured via rustfmt.toml:
max_width = 100
edition = "2021"
imports_granularity = "Module"
CI Integration
Pre-Commit Hooks
pre-commit runs checks before every git commit. If a check fails, the commit is blocked.
pip install pre-commit
Create .pre-commit-config.yaml:
repos:
  - repo: https://github.com/pre-commit/pre-commit-hooks
    rev: v4.5.0
    hooks:
      - id: trailing-whitespace
      - id: end-of-file-fixer
      - id: check-merge-conflict

  - repo: https://github.com/psf/black
    rev: 24.3.0
    hooks:
      - id: black

  - repo: https://github.com/astral-sh/ruff-pre-commit
    rev: v0.3.0
    hooks:
      - id: ruff
        args: [--fix]

  - repo: https://github.com/biomejs/pre-commit
    rev: v0.1.0
    hooks:
      - id: biome-check
        additional_dependencies: ["@biomejs/[email protected]"]
pre-commit install          # Install hooks (run once per repo)
pre-commit run --all-files  # Run manually on all files
GitHub Actions
# .github/workflows/lint.yml
name: Lint and Format Check

on: [push, pull_request]

jobs:
  lint:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4

      - name: Set up Node.js
        uses: actions/setup-node@v4
        with:
          node-version: '20'
          cache: 'npm'

      - name: Install dependencies
        run: npm ci

      - name: Check formatting (Prettier)
        run: npx prettier --check .

      - name: Lint (ESLint)
        run: npx eslint . --max-warnings 0

  lint-python:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with:
          python-version: '3.11'

      - name: Install tools
        run: pip install black ruff

      - name: Check formatting (Black)
        run: black --check .

      - name: Lint (Ruff)
        run: ruff check .
Online Formatters
Sometimes you just need to quickly format a snippet without setting up a local tool. DevPlaybook provides free browser-based formatters at devplaybook.cc:
These tools are useful for one-off formatting tasks, validating API responses, or quickly cleaning up a snippet before pasting it into documentation.
Team Setup Guide: Sharing Configs
The Problem
Individual developers can have formatters installed, but if everyone’s config differs, the formatting still varies. The solution: commit your config files to the repository so everyone uses the same settings.
Files to Commit
.prettierrc             # Prettier config
.prettierignore         # Prettier exclusions
eslint.config.js        # ESLint config
biome.json              # Biome config (if using Biome)
.editorconfig           # Universal editor settings
.pre-commit-config.yaml # Pre-commit hooks
.editorconfig
.editorconfig is supported by almost every editor natively and defines basic formatting rules across all languages:
root = true

[*]
charset = utf-8
end_of_line = lf
insert_final_newline = true
trim_trailing_whitespace = true
indent_style = space
indent_size = 2

[*.py]
indent_size = 4

[Makefile]
indent_style = tab
VS Code Workspace Settings
Add a .vscode/settings.json file to the repository:
{
  "editor.formatOnSave": true,
  "editor.codeActionsOnSave": {
    "source.fixAll.eslint": "explicit"
  },
  "editor.defaultFormatter": "esbenp.prettier-vscode",
  "eslint.validate": ["javascript", "typescript", "jsx", "tsx"]
}
And recommend extensions via .vscode/extensions.json:
{
  "recommendations": [
    "esbenp.prettier-vscode",
    "dbaeumer.vscode-eslint",
    "biomejs.biome"
  ]
}
When a developer opens the project, VS Code prompts them to install the recommended extensions. Combined with committed config files, this means any developer who clones the repo is fully set up in minutes.
npm Scripts
Add standard lint/format scripts to package.json:
{
  "scripts": {
    "lint": "eslint . --max-warnings 0",
    "lint:fix": "eslint . --fix",
    "format": "prettier --write .",
    "format:check": "prettier --check .",
    "check": "npm run format:check && npm run lint"
  }
}
The check script runs both format and lint checks — useful in CI pipelines.
Choosing Your Stack in 2025
| Scenario | Recommended Stack |
|---|---|
| New JS/TS project | Biome (all-in-one, fast) |
| Existing JS/TS project | Prettier + ESLint |
| Python project | Black + Ruff |
| Go project | gofmt + golangci-lint |
| Rust project | rustfmt + Clippy |
| Multi-language monorepo | pre-commit with per-language tools |
The most important thing isn’t which tool you pick — it’s that you automate it. A formatter you have to run manually is a formatter you’ll forget to run. Hook it into your editor save action and your CI pipeline, and code quality becomes a property of the system, not a personal discipline.
Level Up Your Dev Workflow
Found this useful? Explore DevPlaybook — cheat sheets, tool comparisons, and hands-on guides for modern developers.
🛒 Get the DevToolkit Starter Kit on Gumroad — 40+ browser-based dev tools, source code + deployment guide included.

Hey everyone! Honestly, it feels so good to be sitting down and writing to you all again. I want to start with a massive apology for the radio silence and the long gap between my last few posts. Life has a funny way of getting busy, but I’ve missed this community and our deep dives into the future of tech.
We’re talking about a problem that has been bugging me all through 2025 and into 2026: AI situational awareness. Let’s dive in.
The “Goldfish” Problem: Why Your AI is Gaslighting Your Users 🐠🌀
Look, we need to have a genuine heart-to-heart about your AI agents. We’re well into 2026, and yet, most AI “agents” still have the situational awareness of a goldfish in a blender. It’s a bit heartbreaking, isn’t it?
You know the feeling: You’ve spent weeks perfecting your system prompts, the UI is looking like a work of art, and your LLM is sharp. But the second a user actually does something—like upgrading a subscription, changing a delivery address, or updating their profile—the AI is the absolute last one to know. It’s like the “memory” of your agent is stuck in a permanent time lag, trapped in a 2024 batch-processing nightmare.
Imagine you’re building the ultimate AI concierge for a luxury travel app.
Sarah is now officially being gaslit by an algorithm. 🤦♂️ The immersion? Totally gone. The trust? Shattered. This happens because the “Transactional Brain” (Aurora) isn’t talking to the “Analytical Memory” (Redshift) fast enough. We need a way to move that data so quickly it feels like magic. Today, we are fixing that with Live Memory using Amazon Aurora Zero-ETL and Redshift Vector Search.
Step 1: The “Wormhole” (Zero-ETL) 🚀
In the “old days” (way back in 2024), moving data from Aurora to Redshift meant building a “Glue” pipeline. It was like trying to build a bridge between two islands using nothing but popsicle sticks, duct tape, and a whole lot of hope. It broke constantly, it cost a fortune, and it was painfully slow.
Zero-ETL is the modern way to handle this. Think of it as a native “wormhole” between Aurora and Redshift. When you enable it, AWS handles all the heavy lifting and plumbing behind the scenes. No Python scripts to debug, no Lambda triggers to monitor, and absolutely zero drama.

Why this is the “Secret Sauce” for your Agent:
Step 2: From “Rows” to “Recall” (Vector Search) 🧠
Okay, so the data has successfully teleported into Redshift. But here’s the catch: Redshift is a warehouse full of structured tables, and AI Agents don’t really “think” in tables—they think in Vectors (mathematical representations of meaning).
In the past, you’d have to ship this data again to a dedicated vector database. But that just adds more lag! Instead, we use Redshift’s Native Vector Search. This keeps your “Live Memory” in one single, high-performance place. To make this work, we set up a Materialized View in Redshift that automatically calls Amazon Bedrock to turn those new rows into vectors on the fly.
-- The "I don't have a goldfish memory anymore" Query
CREATE MATERIALIZED VIEW live_user_context AS
SELECT
    user_id,
    event_description,
    -- This calls Bedrock to create a vector on the fly!
    amazon_bedrock_embed(event_description) as semantic_vector
FROM aurora_synced_data.user_logs;
Step 3: The “Aha!” Moment 🔍
Now, let’s replay the Sarah scenario. When she asks about her flight, the AI Agent sends a vector query to Redshift. Redshift looks at the most recent events—including the one that landed just 10 seconds ago—and finds the “Canceled Paris / Booked Rome” entry.
The Agent responds: “I see you switched to the Rome trip—great choice! That flight leaves at 8 PM. Should I book a car to the airport?”
Boom. You just saved the user experience. 🥳 You’ve moved from a “chatbot” to a genuine “agent” that understands the present moment.
By The Numbers: Is it worth your time? 📈
We ran some benchmarks to see just how much of a difference this “Live Memory” architecture actually makes. When you compare the old “Batch” world to the new “Zero-ETL” world, the latency gap is massive.

Developer Happiness:
Pro-Tips for the Modern ML Engineer 🛠️
WHERE user_id = '123') to make your search lightning fast. Final Thoughts
Anyway, it feels amazing to be back in the flow and sharing these breakthroughs with you all again. The leap from “static” AI to “live” agents is one of the most exciting shifts we’re seeing this year, and I can’t wait to see how you all implement these “wormholes” in your own stacks. If you run into any snags or just want to geek out over vector search optimizations, drop a comment below or find me over on Dev.to! I promise the next article won’t take nearly as long to reach your screens. Until next time — stay curious, keep building, and let’s make those agents a whole lot smarter. 🚀✨
Best Cron Job Generators and Testers (Free, 2026) — Compared
Cron is 50 years old and still running production workloads at companies of every size. Daily database backups, weekly report emails, hourly cache invalidations, nightly ML training jobs — cron (or a cron-like scheduler) handles an enormous fraction of the world’s scheduled computing.
The syntax is terse enough that even experienced developers reach for a cron expression generator when they need something beyond “run every hour.” The */5 * * * * pattern is memorable. The “every weekday at 9am EST only during business days” pattern is not.
We tested 7 free cron tools — generators, validators, and testers — to find which ones are actually useful for production work.
Understanding Cron Syntax First
A cron expression has 5 (or 6, in extended formats) fields:
* * * * *
│ │ │ │ │
│ │ │ │ └─── Day of week (0-7, where 0 and 7 = Sunday)
│ │ │ └───── Month (1-12)
│ │ └─────── Day of month (1-31)
│ └───────── Hour (0-23)
└─────────── Minute (0-59)
Some schedulers (like Quartz, AWS EventBridge, and Spring) use a 6-field format that adds a seconds field at the start:
* * * * * *
│ │ │ │ │ │
│ │ │ │ │ └─── Day of week
│ │ │ │ └───── Month
│ │ │ └─────── Day of month
│ │ └───────── Hour
│ └─────────── Minute
└─────────── Second (0-59)
Know which format your scheduler expects before you write or paste a cron expression. Mixing them up is the #1 source of cron misconfiguration.
Special syntax:
* — every value*/n — every n values (e.g., */15 = every 15 minutes)n-m — range (e.g., 9-17 = hours 9 through 17)n,m — list (e.g., 1,3,5 = Monday, Wednesday, Friday)@hourly, @daily, @weekly, @monthly, @yearly — shorthand aliases The 7 Tools We Tested
1. DevPlaybook Cron Generator
URL: devplaybook.cc/tools/cron-generator
DevPlaybook’s Cron Generator is built for the workflow where you know what you want to schedule in plain English and need the cron expression.
What it does well:
The plain-English input approach is effective. Describe your schedule (“every weekday at 9:30am”), get the cron expression. This is faster than remembering field order for simple schedules, and it avoids the common mistake of putting the minute and hour fields in the wrong order.
The “next run times” preview shows the next 5 scheduled executions with actual timestamps (including your local timezone). This catches the most common production bug: scheduling something for “every hour” and only realizing after deployment that it’s running at :00 of every hour GMT, not your local timezone.
The generated expression is accompanied by a plain-English description (“At 9:30 AM, Monday through Friday”) so you can double-check that the expression matches your intent before copying it.
What could be better:
Doesn’t support 6-field (Quartz/Spring/AWS) expressions yet.
No syntax for “last day of the month” or other extended cron features used by some schedulers.
Best for: Developers who know the schedule they want but aren’t fluent in cron syntax. The next-run preview is the most valuable feature for avoiding timezone mistakes.
2. DevPlaybook Cron Validator
URL: devplaybook.cc/tools/cron-validator
The Cron Validator does the opposite of the Generator: you paste an existing cron expression and it tells you whether it’s valid and what it means.
What it does well:
Immediately tells you if an expression is valid and why it’s invalid if not. Error messages are specific: “day of week value 8 is out of range (0-7)” is more useful than “invalid expression.”
The description output is clear: 0 2 * * 1 becomes “At 02:00 AM, only on Monday.” This is invaluable for reviewing cron jobs in code review or documentation.
Shows the next 10 scheduled run times. Ten is the right number — it’s enough to confirm the pattern (not just the first occurrence) without being overwhelming.
Best for: Reviewing cron expressions in existing code, validating before deployment, code review.
3. DevPlaybook Cron Builder
URL: devplaybook.cc/tools/cron-builder
The Cron Builder is a visual interface for constructing cron expressions field by field.
What it does well:
Dropdown menus for each field with valid value ranges. You can’t enter an invalid value because the inputs constrain the options. This is useful for developers new to cron syntax who want to learn by building.
The live preview updates as you adjust each field, showing both the expression and a description. Watching how the expression changes as you select “every Tuesday” vs “every Tuesday and Thursday” teaches the syntax faster than reading documentation.
Supports multiple selection for lists (comma-separated) and range selection, which the UI makes significantly more discoverable than raw syntax.
Best for: Learning cron syntax, building expressions with complex field combinations (multiple days, multiple hours).
4. Crontab.guru
URL: crontab.guru
Crontab.guru is the most widely used cron expression explainer. When developers search for “cron expression checker,” this is typically what they find and use.
What it does well:
The “random” feature teaches cron syntax by showing you valid expressions and explaining them. Spend 5 minutes clicking Random and you’ll have a working understanding of the syntax.
The explanation is clean and in a single line: * * * * * → “At every minute.” Clear, unambiguous.
The interface is deliberately minimal — just an input field and the explanation. This is intentional and works well for quick checks.
URL state: the expression is in the URL, so you can bookmark or share a specific expression.
What could be better:
No “next run times” preview. You can see what the expression means but not when it will actually fire.
No validation of the expression against a specific timezone.
No 6-field support.
Best for: Quick expression checking, learning cron syntax, sharing expressions via URL.
5. CronMaker
URL: cronmaker.com
CronMaker supports both 5-field and 6-field (Quartz) cron expressions, which makes it uniquely useful for Java Spring and AWS developers.
What it does well:
The Quartz scheduler support is the reason to use CronMaker. Spring Boot jobs, Quartz schedulers, and AWS EventBridge (CloudWatch Events) use different syntax than standard Unix cron. CronMaker handles all of these.
The expression builder supports Quartz-specific features: L for “last” (last day of month, last Friday of month), W for “nearest weekday,” and # for “nth day of week” (e.g., 2#3 = second Tuesday of the month).
The next-run preview includes 10 scheduled times.
What could be better:
The UI is dated. The layout is functional but clearly hasn’t been updated in years. For a utility tool this might not matter, but it does affect readability.
Best for: Spring Boot, Quartz Scheduler, AWS EventBridge — any context where you need 6-field cron or Quartz-specific syntax.
6. FreeFormatter Cron Validator
URL: freeformatter.com/cron-expression-generator-quartz.html
FreeFormatter’s cron tool focuses on Quartz cron validation.
What it does well:
Handles Quartz syntax. Has a visual field builder for the 6-field format.
What could be better:
Limited additional features. Doesn’t explain what the expression means in plain English. Useful as a validation tool, not a learning tool.
Best for: Quick Quartz expression validation.
7. Cron Expression Descriptor
URL: cronexpressiondescriptor.azurewebsites.net
A tool focused entirely on converting cron expressions to plain English.
What it does well:
Handles complex expressions well, including multi-value fields and ranges. The plain-English output is accurate.
What could be better:
The URL and UX are rough. It’s a port of the open-source CronExpressionDescriptor library.
Best for: Getting a plain-English description of a complex expression when other tools fall short.
Tool Comparison
| Tool | Generator | Validator | Visual Builder | Next Runs | Quartz | Timezone |
|---|---|---|---|---|---|---|
| DevPlaybook Cron Gen | ✅ | ✅ | ❌ | ✅ | ❌ | ✅ |
| DevPlaybook Cron Validator | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ |
| DevPlaybook Cron Builder | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ |
| Crontab.guru | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| CronMaker | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ |
| FreeFormatter | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ |
| Cron Descriptor | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ |
Common Cron Expressions Reference
Every minute
* * * * *
Every 5 minutes
*/5 * * * *
Every hour (at minute :00)
0 * * * *
Every day at midnight
0 0 * * *
Every day at 6am
0 6 * * *
Every weekday at 9am
0 9 * * 1-5
Every Monday at noon
0 12 * * 1
Every first day of the month at midnight
0 0 1 * *
Every 15 minutes, business hours only (9am-5pm, Mon-Fri)
*/15 9-17 * * 1-5
Every Sunday at 3am (good for weekly maintenance)
0 3 * * 0
Quarterly (first day of Jan, Apr, Jul, Oct)
0 0 1 1,4,7,10 *
Every 6 hours
0 */6 * * *
The Timezone Trap (and How to Avoid It)
The #1 production mistake with cron jobs is timezone confusion. Most cron daemons on Linux servers run in UTC. If you schedule 0 9 * * * thinking it runs at 9am local time, it will actually run at 9am UTC — potentially 5-8 hours off depending on your timezone and daylight saving time.
Always verify:
DevPlaybook’s Cron Generator shows next run times in both UTC and your local timezone for this reason.
On Linux, check the system timezone:
timedatectl
# or
cat /etc/timezone
Override cron’s timezone per-user:
# In your crontab (crontab -e)
CRON_TZ=America/New_York
0 9 * * * /path/to/job
For modern cloud infrastructure (AWS Lambda, Google Cloud Run, etc.), the scheduler runs in UTC by default. Always write your expressions in UTC and convert to local time for documentation.
Cron Alternatives Worth Knowing
Traditional cron has limitations: no retry logic, no dependencies between jobs, no distributed execution, limited observability.
For production job scheduling beyond simple periodic tasks:
Airflow — The industry standard for DAG-based workflow scheduling. Overkill for simple jobs, essential for data pipelines with dependencies.
Temporal — Durable execution platform with retry logic, timeouts, and visibility. Good for long-running workflows.
pg_cron — Cron scheduler for PostgreSQL. If your jobs are mostly database operations, running them inside the database reduces network hops and simplifies monitoring.
GitHub Actions with schedule trigger — Good for CI/CD-adjacent jobs: report generation, nightly builds, automated releases.
# GitHub Actions example
on:
  schedule:
    - cron: '0 2 * * *'  # Every day at 2am UTC
Heroku Scheduler — If you’re on Heroku, the scheduler add-on handles cron-like jobs with a simple UI.
For most teams, standard cron (with a tool like Kubernetes CronJobs for containerized workloads) handles 80% of scheduling needs. Save the orchestration platform for when you actually need retry logic, inter-job dependencies, or observability.
Debugging Cron Jobs That Don’t Run
When a cron job doesn’t fire, the debugging order is:
1. Check the crontab is installed
crontab -l          # list current user's crontab
sudo crontab -l     # list root's crontab
2. Check if cron is running
systemctl status cron    # Debian/Ubuntu
systemctl status crond   # RHEL/CentOS
3. Check cron logs
grep CRON /var/log/syslog            # Ubuntu/Debian
grep CRON /var/log/cron              # RHEL/CentOS
journalctl -u cron --since "1 hour ago"
4. Validate the expression
Paste it into DevPlaybook Cron Validator and confirm it’s valid and scheduled when you expect.
5. Check the script runs manually
/bin/bash -c "/path/to/your/script.sh"
Cron runs with a minimal environment. If the script works manually but not in cron, the issue is usually a missing PATH, missing environment variables, or a relative path.
6. Check file permissions
ls -la /path/to/your/script.sh
The script must be executable by the user the cron job runs as.
Our Recommendations
Quickest cron expression lookup: Crontab.guru — fast, reliable, zero friction.
Best for building new expressions: DevPlaybook Cron Generator — plain-English input with timezone-aware next-run preview.
Best for validating existing expressions: DevPlaybook Cron Validator — 10 next-run times with clear error messages.
Best for learning cron syntax: DevPlaybook Cron Builder — visual field-by-field construction teaches the syntax as you use it.
Best for Spring/Quartz/AWS: CronMaker — the only free tool with proper Quartz expression support.
For most developers, the workflow is: use DevPlaybook Cron Generator to build the expression, use DevPlaybook Cron Validator to verify it before deploying, and use Crontab.guru for quick “what does this mean” lookups when reviewing code.
Level Up Your Dev Workflow
Found this useful? Explore DevPlaybook — cheat sheets, tool comparisons, and hands-on guides for modern developers.
🛒 Get the DevToolkit Starter Kit on Gumroad — 40+ browser-based dev tools, source code + deployment guide included.
Your portfolio is the one asset entirely under your control when job hunting. A resume gets 6 seconds. A portfolio gets clicked, explored, and remembered. This guide breaks down what great developer portfolios look like in 2025, the tools that built them, and the patterns worth stealing.
What Hiring Managers Actually Look For
Before diving into examples, understand the audience. Hiring managers and technical leads look for three signals in a portfolio:
The best portfolios answer these questions within 30 seconds of landing on them.
Structure of a High-Signal Portfolio
Every strong developer portfolio follows a similar structure, regardless of design aesthetic:
The mistake most developers make is reversing the priority — leading with skills lists and burying the actual projects.
Portfolio Examples by Type
The GitHub Profile as Portfolio
Many developers underestimate how much signal a well-maintained GitHub profile sends. Your pinned repositories, README profile, and contribution graph are the first stop for technical hiring managers.
What high-signal GitHub profiles have:
username/username repo with a README.md that auto-displays on your profile. Use it to introduce yourself, link to work, show live stats.
# Hi, I'm Alex
Full-stack developer focused on TypeScript, React, and distributed systems.
- Currently building [ProjectName](link)
- Writing about systems design at [blog link]
- Open to senior engineering roles
[](link)
Tools used:
The Minimal Personal Site
Clean, fast, and focused. This style works best for developers who want to let the work speak.
Key characteristics:
Tech stack commonly used:
What makes it work:
The constraint of “minimal” forces clarity. Every element on the page has to earn its spot. Minimal portfolios rarely feel dated because there’s nothing trendy to go stale.
The Technical Blog + Portfolio Hybrid
Developers who write attract inbound opportunities. A portfolio that includes genuine technical writing demonstrates communication ability — the skill that separates senior from staff engineers.
What this looks like:
Content that performs well:
Tools:
The Full-Stack Project Showcase
For mid-to-senior developers, the portfolio is less about aesthetics and more about demonstrated engineering judgment. One well-documented full-stack project beats ten todo apps.
What a strong project showcase includes:
Example project structure in a README:
## Architecture

[Simple diagram or description]

## Key Technical Decisions

**Auth:** JWTs over sessions — stateless works better for the mobile client use case.

**Database:** PostgreSQL with row-level security for multi-tenant data isolation.

**Caching:** Redis for session store + API response caching, cut p99 latency from 800ms to 120ms.

## What I'd Change

The event-driven parts worked well. The synchronous job processing was a mistake
at scale — I'd use a proper queue (BullMQ or SQS) next time.
The Projects That Actually Get Noticed
After reviewing what gets attention in 2025, patterns emerge. Here are the project types that consistently stand out:
Developer Tools
Build something other developers use. This works because:
Examples: a CLI utility, a VS Code extension, a useful npm package, an API testing helper.
Automation Projects
Show that you solve real business problems with code. A script that automated a tedious workflow, a data pipeline that replaced manual work, a Discord bot that actually gets used.
Technical Migrations
Documenting a migration — “I moved this app from CRA to Vite” or “We migrated from REST to GraphQL” — shows real-world engineering judgment that tutorial projects never can.
Open Source Contributions
Even small PRs to established projects demonstrate you can navigate unfamiliar codebases and collaborate with distributed teams. List your significant contributions, not just “fixed typo.”
Common Portfolio Mistakes to Avoid
Too many projects, none impressive — 15 tutorial-style projects is worse than 3 real ones. Edit ruthlessly.
No live demos — If the project isn’t deployed, many reviewers won’t look at it. Use Vercel, Railway, or Render for free hosting.
Private repos only — If hiring managers can’t see your code, your GitHub is invisible. Make project repos public.
Skills section as a buzzword list — Listing 40 technologies makes none of them credible. List what you actually use daily and can discuss deeply.
No mobile optimization — Portfolios get checked on phones. If yours breaks on mobile, that’s a signal about your attention to detail.
Tooling Checklist for Your Portfolio
When setting up your portfolio site:
# Performance check
npx lighthouse https://yourportfolio.com --view

# Check your site's meta tags (important for LinkedIn sharing)
# Open Graph image, title, description should all be set

# Verify your GitHub profile README renders correctly
# Test on both light and dark GitHub themes
Analytics: Add Plausible or a lightweight pixel to see how people navigate your portfolio. It’s useful data for iterating.
Domain: A custom domain (yourname.dev or yourname.com) is worth the $10/year. It signals professionalism and is easy to remember.
The Portfolio Mindset Shift
The developers who build the best portfolios stop thinking of them as “the site I need for job applications” and start thinking of them as “my professional presence on the internet.”
That mindset shift produces something different: a portfolio that’s updated regularly, contains genuine opinions, shows real work in progress, and reads like a person — not a resume in website form.
The best portfolio you can build right now is the one you ship. A live, imperfect portfolio beats a perfect one that’s still in Figma.
Quick Start: What to Build This Week
You don’t need to finish everything before publishing. Launch the minimal version, then improve it. The portfolio that’s live is infinitely more valuable than the one you’re still building.
Level Up Your Dev Workflow
Found this useful? Explore DevPlaybook — cheat sheets, tool comparisons, and hands-on guides for modern developers.
🛒 Get the DevToolkit Starter Kit on Gumroad — 40+ browser-based dev tools, source code + deployment guide included.
Why Most Contact Centers Track the Wrong Metrics
Every contact center has a dashboard. Most of them are useless.
Not because the data is wrong — it’s usually accurate enough. The problem is that most operations track metrics without understanding which ones actually drive outcomes and which ones are just noise. A manager staring at 40 real-time stats is a manager who can’t tell what’s going wrong until it’s already cost them money.
What we’ve seen across hundreds of VICIdial deployments: the centers that outperform track fewer metrics, but they track the right ones, at the right level, at the right frequency. They understand that some KPIs are leading indicators you can act on today and others are lagging indicators that tell you what already happened. They know the difference between an agent-level problem and a campaign-level problem. And they don’t waste time watching numbers that don’t connect to revenue.
Below we cover every KPI that matters for outbound, inbound, and blended contact center operations. For each metric, you’ll get the formula, industry benchmarks, where to find it in VICIdial’s reporting, and — more to the point — what to actually do when the number moves in the wrong direction.
If you already know your CPL inside and out, good. If you don’t, start with our cost per lead benchmarks guide and come back here for the full picture.
The KPI Hierarchy: Leading vs. Lagging Indicators
Before diving into individual metrics, you need a framework for thinking about them. Not all KPIs are created equal, and treating them as a flat list is how you end up micromanaging talk time while your conversion rate craters.
Lagging Indicators (Outcome Metrics)
These tell you what already happened. They’re the scorecard. You can’t directly change them — you change them by moving the leading indicators that feed into them.
Leading Indicators (Operational Metrics)
These are the metrics you can act on right now. When they move, the lagging indicators follow — usually within days or weeks.
The Causal Chain
This is how leading indicators flow into lagging ones for a typical outbound operation:
Dials Per Hour x Contact Rate = Contacts Per Hour
Contacts Per Hour x Conversion Rate = Leads Per Hour
Total Cost / Total Leads = Cost Per Lead
Revenue Per Lead – Cost Per Lead = Profit Per Lead
Every metric in this article connects to this chain somewhere. When a lagging indicator moves in the wrong direction, you trace back through the chain to find the leading indicator that broke. That’s the metric you fix.
Outbound KPIs: Every Metric That Matters
Outbound operations live and die on throughput and conversion. The goal is simple: put agents in front of as many qualified prospects as possible and convert those conversations into outcomes. Every outbound KPI measures some aspect of that equation.
Dials Per Hour (DPH)
Formula: Total Dials / Total Agent Hours
What it measures: Raw dialing throughput — how many calls your dialer is generating per agent per hour.
Benchmarks:
| Dialer Mode | DPH Range | Typical DPH |
|---|---|---|
| Manual / Click-to-Call | 20 – 40 | 30 |
| Preview | 30 – 60 | 45 |
| Progressive | 50 – 90 | 70 |
| Predictive (10+ agents) | 100 – 250 | 180 |
| Predictive (25+ agents, optimized) | 150 – 350 | 220 |
Where to find it in VICIdial: Admin > Reports > Outbound Calling Report. The “Dialable Leads” and “Calls” columns divided by logged-in agent hours give you DPH. Also visible on the Real-Time Report as live dialing velocity. If you want a quick per-agent breakdown outside the GUI, you can query it directly:
SELECT
  vl.user,
  COUNT(*) AS total_dials,
  ROUND(COUNT(*) / (TIMESTAMPDIFF(MINUTE, MIN(vl.call_date), MAX(vl.call_date)) / 60.0), 1) AS dph
FROM vicidial_log vl
WHERE vl.call_date >= CURDATE()
  AND vl.campaign_id = 'SALESCMP'
GROUP BY vl.user
ORDER BY dph DESC;
What to do when it’s off: Low DPH on a predictive dialer almost always means one of three things: hopper starvation (not enough leads loaded), trunk bottleneck (not enough SIP channels), or overly conservative dialing ratios. Check the hopper level first — if it drops below 2x your agent count, the dialer can’t keep pace.
Calls Per Hour (CPH)
Formula: Total Calls Handled / Total Agent Hours
What it measures: The number of calls an agent actually handles per hour, including conversations, voicemails delivered to agents, and quick dispositions. This is distinct from DPH because not every dial results in a call the agent touches.
Benchmarks: 15-40 handled calls per hour for outbound agents on predictive dialers, depending on AMD configuration and contact rate. If AMD is filtering voicemails effectively, most handled calls should be live contacts.
Where to find it in VICIdial: Agent Performance Detail report shows calls handled per agent per hour. The Agent Time Detail report breaks this down further by pause time, wait time, talk time, and disposition time.
What to do when it’s off: If DPH is high but CPH is low, your AMD is catching most voicemails (good) but contact rate is low (needs investigation). If both are low, it’s a dialer configuration or list exhaustion problem.
Contact Rate
Formula: Live Contacts / Total Dials x 100
What it measures: The percentage of dials that result in a live human answering the phone. This is the single most important throughput metric in outbound dialing. Everything downstream multiplies after contact rate.
Benchmarks:
| Data Type | Contact Rate Range | Median |
|---|---|---|
| Fresh inbound leads (0-7 days) | 18 – 35% | 25% |
| Warm data (7-30 days) | 12 – 22% | 16% |
| Aged data (30-90 days) | 8 – 15% | 11% |
| Cold purchased lists | 4 – 10% | 7% |
| Recycled / multi-pass | 3 – 8% | 5% |
Where to find it in VICIdial: Outbound Calling Report shows total dials and human-answered calls per campaign. For a more granular view, the Campaign Calls Detail report breaks out disposition codes — filter to “human answered” dispositions and divide by total dials.
What to do when it’s off: Contact rate is driven by data quality, DID reputation, time-of-day dialing strategy, and AMD configuration. If contact rate drops suddenly, check your DID reputation first — flagged numbers can cut contact rate in half overnight. For a systematic approach, see our VICIdial reporting guide.
Formula: Qualified Outcomes / Live Contacts x 100
What it measures: The percentage of live conversations that produce a qualified lead, sale, appointment, or other desired outcome.
Benchmarks:
| Vertical | Conversion Rate Range | Median |
|---|---|---|
| Home Services | 6 – 12% | 8% |
| Solar (Residential) | 4 – 8% | 6% |
| Insurance (Medicare/ACA) | 3 – 7% | 5% |
| Debt Settlement | 2 – 5% | 3.5% |
| B2B Appointment Setting | 1 – 4% | 2.5% |
Where to find it in VICIdial: Campaign Status report shows disposition counts by status category. Define your “qualified” dispositions (e.g., SALE, APPT, XFER) and divide by total human-answered calls. The Agent Performance Detail report shows conversion rate by agent.
What to do when it’s off: Conversion is a human problem — scripts, training, objection handling, and offer-market fit. But before blaming agents, check if the data changed. A shift from warm leads to cold lists will crater conversion even with the same agents running the same script.
Average Handle Time (AHT)
Formula: (Total Talk Time + Total Hold Time + Total After-Call Work Time) / Total Calls Handled
What it measures: The average total time spent on each interaction, from the moment the call connects to the moment the agent is ready for the next call.
Benchmarks:
| Call Type | AHT Range | Typical AHT |
|---|---|---|
| Outbound lead qualification | 90 – 180 sec | 120 sec |
| Outbound appointment setting | 180 – 360 sec | 240 sec |
| Outbound sales (close on call) | 300 – 900 sec | 480 sec |
| Inbound customer service | 240 – 480 sec | 360 sec |
| Inbound technical support | 420 – 900 sec | 600 sec |
Where to find it in VICIdial: Agent Time Detail report shows average talk time, hold time, and disposition time per agent. The Campaign Calls Detail report gives you aggregate AHT at the campaign level. Note that VICIdial tracks “Talk,” “Dispo,” and “Pause” as separate time categories — you need to add Talk + Dispo to get true AHT.
What to do when it’s off: AHT is tricky because both too high and too low are problems. High AHT means agents are spending too long on non-converting calls (tighten the script, add qualification gates earlier). Low AHT might mean agents are rushing through calls and not properly qualifying (check conversion rate — if both AHT and conversion dropped, agents are cutting corners).
Agent Talk Time Ratio
Formula: Total Talk Time / Total Logged-In Time x 100
What it measures: The percentage of an agent’s shift spent in actual live conversation. This is the purest measure of dialer efficiency and the metric that separates a well-tuned operation from a wasteful one.
Benchmarks:
| Configuration | Talk Time Ratio |
|---|---|
| Manual dialing | 15 – 22% |
| Preview dialer | 22 – 32% |
| Progressive dialer | 30 – 40% |
| Predictive dialer (default config) | 35 – 45% |
| Predictive dialer (optimized) | 45 – 55% |
| Predictive dialer (aggressive, 25+ agents) | 50 – 65% |
Where to find it in VICIdial: Real-Time Report shows current talk/wait/pause status per agent. For historical data, the Agent Time Detail report breaks down total time by category. Calculate: Talk Time / (Talk Time + Wait Time + Pause Time + Dispo Time).
What to do when it’s off: If talk time ratio is below 35% on a predictive dialer, you’re leaving money on the table. Check dial ratios, hopper size, trunk availability, and list penetration. A well-tuned VICIdial predictive dialer should deliver 42-50 minutes of talk time per hour with 15+ agents. For specifics on tuning, see our VICIdial reporting and monitoring guide.
Formula: (Talk Time + Hold Time + After-Call Work) / (Talk Time + Hold Time + After-Call Work + Available/Idle Time) x 100
What it measures: The percentage of an agent’s available time that is actually spent handling interactions. Unlike talk time ratio, occupancy excludes scheduled breaks and pause codes — it only counts time when the agent was available and ready for calls.
Benchmarks: 80-90% for outbound predictive dialing. 75-85% for inbound operations. Sustained occupancy above 90% leads to agent burnout and increased turnover. Below 75% on outbound indicates dialer inefficiency or list exhaustion.
Where to find it in VICIdial: Not directly reported as a single metric. Calculate from Agent Time Detail: (Talk + Dispo + Hold) / (Talk + Dispo + Hold + Wait). Exclude time in pause codes (breaks, lunch, meetings).
What to do when it’s off: High wait time between calls is the primary driver of low occupancy. On outbound, this means the dialer isn’t generating calls fast enough. On inbound, it means call volume is below forecast. For blended operations, routing idle outbound agents to take inbound calls (or vice versa) is the primary occupancy optimization lever.
Formula: (Total Productive Time) / (Total Paid Time) x 100
What it measures: The broadest productivity metric — what percentage of all paid hours are spent on revenue-generating activity. This includes talk time, after-call work, and other productive tasks, but excludes breaks, training, meetings, system downtime, and administrative time.
Benchmarks: 75-85% for well-managed operations. 85%+ is rare and usually unsustainable (agents need breaks). Below 70% means too much non-productive time is eating your payroll.
Where to find it in VICIdial: Requires combining data from VICIdial’s Agent Time Detail with your HR/scheduling system. VICIdial tracks logged-in time and its subcategories, but doesn’t know about total paid hours including offline activities.
What to do when it’s off: Low utilization usually comes from excessive meetings, training that could be done during slow periods, long breaks between sessions, or system downtime. Track pause codes religiously — they tell you exactly where non-productive time goes.
Are Your Agents Spending Half Their Shift Waiting?
Most VICIdial deployments run 15-20% below optimal talk time ratios. Our free audit measures your agent productivity metrics and shows you exactly where the lost time goes. Get Your Free Audit –>
Inbound KPIs: Every Metric That Matters
Inbound operations have a completely different optimization problem. You don’t control how many calls come in — you control how efficiently you handle them and how effectively you resolve customer needs. The KPIs shift from throughput and conversion to speed, quality, and resolution.
Formula: Calls Answered Within Threshold / Total Calls Offered x 100
What it measures: The percentage of inbound calls answered within a target time — usually expressed as “X% of calls answered in Y seconds.” The most common target is 80/20 (80% of calls answered within 20 seconds), though this varies by industry and call type.
Benchmarks:
| Industry | Common SLA Target | Typical Achievement |
|---|---|---|
| General Customer Service | 80/20 | 75 – 85% |
| Technical Support | 80/30 | 70 – 80% |
| Sales / Order Taking | 90/15 | 80 – 90% |
| Healthcare | 80/30 | 70 – 80% |
| Financial Services | 80/20 | 75 – 85% |
| Emergency / Critical Support | 95/10 | 90 – 95% |
Where to find it in VICIdial: Inbound Report shows calls offered, calls answered, and answer speed distribution. The Service Level report (if enabled) directly calculates SLA against your configured threshold. You can also pull this from the Real-Time Report’s queue statistics.
What to do when it’s off: SLA failures almost always come from understaffing, unexpected call volume spikes, or long handle times. Short-term fixes: reduce after-call work time, pull agents from outbound campaigns, enable overflow routing. Long-term fix: improve your workforce management forecasting.
Formula: Abandoned Calls / Total Calls Offered x 100
What it measures: The percentage of inbound callers who hang up before reaching an agent. This is the most visible indicator of customer frustration with wait times.
Benchmarks:
| Scenario | Abandon Rate |
|---|---|
| Excellent | < 3% |
| Good | 3 – 5% |
| Average | 5 – 8% |
| Below Average | 8 – 12% |
| Poor | > 12% |
For outbound predictive dialing, abandon rate has a regulatory dimension: the FTC’s Telemarketing Sales Rule caps outbound abandonment at 3% measured over a 30-day campaign period. VICIdial’s adaptive algorithm is designed to stay within this limit, but aggressive dial ratios can push you over.
Where to find it in VICIdial: Inbound Report shows abandoned call count and percentage. For outbound abandon rate (dropped calls), the Campaign Detail report tracks drops as a percentage of human-answered calls. The Real-Time Report shows current queue depth and wait times — if queue depth is climbing, abandons will follow.
What to do when it’s off: Every second of wait time increases abandon probability. The relationship is nonlinear — abandons are low for the first 20-30 seconds, then spike sharply. If your average speed of answer is over 30 seconds, abandon rate will be elevated regardless of what else you do. Fix the staffing or fix the handle time.
Average Speed of Answer (ASA)
Formula: Total Wait Time for Answered Calls / Total Calls Answered
What it measures: The average time a caller waits in queue before reaching an agent. This is distinct from service level — SLA is a threshold measurement (what percentage hit the target), while ASA is an average.
Benchmarks: 20-30 seconds for customer service, 10-20 seconds for sales queues, 30-60 seconds for technical support. ASA above 60 seconds is a red flag for any queue type.
Where to find it in VICIdial: Inbound Report shows average hold time (which in VICIdial terminology refers to queue wait time for inbound calls). Real-Time Report shows current wait time per queue.
What to do when it’s off: ASA is a direct function of staffing versus volume. The Erlang C model — the standard workforce management formula — takes your call volume, AHT, and target ASA to calculate required staffing. If you’re consistently missing ASA targets, you need either more agents, shorter handle times, or better call deflection (IVR self-service, callback options).
First Call Resolution (FCR)
Formula: Issues Resolved on First Contact / Total Issues x 100
What it measures: The percentage of customer issues resolved during the first interaction, without requiring a callback, transfer, or follow-up. FCR is the strongest single predictor of customer satisfaction in inbound operations.
Benchmarks:
| Channel | FCR Range | Top Quartile |
|---|---|---|
| Phone (Customer Service) | 65 – 80% | 80%+ |
| Phone (Technical Support) | 55 – 75% | 75%+ |
| 50 – 65% | 65%+ | |
| Chat | 60 – 75% | 75%+ |
Where to find it in VICIdial: FCR isn’t natively calculated by VICIdial. You need to define it through dispositions: mark calls as “Resolved” or “Requires Follow-Up” and track the ratio. Alternatively, measure repeat calls — if the same customer calls back within 24-48 hours on the same issue, the first call wasn’t resolved. The Closer In-Group report can help identify repeat callers by phone number.
What to do when it’s off: Low FCR is usually caused by one of three things: agents lack the authority to resolve issues (policy problem), agents lack the knowledge to resolve issues (training problem), or the issue genuinely requires multi-step resolution (process problem). Fix in that order — authority is fastest, process redesign is slowest.
Customer Satisfaction Score (CSAT)
Formula: Positive Responses / Total Survey Responses x 100
What it measures: Direct customer feedback on their interaction experience, typically collected via post-call IVR survey or follow-up SMS/email. Usually measured on a 1-5 or 1-10 scale.
Benchmarks: 80-85% positive (4-5 on a 5-point scale) is typical for well-run inbound operations. Below 75% indicates systemic issues. Above 90% is exceptional. Note that CSAT suffers from response bias — unhappy customers are more likely to respond, so the true satisfaction level is usually higher than reported.
Where to find it in VICIdial: If you’re using VICIdial’s built-in survey functionality (post-call IVR), results are stored in the survey log and accessible through custom reports. Most operations use external survey tools (e.g., a post-call SMS with a link) and track CSAT outside VICIdial.
What to do when it’s off: CSAT is a lagging indicator driven by FCR, ASA, and agent quality. Fix those three and CSAT follows. The most impactful quick win is reducing transfers — every transfer drops CSAT by 10-15 points on average.
Blended & Campaign-Level KPIs
These metrics apply across both inbound and outbound operations, or they measure performance at the campaign or center level rather than the individual interaction level.
Cost Per Lead (CPL)
Formula: Total Campaign Cost / Qualified Leads Generated
What it measures: The fully loaded cost to produce one qualified lead. This is the master outbound metric — the one number that tells you whether your operation is healthy or hemorrhaging cash.
Benchmarks: Varies enormously by vertical. Solar residential: $25-$55 median $38. Insurance: $30-$60 median $42. B2B appointment setting: $55-$150 median $95. Home services: $15-$35 median $24. For the complete benchmark table and a deep dive into the formula, see our full CPL benchmarks guide.
Where to find it in VICIdial: VICIdial doesn’t calculate CPL natively because it doesn’t track costs. You need to export lead counts from the Campaign Status report (filter by qualified dispositions) and divide by your total campaign costs from your accounting system. ViciStack’s analytics dashboard automates this calculation by integrating cost data with VICIdial disposition data.
What to do when it’s off: CPL is a composite. When it moves, something upstream changed. Trace back through the chain: did contact rate drop? Did conversion rate drop? Did costs increase? Our ROI formula guide walks through the full diagnostic framework.
Cost Per Acquisition (CPA) / Cost Per Sale
Formula: Total Campaign Cost / Total Closed Sales (or Acquisitions)
What it measures: The fully loaded cost to produce one closed sale or customer acquisition. CPA goes one step further than CPL by measuring the final revenue-producing event rather than an intermediate qualification step.
Benchmarks:
| Vertical | CPA Range | Median CPA |
|---|---|---|
| Solar (Residential) | $250 – $600 | $400 |
| Insurance (Medicare) | $150 – $400 | $250 |
| Home Improvement | $120 – $350 | $200 |
| Debt Settlement | $300 – $700 | $480 |
| B2B SaaS | $400 – $1,200 | $700 |
| Home Services | $80 – $200 | $130 |
Where to find it in VICIdial: Same approach as CPL but filter dispositions to closed sales only (SALE, CLOSED, etc.) rather than all qualified leads.
What to do when it’s off: If CPL is fine but CPA is high, the problem is downstream — your closers or your transfer process are losing qualified leads. If both CPL and CPA are high, the problem is upstream in your outbound operation.
Revenue Per Call / Revenue Per Contact
Formula: Total Revenue Attributed / Total Calls (or Contacts)
What it measures: The average revenue generated per call attempt or per live contact. This connects dialing activity directly to revenue and helps you evaluate whether a campaign is worth running at all.
Benchmarks: Highly variable by vertical and offer. For outbound sales, typical revenue per contact ranges from $2-$15 for B2C and $10-$50 for B2B. Revenue per dial is typically 10-20% of revenue per contact (because 80-90% of dials don’t reach a live person).
Where to find it in VICIdial: Requires integrating revenue data from your CRM or sales system with VICIdial call data. Export total dials and contacts from the Outbound Calling Report, then divide attributed revenue.
Schedule Adherence
Formula: Time Spent in Scheduled Activity / Total Scheduled Time x 100
What it measures: Whether agents are doing what they’re supposed to be doing when they’re supposed to be doing it. This includes being logged in during scheduled shifts, taking breaks at scheduled times, and being in the correct campaigns or queues.
Benchmarks: 90-95% is the target for most operations. Below 85% indicates a workforce management or discipline problem. Above 97% is essentially perfect and may indicate the schedule isn’t being tracked accurately.
Where to find it in VICIdial: The Agent Detail report shows login/logout times and pause code usage by time of day. Compare against your schedule in your WFM tool. VICIdial’s Timeclock feature can track scheduled vs. actual hours if enabled.
What to do when it’s off: Low schedule adherence kills inbound service levels because staffing models assume agents will be available when scheduled. If adherence is low, figure out whether it’s a few chronic offenders (discipline issue) or a systemic problem (schedules are unrealistic, break rooms are too far from desks, login process is too slow).
After-Call Work (ACW) Time
Formula: Total Disposition + Notes Time / Total Calls Handled
What it measures: The time agents spend on administrative tasks after each call — dispositioning, writing notes, updating CRM records, scheduling callbacks. ACW is part of AHT but worth tracking separately because it’s the most compressible component.
Benchmarks: 15-45 seconds for simple outbound dispositions. 30-90 seconds for inbound customer service. 60-180 seconds for complex B2B or technical support. If ACW exceeds 60 seconds on outbound calls, your disposition workflow needs simplification.
Where to find it in VICIdial: Agent Time Detail report shows “Dispo” time, which is VICIdial’s term for ACW. Campaign settings control the maximum allowed dispo time before auto-pause.
What to do when it’s off: Simplify disposition codes (most campaigns need 8-12, not 40). Implement auto-fill for common fields. Use VICIdial’s custom disposition form to capture only what’s necessary. Every 10 seconds shaved off ACW across 100 calls per agent per day is 17 minutes of recovered productive time — per agent.
Agent-Level vs. Campaign-Level vs. Center-Level Metrics
One of the biggest mistakes in contact center analytics is measuring things at the wrong level. An agent’s conversion rate tells you about that agent. A campaign’s conversion rate tells you about the script, the data, and the offer. The center’s conversion rate tells you almost nothing useful because it blends everything together.
Agent-Level Metrics
These should be tracked per agent, compared against peer averages, and used for coaching and performance management:
| Metric | What It Tells You | Action Threshold |
|---|---|---|
| Conversion Rate | Sales skill and script adherence | Below campaign average by 2+ points |
| AHT | Efficiency and call control | 20%+ above or below campaign average |
| Calls Per Hour | Productivity and system usage | Below 80% of campaign average |
| ACW Time | Process efficiency | 50%+ above campaign average |
| Schedule Adherence | Reliability and discipline | Below 90% |
| Quality Score | Compliance and customer experience | Below 80% on monitored calls |
| Hold Time | Knowledge gaps | 2x+ campaign average |
| Transfer Rate | Escalation patterns | 50%+ above campaign average |
Where to find it in VICIdial: Agent Performance Detail report is the starting point. For deeper analysis, the Agent Time Detail report breaks down every minute of an agent’s day. The Recording Log lets you listen to individual calls for quality scoring.
Campaign-Level Metrics
These should be tracked per campaign, compared against vertical benchmarks, and used for strategic decisions about scaling, sunsetting, or optimizing campaigns:
| Metric | What It Tells You | Action Threshold |
|---|---|---|
| CPL | Overall campaign economics | 20%+ above vertical median |
| Contact Rate | Data quality and DID health | Below 8% on any data type |
| Conversion Rate | Script-market fit | Below vertical median |
| Abandon Rate | Dialer aggressiveness or staffing gaps | Above 3% (outbound), above 5% (inbound) |
| List Penetration | Data exhaustion | Above 80% penetrated |
| Revenue Per Lead | Downstream value | Declining trend over 4+ weeks |
| Callback Success Rate | Recycling effectiveness | Below 40% callback completion |
Where to find it in VICIdial: Campaign Summary report gives you the top-level view. Outbound Calling Report gives you dialing and contact metrics. Campaign Status report gives you disposition distributions.
Center-Level Metrics
These should be tracked for the entire operation, reported to leadership, and used for budgeting and strategic planning:
| Metric | What It Tells You | Review Frequency |
|---|---|---|
| Total CPL (blended) | Operational efficiency | Weekly |
| Revenue / Seat / Month | Productivity at scale | Monthly |
| Agent Utilization | Workforce efficiency | Weekly |
| Attrition Rate | Retention and culture health | Monthly |
| Cost Per Seat / Hour | Total operational cost | Monthly |
| Compliance Incident Rate | Risk exposure | Weekly |
| System Uptime | Technology reliability | Daily |
Where to find it in VICIdial: Most center-level metrics require aggregating data across multiple VICIdial reports. The System Summary report gives you high-level call volume data. For a more comprehensive dashboard, see our guide on building VICIdial dashboards with Grafana and Metabase.
Real-Time vs. Historical Metric Tracking
Not every metric needs to be watched in real time. Staring at a live dashboard that shows 30 numbers updating every 5 seconds creates anxiety, not insight. The key is knowing which metrics require real-time monitoring (because you can and should act immediately when they move) and which only need historical review (because the trends matter more than the moment).
Metrics That Require Real-Time Monitoring
These metrics need to be visible on a wallboard or live dashboard because they indicate problems that get worse by the minute if left unaddressed:
| Metric | Why Real-Time Matters | Alert Threshold |
|---|---|---|
| Queue Depth / Calls Waiting | Callers are actively waiting and may abandon | > 2x staffed agents |
| Service Level (rolling 30 min) | SLA failures compound within the half-hour | Drops below 70% |
| Abandon Rate (rolling 30 min) | Indicates immediate staffing shortage | Exceeds 8% |
| Agent Status (Ready/Paused/Talk) | Identifies agents in excessive pause or dead air | Agent in pause > 10 min without approved code |
| Outbound Drop Rate | FTC compliance violation risk | Exceeds 2.5% (approaching 3% limit) |
| Hopper Level | Dialer will stall if hopper runs dry | Below 2x agent count |
| Trunk Utilization | Insufficient trunks throttle dialing | Above 85% capacity |
Where to find it in VICIdial: The Real-Time Report is your primary tool. It shows agent statuses, queue depths, wait times, and campaign performance in a live-updating view. Configure the Real-Time Report’s refresh interval to 5-10 seconds for wallboard use. VICIdial also supports custom real-time monitoring via the non-agent API, which can feed external dashboards.
Metrics That Require Historical / Trend Analysis
These metrics are meaningless in real time because they need larger sample sizes and trend context to be actionable:
| Metric | Why Historical Matters | Review Frequency |
|---|---|---|
| CPL | Daily fluctuations are noise; weekly trends are signal | Weekly |
| Conversion Rate | Needs 100+ contacts to be statistically meaningful | Weekly by campaign |
| AHT | Daily averages are affected by call mix; weekly trends show real changes | Weekly by agent |
| FCR | Requires callback tracking over 24-48 hours | Weekly |
| CSAT / NPS | Survey sample sizes need 50+ responses | Monthly |
| Agent Utilization | Needs full shift data, not partial | Weekly |
| Contact Rate by List Source | Needs 1,000+ dials per source to be reliable | Weekly |
| Schedule Adherence | Partial-day data is misleading | Weekly by agent |
Where to find it in VICIdial: Historical reports are accessed through Admin > Reports. Key reports: Outbound Calling Report (date range selectable), Agent Performance Detail (supports custom date ranges), Campaign Status (cumulative or periodic), and Export Calls Data (raw call records for custom analysis).
Building a Monitoring Cadence
The monitoring cadence we recommend for a 25+ agent operation:
Every 5-10 minutes (wallboard): Agent statuses, queue depth, service level, abandon rate, outbound drop rate, hopper level
Every hour (supervisor check-in): Talk time ratio by agent, conversion rate vs. target (if volume is sufficient), callback queue status
Daily (end-of-shift review): DPH and CPH by agent, contact rate by campaign, AHT trends, schedule adherence, disposition distribution
Weekly (management review): CPL by campaign, conversion rate by agent and campaign, list source performance, agent utilization, quality scores
Monthly (strategic review): CPA, revenue per lead, attrition rate, cost per seat, vendor performance, compliance incidents
Want Real-Time Dashboards Without the Dashboard Build?
ViciStack’s analytics platform connects to your VICIdial data and delivers pre-built dashboards for every KPI listed above — real-time wallboards, agent scorecards, and campaign performance trending. See What You’re Missing –>
KPI Benchmarks Master Table
Consolidated reference table below. Bookmark this section. Print it. Tape it to the wall next to your wallboard.
Outbound Metrics Benchmarks
| KPI | Formula | Below Average | Average | Good | Excellent |
|---|---|---|---|---|---|
| Contact Rate | Contacts / Dials | < 7% | 7 – 11% | 11 – 16% | > 16% |
| Conversion Rate | Leads / Contacts | < 3% | 3 – 5% | 5 – 8% | > 8% |
| Dials Per Hour | Dials / Agent Hrs | < 120 | 120 – 170 | 170 – 220 | > 220 |
| Talk Time Ratio | Talk / Logged-In | < 30% | 30 – 40% | 40 – 50% | > 50% |
| Occupancy | Productive / Available | < 75% | 75 – 82% | 82 – 88% | > 88% |
| AHT (Lead Qual) | Talk+Hold+ACW / Calls | > 210 sec | 150 – 210 sec | 100 – 150 sec | < 100 sec |
| ACW Time | Dispo Time / Calls | > 45 sec | 30 – 45 sec | 15 – 30 sec | < 15 sec |
| Abandon Rate (Outbound) | Drops / Human Answers | > 5% | 3 – 5% | 1 – 3% | < 1% |
Inbound Metrics Benchmarks
| KPI | Formula | Below Average | Average | Good | Excellent |
|---|---|---|---|---|---|
| Service Level (80/20) | Ans in 20s / Offered | < 70% | 70 – 78% | 78 – 85% | > 85% |
| Abandon Rate | Abandoned / Offered | > 10% | 6 – 10% | 3 – 6% | < 3% |
| ASA | Wait Time / Answered | > 45 sec | 25 – 45 sec | 15 – 25 sec | < 15 sec |
| FCR | Resolved First / Total | < 60% | 60 – 70% | 70 – 80% | > 80% |
| AHT (Cust Service) | Talk+Hold+ACW / Calls | > 500 sec | 360 – 500 sec | 240 – 360 sec | < 240 sec |
| CSAT | Positive / Responses | < 72% | 72 – 80% | 80 – 88% | > 88% |
| Transfer Rate | Transferred / Handled | > 20% | 12 – 20% | 6 – 12% | < 6% |
Center-Level Benchmarks
| KPI | Below Average | Average | Good | Excellent |
|---|---|---|---|---|
| Agent Utilization | < 68% | 68 – 76% | 76 – 84% | > 84% |
| Schedule Adherence | < 85% | 85 – 90% | 90 – 95% | > 95% |
| Attrition Rate (Monthly) | > 12% | 7 – 12% | 4 – 7% | < 4% |
| System Uptime | < 98% | 98 – 99.2% | 99.2 – 99.8% | > 99.8% |
| Cost Per Agent Hour | > $38 | $30 – $38 | $24 – $30 | < $24 |
Setting KPI Targets: A Practical Framework
Benchmarks are useful for context, but your targets should be set based on your operation’s current performance, not industry averages. This is how we set targets that are ambitious but achievable.
Step 1: Establish Your Baseline
Pull 4-6 weeks of data for every KPI. Don’t use a single week — call center performance has natural week-to-week variation driven by data freshness cycles, staffing fluctuations, and seasonal patterns. You need enough data to see through the noise.
Step 2: Identify Your Quartile
For each metric, determine where you sit relative to the benchmarks:
Step 3: Set Cascading Targets
Start with the lagging indicator target (e.g., “Reduce CPL from $52 to $42 within 90 days”), then work backward to the leading indicator targets that will get you there:
Example cascade for a CPL reduction from $52 to $42:
| Metric | Current | 30-Day Target | 60-Day Target | 90-Day Target |
|---|---|---|---|---|
| CPL | $52.00 | $48.00 | $44.50 | $42.00 |
| Contact Rate | 9.2% | 11.0% | 12.5% | 13.0% |
| Conversion Rate | 4.8% | 5.0% | 5.5% | 6.0% |
| Talk Time Ratio | 32% | 38% | 42% | 44% |
| ACW Time | 52 sec | 40 sec | 30 sec | 25 sec |
The 30-day targets are infrastructure wins (dialer tuning, AMD optimization). The 60-day targets add data strategy improvements. The 90-day targets layer in agent performance gains.
Step 4: Assign Accountability
Every KPI target needs an owner:
A metric without an owner is a metric that won’t improve.
Common KPI Mistakes and How to Avoid Them
Mistake 1: Optimizing One Metric at the Expense of Others
The classic example: pushing agents to reduce AHT causes them to rush calls, which drops conversion rate, which raises CPL. Every KPI exists in tension with others. When you set a target for one metric, check the adjacent metrics for unintended consequences.
The fix: Always set KPI targets in groups, not individually. If you’re targeting lower AHT, simultaneously set a floor on conversion rate. If you’re targeting higher conversion, simultaneously set a ceiling on AHT.
Mistake 2: Comparing Agents Across Different Campaigns
An agent running a warm solar appointment campaign at 8% conversion is not outperforming an agent running cold B2B appointment setting at 3% conversion. The campaigns have entirely different dynamics. Compare agents against the average for their specific campaign, not against each other across campaigns.
The fix: Normalize agent metrics by campaign. Report agent performance as a percentage of campaign average (e.g., “+15% above campaign conversion rate”) rather than absolute numbers.
Mistake 3: Treating Weekly Variance as Signal
Contact rate dropped from 11.2% to 10.4% this week. Is something wrong? Maybe. Or maybe it’s normal variance. In a 25-agent operation making 693,000 dials per month, weekly contact rate will naturally fluctuate by 0.5-1.5 percentage points based on list mix, day-of-week effects, and random chance.
The fix: Use 4-week rolling averages for trend analysis. Only investigate when a metric moves more than 2 standard deviations from its rolling average, or when the rolling average itself shows a sustained directional change over 3+ weeks.
Mistake 4: Ignoring Qualitative Metrics
Numbers tell you what happened. They don’t tell you why. A conversion rate drop could be a script problem, a data quality shift, a competitor launching a better offer, or regulatory changes making prospects more cautious. You won’t find the cause in the quantitative KPIs alone.
The fix: Supplement quantitative KPIs with regular call monitoring, agent feedback sessions, and disposition code analysis. VICIdial’s recording log lets you listen to calls by disposition — pull a sample of 20-30 non-converting calls each week and listen for patterns.
Mistake 5: Reporting Vanity Metrics to Leadership
Leadership doesn’t need to know your dials per hour. They need to know CPL, CPA, revenue per lead, and ROI. Reporting operational metrics to people who can’t act on them creates confusion and erodes trust. Report outcomes to leadership, reserve operational metrics for operational managers.
The fix: Build two dashboards. The leadership dashboard shows 5-7 lagging indicators with trend lines. The operations dashboard shows 15-20 leading and lagging indicators with drill-down capability. For guidance on building these, see our Grafana and Metabase dashboard guide.
Putting It All Together: The KPI Review Meeting
The agenda we recommend for a weekly KPI review with an operations team of 25+ agents:
Duration: 30 minutes. Not 60. If your KPI meeting takes an hour, you’re reviewing too many metrics or discussing action items that belong in separate follow-ups.
Attendees: Campaign managers, team leads, QA lead, dialer administrator. Not agents — agent coaching happens 1-on-1.
Agenda:
Scorecard review (5 min): CPL, conversion rate, contact rate, service level — the top-line numbers. Are they on target? Green/yellow/red status for each campaign.
Variance analysis (10 min): For any metric in yellow or red, what changed? Trace the causal chain from lagging to leading indicators. Did contact rate drop because a list expired? Did conversion drop because we changed the script? Did AHT spike because we onboarded new agents?
Action items from last week (5 min): Did we implement the changes we committed to? What was the measurable result?
New action items (10 min): Based on today’s data, what are the top 1-2 changes we’ll implement this week? Assign owners, set expected impact, define how we’ll measure it.
That’s it. No deep dives into agent-level data (that’s for team lead 1-on-1s). No system architecture discussions (that’s for the technical team). No strategic planning (that’s monthly). The weekly KPI meeting is purely: where are we, what changed, what are we doing about it.
Frequently Asked Questions
What are the most important KPIs for an outbound call center?
The five that matter most for outbound operations are: Cost Per Lead (the master metric), Contact Rate (the biggest operational lever), Conversion Rate (the revenue driver), Talk Time Ratio (the efficiency indicator), and Abandon Rate (the compliance guardrail). If you can only track five numbers, track those. CPL tells you whether you’re making or losing money. Contact rate and conversion rate are the two multipliers that determine lead volume. Talk time ratio tells you whether your dialer is actually working. And abandon rate keeps you out of trouble with the FTC’s 3% rule. Every other outbound metric is either an input to these five or a secondary diagnostic you only need when one of these five goes sideways.
How do I calculate cost per lead for my call center?
Fully loaded CPL = Total Campaign Cost / Qualified Leads Generated. The key word is “fully loaded” — include agent wages, payroll taxes, benefits, telecom, list/data purchases, dialer infrastructure, management and QA salaries, compliance costs, facilities, and overhead. Most centers only count agent wages and list costs, which understates CPL by 30-60%. Calculate it at the campaign level first, never as a blended average across campaigns. And count only leads that survive qualification — not raw dispositions. Our CPL benchmarks guide walks through a detailed worked example with a cost breakdown table for a 25-agent operation.
What’s a good conversion rate for outbound calls?
It depends on the vertical, the data type, and what you’re converting to. For B2C outbound lead qualification on warm data, 5-8% is good and above 8% is excellent. For cold data, 2-4% is good. For B2B appointment setting, 1-3% is realistic and above 3% is strong. The biggest factor isn’t agent skill — it’s data quality and recency. Fresh inbound leads (0-7 days old) convert at 2-4x the rate of aged purchased lists, regardless of who’s dialing them. If your conversion rate is below the vertical median in our benchmarks table, check the data source before blaming agents.
How do I measure agent performance in VICIdial?
Start with the Agent Performance Detail report, which shows calls handled, talk time, pause time, disposition time, and conversion metrics per agent for any date range. The Agent Time Detail report breaks down every minute of the agent’s shift. For quality measurement, use the Recording Log to pull and score a sample of each agent’s calls weekly. The most actionable agent metrics are: conversion rate vs. campaign average, AHT vs. campaign average, calls per hour, schedule adherence, and quality scores from call monitoring. Compare agents against their campaign peers, not against agents on different campaigns. A 6% converter on a cold data campaign is likely outperforming a 6% converter on warm inbound leads.
What’s the difference between occupancy rate and utilization rate?
Occupancy rate measures the percentage of an agent’s available time spent handling calls (talk + hold + after-call work / available time). It excludes breaks, training, and other scheduled off-phone activities. Agent utilization measures the percentage of an agent’s total paid time spent on productive work, including off-phone productive activities. Occupancy can be 88% while utilization is 76% — because the agent was only available for calls during 86% of their shift (the rest was breaks, meetings, and training). Both matter. Occupancy tells you whether the dialer is keeping agents busy when they’re available. Utilization tells you whether the overall schedule is efficient. Target 82-88% occupancy and 76-84% utilization. Sustained occupancy above 90% leads to burnout and turnover.
How often should I review contact center KPIs?
Real-time metrics (queue depth, agent status, service level, abandon rate, outbound drop rate) should be on a wallboard or live dashboard and monitored continuously by supervisors. Daily metrics (DPH, CPH, contact rate, schedule adherence) should be reviewed at end-of-shift by team leads. Weekly metrics (CPL, conversion rate, AHT trends, list source performance, agent utilization) should be reviewed in a 30-minute management meeting. Monthly metrics (CPA, revenue per lead, attrition rate, cost per seat, CSAT/NPS) should go to leadership. The biggest mistake is reviewing weekly-cadence metrics in real time — daily fluctuations in conversion rate or CPL are noise, not signal. Use 4-week rolling averages for trend analysis.
What is a good service level for an inbound call center?
The industry standard is 80/20 — 80% of calls answered within 20 seconds. But “good” depends on your context. Sales queues where every missed call is lost revenue should target 90/15 or better. Technical support with complex issues can often get away with 80/30. Cost-sensitive operations sometimes drop to 70/30 and absorb the higher abandon rate. The tradeoff is always service level vs. staffing cost — achieving 90/15 requires significantly more agents than 80/20 for the same call volume. Use Erlang C calculations to model the staffing impact of different SLA targets before committing. Whatever target you set, measure it in 30-minute intervals, not daily averages — a daily average of 82% can mask severe intraday dips that drive abandonment and customer frustration during peak hours.
How do I improve first call resolution in my contact center?
First call resolution improves through three levers, in order of speed and impact. First, expand agent authority — if agents have to transfer or escalate issues they’re capable of handling because policy won’t let them, fix the policy. This is the fastest FCR win and costs nothing. Second, improve agent knowledge — build a searchable knowledge base, create decision trees for common issues, and ensure agents can find answers without putting customers on hold. Third, redesign processes that inherently require multiple contacts — if a request “always” needs a callback because a different department handles part of it, integrate that department’s capability into the front-line agent’s toolkit. Track FCR by measuring repeat calls from the same phone number within 48 hours. In VICIdial, you can identify repeat callers through the Closer In-Group report and call logs filtered by phone number. Target 75%+ FCR for customer service and 70%+ for technical support.
Picking the right colors for a project takes longer than it should. You need palettes that look good, meet contrast requirements, work as design tokens, and don’t require a full-time designer to maintain.
These tools solve different parts of that problem. Here’s what works, what doesn’t, and how to actually use them in a development workflow.
Why Developers Need Color Palette Tools
You’re building a dashboard, SaaS app, or landing page. You need:
Doing this from scratch takes hours. Good tools get you 80% of the way there in minutes.
1. Coolors — The Quickstart Generator
Best for: Generating initial palette ideas quickly
Coolors is the most popular palette generator. Press spacebar, get a new 5-color palette. Lock colors you like, regenerate the rest.
Features:
How to use it as a developer:
/* Export from Coolors as CSS custom properties */
:root {
  --primary-50: #EEF2FF;
  --primary-500: #6366F1;
  --primary-900: #312E81;
}
Limitation: 5-color palettes are great for mood boards, but you need 10-step scales (50, 100, 200…900) for design system work. Coolors doesn’t generate those automatically.
2. Radix Colors — Production-Ready Semantic Palettes
Best for: Building accessible UI components with consistent scales
Radix Colors (from the team behind Radix UI) provides 30+ meticulously crafted color scales, each with 12 steps:
| Step | Purpose |
|---|---|
| 1-2 | App backgrounds |
| 3-4 | Subtle backgrounds |
| 5-6 | UI element backgrounds |
| 7-8 | Borders, separators |
| 9-10 | Solid backgrounds |
| 11-12 | Text |
Every scale works in both light and dark mode. The contrast ratios are pre-calculated. You get CSS custom properties, Tailwind config, and figma files.
Installation:
npm install @radix-ui/colors
/* Use Radix color scales in CSS */
@import '@radix-ui/colors/blue.css';
@import '@radix-ui/colors/blue-dark.css';

.button {
  background: var(--blue-9);  /* Solid blue, AA compliant */
  color: white;
}

.button:hover {
  background: var(--blue-10);
}
Tailwind integration:
// tailwind.config.js
const { blue, gray } = require('@radix-ui/colors')

module.exports = {
  theme: {
    extend: {
      colors: {
        blue: {
          1: blue.blue1,
          // ... etc
          9: blue.blue9,
        }
      }
    }
  }
}
Best for: Any project using Radix UI components, or teams that want a mathematically consistent color system.
3. shadcn/ui Theme Generator
Best for: Projects using shadcn/ui or similar component libraries
shadcn/ui’s built-in theme system uses CSS variables mapped to semantic names: --background, --foreground, --primary, --secondary, --muted, --accent, etc.
The official theme generator lets you pick a base color and generates a complete CSS variable set for both light and dark mode.
Generated output looks like:
@layer base {
  :root {
    --background: 0 0% 100%;
    --foreground: 222.2 84% 4.9%;
    --primary: 221.2 83.2% 53.3%;
    --primary-foreground: 210 40% 98%;
    --secondary: 210 40% 96.1%;
    --secondary-foreground: 222.2 47.4% 11.2%;
    /* ... */
  }

  .dark {
    --background: 222.2 84% 4.9%;
    --foreground: 210 40% 98%;
    --primary: 217.2 91.2% 59.8%;
    /* ... */
  }
}
Usage:
globals.css
This is the fastest path to a complete, dark-mode-ready color system for shadcn/ui projects.
4. Tailwind CSS Color Generator
Best for: Tailwind projects that need custom brand colors matching Tailwind’s scale format
Tailwind’s built-in colors use a 50-900 scale. If your brand color is #FF6B2B, you need matching shades from 50 (very light) to 900 (very dark). Doing this manually is tedious.
Recommended tools:
uicolors.app: Enter any hex, get a full Tailwind-format palette. Shows contrast ratios and WCAG compliance for each step.
tints.dev: Another Tailwind-specific palette generator with live preview.
Output format:
// tailwind.config.js
module.exports = {
  theme: {
    extend: {
      colors: {
        brand: {
          50:  '#FFF4EE',
          100: '#FFE4CC',
          200: '#FFC999',
          300: '#FFAD66',
          400: '#FF9133',
          500: '#FF6B2B',  // Your base color
          600: '#CC5522',
          700: '#993F1A',
          800: '#662A11',
          900: '#331508',
          950: '#1A0A04',
        }
      }
    }
  }
}
5. Realtime Colors — Preview in Context
Best for: Checking how palettes look in real UI before committing
Realtime Colors shows your color choices applied to an actual web layout in real time. Instead of staring at swatches, you see how your palette looks on a nav, hero section, cards, and buttons.
Why it matters: A palette that looks great as abstract swatches can look terrible in context. Too much contrast, wrong proportions, or colors that clash in UI elements.
Features:
Font pairing suggestions
Free
6. Huemint — AI-Powered Palette Generation
Best for: Getting unstuck when standard generators aren’t giving you what you want
Huemint uses machine learning to generate palettes based on specified relationships (brand, background, foreground, etc.). You define the role each color plays, and it generates coordinated options.
Useful when:
You’re exploring different aesthetic directions
Free
7. ColorBox by Lyft Design
Best for: Generating accessible, perceptually-uniform color scales
ColorBox (open-sourced by Lyft) generates 10-step color scales with perceptual uniformity — meaning each step looks equally different from the last, which isn’t always true with simple lightness adjustments.
This matters for:
Design systems requiring predictable color behavior
Free, open source
Building a Complete Color System for a Web App
Here’s a practical workflow combining these tools:
Step 1: Establish your brand primary
Start with your brand color. If you don’t have one, pick something from Coolors or let Huemint suggest options.
Step 2: Generate full scales
Use uicolors.app or tints.dev to generate the full 50-900 scale for your primary. Also generate scales for:
Step 3: Map to semantic tokens
Create CSS custom properties with semantic names, not just numeric scales:
:root {
  /* Scales */
  --blue-500: #3B82F6;
  --green-500: #22C55E;
  --red-500: #EF4444;

  /* Semantic tokens */
  --color-primary: var(--blue-500);
  --color-success: var(--green-500);
  --color-error: var(--red-500);

  /* Surface tokens */
  --bg-page: #FFFFFF;
  --bg-card: #F9FAFB;
  --border-default: #E5E7EB;

  /* Text tokens */
  --text-primary: #111827;
  --text-secondary: #6B7280;
  --text-muted: #9CA3AF;
}

.dark {
  --bg-page: #0F172A;
  --bg-card: #1E293B;
  --border-default: #334155;
  --text-primary: #F1F5F9;
  --text-secondary: #94A3B8;
  --text-muted: #64748B;
}
Step 4: Verify contrast
Use the contrast checker at webaim.org/resources/contrastchecker or Coolors’ built-in checker to verify WCAG compliance for your text/background combinations.
Minimum requirements:
Step 5: Test in dark mode
Don’t assume light mode colors invert nicely. Test every semantic token in dark mode explicitly.
Quick Comparison
| Tool | Best Use Case | Output Formats | Free? |
|---|---|---|---|
| Coolors | Palette ideation | CSS, SCSS, hex | Yes |
| Radix Colors | Accessible UI scales | CSS vars, Tailwind | Yes |
| shadcn/ui themes | shadcn projects | CSS vars | Yes |
| uicolors.app | Tailwind scale from brand color | Tailwind config | Yes |
| Realtime Colors | Preview in UI context | CSS vars, Tailwind | Yes |
| Huemint | AI-assisted palette gen | CSS vars | Yes |
| ColorBox | Perceptually-uniform scales | Various | Yes |
Find more free developer tools at DevPlaybook.cc, including a CSS Gradient Generator, Color Picker, and 15+ other tools for daily development work.
Level Up Your Dev Workflow
Found this useful? Explore DevPlaybook — cheat sheets, tool comparisons, and hands-on guides for modern developers.
🛒 Get the DevToolkit Starter Kit on Gumroad — 40+ browser-based dev tools, source code + deployment guide included.
TL;DR
The OWASP Smart Contract Top 10: 2026 is live. Based on 2025 incident data and practitioner surveys, it reshuffles the risk landscape. Reentrancy dropped from #2 to #8. Proxy & Upgradeability Vulnerabilities entered at #10 — a brand new category. And Business Logic Vulnerabilities climbed to #2, reflecting where the real money is being lost.
If you’re still auditing like it’s 2023, this ranking is your wake-up call.
What Changed (and Why It Matters)
The 2026 Ranking
| # | Category | Trend |
|---|---|---|
| SC01 | Access Control Vulnerabilities | → Stable at #1 |
| SC02 | Business Logic Vulnerabilities | ↑ New to Top 3 |
| SC03 | Price Oracle Manipulation | → Stable |
| SC04 | Flash Loan–Facilitated Attacks | → Stable |
| SC05 | Lack of Input Validation | ↑ Climbed |
| SC06 | Unchecked External Calls | → Stable |
| SC07 | Arithmetic Errors | ↓ Dropped |
| SC08 | Reentrancy Attacks | ↓↓ Fell from #2 |
| SC09 | Integer Overflow and Underflow | ↓ Dropped |
| SC10 | Proxy & Upgradeability Vulns | 🆕 New entry |
Three shifts stand out. Let’s unpack each.
1. Reentrancy: From #2 to #8 — Progress, Not Safety
Reentrancy falling six spots is a success story with a footnote.
Why it dropped
nonReentrant modifier is now near-universalReentrancyGuardTransient made protection cheaper (transient storage = lower gas) Why you can’t ignore it
Cross-contract reentrancy is alive and well. When Contract A calls Contract B which calls back into Contract A through Contract C, single-contract reentrancy guards don’t help. The 2025 incident data shows these multi-contract chains are where reentrancy still bites.
Read-only reentrancy is the silent killer. If your view function reads state that’s mid-update during an external call, an attacker can get stale data. The fix: use _reentrancyGuardEntered() checks even in view functions.
// ❌ Vulnerable: view function reads inconsistent state
function getPrice() public view returns (uint256) {
    return totalAssets / totalShares; // stale during reentrant call
}

// ✅ Protected: fails if reentrancy guard is active
function getPrice() public view returns (uint256) {
    require(!_reentrancyGuardEntered(), "ReentrancyGuard: reentrant view");
    return totalAssets / totalShares;
}
Takeaway: Reentrancy at #8 means the simple variants are solved. The subtle ones are now the actual threat.
2. Business Logic Vulnerabilities at #2 — The Auditor’s Nightmare
This is the category that keeps auditors up at night because there’s no static analysis tool that catches it.
Business logic vulnerabilities are flaws in the economic design — reward calculations, fee structures, liquidation thresholds, governance mechanics — that work exactly as coded but break under adversarial conditions.
Real examples from 2025-2026
Reward draining: A lending protocol’s reward distribution calculated interest per-block but didn’t account for flash-loan deposits lasting exactly one block. Attacker deposits $50M via flash loan, claims rewards, repays — net profit on “one-block lending.”
Liquidation cascades: Oracle update timing + liquidation thresholds created a window where healthy positions could be liquidated. Not a bug — a design flaw.
Governance capture: Protocol required 10% quorum for proposals. Attacker flash-loaned governance tokens, passed a proposal to drain the treasury, all in one transaction.
What to do about it
totalDeposits >= totalWithdrawals + fees) and fuzz against them aggressively.// Foundry invariant test example
function invariant_solvency() public {
uint256 totalDeposits = vault.totalAssets();
uint256 totalShares = vault.totalSupply();
// Vault should never be insolvent
assert(totalDeposits >= totalShares * vault.minSharePrice() / 1e18);
// No single user should hold >50% of shares (governance risk)
assert(vault.balanceOf(largestHolder) <= totalShares / 2);
}
3. Proxy & Upgradeability Vulnerabilities — The New #10
This is the first time proxy bugs have their own OWASP category, and it’s overdue. 2025 saw several high-profile incidents where the upgrade mechanism itself was the attack vector.
The three proxy pitfalls
1. Unprotected initialize() functions
After deploying a proxy, the implementation contract needs to be initialized. If initialize() isn’t protected or can be called twice, an attacker can reinitialize with their own parameters.
// ❌ No protection against re-initialization
function initialize(address _owner) public {
    owner = _owner;
}

// ✅ Using OpenZeppelin's initializer modifier
function initialize(address _owner) public initializer {
    __Ownable_init(_owner);
}
2. Storage collisions
Proxy patterns (UUPS, Transparent, Beacon) store implementation addresses in specific storage slots. If your implementation contract accidentally uses the same slot for a state variable, upgrading corrupts your data.
// EIP-1967 implementation slot:
// bytes32(uint256(keccak256("eip1967.proxy.implementation")) - 1)
// = 0x360894a13ba1a3210667c828492db98dca3e2076cc3735a920a3ca505d382bbc
//
// If your contract stores a variable at this exact slot → catastrophic
3. Governance key compromise
The most expensive variant. If the key that controls upgrades is compromised (or is a single EOA), an attacker can upgrade the implementation to a malicious contract that drains everything.
The audit checklist for proxies
initialize() uses initializer modifier and can only be called oncehardhat-upgrades or forge inspect)_authorizeUpgrade() with proper access control_disableInitializers() in constructor Updated Audit Priority Matrix
Based on the 2026 ranking, here’s how to allocate audit time:
Tier 1: Spend 50% of audit hours here
Tier 2: Spend 30% here
Tier 3: Spend 20% here
The Honourable Mentions You Shouldn’t Ignore
OWASP also listed categories that didn’t make the top 10 but are increasingly relevant:
Cross-Chain MEV — Source-chain event leakage enabling sandwich attacks on destination chains. The Symbiosis incident ($5.27M extracted) demonstrated this in 2025.
Permit Front-Running & Nonce DoS — Attackers front-run permit() calls to consume nonces, causing legitimate transactions to revert. If your protocol composes permit into deposit flows without a fallback, this is a DoS vector.
Governance Attack Vectors — Flash-loan voting, rushed proposals, timelock bypasses. If your protocol has on-chain governance, this deserves dedicated review time.
What This Means for Solana
The OWASP list is EVM-focused, but the patterns translate:
| EVM Category | Solana Equivalent |
|---|---|
| Access Control | Missing signer/owner checks on program instructions |
| Business Logic | Same — economic design flaws are chain-agnostic |
| Oracle Manipulation | Pyth/Switchboard staleness, confidence interval checks |
| Reentrancy | CPI (Cross-Program Invocation) reentrancy |
| Proxy/Upgradeability | Program upgrade authority management |
Solana developers should read the OWASP list through the lens of their own runtime. The vulnerability classes are universal even when the implementations differ.
Action Items
The OWASP Smart Contract Top 10 is derived from 2025 incident data and practitioner surveys. The 2026 list is forward-looking — projecting which risks will be most significant based on observed trends. Full methodology available at scs.owasp.org/sctop10/methodology.
What’s your take — is reentrancy really less dangerous, or just less visible? Drop your thoughts in the comments.