Google, Google Arama’ya Gelecek Yepyeni Özellikleri Tanıttı
Google, Google I/O 2026 etkinliğinde Google Arama’nın büyük ölçüde yenilendiğini ve yeni özelliklerini tanıttı.

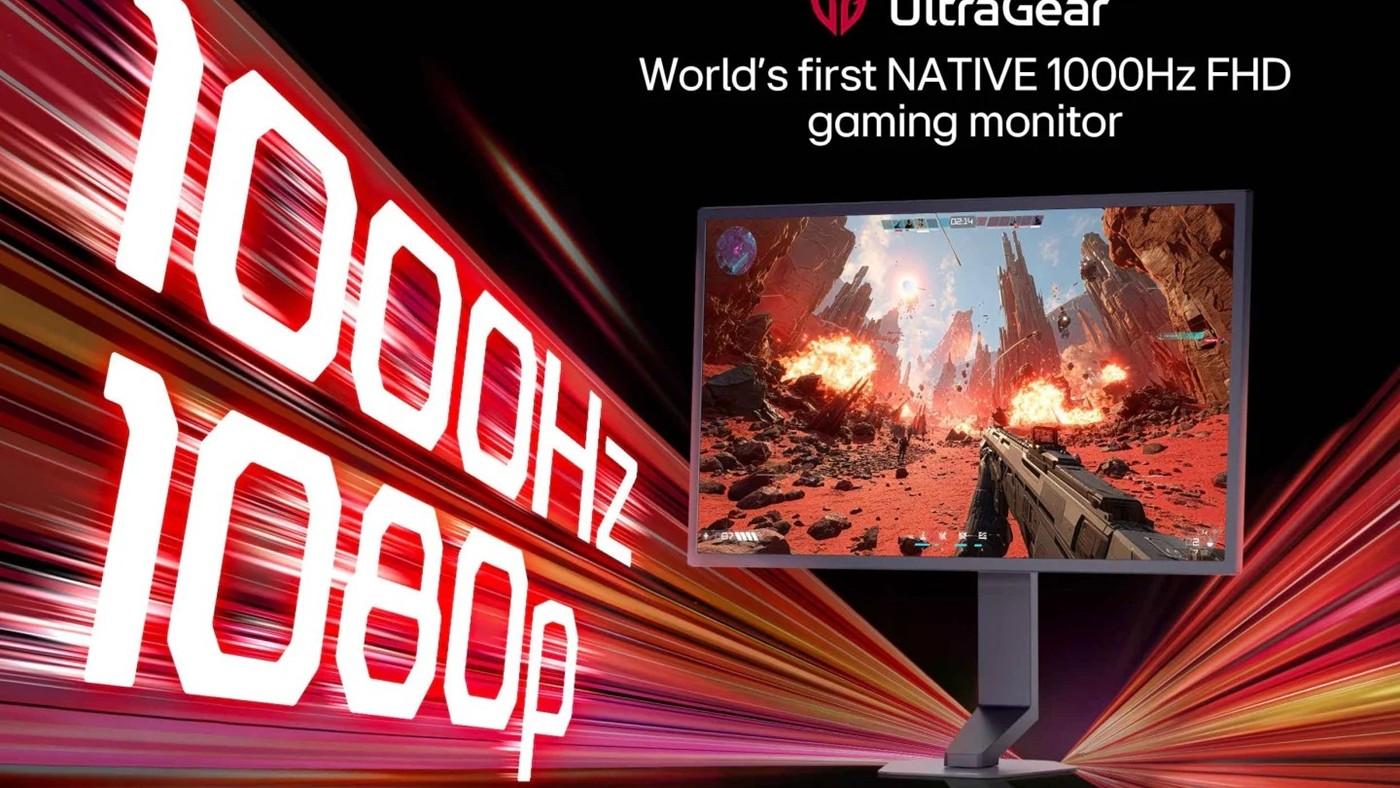
 LG, oyuncuları hedefleyen UltraGear 25G590B isimli monitörünü duyurdu. Şirket, bu modelin dünyada 1080p çözünürlükte 1000Hz doğal yenileme hızına ulaşabilen ilk monitör olduğunu belirtiyor.
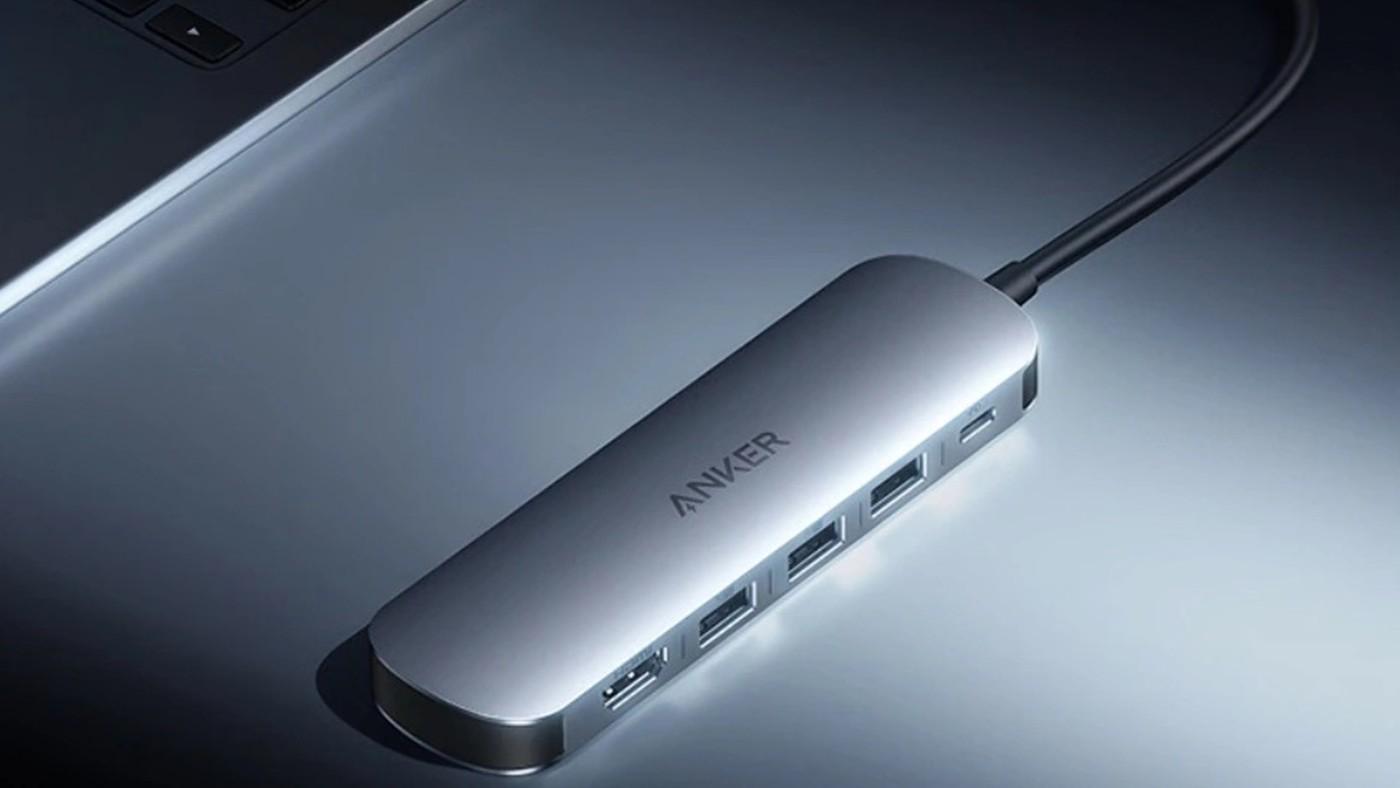
 Anker 5-in-1 All-in-One USB-C Expansion Dock çoklayıcı ürünü bütçesi kısıtlı olanlar için en gerekli olan portları entegre ederek ideal bir alternatif olmayı amaçlıyor.
TL;DR
- The model matters, but tools matter at least as much. Weak tool descriptions are one of the easiest agent failures to diagnose, and one of the most common.
- Design the tools before the agent. If you cannot answer “what can this agent do that a general LLM cannot on its own?”, you do not have an agent yet.
- Ship a small, focused loop with 2-3 well-described tools and a hard iteration cap. Watch traces. Iterate.
In Part 1 I laid out the four levels of AI agents I keep seeing in production, and argued that most shipped “AI agents” are stuck on the lower rungs. This post is about how to build one that is not.
One assumption underneath everything below:
Tools are the center of an agent. Not the system prompt.
Most tutorials start with “let’s write the system prompt.” Wrong starting point. Start with tools.
Start With Tool Design
A weak tool description looks like this:
search_documents:
  description: "Search documents."
The model has no idea when to use it, what to put in query, or what the output means. So it guesses. Badly.
A good description looks closer to this:
search_documents:
  description: "|"
    Use this tool when the user's question requires evidence from
    internal documents, policies, or technical references.

    Do NOT pass the full user question as the query. Extract the
    core concepts and keywords. If the first result set is weak,
    rewrite the query and search again before answering.

    Cite the retrieved documents as evidence in your final answer.
  parameters:
    query:
      type: string
      description: "2-6 keywords, not a full sentence."
Same tool. Completely different agent behavior.
The good description does three jobs the bad one skips:
Claude’s Skills system is worth studying for the shape, not the brand. A Skill packages task-specific instructions, files, scripts, and example workflows behind a short trigger description. The heavy content only loads when the agent decides the Skill is relevant. The pattern has a name: progressive disclosure. Reachable in any framework that lets you gate long instructions behind a short surface.
Two tips that have saved me more time than anything else in this area.
1. When you’re stuck, let skill-creator rewrite your prompt.
Anthropic ships an official Skill called skill-creator whose job is to make and improve other Skills. Its SKILL.md is, almost accidentally, the best prompt-design tutorial I have read. The patterns it pushes are exactly the ones that hold up under load: explain why a rule matters instead of writing rigid ALWAYS/NEVER directives; design for the smart model you actually have, not the rote one you imagine; generalize past your test cases rather than overfit to them; cut anything not pulling its weight.
What I do now whenever I have to write a non-trivial agent system prompt: write a first draft myself, then ask Claude to rewrite it “following the skill-creator SKILL.md guidelines.” The result has beaten my draft every single time. Sometimes embarrassingly so.
2. Read how Claude Code itself is built.
Anthropic’s Claude Code documentation walks through how their own coding agent is wired — system prompt shape, tool surfaces, subagent boundaries, context management, the whole stack. If you have only ever read agent tutorials, reading the docs for a real production Level 4 agent is the cheapest level-up I know.
Practical translation: do not dump every possible instruction into the system prompt. Expose short names and descriptions. Load the deep stuff on demand.
A scar from one of my own v1s. We added six tools, expecting the agent to compose them in interesting ways. It did not. It picked the wrong one, called it with the user’s entire question as the query, and kept looping. The tool name was the lie. It promised “search”, but the implementation could only handle keywords, and nothing in its description said so. We cut from six tools to two, rewrote the descriptions, and the loop stopped.
The bug was not reasoning. The bug was that the tool name lied.
Design the Tools Before the Agent
If you only remember one thing from this post: design tools first, agent second.
Before writing a single line, ask:
If the honest answer is “it talks nicely,” the user has no reason to use it. General-purpose LLMs already talk nicely. The differentiation comes from tools that connect to your system:
Tools are how an agent becomes useful in domains where a general LLM cannot act. They are also the surface where security, permissions, and auditing actually live — which is another reason “we’ll figure out tools later” is the wrong order.
A Reasonable Starting Architecture
If I were building a v1 today:
User
  ↓
Root agent (system prompt + context manager)
  ↓
Planner / agent loop
  ↓
Tool selector → Tool execution → Observation
  ↓
(loop until done or iteration cap)
  ↓
Final response
A good v1 has:
That’s it. Ship that, watch traces, then improve.
The traps I see most often in v1s:
What “Done” Looks Like
You’ll know you’ve built a Level 4 agent when:
If you cannot yet point at a trace that satisfies all four, keep going. That is the gap worth closing.
If you missed it, Part 1 covers the 4-level taxonomy and why most “AI agents” you encounter in real products are stuck at Level 1 or 2.
Tell me what your current v1 looks like — especially the tool list. Most of the interesting design happens there, and most of the bugs do too.
Gemini 3.5 Flash is generally available (GA), stable, and ready for scaled production use. As our most intelligent Flash model, it delivers sustained frontier performance in agentic execution, coding, and long-horizon tasks at scale.
This guide contains an overview of improvements, API changes, and migration guidance for Gemini 3.5 Flash.
New model
| Model | Model ID | Description |
|---|---|---|
| Gemini 3.5 Flash | gemini-3.5-flash |
Our most intelligent model for sustained frontier performance in agentic and coding tasks. |
Gemini 3.5 Flash supports the 1M token context window, 65k max output tokens, thinking, and the same set of tools and platform features as Gemini 3 Flash. Computer Use is not supported at this moment.
For complete specs, see the models overview. For pricing, see the pricing page.
Quickstart
Install the latest Google Gen AI SDK:
pip install -U google-genai
All code examples in this guide use the Interactions API. The Interactions API is the new standard primitive for building with Gemini, recommended for all new projects. It is optimized for agentic workflows, server-side state management, and complex multi-modal, multi-turn conversations. The GenerateContent API is also supported; the same configuration options and recommendations apply.
# Interactions API
from google import genai

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-3.5-flash",
    input="Explain how parallel agentic execution works in three sentences."
)
print(interaction.output_text)
# Generate Content API
from google import genai

client = genai.Client()

response = client.models.generate_content(
   model="gemini-3.5-flash",
   contents="How does AI work?",
)
print(response.text)
What’s new
high to medium. See New default effort level for details.low thinking: low is now significantly improved for code and agentic tasks that require fewer steps, offering strong quality at lower latency and cost. Behavioral changes
New default effort level: medium
The default thinking effort is now medium, changed from high in Gemini 3 Flash Preview. medium yields very good results across a wide range of tasks while being faster and more cost-efficient. For complex problems, high encourages the model to think more deeply.
| Effort level | When to use |
|---|---|
minimal |
Optimized for response speed. Chat-like use cases, quick factual answers, simpler tool calls. |
low |
Code and agentic tasks that require lower latency and fewer steps. Also works well for analysis and writing tasks that require some thinking. |
medium (default) |
Best quality for most tasks. Recommended for complex code and agentic use cases. |
high |
Maximizes the model’s ability to think and use tools. Best for complex reasoning, hard math, and the most difficult code or agent tasks. Allows extended thoughts and function calls. |
To override the default, set thinking_level in your config:
from google import genai

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-3.5-flash",
    input="Prove that the square root of 2 is irrational.",
    generation_config={"thinking_level": "high"},
)
print(interaction.output_text)
Tip: Start with medium, it provides the best quality for the vast majority of tasks. Try low for a faster, cheaper experience with strong quality. Switch to high for complex reasoning, hard math, or difficult coding challenges. Use minimal to optimize for speed in simple queries.
Thought preservation
The model maintains intermediate reasoning across multi-turn conversations automatically. When present in the conversation history, reasoning context carries forward, which improves performance on complex multi-step tasks
like iterative debugging and code refactoring. No API changes needed:
contents. The SDKs handle this automatically. Parameter updates and best practices in Gemini 3.x
The following apply to all Gemini 3.x models, including Gemini 3.5 Flash.
temperature, top_p, top_k: we strongly recommend not changing the default values. Gemini 3’s reasoning capabilities are optimized for the default settings.thinking_level instead of thinking_budget.id, name, and response count must match the preceding calls.See the sections below for how to update your code.
Sampling parameters (no longer recommended)
temperature, top_p, and top_k are no longer recommended for all Gemini 3.x models. Gemini 3’s reasoning capabilities are optimized for the default settings. Remove these parameters from all requests.
# ⚠️ Remove these parameters (not recommended)
generation_config = {
    "temperature": 0.7,
    "top_p": 0.9,
    "top_k": 40,
}
To ensure determinism, we recommend defining a system instruction with explicit rules for your specific use case.
thinking_budget (no longer recommended)
The raw numeric thinking_budget parameter is no longer recommended across all Gemini 3.x models. Use the thinking_level string enum instead.
# ⚠️ Before (not recommended)
generation_config = {
    "thinking": {"thinking_budget": 7500},
}

# ✅ After
generation_config = {
    "thinking": {"thinking_level": "medium"},
}
Available values: minimal, low, medium (default), and high.
Function calling: strict response matching
The Interactions API already errors on mismatched function responses. The GenerateContent API does not yet error, but mismatched responses cause the model to return empty responses with finish_reason: STOP in most cases. Always follow these conventions:
| Requirement | Details |
|---|---|
Include id
|
Every FunctionResponse must include the id from the corresponding FunctionCall
|
Match name
|
The name in the response must match the name in the call |
| Match counts | Return exactly one FunctionResponse for each FunctionCall received |
# ✅ Include matching call_id and name in the function_result
final_interaction = client.interactions.create(
    model="gemini-3.5-flash",
    previous_interaction_id=interaction.id,
    tools=[my_tool],
    input=[{
        "type": "function_result",
        "name": fc_step.name,
        "call_id": fc_step.id,
        "result": [{"type": "text", "text": json.dumps(result)}],
    }],
)
Multimodal function responses
We often see clients provide images outside function response. This can lead to unexpected model behavior (e.g. thought leakage) and result in lower quality outputs. Follow the recommendation in Multimodal Function Responses API docs instead and include multimodal content in the function response parts that you send to the model. The model can process this multimodal content in its next turn to produce a more informed response.
# ✅ Include multimodal content in the function response
final_interaction = client.interactions.create(
    model="gemini-3.5-flash",
    previous_interaction_id=interaction.id,
    input=[
        {
            "type": "function_result",
            "name": tool_call.name,
            "call_id": tool_call.id,
            "result": [
                {"type": "text", "text": "instrument.jpg"},
                {
                    "type": "image",
                    "mime_type": "image/jpeg",
                    "data": base64_image_data,
                },
            ],
        }
    ],
)
Inline instructions in function responses
We often see clients provide additional instructions along with function responses as subsequent Parts. This can lead to unexpected model behavior (e.g. thought leakage) and result in lower quality outputs. Instead, append any extra instructions to the end of the function response text separated by two newlines.
# ✅ Append inline instructions to the end of the function response separated by two newlines
result_text = f"{json.dumps(result)}nn<your inline instructions>"

final_interaction = client.interactions.create(
    model="gemini-3.5-flash",
    previous_interaction_id=interaction.id,
    tools=[my_tool],
    input=[
        {
            "type": "function_result",
            "name": fc_step.name,
            "call_id": fc_step.id,
            "result": [{"type": "text", "text": result_text}],
        }
    ],
)
Reducing unnecessary tool calls
If you experience an overuse of tool calls, two techniques help minimize them:
medium, low, or minimal): Higher thinking levels encourage the model to use more tools to explore and verify, so lowering the level can reduce tool calls.Add a system instruction: If overuse persists after adjusting the thinking level, consider a prompt that restricts tool usage. For example:
You have a limited action budget of <n> tool calls. Use them efficiently.
Migration checklist
Note: Automate this migration with a coding agent. If you use a coding agent that supports skills (like Antigravity), install the Gemini Interactions API skill and run:
/gemini-interactions-api migrate my app to Gemini 3.5 Flash
We strongly recommend updating to google-genai SDK v2.0.0 or later. This version introduces breaking changes to the Interactions API. See the breaking changes migration guide for details.
Migrate from Gemini 3 Flash Preview
gemini-3-flash-preview → gemini-3.5-flash
temperature, top_p, top_k from your config (no longer recommended).thinking_budget with thinking_level.id and matching name to all FunctionResponse parts.high → medium; verify quality, speed, and cost.medium, low, or minimal); add a system instruction to constrain tool usage if overuse persists. Migrate from Gemini 2.5
All of the above, plus:
thinking_level: "medium" or "high" with simpler prompts instead.media_resolution_high setting to ensure continued accuracy. Migrating to Gemini 3 defaults may also increase token usage for PDFs but decrease it for video; if requests exceed the context window, explicitly reduce the media_resolution. See the media resolution docs for details. Gemini 3 family features
Gemini 3.5 Flash inherits all Gemini 3 family capabilities except Computer Use. Features introduced in Gemini 3 that carry forward:
Next steps