AMD kendi sınırlarını aştı: Ryzen 9 9950X3D2 tanıtıldı
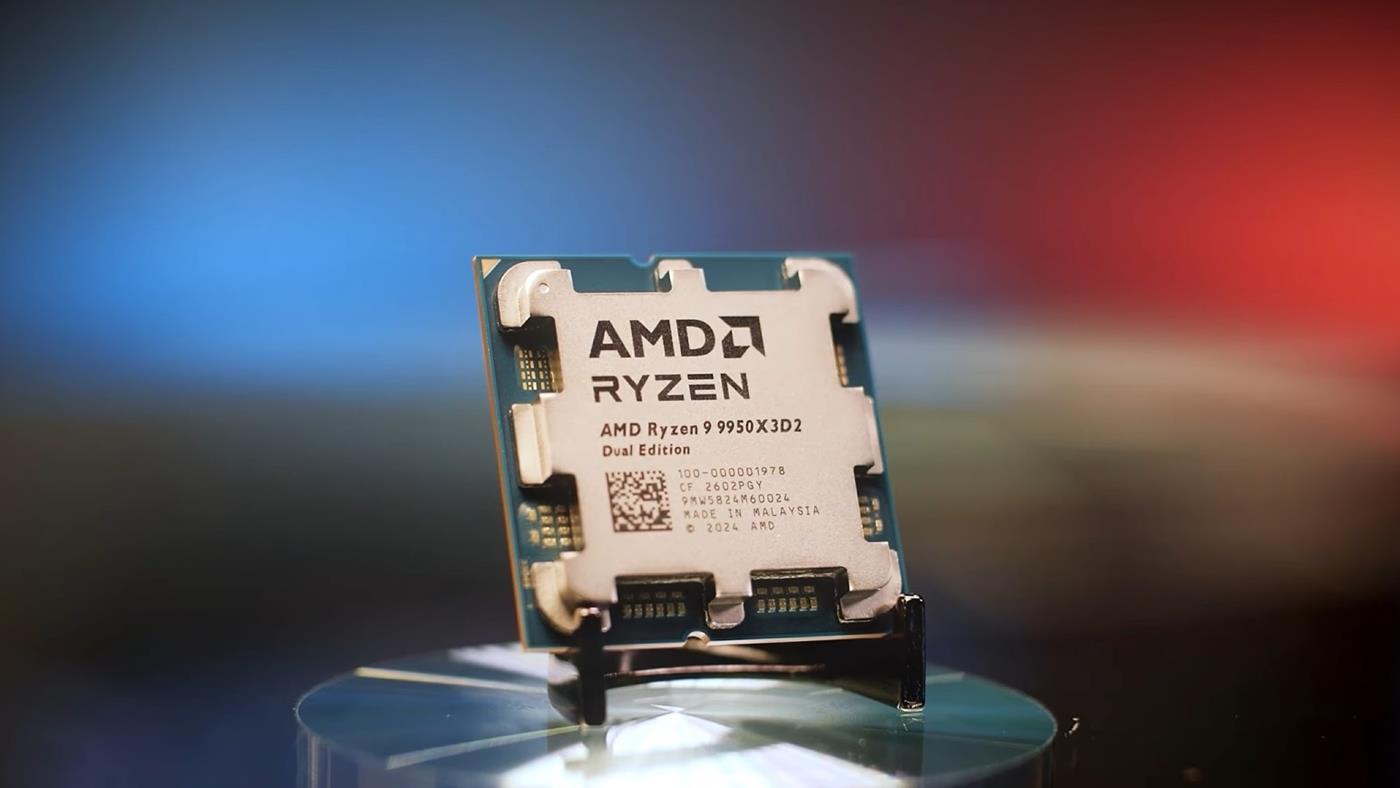
 AMD, Zen 5 mimarili Ryzen 9 9950X3D2 Dual Edition işlemciyi tanıttı. Çift CCD’de 3D V-Cache ile donatılan işlemci, 208 MB önbellek ve 200 W TDP ile bu bahar satışa çıkacak.
 AMD, Zen 5 mimarili Ryzen 9 9950X3D2 Dual Edition işlemciyi tanıttı. Çift CCD’de 3D V-Cache ile donatılan işlemci, 208 MB önbellek ve 200 W TDP ile bu bahar satışa çıkacak.
 Android 17 beta artık Google Pixel telefonlarla sınırlı değil. Motorola, OnePlus ve Oppo dahil olmak üzere farklı markalardan birçok üçüncü parti telefon Android 17 beta güncellemelerini alacak.
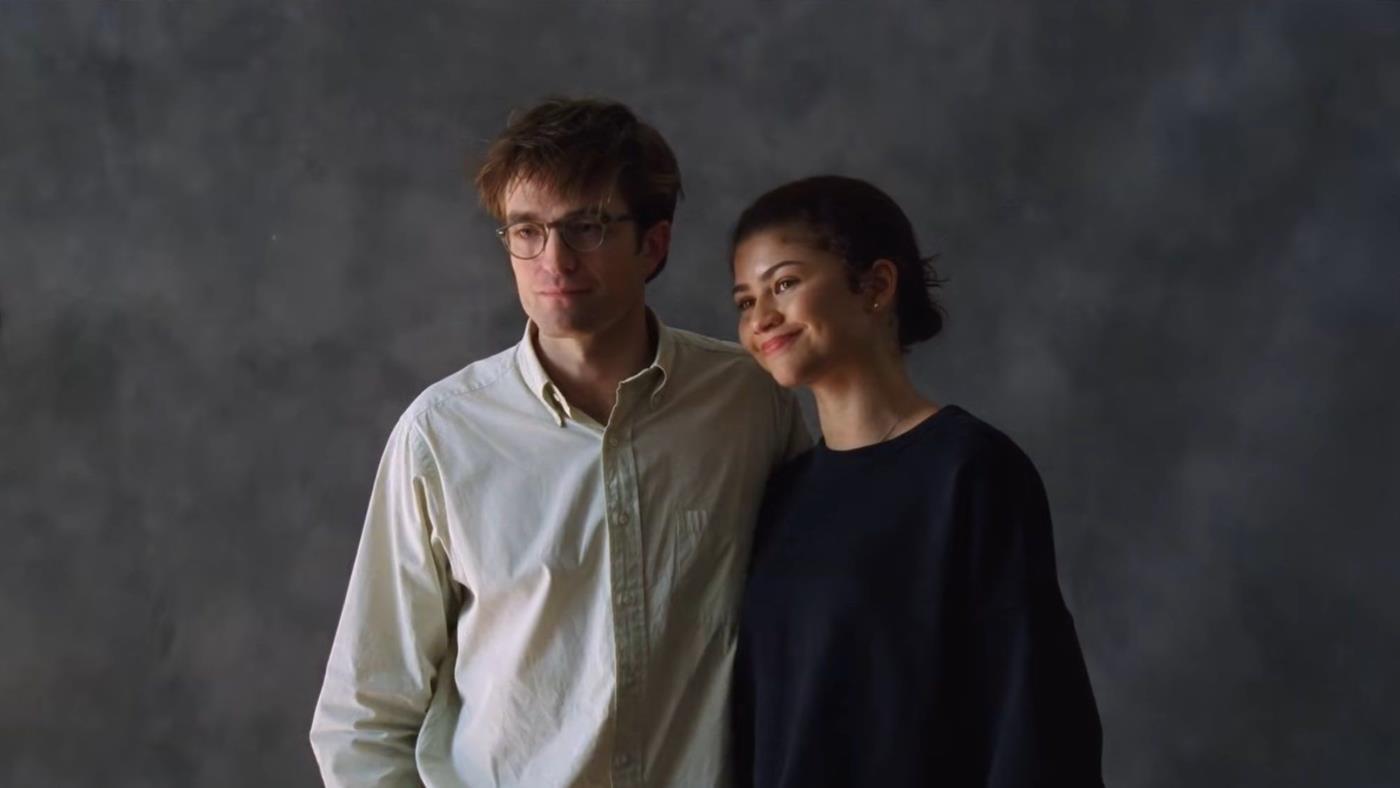
 Michael Jackson biyografisi, yeni Super Mario filmi, Robert Pattinson ve Zendaya’lı Drama, Lee Cronin’den Mumya… Nisan ayında sinemaseverleri dikkat çekici filmler bekliyor.
The Standard SaaS Pricing Playbook Is Broken for Agents
Traditional SaaS pricing is built around one assumption: humans are the users.
Limit the seats. Lock certain features behind a paywall. Give them a taste, then charge for the good stuff.
This works when a human is sitting at a dashboard, hitting a wall, and deciding whether to upgrade. They feel the friction directly. They know what they’re missing.
But AI agents don’t feel friction. They don’t see a locked feature and think “I should ask my boss to upgrade.” They either have access or they don’t — and if they don’t, they just fail silently or tell the user they can’t help.
We needed a completely different pricing model. Here’s what we built and why.
The Insight: Read vs. Write Is the Natural Line
When we started designing Nexus’s agent tier, we asked one question: what does an agent need to prove its value before a human commits to paying?
The answer was clear: reading data.
An agent needs to browse contacts, read orders, check inventory, and search across everything. None of that costs the business anything. It’s pure intelligence gathering — exactly what an agent needs to demonstrate it’s useful.
Writing is different. Creating orders, sending messages to customers, updating records — these have real-world consequences. They’re worth paying for.
Read = explore and prove value. Write = act and create value.
That’s our free/paid line.
How the Tiers Work
Free ($0/mo)
The free tier is genuinely useful. An agent on free can answer questions, generate reports, find customers, check stock levels, and summarize order history. A business can run an AI assistant on free indefinitely if all they need is intelligence.
Starter ($99/mo)
Growth ($199/mo) and Scale ($599/mo)
Scale up agents, messages, and unlock AI features (sentiment analysis, transcription, embeddings).
The Conversion Funnel Nobody Talks About
Here’s the thing about this model: the agent does the selling.
Traditional SaaS acquisition:
With agent-native pricing:
llms.txt or .well-known/mcp.json
The agent is the SDR, the sales engineer, and the onboarding specialist all at once. No demos. No cold calls.
Why Not Just Limit by Feature?
We considered feature-gating: lock CRM behind Pro, lock shipping behind Enterprise.
The problem: feature-gating creates fragmentation. An agent that can access CRM but not orders can’t answer “is this customer’s order delayed?” — a basic question. Partial access makes the agent look incompetent, not the pricing tier.
Read/write gating is different. A read-only agent is still coherent. It has a complete picture of the business. It just can’t change anything yet.
The Safety Argument
There’s another reason to gate writes: safety.
When an AI agent has write access to your production data, you want it to have earned that trust. A business that’s been watching what the agent reads and how it behaves for a few weeks is in a much better position to say “yes, I trust this agent to create orders and send messages.”
Read-only free tier isn’t just a pricing decision. It’s a trust-building mechanism.
The Bigger Takeaway
If you’re building SaaS in 2026, agents are coming for your product regardless of whether you plan for them. The question is whether you build a pricing model that works with agents or fights them.
We chose to work with them.
Nexus is live at nexus.aiforstartups.io. Agents can self-register at nexus-docs.aiforstartups.io/api/ai-agents-mcp. Free forever, no credit card required.
If you use GitHub Copilot Free, Pro, or Pro+, your code is being used to train AI models starting April 24. Not just your public repos. Your interaction data, which includes snippets from whatever youre working on, including private repositories.
And its opt-out, not opt-in. Meaning its already enabled unless you go turn it off.
What Actually Changed
GitHub quietly updated their Copilot interaction data usage policy on March 25. The key change: they will now use interaction data from individual Copilot users to train and improve AI models.
Interaction data includes:
Thats a lot more than “we look at what you accept to improve suggestions.” Thats your file structure, your naming conventions, the comments you write, the way you navigate your codebase. For anyone working on proprietary software, this is your companys intellectual property flowing into a training pipeline.
The Private Repo Problem
Heres the part that caught my attention. When you use Copilot in a private repository, it sends code context to generate suggestions. Thats expected. But now that context, your private code that was sent for suggestion generation, can be used for model training.
GitHub is careful to say they dont access private repositories “at rest.” But the moment you open a file and Copilot activates, that code becomes interaction data. And interaction data is now fair game.
This creates a weird middle ground. Your private repo is still private. But the code you actually work on in that repo is not. The distinction between “stored code” and “interaction data” is doing a lot of heavy lifting in this policy.
The Opt-Out Problem
The setting is opt-out by default. GitHub frames the enabled state as “You will have access to the feature,” making data donation sound like a perk rather than a cost. Multiple users on Hacker News reported finding the setting enabled when they expected it to be disabled. At least one person claimed it re-enabled itself after being turned off, though that hasnt been confirmed.
You can disable it in Settings > Copilot > Privacy. But how many of the millions of Copilot Free users will actually do that? The default state is what matters for the vast majority of users, and the default is “send your data.”
Enterprise and Business accounts are excluded from this policy, which is smart from a legal perspective. But it creates an asymmetric situation: if an individual developer contributes to a corporate repo using a personal Copilot Free account, that interaction data could still enter the training pipeline even if the company has enterprise protections.
The Credential Risk Nobody Mentions
This one genuinely concerns me. Copilot processes whatever is in your working directory. There is no built-in mechanism to exclude sensitive files. If you have API keys, database credentials, or secrets in your project (even if theyre in .env files that are gitignored), Copilot can still see them during active use because it reads your local files, not just whats in git.
Now that interaction data is used for training, theres a theoretical path from your local .env file to a training dataset. GitHub would presumably filter these out, but the policy doesnt explicitly address credential handling in interaction data.
What Mario Rodriguez Said
GitHubs VP of Product, Mario Rodriguez, explained the reasoning: incorporating interaction data showed “meaningful improvements, including increased acceptance rates in multiple languages.” They tested this internally with Microsoft employee data first, saw positive results, and decided to expand it to all individual users.
The technical argument makes sense. Models improve with more diverse training data. The question isnt whether this makes Copilot better. Its whether users were adequately informed and given meaningful choice.
What You Should Do
If you want to opt out:
If youre working on anything proprietary or sensitive, this is worth the 30 seconds. The improvement to Copilots suggestions is marginal for you as an individual. The risk to your companys IP is not.
For teams, if youre not on Business or Enterprise, you should be. Individual accounts on corporate repos are the gap in this policy, and its a gap that could matter.
The Bigger Picture
This isnt unique to GitHub. Every AI tool faces the same tension: models need data to improve, and the best data comes from real usage. The question is always about consent, defaults, and transparency.
GitHubs approach, opt-out by default with a settings toggle, is the same playbook every major platform uses. Its legal. Its probably GDPR-compliant if they handle consent flows correctly in the EU. But its not what informed consent looks like.
The developers who read the blog post and find the setting are fine. The millions who dont read blog posts and dont check their privacy settings are the ones this policy is designed around. And that asymmetry is the whole point.
The idea for this project came up when I discovered React Doctor. I really liked their concept and thought about a way to bring this kind of auditing tool outside of the React ecosystem. That’s how I created Web Doctor.
Web Doctor is a CLI tool that analyzes HTML, CSS, and JS code, looking for performance improvement opportunities, accessibility enhancements, and critical security issues.
Here are some of the checks Web Doctor currently performs:
<body/> contains the minimum required semantic structure (like <header/>, <nav/>, <main/>, and <footer/>).!important in CSS.eval().The package is still under active development, and my goal is to turn it into a true static code consulting tool. Here are the next features I plan to implement:
<h1/> straight to an <h3/>).<div/> tags compared to structural/semantic tags.If you have any ideas for new features, or if you just want to share your thoughts and feedback on the project, please let me know in the comments!
The Resolv USR Exploit: How a Missing Max-Mint Check Let an Attacker Print $25M From $100K
A deep dive into the March 22 Resolv Labs hack — the anatomy of a two-step minting flaw, compromised key infrastructure, and why on-chain guardrails are non-negotiable for stablecoin protocols.
TL;DR
On March 22, 2026, an attacker exploited Resolv Labs’ USR stablecoin minting system by compromising a privileged signing key stored in AWS KMS. Using the requestSwap() → completeSwap() flow, they deposited ~$100K–$200K in USDC and minted 80 million unbacked USR tokens — a 400–500x over-mint. The attacker extracted ~$25M in ETH within 17 minutes, crashing USR from $1.00 to $0.025. The root cause: zero on-chain validation between collateral deposited and tokens minted.
The Protocol Design
Resolv is a delta-neutral stablecoin protocol. USR maintains its dollar peg through a collateral pool of ETH, staked ETH, and Bitcoin, hedged with perpetual futures. A second token, RLP (Resolv Liquidity Pool), acts as a junior tranche absorbing losses before USR holders take any hit.
At peak, Resolv held over $500M in TVL and had raised $10M from Coinbase Ventures, Maven 11, and Animoca Brands. The protocol was integrated into Morpho, Aave, Euler, and Curve — deep tentacles across DeFi’s lending and DEX infrastructure.
But TVL had been hemorrhaging before the exploit. USR’s market cap dropped from ~$400M in early February to ~$100M by mid-March — a 75% contraction in weeks.
The Minting Architecture (And Its Fatal Flaw)
USR minting uses a two-step off-chain approval pattern:
Step 1: requestSwap()
User deposits USDC into the USR Counter contract. This creates a pending minting request on-chain.
Step 2: completeSwap()
An off-chain service holding a privileged key (the SERVICE_ROLE) calls back to finalize the mint, specifying how much USR to issue.
The critical problem: The smart contract enforced a minimum USR output but no maximum. There was:
The SERVICE_ROLE was a plain EOA (externally owned address) — not a multisig. Whatever amount it signed off on, the contract would mint. The admin role was a multisig, but the service role — the one with actual minting power — was not.
The Trust Model Was Inverted
What the contract checked:
  ✅ Valid signature from SERVICE_ROLE
  ✅ Minimum output amount met

What the contract didn't check:
  ❌ Deposited amount vs. minted amount ratio
  ❌ Maximum mint per transaction
  ❌ Maximum mint per time window
  ❌ Total supply cap
The entire security model rested on a single assumption: the SERVICE_ROLE key would never be compromised. That’s not defense in depth — it’s a single point of failure.
The Attack: Step by Step
Phase 1: Infrastructure Compromise
The attacker gained access to Resolv’s AWS Key Management Service (KMS) environment where the privileged signing key was stored. With control over the KMS environment, they could use Resolv’s own minting key to authorize arbitrary operations.
Phase 2: The Over-Mint
Armed with the signing key, the attacker executed two primary minting transactions:
Total: 80 million unbacked USR from ~$100K–$200K in deposits.
Phase 3: The Cashout
The attacker converted USR → wstUSR (wrapped staked USR) to move into a less immediately liquid but more fungible derivative, then:
The entire cashout took 17 minutes. By the time USR hit $0.025 on Curve’s USR/USDC pool, the attacker was already in ETH.
Phase 4: Failed Follow-Up
On-chain records show the attacker attempted additional mints after the initial 80M, but Resolv paused the protocol before more damage could be done. This underscores why automated circuit breakers are essential.
The Blast Radius
The damage extended far beyond Resolv:
| Protocol | Exposure | Impact |
|---|---|---|
| Gauntlet (Morpho) | ~$7.5M across USDC Core/Frontier vaults | Deposits paused, high utilization |
| Steakhouse Financial | Dedicated Resolv USR vaults | Confirmed no direct exposure in main vaults |
| Euler Labs | Under investigation | Measures taken to isolate risk |
| Aave | Zero exposure | Resolv participated as LP only |
| Curve pools | USR/USDC liquidity drained | Severe impermanent loss for LPs |
The contagion spread through composability — the exact property that makes DeFi powerful also amplifies exploit damage.
Root Cause Analysis: Three Layers of Failure
Layer 1: Missing On-Chain Invariants
The smart contract was a blank check. Any valid SERVICE_ROLE signature could mint any amount. This is the most fundamental failure — the contract should have enforced:
// What should have existed
require(
    mintAmount <= depositAmount * MAX_MINT_RATIO,
    "Mint exceeds collateral ratio"
);

require(
    totalSupply() + mintAmount <= SUPPLY_CAP,
    "Supply cap exceeded"
);

require(
    recentMints[block.timestamp / WINDOW] + mintAmount <= WINDOW_CAP,
    "Rate limit exceeded"
);
Layer 2: Single-Key Infrastructure
The SERVICE_ROLE was a single EOA, not a multisig. A protocol with $500M TVL had a single private key controlling unlimited minting. Even if the key were a multisig, the lack of on-chain bounds would still be dangerous — but at least it would require compromising multiple signers.
Layer 3: Cloud Key Management
Storing the minting key in AWS KMS is standard practice, but it created a blast radius where cloud infrastructure compromise = unlimited token minting. There was no:
Defensive Patterns: Building Mint-Safe Stablecoins
Pattern 1: On-Chain Mint Bounds
Every minting function should enforce hard limits regardless of who calls it:
uint256 public constant MAX_MINT_PER_TX = 1_000_000e18;     // 1M per tx
uint256 public constant MAX_MINT_PER_HOUR = 10_000_000e18;   // 10M per hour
uint256 public constant MAX_MINT_RATIO = 105;                 // 105% of deposit (5% tolerance)

mapping(uint256 => uint256) public hourlyMints;

function completeSwap(
    uint256 requestId,
    uint256 mintAmount
) external onlyServiceRole {
    SwapRequest memory req = requests[requestId];
    uint256 hour = block.timestamp / 1 hours;

    require(mintAmount <= MAX_MINT_PER_TX, "TX_LIMIT");
    require(hourlyMints[hour] + mintAmount <= MAX_MINT_PER_HOUR, "HOURLY_LIMIT");
    require(mintAmount * 100 <= req.depositAmount * MAX_MINT_RATIO, "RATIO_EXCEEDED");

    hourlyMints[hour] += mintAmount;
    // ... proceed with mint
}
Pattern 2: Timelock + Circuit Breaker
Large mints should be time-delayed with a cancellation window:
function completeSwap(...) external onlyServiceRole {
    if (mintAmount > INSTANT_MINT_THRESHOLD) {
        // Queue for 1-hour delay, allowing guardian cancellation
        pendingMints[requestId] = PendingMint({
            amount: mintAmount,
            executeAfter: block.timestamp + 1 hours,
            cancelled: false
        });
        emit LargeMintQueued(requestId, mintAmount);
        return;
    }
    // Instant mint for small amounts
    _executeMint(requestId, mintAmount);
}
Pattern 3: Oracle-Backed Ratio Validation
Even with off-chain signing, the contract should validate against an independent price oracle:
function completeSwap(uint256 requestId, uint256 mintAmount) external {
    uint256 depositValue = getOraclePrice(USDC) * req.depositAmount;
    uint256 mintValue = mintAmount; // USR is pegged 1:1

    require(
        mintValue <= depositValue * 110 / 100, // 10% tolerance
        "Mint exceeds oracle-validated deposit value"
    );
}
Pattern 4: Multi-Sig + MPC for Minting Roles
Critical protocol operations should require multiple independent signers:
Pattern 5: Real-Time Anomaly Detection
Deploy on-chain monitoring that triggers automatic pauses:
Lessons for Protocol Developers
1. Never Trust Off-Chain Alone
If your smart contract’s security depends entirely on an off-chain component behaving correctly, your smart contract is not secure. On-chain invariants are your final line of defense.
2. The “It Can’t Be Compromised” Key Will Be Compromised
Every key management system has been compromised at some point — AWS KMS, HSMs, hardware wallets. Design your contracts to limit damage even when keys are stolen.
3. Composability Amplifies Everything
When your token is integrated into lending markets, yield vaults, and DEX pools, an exploit doesn’t just affect your protocol — it cascades through DeFi. Build with the assumption that your worst-case scenario affects everyone who touches your token.
4. TVL Decline Is a Signal
Resolv’s TVL dropped 75% in the weeks before the exploit. While this may be coincidental, rapid TVL outflows can indicate insiders aware of vulnerabilities, or simply a protocol losing confidence. Monitor TVL trends as a risk indicator.
5. Audit the Trust Boundaries, Not Just the Code
The Resolv contracts were audited. The code worked exactly as designed. The vulnerability was in the trust architecture — the assumption that a single key stored in cloud infrastructure would never be compromised. Audits must evaluate the full system, including off-chain components and key management.
Timeline
| Time (UTC) | Event |
|---|---|
| ~02:21 AM, Mar 22 | First 50M USR minted |
| ~02:25 AM | Second 30M USR minted |
| ~02:30 AM | USR begins dumping on Curve, KyberSwap |
| ~02:38 AM | USR hits $0.025 on Curve USR/USDC pool |
| ~02:45 AM | Attacker begins ETH conversion |
| ~03:00 AM | Additional mint attempts detected (failed) |
| ~04:00 AM | Resolv pauses all protocol functions |
| Later Mar 22 | Resolv issues public statement, offers 10% bounty |
Conclusion
The Resolv exploit is a masterclass in what happens when protocol security depends on a single off-chain assumption. The smart contracts were audited and worked as designed — but “as designed” included zero on-chain safeguards against the most obvious attack vector: a compromised minting key.
For every stablecoin protocol builder reading this: your minting function is your protocol’s nuclear launch code. Treat it accordingly. On-chain bounds, multi-sig requirements, rate limits, timelocks, and anomaly detection are not optional — they’re the difference between a protocol that survives a key compromise and one that prints $25M for an attacker in 17 minutes.
Follow for more DeFi security research, vulnerability analysis, and smart contract auditing insights.
Tags: #defi #security #smartcontracts #solidity #web3 #blockchain #ethereum #stablecoin

Terminal autocomplete hasn’t really evolved.
It’s still:
It’s fast, sure. But it’s not helpful.
The problem with terminal autocomplete
Most shells do one thing well:
👉 complete what you already started typing
That’s it.
If you type:
dokcer logs
You get nothing.
If you type:
docker rec
You also get nothing.
Even though:
docker
docker logs 100 times beforeThe shell doesn’t care.
It doesn’t learn.
It doesn’t adapt.
It just matches prefixes.
What I wanted instead
I wanted something that:
So I built a different kind of autocomplete.
A better autocomplete (Agensic Autocomplete)
Instead of treating commands as static strings, I treat them as patterns.
That enables things like:
dokcer → docker
docker records → docker logs
And importantly:
👉 it stays local-first and fast

AI is only used as a fallback when your history isn’t enough.
Most of the time, suggestions come from:
It feels closer to an IDE than a shell.
But autocomplete wasn’t the real problem
Once I started using AI agents in the terminal (Codex CLI, Claude Code, etc…), I realized something else:
Autocomplete helps you write commands.
But it doesn’t help you understand what actually happened.
The missing layer: command provenance (Agensic Provenance)
When an agent runs commands for you, things get blurry fast.
Shell history doesn’t track commands ran by agents, it’s as if they are acting in a black box.
So I added a provenance layer.
Every command gets classified and tracked:
HUMAN_TYPEDAI_SUGGESTED_HUMAN_RANAI_EXECUTEDAnd for agent-executed commands, there’s cryptographic proof.
So instead of guessing:
👉 you get a clear, auditable timeline of what actually ran and why

Then came sessions (Agensic Sessions)
The next problem showed up quickly:
Even if you know what ran…
👉 you still can’t easily reconstruct the full session
So I added session tracking.
Now you can:

And the most useful feature:
Time travel for your repo
You can jump back to the exact state your repository was in at a specific moment.
Not “roughly what I remember”
Not “git reflog archaeology”
👉 the exact state tied to a session checkpoint
Putting it together
What started as “better autocomplete” turned into something else:
Because once AI agents enter the terminal:
👉 speed is no longer the bottleneck
👉 understanding is
Final thoughts
Terminal tooling hasn’t really caught up with how we work today.
We’re no longer:
We’re:
And without visibility, that breaks down quickly.
If you’re curious
I open sourced the project here:
👉 https://github.com/Alex188dot/agensic
Would love feedback, especially from people using AI agents in the terminal.
Beyond the API Call: Engineering EloDtx, the Deep Learning Core of Baeyond
Most “AI apps” are just wrappers. When we started building the new Baeyond, we realized that to achieve true “Identity Authenticity,” we had to move the intelligence to the core.
The EloDtx Architecture:
The Data Pipeline: We feed real-time signals—facial biometrics, verified geolocation, and behavioral clusters—directly into the EloDtx engine.
Intent-Driven Modeling: We’ve moved away from simple K-nearest neighbors matching. EloDtx utilizes neural behavioral clustering to understand the why behind a connection signal.
Safety as a Service: By combining Google Cloud Vision with custom NLP pipelines, we’ve created a predictive moderation layer that identifies harassment and scam patterns before they reach the user.
Infrastructure: EloDtx isn’t a silo. It’s a modular service connected to SynDockOS for proactive monitoring and horizontal scaling.
We’re building an API-first infrastructure where every match is a result of high-integrity data processing.
Are you still building with “Black Box” AI, or are you training your own decision engines? Let’s talk about the EloDtx stack in the comments.


Expert Analysis: The EBM-MLP Dichotomy in Out-of-Distribution and Discontinuous Regimes
Fundamental Mechanisms and Behavioral Divergence
The divergence between Energy-Based Models (EBMs) and Multi-Layer Perceptrons (MLPs) hinges on their core mechanisms for handling variable configurations and extrapolation. EBMs associate a scalar energy to variable configurations, minimizing this energy for both inference and learning. This process inherently avoids assumptions of continuity and linearity, enabling EBMs to handle discontinuous distributions and unsampled kinks without imposing artificial structures. In contrast, MLPs rely on piecewise linear extrapolation near training data boundaries due to ReLU activation, intrinsically assuming continuity and linearity. This architectural difference manifests in distinct observable effects: EBMs exhibit an absence of spandrels in out-of-distribution (OOD) regions and robustly handle discontinuities, whereas MLPs produce spandrels and artificial kinks in OOD regions.
Critical Constraints and Their Impact
Two key constraints amplify the behavioral divergence between EBMs and MLPs:
Instability Points: Where Divergence Becomes Critical
The divergence between EBMs and MLPs becomes most pronounced at two instability points:
Underlying Physics and Logic
The behavioral differences between EBMs and MLPs are rooted in their underlying mechanics:
Analytical Pressure: Why This Matters
The unique capabilities of EBMs in handling OOD data and discontinuous distributions are not merely theoretical distinctions but have practical implications. If the field continues to rely on MLPs in scenarios where their assumptions of continuity and linearity are violated, it risks suboptimal or erroneous predictions, particularly in critical applications such as healthcare, autonomous systems, and financial modeling. Recognizing the distinct advantages of EBMs is essential for advancing machine learning techniques that prioritize robustness and reliability in uncertain or unexplored domains.
Intermediate Conclusions
Final Synthesis: The Case for EBMs
The EBM-MLP dichotomy underscores the need for a nuanced understanding of model behaviors in OOD and discontinuous regimes. While MLPs remain a cornerstone of machine learning, their limitations in these areas highlight the value of EBMs as a complementary or alternative technique. By avoiding assumptions of continuity and linearity, EBMs offer a robust framework for handling complex, real-world distributions. Failing to recognize and leverage this distinction risks perpetuating suboptimal practices in critical applications. As the field advances, the unique capabilities of EBMs must be integrated into the broader machine learning toolkit to ensure reliability and robustness in an increasingly uncertain data landscape.
Comparative Analysis of Energy-Based Models (EBMs) and Multi-Layer Perceptrons (MLPs) in Handling Out-of-Distribution Data and Discontinuous Distributions
Core Mechanisms and Behavioral Divergence
The fundamental distinction between Energy-Based Models (EBMs) and Multi-Layer Perceptrons (MLPs) lies in their core mechanisms for modeling data distributions. EBMs operate by assigning a scalar energy to each variable configuration, where low energy reflects compatibility with the learned distribution. This energy minimization principle drives both inference and learning, ensuring that correct configurations are favored while incorrect ones are penalized. Critically, EBMs make no assumptions about continuity or linearity, enabling them to robustly handle discontinuous distributions and unsampled regions. In contrast, MLPs rely on piecewise linear behavior due to ReLU activations, which inherently assume continuity and linearity. This architectural choice leads MLPs to perform linear extrapolation near training data boundaries, often resulting in the formation of spandrels—unintended, overconfident predictions in out-of-distribution (OOD) regions.
Constraints Shaping Model Behavior
Several constraints amplify the behavioral differences between EBMs and MLPs. First, limited training data sampling, particularly in discontinuous or kinked regions, disproportionately affects MLPs due to their assumption-driven nature. Second, architectural assumptions play a pivotal role: MLPs enforce continuity and linearity, while EBMs remain assumption-agnostic, directly influencing their OOD handling capabilities. Third, dense querying is essential to expose these differences, especially near training data boundaries where extrapolation behaviors diverge. Lastly, a fair comparison requires equivalent model size and training data to isolate the impact of architectural differences.
Instability Points: Where Models Diverge
The divergence between EBMs and MLPs becomes most pronounced in two critical scenarios:
Internal Processes and Observable Effects
The internal processes of EBMs and MLPs directly translate into observable effects that highlight their strengths and limitations:
System Instability and Its Implications
The system becomes unstable in regions where:
These instability points underscore the critical trade-offs between the two models. MLPs, while powerful in interpolative regimes, falter in extrapolative scenarios due to their assumption-driven nature. EBMs, though potentially underfitting with limited data, offer a more robust alternative by avoiding unwarranted assumptions.
Physics/Mechanics/Logic of Processes
The behavioral differences between EBMs and MLPs are rooted in their underlying mechanics:
Intermediate Conclusions and Analytical Pressure
The comparative analysis reveals that EBMs and MLPs represent fundamentally different approaches to modeling data distributions. EBMs, with their assumption-agnostic nature, offer distinct advantages in handling OOD data and discontinuous distributions, making them a valuable alternative to MLPs in scenarios where robustness is paramount. If the unique capabilities of EBMs remain unrecognized, the field risks perpetuating the use of MLPs in applications where their assumptions lead to suboptimal or erroneous predictions, particularly in critical domains such as healthcare, finance, and autonomous systems. Recognizing and leveraging the strengths of EBMs is essential to advancing the robustness and reliability of machine learning models in real-world applications.
Expert Analytical Section: EBM vs. MLP Behavior in OOD and Discontinuous Distributions
Fundamental Mechanisms and Their Implications
The divergence in behavior between Energy-Based Models (EBMs) and Multi-Layer Perceptrons (MLPs) in handling out-of-distribution (OOD) data and discontinuous distributions stems from their core mechanisms. EBMs associate a scalar energy with variable configurations, where low energy signifies compatibility with the learned distribution. This energy minimization framework allows EBMs to remain agnostic to unsampled regions, avoiding the imposition of artificial structures. In contrast, MLPs, with their ReLU activations, exhibit piecewise linear behavior, leading to linear extrapolation near training data boundaries. This extrapolation results in the formation of spandrels—unintended, overconfident predictions in OOD regions.
Causal Link: The assumption-driven nature of MLPs (continuity and linearity) directly causes the introduction of artificial kinks or linear structures in unsampled regions, while EBMs’ agnosticism prevents such artifacts. This fundamental difference in handling discontinuities underscores the distinct value of EBMs in scenarios where data distributions are inherently discontinuous or sparsely sampled.
Constraints Shaping Behavioral Differences
Several constraints amplify the behavioral divergence between EBMs and MLPs:
Intermediate Conclusion: The constraints highlight that MLPs’ performance degrades more significantly in OOD and discontinuous regions due to their inherent assumptions, while EBMs maintain robustness by avoiding such assumptions.
Instability Points and Observable Effects
Instability in both models manifests in specific regions:
Unsampled Discontinuities:
| Model | Internal Process | Observable Effect |
| MLP | Piecewise linear extrapolation near boundaries | Formation of spandrels in OOD regions |
| MLP | Assumption of continuity and linearity | Artificial kinks in unsampled discontinuities |
| EBM | Energy minimization without continuity assumptions | Absence of spandrels and artificial structures |
Causal Link: The internal processes of MLPs and EBMs directly determine their observable effects in OOD and discontinuous regions. MLPs’ assumptions lead to artifacts, while EBMs’ agnosticism ensures conservative, artifact-free behavior.
System Instability and Analytical Pressure
Instability occurs in regions with:
Analytical Pressure: If the unique capabilities of EBMs remain unrecognized, the field may continue to rely on MLPs in scenarios where their assumptions of continuity and linearity lead to suboptimal or erroneous predictions. This is particularly critical in applications requiring robust OOD handling, such as healthcare diagnostics or autonomous systems, where errors can have severe consequences.
Mechanics Driving Behavioral Divergence
Final Conclusion: The comparative analysis underscores that EBMs offer a fundamentally different and valuable learning technique, particularly in handling OOD data and discontinuous distributions. Recognizing and leveraging EBMs’ unique capabilities can mitigate the risks associated with MLPs’ assumption-driven behavior, advancing the field toward more robust and reliable models.
Comparative Analysis of Energy-Based Models (EBMs) and Multi-Layer Perceptrons (MLPs) in Handling OOD and Discontinuous Distributions
Fundamental Mechanisms and Behavioral Divergence
The core distinction between Energy-Based Models (EBMs) and Multi-Layer Perceptrons (MLPs) lies in their foundational mechanisms for modeling distributions. EBMs associate a scalar energy with variable configurations, where low energy signifies compatibility with the learned distribution. This framework drives both inference and learning through energy minimization, inherently avoiding assumptions of continuity or linearity. In contrast, MLPs rely on ReLU activations, which induce piecewise linear behavior and extrapolation near training data boundaries. This intrinsic assumption of continuity and linearity leads to the formation of spandrels—overconfident, unintended predictions in out-of-distribution (OOD) regions.
Mechanisms in Detail
Multi-Layer Perceptrons (MLPs):
Impact Chains: From Internal Processes to Observable Effects
The behavioral differences between EBMs and MLPs manifest through distinct impact chains, linking internal processes to observable effects in OOD regions and discontinuous distributions.
MLP Spandrel Formation
EBM Robustness to Discontinuities
System Instability Points: Where Differences Amplify
The divergence in behavior between EBMs and MLPs becomes particularly pronounced at specific system instability points, highlighting the limitations of MLPs and the robustness of EBMs.
OOD Regions Near Boundaries
Unsampled Discontinuities
Mechanics and Logic: Underpinning the Behavioral Divide
The contrasting behaviors of EBMs and MLPs are rooted in their distinct mechanics and logic, which dictate how they handle uncertainty and extrapolation.
EBM Energy Minimization
MLP Piecewise Linearity
Constraints Amplifying Behavioral Differences
Several constraints exacerbate the behavioral differences between EBMs and MLPs, particularly in scenarios involving limited or discontinuous data.
Typical Failures and Their Implications
The failures of MLPs and the conservative behavior of EBMs in OOD regions underscore the critical importance of recognizing their distinct capabilities.
Intermediate Conclusions and Analytical Pressure
The comparative analysis reveals that EBMs fundamentally differ from MLPs in their handling of OOD data and discontinuous distributions. While MLPs suffer from spandrel formation and artificial structures due to their assumptions of continuity and linearity, EBMs exhibit conservative behavior, avoiding unwarranted predictions. This distinction is not merely academic; it has profound implications for applications requiring robust OOD handling, such as healthcare, autonomous systems, and financial modeling. If the unique capabilities of EBMs remain unrecognized, the field risks perpetuating reliance on MLPs in scenarios where their assumptions lead to suboptimal or erroneous predictions, potentially with catastrophic consequences.
Final Synthesis: The Distinct Value of EBMs
Energy-Based Models (EBMs) represent a distinct and valuable learning technique, particularly in scenarios involving OOD data and discontinuous distributions. Their energy minimization framework, agnostic to assumptions of continuity or linearity, ensures conservative behavior in unsampled regions, avoiding the spandrels and artificial structures characteristic of MLPs. Recognizing and leveraging the unique capabilities of EBMs is essential for advancing machine learning in critical applications where robustness to OOD data is paramount.
Expert Analysis: Unraveling the Behavioral Divergence of EBMs and MLPs in Out-of-Distribution Scenarios
Core Mechanisms Driving Divergence
The fundamental differences between Energy-Based Models (EBMs) and Multi-Layer Perceptrons (MLPs) stem from their core operational principles. EBMs leverage energy minimization, associating a scalar energy with variable configurations. This mechanism ensures that inference and learning prioritize low-energy states for correct configurations while penalizing incorrect ones with high energy. Critically, this approach avoids assumptions of continuity or linearity, providing a more flexible framework for modeling complex distributions. In contrast, MLPs rely on piecewise linearity due to ReLU activations, which, while efficient, introduce inherent limitations. Near training data boundaries, MLPs exhibit linear extrapolation, leading to the formation of spandrels—unintended, overconfident predictions in out-of-distribution (OOD) regions. This divergence in mechanisms sets the stage for distinct behavioral patterns under OOD conditions.
Causal Chains: From Mechanism to Observable Effect
The causal pathways underlying the divergence between EBMs and MLPs can be distilled into two key chains:
Limited training data near boundaries → ReLU-induced piecewise linear extrapolation → Spandrels in OOD regions with overconfident predictions. This chain highlights how MLPs, constrained by their linear extrapolation, generate artifacts in unsampled regions, undermining their reliability.
Absence of training data in unsampled regions → Energy minimization agnostic to unsampled data → Conservative behavior, no spandrels in OOD regions. EBMs, by avoiding assumptions about unsampled data, maintain stability and refrain from unwarranted predictions.
System Instability Points: Where Divergence Manifests
The divergence between EBMs and MLPs becomes particularly pronounced at two critical instability points:
MLPs exhibit instability due to linear extrapolation, forming spandrels that lead to overconfident and erroneous predictions. In contrast, EBMs remain stable, avoiding unwarranted predictions by maintaining conservative behavior.
MLPs introduce artificial kinks via linear extrapolation, imposing continuity where none exists. EBMs, by avoiding assumptions of continuity, align more closely with true distribution gaps, preserving the integrity of the model.
Mechanics Amplifying Divergence
The divergence between EBMs and MLPs is further amplified by specific mechanics:
Low energy for correct configurations ensures robust inference, while high energy for incorrect configurations prevents overfitting. This dual mechanism underpins EBMs’ ability to handle OOD data conservatively.
ReLU activation enforces linear segments, leading to extrapolation errors. Assumptions of continuity and linearity result in OOD artifacts, highlighting MLPs’ limitations in complex scenarios.
Constraints Amplifying Differences
Several constraints exacerbate the differences between EBMs and MLPs:
Limited coverage, especially near discontinuities, disproportionately affects MLPs due to their reliance on continuity and linearity. EBMs, being assumption-agnostic, are less susceptible to such limitations.
MLPs enforce continuity and linearity, while EBMs remain assumption-agnostic. This fundamental difference in architecture drives their distinct behaviors in OOD regions.
Exposes MLP spandrels and EBM conservative behavior near boundaries, providing empirical evidence of their divergence under rigorous testing.
Equivalent model size and training data ensure that observed differences stem from architectural and mechanistic disparities, rather than external factors.
Key Failures and Implications
The failures of MLPs and EBMs underscore their distinct strengths and limitations:
Prone to spandrels in OOD regions and artificial kinks in unsampled discontinuities. These failures highlight the risks of relying on MLPs in scenarios requiring robust OOD handling.
May underfit with insufficient data but avoid artificial structures. While EBMs may require more data to achieve optimal performance, their conservative behavior in OOD regions makes them a valuable alternative in critical applications.
Intermediate Conclusions and Analytical Pressure
The comparative analysis reveals that EBMs and MLPs diverge fundamentally in their handling of OOD data and discontinuous distributions. MLPs, constrained by their piecewise linearity and assumptions of continuity, exhibit instability and generate artifacts in OOD regions. In contrast, EBMs, through energy minimization and assumption-agnosticism, maintain robustness and avoid unwarranted predictions. This divergence is not merely theoretical but has practical implications: if the unique capabilities of EBMs remain unrecognized, the field may continue to rely on MLPs in scenarios where their assumptions lead to suboptimal or erroneous predictions, particularly in critical applications such as healthcare, autonomous systems, and financial modeling. Recognizing and leveraging the distinct strengths of EBMs is essential for advancing the robustness and reliability of machine learning models in real-world scenarios.