# Day 5 of learning AI Engineering: built a small RAG app over a PDF

I built a small RAG (Retrieval Augmented Generation) project where a user can ask questions from a PDF, and the LLM answers from that PDF along with the page number to look at. The stack is LangChain, OpenAI embeddings, and Qdrant running in Docker.

A small note before we start: this exact same pipeline is what powers web-apps like an “AI Tutor in Educative”, an “AI web page builder”. The only thing that changes between those products and my PDF Q&A is the data source. That is the key idea to take away.

What RAG is, in one line

Take a document → break it into small chunks → turn each chunk into a vector (a list of numbers) → store those vectors in a database. Later, when the user asks a question, turn the question into a vector too, find the closest chunks, and feed them to an LLM as context.

INDEXING (run once)
───────────────────

   PDF file
      │
      ▼
   PyPDFLoader
      │  one Document per page (text + metadata)
      ▼
   RecursiveCharacterTextSplitter
      │  chunk_size = 1000, overlap = 200
      ▼
   ~200 small text chunks
      │
      ▼
   OpenAIEmbeddings (text-embedding-3-small)
      │  each chunk becomes a 1536-dim vector
      ▼
   Qdrant (running in Docker)
      │  vector + chunk text + page metadata stored


QUERY (every user question)
───────────────────────────

   "explain me about variables"
      │
      ▼
   OpenAIEmbeddings
      │  same model, same vector space
      ▼
   Query vector (1536-dim)
      │
      ▼
   Qdrant similarity_search (cosine, top k = 4)
      │  closest 4 chunks come back
      ▼
   Build a prompt with those chunks as context
      │
      ▼
   OpenAI Chat Completion (gpt-5-nano)
      │
      ▼
   Final answer + page citations

The stack and why I picked it

  • LangChain is the glue. It gives me one interface to talk to many providers. If I want to swap OpenAI for Cohere, or Qdrant for Pinecone, I change one line. It also has loaders for PDFs, websites, Notion, Google Docs, CSVs, image files, and a lot more. Plus tools for chains, agents, memory, prompts, and output parsing.
  • Qdrant is the vector database. I ran it locally in Docker so I don’t have to pay for a managed service while learning.
  • OpenAI text-embedding-3-small is the embedding model. More on why this one and not the large one further down.
  • uv instead of pip. Faster, lockfile-based, and the modern Python experience.

Some things worth pointing out:

  • The embedding model is just a client — no API call happens when you create it. The actual call to OpenAI happens inside from_documents.
  • from_documents is the convenience method. It connects to Qdrant, creates the collection, embeds every chunk, and inserts it. One call, three jobs.

Now the real question — how big a PDF can I actually ingest?

This is the part I couldn’t find a straight answer to in any tutorial. The pipeline above worked beautifully for my 123 KB, 71-page PDF. But what about a 100 MB book? A 1 GB legal document dump?

The answer has many layers. There is no single PDF size limit.

Layer Hard limit? What actually matters
PyPDFLoader No RAM. The whole PDF gets loaded into memory before chunking.
RecursiveCharacterTextSplitter No None. It just splits whatever you give it.
OpenAI embeddings API Yes Tokens per input + rate limits per minute + your wallet.
Qdrant Practically no Designed for millions of vectors.
Your laptop Yes RAM, disk, and patience.

The actual bottleneck is almost always OpenAI, not Python or Qdrant.

What OpenAI actually limits

There are three things to watch on the embeddings API.

1. Max tokens per single input — 8,191

Each chunk you send to be embedded can be at most 8,191 tokens, which is roughly 32,000 characters. My chunk_size=1000 is way below that, so this is never hit in normal RAG. Official source: https://platform.openai.com/docs/guides/embeddings

2. Rate limits — RPM (requests per minute) and TPM (tokens per minute)

These depend on your account tier. Tier 1, where most new accounts start, looks like this:

Tier RPM TPM Batch queue limit
Free 100 40,000 —
Tier 1 3,000 1,000,000 3,000,000
Tier 2 5,000 1,000,000 20,000,000
Tier 3 5,000 5,000,000 100,000,000
Tier 4 10,000 5,000,000 500,000,000
Tier 5 10,000 10,000,000 4,000,000,000

Your tier moves up automatically as you spend more on the platform.

When you hit the TPM, LangChain backs off and retries automatically. So your script doesn’t crash — it just takes longer.

3. The cost — $0.02 per 1M tokens for text-embedding-3-small

This is the most underrated number. A 100 MB text PDF is roughly 20–50 million tokens. That works out to about $0.40 to $1.00 in embedding cost. Real-world cheap. Pricing page: https://platform.openai.com/docs/pricing
Stop Guessing Your Network: Using PowerShell and TCP Commands to Understand What’s Happening Behind the Scenes

Most developers and IT beginners only touch networking when something breaks.

The internet is “working,” the API is responding, Docker containers are starting, and life moves on.

Until one day:

  • Your app cannot connect to a database
  • Docker says the daemon is unreachable
  • A server responds slowly for no obvious reason
  • A device disappears from the network
  • SSH refuses connections
  • Your Raspberry Pi suddenly becomes invisible

That is usually when people realize they do not actually understand their network.

One of the best ways to fix that is by learning how to inspect and troubleshoot networks directly from the terminal using PowerShell and TCP-based tools.

This post is inspired by a networking article from Paessler Blog and expands it into a more developer-focused practical guide. (blog.paessler.com)

Why PowerShell Matters for Networking

For years, networking on Windows relied heavily on old tools like:

  • ping
  • ipconfig
  • netstat
  • tracert
  • netsh

These still work.

But modern Windows networking is increasingly PowerShell-driven. Microsoft has gradually shifted many administration and diagnostic workflows toward PowerShell because it is:

  • scriptable
  • automatable
  • object-oriented
  • easier to integrate into larger workflows

Instead of parsing messy text output, PowerShell returns structured objects you can filter, sort, and automate. (blog.paessler.com)

Understanding TCP Before Troubleshooting

Most developer tools rely on TCP underneath:

  • Docker
  • APIs
  • databases
  • SSH
  • web servers
  • cloud platforms

TCP (Transmission Control Protocol) is responsible for:

  • reliable communication
  • packet ordering
  • retransmission
  • connection establishment

When applications fail to communicate, the problem is often not the application itself — it is the TCP/network layer.

Understanding a few networking commands can save hours of frustration.

1. Check Your Network Configuration

The first thing to inspect is your machine’s network configuration.

Get-NetIPAddress

This gives you:

  • IP address
  • subnet
  • interface
  • IPv4/IPv6 details

You can also use:

ipconfig

But PowerShell gives more structured information.

2. Test Connectivity Properly

Most people know ping.

PowerShell modernizes it with:

Test-Connection google.com

You can test multiple systems:

Test-Connection google.com, github.com

Or continuously monitor latency:

Test-Connection 192.168.1.1 -Count 10

This helps detect:

  • unstable Wi-Fi
  • packet loss
  • intermittent routing issues

Microsoft’s networking documentation also recommends PowerShell-based connectivity testing for modern administration workflows. (Microsoft Learn)

3. Discover Devices on Your Network

One of the most useful troubleshooting techniques is identifying what devices are actually online.

You can inspect your ARP table:

arp -a

This maps:

  • IP addresses
  • MAC addresses

to devices your machine has communicated with recently.

Modern network discovery guides still rely heavily on ARP-based discovery for local troubleshooting. (blog.paessler.com)

4. Scan an Entire Subnet

Suppose your Raspberry Pi disappeared from the network.

You can sweep your subnet:

1..254 | ForEach-Object {
    Test-Connection "192.168.1.$_" -Count 1 -Quiet
}

This checks which devices respond.

Microsoft demonstrates similar subnet enumeration approaches in PowerShell networking examples. (Microsoft Learn)

5. Find Open TCP Ports

Sometimes the device is online, but the service is not.

For example:

  • SSH may not be running
  • Docker daemon may be down
  • database service may have crashed

You can test ports directly:

Test-NetConnection 192.168.1.10 -Port 22

Example ports:

Service Port
SSH 22
HTTP 80
HTTPS 443
MySQL 3306
PostgreSQL 5432
Docker API 2375/2376

This immediately tells you whether the issue is:

  • routing
  • firewall
  • service availability
  • TCP-level rejection

6. Monitor Active TCP Connections

To inspect live connections:

Get-NetTCPConnection

You can filter by state:

Get-NetTCPConnection | Where-Object {$_.State -eq "Established"}

Or inspect a specific port:

Get-NetTCPConnection -LocalPort 80

This is extremely useful when debugging:

  • APIs
  • containers
  • backend services
  • reverse proxies

7. Troubleshoot Docker Connectivity

If Docker suddenly breaks on Windows, PowerShell networking commands become incredibly useful.

For example, errors like:

failed to connect to the docker API

often indicate:

  • Docker daemon stopped
  • named pipe failure
  • TCP bridge issue
  • virtualization problem

Useful checks:

Get-Service *docker*
Test-NetConnection localhost -Port 2375
docker context ls

Understanding networking basics makes Docker troubleshooting much easier because Docker heavily relies on virtual networking and TCP communication internally.

8. Automate Network Diagnostics

This is where PowerShell becomes powerful.

Instead of manually checking systems one by one, you can automate diagnostics.

Example:

$servers = @(
    "192.168.1.10",
    "192.168.1.11",
    "192.168.1.12"
)

foreach ($server in $servers) {
    Test-NetConnection $server -Port 22
}

Now you can verify SSH availability across multiple systems automatically.

This scales extremely well for:

  • labs
  • classrooms
  • hubs
  • server farms
  • IoT deployments

9. Network Monitoring at Scale

At some point, command-line troubleshooting is not enough.

That is where monitoring systems come in.

Platforms like PRTG Network Monitor automate:

  • network discovery
  • latency tracking
  • device monitoring
  • traffic inspection
  • uptime monitoring

Modern network visibility systems combine:

  • ARP discovery
  • TCP monitoring
  • SNMP
  • device inventories
  • automated alerting

to give administrators full infrastructure visibility. (blog.paessler.com)

Real Lesson: Developers Need Networking Skills

One pattern keeps repeating in modern software engineering:

The deeper you go, the more networking matters.

Machine learning engineers, backend developers, DevOps engineers, cybersecurity analysts, embedded engineers, and cloud architects all eventually run into:

  • ports
  • sockets
  • firewalls
  • routing
  • DNS
  • TCP failures

Networking knowledge is no longer optional.

Final Thoughts

Learning PowerShell networking commands is not about becoming a network engineer overnight.

It is about gaining visibility.

Once you can inspect:

  • connections
  • devices
  • ports
  • adapters
  • latency
  • routing

you stop guessing and start diagnosing systems properly.

And honestly, that is one of the biggest transitions from beginner developer to advanced engineer.

Further Reading

(blog.paessler.com)

BAE: Irak'tan atılan 6 İHA'ya müdahale edildi

Birleşik Arap Emirlikleri Savunma Bakanlığı, son 48 saatte Irak topraklarından atılan 6 insansız hava aracının hava savunma sistemlerince etkisiz hale getirildiğini, can kaybı veya kritik tesislerin etkilenmediğini açıkladı. Ayrıca, 17 Mayıs’ta Barakah Nükleer Santrali’ne düzenlenen saldırının da Irak’tan yapıldığı soruşturmayla tespit edildi.

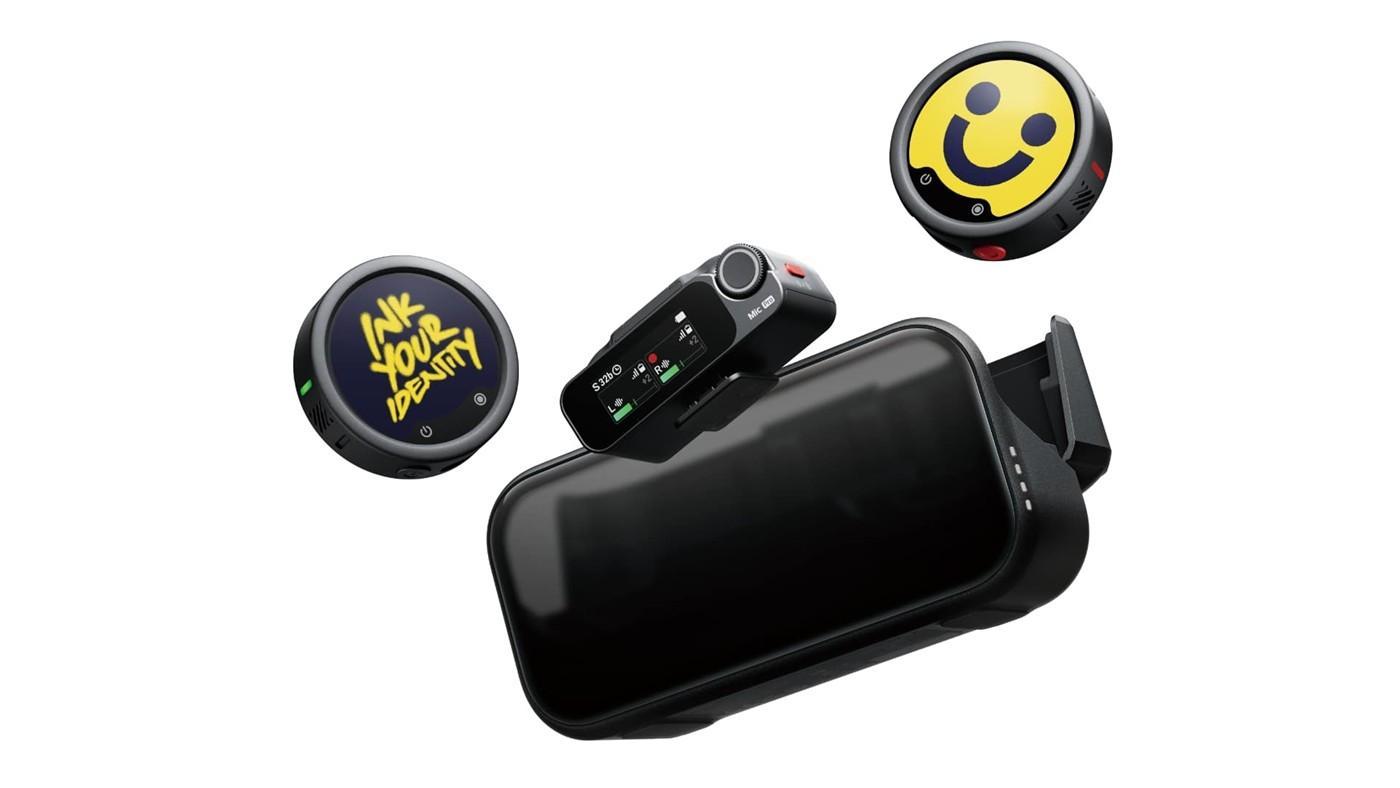
Insta360 Mic Pro e-mürekkep ekranı ile geliyor

Yeniliği seven yayıncılar için geliştirilen Insta360 Mic Pro kablosuz mikrofon seti dahili ekranının yanı sıra yüksek ses kalitesi, dahili depolama alanı, bağımsız kullanım gibi özelliklerle geliyor.
What Happens When You Run `npm run dev`

Hello, I’m Maneshwar. I’m building git-lrc, a Micro AI code reviewer that runs on every commit. It is free and source-available on Github. Star git-lrc to help devs discover the project. Do give it a try and share your feedback for improving the project.

You’ve run npm run dev approximately 1,000 times in your life.

You’ve watched the terminal blink.

You’ve switched to the browser.

Magic happened.

But do you actually know what’s going on? Like, really know?

Today we go all the way down the hole understanding shell, process spawning, module graphs, Hot Module Replacement, React Fast Refresh.

Step 0: You press Enter

npm run dev

Your shell looks up npm in your PATH and finds it — often inside whatever directory nvm installed Node into, or at a system path like /usr/local/bin/npm. It hands control to the npm CLI, which is itself just a Node.js script.

npm then does one thing: reads your package.json.

{
  "scripts": {
    "dev": "vite"
  }
}

It finds "dev": "vite" and prepares to run it.

Step 1: npm spawns a child process

npm temporarily adds ./node_modules/.bin to your PATH, then spawns a child process running the dev command.

So "vite" resolves to ./node_modules/.bin/vite, which is a symlink to the actual Vite binary inside node_modules/vite/bin/vite.js.

No magic. It’s just Node running a JS file.

Step 2: Vite boots up

Vite reads your vite.config.js (or .ts), registers plugins, and does something really clever before anything is served.

The esbuild pre-bundling trick

Vite uses esbuild written in Go, absurdly fast to pre-process your node_modules dependencies.

It does two things:

  1. Converts CommonJS to ESM. Browsers can’t natively load require(). esbuild rewrites it.
  2. Collapses packages with many internal files into one. lodash has 600+ tiny files. esbuild merges them so the browser makes one request, not 600.

The result is cached in .vite/deps/. Touch node_modules? Cache busts.
Otherwise it skips this step entirely on restart.

Step 3: The dev server is just… an HTTP server

Vite starts a plain Node.js HTTP server on localhost:5173.

No webpack dev server magic, no complex middleware chains.

When the browser requests a file, Vite:

  1. Reads it from disk
  2. Transforms it on-the-fly (JSX → JS, TypeScript → JS, .css → injected <style>)
  3. Serves it as a native ES Module

The browser itself handles module resolution using <script type="module">.

The key insight: Vite doesn’t bundle your source code in dev mode at all.

The browser fetches each file individually as an ES module.

This is why Vite’s dev startup is near-instant regardless of your project size it only processes what the browser actually asks for.

Each arrow is a real HTTP request. The browser is doing the graph traversal for you.

Step 4: The module graph

As files are requested, Vite builds an internal module dependency graph a map of who imports what.

This graph is lazy, only nodes that get requested exist in it.

If you never navigate to a route, those components are never fetched, never in the graph.

This is the structure that makes HMR fast.

When a file changes, Vite doesn’t scan all your code.

It just walks this graph.

Step 5: You save a file — here’s where it gets interesting

5a. OS notifies Vite immediately

Vite uses chokidar which wraps OS-native file system events:

OS API Mechanism
Linux inotify Kernel watches inodes directly
macOS FSEvents Core Services file-system event API
Windows ReadDirectoryChangesW Win32 API

Zero polling. The OS taps Vite on the shoulder the moment your editor flushes to disk.

5b. Walk the graph, find the HMR boundary

Vite walks up the module graph from the changed file, looking for the first ancestor that has registered an HMR handler via import.meta.hot.accept().

With React, you never write import.meta.hot.accept() yourself.

The @vitejs/plugin-react plugin (which uses React Fast Refresh) automatically injects this into every component file at transform time. It’s invisible to you.

If no boundary is found all the way up to main.jsx full page reload.

You’ll see this happen when you edit vite.config.js or a non-component JS utility that isn’t HMR-aware.

5c. Server re-transforms only the changed file

Vite re-runs just Button.jsx through its plugin pipeline JSX transform, any Babel plugins, etc.

The result is a fresh ES module in memory.

5d. Browser fetches the new module via dynamic import

The HMR client (a small script Vite injects into your page) is told an update is available and calls:

import('/components/Button.jsx?t=1718023456789')

The ?t=timestamp query param is the cache-buster. The browser sees a URL it hasn’t fetched before, makes a real HTTP request, gets the new module.

5e. The module swap — hot.dispose and hot.accept

Vite’s HMR runtime is built around two functions you (or, with React, the plugin) register on import.meta.hot:

// In a module that wants to handle its own updates:

// Clean up before this module is replaced —
// cancel timers, unsubscribe, remove listeners.
import.meta.hot.dispose((data) => {
  clearInterval(timer)
})

// Receive the freshly imported module and re-wire things.
import.meta.hot.accept((newModule) => {
  // newModule is the updated exports
})

A subtle but important detail: Vite’s HMR doesn’t literally swap the original imported module object for everyone up the chain.

The accepting module i.e the HMR boundary is responsible for taking the new exports and applying them.

That simplified model is what lets Vite skip the expensive work of rewriting every importer, and it’s enough for almost every real dev scenario.

dispose is where you cancel a setInterval, unsubscribe from a store, or remove an event listener, anything that would leak if the old module just got abandoned.

Note on CSS: stylesheets take a slightly different path. When a .css file changes, Vite doesn’t dynamically re-import a JS module, it swaps the <link> (or <style>) tag for the updated stylesheet, which avoids a flash of unstyled content.

Step 6: React Fast Refresh does the actual re-render

React Fast Refresh is a separate system built by the React team. When the new component module lands, it:

  1. Compares hook signatures. If Button had useState, useEffect before and still has useState, useEffect after, state is preserved. Add or remove a hook? State resets for that component only.

  2. Finds all live instances in the React fiber tree.

  3. Surgically re-renders only the affected subtree. Parent components don’t re-render. Siblings don’t re-render. Just the changed component and its children.

This is why you can edit a component’s styling while a form is mid-fill and the form doesn’t reset. The form state lives in a parent or sibling — Fast Refresh never touched it.

The full picture

Why does this matter?

If you’re on webpack’s dev server, a file save triggers a rebuild of the bundle, even with HMR. On a mid-size project that can mean noticeable latency between save and browser update.

With Vite’s native-ESM approach, the server does almost nothing (one file transform), the browser fetches one URL, and Fast Refresh touches one subtree.

The entire round trip is typically very fast and stays fast as your project grows.

That’s not a marginal improvement.

It fundamentally changes how you work — edit → see result becomes nearly instantaneous.

AI agents write code fast. They also silently remove logic, change behavior, and introduce bugs — without telling you. You often find out in production.

git-lrc fixes this. It hooks into git commit and reviews every diff before it lands. 60-second setup. Completely free.*

Any feedback or contributors are welcome! It’s online, source-available, and ready for anyone to use.

⭐ Star it on GitHub:

GitHub logo

HexmosTech
/
git-lrc

Free, Micro AI Code Reviews That Run on Commit

AI agents write code fast. They also silently remove logic, change behavior, and introduce bugs — without telling you. You often find out in production.

git-lrc fixes this. It hooks into git commit and reviews every diff before it lands. 60-second setup. Completely free.

See It In Action

See git-lrc catch serious security issues such as leaked credentials, expensive cloud
operations, and sensitive material in log statements

git-lrc-intro-60s.mp4

Why

  • 🤖 AI agents silently break things. Code removed. Logic changed. Edge cases gone. You won’t notice until production.
  • 🔍 Catch it before it ships. AI-powered inline comments show you exactly what changed and what looks wrong.
  • 🔁 Build a…