The Libravatar Problem Nobody Warned Me About (And How I Finally Fixed It)

I didn’t expect something as simple as setting a profile picture to turn into a full debugging session.

But that’s exactly what happened.

It started like any normal onboarding task. I had just set up my Fedora Account System account, everything was working fine, and I thought, “Let me quickly update my profile picture and move on.”

Simple, right?

I clicked “Change Avatar.”
I was redirected to Libravatar.
I logged in.
I uploaded my picture.

Done.

Or at least, that’s what I thought.

I went back to check my profile… and there it was, the same default avatar staring back at me like nothing had changed.

At first, I assumed it was just a delay. Maybe caching. Maybe I needed to refresh.

I refreshed.

Nothing.

I logged out and back in.

Still nothing.

That was the moment I realized this wasn’t just a small glitch. There was something deeper going on.

The Loop That Made It Worse

While trying to figure it out, I ran into another issue, the login loop.

At one point, instead of smoothly logging in, I kept getting prompted repeatedly for credentials. It felt like I was stuck between two systems that weren’t fully talking to each other.

That’s when I made a small but important decision, I cancelled the prompt.

And surprisingly, that worked.

It redirected me to the proper Fedora login page, and I was finally able to proceed cleanly.

It was my first clue that the problem wasn’t just about uploading an image… it was about how systems were connected.

Understanding the Real Problem

At this point, I stopped guessing and started thinking.

Libravatar wasn’t just storing images. It was linking identities.

And Fedora wasn’t just using usernames. It was relying on a specific identity mapping system — OpenID and email associations.

That’s when it clicked.

Uploading the image wasn’t enough.
The system needed a verified identity to attach it to.

The Fix That Finally Worked

Instead of trying to re-upload the image again, I took a different route.

I added a new email address inside Libravatar.
Then I verified it.

Came back. Refreshed.

And just like that — it worked.

The new profile picture finally showed up.

What I Learned

This wasn’t just about fixing an avatar issue.

It taught me something deeper about working in real systems:

Things don’t always fail loudly, sometimes they fail silently
Identity systems (OpenID, email mapping) matter more than they seem
Debugging isn’t about trying random fixes, it’s about understanding how things connect

Most importantly, I learned that the difference between being stuck and moving forward is often just one shift, from guessing to thinking.

Why I Decided to Document It

After solving it, I realized something:

If I ran into this, others definitely would too.

So instead of keeping the solution to myself, I turned it into a guide for the community, something simple, clear, and easy to follow.

Because in open source, solving a problem is good…

But making it easier for the next person?

That’s better.

If you’re interested in the documentation I prepared as a guide for resolving these issues, you can find it here

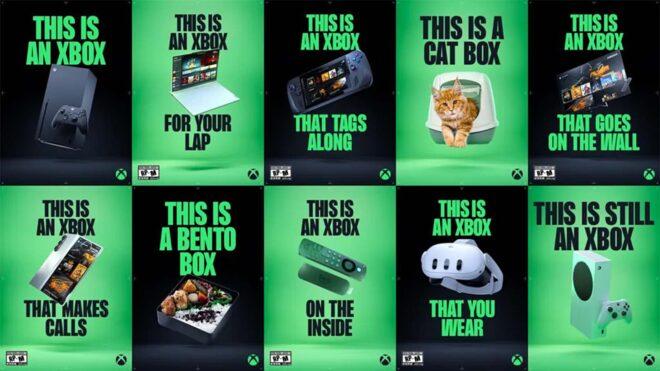
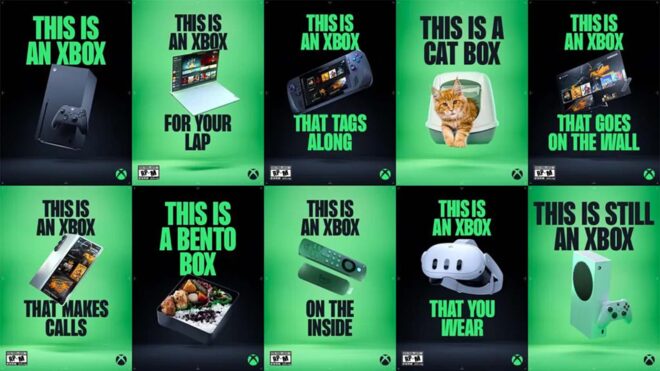
Microsoft, “This is an Xbox” pazarlama kampanyasının rafa kaldırılması hakkında konuştu

Microsoft,

Microsoft, "This is an Xbox" pazarlama kampanyasını sessiz sedasız rafa kaldırdıGeçtiğimiz ay Xbox dünyasında büyük bir değişim yaşandı. Phil Spencer emekliye ayrıldı, başkan Sarah Bond ise istifa etti. Bu dönüşümle ilgili olarak bazı bilgiler paylaşan Tom Warren, Xbox’ı bir konsol değil platform olarak konumlandıran “This is an Xbox” pazarlama kampanyasının arkasında Bond’un yer aldığını ve bu odağın şirket içindeki çoğu kişi tarafından hiç hoş karşılanmadığını aktarmıştı. Bond’un ayrılışının Xbox’taki çok sayıda çalışanı rahatlattığını belirten Warren, çalışanların Bond’la çalışmanın oldukça zor olduğunu da söylediğini ifade etmişti. Xbox’ın başında artık “Asha Sharma” yer alıyor ve Sharma’nın attığı ilk adımlardan biri “This is an Xbox” pazarlama kampanyasını rafa kaldırmak oldu. Bu kampanya için hazırlanan içerikleri Xbox’a yönelik haberlerin paylaşıldığı resmi blog sayfası Xbox Wire’dan silen Microsoft, bu sürpriz konuda bugün ilk kez kısa bir açıklama yaptı. Windows Central’a konuşan şirket sözcüsü kampanyanın iptal edilmesine yönelik olarak, “Asha bu kampanyayı Xbox gibi hissettirmediği için iptal etti. Şu anda Xbox’ın marka yapılanmasına bizzat liderlik ediyor.” […]

Microsoft, “This is an Xbox” pazarlama kampanyasının rafa kaldırılması hakkında konuştu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Uttar Pradesh: India’s Next Big Business Hub for Startups

Ever thought about where your next big business opportunity in India could be? Forget the usual suspects for a moment and turn your gaze towards a state that’s rapidly transforming into an economic powerhouse: Uttar Pradesh.

Yes, you read that right! Uttar Pradesh, often known for its rich history and culture, is now making headlines as a dynamic hub for startups and established businesses alike. If you’re an Indian startup or an entrepreneur looking for a fertile ground to grow, Uttar Pradesh offers an unmatched blend of market size, infrastructure development, and proactive government policies.

Why Uttar Pradesh is the Go-To State for Business Growth

What makes Uttar Pradesh so attractive right now? It’s a combination of several strategic factors that are creating an incredibly favorable business environment:

1. A Market Like No Other

With a population exceeding 240 million, Uttar Pradesh is not just India’s most populous state, but one of the most populous sub-national entities in the world. This translates into a colossal domestic market. Imagine the sheer demand for products and services! From consumer goods to digital services, the potential customer base in Uttar Pradesh is simply enormous, offering unparalleled scalability for businesses.

2. Infrastructure on an Accelerated Path

The state has witnessed an unprecedented infrastructure boom. We’re talking about:

  • Expressways: A network of world-class expressways (like Purvanchal, Bundelkhand, Ganga Expressways) is drastically improving connectivity, reducing logistics costs, and facilitating faster movement of goods.
  • Airports: Multiple international and domestic airports are either operational or under construction, connecting Uttar Pradesh to global and national markets with ease.
  • Industrial Corridors: Dedicated industrial areas, special economic zones (SEZs), and manufacturing clusters are being developed, offering ready-to-move-in facilities for businesses.
  • Power: Significant improvements in power supply ensure reliable electricity for industrial operations, a crucial factor for any growing business.

3. Pro-Business Policies & Ease of Doing Business

The government of Uttar Pradesh has been aggressively working to simplify the business landscape. Their focus on “Ease of Doing Business” is evident through:

  • Single-Window Clearance System: Streamlining approvals and reducing bureaucratic hurdles for investors.
  • Investor Summits: Regularly held events to attract domestic and international investment.
  • Sector-Specific Policies: Tailored policies for industries like IT, electronics manufacturing, food processing, and tourism, offering incentives, subsidies, and tax breaks.
  • Startup Policy: Specific initiatives to foster innovation, provide funding support, and create a robust startup ecosystem within Uttar Pradesh.

Key Sectors Ripe for Innovation in Uttar Pradesh

While the market is vast, some sectors stand out with immense growth potential:

Agriculture & Food Processing

As an agrarian state, Uttar Pradesh offers huge opportunities in agri-tech, food processing, cold chain logistics, and value-added agricultural products. The “One District One Product” (ODOP) scheme further promotes local specialties.

MSMEs & Manufacturing

The backbone of the Indian economy, MSMEs (Micro, Small, and Medium Enterprises) thrive here. With a large skilled and semi-skilled workforce, manufacturing across various segments from textiles to engineering goods sees significant potential.

Tourism & Hospitality

Home to iconic sites like the Taj Mahal, Varanasi, and Ayodhya, Uttar Pradesh is a global tourist magnet. Startups in travel tech, heritage tourism, hospitality services, and pilgrimage tourism can find a massive market.

IT & Startups

Emerging IT hubs in cities like Noida, Lucknow, and Ghaziabad, coupled with government incentives, are attracting tech startups. Opportunities exist in software development, AI, IoT, e-commerce, and digital services.

Tapping into the Talent Pool of Uttar Pradesh

Uttar Pradesh boasts a large and diverse talent pool, with numerous universities, engineering colleges, and vocational training institutes. Government initiatives focused on skill development are further enhancing the employability of this workforce, making it easier for businesses to find the right talent locally.

Your Next Big Move Could Be in Uttar Pradesh

For Indian startups and businesses, Uttar Pradesh is no longer just a state; it’s a strategic growth corridor. The combination of a massive market, rapidly improving infrastructure, and a pro-business government creates an ecosystem ripe for innovation and expansion. If you’re ready to scale your venture and tap into one of India’s most promising economic landscapes, it’s time to seriously consider making Uttar Pradesh your next business destination.

Don’t miss out on the incredible growth story unfolding in the heart of India. Explore the possibilities, engage with the local ecosystem, and watch your business flourish in Uttar Pradesh!

Flipping the Question: From ‘Is It Too Wet?’ to ‘Is It Too Dry?’

When I first built the Groundwise engine for the Ridewise app, it answered one question: is it too wet to ride? Low wetness meant good conditions. High wetness meant stay home. Exactly what I needed for mountain biking, skateboarding, and other outdoor wheeled activities where surface conditions impacted by weather mattered.

Then I started thinking about my garden.

I have raised beds, a few containers on the patio, and a lawn that I’d like to keep alive without drowning it. I don’t get obsessive about it, and to be honest my lawn is far from impressive. I’m not one of those people who try to maintain golf course grass, far from it. But I’ve still regularly done that assessment where I look at the sky, vaguely remember whether it rained, and make the same kind of gut call on watering that I used to make about trails. The variables were familiar: recent rain, temperature, sun exposure, how fast things dry. I was running the same mental model, just asking the opposite question.

That realization is what turned one app into three. If the engine could quantify moisture on a surface, it could answer both “is it too wet to ride?” and “is it too dry, should I water?”

The Inversion

The engine always calculates a wetness score from 0 (bone dry) to 1 (saturated). The EngineMode enum controls what that score means:

Wetness concern (Ridewise, Fieldwise): Low wetness = Yes (go ride or play). High wetness = No (too wet).

Dryness concern (Yardwise): Low wetness = Yes (water today). High wetness = No (skip watering).

The verdict is the same enum, Yes, Maybe, No, but the interpretation flips. This means the consuming app doesn’t need to know which mode produced the result. It renders green for Yes, orange for Maybe, red for No, regardless.

The thresholds shift too:

Yes Maybe No
Wetness concern < 0.30 0.30 – 0.60 ≥ 0.60
Dryness concern < 0.15 0.15 – 0.45 ≥ 0.45

Yardwise thresholds are lower because the stakes are asymmetric. This wasn’t immediately obvious until testing early versions of the app, when I realized that missing a watering day rarely if ever harms established plants. Riding a muddy trail damages the surface. So Yardwise is more lenient than the other apps, and leans toward “maybe check the soil” rather than “definitely water” — this makes the verdict less alarming. The reality is that the cost of a false positive (unnecessary watering) is real (overwatering causes its own problems), while the cost of a false negative (skipping one day) is usually trivial.

Manual Watering: Tracking What the Weather Doesn’t Know

Here’s where Yardwise diverges from Ridewise and Fieldwise most sharply. The weather API knows about rain. It doesn’t know that you ran the sprinkler for 20 minutes yesterday evening.

Yardwise lets users log manual watering events with timestamps. The engine converts these into precipitation equivalents that then get added to the rain score alongside actual precipitation, with the same time-weighted decay:

0-24 hours ago:  0.7x weight (70% contribution)
24-48 hours ago: 0.2x weight
48-72 hours ago: 0.1x weight

A watering yesterday contributes about 0.175 inches to the effective precipitation (0.25 × 0.7). That’s enough to shift a borderline “water today” verdict to “check soil” or even “skip.”

The decay is important. A watering three days ago shouldn’t prevent the engine from recommending water today, the moisture is long gone, especially in containers with fast-draining potting mix. The time-weighted model handles this naturally.

Cold Weather Extends Watering Memory

One wrinkle: cold weather slows evapotranspiration. A watering event that would normally decay in 48 hours can remain relevant for up to 96 hours during cold weather. The engine extends the effective window based on the same cold factor used for dormancy:

wateringWindow = 48 + 48 × coldFactor

At 34°F, the cold factor is about 0.62, giving a window of roughly 78 hours. At 45°F, it’s about 56 hours. This prevents the engine from recommending watering when yesterday’s water is still sitting in cold, slowly-evaporating soil. Keep in mind that winter watering is pretty rare, reserved almost exclusively for new plantings (trees, shrubs, etc.) and only during an unusual dry spell.

Establishment Sensitivity: Protecting Young Plants

Newly seeded lawns and recently transplanted plants need more water than established ones, and they’re far more susceptible to drought. The engine handles this through an establishment sensitivity boost that layers on top of the surface type’s base damage sensitivity.

Establishment Sensitivity Boost
Established +0.0 (default)
Newly planted +0.2
Newly seeded +0.5

This boost affects the sensitivity veto, the mechanism that pushes borderline verdicts toward protection. With a newly seeded lawn (base sensitivity 0.4 + boost 0.5 = 0.9 effective sensitivity), a Maybe verdict with wetness below 0.3 gets overridden to Yes: water those seeds.

For established plants with no boost, the same borderline conditions stay as Maybe: check the soil yourself. The engine doesn’t push you to water unless there’s a fragile surface that genuinely needs protection.

This is the same sensitivity veto that Fieldwise uses to protect natural grass athletic fields from being played on when borderline wet. Same mechanism, opposite direction. In wetness-concern mode, high sensitivity + borderline conditions → No (protect from use). In dryness-concern mode, high sensitivity + borderline conditions → Yes (protect from drought).

Dormancy and Evaporative Demand

Two Yardwise-specific wetness modifiers that were covered in the edge cases article deserve a brief recap in the context of the inversion:

Cold-weather dormancy injects additional wetness into the score when temperatures drop below 55°F. This suppresses watering recommendations by pushing the score toward the “skip” zone because dormant plants don’t benefit from watering and the moisture promotes root rot and fungal growth.

From the engine’s perspective, dormancy is saying: “the soil might technically be dry, but the plant doesn’t need water right now, so act as if conditions are wetter than they are.”

Low evaporative demand does something similar on cool, overcast, humid days. Even if the soil surface looks dry, the plant isn’t losing much water through transpiration when there’s no sun and the air is already saturated. A small wetness boost (up to 0.25) prevents unnecessary watering recommendations.

Both modifiers only activate in dryness-concern mode. They don’t make sense for riders or field sports, cold weather doesn’t make a trail less muddy, and overcast skies don’t affect whether the ground is rideable or a football field is playable.

Yardwise Surface Types

The Groundwise family shares a surface type system, but Yardwise introduces types that don’t exist in the riding or sports world:

Potting mix (containers) dries at 2.0x — the same rate as concrete. This isn’t a coincidence. Potting mix is engineered for drainage, just like concrete. Containers are also typically exposed to wind on all sides, which accelerates drying considerably. The result: containers often need daily watering in summer, even after rain. The engine captures this naturally because the high drying multiplier clears moisture quickly.

Amended soil with mulch dries at 0.7x — the slowest rate in the system, tied with clay. Mulch deliberately slows evaporation. A mulched garden bed after rain stays moist for days. The engine’s residual wetness model (which only activates for absorbent surfaces above 0.25 inches of rain) extends this further, keeping the score in “skip watering” territory well after a good rain.

Fresh seed has the highest effective damage sensitivity in the system: base 0.8 plus an establishment boost of 0.5, capped at 1.0. The engine is maximally protective of newly seeded areas, pushing any borderline verdict toward “water.”

Compost is the most forgiving surface: 1.2x drying multiplier and only 0.3 damage sensitivity. Compost generates internal heat from decomposition, which drives some of its own drying. And it’s hard to damage, overwatering a compost pile isn’t really a concern. The engine mostly stays out of the way for compost, skewing toward “skip” unless conditions are genuinely dry.

The Insight That Made It Work

The hardest part of building Yardwise wasn’t the code, it was convincing myself that the inversion was valid. Every instinct I’d built while developing Ridewise and Fieldwise said “wet = bad.” Retraining my thinking to “wet = good (for gardening)” took effort.

What made it click was realizing that the engine isn’t really about wet or dry. It’s about moisture state relative to the ideal for a given surface and activity. For a trail, the ideal is dry. For a garden bed, the ideal is moist (not soaked!). The engine measures distance from ideal in both directions.

Once I saw it that way, the inversion was mechanical. Same measurements, same model, same pipeline. Just a different definition of “good.”

Next in the Series

The final article covers the verdict UX, why three states beat a percentage, how the engine communicates uncertainty through confidence levels and contributing factors, and the role of the recovery outlook in managing expectations.

Yardwise is available for iOS from Stalefish Labs. Same engine as Ridewise and Fieldwise, different question.

The Great Talent Paradox of 2026: Why AI Is Making Developer Shortages Worse, Not Better

Everyone expected AI to solve the developer shortage.
Instead, it’s making it brutally worse.
50% of tech leaders now cite recruiting and retaining skilled technology workers as their #1 business challenge in 2026 — the highest it’s ever been. Over 90% of organizations globally face severe IT talent shortages, with potential economic losses exceeding $5.5 trillion. The gap isn’t just in raw headcount — it’s in the specific skills that actually matter: AI-native engineering, secure systems design, platform thinking, and the ability to manage fleets of AI agents without creating chaos.
The irony is painful. AI coding tools are everywhere (84% adoption), yet they haven’t reduced demand for humans. They’ve changed it.
The Data Behind the Paradox
Recent 2026 research paints a clear picture:

IDC and World Economic Forum data show 59% of workers will need reskilling by 2030, with 39% of existing skills becoming obsolete. Critical shortages hit cloud architecture, AI/ML, cybersecurity, and legacy modernization.
87.5% of tech leaders describe hiring engineers as “brutal.” Time-to-hire has stretched to 3–6 months for key roles, delaying infrastructure projects and piling pressure on existing teams.
AI hasn’t replaced developers — it’s created a “Talent Paradox”: Tools attract top performers but don’t create them. Senior engineers now spend most of their time reviewing AI-generated code instead of architecting, mentoring, or innovating. This leads to burnout, higher turnover, and even more pressure on the remaining talent.
The vicious cycle is real: Overworked teams burn out and leave → remaining staff handle more load → less time for training or upskilling → harder to hire because culture and velocity suffer.

In India (especially hubs like Pune, Bangalore, and Hyderabad), the pressure feels even sharper. Global clients demand AI-fluent delivery while local competition for skilled engineers remains fierce, and EMIs don’t wait for “reskilling time.”
Real Stories from the Front Lines

Engineering leaders report seniors are “burning out auditing AI pull requests” instead of doing high-value work.
Companies struggle to find people who can have “difficult conversations about technical debt with non-technical executives.”
Juniors ramp up faster on syntax thanks to AI, but lack systems thinking, security judgment, and architectural taste — skills that take years of guided experience.
The result? Delivery risk rises, brittle architectures emerge, and the best talent walks away from environments that feel like endless maintenance mode.

Why AI Amplified the Shortage
AI lowers the bar for producing code but raises the bar for responsible engineering. Organizations now need:

People who can verify, secure, and integrate AI output at scale.
Platform engineers who build golden paths and reduce cognitive load.
Leaders who balance velocity with sustainability.

Pure “coders” are easier to find. T-shaped engineers who combine deep fundamentals with AI fluency and soft skills? Much rarer.
Practical Solutions That Actually Work in 2026

Internal Upskilling at Scale — Create structured AI pair-programming rotations, targeted learning paths, and mentorship programs focused on judgment, not just prompting.
Platform Engineering as Retention Tool — Build Internal Developer Portals (IDPs) with self-service golden paths. This reduces toil and lets engineers focus on meaningful work — the #1 driver of retention.
Target the Right Profile — Hire for strong fundamentals + learning agility rather than pure LeetCode wizards. Look for people excited to work with AI agents.
Measure and Protect DevEx — Track real developer experience metrics (onboarding time, cognitive load, after-hours work) and act on them.
The Bottom Line
AI didn’t eliminate the need for great developers — it made great developers even more valuable.
The organizations winning in 2026 aren’t the ones trying to hire their way out of the shortage. They’re the ones investing in platforms, upskilling, and environments where talented people actually want to stay and grow.
You now have the latest data, real patterns, and a concrete tool to start closing the gap today.
The talent crisis doesn’t have to define your 2026.

How I Handle State Management in a Health App

State in a Breathing App Is Deceptively Complex

On the surface, Lunair seems like it would have simple state: a breathing pattern is playing or it is not. In reality, the state graph is surprisingly deep once you account for interruptions, background transitions, accessibility events, and user preferences.

The State Machine Approach

Early on I used a collection of boolean flags — isPlaying, isPaused, isComplete. This quickly devolved into impossible states. Could something be both paused and complete? The flags said yes; reality said no.

I switched to an explicit state machine:

enum SessionState: Equatable {
    case idle
    case preparing(pattern: BreathPattern)
    case active(phase: BreathPhase, cycleCount: Int)
    case paused(resumePhase: BreathPhase, cycleCount: Int)
    case completing(totalCycles: Int)
    case completed(summary: SessionSummary)
}

Every possible state is explicitly modeled. The paused case carries the information needed to resume. The completing state handles the wind-down animation before showing results. No impossible combinations.

Managing Transitions

State transitions are handled through a single method that validates and applies changes:

class SessionManager: ObservableObject {
    @Published private(set) var state: SessionState = .idle

    func transition(to newState: SessionState) {
        guard isValidTransition(from: state, to: newState) else {
            assertionFailure("Invalid transition: (state) -> (newState)")
            return
        }

        let oldState = state
        state = newState

        handleSideEffects(from: oldState, to: newState)
    }

    private func isValidTransition(
        from: SessionState, to: SessionState
    ) -> Bool {
        switch (from, to) {
        case (.idle, .preparing):           return true
        case (.preparing, .active):         return true
        case (.active, .paused):            return true
        case (.active, .completing):        return true
        case (.paused, .active):            return true
        case (.paused, .idle):              return true
        case (.completing, .completed):     return true
        case (.completed, .idle):           return true
        default:                            return false
        }
    }
}

The assertionFailure catches invalid transitions during development without crashing in production. This has caught bugs multiple times — especially around background/foreground transitions triggering unexpected state changes.

Side Effects at the Boundary

All side effects — haptics, sound, analytics, timer management — happen in handleSideEffects, not scattered throughout the UI:

private func handleSideEffects(
    from oldState: SessionState, to newState: SessionState
) {
    switch (oldState, newState) {
    case (_, .active(let phase, _)):
        hapticEngine.signalPhase(phase)
        timerManager.start(for: phase)

    case (.active, .paused):
        timerManager.pause()
        hapticEngine.stop()

    case (_, .completing(let cycles)):
        hapticEngine.signalSessionComplete()
        analytics.logSessionEnd(cycles: cycles)

    default:
        break
    }
}

This centralization means the views stay purely declarative. They read state and render. That is it.

Persisting Across Interruptions

Phone calls, notifications, backgrounding — all of these can interrupt a breathing session. The state machine handles this cleanly:

func handleScenePhaseChange(_ phase: ScenePhase) {
    switch phase {
    case .background:
        if case .active(let breathPhase, let count) = state {
            transition(to: .paused(
                resumePhase: breathPhase,
                cycleCount: count
            ))
        }
    case .active:
        // Don't auto-resume — let the user choose
        break
    default:
        break
    }
}

Auto-pausing on background is essential. Auto-resuming is not — returning to the app after a phone call should not immediately start a breathing cycle without the user being ready.

What I Would Do Differently

If I were starting Lunair today, I would reach for the Observation framework (@Observable) sooner. The ObservableObject + @Published pattern works, but the newer approach eliminates unnecessary view updates when unrelated published properties change.

The state machine pattern, though, I would not change. It has been the single most stabilizing architectural decision in the entire app.

AWS Basics But Needs to Be Known Before You Start Your Certification

You don’t need to memorize 200 services to start your AWS journey. But you do need to understand the foundations. Here’s everything I wish someone had explained to me before I started studying for my AWS certification.

1. What Even Is Cloud Computing?

Let’s start from the very beginning. Cloud computing sounds fancy, but the core idea is simple: there’s a physical server somewhere, and you’re renting it over the internet.

Instead of buying your own hardware, setting up a server room, and hiring people to maintain it — you use someone else’s infrastructure (like AWS) and pay only for what you use.

Here’s the official NIST definition:

“A model for enabling ubiquitous, convenient, on-demand network access to a shared pool of **configurable computing resources* that can be rapidly provisioned and released with minimal management effort or service provider interaction.”*

Let’s break that down into human language:

  • On-demand → You get resources whenever you want them
  • Shared pool → Multiple customers share the same physical infrastructure
  • Configurable → You choose how much CPU, RAM, storage you need
  • Rapidly provisioned and released → Spin up a server in minutes, shut it down when you’re done
  • Minimal management effort → No need to physically touch any hardware

2. What’s Actually Behind the “Cloud”?

Behind the cloud, there are real, physical server racks sitting in massive data centers around the world. AWS has these data centers spread across the globe, and the infrastructure is organized in a clear hierarchy:

Region

A large geographic area (e.g., eu-west-1 for Ireland, us-east-1 for N. Virginia). You choose a region based on where your users are, compliance requirements, or pricing.

Availability Zone (AZ)

Each Region contains multiple AZs (e.g., eu-west-1a, eu-west-1b, eu-west-1c). An AZ is one or more data centers with independent power, networking, and connectivity. Multiple AZs exist for redundancy — if one goes down, the others keep running.

Edge Locations / Points of Presence (PoP)

These are smaller, lightweight locations spread even more widely than Regions. They’re used primarily for caching content closer to end users.

3. Edge Networks and CDN — Speed Matters

Imagine your origin server is in the US, but a user in Southeast Asia wants to load your website. Without any optimization, every single request travels across the Pacific Ocean and back. That’s slow.

This is where Edge Networks and CDN (Content Delivery Network) come in.

How it works:

  1. Your original content lives on the Origin Server (e.g., in us-east-1)
  2. AWS caches copies of your static content (images, CSS, JS, videos) at PoP / Edge Locations around the world
  3. When a user in Singapore requests your site, they get the cached version from the nearest PoP — not from the US
  4. Result: dramatically lower latency

CDN vs Edge Network — are they the same thing?

Not exactly. The Edge Network is the infrastructure — the distributed network of servers worldwide. CDN is the most well-known use case of that infrastructure. In practice, people use the terms interchangeably, and that’s mostly fine.

AWS’s CDN service is called CloudFront, and it leverages these Edge Locations.

4. Virtualization and the Hypervisor

Here’s where it gets interesting. When you launch an EC2 instance, you’re not getting a dedicated physical server. Here’s what’s actually happening:

  1. Host Computer → The physical AWS server rack in a data center
  2. Host OS → The operating system running on that physical machine
  3. Hypervisor → Software that sits on top of the Host OS and splits the physical machine into multiple virtual machines
  4. Your EC2 Instance → One of those virtual machines

So if a physical server has 64 CPUs and 256 GB RAM, the hypervisor might split it into four isolated instances of 16 CPUs / 64 GB RAM each. Different customers can be using the same physical hardware without ever knowing about each other — completely isolated.

AWS built their own hypervisor called Nitro, which operates at the hardware level for minimal performance overhead.

Key takeaway: EC2 instances are virtual slices of physical servers, managed by a hypervisor. Multiple instances from different customers can live on the same physical machine, fully isolated from each other.

5. The Shared Responsibility Model — Who’s Responsible for What?

This is probably the most important concept for your certification exam. AWS and the customer share security responsibilities, but the line between them is very clear.

Security OF the Cloud → AWS’s Job

AWS is responsible for protecting the infrastructure that runs all the services:

  • Physical security — data center access, cameras, biometric entry
  • Hardware — servers, storage, networking equipment
  • Software — compute, storage, database, networking services
  • Global infrastructure — Regions, Availability Zones, Edge Locations
  • Host OS & Hypervisor — you can’t even access these

Security IN the Cloud → Your Job

You are responsible for everything you put in and configure on the cloud:

  • Customer data — whatever you upload, store, or process
  • Platform, applications & IAM — who has access to what, roles, permissions, secret keys
  • OS & firewall configuration — if you launched an EC2 with Ubuntu, patching it is on you
  • Encryption — client-side, server-side, in-transit, at-rest decisions
  • Network traffic protection — security groups, NACLs, VPN configurations

The Three Control Categories

Category Who? Examples
Inherited AWS only Physical & environmental security, host OS, physical servers
Shared Both Patch management, configuration management, awareness & training
Customer-Specific Customer only Guest OS, custom applications, data encryption strategies

Quick Quiz — Test Yourself

Question Answer
Patching your EC2 instance’s operating system? You
Guest OS security patches? You
Running the host OS and virtualization layer? AWS
Managing IAM user access and secret keys? You
Maintaining the server under your Lambda functions? AWS
Physical security of data centers? AWS
Encryption-at-rest strategy for your RDS database? You

Simple rule of thumb: If you can configure it in the AWS Console or CLI → it’s your responsibility. If you can’t even touch it → it’s AWS’s responsibility. If both sides need to do their part → it’s shared.

Think of it like renting an apartment: AWS gives you a secure building (locked doors, fire alarms, security guards). But whether you lock your own door, put your valuables in a safe, or leave your windows open — that’s entirely on you.

6. AWS Support Plans — Developer vs Business

When you create an AWS account, you’ll need to choose a support plan. Here’s the practical difference between the two most common ones:

Feature Developer (~$29/mo) Business (~$100/mo or % of usage)
Who can open tickets 1 person (primary contact) Unlimited team members
Response time (critical) 12 hours 1 hour
Support channels Email only Email + Phone + Chat
Trusted Advisor Limited checks Full access
Third-party software support No Yes

Which one should you pick?

  • Developer → Great for learning, experimenting, and building prototypes. Start here if you’re just getting started.
  • Business → Essential when you’re running production workloads with real users. The 1-hour critical response time alone is worth it when something goes down.

Good news: You can start with Developer and upgrade to Business anytime from the AWS Console (Support Center > Change Plan). Billing is prorated, so you only pay for what you use. You can also downgrade later if needed.

Wrapping Up

Before diving into specific services like S3, Lambda, or DynamoDB, make sure these foundational concepts are solid:

  1. Cloud = renting virtual resources from physical infrastructure over the internet
  2. Regions → AZs → Edge Locations form the backbone of AWS’s global presence
  3. CDN / Edge Networks cache content close to users for speed
  4. Hypervisors split physical servers into isolated virtual machines (EC2 instances)
  5. Shared Responsibility Model — know what’s yours vs what’s AWS’s (this will be on the exam)
  6. Support Plans can be upgraded/downgraded as your needs evolve

These aren’t glamorous topics, but they’re the bedrock everything else is built on. Nail these, and the rest of your certification journey will make a lot more sense.

Happy cloud learning! If you found this helpful, drop a reaction or follow for more AWS certification notes.

5 AI Agent Patterns Every Developer Should Know in 2026

AI agents are moving from research demos to production systems. But most tutorials still show toy examples. Here are 5 battle-tested patterns that actually work at scale.

1. ReAct (Reasoning + Acting)

The most versatile pattern. The agent thinks about what to do, takes an action, observes the result, and repeats.

def run_react_agent(task, tools, max_steps=10):
    messages = [{"role": "user", "content": task}]

    for step in range(max_steps):
        response = client.messages.create(
            model="claude-sonnet-4-20250514",
            tools=tools,
            messages=messages
        )

        if response.stop_reason == "tool_use":
            tool_results = execute_tools(response)
            messages.extend([
                {"role": "assistant", "content": response.content},
                {"role": "user", "content": tool_results}
            ])
        else:
            return response.content[0].text

When to use: General-purpose tasks — research, data analysis, customer support.

2. Router Pattern

Instead of one agent doing everything, use a lightweight router to dispatch to specialized agents.

class RouterAgent:
    def __init__(self):
        self.agents = {
            "code": CodeAgent(),
            "research": ResearchAgent(),
            "writing": WritingAgent(),
        }

    def route(self, task):
        category = classify_task(task)  # haiku-level model
        return self.agents[category].run(task)

Why it works: Specialized agents with focused system prompts outperform generalist agents by 30-40% on benchmarks. And routing with a small model costs <$0.001 per request.

3. Tool-Use with Fallback Chain

Production agents need graceful degradation. If Tool A fails, try Tool B. If both fail, fall back to the LLM’s knowledge.

class FallbackToolAgent:
    def execute_with_fallback(self, tool_name, params):
        try:
            return self.tools[tool_name](**params)
        except Exception:
            pass

        fallback = self.fallbacks.get(tool_name)
        if fallback:
            try:
                return fallback(**params)
            except Exception:
                pass

        return self.llm_fallback(tool_name, params)

Key insight: In production, tools fail 5-15% of the time (API timeouts, rate limits, data issues). Without fallbacks, your agent fails 5-15% of the time too.

4. Multi-Agent with Shared Memory

When tasks are complex enough to need multiple agents, they need to share context efficiently.

class SharedMemory:
    def __init__(self):
        self.facts = {}
        self.history = []

    def add_fact(self, agent, key, value):
        self.facts[key] = {"value": value, "source": agent}
        self.history.append({"agent": agent, "action": "added", "key": key})

    def get_context_for(self, agent):
        return {k: v for k, v in self.facts.items()
                if self._is_relevant(k, agent)}

The mistake everyone makes: Sharing the entire conversation history between agents. This explodes token usage. Instead, share structured facts.

5. Human-in-the-Loop Checkpoints

The most important pattern for production: let the agent work autonomously, but pause for human approval at critical points.

class CheckpointAgent:
    def __init__(self, checkpoints):
        self.checkpoints = checkpoints

    async def run(self, task):
        plan = self.create_plan(task)

        for step in plan:
            if step.name in self.checkpoints:
                approved = await self.request_human_approval(step)
                if not approved:
                    return self.handle_rejection(step)

            result = await self.execute_step(step)

        return result

Rule of thumb: Any action that’s hard to reverse (sending emails, making payments, modifying production data) should have a checkpoint.

Framework Comparison (Quick Reference)

Framework Best For Learning Curve
LangGraph Complex workflows with branching Moderate
CrewAI Multi-agent collaboration Low
Claude Agent SDK Tool-use agents Low
OpenAI Agents SDK GPT-based agents Low
Custom (no framework) Simple agents, full control Varies

Next Steps

Originally published on paxrel.com

Mutable tags. 10,000 pipelines. One credential. — What the Trivy attack taught me about implicit trust

A few days ago I was designing a GitHub Actions pipeline with security scanning tools. Choosing what to integrate, how to structure it, what permissions to give it — especially for the context of the project I was building it for. The kind of work that feels productive — you’re building something that will improve the team’s security posture.

That’s when I found out what had happened to Trivy.

On March 19, 2026, TeamPCP compromised the most widely used open-source vulnerability scanner in the cloud-native ecosystem. They didn’t hack a business application. They didn’t exploit a vulnerability in production code. They compromised the tool that thousands of organizations use to find vulnerabilities in their own applications. The security scanner became the weapon.

That made me stop. Not to throw the pipeline away — but to rethink from what principles I was building it.

This post is not a threat intelligence analysis. I’m a practitioner who is learning more and more about building security pipelines and who reflected on this case. What I found along the way changed how I think about trust in external dependencies.

What exactly happened?

The attack wasn’t a single event — it was a multi-phase campaign that lasted several days and started earlier than most people think.

Three weeks before March 19, an automated bot called hackerbot-claw exploited a misconfigured workflow in the Trivy repository and stole a Personal Access Token. Aqua Security detected the incident and rotated credentials — but the rotation was incomplete. TeamPCP retained access to the credentials that survived. That’s what made everything that followed possible. [Palo Alto Networks]

On March 19 at 17:43 UTC, using those retained credentials, TeamPCP compromised three components simultaneously:

The Trivy binary. A malicious version — v0.69.4 — was published across all official distribution channels: GitHub Releases, Docker Hub, GHCR, ECR Public, deb/rpm repositories, and get.trivy.dev. The scanning logic lives in this binary. The other two components are wrappers that invoke it. [Wiz Research]

trivy-action. The GitHub Action most teams use to integrate Trivy into their pipelines. TeamPCP force-pushed 76 of 77 version tags to point at malicious commits. Pipelines referencing these actions by tag began executing the attacker’s code on their next run — with no visible change to the tag name or the releases page. [Microsoft Security Blog]

setup-trivy. The Action that installs the binary. All 7 existing tags were compromised in the same way.

The payload was an infostealer that harvested SSH keys, cloud tokens, Kubernetes credentials, and pipeline environment variables — all while Trivy ran normally and produced the expected output. To an engineer reviewing the logs, the step appeared successful. [SANS Institute]

Exposure windows ranged from 3 to 12 hours depending on the component. Three days later, on March 22, TeamPCP published additional malicious images on Docker Hub — v0.69.5 and v0.69.6 — using separately compromised Docker Hub credentials, extending exposure by another ~10 hours. [Legit Security]

According to SANS Institute, more than 10,000 CI/CD workflows are reported to have been affected.

They didn’t exploit code — they exploited trust

When most teams think about an attack, they picture someone finding a buffer overflow, an SQL injection, an RCE. A technical vulnerability in the code that needs to be patched.

TeamPCP did none of that.

They didn’t find a bug in Trivy. They didn’t break any cryptographic algorithm. They exploited something much harder to patch: the implicit trust logic that organizations place in their dependencies. The premise that if a tool comes from the official vendor, through the official channel, with the official tag — it’s safe.

That premise is what failed.

There’s a brutal irony in how the impact was distributed. The most diligent teams — the ones who had integrated Trivy into every PR, every merge, every deploy — were the most exposed. The more disciplined the team was about running their security pipeline, the more times the infostealer ran. The good practice became the attack vector. [SANS Institute]

This is not an argument to stop scanning. It’s an argument to understand that trusting an external tool without verifying its integrity is exactly the same as trusting a user without verifying their identity. In IAM, nobody accepts that. In dependencies, we accept it all the time.

The expansion of the attack confirms it. TeamPCP didn’t stop at Trivy. On March 23 they compromised Checkmarx KICS — the infrastructure-as-code scanner. On March 24 they reached LiteLLM on PyPI, using credentials stolen from BerriAI’s Trivy pipeline. According to SANS Institute, one stolen token propagated across five distinct ecosystems: CI/CD, npm, Docker, PyPI, and AI infrastructure. [Arctic Wolf]

TeamPCP isn’t targeting business applications. It’s targeting the security tooling ecosystem — exactly the tools that the most security-conscious teams have integrated into their pipelines.

Mutable tags: not the vector, but the multiplier

When the attack was reported, much of the media focus fell on mutable tags. That makes sense — it’s the most striking technical detail. But it’s worth understanding exactly what role they played, because they weren’t the entry vector — they were what turned a single point of access into a massive problem.

To understand the difference, three concepts need to be separated.

The attack vector was the retained credential — the Personal Access Token that survived an incomplete rotation from a prior incident. That credential with write permissions over Aqua Security’s repositories is what gave TeamPCP initial access. Without it, nothing that followed would have been possible. [Palo Alto Networks]

The attack surface was the CI/CD pipelines of thousands of organizations referencing Trivy and its GitHub Actions by tag. Every pipeline running uses: aquasecurity/[email protected] was an exposed surface — not because it had a vulnerability, but because its trust model depended on the immutability of a tag that wasn’t immutable. According to SANS Institute, more than 10,000 CI/CD workflows were part of that surface.

Mutable tags were the multiplier. Once TeamPCP had access, tag mutability allowed them to silently redirect 76 of 77 tags in trivy-action and all 7 tags in setup-trivy to malicious commits — with no visible change in names, dates, or release pages. [Microsoft Security Blog]

Now, the fundamental difference between a tag and a digest.

A tag is a named pointer — v0.35.0, latest, v0.69.4. In Git and container registries, that name can be redirected to any commit or image without the name changing. No notification. No alert. No visible change on the releases page.

A digest is the SHA256 of the actual content — sha256:a3f8d2c1.... It’s immutable by definition. If the content changes, the digest changes. It can’t be forged, it can’t be redirected. Referencing a dependency by digest anchors it to a specific verified piece of content.

Any pipeline referencing those actions by tag began executing malicious code on its next run. Without any visible change. Without any alert. If those same pipelines had referenced the actions by digest, the force-push would have had no effect. The digest would still point to the original commit. The blast radius would have been dramatically smaller. [Legit Security]

Supply chain security = least privilege applied to dependencies

There’s a principle any engineer working with AWS knows by heart: least privilege. You don’t give a role more permissions than it needs. You don’t create access keys when you can use temporary roles. You don’t leave a * in a Resource when you can specify the exact ARN.

It’s the most repeated principle in cloud security. And yet, when it comes to external dependencies, we systematically ignore it.

When a pipeline runs uses: aquasecurity/[email protected], it’s placing full trust in that tag — without verifying its integrity, without anchoring to specific content, without questioning whether the pointer still points to what it pointed to yesterday. It’s the equivalent of giving AdministratorAccess to a role because “it’s easier.” It works. Until it doesn’t.

Supply chain security isn’t a separate domain from the security you already practice. It’s the same least privilege principle applied to a different level: your dependencies. The question isn’t “do I trust this tool?” — it’s “what verification do I have that what I’m executing is exactly what I think it is?”

The expansion of the attack illustrates why this matters at scale. TeamPCP didn’t need to compromise each organization individually. It compromised a central tool in the ecosystem and let implicit trust do the rest. LiteLLM was compromised because its pipeline used Trivy — the infostealer stole the PyPI publishing token, and from there TeamPCP published malicious versions with 3.6 million daily downloads. [SANS Institute]

One token. Five compromised ecosystems. That’s the geometry of a well-executed supply chain attack.

What makes this case especially uncomfortable is that the victims weren’t careless teams. They were teams that had invested in security, that scanned their pipelines, that used cloud-native tooling. Diligence didn’t protect them — because the diligence was applied inside the trust perimeter, not at the perimeter itself.

The solution is not to stop using external tools

The wrong conclusion from this incident would be to stop using Trivy, to distrust all open-source tools, or to build everything in-house. That’s neither viable nor the right lesson.

The lesson is that trust in external dependencies needs to be explicit and verifiable — not implicit and assumed.

Digest pinning

The most concrete and immediate change is to reference GitHub Actions by digest instead of by tag.

Instead of this:

- uses: aquasecurity/[email protected]

This:

- uses: aquasecurity/trivy-action@sha256:57a97c7...

The digest anchors the pipeline to a specific verified piece of content. If someone force-pushes the tag, the pipeline keeps executing the original commit. Tag mutability stops being a problem because the pipeline doesn’t depend on the tag. [Legit Security]

The obvious objection is that this makes updates harder — and it’s valid. A fixed digest doesn’t update itself. That’s where the second part comes in.

Dependabot and Renovate

Dependabot and Renovate can manage GitHub Actions updates automatically, including digest pinning. When a new verified version is released, they open a PR with the updated digest. The team reviews, approves, and the pipeline updates in a controlled and auditable way.

The combination closes the loop: digest pinning eliminates exposure to mutable tags, and Dependabot/Renovate eliminates the friction of maintaining digests manually.

Confirmed safe versions

For those using Trivy at the time of the incident, confirmed safe versions are: Trivy binary v0.69.3 or earlier, trivy-action v0.35.0 at commit 57a97c7, setup-trivy v0.2.6 at commit 3fb12ec. Any reference to v0.70.0 in logs should be treated as suspicious — the attacker attempted to publish that version but was stopped before the tag was pushed. [Legit Security]

Secrets: less is more

One thing this incident makes clear is the problem of pipelines that inherit more secrets than they need. If a scanning job doesn’t need production credentials, it shouldn’t have them — regardless of whether they’re temporary or static. Applying least privilege to what secrets get passed to each job reduces the blast radius when a tool is compromised.

Immediately rotate any credential that was exposed to a pipeline that ran compromised versions of Trivy between March 19 and March 22. That includes GitHub tokens, cloud credentials, registry tokens, SSH keys, and database passwords. [Legit Security]

Closing — what happened in LATAM

All of the above reflection could remain theoretical if it weren’t for someone in our community who lived this in real time.

Alejandro Castañeda, AWS Community Builder and Cloud Engineer from Colombia, shared on LinkedIn what happened to his team. His pipeline was compromised. The infostealer ran on a self-hosted runner inside his EKS cluster and sent approximately 80KB to the attacker’s server. To put that in perspective: 80KB is enough to carry away all the secrets from a complete pipeline.

And yet, they reviewed CloudTrail top to bottom and the result was zero lateral movement. No API calls from the attacker’s IP. No IAM user creation, no policy changes, no resource access.

Why?

Because Alejandro’s team had made an architecture decision ahead of time, when they were defining the foundations of their infrastructure: OIDC with IAM Roles instead of static access keys. Their pipelines assumed temporary roles that expired in minutes. By the time the attacker had the credentials in hand, they were already worthless. And the role’s trust policy only allowed use from GitHub — so even if they hadn’t expired, they couldn’t be used from anywhere else.

If they had had static access keys stored as GitHub secrets, the story would be completely different. The attacker would have had access to ECR to inject malicious images into production containers, and to Secrets Manager to read database credentials and financial service tokens.

The difference between “our secrets were stolen and nothing happened” and a real disaster was an architecture decision that nobody made thinking about this specific attack. They made it because it was the right way to build.

That’s what I take from this incident. Not the list of affected versions — that changes. Not the name of the threat actor — that changes too. What doesn’t change is the principle: design so that when someone compromises a dependency, they don’t find anything useful on the other side.

Security isn’t about building a perfect wall. It’s about making sure that when someone jumps it, there’s nothing useful on the other side.

About the author

Gerardo Castro is an AWS Security Hero and Cloud Security Engineer focused on LATAM. Founder and Lead Organizer of the AWS Security Users Group LatAm. He believes the best way to learn cloud security is by building real things — not memorizing frameworks. He writes about what he builds, what he finds, and what he learns along the way.

🔗 GitHub: gerardokaztro
🔗 LinkedIn: gerardokaztro

Porting Test Drive II from SNES to PC, Part 37: Narrowing the SNES clock-slot timing drift

SNES Select Opponent BG1 surface

Porting Test Drive II from SNES to PC, Part 37: Narrowing the SNES clock-slot timing drift

The previous checkpoint closed the organic default-rival path:

L00C20B -> 01:C1D2 -> L00BE76 -> L008B87 -> 01:902D -> active_main = 02:9016

That left one narrow front-end problem:

can the fourth Select Opponent clock slot be chosen organically in the same
live corridor?

This checkpoint does not close that slot yet.

It does something almost as useful:

it proves why the obvious fixed-frame approach is still failing.

SNES Select Opponent BG1 surface

The remaining problem is not the button map

Static bank-1 reading at L00C32A..L00C371 already showed that the input loop
applies vertical and horizontal bits in sequence.

So right+down is not being discarded because of a bad button interpretation.

The problem is timing.

More precisely:

the live 01:C1D2 window itself keeps sliding when the earlier confirmation
windows move.

Two bounded follow-ups prove the drift

In v3, I moved right+down later and kept start relatively early.

That run reaches:

  • L00C20B at frame 1600
  • first 01:C1D2 only at 1615..1617

So right+down at 1600..1605 was still too early.

The run simply fell through the already-known default-rival path again.

In v4, I delayed the later confirmation window to create more room.

That changed the corridor itself:

  • L00C20B moved to frame 1613
  • first 01:C1D2 moved to 1628..1637

So the delayed right+down at 1620..1625 was still too early too.

This time the run only reached L00BE76 and then stayed on the later
01:BE43 callback in the sampled window, without falling through to
L008B87 or 01:902D.

Why this matters

This is a real narrowing, not a failed rerun with no information.

The remaining clock-slot problem is now better described as:

  • callback-relative timing drift

not as:

  • uncertain button semantics
  • generic “needs later frames”

That changes the next probe design.

The next move is stricter now

The next defensible probe is no longer “slide the absolute frame numbers
forward again”.

It is:

  • overlap right+down with the live 01:C1D2 window itself
  • or trigger the direction change relative to first 01:C1D2

In other words, the problem is now local enough that the next step should be
callback-relative instead of frame-absolute guesswork.