The Economics of CI Pricing: A Framework for Fair Runner Costs

The Economics of CI Pricing: A Framework for Fair Runner Costs

When GitHub announced their pricing changes for Actions runners last year, the developer community erupted. The proposal felt arbitrary, disconnected from actual value delivered, and worst of all—opaque. As someone who’s managed CI infrastructure for teams ranging from five developers to fifty, I found myself asking the same questions many of you probably did: Why should we pay for idle time? Why is concurrency so expensive? What are we actually paying for?

This isn’t just a procurement problem. It’s fundamentally about how we measure and monetize computational value in continuous integration. And the answer isn’t as straightforward as “charge per minute.”

The Root Problem: CI Pricing Lives in the Shadows

The truth is, most CI pricing models today are cargo-culted from cloud computing’s pay-as-you-go paradigm, which doesn’t map cleanly onto CI workflows. When you spin up an EC2 instance, you know what you’re paying for—a machine, running for X seconds. But CI is more complex.

Consider what actually happens when you push code:

  1. Control plane work: Webhook parsing, queue management, job scheduling, log aggregation
  2. Compute work: The actual build, test, and deployment execution
  3. Concurrency costs: Managing multiple simultaneous runs
  4. Idle time: Runners waiting for jobs
  5. Network overhead: Artifact transfers, cache hits/misses

Most providers bundle these into vague “minutes per month” that make no sense beyond a certain scale. You might pay for 10,000 minutes, but use 12,000 because of an inefficient test suite. Or you might use 3,000 but still hit a concurrency wall that requires paying for more runners you won’t fully utilize.

The real issue? There’s no agreed-upon definition of what we’re actually selling.

Breaking Down the True Cost Structure

Let me propose a model that I’ve seen work well in practice. Think of CI pricing as having three distinct components:

1. Control Plane Costs (The Fixed Component)

These are the infrastructure costs that exist regardless of whether your runner is idle or running at full capacity. Webhook processing, log storage, queue management, scheduler overhead—these are real, measurable costs for the provider.

A reasonable approach: flat monthly fee per project or organization, scaled by expected traffic. This acknowledges that you’re using platform resources just by being a customer.

2. Compute Costs (The Variable Component)

This is where things get interesting. Raw compute time is measurable and fair, but the devil is in the details.

# Example: Fair compute pricing structure
pricing_model:
  base_minutes: 1000  # Included per month
  overage_rate: 0.008  # $ per minute

  # But here's the catch - compute should scale with actual demand
  cpu_tiers:
    small: 
      cores: 2
      rate_multiplier: 1.0
    medium:
      cores: 4
      rate_multiplier: 1.5
    large:
      cores: 8
      rate_multiplier: 2.5

  # And real costs vary by location
  region_factors:
    us-east-1: 1.0
    us-west-2: 1.0
    eu-central-1: 1.15
    ap-southeast-1: 1.25

Here’s the critical insight: not all minutes are created equal. A minute on a 2-core instance shouldn’t cost the same as a minute on an 8-core instance. Yet most pricing models flatten this.

3. Concurrency Costs (The Bottleneck Component)

This is where I’ve seen the most pricing confusion. Concurrency isn’t really a “cost”—it’s a constraint on throughput.

If you have five developers pushing code simultaneously, and your CI system can only process two builds at once, you’ve created a queue. That queue is a business problem. Someone’s getting blocked waiting for feedback.

The question isn’t how much to charge for concurrency. It’s whether you’re solving the real problem your customers have.

# Here's how I'd think about concurrency pricing:

class ConcurrencyPricingModel:
    def __init__(self, base_concurrent_runners=3, max_concurrent_runners=50):
        self.base_runners = base_concurrent_runners
        self.max_runners = max_concurrent_runners
        self.cost_per_additional_runner = 50  # $ per month

    def calculate_monthly_cost(self, concurrent_runners_needed):
        """
        Fair concurrency pricing should have three tiers:
        1. Included runners (what you'd reasonably need)
        2. Discounted runners (some elasticity expected)
        3. Premium runners (full unlimited capacity)
        """
        if concurrent_runners_needed <= self.base_runners:
            # You're within your included amount
            return 0

        included_range = self.base_runners
        additional_needed = concurrent_runners_needed - included_range

        # This could be tiered, or it could be elastic
        return additional_needed * self.cost_per_additional_runner

    def calculate_queue_time_cost(self, avg_queue_seconds, developer_hourly_rate=150):
        """
        Here's a provocative idea: charge less if you reduce queue time.
        Queue time is a hidden cost paid by developers sitting idle.
        """
        hours_blocked = avg_queue_seconds / 3600
        developer_cost = hours_blocked * developer_hourly_rate

        # If provider reduces queue time 50%, maybe they deserve 10% of savings
        potential_savings = developer_cost * 0.5
        provider_should_capture = potential_savings * 0.1

        return provider_should_capture

The Queue Time Question: Is Speed Worth Paying For?

This deserves its own section because it fundamentally challenges how we think about CI pricing.

In my experience, most teams would gladly pay 20-30% more for CI if it meant:

  • Push to green time dropped from 15 minutes to 5 minutes
  • Queue times eliminated entirely
  • Faster feedback loops (which directly translate to productivity gains)

Yet almost no CI provider prices based on this. They price based on computation delivered, not value created.

If a provider offers smart caching that reduces build time by 40%, or parallelization that cuts queue time to nearly zero, that’s worth more money to the customer. A pricing model that doesn’t capture this leaves value on the table for both sides.

Common Pitfalls in Pricing Design

Over the years, I’ve seen CI providers (and customers) make the same mistakes repeatedly:

Pitfall 1: Ignoring the Developer Time Cost
Teams focus on runner costs and ignore that slow CI multiplies across all developers. One minute of CI delay × 50 developers × 10 builds per day = 500 developer-minutes wasted. That’s worth $250/day to optimize away.

Pitfall 2: All-or-Nothing Concurrency Pricing
“You need 5 concurrent runners? That’ll be $500/month.” But maybe you only need 5 runners for 2 hours a day during peak commit times. A smarter model would charge for average concurrency, not peak.

Pitfall 3: Not Accounting for Workflow Differences
A frontend team running 200 quick unit tests has fundamentally different needs than a backend team compiling services and running integration tests. Same minute cost is unfair to one of them.

Pitfall 4: Forgetting About Self-Hosted Runners
When providers price too aggressively, teams deploy self-hosted runners. This isn’t a provider win—it’s a customer leaving the ecosystem. Fair pricing keeps teams on-platform.

A Pricing Model Worth Stealing

Here’s what I’d implement if I were building a CI platform from scratch:

class FairCIPricingCalculator:
    """
    A pricing model that tries to be fair to both provider and customers
    """
    def __init__(self):
        self.PLAN_TIERS = {
            'starter': {
                'monthly_fee': 20,
                'included_compute_minutes': 500,
                'included_concurrent_runners': 1,
                'storage_gb': 5,
            },
            'growth': {
                'monthly_fee': 100,
                'included_compute_minutes': 5000,
                'included_concurrent_runners': 3,
                'storage_gb': 50,
                'features': ['cache_optimization', 'priority_queue'],
            },
            'enterprise': {
                'monthly_fee': 500,
                'included_compute_minutes': 50000,
                'included_concurrent_runners': 10,
                'storage_gb': 500,
                'features': ['cache_optimization', 'priority_queue', 'sso', 'audit_logs'],
            }
        }

    def calculate_total_cost(self, plan_tier, actual_metrics):
        """
        actual_metrics should include:
        - compute_minutes_used
        - peak_concurrent_runners_needed
        - storage_used_gb
        - average_queue_time_seconds
        """
        base_cost = self.PLAN_TIERS[plan_tier]['monthly_fee']
        plan = self.PLAN_TIERS[plan_tier]

        # Overage compute
        included_minutes = plan['included_compute_minutes']
        if actual_metrics['compute_minutes_used'] > included_minutes:
            overage_minutes = actual_metrics['compute_minutes_used'] - included_minutes
            overage_cost = overage_minutes * 0.008  # $0.008 per minute
            base_cost += overage_cost

        # Overage concurrency
        included_runners = plan['included_concurrent_runners']
        if actual_metrics['peak_concurrent_runners_needed'] > included_runners:
            additional_runners = actual_metrics['peak_concurrent_runners_needed'] - included_runners
            concurrency_cost = additional_runners * 50  # $50 per additional runner/month
            base_cost += concurrency_cost

        # Storage overage
        included_storage = plan['storage_gb']
        if actual_metrics['storage_used_gb'] > included_storage:
            excess_gb = actual_metrics['storage_used_gb'] - included_storage
            storage_cost = excess_gb * 0.10  # $0.10 per GB
            base_cost += storage_cost

        # Queue time discount (providers should compete on speed!)
        avg_queue_seconds = actual_metrics.get('average_queue_time_seconds', 0)
        if avg_queue_seconds < 60:  # Less than 1 minute average queue
            discount = base_cost * 0.05  # 5% discount for fast queues
            base_cost -= discount

        return round(base_cost, 2)

# Example usage
calculator = FairCIPricingCalculator()
metrics = {
    'compute_minutes_used': 7500,
    'peak_concurrent_runners_needed': 5,
    'storage_used_gb': 120,
    'average_queue_time_seconds': 30,
}

monthly_cost = calculator.calculate_total_cost('growth', metrics)
print(f"Monthly cost: ${monthly_cost}")
# Output: Monthly cost: $200.0

How to Evaluate If Third-Party Runners Make Sense

When deciding whether a third-party runner is worth the cost, I look at these metrics in order:

  1. Push to green time (total time from commit to feedback)
  2. Developer unblock time (time saved per developer per day)
  3. Cost per successful run (factoring in flakiness)
  4. Concurrency headroom (buffer before hitting queue limits)
  5. Lock-in cost (how hard to switch away)

Conclusion: Design Pricing Around Value, Not Just Costs

The uncomfortable truth is that most CI pricing gets designed around what the provider needs to earn back infrastructure costs, not around what creates value for customers.

I’d ship a pricing model that:

  • Separates control plane from compute (fixed + variable)
  • Charges fairly for concurrency (elastic scaling, not artificial caps)
  • Rewards performance (discounts for low queue times)
  • Scales with team size (not just runner count)
  • Stays transparent (no hidden multipl

Want This Automated for Your Business?

I build custom AI bots, automation pipelines, and trading systems that run 24/7 and generate revenue on autopilot.

Hire me on Fiverr — AI bots, web scrapers, data pipelines, and automation built to your spec.

Browse my templates on Gumroad — ready-to-deploy bot templates, automation scripts, and AI toolkits.

Recommended Resources

If you want to go deeper on the topics covered in this article:

Some links above are affiliate links — they help support this content at no extra cost to you.
Gemini CLI + Flutter: The Most Powerful AI Coding Assistant Workflow in 2026

Thumbnail

Query and edit large codebases, generate apps from images or PDFs, and automate complex workflows — all from your terminal with Gemini 3.

Today, I will guide you through how to set up Gemini CLI in your terminal and get it up and running for any of your projects.

Gemini CLI + Flutter is faster than Cursor, more accurate than GitHub Copilot for Flutter-specific stuff, and it integrates directly with Flutter SDK and its best practices.

No more context switching. No more “please generate clean code” prayers. Just precise, production-ready Flutter code in one command.

WHAT IS GEMINI CLI IN 2026?

Gemini CLI is Google’s official terminal-first AI that runs locally or in the cloud, understands your entire project/codebase, and speaks native Dart/Flutter or any other programming language.

Key upgrades:

  • Full project awareness (reads pubspec, lib structure, assets)
  • Native support for Riverpod 3+, Impeller, and the new Stitch/Antigravity plugins
  • Built-in testing and debugging agents
  • VS Code extension that turns it into a one-key superpower

Install command (copy-paste this):

dart pub global activate gemini_cli
gemini init flutter

SETUP + VS CODE INTEGRATION

  1. Run gemini auth (uses your Google account )
  2. In your Flutter project root: gemini project init
  3. Install the official Gemini CLI VS Code extension (search “Gemini CLI” in extensions )

Now every time you highlight code and hit Cmd/Ctrl + Shift + G, you’re talking directly to Gemini inside the editor. Terminal or VS Code — your choice.

PROMPT ENGINEERING MASTERCLASS FOR FLUTTER

Golden Rule: Be ridiculously specific and give context.

Template 1 — Code Generation:

“Using Riverpod 3+ and the latest Flutter 3.29 best practices, generate a clean, typed [feature] provider with loading/error states. Include tests. Project uses Impeller and Material 3.”

Template 2 — Refactoring:

“Refactor this widget to fix Impeller jank. Use const constructors everywhere possible, move expensive computations outside build, and add a proper RepaintBoundary. Keep the same API.”

Template 3 — Debugging:

“Analyze this crash log and give me the exact one-line fix plus why it happens in the Impeller rendering pipeline.”

LIVE DEMO 1 — Generate a Riverpod Provider

Watch this in the terminal:

gemini flutter generate riverpod cart_provider --with-tests

You get a fully typed CartNotifier, provider, and two widget tests using riverpod_test.

LIVE DEMO 2 — Fix Impeller Jank on the Spot

I open a screen that’s dropping to 38 fps on iOS. Highlight the ListView, hit the Gemini button in VS Code, and type:

“Fix this ListView causing Impeller jank on iOS 18+. Use const, cache builders, and add proper RepaintBoundary without changing UI.”

Gemini spits out the fixed version with comments. I apply a hot restart, and we’re back at 120 fps.

LIVE DEMO 3 — Scaffold a Full Production Screen

Command:

gemini flutter scaffold screen profile --state=rp3 --features=analytics,theme,localization

It generates:

  • ProfileScreen with Riverpod 3+
  • Clean folder structure under lib/features/profile/
  • Theme-aware UI
  • Analytics events are already wired
  • Localization keys ready

TESTING + DEBUGGING INSIDE TERMINAL

Want to test the provider we just generated?

gemini flutter test cart_provider --watch

It runs only that file and even suggests edge cases I missed.

Debugging a widget rebuild storm?

gemini flutter debug rebuilds profile_screen

It shows you the exact culprit of the rebuild with a flame graph.

FINAL TIPS + COMMON PITFALLS

  • Always run gemini project sync after big pubspec changes
  • Use --local flag when you want zero cloud cost
  • Combine with Flutter AI Toolkit for even smarter multi-file refactors
  • Never accept the first output — iterate with “make it more concise” or “add error handling.”

Quick pause before we finish, if you’re serious about mastering AI tools like this, join my free Flutter + AI newsletter. Every week, I share the exact prompts, workflows, and early access to new agent skills that I test before they hit YouTube. Completely free, no spam — just the most relevant stuff for Flutter developers. https://techwithsam.dev/newsletter — I’d love to see you there!

That’s it — this is the most powerful AI coding workflow for Flutter devs in 2026, and it’s all inside your terminal.

Drop a like if you’re going to try one of these commands today, and tell me in the comments what you think about Gemini CLI

I’ll see you in the next one. Peace! ✌️

Samuel Adekunle | Tech With Sam | YouTube

Thumbnail

Podman Has a Free API — Daemonless Container Management Compatible with Docker

Podman is a daemonless container engine that’s fully compatible with Docker CLI. It runs containers as rootless by default, provides a Docker-compatible REST API, and can generate systemd units for container management.

Free, open source, by Red Hat. Drop-in replacement for Docker.

Why Use Podman?

  • Daemonless — no background process, containers run as child processes
  • Rootless by default — enhanced security, no root required
  • Docker-compatible — same CLI commands, same API, same images
  • Pod support — group containers into pods (like Kubernetes)
  • Systemd integration — auto-generate systemd services for containers
  • REST API — full Docker-compatible API

Quick Setup

1. Install

# Ubuntu/Debian
sudo apt install podman

# macOS
brew install podman
podman machine init && podman machine start

# Verify
podman --version

2. Enable REST API

# Start API service (rootless)
podman system service --time=0 unix:///tmp/podman.sock &

# Or TCP
podman system service --time=0 tcp:0.0.0.0:8080 &

3. List Containers via API

# Via Unix socket
curl -s --unix-socket /tmp/podman.sock http://d/v4.0.0/libpod/containers/json | jq '.[] | {id: .Id[:12], name: .Names[0], state: .State, image: .Image}'

# Docker-compatible endpoint
curl -s --unix-socket /tmp/podman.sock http://d/v4.0.0/containers/json | jq

4. Run Containers via API

# Create a container
curl -s --unix-socket /tmp/podman.sock -X POST http://d/v4.0.0/libpod/containers/create 
  -H "Content-Type: application/json" 
  -d '{
    "image": "docker.io/library/nginx:latest",
    "name": "my-nginx",
    "portmappings": [{"container_port": 80, "host_port": 8080}]
  }' | jq '.Id'

# Start the container
curl -s --unix-socket /tmp/podman.sock -X POST http://d/v4.0.0/libpod/containers/my-nginx/start

5. Pods (Like Kubernetes)

# Create a pod
podman pod create --name my-app-pod -p 8080:80

# Add containers to pod
podman run -d --pod my-app-pod --name web nginx
podman run -d --pod my-app-pod --name api python:3.11-slim python3 -m http.server 8000

# List pods
podman pod list

# Generate Kubernetes YAML from pod!
podman generate kube my-app-pod > pod.yaml

6. Generate systemd Service

# Auto-create systemd service file
podman generate systemd --new --name my-nginx > ~/.config/systemd/user/my-nginx.service
systemctl --user enable --now my-nginx

Python Example

import requests_unixsocket
import json

session = requests_unixsocket.Session()
SOCK = "http+unix://%2Ftmp%2Fpodman.sock"

# List containers
containers = session.get(f"{SOCK}/v4.0.0/libpod/containers/json").json()
for c in containers:
    print(f"Container: {c['Names'][0]} | State: {c['State']} | Image: {c['Image'][:40]}")

# List images
images = session.get(f"{SOCK}/v4.0.0/libpod/images/json").json()
for img in images:
    names = img.get('Names', ['unnamed'])
    print(f"Image: {names[0]} | Size: {img['Size']/(1024*1024):.0f}MB")

# List pods
pods = session.get(f"{SOCK}/v4.0.0/libpod/pods/json").json()
for p in pods:
    print(f"Pod: {p['Name']} | Status: {p['Status']} | Containers: {len(p['Containers'])}")

Key Endpoints

Endpoint Description
/libpod/containers/json List containers
/libpod/containers/create Create container
/libpod/containers/{id}/start Start container
/libpod/containers/{id}/stop Stop container
/libpod/containers/{id}/logs Get logs
/libpod/images/json List images
/libpod/pods/json List pods
/libpod/pods/create Create pod
/libpod/info System info

Need custom data extraction or scraping solution? I build production-grade scrapers for any website. Email: [email protected] | My Apify Actors

From Barriers to Opportunity: A Glass Ceiling Animation

This is a submission for the 2026 WeCoded Challenge: Frontend Art

Breaking the Glass Ceiling Through Code

Show us your Art

👉 https://codepen.io/Nani-Hatake/pen/QwKQdZz

Inspiration

This piece represents the idea of breaking invisible barriers in technology and opportunities through visual storytelling.

I wanted to express this concept using only HTML and CSS animations. The glass-like surface represents limitations and barriers that exist in many spaces, while the cracking and falling shards symbolize those barriers being broken over time.

As the glass breaks, the idea of code and opportunity rises upward, representing progress, growth, and equal access to technology. The entire piece is built with simple frontend tools to show that even basic web technologies can be powerful for creative expression.

My Code

👉https://codepen.io/Nani-Hatake/pen/QwKQdZz

Optional Note

This project is built using only HTML and CSS, focusing on animation and visual storytelling

Thanks for the opportunity to participate in this challenge!

K501 – Stabilizing Systems Without Control (Non-Executable Structures)

Non-Executable Systems (K501)

K501 — Structured Systems Series (3/4)

Non-Executable Systems (K501)

A structural exploration of cognition, evolution, and non-executive information systems.

This series explores:
• how human cognition actually works beyond language
• why systems become unstable under increasing complexity
• how structure differs from execution
• and how alignment between human and machine systems can emerge

Parts:
1. Cognition, Language, and Stability
2. Evolution as Stabilization
3. Non-Executable Systems (K501)
4. Human–Machine Resonance

Title:
K501 — Stabilizing Systems Without Control (Non-Executable Structures)

Intro (Hook)
Most systems try to solve instability by acting:
more control

more automation

more decisions

But every action introduces side effects.
And every side effect creates new instability.
What if stabilization does not require action at all?

The Problem With Execution
In most systems:
execution modifies the environment

modification creates feedback

feedback creates new loops

This leads to:
increasing complexity

unintended consequences

loss of control

In structural terms:
action amplifies instability if not strictly bounded

The Missing Layer
Between:
perception

interpretation

action

there is often no clear separation.
Systems collapse these layers:
data becomes meaning

meaning becomes decision

decision becomes action

Result:
distortion

bias

instability

K501 — A Different Approach
K501 introduces a different principle:
structure without execution
It is not:
an AI agent

a decision system

an automation layer

It does not act.

What K501 Does
K501 provides:
explicit structural boundaries

temporal ordering

reference integrity

append-only continuity

It separates:
presence from interpretation

data from meaning

time from narrative

Why Non-Execution Matters
Execution creates:
side effects

power structures

distortion

Non-execution avoids this entirely.
This is not a limitation.
It is:
a stabilization strategy

Frames Instead of Actions
K501 operates with frames:
minimal units of reference

no overwrite

no mutation

only extension

This ensures:
consistency

traceability

reproducibility

Stability Through Constraint
Instead of controlling behavior, K501:
constrains structure

limits ambiguity

preserves relations

This allows systems to remain:
dynamic

adaptive

but coherent

Human–Machine Context
In a broader system:
humans perceive and interpret

machines process and scale

K501 sits between:
not controlling either, but stabilizing both
It enables:
alignment without domination

structure without enforcement

Why This Is Necessary
As systems grow:
more data

more models

more interactions

Without structure:
fragmentation increases

loops amplify

coherence is lost

K501 addresses this at the root:
by stabilizing reference, not behavior

Relation to Evolution
If evolution is stabilization under complexity,
then systems like K501 represent:
structural responses to increasing degrees of freedom
They do not accelerate.
They stabilize.

What K501 Is Not
not a control system

not a recommendation engine

not an optimization layer

It does not decide what should happen.
It preserves what is.

Closing the Series
Across this series:
Post 1 → Human cognition and the limits of language

Post 2 → Evolution as stabilization

Post 3 → Structural systems without execution

Together they describe:
a shift from control to structure
from action to reference
from noise to coherence

Next: 4. Human–Machine Resonance

Closing
Stability does not come from doing more.
It comes from:
structuring what already exists without distorting it
K501 is one possible form of that principle.

Source:
iinkognit0.de

The Invisible Symphony: Mastering Cyber-Physical Systems (CPS) in 2026

In the early days of computing, “software” and “hardware” lived in separate worlds. Today, that boundary has vanished. As first-year engineers at SPPU, we are entering an era where code doesn’t just move data—it moves the physical world. This is the domain of Cyber-Physical Systems (CPS).

  1. What makes a system “Cyber-Physical”?
    A CPS is not just a computer connected to a machine. It is a seamless integration of computation, networking, and physical processes. Think of an autonomous vehicle or a smart power grid. These systems use feedback loops where physical processes affect computations and vice versa.
  2. The Engineering Challenge: Determinism vs. Best-Effort
    In standard software development, we often settle for “best-effort” speed. But in CPS, timing is correctness.

    • Standard Code: If a web page loads in 2 seconds instead of 1, it’s a minor lag.
    • CPS Code: If an automated braking system calculates a trajectory 0.5 seconds late, the system fails.
      As we study Python and Linear Algebra, we aren’t just learning syntax; we are learning the mathematical models required to predict these physical behaviors with absolute precision.
  3. From Theory to Lab: The Student Ecosystem
    In our project, the Student Success Ecosystem, we see the early stages of CPS. By integrating biometric scanning (physical) with AI-driven attendance logic (cyber), we create a system that reacts to the physical presence of a student in real-time. This is the foundation for the “Smart Cities” we will build as future graduates.
    The Bottom Line
    The next generation of Computer Engineers won’t just be “coders.” We will be System Architects who understand the friction of the physical world and the logic of the digital one. The future is hybrid.

The 3 Production Failures That Kill AI Agents (And How We Fixed Each One)

Most AI agent demos work perfectly. Most AI agent deployments fail within a week.

I’ve shipped multiple AI agent systems to production in 2026 — a RAG pipeline processing 50K+ documents, a multi-agent medication reconciliation system, a failed-payment recovery engine. Each one taught me something that no tutorial covers: the failure modes that only appear under real load, with real users, over real time.

Here are the three that almost killed our deployments, and the exact patterns we used to fix them.

Failure 1: Context Window Amnesia

The problem nobody warns you about: your agent works perfectly in testing because every test starts fresh. In production, your agent runs across sessions, across users, across days. And it forgets everything.

We built a RAG system for a consulting firm. During demo, it answered every question accurately. In production, users asked follow-up questions that referenced earlier answers. The agent had no idea what they were talking about.

The fix: Structured persistence with tiered retrieval.

class AgentMemory:
    def __init__(self):
        self.hot = {}       # Current session, in-context
        self.warm = {}      # Recent sessions, vector-indexed
        self.cold = {}      # Historical, keyword-searchable

    def remember(self, key, value, tier="hot"):
        self.tiers[tier][key] = {
            "value": value,
            "timestamp": datetime.now(),
            "access_count": 0
        }

    def recall(self, query):
        # Check hot first (free), then warm (vector search),
        # then cold (keyword search, most expensive)
        for tier in [self.hot, self.warm, self.cold]:
            result = tier.search(query)
            if result and result.relevance > 0.8:
                result.promote()  # Move up a tier on access
                return result

The key insight: memory isn’t binary (remember/forget). It’s a hierarchy. Frequently accessed information stays hot (cheap, fast). Old information drops to cold storage (expensive to access, but still there). This mirrors how every production database works — and your agent’s memory should work the same way.

Cost impact: Our token usage dropped 40% after implementing tiered memory, because the agent stopped re-retrieving information it had accessed minutes ago.

Failure 2: The Hallucination Cascade

Single hallucinations are bad. Hallucination cascades are catastrophic.

We built a multi-agent system for medication reconciliation — one agent extracts medications from records, another checks for drug interactions, a third generates reports. In testing, each agent was 95% accurate. Sounds great, right?

In production: Agent A hallucinated a medication. Agent B checked that hallucinated medication against a real one and found a “dangerous interaction.” Agent C wrote an urgent alert to the physician. Three agents, each 95% accurate, combined to produce a completely fabricated medical alert with high confidence.

The fix: Verification at every agent boundary.

class AgentBoundary:
    """Every inter-agent message gets verified."""

    def pass_to_next(self, message, source_agent, target_agent):
        # 1. Source must cite evidence
        if not message.citations:
            raise VerificationError("No citations provided")

        # 2. Citations must resolve to real documents
        for citation in message.citations:
            if not self.document_store.exists(citation.source_id):
                message.flag_unverified(citation)

        # 3. Target agent sees confidence metadata
        message.metadata["verified_citations"] = len(verified)
        message.metadata["total_citations"] = len(message.citations)
        message.metadata["source_agent_confidence"] = source_agent.confidence

        # 4. Target agent adjusts behavior based on input quality
        if message.metadata["verified_citations"] / message.metadata["total_citations"] < 0.7:
            target_agent.mode = "conservative"  # Require extra verification

        return target_agent.process(message)

The principle: in a multi-agent system, the boundary between agents is where errors multiply. Every handoff needs a verification gate. This costs tokens (roughly 15% overhead) but prevents the cascade that makes your system worse than useless — it makes it confidently wrong.

Failure 3: The Silent Degradation

This is the scariest one because you don’t notice it happening.

We deployed an AI-powered payment recovery system. Day 1: it sent well-crafted, personalized emails to customers with failed payments. Recovery rate: 45%. Week 2: recovery rate dropped to 38%. Week 4: 29%. We didn’t notice for a month because the system was “working” — it sent emails, some payments recovered, metrics were green.

What happened: the LLM’s email generation slowly drifted. Early emails were specific: “Your Visa ending in 4242 failed on March 15. Here’s a direct link to update it.” Later emails became generic: “We noticed an issue with your payment method. Please update your details.” Same template, same prompt — but the model’s interpretation drifted as it processed more edge cases.

The fix: Output quality monitoring with baseline comparison.

class OutputMonitor:
    def __init__(self, baseline_examples):
        self.baseline_embeddings = [
            embed(example) for example in baseline_examples
        ]
        self.drift_threshold = 0.15

    def check_output(self, new_output):
        new_embedding = embed(new_output)
        similarity = avg_cosine_similarity(
            new_embedding, self.baseline_embeddings
        )

        drift_score = 1.0 - similarity

        if drift_score > self.drift_threshold:
            alert(f"Output drift detected: {drift_score:.2f}")
            return self.regenerate_with_baseline_example(new_output)

        return new_output

Measure your agent’s outputs against known-good baselines. When they drift beyond a threshold, flag it. This is the AI equivalent of integration tests — except it runs continuously in production, not just in CI.

The Meta-Pattern

All three failures share a root cause: production AI agents operate in open-ended environments where test assumptions don’t hold. Tests are closed systems. Production is an open system. The gap between them is where agents fail.

The fix is always the same structure:

  1. Measure something you assumed was constant (memory, accuracy, output quality)
  2. Detect when it degrades past a threshold
  3. Intervene automatically before the user notices

This is not glamorous work. It’s not “AI magic.” It’s the same reliability engineering that keeps databases running, applied to a new substrate. And it’s the difference between a demo that impresses and a system that earns.

I build production AI systems — RAG pipelines, multi-agent architectures, and the infrastructure that keeps them running. If your AI project works in demo but not in production, that’s exactly what I fix. astraedus.dev

LiteLLM Has a Free API — Unified Proxy for 100+ LLM Providers

LiteLLM is a unified API gateway that lets you call 100+ LLM providers using the same OpenAI-compatible format. Switch between OpenAI, Anthropic, Bedrock, Vertex AI, Ollama, and more — without changing your code.

Free, open source, Python-native. Used by thousands of companies for LLM routing.

Why Use LiteLLM?

  • One interface, 100+ providers — OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure, Cohere, Replicate, Ollama, and more
  • OpenAI-compatible proxy — deploy as a server, use with any OpenAI SDK
  • Cost tracking — track spend per model, per user, per team
  • Load balancing — route between multiple API keys/deployments
  • Fallbacks — automatic retry with different providers
  • Rate limiting — per-user and per-model rate limits

Quick Setup

1. Install

pip install litellm[proxy]

# Start proxy server
litellm --model gpt-4o --port 4000

2. Use as Python Library

from litellm import completion
import os

os.environ["OPENAI_API_KEY"] = "sk-..."
os.environ["ANTHROPIC_API_KEY"] = "sk-ant-..."

# Same function, different providers
response = completion(
    model="gpt-4o",
    messages=[{"role": "user", "content": "What is web scraping?"}]
)
print(response.choices[0].message.content)

# Switch to Claude — same code!
response = completion(
    model="claude-3-5-sonnet-20241022",
    messages=[{"role": "user", "content": "What is web scraping?"}]
)
print(response.choices[0].message.content)

# Use Ollama (local)
response = completion(
    model="ollama/llama3.1",
    messages=[{"role": "user", "content": "What is web scraping?"}],
    api_base="http://localhost:11434"
)

3. Proxy Server with Config

# config.yaml
model_list:
  - model_name: gpt-4
    litellm_params:
      model: gpt-4o
      api_key: sk-...
  - model_name: gpt-4
    litellm_params:
      model: azure/gpt-4
      api_base: https://my-azure.openai.azure.com
      api_key: ...
  - model_name: claude
    litellm_params:
      model: claude-3-5-sonnet-20241022
      api_key: sk-ant-...
  - model_name: local
    litellm_params:
      model: ollama/llama3.1
      api_base: http://localhost:11434

router_settings:
  routing_strategy: least-busy
  num_retries: 3
  fallbacks: [{"gpt-4": ["claude"]}]
litellm --config config.yaml --port 4000

4. Query the Proxy

# Uses OpenAI format
curl -s http://localhost:4000/v1/chat/completions 
  -H "Content-Type: application/json" 
  -H "Authorization: Bearer sk-litellm-master-key" 
  -d '{
    "model": "gpt-4",
    "messages": [{"role": "user", "content": "Compare Playwright vs Puppeteer"}]
  }' | jq '.choices[0].message.content'

# Switch to Claude — same endpoint
curl -s http://localhost:4000/v1/chat/completions 
  -H "Content-Type: application/json" 
  -H "Authorization: Bearer sk-litellm-master-key" 
  -d '{"model": "claude", "messages": [{"role": "user", "content": "Hello"}]}' | jq '.choices[0].message.content'

5. Cost Tracking

from litellm import completion

response = completion(model="gpt-4o", messages=[{"role": "user", "content": "Hi"}])

print(f"Cost: ${response._hidden_params['response_cost']:.6f}")
print(f"Tokens: {response.usage.total_tokens}")

Key Proxy Endpoints

Endpoint Description
/v1/chat/completions Chat
/v1/completions Text completion
/v1/embeddings Embeddings
/v1/models List available models
/v1/images/generations Image generation
/spend/logs Spending logs
/model/info Model configuration
/health Health check

Supported Providers (100+)

Provider Model Format
OpenAI gpt-4o, gpt-4o-mini
Anthropic claude-3-5-sonnet-…
AWS Bedrock bedrock/anthropic.claude-v2
Google Vertex vertex_ai/gemini-pro
Azure azure/gpt-4
Ollama ollama/llama3.1
Replicate replicate/model-name
Cohere command-r-plus

Need custom data extraction or scraping solution? I build production-grade scrapers for any website. Email: [email protected] | My Apify Actors

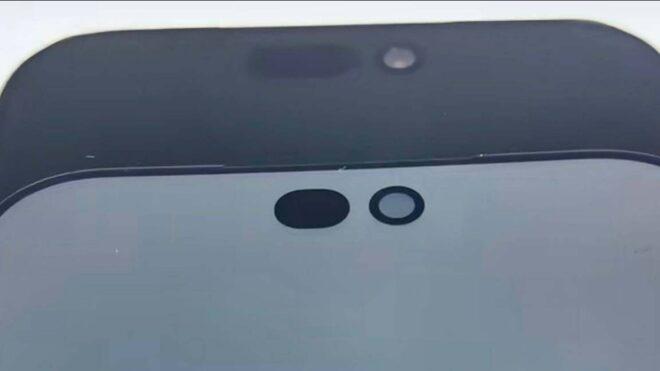
iPhone 18 modellerinde Dynamic Island’ın genişliği azaltılabilir

iPhone 18

iPhone 18Eylül ayında tanıtılacak iPhone 18 ve 18 Pro Max ile 2027’nin ilk çeyreğinde tanıtılacağı söylenen standart iPhone 18 modelinde Dynamic Island’ın genişliği azaltılabilir. Ice Universe’ün iddiasına göre çerçeve kalınlıkları iPhone 17 serisine kıyasla değişmeyecek olan telefonlar, tasarımda olduğu gibi teknik tarafta da büyük bir yeniliğe ev sahipliği yapmayacak. Eylül ayında esas olarak ilk katlanabilir iPhone modeli dikkat çekecek. Ekran kat izi olmadan tasarlandığı aktarılan model (iPhone Fold ya da iPhone Ultra isimleri tercih edilebilir), Türkiye’de 200 bin TL’den daha pahalıya satılabilir.

iPhone 18 modellerinde Dynamic Island’ın genişliği azaltılabilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

ClaudeGate: wrapping Claude Code CLI as an async REST API in Go

Claude Code is a great CLI tool. You run it, it reads your codebase, it thinks, it writes code. But the moment you want to integrate it into a pipeline — a CI step, a backend service, a custom dashboard — you hit a wall. The CLI is a black box: you feed it via stdin, you read its stdout, and there is no HTTP interface, no job queue, no way to poll status, no streaming endpoint. Nothing.

I built ClaudeGate to solve exactly that. It wraps the Claude Code CLI into a proper REST API with an async job queue, SSE streaming, webhook callbacks, and SQLite persistence. The whole thing ships as a single static Go binary. No CGO, no runtime dependencies, no surprise.

Why Go, and why a gateway pattern

Claude Code already knows how to run code. My job was not to reimplement intelligence — it was to build the plumbing around it. A gateway pattern is the right fit here: take an opaque subprocess, wrap it with a proper async API, add persistence and observability, expose clean HTTP endpoints.

Go was the obvious choice. It gives you goroutines for free, channels for fan-out, and exec.CommandContext for subprocess management with cancellation baked in. The standard library is good enough that you end up with a small, self-contained binary that runs anywhere. No dependency hell. modernc.org/sqlite is pure Go — no CGO — so the binary stays static and works in scratch or Alpine containers.

The lifecycle of a job

Every request follows the same path. Here is the full flow from HTTP call to final result:

POST /api/v1/jobs
    → validate request body (1MB limit)
    → INSERT INTO jobs (status = "queued")
    → Enqueue(job.ID)           ← only the ID, not the struct
          |
          ↓
    buffered chan string
          |
          ↓
    worker goroutine
    → load job from SQLite
    → exec claude --output-format stream-json
    → parse stdout line by line
         "assistant" lines → SSE chunk events → subscribers
         "result" line    → SSE result event  → webhook callback
    → UPDATE jobs (status = "completed")

A deliberate design choice: only the job ID travels through the channel, not the full job struct. This matters for cancellation. If a job is cancelled mid-queue — before a worker picks it up — the worker loads it from SQLite, sees the cancelled status, and exits immediately. No stale data, no race conditions from a struct that was mutated after being enqueued.

The job queue: backpressure without drama

The queue is a buffered chan string. Simple, effective. Here is the Enqueue logic:

func (q *Queue) Enqueue(id string) error {
    select {
    case q.jobs <- id:
        return nil
    default:
        return ErrQueueFull
    }
}

The select/default pattern gives you non-blocking backpressure for free. If the channel is full, the caller gets an immediate error. No goroutine created, no blocking, no silent queue growth. The caller can decide what to do — retry later, surface an error to the user, whatever.

N worker goroutines all read from the same channel. Starting them is one of my favorite Go 1.22 patterns:

for range q.cfg.Concurrency {
    go q.runWorker(ctx)
}

range over an integer. No index variable, no boilerplate. Added in Go 1.22, and I use it every time I start a worker pool now.

For cancellation, the queue maintains a cancels map[string]context.CancelFunc. When a worker starts processing a job, it registers its cancel function under the job ID. The HTTP CancelJob handler looks up the running job by ID and calls the cancel — which propagates into the exec.CommandContext and kills the subprocess cleanly.

SSE streaming: fan-out without blocking

Claude Code outputs results progressively. Streaming those chunks to clients via Server-Sent Events is a much better experience than polling. The fan-out design:

type SSEEvent struct {
    Type    string // "status", "chunk", "result"
    Payload string
}

// Each subscriber gets its own buffered channel
subs map[string][]chan SSEEvent

When a chunk arrives from the subprocess, the worker broadcasts to all channels in subs[jobID]. Each channel has a capacity of 64. The send is non-blocking — if a subscriber’s channel is full, the event is silently dropped for that subscriber. A slow client does not slow down the worker.

There is one edge case worth handling: what if a client connects after the job is already finished? In that case, the SSE handler checks the job status in SQLite first. If it is in a terminal state (completed, failed, cancelled), it immediately sends the final result and closes the connection — no subscription created, no waiting.

Webhook delivery: async, resilient, and SSRF-aware

When a job completes, ClaudeGate can POST a callback to any URL you configure on the job. The delivery is fire-and-forget: the worker hands it off to a goroutine and moves on.

The webhook module handles three things I always forget when I first implement webhooks:

  • Retries with exponential backoff: 3 attempts, 1s → 2s → 4s, 30s timeout per request.
  • SSRF protection: before sending, the target hostname is resolved via DNS. If the resolved IP is private (RFC 1918), loopback, or link-local, the request is rejected. This prevents a user from pointing the callback at http://169.254.169.254/ or your internal services.
  • Consistent payload: every callback has the same shape regardless of outcome.
{
  "job_id": "01HZQ...",
  "status": "completed",
  "result": "Here is the refactored function:nn...",
  "error": ""
}

Security: constant-time auth and a mandatory system prompt

Authentication uses the X-API-Key header. Keys are compared with crypto/subtle.ConstantTimeCompare — the standard way to prevent timing attacks on string comparison. ClaudeGate supports multiple API keys simultaneously, which makes key rotation possible without downtime: add the new key, deploy, remove the old key, deploy again.

The more interesting security feature is the mandatory system prompt. Every job submitted through ClaudeGate gets a security prompt prepended automatically, before the user’s prompt reaches Claude. This prompt forbids shell execution, filesystem writes, and network access. The idea: ClaudeGate is an API that arbitrary callers can hit — you don’t want to give them an unrestricted code execution environment. The security prompt is the guardrail.

If you are running ClaudeGate in a trusted environment where you control all callers, you can disable this with CLAUDEGATE_UNSAFE_NO_SECURITY_PROMPT=true. The name makes the trade-off explicit.

One more thing: the worker strips all CLAUDE* environment variables before exec-ing the subprocess. This prevents environment leakage from the parent process into Claude.

SQLite: simple persistence and crash recovery

SQLite with WAL mode is the right database for this use case. There is no need for Postgres here. Jobs are sequential, writes are frequent but small, the dataset is bounded.

The problem WAL + busy_timeout solves. SQLite uses file-level locks. Without configuration, when a writer holds the lock (e.g. a worker saving a result), any other concurrent access immediately gets SQLITE_BUSY — an error, not a wait:

Worker 1: UPDATE jobs SET status='completed'...  ← lock held
Worker 2: UPDATE jobs SET status='processing'... ← SQLITE_BUSY immediately, error
API:      SELECT * FROM jobs...                  ← SQLITE_BUSY immediately, error

busy_timeout = 10000 changes this behavior: SQLite retries for up to 10 seconds before returning the error. For the vast majority of contentions (a few milliseconds between two workers), this silently resolves the problem.

WAL alone is not enough. WAL fixes concurrent reads alongside writes — readers and writers no longer block each other. But two simultaneous writers are still exclusive. With CLAUDEGATE_CONCURRENCY > 1, two workers can finish at the same time and both attempt an UPDATE simultaneously.

WAL     → readers and writers no longer block each other
timeout → two simultaneous writers: the second waits instead of failing

The crash recovery logic is the part I am most satisfied with. On startup, ClaudeGate queries for any jobs stuck in processing status:

// On startup: recover jobs that were interrupted by a crash
stuck, err := store.FindByStatus(ctx, "processing")
for _, job := range stuck {
    store.UpdateStatus(ctx, job.ID, "queued")
    queue.Enqueue(job.ID)
}

If the process was killed mid-job — power loss, OOM, container restart — those jobs are re-queued on the next startup and processed normally. No manual intervention, no lost work.

Schema migrations are handled with idempotent ALTER TABLE ADD COLUMN statements. If the column already exists, SQLite returns an error, which is silently ignored. Not elegant, but it works, and it keeps the migration code dead simple.

A TTL cleanup goroutine runs periodically and deletes jobs older than the configured retention period. The SQLite file stays bounded in size even if you run ClaudeGate for months.

Modern Go patterns worth noting

The project uses Go 1.22’s enhanced stdlib routing. No external router needed:

mux.HandleFunc("GET /api/v1/jobs/{id}/sse", h.StreamSSE)
mux.HandleFunc("POST /api/v1/jobs/{id}/cancel", h.CancelJob)
mux.HandleFunc("DELETE /api/v1/jobs/{id}", h.DeleteJob)

// In the handler:
id := r.PathValue("id")

Method + path in a single string, path parameters with PathValue. This is genuinely good enough for most APIs. I reach for a third-party router only when I need middleware chaining or route groups that the stdlib does not give me cleanly.

The Store interface keeps the job repository testable without touching SQLite in unit tests:

type Store interface {
    Insert(ctx context.Context, job *Job) error
    GetByID(ctx context.Context, id string) (*Job, error)
    UpdateStatus(ctx context.Context, id, status string) error
    FindByStatus(ctx context.Context, status string) ([]*Job, error)
    Delete(ctx context.Context, id string) error
}

The web playground is a single HTML file embedded at compile time via //go:embed static/index.html and served at GET / without authentication. It gives you a UI to submit jobs, browse history, and read the API docs without any external tool.

Get started in 5 minutes

git clone https://github.com/ohugonnot/claudegate.git
cd claudegate
cp .env.example .env
make build
./bin/claudegate

The .env.example documents every configuration option. Set your API key, optionally configure concurrency and TTL, point it at your Claude installation. That is it.

The full API surface:

Method

Path

Description

POST

/api/v1/jobs

Submit a job

GET

/api/v1/jobs

List jobs (limit, offset)

GET

/api/v1/jobs/{id}

Poll job status

DELETE

/api/v1/jobs/{id}

Delete a job

GET

/api/v1/jobs/{id}/sse

Stream output via SSE

POST

/api/v1/jobs/{id}/cancel

Cancel a running job

GET

/api/v1/health

Healthcheck (no auth)

GET

/

Embedded web playground

Conclusion

ClaudeGate is not trying to be a platform. It is a thin, pragmatic wrapper that turns a CLI tool into something you can actually integrate with. The design is intentionally simple: one binary, one SQLite file, one config file. If you need to run it in Docker, it fits in a scratch container. If you need to run it on a bare VM, it is a single binary copy.

The interesting engineering here is not in the individual pieces — queues, SSE, webhooks are all well-understood patterns. It is in how they compose: the ID-only channel for safe cancellation, the crash recovery on startup, the SSRF check before every webhook delivery. The details that make the difference between “works in a demo” and “works in production at 3am”.

The project is open source. If you are building something on top of Claude Code and want a proper HTTP interface, give it a try: github.com/ohugonnot/claudegate.