TL;DR: Most drift monitoring setups alert on the wrong thing. Feature distribution drift is cheap to compute and almost always misleading. Prediction drift plus a delayed ground-truth feedback loop catches the failures that actually cost money. Here is the setup I use at Yokoy.
A model that returns HTTP 200 with a plausible-looking float is the worst kind of broken. No exception, no pager, no Slack message. The metric only moves three weeks later when finance reviews the numbers.
I have spent the last two years rebuilding the monitoring story for our expense classification models. What follows is what I kept after throwing out the rest.
The mistake I keep seeing
Teams instrument input feature drift first because it is the easiest thing to compute. Pull yesterday’s feature values, pull today’s, run a KS test on each column, alert when p < 0.05.
This generates noise. A lot of noise.
Features drift constantly for reasons that have nothing to do with model quality. A new customer onboards, the merchant category distribution shifts, you get a Slack ping at 03:00 for something that does not matter. After two weeks of this, on-call mutes the channel. After four weeks, the channel is deleted.
The problem is not the test. The problem is that input drift is a weak proxy for what you actually care about: did model performance degrade.
What to monitor instead
Three signals, ranked by cost and value.
| Signal |
Compute cost |
Latency to detect |
False positive rate |
| Input feature drift |
Low |
Hours |
High |
| Prediction distribution drift |
Low |
Hours |
Medium |
| Performance vs delayed labels |
Medium |
Days to weeks |
Low |
Prediction drift is the underrated one. If your model started returning a different distribution of outputs without you shipping new weights, something upstream broke. Could be feature pipeline. Could be a provider returning malformed embeddings. Could be a real population shift. All of these are worth investigating.
The detection logic is short:
from scipy.stats import wasserstein_distance
import numpy as np

def prediction_drift_score(reference: np.ndarray, current: np.ndarray) -> float:
    return wasserstein_distance(reference, current)

# reference = predictions from the validation window when the model was promoted
# current = predictions from the last 24h of production traffic
# alert when score exceeds the 99th percentile of bootstrapped baseline scores
Wasserstein over KS for prediction monitoring. KS is hypersensitive to large samples and you will have large samples in production. With 500k predictions per day, KS rejects the null hypothesis for differences nobody cares about.
The feedback loop is non-negotiable
For expense classification, ground truth arrives when a human approves or corrects the prediction. Median latency is four days. P95 is three weeks.
We log every prediction with a join key and write it to a Parquet table partitioned by date. When labels arrive, a nightly Kubeflow pipeline joins them and computes per-segment performance: accuracy per merchant category, per country, per customer tier.
The per-segment view is what surfaces the failures. Aggregate accuracy stays at 94% while accuracy on a specific Swiss VAT category collapses to 71%. The aggregate view would never have caught it.
# Simplified pipeline component spec
- name: compute-segmented-metrics
  inputs:
    predictions_table: gs://yokoy-ml/predictions/dt={{date}}
    labels_table: gs://yokoy-ml/labels/dt={{date}}
  outputs:
    metrics_table: gs://yokoy-ml/metrics/dt={{date}}
  segments:
    - merchant_category
    - country
    - customer_tier
  resource_request:
    cpu: 4
    memory: 16Gi
The cost: roughly 12 minutes of compute per day on our volume. The value: every regression we caught in the last 18 months was caught here, not by drift monitoring.
Where input drift still earns its place
I have not fully abandoned input drift. It is useful as a debugging tool after the fact. When per-segment accuracy drops, the first question is which features moved. Having the historical drift scores already computed means the investigation starts with a query instead of a backfill.
So compute it, store it, do not alert on it.
A note on LLM-based features
We added an LLM-derived feature last year for invoice text classification, routed through a gateway in front of multiple providers (Bifrost handles this for us, though others like LiteLLM or Portkey cover the same ground). The drift profile changed immediately. Provider model updates, even minor ones, shift the feature distribution in ways you cannot see from your side.
Lesson: pin the provider model version explicitly. Treat a provider model change as a feature pipeline change. Re-run the validation set. This sounds obvious until the day a default model alias updates and you find out from the metrics.
Trade-offs and Limitations
Per-segment monitoring has a cardinality problem. With three segments of 50, 30, and 5 values you get 7500 cells. Most are empty or have too few samples for meaningful metrics. We use a minimum sample threshold of 100 per cell per day and accept that long-tail segments take longer to detect issues in.
Delayed labels mean delayed detection. For models where the label takes weeks, you need a complementary fast signal. Prediction drift fills part of that gap but it is a leading indicator, not a measurement.
Wasserstein distance has no native interpretation in production units. You bootstrap a baseline and alert on deviation from it. This works but it is not as crisp as “accuracy dropped 3 points.”
Storing every prediction with features for joinability is expensive. We compress aggressively and tier old partitions to cold storage after 90 days. Plan the storage cost before you build it, not after.
Further Reading

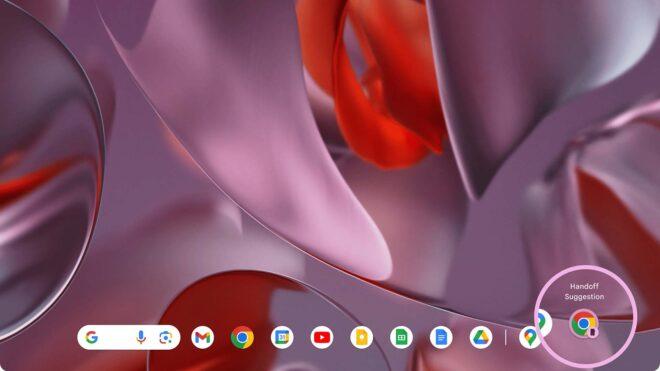
 Google, I/O 2026 etkinliğinde Android 17 işletim sistemi için geliştirilen, Apple’ın Handoff sistemine benzer “Continue On” altyapısını da duyurdu. Bu altyapı, kullanıcıların Android cihazlarını uygulama kullanımları özelinde birbirine bağlamasına imkan tanıyor. Örneğin telefondaki bir uygulamada açılan doküman ya da e-posta, doğrudan tablette de görünüyor ve tek dokunmayla açılabiliyor. Zaman kazandıran bu altyapı için her iki cihazda da aynı hesabın kullanılması gerekiyor.
 SuperGrok ve X Premium aboneleri bundan böyle OpenClaw içerisinde Grok yapay zekâ modelini kullanabilecek ve geniş bir ortamda entegrasyon imkânı bulacak.

