Yenilenen Dacia Logan Türkiye’de: İşte Fiyatı ve Özellikleri
Yenilenen Dacia Logan’ın Türkiye fiyatı açıklandı.

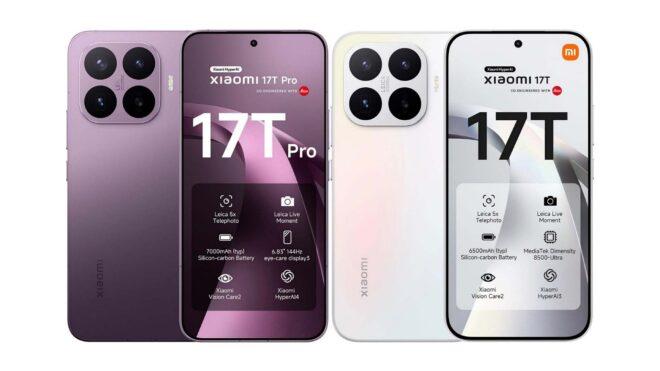
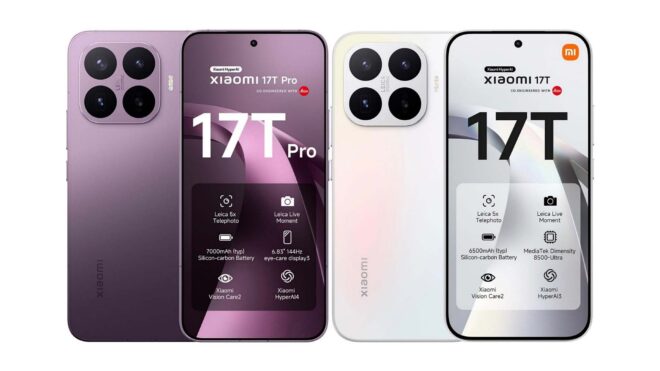 Xiaomi tarafından yapılan doğrulamaya göre Xiaomi 17T ve 17T Pro modelleri Türkiye’de resmi olarak 28 Mayıs’ta satışa sunulacak. Fiyatları henüz belli olmayan ancak büyük satış kanallarında listelenmeye başlayan telefonlardan Xiaomi 17T, 6,59 inç boyutunda 120 Hz AMOLED ekran, MediaTek Dimensity 8500 Ultra işlemci, 12 GB LPDDR5X RAM, 256/512 GB UFS 4.1 depolama, 67W şarj destekli 6.500 mAh batarya ve 32 megapiksel selfie kamerası ile geliyor. Cihazın arkasında ise 50 megapiksellik Light Fusion 800 sensörlü geniş açı, 5x optik zoom sunan 50 megapiksel telefoto ve 12 megapiksel ultra geniş açı kameralar bir araya getiriliyor. Üstte yer alan Xiaomi 17T Pro ise sızıntıya göre 6,83 inç boyutunda 144 Hz AMOLED ekran, MediaTek Dimensity 9500 işlemci, 12 GB LPDDR5X RAM, 512 GB UFS 4.1 depolama, 100W şarj destekli 7.000 mAh batarya ve 32 megapiksel selfie kamerasıyla geliyor. Cihazın arkasında 50 megapiksellik Light Fusion 950 sensörlü geniş açı, 5x optik zoom sunan 50 megapiksel […]
Xiaomi 17T ve 17T Pro, Türkiye’de 28 Mayıs’ta satışa sunulacak yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Notes from your fellow Engineer..
A few months ago, I was treating Generative AI the same way many backend engineers probably still are.
Interesting technology? Definitely.
Worth exploring at some point? Sure.
But directly relevant to backend engineering?
I wasn’t fully convinced yet.
Most of my day-to-day work still revolved around things like:
AI felt like a separate world.
But lately, I’ve started noticing something interesting.
AI is slowly beginning to look less like a standalone feature…
…and more like another layer of modern software architecture.
Not replacing backend systems.
But integrating deeply into them.
The more I explored modern AI applications, the more familiar the problems started feeling.
Because once you move beyond the demo layer, AI systems suddenly involve things backend engineers already spend years dealing with:
At some point it clicked for me:
A lot of modern AI engineering is still fundamentally systems engineering.
Just with a new layer added on top.
One thing I misunderstood initially was thinking AI engineering was mostly about prompts and models.
But honestly, what’s becoming more interesting to me is everything around the model.
Things like:
That’s where backend engineering and AI start blending together.
And I think many backend engineers are actually in a stronger position here than they realize.
If you already understand:
…you’re already bringing valuable foundations into AI systems engineering.
Right now I’m personally spending time learning:
Not from a research perspective.
But from a practical engineering perspective.
Because honestly, this shift feels very similar to what happened with cloud adoption years ago.
At first it looked specialized.
Then suddenly it became part of mainstream engineering.
I have a feeling AI may follow a similar path.
Curious how other backend engineers are approaching this right now.
Are you actively learning AI systems yet, or still observing where the industry goes?
I’ll be sharing more practical thoughts around:
as I continue exploring this space.
Always happy to learn from other engineers building in this area too.
Three days after a release, an issue arrived: “The install command doesn’t work.” A module path change in that release had broken go install. My test suite had passed. My local build had passed. CI had passed. The binary was broken anyway, and I found out from a user report, not from a check.
That was the first gap. There were more: no performance baseline, so I wouldn’t know when a new rule was 3x slower. No way to verify whether the GitHub Action I’d published actually ran correctly in a user’s workflow. Each gap seemed minor on its own. Together, they meant I was shipping changes I couldn’t fully verify.
This is the CI harness I assembled over 11 months: 7 checks, each added after a specific failure made the gap impossible to ignore.
The Harness at a Glance
| Check | Added | What it prevents |
|---|---|---|
| Tests & coverage | 2025-06 | Regressions going unnoticed |
| Installability | 2025-07 | A broken binary reaching users |
| Static analysis | 2026-01 | Code quality regressions, potential bugs |
| PR label enforcement | 2026-02 | Incomplete release notes |
| Benchmark comparison | 2026-02 | Unnoticed performance regressions |
| Action smoke test | 2026-05 | Breaking changes to the published Action |
| Invisible Unicode detection | 2026-05 | Zero-width characters sneaking into source |
1. The Coverage Gate: A Tripwire for Vanishing Tests (June 2025)
Purpose: run the full test suite on every PR and enforce a minimum coverage threshold.
“Run tests” is not the same as “enforce coverage.” A PR that deletes test helpers or bypasses a code path drops the coverage number silently if you’re only running go test without tracking the percentage. The threshold forces the question every time: coverage falls below the minimum, CI fails.
- name: Test with coverage
  run: |
    go test ./... -coverprofile=coverage.out
    go tool cover -func=coverage.out |
      awk '/total:/ { pct=$3+0; if (pct < 80) { print "Coverage " $3 " is below 80%"; exit 1 } }'
What it prevents: regressions going unnoticed. The test suite catches broken behavior; the coverage gate catches the removal of the tests that would have caught it.
2. The Install Canary: Proving Users Can Still Get In (July 2025)
Purpose: verify that go install github.com/shinagawa-web/gomarklint@latest still works after every push to main.
This sounds obvious until it breaks. Module path changes, missing main packages, incorrect version tags: any of these will produce an install error that a passing test suite won’t catch. The check runs go install on the actual published module (not the local source) in a clean environment. If it fails on a PR, the PR cannot merge; if it catches something on main, main goes red until it’s resolved.
What it prevents: releasing a binary that users cannot install. That’s a silent failure that lands in your issue tracker three days later when someone reports “the install command doesn’t work.”
3. The Review Inliner: Surfacing Lint Where You Read Code (January 2026)
Purpose: surface lint errors inline on PRs rather than as a buried log line.
reviewdog runs golangci-lint and posts results as PR review comments on the specific lines that triggered the warning. The feedback loop matters: a lint error posted as a CI log line gets skimmed; a review comment on the line of code gets read.
What it prevents: code quality regressions that tests don’t exercise. The enabled linters target cyclomatic complexity (gocyclo), cognitive complexity (gocognit), function length (funlen), unchecked errors (errcheck), and suspicious constructs (staticcheck, govet). In practice the complexity linters fire most often — a function that passes every test can still be flagged for being too difficult to reason about.
4. The Changelog Guard: Blocking the Invisible PR (February 2026)
Purpose: auto-assign labels from Conventional Commits prefixes (feat:, fix:, chore:, etc.) and block merging any PR that carries no label.
Release notes in gomarklint are generated from PR labels. A PR merged without a label is invisible in the changelog. The enforcement step runs on pull_request events and fails if no label is present after the auto-assignment pass.
What it prevents: gaps in release notes. If the changelog can’t be trusted, the project’s version history can’t be trusted either.
5. The Performance Witness: Catching the 3x Slowdown That Passes Tests (February 2026)
Purpose: run the full benchmark suite on both the PR branch and main, then post the delta as a PR comment.
The comment uses a three-state indicator: ✅ if the PR branch is no slower than main, ⚠️ if it is 10–50% slower, and ❌ if it is more than 50% slower. This check does not hard-fail CI: it posts a warning comment and lets the reviewer decide whether to proceed.
Trap: hard-failing on performance regressions trains reviewers to ignore the check. Early versions did fail CI when the threshold was crossed. The problem is runner variance: GitHub Actions runners share hardware, and a run on a busy runner is measurably slower than a previous run on a quiet one. That variance exceeded the threshold I needed to catch real regressions. After two false positives in a row, I started dismissing the failures on sight. The fix was to post the data without blocking: the comparison still runs, the comment still appears, but the merge decision stays with the reviewer.
What it prevents: performance regressions that pass every unit test. A new rule implementation that is correct but 3x slower will show up immediately. The decision to merge or revise is still human, but the data is always there.
6. The Wrapper Probe: Testing What Users Actually Run (May 2026)
Purpose: actually run the published GitHub Action against a real Markdown fixture on every relevant change to the Action definition or the underlying binary.
A GitHub Action can have valid YAML and a valid binary and still fail in ways that neither validates: wrong input names, incorrect default values, broken entrypoint paths. The smoke test checks out the Action from the PR branch and runs it end-to-end in CI against a controlled fixture directory.
What it prevents: breaking changes to the Action going unnoticed. Users of the Action would hit the failure; I would not, because my own tests don’t exercise the Action wrapper layer.
7. The Hidden-Character Scanner: Defending Against Code You Cannot See (May 2026)
Purpose: defend against supply-chain attacks that hide malicious code inside invisible Unicode characters embedded in .go and .sh files.
In March 2026, the GlassWorm attack was disclosed. It works by embedding malicious code inside Unicode variation selector characters (U+E0100–U+E01EF) — characters invisible in editors, invisible in GitHub’s diff view, invisible to standard code review. A single visible source line can carry approximately 18,000 hidden lines of code. Over 151 GitHub repositories and 72 Open VSX extensions were confirmed compromised before the attack was publicly documented.
The check greps for the specific character ranges used in the attack on every push and PR touching Go or shell files:
#!/bin/sh
grep -rPn
  '[x{200B}x{200C}x{200D}x{FEFF}]|[x{E0100}-x{E01EF}]'
  --include='*.go' --include='*.sh' . && {
    echo "Invisible Unicode characters detected"
    exit 1
  }
# grep exits 1 when no match (success), 0 when match found (failure), 2 on error
[ $? -eq 2 ] && { echo "grep error: scan failed"; exit 2; }
exit 0
The job fails with a non-zero exit code on any match, and with a distinct exit code on grep errors, so a scan failure cannot silently bypass the check.
What it prevents: a contaminated contribution entering the codebase undetected. The threat isn’t accidental encoding corruption — it’s deliberate concealment. Standard diff review offers no protection against it.
The Local Mirror: Catching Failures Before They Become PRs
The CI harness runs on GitHub Actions, which means feedback arrives after a push. A PR that fails lint or drops below the coverage threshold wastes a round-trip: push, wait, read the failure, fix locally, push again.
The pre-push hook is the local mirror of the harness. It runs golangci-lint, the unit test suite, and E2E tests before git push completes. If any check fails, the push is aborted. The PR never gets opened in a broken state.
#!/bin/sh
set -e
golangci-lint run ./...
go test ./...
go test -tags e2e ./...
The hook can be bypassed with git push --no-verify for genuine emergencies, but that’s an explicit override, not the default path.
How the Harness Grew
I started with tests only, because that’s where every project should start. Each subsequent check was added after a specific failure: the installability check came after a broken binary slipped to users; benchmarks came after a performance regression went unnoticed through two releases; the Action smoke test came after I realized I had been testing the binary but not the wrapper that users actually invoke.
The harness wasn’t designed. It was accumulated. Each new check costs very little once the infrastructure is in place (a new job, an existing action, a few lines of shell), and the protection adds up.
One gap it still doesn’t close: the pre-push hook is opt-in and only runs on my machine. A new contributor submitting their first PR gets CI feedback rather than local feedback: the round-trip I eliminated for myself still exists for everyone else.
What Does Your Harness Look Like?
This is how I maintain quality in gomarklint: automated gates that catch categories of failure I’ve already experienced, running on every push and PR without my involvement.
What does your CI harness include? Have you added checks that go beyond tests and lint, things like installability verification, Action smoke tests, or performance baselines? I’m curious what gaps yours was built to close.

Originally published at https://shai-kr.github.io/data-ninja-ai-lab/blog/2026-05-19-outbound-access-protection-semantic-models.html.
Most Power BI security conversations stop at the report.
Who can open it?
Which workspace is it in?
Which RLS role applies?
Can users export data?
Those questions still matter. But they are no longer enough.
Microsoft’s preview of Outbound Access Protection for semantic models is important because it treats the semantic model as something more than a reporting artifact. It treats it as part of the data movement boundary.
That is the right mental model.
A semantic model can connect to multiple sources. It can use Import. It can use DirectQuery. It can combine tables. It can pass filter context into source queries. It can reach across workspaces and external endpoints.
So the governance question is not only:
Who can consume this model?
It is also:
Where is this model allowed to connect?

The risk is not theoretical
The uncomfortable part is that the semantic layer can become a path between sources.
Imagine a composite model with data from Source A and Source B. A user selects a value that comes from Source A. A visual or relationship pushes that value into a query against Source B.
The result does not have to be useful.
The problem is that a sensitive value may now appear in the wrong place, such as a query sent to another endpoint or a log outside the intended boundary.
That is the kind of risk many BI teams do not model explicitly.
They think about permissions on the report. They think about who can see the data. They think about gateway configuration.
But they do not always think about outbound movement from the workspace itself.

What Outbound Access Protection changes
Outbound Access Protection is a workspace-level control in Microsoft Fabric.
When it is enabled, outbound public access is blocked by default. The workspace can only connect to destinations that have been explicitly allowed.
For semantic models, the important detail is where enforcement happens. According to Microsoft’s announcement, enforcement happens on the model’s bound data connection. That means Power Query transformations, M expressions, and model parameters should not be able to route around the policy because the connection itself is evaluated before data moves.
That is a much stronger control than hoping every model author makes the right choice manually.
It also changes the review process.
Before this kind of control, a workspace review might ask:
Now the review also needs to ask:
That is a better conversation.
Where the setting lives
The setting is under the workspace network security configuration.
The relevant path is:
Workspace settings > Network security > Outbound access protection > Block outbound public access

The toggle is simple. The operating model behind it is not.
Turning it on without planning can break legitimate model refreshes or DirectQuery paths. Leaving it off in sensitive workspaces means the model can still be bound to destinations you may not want it to reach.
This is why I would not treat Outbound Access Protection as an admin checkbox.
I would treat it as a workspace design decision.
The local workspace still needs to be allowed
One detail from the announcement is easy to miss.
The default configuration can block connections that are perceived as cross-workspace, including sources accessed through SQL, ADLS Gen2, and other non-Fabric connection kinds.
That can include data that feels local to the workspace.
For example, a semantic model may connect to a lakehouse in the same workspace through the SQL analytics endpoint or through the OneLake ADLS Gen2 path. From the policy point of view, those connection kinds may still need explicit exceptions.
That matters because a team can easily say:
This model only connects to our own lakehouse.
But the implementation detail still matters.
For Import or DirectQuery, you may need the SQL endpoint fully qualified domain name. For Direct Lake style paths, you may need the ADLS Gen2 or OneLake URL pattern.
The governance takeaway is simple:
Do not only document the business source. Document the actual connection path.
A practical rollout checklist
If I were enabling this for a real Fabric workspace, I would not start with the toggle.
I would start with an inventory.

The basic checklist:
The important part is the review discipline.
A new source should not be a casual model change. If it changes where the workspace can send outbound traffic, it should trigger an access review.
What BI teams should take from this
This preview is not only a security feature.
It is a sign that semantic model governance is getting more serious.
For years, many organizations treated semantic models as a trusted middle layer because they were built by BI teams and consumed through reports.
That assumption is weaker now.
Semantic models sit in the middle of more workflows:
As the semantic model becomes more central, it also becomes more important to control what it can reach.
That is the part I like about Outbound Access Protection.
It forces a better architecture question:
Should this workspace be allowed to send data or queries to that destination?
If the answer is yes, make it explicit.
If the answer is no, the platform should block it.
That is how semantic models move from useful BI assets to governed platform components.
Sources
Shai Karmani