The problem nobody talks about
You have a payment gateway. It fails sometimes. So you add a retry.
Now you have a worse problem: a customer clicks “Pay”, the request reaches Stripe, the charge goes through, but the response never comes back. Your retry fires. Stripe charges them again.
That’s not a hypothetical. It’s the default behavior of any naive retry implementation, and it happens in production every day.
This post is about how we built a checkout system that handles this correctly — with retry that never double-charges, a circuit breaker that protects the service when the gateway is degraded, and a feedback loop that adjusts its own configuration under load.
Then we stress-tested it with k6 and measured everything.
The code is in the backendkit-monorepo shopify-backend example
(https://github.com/BackendKit-labs/backendkit-monorepo/tree/master/examples/shopify-backend).
The architecture
The order flow is a typed pipeline of four steps:
POST /orders
→ ValidateInventoryStep checks stock, reserves units
→ CalculatePricingStep applies discounts, computes total
→ ChargePaymentStep calls payment gateway with retry + idempotency
→ CreateOrderStep persists order, emits events
Each step receives a typed OrderContext, returns Result, and the pipeline stops at the first failure. No exceptions, no try/catch chains — errors are values.
The payment step is where the interesting work happens:

Three things to notice:
-
The idempotency.key is charge:${ctx.orderId} — unique per order, not per request. If the first attempt charges successfully but the response is lost, the retry hits the idempotency cache and returns the stored result. Stripe is never called again.
-
retryIf only retries on 500/503 — not on 400/422/404. Business errors don’t retry.
3. jitter: ‘full’ randomizes the backoff delay to prevent thundering herd when multiple orders fail simultaneously.
Test 1: The baseline — normal traffic
Script: order-flow.k6.js — ramps to 50 VUs over 2 minutes, full pipeline per iteration.
✓ success rate: 96.58%
✓ p95 latency: 2.03s
avg latency: 1.17s
throughput: 13.5 orders/second
fail rate: 3.42% (simulated gateway noise)
Under 50 concurrent users, the full pipeline — inventory check, pricing, payment, order creation — completes in 1.17 seconds on average. The 3.42% failure rate is the configured background noise of the payment simulator, not application errors.
This is the baseline. Every number that follows is measured against this.
Test 2: What happens when the gateway degrades
Script: circuit-breaker.k6.js — sets PAYMENT_FAILURE_RATE=0.8, ramps to 30 VUs.
Without a circuit breaker, 80% failure rate means 80% of requests wait for the full gateway timeout before failing.
With 30 VUs × 1-2 second timeout = threads exhaust,
queue backs up, the entire service starts degrading — not just payments.
With a circuit breaker:
health endpoint: 100% reachable throughout
avg response time: 5.05ms
fast-fail response: ~5ms (vs 1.17s baseline)
http_req_failed: 49.99%
The 49.99% failure rate splits exactly in half: health check requests (all succeed) and payment requests (circuit open, fast-fail).
When the breaker trips, payment failures come back in 5 milliseconds instead of waiting 1-2 seconds for a gateway that’s known to be down.
The service never stopped responding. Health endpoints stayed at 100% throughout. The circuit breaker isolated the payment failure from the rest of the system.
Test 3: Retry + idempotency under 60% failure rate
Script: retry-idempotency.k6.js — three concurrent scenarios, 60% gateway failure rate.
This is the scenario that matters most for e-commerce. A gateway failing 60% of the time is a degraded but not dead dependency — exactly when retry is most valuable and most dangerous.
[retry_resilience] success rate: 78.2%
[retry_resilience] retried requests: 825 with latency >500ms
[idempotency_replay] replay rate: 100.0%
[lifecycle] correct cycles: 4/4
p95 latency (with retries): 1345ms
The math checks out. With 60% failure per attempt and 3 max attempts, probability of all three failing = 0.6³ = 21.6%. Actual failure rate: 21.8%. The retry is working exactly as the probability model predicts.
Those 825 requests with latency >500ms are orders that failed on the first attempt but succeeded on retry. Without retry, they’re lost sales. With retry, they’re completed transactions — and none of them charged the customer twice.
Idempotency replay: 100%. Every duplicate request — simulating the “response lost in transit” scenario — returned the cached result without executing the payment handler. The 100% rate held across both this test and the dedicated idempotency test run independently.
Lifecycle test: 4/4. This validates the subtle but critical behavior:
- Handler fails → key not cached → retry executes handler again ✓
- Handler succeeds → key cached → duplicate request returns replay ✓
A naive idempotency implementation that caches failures would block legitimate retries. This one doesn’t.
Test 4: The idempotency contract
Script: idempotency.k6.js — four parallel scenarios, 1383 total iterations.
replay success rate: 100%
missing Idempotency-Key → 422: 30/30
invalid key format → 422: 30/30
overall fail rate: 3.3% (same as baseline)
p95 latency: 1322ms
The contract is enforced at the boundary. A client that forgets to send an Idempotency-Key header gets a 422 — not a silent pass-through that bypasses the protection. Invalid key formats are rejected before touching any business logic.
The 3.3% overall failure rate is statistically identical to the baseline 3.42%. The idempotency layer adds zero latency and zero failures to the normal flow.
Test 5: The system that tunes itself
Script: auto-learning.k6.js — three phases over 160 seconds.
This is the part that has no equivalent in the NestJS ecosystem.
Phase 1 — Baseline (t=0s): 5 VUs, 5% failure, 100ms delay
Phase 2 — Stress (t=50s): 25 VUs, 85% failure, 1000ms delay
Phase 3 — Recovery (t=110s): 5 VUs, 2% failure, 80ms delay
The auto-learning module observes every request, runs z-score analysis on latency and error distributions, and adjusts configuration on a 30-second feedback cycle.
Here’s what the logs showed:
t=0s Initial config:
timeoutMs=2804ms maxRetries=2 cbFailureThreshold=10
[t=50s to t=100s — stress is running, system is collecting data]
t=105s AUTO-LEARNING ADJUSTS:
timeoutMs: 2804ms → 3916ms (+40%)
maxRetries: 2 → 3 (+1)
cbFailureThreshold: unchanged
t=110s Recovery phase begins
Config maintained — insufficient recovery data for next cycle
55 seconds from stress beginning to autonomous configuration change. Two decisions made without human intervention:
- timeoutMs +40% — the gateway was responding in ~1000ms. The system widened its timeout window to avoid prematurely failing requests that would eventually succeed.
- maxRetries +1 — high failure rate detected. One more retry attempt increases recovery probability from 78.4% to 91.6% under those conditions.
The cbFailureThreshold stayed at 10. The system identified that the circuit breaker configuration was already correct for the observed pattern and left it alone.
The config did not revert during recovery. This is intentional — the system is conservative. It needs sustained evidence of healthy traffic before relaxing thresholds, to avoid oscillating between states. In production, that’s the right behavior.
The health check on the auto-learning endpoint: 100% throughout all 160 seconds.
What the numbers say together

What this is and what it isn’t
This is a reference implementation built on BackendKit Labs (https://github.com/BackendKit-labs/backendkit-monorepo) — a suite o resilience and observability packages for NestJS we’re building and validating publicly. The shopify-backend example exists specifically to test these patterns under realistic conditions and share the results.
The suite is young. These tests are part of the validation process, not proof of production hardening. If you run similar patterns in your own codebase and find edge cases, open an issue (https://github.com/BackendKit-labs/backendkit-monorepo/issues) — that’s exactly the feedback that matters at this stage.
The full example, all k6 scripts, and the source are in the monorepo
(https://github.com/BackendKit-labs/backendkit monorepo/tree/master/examples/shopify-backend).
Written by Mairon Cuello (https://www.linkedin.com/in/maironcuellomartinez/) — Building open source resilience tooling for NestJS backends.
GitHub: BackendKit-labs/backendkit-monorepo (https://github.com/BackendKit-labs/backendkit-monorepo)

 Türkiye’de güneş ve rüzgar enerjisinden üretilen elektrik, Nisan 2026’da ilk kez kömür santrallerini geçti. Yenilenebilir enerjinin toplam üretimdeki payı yüzde 71’e ulaştı.
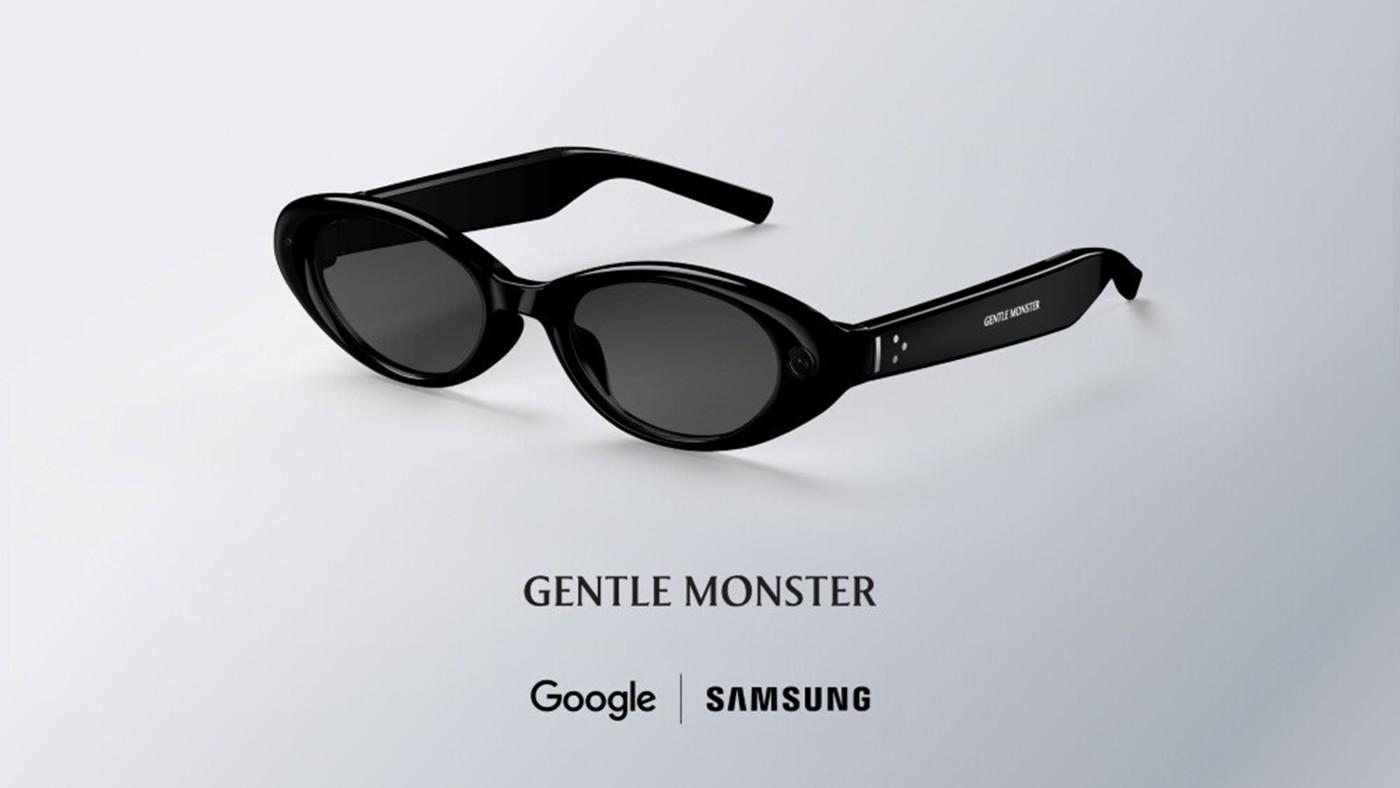
 Samsung ve Google, Gemini destekli yeni akıllı gözlüklerini ilk kez gösterdi. Yeni model, canlı çeviri, navigasyon ve sesli yapay zekâ özellikleriyle geliyor. İşte detaylar…
 Tesla’nın Full Self-Driving (FSD) sürüş sistemi Litvanya’da resmen kullanıma sunuldu. Ülke, Hollanda’nın ardından Avrupa’da FSD’yi onaylayan ikinci devlet oldu.


