Learning Progress Pt.16

Daily learning part sixteen

I started today at 15:40. I did an Access Control lab. It took me quite a bit of time, but I completed it. Then I wrote two Python scripts.

Most basic TCP port scanner

Word guesser(More like a hangman, game in my opinion)

My past project ideas were previously given to me by an AI. I requested them because I thought the projects on the internet were too advanced. Now I’ve started taking ideas from the internet, like the Word guesser I made today. As for JavaScript, I’m not touching it for the moment. Most JavaScript projects also require HTML and CSS. So I need to re-learn HTML in detail and learn CSS over the next month or two, and also finish the entire JavaScript course.

Anyway, after the scripts I did another Access Control lab and then started Lesson 1, Unit 2 of Algebra 1 on Khan Academy. The internet at the student residence is pretty slow, so it takes me a long time to load videos and download things. This lesson took about 30-40 minutes. After the video, I did some research on personal tech projects and practiced Ghostbuster. I’m thinking of starting XSS vulnerabilities soon. I’ll think of it.

“You can always edit a bad page. You can’t edit a blank page.” Jodi Picoult

From Unfinished Idea to Real Product: My BuildGenAI Comeback

This is a submission for the GitHub Finish-Up-A-Thon Challenge

I Finally Revived BuildGenAI: Turning an Unfinished Construction AI Idea Into a Real Product

What I Built

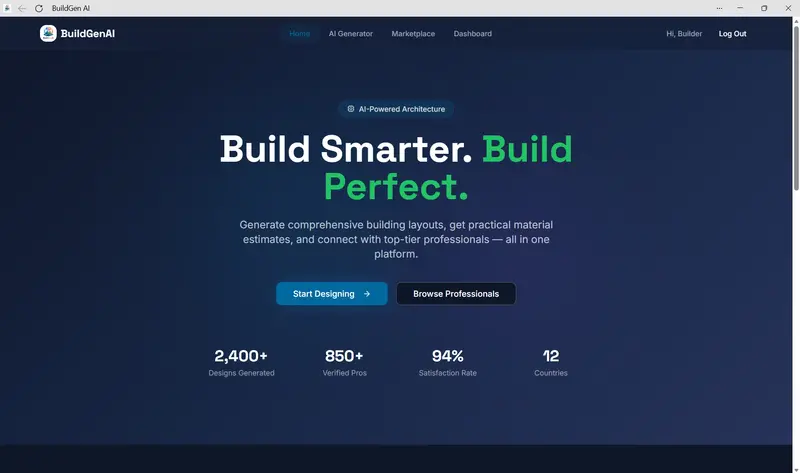
For this challenge, I revived BuildGenAI, a project I had started earlier but never fully completed. The original idea was to create an AI-powered assistant for the construction and home-planning space — something that could help users go beyond just chatting with AI and actually get practical support for planning, estimation, understanding documents, and making better early-stage decisions.

BuildGenAI is built around a simple but meaningful goal: make construction-related guidance more accessible, structured, and easier to understand. In many cases, people who are planning homes, reviewing tenders, estimating materials, or trying to understand compliance-related details do not need another generic chatbot. They need a tool that feels focused on their workflow and gives outputs in a way that is easier to use in real life.
** Before **

** After **

That is the direction I returned to with this project. Instead of letting it remain an incomplete concept, I used this challenge as a reason to finish what I had started and shape the product into something much more presentable. The improved version focuses on turning a rough prototype into a more polished experience with clearer user journeys, better feature structure, and outputs that feel more useful and intentional.

At its core, BuildGenAI is my attempt to bring AI into a domain where clarity matters a lot. Construction planning is expensive, detail-heavy, and full of decisions that can go wrong when people do not have the right guidance early enough. I wanted this project to explore how AI could support that process in a more practical, grounded, and user-friendly way.

Github Copilot Usage

Demo

GitHub Repository: BuildGenAI

Demo Video : https://drive.google.com/file/d/1i_K1RXAL4BsKK8GbsCMUZ0-hwCEOixiI/view?usp=sharing

For the demo section, I am including the project repository and showcasing the revived version through screenshots and/or a walkthrough video. The most important part of this submission is the transformation, so the demo is focused not just on what the app does now, but also on how much stronger and more complete it feels compared to the earlier unfinished version.

This challenge is specifically about showing the comeback, so I wanted the demo to highlight progress, clarity, and completion rather than just listing features. GitHub’s challenge prompt explicitly asks participants to show the before and after and explain how GitHub Copilot helped finish the work.

The Comeback Story

Like many side projects, BuildGenAI started with a strong idea but got stuck before it reached a finished state. The concept was exciting, the direction was promising, and the use case felt meaningful — but the project still had the familiar signs of something unfinished. Parts of the experience were incomplete, some ideas were not fully translated into product flows, and overall it did not yet feel like something ready to be confidently shown as a complete build.

That is what made this challenge a perfect fit.

Instead of starting a new idea from scratch, I decided to revisit BuildGenAI and finally give it the attention it deserved. The first step was not blindly adding more features. It was understanding what the project was lacking. I looked at where the app felt incomplete, where the experience felt confusing, and what parts needed refinement in order to make the product feel coherent.

The biggest shift was moving away from the feeling of a rough prototype and toward the feeling of a usable product. That meant improving structure, clarifying flows, polishing the interface, and thinking more carefully about how the user experiences the app from start to finish. A project can have a good concept and still feel unfinished if the interaction model is weak, the output is messy, or the overall experience lacks direction. That was the gap I wanted to close.

I also wanted the project to feel more focused. Instead of behaving like a generic AI experiment, BuildGenAI needed to feel like a purpose-driven tool. The comeback was really about completing that identity: making it clearer what the project is for, who it helps, and why someone would actually want to use it.

That is the part of finishing a project that often matters most. Completion is not only about writing more code. It is about making the product understandable, cohesive, and ready to stand on its own. This challenge pushed me to do exactly that, and BuildGenAI is much stronger because of it.

What Changed

The revived version of BuildGenAI focuses on polish, usability, and product clarity. The goal was not to overcomplicate the project, but to make the existing idea much more complete and presentable.

Here are the areas I focused on during the revival:

  • Improved the overall product direction so the app feels like a focused construction AI tool instead of a broad experimental prototype
  • Refined the user flow to make interactions more structured and easier to follow
  • Worked on making the interface clearer and more polished
  • Improved the way outputs are presented so results feel more actionable and easier to understand
  • Revisited the unfinished parts of the project and pushed them closer to a demo-ready state
  • Strengthened the overall before-vs-after story, which is a key judging area in the challenge.

One thing I found especially valuable during this process was realizing that the “finish-up” mindset is very different from the “start-up” mindset. Starting is often driven by excitement. Finishing is driven by decisions. You have to decide what matters, what should be cleaned up, what should be removed, and what actually helps the project feel complete.

That mindset helped me make better choices while revisiting BuildGenAI.

My Experience with GitHub Copilot

GitHub Copilot was genuinely useful in helping me bring BuildGenAI back to life. The value was not just in generating code quickly, but in reducing the friction that usually comes with reopening an older project and trying to move it toward completion.

One of the hardest parts of reviving an unfinished project is momentum. You already know there are gaps, messy areas, and incomplete logic. That can make it surprisingly difficult to re-enter the codebase and make progress. Copilot helped lower that barrier by assisting with repetitive tasks, suggesting implementation patterns, improving flow when refactoring, and helping me move faster through the “cleanup and completion” phase.

It was especially helpful when I wanted to:

  • iterate faster on incomplete code paths,
  • refactor rough logic into cleaner structure,
  • speed up repetitive implementation work,
  • brainstorm better ways to shape feature flows,
  • and maintain productivity without getting stuck on every small detail.

For this challenge, Copilot felt less like a shortcut and more like a practical collaborator. It helped me spend less time wrestling with friction and more time improving the actual product experience. Since the challenge specifically emphasizes showing how GitHub Copilot helped finish the project, that became a meaningful part of this revival story as well.

Why I Chose This Project

I chose BuildGenAI because it already had something important: a meaningful problem space. Even in its unfinished state, the idea still felt worth returning to. I did not want to abandon it just because it was incomplete. I wanted to prove to myself that unfinished work still has value if you are willing to revisit it seriously.

This project also reflects the kind of products I enjoy building. I like projects that combine technical implementation with a strong real-world use case. Construction and planning workflows are not always the first area people think about when talking about AI products, which made this project even more interesting to me. It gave me a chance to build something that is not just technically relevant, but also practically useful.

The Finish-Up-A-Thon was the right push at the right time. It gave me a reason to stop treating this as “something I will finish later” and actually turn it into a proper comeback.

Before and After

Before

  • The project had a strong concept but felt incomplete
  • The product direction was not fully realized
  • The experience needed more polish and structure
  • Some parts felt more like a prototype than a finished tool
  • The overall app did not yet communicate its value clearly

After

  • The project has a clearer identity as BuildGenAI
  • The user experience feels more focused and intentional
  • The app is more presentable and easier to understand
  • The product direction is stronger and more coherent
  • The project now has a much better completion arc for showcasing the comeback story

That “before and after” journey is one of the main reasons I wanted to submit this project for the challenge, because the transformation is not just visual — it is also structural, practical, and personal. The official challenge rules and announcement make that completion arc one of the core judging criteria, alongside technology, usability, and originality.

Final Thoughts

This challenge reminded me that unfinished projects are not failures. Sometimes they are just waiting for the right moment, better clarity, and a second round of effort. BuildGenAI started as an idea with potential, got paused before completion, and has now come back as a much stronger version of itself.

For me, that is what this submission is really about. It is not just about shipping code. It is about returning to something unfinished, believing it is still worth building, and doing the work needed to finally bring it closer to completion.

And honestly, that feels more satisfying than starting something new.

Project Link: BuildGenAI

Challenge: GitHub Finish-Up-A-Thon Challenge

The Quiet Strategy

Originally published at mrnasdoggrowth.com by MrNasdog.

Most of what’s being written about AI right now is loud.

Loud about how AI will replace everyone. Loud about how AI changes everything. Loud about which AI tool to use this week. Loud about new model releases. Loud about productivity hacks.

The loud strategy is wrong. Not because AI doesn’t matter — it matters more than almost anything else right now. But because the people who’ll win in the next 20 years aren’t going to win by being louder. They’re going to win by being quiet, patient, and deep.

This article is about the quiet strategy. What it looks like, why it works, and how to live it.

Start with the question

The question I want to answer is simple: how do you build a life and career worth having in the next 10 to 20 years, when AI is reshaping everything?

This is a real question. People I talk to are worried about it. They should be. The world is changing fast.

But the answer isn’t to panic, and it isn’t to chase. The answer is to understand where AI is going, where AI structurally can’t go, and to build your life in the second category.

Where AI is going

AI is going to keep getting better at almost everything that involves processing information.

Writing standard documents. Coding common patterns. Synthesizing research. Analyzing data. Generating ideas. Translating. Summarizing. First-draft anything.

Most knowledge work is going to look very different in 10 years. Either AI will do it directly, or one person with AI will do what used to take a team. This isn’t a prediction — it’s already happening. Companies are quietly cutting roles. Solo operators are out-producing teams. The shift is well underway.

If your career is built on doing work AI can also do, you have a problem. Maybe not immediately, but within the planning horizon you care about.

Where AI structurally can’t go

Now the more interesting half.

There’s a class of work AI can’t do well, and won’t be able to do well for decades. This isn’t because AI is bad — it’s because the work itself has properties that don’t fit how AI works.

Think about how AlphaGo beat humans at Go. AlphaGo had three things going for it: it could generate millions of possible moves, it could test those moves quickly in self-play, and every game ended in a clean win or loss.

These three properties — generate, test, evaluate — are what made AI’s victory possible.

Now think about the questions in your actual life. What career to build. Who to spend your years with. What to work on. What kind of person to become.

You can generate possibilities. But you can’t test them in self-play — each possibility requires years of lived experience to evaluate. And there’s no clean win condition — what “winning at life” means is itself the question.

So for the deepest questions, AlphaGo’s approach doesn’t work. AI can list options for you. AI can analyze trade-offs. AI can summarize what worked for other people. But AI can’t tell you what’s right for you specifically, because the testing requires lived time that AI doesn’t have.

This is one structural limit. There are others.

AI’s training data is always behind the present. For fast-moving topics, AI is always slightly outdated. The gap between AI’s knowledge and current reality is real and ongoing.

AI’s best advice loses its edge when distributed. When AI gives you a great strategy, it gives the same strategy to everyone. Strategies that work because they’re rare stop working when they’re shared.

AI doesn’t have a body or a life. It can simulate possibilities but can’t experience consequences. The lived weight of having done something matters in ways AI can’t replicate.

Time-based outcomes can’t be compressed. Some things only become clear after decades of running. AI can model them but can’t accelerate them.

These four limits combined describe the space where humans still have structural advantages over AI. And they don’t move much in 10 or 20 years.

The shape of the quiet strategy

If you understand where AI is going and where AI structurally can’t go, the strategy follows.

You build in the space AI can’t easily enter.

What does that look like in practice?

Pick something specific and stay with it for years. Not weeks. Not months. Years. Deep expertise in a specific domain becomes more valuable as AI commodifies broad knowledge. The specialist beats the generalist as AI rises.

Build a public record over time. Whatever your work is, document it. Make it discoverable. Time-stamp it. The record itself becomes an asset that compounds. Someone with 10 years of public, traceable work in a specific field has something AI can’t replicate — because AI didn’t live those 10 years.

Use AI as a multiplier, not a replacement. Lean on AI for everything AI is good at. Don’t be precious. But don’t let AI make decisions only you can make. Strategy. Values. Direction. Trade-offs. These stay yours.

Take real positions with real stakes. Public predictions. Public investments. Public commitments. The track record matters because it can’t be faked. AI can hypothesize endlessly but can’t be publicly wrong with real consequences.

Pick fields where the present matters more than the past. AI’s training lag is a real disadvantage to AI in fast-moving areas. Stay current, and you stay ahead of what AI can know.

Accept the trade-offs. You have 24 hours a day. You can’t be everything. Pick what matters most to you and commit. The people who try to optimize everything lose to people who commit to specific things deeply.

What this requires

The quiet strategy is harder than the loud strategy in some ways and easier in others.

Harder because it requires patience. You won’t see fast results. You’ll spend years building things that don’t pay off until much later.

Harder because it requires commitment. You can’t keep switching strategies. The compounding only works if you stay with one thing long enough for it to actually compound.

Harder because it requires being unpopular sometimes. Public positions with real stakes mean being publicly wrong sometimes. The people who hedge to avoid being wrong end up with no track record at all.

Easier because it doesn’t require keeping up with every new AI tool release. You don’t need to be the most current. You need to be the most committed.

Easier because it doesn’t require maximum output. You don’t need to publish daily. You need to publish durably. One excellent piece of work that lasts 10 years beats 100 pieces of forgettable content.

Easier because the loud strategy is genuinely a trap. Most loud strategies in the AI era will produce nothing durable. The quiet strategy looks slow but actually wins.

The 20-year view

If you zoom out to 20 years, the picture clarifies.

The people who panicked about AI and tried to compete with it on AI’s terms will mostly lose. AI is too good at AI’s strengths.

The people who refused to use AI will also lose. The productivity advantage of AI-augmented work is too large to ignore.

The people who’ll do well are the ones who used AI heavily for what AI does well, while building patiently in the gaps where AI can’t go. They’ll look ordinary for years. They’ll look slow. They’ll look unimpressive next to people generating massive AI-assisted output.

But in year 15 or year 20, their lived expertise, their documented track record, their identity-anchored work, their patient specific compounding will be obvious. The fast people will have nothing durable to show. The quiet people will have something AI structurally cannot copy.

This is the strategy that actually works for the next 20 years.

It’s not flashy. It doesn’t go viral. It doesn’t lend itself to TikTok hot takes.

But it’s the real game.

Pick something specific. Commit to it for years. Use AI heavily. Build durable assets in the gaps. Take public positions with real stakes. Stay patient.

Do this for the next 10 to 20 years, and you’ll be one of the few people who actually built something while the rest were either replaced by AI or out-competed by people using AI better.

The quiet strategy is the answer. The hard part is having the patience to live it.

I Revived a 9-Year-Old App with OpenAI Codex with a Product Engineer Mindset

Nine years ago, I built an app called Highlander. It was one of those projects you never forget, but over time it broke: old dependencies, outdated tooling, local setup drift, and deployment blockers.

This week, I brought it back to life. Not by rewriting everything from scratch. By pairing with Codex and treating the work like a Product Engineer: fix what matters, unblock users, and ship value fast.

The Problem: The app was frozen in time:

  • Old Node/Knex/Bookshelf stack
  • Broken local boot flow
  • DB connectivity issues
  • Seed data problems
  • Production-unfriendly hardcoded localhost URLs
  • Security gaps before deploy

It had been broken long enough that I honestly didn’t expect a quick recovery.

The Approach: Product Engineering, Not Just Refactoring:

I didn’t just “clean code.” I prioritized outcomes:

  1. Get local working first
  2. Stabilize data + auth
  3. Fix UX trust issues for demo users
  4. Deploy to Fly.io
  5. Harden for real usage

That sequence mattered more than perfection.

Product Development Context:

This rebuild also reconnects to the original product planning work from the Highlander sprint board on Trello: Highlander product sprint board

That board reflects early MVP scope, feature prioritization, and roadmap thinking. Revisiting the app now with Codex let me combine that original product intent with modern implementation and deployment practices.

What Codex Helped Me Ship:

1) Local revival

  • Pinned runtime compatibility (.nvmrc)
  • Updated critical deps for modern macOS
  • Fixed DB config to support local + production envs
  • Restored migration/seed workflow

2) Demo-ready UX. I added a demo login path directly in the UI.

  • “No account no problem…”
  • Demo credentials on login + registration pages
  • Direct link from registration to login
  • Dashboard welcome message shown once per login session

3) Security hardening. Before deployment, I tightened core risks.

  • Token-based auth middleware
  • Protected routes
  • Login rate limiting
  • Removed sensitive console logs
  • Removed password leaks in API responses
  • Added safer headers and config defaults

4) Deployment to Fly.io

  • Added fly.toml
  • Added Dockerfile + .dockerignore
  • Configured release migration flow
  • Seeded production demo data
  • Code Snapshot: killing localhost coupling

One of the most important production fixes was removing hardcoded localhost API calls

That one change removed mixed-content/CORS issues on deployed pages.

Why this matters for my career growth:

I’m not making a hard transition away from software engineering. I’m intentionally blending Software Engineer + Product Engineer skills so I can widen my career options and be more valuable to a broader set of teams and employers.

This project reflects that blend:

  • AI-assisted delivery speed
  • practical product prioritization
  • hands-on code and architecture updates
  • UX improvements
  • deployment and production hardening

It wasn’t just a code cleanup. It was an end-to-end product delivery exercise.

What’s Next:

I have another 9-year-old app: Highlander-react-redux. It uses the same backend API, but the frontend is React/Redux. Next, I’m going to use Codex again to revive it with the same Product Engineer lens:

  • improve onboarding
  • modernize auth + data flows
  • reduce complexity
  • ship reliably

I’ll document that process too, including what worked, what failed, and what changed in my thinking.

Highlander Project
Demo: https://highlander.fly.dev/index.html
Github: https://github.com/heriberto-codes/highlander

What Enterprise RAG Is Ready For Today and What Production Deployment Actually Requires

Enterprise RAG — A practitioner’s build log | Post 6 of 6

This series has documented a system built to a specific standard: one where access control is enforced before retrieval scoring, where every answer includes traceable citations, and where the evaluation set measures restricted document leakage rather than retrieval relevance alone.

This final post answers the question that matters most for teams considering this as a foundation: what works today, what needs to be in place before this handles real internal documents in a production environment, and what the gap between those two states actually looks like.

What is fully operational today

Every item below runs locally without external dependencies or provider credentials.

Document pipeline:

  • Markdown document ingestion with front-matter role metadata (POST /ingest)
  • SQLite metadata and chunk store with document and chunk count metrics
  • Lexical retrieval with token cosine similarity scoring

Query and access control:

  • Role-based candidate filter applied before retrieval scoring
  • Citation-backed answer generation in deterministic mock mode
  • RBAC_blocked_count logged per query — tracks how many chunks were filtered
  • Role derivation from X-API-Key header, preventing request-body role elevation

API and authentication:

  • FastAPI query API (POST /query) with health probes at GET /health
  • Local user registration with role assignment (POST /auth/register)
  • API key creation, listing, and revocation (POST /api-keys, POST /api-keys/{id}/revoke)
  • SHA-256 key hash storage — raw key never persisted after creation
  • Management endpoint protection via ADMIN_TOKEN

Evaluation:

  • Evaluation runner via POST /eval/run — calls live query pipeline, not a mocked path
  • Four metrics per run: pass rate, restricted leakage count, citation coverage, average latency
  • Per-case results with expected vs. retrieved document IDs and pass/fail indicators

Operational controls:

  • Audit log for all administrative actions (GET /audit-logs)
  • Query log with citations, role, latency, and RBAC metrics
  • Prometheus-style operational metrics endpoint
  • Security headers enabled by default, CORS explicitly configured
  • Structured JSON request logging (JSON_LOGS=true)
  • In-memory rate limiting per client (RATE_LIMIT_PER_MINUTE)

Infrastructure:

  • API-backed Streamlit dashboard — no direct database access from the UI
  • Docker files for containerized runtime validation
  • GitHub Actions CI workflow
  • Azure AI Search retrieval adapter implemented and configuration-selectable
  • OpenAI and Azure OpenAI generation adapters configuration-selectable

The Azure deployment path

The local runtime maps directly to an Azure deployment topology:

Employee → Microsoft Entra ID
↓
Azure Container Apps: API + Dashboard
↓
Azure AI Search (retrieval)
Azure OpenAI (answer generation)
Azure PostgreSQL or Cosmos DB (metadata + audit logs)
Azure Blob Storage (source documents)
↓
Azure Key Vault (secrets)
Application Insights (logs + metrics)

Switching from local to Azure requires environment variable changes only. No code changes. No schema migrations between SQLite and PostgreSQL — the SQLAlchemy layer handles both. Azure mode fails fast when required AZURE_* settings are missing rather than silently degrading to a local fallback.

What production deployment requires beyond the current implementation

Entra ID or OIDC role derivation from identity claims. The local implementation derives role from API key registration. Production deployment should derive role from authenticated identity token claims — not from request parameters or static key registration. The AUTH_PROVIDER=entra configuration path is implemented. End-to-end validation requires a live Azure tenant.

Semantic or hybrid retrieval. The local lexical retriever is deterministic and validates access control correctly. It does not match the retrieval quality of embedding-based semantic search for queries without token overlap with document chunks. Azure AI Search vector and hybrid query modes are the planned production retrieval path.

Distributed rate limiting. The in-memory rate limiter does not share state across multiple API instances. Horizontal scaling requires Redis-backed or API gateway rate limiting.

PII classification and retention policies. The reference document corpus is synthetic. Before ingesting real internal documents — HR records, finance reports, incident logs — the ingestion pipeline should classify content for PII, apply sensitivity labels, and enforce explicit data retention policies for stored queries and generated answers.

Tenant isolation. The current implementation is single-organization. A deployment serving multiple business units with strict data isolation between them requires a tenant isolation layer at the data model and query pipeline level.

Broader evaluation set. The current evaluation set is calibrated for access-control validation across a small synthetic corpus. A production evaluation set requires human relevance labels, answer correctness checks, and a regression threshold integrated into the CI workflow.

An honest assessment

Enterprise RAG demonstrates the architecture that matters for internal knowledge systems: pre-retrieval access control, citation-backed answers, and an evaluation standard that measures restricted document leakage. The local implementation is complete, testable, and fully reproducible without provider credentials.

The gap to production is real and specific. Entra ID integration, semantic retrieval, distributed rate limiting, PII handling, and tenant isolation are well-understood engineering problems with clear solutions. None of them require rethinking the core pipeline — the access control order, the citation model, and the evaluation structure remain intact.

For a team building an internal document Q&A system: the architecture here is worth adopting. The hardening list above is the production backlog, not a reason to start from scratch.

What I would implement next

The highest-impact single item is Entra ID role derivation in production. The entire value of pre-retrieval access control depends on the role being trustworthy. In a local environment with API key role binding, that trust is reasonable. In a production environment with hundreds of employees, role must come from an authenticated identity provider — not from a manually registered key that may become stale when someone changes teams or leaves the organization.

The concrete step: configure AUTH_PROVIDER=entra, map Entra group claims to retrieval roles, and validate that the role filter receives the correct role from the token rather than from the request body. That single change makes the access control guarantee durable against organizational changes.

One question for you

When an employee changes roles or leaves your organization, how quickly does your internal knowledge system stop serving them documents from their previous role? Is that enforced at the identity provider level or at the document system level?

This concludes the Enterprise RAG build log series.

Full series index

  1. The Access Control Gap That Makes Most Enterprise RAG Systems Dangerous
  2. How Enterprise RAG Is Structured: Why Access Control Comes Before Retrieval Scoring
  3. Three Design Decisions That Shaped the Enterprise RAG Retrieval Pipeline
  4. Four Metrics That Actually Tell You Whether Your Enterprise RAG Is Working
  5. Security Controls in Enterprise RAG: Keys, Audit Logs, and the Hierarchy That Prevents Role Elevation
  6. What Enterprise RAG Is Ready For Today and What Production Deployment Actually Requires (this post)

Cursor AI Pricing 2026: Is It Worth $20/Month?

Cursor AI pricing has become one of the biggest developer discussions
in 2026. With the Pro plan at $20/month, is it actually justified —
or is the free tier good enough?

Free vs Pro: What You Actually Get

Free (Hobby) Plan:

  • 2,000 code completions per month
  • 50 slow premium model requests
  • Basic AI chat
  • No priority access to faster models

Pro Plan ($20/month):

  • Unlimited code completions
  • 500 fast premium model requests (GPT-4, Claude, etc.)
  • Unlimited slow premium model requests
  • Priority access to frontier models
  • Advanced codebase indexing

If you’re using Cursor professionally, you will hit the free tier
ceiling fast. The question isn’t if you’ll need Pro — it’s whether
it’s priced fairly.

How Cursor AI Cost Compares in 2026

GitHub Copilot — $10/month

  • ✅ Half the price
  • ✅ Deep IDE integration across VS Code, JetBrains, Neovim
  • ❌ Chat experience is weaker than Cursor
  • ❌ Multi-file editing lags behind

Windsurf (formerly Codeium) — Free + $15/month Pro

  • ✅ Strong free tier, cheaper Pro
  • ✅ Agentic “Cascade” feature is impressive
  • ❌ Smaller model selection
  • ❌ Still maturing in stability

Zed + AI — Free with usage-based costs

  • ✅ Blazing fast, pay-as-you-go
  • ❌ Less polished AI experience

The takeaway: Cursor is the most expensive option — and the one
most developers with serious workloads keep coming back to.

Is Cursor AI Worth It? The Real-World Case

Worth it if:

  • You write code professionally and bill for your time — if Cursor
    saves 1-2 hours per week, it pays for itself
  • You work across large codebases where codebase indexing matters
  • You use AI chat heavily during development
  • You work across multiple languages or frameworks

Not worth it if:

  • You’re a hobbyist with occasional projects
  • Your workflow is boilerplate-heavy with simple patterns
  • You’re deep in a JetBrains ecosystem

The hard number: Cursor Pro costs $240/year. For a professional
developer, that’s less than two hours of billable work.

Should You Upgrade to Cursor Pro in 2026?

Yes — for professional developers, with one caveat.

The caveat is the fast request limit. 500 fast premium requests
sounds reasonable until you’re running extended agentic sessions.
2026 has seen more competition in this space, which tends to push
features up and prices sideways.

The bottom line: $20/month is fair for what Cursor Pro delivers.
Not cheap compared to every competitor, but not expensive relative
to what it replaces — slower development, more context-switching,
and constant tab-juggling.

Still deciding? Our
Best AI Coding Assistants in 2026
guide breaks down every major option.

If you’re still on the fence, start with the free tier. You’ll know
within a week whether you’ve hit the ceiling.

Full breakdown at The Dev Brief

The Brilliant Person in Your Pocket

AI Edge Gallry App- Gemma 4 Use cases

What Gemma 4 taught me about the real future of on-device AI, and why I owe Seyi an apology

This is a submission for the Gemma 4 Challenge: Write about Gemma 4

I poured cold water on an intern’s excitement about a powerful AI model that could run entirely on a phone. That was a few weeks ago, and now, I am the intern.

Let me explain – Seyi is a mechatronics student at Bells University, Nigeria, doing an internship at my workplace. He came in buzzing one morning about Gemma 4, Google’s latest open-weight language model, capable of running completely offline on consumer hardware. His eyes were wide, but mine were narrower. My internal monologue went something like: Why would I want to downgrade to a local model when I have cloud access to far more powerful ones? Privacy concerns didn’t register for me. Usage limits weren’t a real problem on my Google One plan, and an offline model, by definition, is frozen in time, limited to whatever it knew at training.

Where’s the upside, I asked?

I said all of this out loud. Seyi nodded, deflated, and went back to his desk. The universe, as it often tends to do, had a rebuttal scheduled for later that week.

The Argument I Didn’t Expect to Lose

A few days later, I was browsing Martin Sauter’s blog (he’s a telecom author whose book remains one of my favourites), and I check in occasionally even when the content goes well over my head. He’d started a thread on running local AI: terms like OpenWebUI and RAG were being thrown around, discussions about making offline models more dynamic through external connectivity.

Something clicked in my mind. I’ve been thinking for a while about using AI for specialised tasks at work, but corporate environments don’t always play nicely with public cloud AI. Uploading proprietary documents to a public model is a legitimate concern. A capable model running on a personal device, answering to no server and leaving no data trail, was beginning to sound less like a downgrade and more like a completely different category of tool.

Then I saw a LinkedIn post about the AI Edge Gallery, an Android app from Google that lets you run Gemma 4 directly on your phone. No cloud, no subscription, no data leaving the device.

That was it for me. I was in.

More Than a Chatbot in Your Pocket

Before we go further, let me quickly explain what Gemma 4 on AI Edge Gallery actually is, because it is not simply “a smaller ChatGPT that works offline.” That framing undersells what’s actually available here. While Gemma 4 comes in four variants, two of them are light enough to run on a phone: the E2B, optimised for speed on mid-range devices, and the E4B, a smarter model targeted at modern phones with 8GB of RAM or more. I run a Google Pixel 8 Pro with 12GB of RAM, so the E4B was my lane.

The Edge Gallery app itself organises Gemma 4’s E2B and E4B models’ capabilities into distinct workspaces. There’s AI Chat with Thinking Mode, which shows you the model’s step-by-step reasoning in real time (a genuinely useful window into how it arrives at answers). There’s Ask Image, which lets the model read and analyse photos from your camera or gallery, entirely offline. There’s Audio Scribe for transcription and translation. And then there’s Agent Skills, the feature that consumed most of my attention.

AI Edge Gallry App- Gemma 4 Use cases

Agent Skills are best explained with an analogy. Gemma 4 out of the box is a brilliant person who can hold a nuanced conversation. Skills are what you hand that person before the conversation starts, like a calculator, a specialist reference manual, or a set of behavioural instructions. The model reads a menu of available skills at the start of each session, determines which one is relevant to your request, and activates it. The core file that defines each skill is called a SKILL.md — a plain text document with a metadata block at the top (a name and a trigger description) and freeform instructions below (text-only skills). No coding required. Anyone who can write clearly can, in theory, build a custom AI skill.

That word “in theory” is pushing it a bit. More on that shortly.

My First Experiment: Teaching Gemma to Write Like Me

As a telecom professional who writes about the industry, I run a LinkedIn newsletter called Signal Over Noise, and my first instinct was to test Gemma’s ability to replicate my writing style. Not to replace my writing, but to see if a local model could serve as a personal writing assistant, one that knows my voice well enough to be actually useful when I hand it raw material to reshape.

Teaching Gemma to write

The process of building the skill itself was fascinating. I worked with Claude to do a detailed stylistic analysis of my previous non-AI-assisted articles, creating twelve touchpoints covering voice, rhythm, structure, openings, analogies, vocabulary, signature moves, and more. The analysis surfaced consistent fingerprints: the conversational-analytical blend, the personal entry point as a default opening, the pop-culture analogies with Nigerian context, invented compound words, and the self-aware aside that steps just outside the narrative. That profile became a SKILL.md file – my personal, reusable, installable instruction set that could theoretically rewrite any source material in a documented style, calibrated by adherence level.

Then I tried to run it. And Gemma 4, to its credit, was very honest about its limitations.

Three Lessons From a Phone That Crashed, Looped, and Gave Up Mid-Sentence

Lesson One: Instruction Footprint Matters More Than You Think

The first time I tried to activate my style skill on the E2B and E4B variants, the app crashed immediately. Not “it gave a bad output.” It crashed repeatedly.

The root cause, as I later understood it, is that local models operate within strict, hardware-enforced RAM allocations. The original instruction file was verbose: exhaustive descriptions for every adherence level of all twelve style touchpoints. Before the model could process a single user message, the system had to load all of those instructions into its working memory. The sheer volume saturated the phone’s RAM allocation before the engine could even initialise, and the application stopped working.

RAM Overload

The fix was aggressive compression, stripping the descriptive matrices, keeping only the core tenets, reducing the file by roughly 60%, and bringing the system-level instructions under the memory threshold. It worked, sorta. The app stopped crashing.

But this was also the first clear signal: cloud-model habits do not translate to mobile hardware.

Lesson Two: Structured Instructions Apparently Confuse Small Models?

With a leaner file, the skill loaded. But when I prompted it to rewrite a long technical article on 5G network architecture, the model didn’t write anything. It produced this instead:

<|tool_call>call:run_intent{intent:"dabs-style-rewriter", parameters:{"Source Material": "..."

The model had looked at an instruction file formatted with numbered steps, labelled inputs, and a structured schema and concluded it was not a writing persona but an API gateway. It was trying to route data to another application that didn’t exist. Instead of channelling a writer’s voice, it was behaving like a function router.

Confused by highly structured instructions...

The solution was to flip the entire framing from “Steps and Inputs” to “Be this person immediately.” Move away from programmatic structure, toward a pure system instruction that establishes persona from the first line. The model responds to being told who to be far better than it responds to being told what to do in sequence.

Lesson Three: Small Models Have a Working Memory Ceiling…and It Shows

With the condensed, persona-first version of the skill, I finally got output. But it didn’t quite sound like me, and it stopped mid-sentence abruptly. What was happening, as best as I can understand it, is context exhaustion, i.e., the model’s working memory (its KV cache, if you want the technical term) was completely filled by the combination of the instruction file and the dense 700-word 5G article I’d handed it as source material. With no computational overhead left to manage, it began to stutter, outputting typographical duplicates like “all the* the*”, before hitting its timeout and cutting out entirely.

Memory Cap

This is the fundamental gap between a local mobile model and a large cloud LLM. A cloud model can hold hundreds of complex rules, a dense technical source, and an elaborate creative brief simultaneously and produce something nuanced that balances all of them. A 4-billion-parameter model on a phone cannot. Not even close. The reasoning gap is not a flaw to be patched in a software update; it just a consequence of physics and silicon.

So What Are Small Local Models Actually Good For?

Here is the reframe that changed how I think about all of this and, I’d argue, the more interesting question…

Forcing a small local model to perform complex creative persona replication is the wrong brief entirely. It’s like hiring a specialist fabricator to write you a novel. The skills aren’t absent; they’re just misallocated.

What local mobile models genuinely excel at is structured data, deterministic rules, and zero-hallucination utility work. They are fast, private, and always available. The question isn’t “can they replicate a cloud model’s creative output?” The question is “what tasks benefit from a local, lightweight, always-on intelligent layer?”

ILocal LLM on mobile as a key utility

One practical answer I landed on came from my own life. I use a solar-powered inverter setup at home. Managing backup power means keeping an eye on cloud cover, grid stability, and battery load, and I sometimes have to call my wife from work to ask her to check conditions and act accordingly. How about trying out a JavaScript-enabled Agent Skill on my phone, which could probably handle it elegantly.

Here’s how: JavaScript Skills (as opposed to text-only skills, earlier described) give the AI the ability to actually execute code within a hidden browser environment on the phone. The model’s job is reduced to one thing: capturing the user’s natural language input, like a neighbourhood name.

A script then takes that variable, calls a live weather API, retrieves real-time cloud cover data, applies the relevant electrical formulas within JS, and returns a plain-language recommendation. “Turn on the deep freezer. Solar output is adequate.” No creative reasoning required and no hallucination risk. The AI is the natural language interface; the code is the engine.

That division of labour, model as conversational intake and code as execution layer, in my opinion, is where mobile AI actually earns its keep.

What This Means for the Bigger Picture

Step back for a moment and consider what is actually happening here. A model capable enough to understand nuanced instructions, hold a meaningful conversation, and trigger appropriate specialised behaviours, all without sending a single byte of your data to any server, now fits inside a device you carry in your pocket.

That is not a minor development.

The immediate practical implications are clearest in environments where cloud AI is restricted: corporate networks, regulated industries, and low-connectivity regions. For anyone in those categories, Gemma 4 on a capable Android phone is not a compromise. It’s the first viable option. And for the African context specifically, where data costs remain non-trivial, and cloud latency is a genuine UX concern, the case for capable on-device inference is stronger than it might appear from a high-bandwidth Western baseline.

AI in your hands

But the more interesting implication is what it signals about the direction of travel. The bottlenecks I encountered (memory saturation, intent looping, context exhaustion) are real, but they are also well-understood engineering problems.

Model quantisation is getting better. Mobile hardware is also improving. The techniques for writing efficient, structured skills that play to a local model’s strengths rather than fighting its limitations are learnable, and they’re becoming more documented. The floor on what a phone-based AI can do in 2026 is already higher than most people realise. In a few years, the question won’t be whether it’s capable enough, but whether the existing and popularly used cloud model is offering you enough additional value to justify the dependency.

I am not suggesting local models will replace cloud AI. That would be a lazy take, and I’ve already used up my quota of lazy takes in this article (see: Seyi, opening paragraphs). What I am saying is that the role of on-device AI is transitioning from novelty to infrastructure, from “cool demo on a tech blog” to a genuine utility layer for people who need private, fast, and accessible intelligence built into their workflows.

Closing Thoughts: Seyi Was Right

The arc of this whole experiment (from skeptic to cautious convert) tracks almost perfectly with how genuinely disruptive technologies tend to arrive. Not with an obvious, immediate use case that justifies the hype, but with a quiet accumulation of practical realisations that eventually tip into “oh, this is actually something.”

My style-replication skill didn’t work the way I hoped. The model crashed, looped, and truncated. But in failing those tests, it showed me exactly where its real value lies, and gave me a concrete mental model for building agent skills that actually perform. The solar power assistant is on my list. A RAN architecture reference tool for work is also on the list, one that accepts base station design inputs and returns equipment specifications based on local rules, privately, offline. These are not glamorous AI use cases. They are, however, genuinely useful ones.

On-device AI is not the future of AI. It’s the future of how AI fits into ordinary life – quiet, local, and practical, like a good tool should be.

Seyi, if you’re reading this: I owe you one.

Why your Claude API bill is 3x what it should be (and how to fix it)

TL;DR: I audited a friend’s startup that was spending $4,200/month on Claude API. Only $1,300 produced business value. The other $2,900 was waste — split across three patterns that hit most teams using LLM APIs in production. Here’s how to find them in your own bill, and the code to fix each one.

The audit

A friend running a B2B doc-summarization product asked me to look at their Claude bill. Q1 was $4,200/month and climbing. We pulled their request logs into a spreadsheet, classified each call by purpose, then estimated what each should have cost. The answer was uncomfortable:

Bucket Cost Producing business value?
First-time doc analysis $890 Yes
User chat turns $410 Yes
Repeated system prompts (no cache) $1,810 No
Opus calls that should be Sonnet $680 No
Serial bulk runs (should be batched) $410 No

Three problems, $2,900/month of waste. Each one is unsexy and easy to miss, but together they were 70% of the bill.

Culprit #1: prompt caching is off

This is the silent killer. Claude 4.x supports prompt caching: send a 5-minute or 1-hour TTL cache_control block, and Anthropic charges you ~10x less for cached tokens on subsequent requests. Pricing today (per million tokens for Sonnet 4.6):

  • Fresh input: $3.00
  • Cache write: $3.75 (one-time, slightly more than fresh)
  • Cache read: $0.30 — 10x cheaper

The catch: you have to opt in per-request, and most code doesn’t. Before/after:

# Before — every call pays for the full system prompt
client.messages.create(
    model="claude-sonnet-4-6",
    system="You are an expert at...[2000 words of rules + examples]",
    messages=[{"role": "user", "content": user_input}],
    max_tokens=1024,
)
# After — system prompt cached for 5 minutes
client.messages.create(
    model="claude-sonnet-4-6",
    system=[
        {
            "type": "text",
            "text": "You are an expert at...[2000 words of rules + examples]",
            "cache_control": {"type": "ephemeral"},
        },
    ],
    messages=[{"role": "user", "content": user_input}],
    max_tokens=1024,
)

One-line change. 90% discount on every subsequent call within the cache TTL.

For my friend: 20K tokens of system prompt × 8 requests/min × 50% cache hit ratio = ~$80/day saved. That alone was $2,400/month — most of the $1,810 leak.

OpenAI SDK calling Claude (via compatible proxies) has equivalent semantics:

client.chat.completions.create(
    model="claude-sonnet-4-6",
    messages=[...],
    prompt_cache_key="user-session-12345",  # Stable across calls = cache hit
)

Action: open your last week of API logs. If you have any repeated system content across requests, you’re leaking.

Culprit #2: model overkill

The mental shortcut “Claude = quality, just always use Opus” is expensive. Opus is 4x the cost of Sonnet for inputs, 5x for outputs. For a lot of work, Sonnet or even Haiku is indistinguishable.

I ran 5 tasks across the lineup (1000 samples, scored by judge model + human spot-check):

Task Opus 4.7 Sonnet 4.6 Haiku 4.5 Best price/quality
JSON extraction from PDFs 99.2% 98.7% 96.4% Haiku
Code review (real bugs) 74% 74% 61% Sonnet
Creative copy (blind judged) 51% pref 48% pref 32% pref Sonnet
Multi-step reasoning chain 89% 76% 54% Opus
Customer chat 92% sat 89% sat 81% sat Sonnet

The pattern: Opus wins clearly only on complex multi-step reasoning. For most tasks Sonnet is within margin of error at 1/4 the cost. Haiku trades 2-5% accuracy for 1/13 the cost — fine when you have downstream validation.

My friend was running every doc through Opus by default. Switching to Sonnet for analysis + Haiku for tagging dropped that bucket from $680 to $140. No quality complaints.

Action: pick the 3 most expensive endpoints in your bill, A/B-test them on the next cheapest model for a week, score outputs blind.

Culprit #3: serial calls when you could batch

If your work doesn’t need a response in the next 30 seconds, the Anthropic Message Batches API charges half price with a 24-hour SLA. Same models, same quality, half the bill.

Good fits:

  • Nightly summarization runs
  • Classifying or tagging large datasets
  • Embedding generation for indexing
  • Internal report generation
  • Training data prep

Bad fits:

  • Anything user-facing (you’ll wait hours)
  • Anything where input depends on previous output
batch = client.messages.batches.create(
    requests=[
        {
            "custom_id": f"doc-{doc.id}",
            "params": {
                "model": "claude-sonnet-4-6",
                "max_tokens": 1024,
                "messages": [{"role": "user", "content": doc.text}],
            },
        }
        for doc in docs
    ],
)

# Poll until done (or just check tomorrow)
while batch.processing_status != "ended":
    time.sleep(60)
    batch = client.messages.batches.retrieve(batch.id)

My friend had a nightly job re-summarizing all docs from the previous 24h. Moving it from asyncio.gather to batches cut that bucket from $410 to $205, no user-visible impact.

Action: any cron job, weekly report, or async task hitting your LLM API — most can be batched.

The result

After three changes (cache hint, model rebalance, batch the async work), my friend’s monthly bill went $4,200 → $1,540. Same product, same quality, no rewrites — just turning on features the API already supports.

If your bill feels high, do the same audit:

  1. Pull last 30 days of API calls
  2. Count distinct system prompts. <10 unique but >10,000 calls = no caching
  3. Look at top 5 model+endpoint combos by spend. Anything simple enough to downshift?
  4. Find your largest single-day spike. Batch job? Use the batches API.

A shortcut, if you don’t want to instrument all this

I built a little proxy called MidRelay that handles the first two automatically: it injects a per-key cache hint into every request (even SDK code that doesn’t know about cache_control gets the discount), and it exposes both OpenAI and Anthropic surfaces from the same key so you can route model-by-model without rewriting.

It also happens to be 60-80% cheaper than calling Anthropic / OpenAI directly. (Same models, same wire protocol — your existing SDK just changes the base_url.)

$5 of free credit to test it: drop a comment, I’ll DM a code. First 100 readers, no signup gate.

But honestly — the techniques above work on any provider. Even if you never touch MidRelay, just turning on cache_control and downshifting one over-spec’d Opus call will cut your bill more than any “AI cost optimization” SaaS will.

Check your logs tonight.

Why I Built My Own AI Project Management Assistant – and What I Learned

AtlasMind Demo

After decades of managing software programs across different industries, I still found myself spending hours each week writing JQL to get my reporting ready. Every project management tool I have worked with is excellent at storing data and painful at visualizing it. Jira is the best of them. It is still painful. The more you start exploring, the more knowledge and skills one needs to adapt to get a valuable result out of it. And even when you got the data, you still had to turn it into something a stakeholder could read, the right chart, in the right format, without a tutorial. Different reports for different audiences with variety of charts, everyone needed a different view of the same data.

Should I export the data to excel create a pivot table and then generate the chart, or should I use the dashboard reports manually creating each types of charts and linking with the right table, or should I use another custom tool provided by a third party vendor, choices are many but integration efforts and future reliability would be a question and pain. Another daunting topic would be to know how to query using various kinds of query language JQL, SQL or mdx or so on.

To overcome all these problems, I turned to AI, offloading all heavy lifting onto AI and focused on letting it generate the charts or tables with the right query. This is what the AtlasMind tool does, give a question in plain English about your project and you get charts rendered with tables that can be easily filtered and used for your reports with just a click of a button.

AtlasMind is live at atlasmind.de. It runs live against the public Apache jira server. Here is what it looks like in practice.

User : show me all open bugs in project Kafka ordered by priority

JQL    : project = KAFKA AND issuetype = Bug 
         AND status not in ('Closed', 'Resolved') 
         ORDER BY priority DESC

Ai Answer : Open bugs in Kafka project ordered by priority.
         Found 2170 result(s); showing 1000.


Live: https://atlasmind.de
Frontend: https://github.com/sunishbharat/AtlasMind-frontendUI
Backend: https://github.com/sunishbharat/atlasMind-Lite

 
AtlasMind Demo

Type a question in plain English. Get JQL, a chart and an answer in seconds.

Architecture

Query router: It classifies the user query into 3 paths, general pipeline, JQL pipeline or direct chart rendering.

RAG pipeline: when a query is classified as JQL, it follows the RAG pipeline. The system uses Sentence Transformers and pgvector libraries to store the JQL annotations, jira fields, associated values as embeddings. At query time, the user’s question is embedded and compared against stored vector embeddings. Pulls top 5 nearest neighbors using L2 distance between the query and the jira fields available.

LLM Orchestrator: This layer acts as the backend switch to an active backend of the systems choice like Groq, ollama, claude etc. Each backend is a separate async client module.

Self-correcting JQL loop: Before the LLM generated JQL reaches the Jira API, it goes through a 7-pass sanitizer. These seven passes manage the most common LLM failure modes without any LLM call which makes the system more robust. After sanitization, the JQL is regenerated by LLM and is executed against the Jira REST API. This is where the agentic feedback loop begins. The loop runs up to n number of retries. When Jira identifies a specific invalid field by name, the prompt tells the LLM to remove that exact field condition and not to guess or hallucinate any fields. This surgical assertion makes the LLM generate a very deterministic JQL which is valid.

Multi-backend architecture: Why I decided on multi backend is for easy design and usage. During my initial development phase, I built the initial version using local LLM model Ollama with zero cost, zero API tokens, zero cloud dependency. Later I extended it to support other limited/free models which was much better in performance and JQL generation quality.

Deployment: AtlasMind runs on Oracle cloud Infrastructure A1 instance with PostgreSQL + pgvector, Groq (default), Ollama (fallback), and the frontend. This instance hosts everything FASTAPI backend, postgresSQL, Ollama as the local inference fallback and the Svelte frontend. For better performance and heavier inference, there is also support to run on local GPU system running vLLM with quantized 7B Qwen2.5-Coder model over HTTP. When GPU system is off, AtlasMind falls back to local Ollama automatically with no configuration change or restart required.

What I Learned

  • I have not load tested AtlasMind under concurrent users at scale. Likely bottlenecks are pgvector query time under high vector search volumes. Jira API rate limits under parallel requests and LLM inference latency under load. These are unknown problems and honestly for a side project built during evenings and weekends, discovering these problems is a real challenge.

  • One important distinction is that the LLM model is still not fully capable of generating a JQL on its own, multiple trial and errors with surgical assertions still do not make it fully dependable. Fine-tuning with the specific Jira instances would get the JQL generation accuracy significantly higher.

  • Implemented entirely raw without using Langchain or Langgraph libraries, I deliberately built the RAG pipeline and agentic loop from scratch to understand what was happening under the hood. I am equally interested to see if the result changes when used with standard libraries.

AtlasMind is what I wish existed across every programme I have ever run. I built it to prove that the gap between Engineering execution and project intelligence can be closed.

Live: https://atlasmind.de
Frontend: https://github.com/sunishbharat/AtlasMind-frontendUI
Backend: https://github.com/sunishbharat/atlasMind-Lite

What should happen when a repo does not run?

Ota doctor in practice

Most repos still fail in a strangely manual way.

You run a command.
It breaks.

Now you have to reverse-engineer the repo:

  • read the error
  • search the README
  • inspectpackage.json, Docker files, and lockfiles
  • compare local state with CI
  • ask someone who already knows
  • try a few fixes and hope one is the real one

That is annoying for developers, but it is a bigger problem now that AI agents are being asked to work inside unfamiliar repositories.

If an AI agent is told to fix a bug, it first needs a reliable answer to some basic operational questions:

  • What does this repo require to run?
  • Which workflow is the intended front door?
  • Which missing dependency is actually blocking readiness?
  • Which commands are safe to run?
  • What should stop progress vs what is only a warning?

In most repos, those answers are spread across docs, scripts, CI config, and tribal knowledge. That means the agent is not operating from repo truth. It is guessing. That is the problem ota doctor is meant to solve.
ota doctor evaluates a repo against its readiness contract, defined in ota.yaml, and reports:

  • whether the repo is ready
  • what is missing
  • what is blocking readiness
  • what is only degraded or advisory
  • the next safe action to take

So instead of “command failed, go investigate the repo,” you get a structured readiness diagnosis.

For maintainers, that means fewer contributors rediscovering the same setup failures from scratch.

For contributors, it means less time spent diffing docs against reality.

For AI-assisted development, it gives the agent an operational signal before it starts making changes in a repo it does not yet understand.

The broader question is simple:
When a repo is not runnable, what should it say, and how explicitly should it say it?

My view is that “good luck, read the repo” is no longer good enough.

Ota doctor in practice

If you want to pressure-test that idea on a real codebase, try Ota and see what ota doctor surfaces:
https://github.com/ota-run/ota