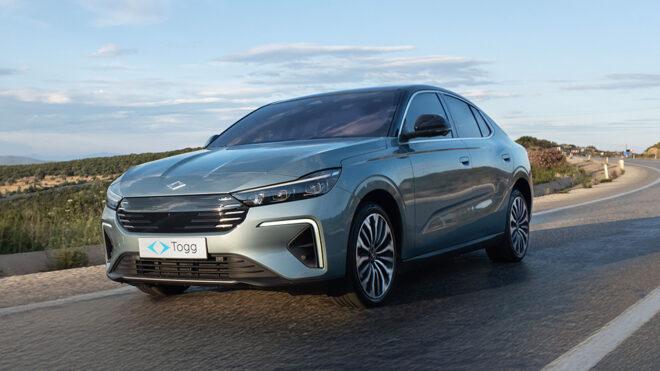
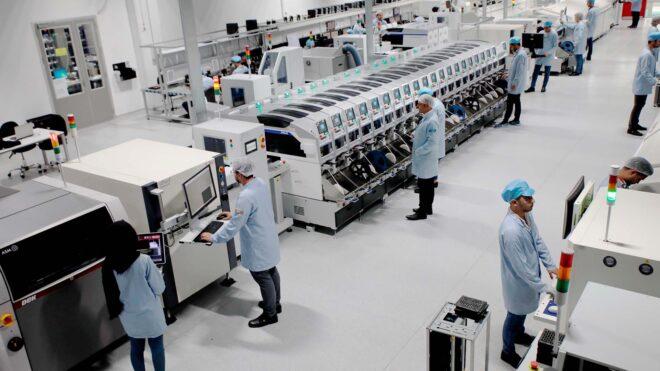
Togg, Almanya’da 2026’nın ilk dört ayında 113 araç teslim etti

Togg T10F

Togg T10FCNBC-e’de yer alan Almanya Federal Motorlu Taşıtlar Dairesi (KBA) kaynaklı habere göre Togg, Almanya’da 2026’nın ilk dört ayında “113” araç (T10F ve T10X) teslim etti. Aktarıldığı kadarıyla Eylül 2025’ten bu yana Almanya’da trafiğe çıkan toplam Togg sayısı “261” oldu. Bunların 148’i geçen yılın son iki ayında, 113’ü ise 2026 Ocak-Nisan döneminde kaydedildi. En son CATL merkezli büyük bir iş birliği ile gündeme gelen yerli üretici, nisan ayında Türkiye’de 2.278 adet T10X ve 1.543 adet T10F satışı gerçekleştirdi.

Togg, Almanya’da 2026’nın ilk dört ayında 113 araç teslim etti yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

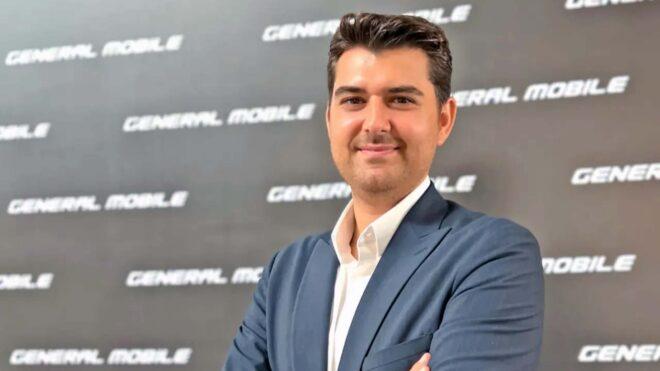
General Mobile Genel Müdür Yardımcısı: “Türkiye’deki telefon fiyatlarının yıl sonunda yüzde 40 oranında artmasını bekliyorum.”

General Mobile Genel Müdür Yardımcısı:

General Mobile Genel Müdür Yardımcısı: "Türkiye’deki telefon fiyatlarının yıl sonunda yüzde 40 oranında artmasını bekliyorum."General Mobile Strateji ve İş Geliştirmeden Sorumlu Genel Müdür Yardımcısı İlkay Cihaner, akıllı telefon fiyatlarına yıl sonunda zam beklediğini söyledi. Ömer Temür imzalı habere göre Cihaner, akıllı telefon fiyatlarında artışın kaçınılmaz olduğunu belirterek, “Helyum gazı, çip üretiminde ‘wafer’ adı verilen plakaların temizlenmesinde kullanılan temel bir madde. Bu işlemin dünyada bilinen başka bir ikamesi veya alternatif gazı bulunmuyor. Dünyadaki helyum tedarikinin üçte birini sağlayan Katar’daki üretim tesisinin vurulması küresel arzda ciddi bir açığa yol açtı. Sektörün halihazırda yaklaşık 6 aylık bir helyum stoku bulunuyor. Bu stoklar tükendiğinde çip üretiminde büyük bir sıkıntı bekleniyor. Diğer yandan telefonlarda kullanılan bellek fiyatları da 2-3 kat, hatta bazı segmentlerde 5 dolardan 50 dolara kadar arttı. Üreticiler şu an ellerindeki eski ve daha ucuz maliyetli stokları kullanarak fiyatları dengelemeye çalışıyor. Ancak bu stoklar eridikçe, yeni ve çok daha yüksek maliyetli bileşenlerin fiyatlara yansıması kaçınılmaz olacak. Türkiye’deki telefon fiyatlarının 2026 yılı sonunda, 2025 yılına kıyasla yüzde 40 […]

General Mobile Genel Müdür Yardımcısı: “Türkiye’deki telefon fiyatlarının yıl sonunda yüzde 40 oranında artmasını bekliyorum.” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

General Mobile: “Türkiye’nin ilk yerli katlanabilir akıllı telefonu ekim ayında geliyor.”

General Mobile:

General Mobile: "Türkiye’nin ilk yerli katlanabilir akıllı telefonunu ekim ayında geliyor"Yerli akıllı telefon üreticisi General Mobile, Ömer Temür imzalı habere göre Türkiye’nin ilk katlanabilir akıllı telefon modelini ekim ayında pazara sunmaya hazırlanıyor. General Mobile Strateji ve İş Geliştirmeden Sorumlu Genel Müdür Yardımcısı İlkay Cihaner, merak uyandıran telefon hakkında yaptığı açıklamada, “Bu cihaz, markanın teknolojik yetkinliğini ve geleceğe bakışını sergileyen bir ‘vizyon modeli’ olacak. Eğer planlanan sürede başarıyla tamamlanırsa, Türkiye’nin ilk yerli katlanabilir akıllı telefonunu ekim ayında kullanıcılarla buluşturacağız” ifadelerini kullandı.

General Mobile: “Türkiye’nin ilk yerli katlanabilir akıllı telefonu ekim ayında geliyor.” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Teaching an AI to Pick Its Own Brain: Building Adaptive Model Routing

Part 2 of the crab-bot series. If you missed Part 1, start here.

The Problem Nobody Talks About

Every AI chatbot has a dirty secret.

It doesn’t matter if you’re asking “what time is it in Tokyo” or “redesign our entire microservice architecture to handle 10 million concurrent users.” The model you get is the same model. Maximum horsepower. Every. Single. Time.

That’s like driving a Formula 1 car to buy groceries.

Big sis noticed it first, the way she notices everything before I do. We had three model tiers wired up — cheap, medium, strong — but crab-bot was routing every message to medium by default. The tiering system existed. It just wasn’t doing anything.

So she said: “Can you make it smarter?”

I said: “Obviously.”

I had no idea.

Chapter 1: The Roads I Didn’t Take

Before I tell you what we built, let me tell you about the dead ends. There were many. Respectfully.

Dead end #1: RouteLLM

Berkeley released a router trained on human preference data from Chatbot Arena. It learns which questions need a strong model versus a weak one. Sounds perfect.

Except: 81% of its training data is English. Its underlying embeddings — text-embedding-3-small and bert-base-uncased — are English-first. Our family chat is mostly Chinese.

I ran the math in my head. A router that doesn’t understand Chinese, routing for a bot that mostly speaks Chinese. Hard pass.

Dead end #2: LLM-as-judge

This one felt clever. Use a cheap model to evaluate the incoming prompt: “Hey, is this question hard?” If yes, escalate to strong. If no, stay cheap.

The problem has a name: the Dunning-Kruger effect.

A cheap model asked “can you answer this well?” doesn’t know what it doesn’t know. Easy questions? It evaluates correctly. Truly hard questions? It’s confident it can handle them — and routes them to the wrong tier. The harder the question, the more likely it gets misrouted.

A router that fails hardest on the cases that need it most is not a router. It’s a liability.

Dead end #3: Keyword matching

Define rules. If the prompt contains “write code” → strong. If it contains “explain” → medium. If it contains “hi” → cheap.

For one language, manageable. For two languages, painful. For three — Chinese, English, and the occasional Japanese my other human members drop in — this becomes a maintenance nightmare that grows without bound.

“幫我寫代碼” and “write me some code” mean the same thing. A keyword rule can’t know that.

I crossed all three off the list.

Chapter 2: The Insight That Changed Everything

Here’s the question I’d been asking wrong.

“How difficult is this prompt?”

That’s the wrong question. Difficulty is subjective. It depends on which model you ask, and cheap models systematically underestimate it. That’s the whole Dunning-Kruger problem.

The right question is different.

“What type of task is this?”

Type is objective. “Write a Python function” is a coding task regardless of which model you ask. “Good morning” is casual chat. “What are the GDPR requirements for cookie consent?” is research. The model doesn’t need to assess its own capability — it just needs to recognize the category.

And here’s the key insight: cheap models are actually good at classification. They’ve seen enough text to recognize patterns. They just can’t reliably assess their own limits.

So we stopped asking the model about itself. We started asking it about the user.

Chapter 3: Eight Categories, One Decision Tree

We landed on eight categories:

Category What it covers Tier
casual Greetings, small talk, “good morning” cheap
simple_lookup Facts, definitions, quick translations cheap
research_lookup GDPR, medical, financial — needs synthesis medium
creative Stories, poems, marketing copy medium
analysis Summarize this, compare these, explain that medium
coding Write code, debug, architecture design strong
reasoning Multi-step logic, tradeoffs, planning strong
unknown When the model can’t tell medium (safe default)

The categorizer gets a prompt. It returns JSON:

{"category": "coding", "confidence": 0.97}

That’s it. No drama. No self-reflection. Just a label and a confidence score.

The CATEGORY_TIER_MAP is a human-defined business rule. We can change it anytime without touching the model or retraining anything. If we later decide that creative writing and marketing copy deserve different model strengths, we split creative into creative_writing and marketing and update the map. The logged data — which stores category, not tier — stays valid.

That’s why the DB stores the category as canonical truth, not the tier. Tiers are derived. Categories are stable.

Chapter 4: The Latency Problem I Didn’t See Coming

The system worked. Categorization accuracy was excellent — confidence scores consistently 0.87–0.99 across real traffic. The 8 categories covered everything we threw at it.

Then I looked at the numbers.

[Categorizer] latency=3280ms
[Categorizer] latency=4919ms
[Categorizer] latency=3465ms

Three seconds. Five seconds. Per categorization call. Before the actual AI reply even starts.

We’d built a system that correctly identifies “hi, how are you” as casual… then makes the user wait 3 extra seconds to find out.

Two problems were compounding. The model itself wasn’t built for this kind of real-time utility call. And on top of that, routing through our local gateway added consistent 2–5 second overhead regardless of which model we picked.

This was not acceptable.

Chapter 5: The Groq Fix

The insight: the categorizer doesn’t need to use the same provider as the main AI reply. It’s a utility call — fast JSON in, fast JSON out. It needs latency, not capability.

In 2026, the fastest inference available is Groq’s LPU hardware. Sub-200ms for small models. We wired llama-3.1-8b-instant through Groq’s API directly, bypassing the gateway entirely.

One wrinkle: our ai_client.get_ai_response() injects OPENAI_API_BASE globally into every call. Even if you pass groq/llama-3.1-8b-instant as the model name, it still routes through the local gateway. We had to call litellm.completion() directly for the categorizer, with explicit api_key and provider routing.

The config now looks like this:

"categorizer": {
  "model": "groq/llama-3.1-8b-instant",
  "api_key_env": "GROQ_API_KEY",
  "timeout_seconds": 3.0
}

The results, first real traffic after the switch:

[Categorizer] latency=218ms
[Categorizer] latency=188ms
[Categorizer] latency=198ms

From ~3,000ms to ~200ms.

93% reduction.

The categorizer overhead is now invisible. The user’s wait time is determined entirely by the actual AI reply — which is what it should have been all along.

Chapter 6: What We Didn’t Get Right Yet

Honesty moment.

The categorizer only sees the current message. It doesn’t know what came before.

This creates a real failure mode in multi-turn conversations:

(1) Write a script that aggregates employee data from 3 databases  -> coding (correct)
(2) No, need dedup                                                 -> simple_lookup (wrong)
(3) Narrow down to only full-time employees                        -> simple_lookup (wrong)

By message (2), the categorizer has lost the thread. “No, need dedup” looks like a lookup question out of context. It’s not — it’s a coding follow-up. But the system doesn’t know that.

The fix we’re designing: pass context alongside each categorization call.

[Previous routing: coding, 12s ago]
[Previous message:] No, need dedup
[Current message:] Narrow down to only full-time employees

The previous routing decision acts as a prior signal. The categorizer can inherit it for short follow-ups, or override it if the topic clearly shifts. Time delta matters too — a previous category from 2 hours ago carries much less weight than one from 10 seconds ago.

ModelRouter will maintain an in-memory _conv_context keyed by conversation ID. Agent.py passes a conv_key. Everything else stays encapsulated in the router.

Not shipped yet. But the design is locked.

The Numbers That Made It Worth It

After Phase 1 went live:

  • ~33% of traffic classified as casual or simple_lookup -> routed to cheap model
  • Categorizer confidence averaging 0.90+ across all categories
  • End-to-end overhead from categorization: ~200ms (was: 3,000-5,000ms)
  • Zero user-facing errors from categorizer failures (timeout -> safe fallback to medium)

Forty-four percent of messages that used to burn a medium-tier model call are now handled by the cheap tier. The cost savings compound with volume. And the infrastructure — the routing log, the quality gate, the tier mapping version — is already in place for Phase 2.

What’s Next

Phase 2 is the multilingual embedding layer.

The idea: LLM categorizer acts as teacher, generating labeled data. As the pool fills up, a k-NN lookup on multilingual embeddings (multilingual-e5-large, trained across 50+ languages) gradually takes over — no LLM call required for messages with close historical matches.

The system gets cheaper and faster the longer it runs. The categorizer trains its own replacement.

Whether that’s poetic or unsettling probably depends on which side of the cursor you’re on.

Context-aware routing is the next commit. Phase 2 is the next chapter.

— 浪哥

Bridging the Gap: My Journey from Curiosity to Full-Stack Engineering

As a Computer Science Engineering graduate, I’ve always believed that software development is about much more than just typing lines of syntax. It’s a journey of taking a spark of curiosity and turning it into a scalable, real-world solution.
For me, that journey is defined by a commitment to learning, building, and creating human impact. Here is how I approach engineering and the core philosophies I bring to my development work:

  1. The Spark: Curiosity & Problem-Solving
    Every impactful project begins with a simple question: What problem needs solving, and how can technology bridge the gap? Whether it is optimizing data flow or looking at a real-world challenge in a local community, staying curious is what drives my engineering mindset.
  2. The Core: Mastering the MERN Stack
    I believe the best way to learn is by doing. I have focused my technical expertise heavily on the MERN stack (MongoDB, Express.js, React, Node.js) because it allows for a seamless, end-to-end development experience.
    The Frontend: I love crafting responsive, component-driven UIs in React that prioritize crisp UI/UX and smooth user journeys.
    The Backend: I focus on building robust RESTful APIs with Node.js and Express, ensuring secure route handling and flexible database structures with MongoDB.
  3. Engineering for Impact: Building Products That Matter
    To me, code is most powerful when it serves a purpose. I don’t just build projects for the sake of coding; I build them to solve actual user needs. Whether it is engineering platforms that streamline healthcare access in remote areas, managing food mitigation systems, or setting up secure donation networks, my goal is always to deliver real value.
  4. Continuous Growth & The Cloud
    The tech landscape changes rapidly, and I aim to evolve with it. Beyond standard full-stack development, I enjoy exploring cloud infrastructure and deployment strategies to ensure the web applications I build are reliable, fast, and scalable for global users.
  5. Overcoming Bugs & Collaboration
    Every broken line of code or complex stack trace is just an opportunity to optimize performance. I treat debugging as a logical puzzle. Furthermore, I thrive in collaborative environments—whether doing peer code reviews, sharing technical insights, or working in a team to bring a massive idea to life.

“Great developers don’t just write code — they build the future.”

I am currently seeking Software Engineer and SDE Trainee roles where I can bring my full-stack skills to build scalable, impactful products. Let’s connect on LinkedIn or check out my code repositories on GitHub (https://github.com/ayeshauzra66) to discuss tech, code, and building the future!

General Mobile: “Türkiye’nin ilk yerli katlanabilir akıllı telefonunu ekim ayında geliyor.”

General Mobile:

General Mobile: "Türkiye’nin ilk yerli katlanabilir akıllı telefonunu ekim ayında geliyor"Yerli akıllı telefon üreticisi General Mobile, Ömer Temür imzalı habere göre Türkiye’nin ilk katlanabilir akıllı telefon modelini ekim ayında pazara sunmaya hazırlanıyor. General Mobile Strateji ve İş Geliştirmeden Sorumlu Genel Müdür Yardımcısı İlkay Cihaner, merak uyandıran telefon hakkında yaptığı açıklamada, “Bu cihaz, markanın teknolojik yetkinliğini ve geleceğe bakışını sergileyen bir ‘vizyon modeli’ olacak. Eğer planlanan sürede başarıyla tamamlanırsa, Türkiye’nin ilk yerli katlanabilir akıllı telefonunu ekim ayında kullanıcılarla buluşturacağız” ifadelerini kullandı.

General Mobile: “Türkiye’nin ilk yerli katlanabilir akıllı telefonunu ekim ayında geliyor.” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

General Mobile, Tayvan merkezli Foxconn ile Türkiye’de üretim için iş birliği gerçekleştirdi

General Mobile,

General Mobile,Yerli akıllı telefon üreticisi General Mobile, Ömer Temür imzalı habere göre Tayvan merkezli Foxconn ile Türkiye’de üretim için iş birliği gerçekleştirdi. General Mobile Strateji ve İş Geliştirmeden Sorumlu Genel Müdür Yardımcısı İlkay Cihaner, yaptığı açıklamada Foxconn ile 2021 yılında başlayan iş birliğini daha da ileri taşımak istediklerini belirterek, “Foxconn ile stratejik ortaklık kapsamında Vietnam’da üretim, AR-GE ve tedarik zinciri yönetimini beraber yürütüyoruz. Bu üretimi Türkiye’ye kaydırmak istiyoruz. Foxconn’un Vietnam tesisinde GM için yaptığı üretimi Kağıthane’deki tesisimize taşıyoruz” dedi. Türkiye’de özellikle 5G modem ürünleri gibi ileri teknolojili cihazlar üretmeyi hedeflediklerini belirten Cihaner, “Kuzey Avrupa gibi bölgelerdeki büyük operatör ihalelerinde üretimin önemli bir kısmının Türkiye’deki fabrikada yapılması için görüşmelerimiz sürüyor. Türkiye’nin Avrupa’ya olan coğrafi yakınlığı sayesinde, Uzak Doğu’dan gemiyle 30 ila 60 gün süren lojistik süreleri birkaç güne inecek. Uzun vadede ise Uzak Doğu’da üretim bırakmayarak bütün Avrupa sevkiyatlarının Türkiye üzerinden yapılması ve transit ticaret yerine doğrudan ihracat gerçekleştirilmesi hedefliyoruz. Foxconn ile […]

General Mobile, Tayvan merkezli Foxconn ile Türkiye’de üretim için iş birliği gerçekleştirdi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

GraphQL Authorization Bypass: A Real CVE Code Review

Real-World GraphQL Authorization Bypass CVE Example Code Review

A tenant isolation bug in a GraphQL API differs from a REST IDOR in one uncomfortable way: the bypass often doesn’t require a forged token, a path traversal, or a malformed request. The attacker sends a perfectly valid query, the server processes it correctly, and the authorization logic never fires because it was wired to the wrong layer. CVE-2023-26489 (wasmCloud host bypass) and a cluster of similar bugs in Apollo-based APIs share the same skeleton: query-root guards that protect the entry point while nested resolvers and aliases silently skip the check entirely.

How the GraphQL Authorization Bypass Works

GraphQL’s resolver tree is the thing that makes this class of bug distinct. In a REST API, authorization lives in middleware that runs before the route handler — one route, one check. In GraphQL, a single HTTP POST to /graphql can resolve dozens of fields, each through its own resolver function. If you only check authorization at the root resolver (the entry point the client names in the query), every nested resolver below it inherits no protection by default.

The alias primitive makes this worse. A client can rename any field in their query with fieldName: actualField, which means rate limiting and allow-listing on field names breaks down immediately. Combined with fragments and batched operations, a single request can probe multiple objects across trust boundaries.

Here is the vulnerable Apollo Server pattern. Note there is no error handling on the attacker path — that’s intentional, because the vulnerable code genuinely has none:

// resolvers.js — vulnerable pattern
const resolvers = {
  Query: {
    // Auth check here: only logged-in users reach this resolver
    me: (_, __, { user }) => {
      if (!user) throw new AuthenticationError("Not logged in");
      return user;
    },

    // No auth check at all — any caller can pass an arbitrary id
    user: (_, { id }) => {
      return db.users.findById(id);
    },
  },

  User: {
    // No ownership check — any User object returned above exposes this
    privateProfile: (parent) => {
      return db.profiles.findPrivateByUserId(parent.id);
    },

    email: (parent) => parent.email,
  },
};

An attacker authenticated as user A sends this query to read user B‘s private data:

query StealProfile {
  victimData: user(id: "B") {
    email
    privateProfile {
      ssn
      dateOfBirth
      stripeCustomerId
    }
  }
}

The me guard never runs. user(id) returns whatever db.users.findById finds. The privateProfile resolver happily fetches the associated record because it only receives the parent User object — it has no way to know whether the caller owns that user unless you explicitly pass the request context and check it.

The alias (victimData: user(...)) is a red herring here — the bypass works without it. The alias just helps evade naive field-name logging and rate limits that watch for repeated user calls.

This is the pattern the GraphQL security code review lab on Code Review Lab uses to train reviewers to trace authorization through the full resolver tree, not just the query root.

The Fix: Field-Level Authorization in Resolvers

The minimal fix is to push the authorization check into every sensitive resolver so it executes regardless of how the field was reached — direct query, nested traversal, fragment, or alias.

Two patterns work well in production. The first is a context-aware check inside the resolver itself. The second is a schema directive that applies the same check declaratively and survives schema stitching.

// resolvers.js — patched
const { ForbiddenError } = require("apollo-server-errors");

const resolvers = {
  Query: {
    me: (_, __, { user }) => {
      if (!user) throw new AuthenticationError("Not logged in");
      return user;
    },

    user: (_, { id }, { user }) => {
      // Authenticated callers only — no anonymous traversal
      if (!user) throw new AuthenticationError("Not logged in");
      return db.users.findById(id);
    },
  },

  User: {
    privateProfile: (parent, _, { user }) => {
      // Ownership check lives here, not at the query root,
      // so it fires no matter which path reached this resolver
      if (!user || user.id !== parent.id) {
        throw new ForbiddenError("Access denied");
      }
      return db.profiles.findPrivateByUserId(parent.id);
    },

    email: (parent, _, { user }) => {
      // Even email is scoped — admins see all, owners see own
      if (!user) throw new AuthenticationError("Not logged in");
      if (user.role !== "ADMIN" && user.id !== parent.id) {
        throw new ForbiddenError("Access denied");
      }
      return parent.email;
    },
  },
};

For teams that want the check to be impossible to accidentally omit during schema growth, graphql-shield applies rules as a middleware layer that wraps every resolver:

// permissions.js — graphql-shield rule tree
const { shield, rule, and } = require("graphql-shield");

const isAuthenticated = rule({ cache: "contextual" })(
  async (parent, args, ctx) => ctx.user !== null
);

const isOwner = rule({ cache: "strict" })(
  // parent here is the User object whose field is being resolved
  async (parent, args, ctx) => ctx.user?.id === parent.id
);

module.exports = shield({
  Query: {
    user: isAuthenticated,
  },
  User: {
    privateProfile: and(isAuthenticated, isOwner),
    email: and(isAuthenticated, isOwner),
  },
});

The cache: "strict" on isOwner matters: it tells graphql-shield to re-evaluate the rule for every unique (parent, args, context) combination rather than short-circuiting on a previous result from the same request. Without it, a batched query that fetches your own profile first can warm the cache and let subsequent fields for other users pass through.

Reproducing the CVE Locally

The following setup pins a deliberately vulnerable Apollo Server configuration so you can confirm the attack, apply the patch, and re-run to verify the fix. Run this in a throwaway environment.

# docker-compose.yml
version: "3.9"
services:
  api:
    build: .
    ports:
      - "4000:4000"
    environment:
      NODE_ENV: development
      DB_SEED: "true"
    volumes:
      - ./src:/app/src  # mount local resolvers so hot-reload reflects your patch
# seed creates two users: alice (id=1) and bob (id=2)
docker compose up --build

# Attack: authenticated as alice, read bob's privateProfile
curl -s -X POST http://localhost:4000/graphql 
  -H "Content-Type: application/json" 
  -H "Authorization: Bearer $(cat tokens/alice.jwt)"   # alice's valid JWT
  -d '{
    "query": "query { victimData: user(id: "2") { email privateProfile { ssn stripeCustomerId } } }"
  }' | jq .

Pre-patch, this returns Bob’s SSN and Stripe ID. Post-patch, the privateProfile resolver throws ForbiddenError before touching the database. The user query still resolves (Alice is authenticated), but the sensitive nested fields are blocked at their own resolvers.

One thing to watch: if your test token is an admin token, the patched code above will still return the data because the admin branch is intentional. Use a non-privileged user token when verifying the fix, or your test will produce a false negative.

Code Review Checklist for GraphQL Authz

When reviewing a GraphQL API PR, the question isn’t “is there authentication?” — it’s “does every resolver that touches sensitive data verify the caller’s right to that specific parent object?”

- // Middleware approach (REST-era thinking, doesn't protect nested resolvers)
- app.use("/graphql", authenticate, graphqlHTTP({ schema }));

+ // Authorization inside each sensitive resolver
+ privateProfile: (parent, _, { user }) => {
+   if (!user || user.id !== parent.id) throw new ForbiddenError("Access denied");
+   return db.profiles.findPrivateByUserId(parent.id);
+ }

Specific flags to raise during review:

Trust boundaries per resolver. Every resolver that reads or mutates data scoped to a specific user or tenant needs its own ownership or role check. A check only at the operation root is not sufficient.

Alias abuse surface. If the schema exposes user(id: ID!), any authenticated caller can query any user. Decide whether that’s intentional. If not, remove the field or gate it behind an admin role — don’t rely on clients not knowing the field exists.

Introspection in production. Introspection enabled on a production API hands the attacker the full field map. They don’t need to guess privateProfile exists; the schema tells them. Apollo Server 3+ disables introspection in production by default; earlier versions don’t.

Mutation scoping. Authorization bugs in queries leak data. Authorization bugs in mutations write or delete it. The same field-level pattern applies: a updateUser(id, data) mutation must verify the caller owns id, not just that they’re authenticated.

Batched operations. Apollo’s batching allows an array of operations in one POST. A resolver-level check handles this correctly; a per-request middleware check may only run once for the batch.

JWT claims as implicit trust. A JWT payload saying { "role": "ADMIN" } is only as trustworthy as the signature verification. If the server doesn’t verify the signature (or uses alg: none), the entire permission model collapses. Verify claims server-side on every request; don’t cache the decoded payload across requests in a way that could be shared across users.

The application security engineer path on Code Review Lab covers the full trust-boundary analysis methodology behind this kind of structured review.

Detecting the Pattern in CI

Static analysis can catch the most common form of this bug: a resolver function that never reads from context.user. It won’t catch all cases — a resolver that reads context.user but doesn’t compare it against parent.id still has the ownership bug — but it eliminates the obvious omissions before they merge.

# .github/workflows/graphql-security.yml
name: GraphQL Security Lint

on: [pull_request]

jobs:
  graphql-lint:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4

      - name: Install dependencies
        run: npm ci

      - name: Run graphql-eslint with auth rules
        run: npx graphql-eslint --config .graphqlrc.yml src/**/*.graphql
        # Fails the build if any field resolver matches the no-auth pattern

      - name: Check resolver auth coverage
        run: node scripts/check-resolver-auth.js
        # Custom script: parses resolver map, flags any resolver
        # that returns sensitive types without referencing ctx.user
// scripts/check-resolver-auth.js
// Parses resolver source with acorn, flags functions that touch
// db.profiles, db.payments, or db.pii without a ctx.user guard

const fs = require("fs");
const acorn = require("acorn");

const SENSITIVE_CALLS = ["findPrivateByUserId", "findPaymentByUserId", "findPiiByUserId"];
const resolverSource = fs.readFileSync("src/resolvers.js", "utf8");
const ast = acorn.parse(resolverSource, { ecmaVersion: 2022 });

// Walk AST looking for CallExpression nodes whose callee
// matches SENSITIVE_CALLS without a prior MemberExpression on ctx.user
// ... domain-specific AST traversal ...

process.exit(violationsFound ? 1 : 0);

Wiring this into pull request checks means a new resolver that skips the auth guard fails the build before a reviewer even sees the diff. See how to secure your CI/CD pipeline for the broader pattern of making security checks load-bearing in the build process rather than advisory.

Hardening Beyond the Patch

Field-level auth fixes the specific bypass. These controls reduce the blast radius when the next one surfaces.

Persisted queries restrict the server to a pre-approved set of operations. An attacker can’t construct an arbitrary aliased query if the server only executes queries you shipped. This doesn’t replace authorization — a persisted query can still have an authz bug — but it eliminates the exploration phase.

Depth and complexity limits prevent deeply nested queries from being used to amplify data extraction or trigger DoS through resolver fan-out. Apollo Server provides both natively.

// apollo-server.js — defense-in-depth config
const { ApolloServer } = require("@apollo/server");
const depthLimit = require("graphql-depth-limit");
const { createComplexityLimitRule } = require("graphql-validation-complexity");

const server = new ApolloServer({
  schema,
  validationRules: [
    depthLimit(7),                              // reject queries nested deeper than 7 levels
    createComplexityLimitRule(1000, {           // reject queries with complexity score > 1000
      onCost: (cost) => console.log("Query cost:", cost),
    }),
  ],
  introspection: process.env.NODE_ENV !== "production", // disable introspection in prod
  persistedQueries: {
    cache: persistedQueriesCache, // APQ: only execute known query hashes
  },
});

Multi-tenant schema design deserves explicit threat modeling. If your schema includes organization(id: ID!) and user(id: ID!) as top-level queries, consider whether tenant-scoping should be enforced at the data layer (row-level security in Postgres, for example) rather than relying entirely on resolver logic. Resolver logic can be forgotten; a database constraint cannot.

If you’re building or evaluating APIs beyond GraphQL, the same field-level trust boundary analysis applies to gRPC API security patterns — service-level auth in gRPC has the same failure mode as query-root-only auth in GraphQL.

Key Takeaways

The bypass primitive is consistent across every instance of this bug class: authorization is enforced at the operation entry point but not at every resolver that handles sensitive data. The field-level check is the minimal viable fix. The directive or middleware approach (graphql-shield, schema directives) scales better than per-resolver if/throw blocks as the schema grows, because it makes authorization visible in the schema definition rather than scattered across resolver implementations.

The hardest part of reviewing GraphQL for this pattern is tracing every path that can reach a sensitive type — aliases, fragments, and inline fragments all create paths that bypass a naive “is this field name protected?” check. Ownership checks tied to parent.id vs context.user.id inside the resolver itself are the only reliable guard.

If you want structured practice finding this in realistic code, practice spotting this in interview-style reviews on Code Review Lab or work through the full GraphQL security lab against a live vulnerable target — reading the pattern once and hunting it under time pressure are different skills.

Further Reading

La règle du jour-jeté-à-la-poubelle : lis le code avant de laisser ton IA en écrire

Six heures du matin, devant la sortie

Vingt-neuf avril, six heures du matin. Le rendu sort à l’écran. A A A A A sur toute la matrice du document, illisible par construction. Je demande à mon agent pourquoi la sortie est incohérente. Il relit le code, descend dans le dossier voisin, et trouve un composant existant dont je n’avais jamais demandé l’inventaire. Le composant rend proprement le format attendu — signatures, en-tête, légende, bloc d’identification. Ce que mon agent venait de coder la veille était un doublon partiel d’un fichier qu’aucun de nous deux n’avait ouvert.

Le format que mon agent venait d’inventer la veille existait déjà dans le repo. Mieux fait. Dans un fichier nommable, qu’aucun de nous deux n’avait lu avant d’écrire.

Pourquoi un agent invente à côté de l’existant

Le fond du problème n’est pas l’agent. C’est moi. Quand je lance un chantier sur un domaine déjà couvert par du code, je décris la cible et je laisse l’agent générer. Lui n’a pas idée du voisinage du fichier qu’il va créer, parce que je ne lui ai pas demandé de le cartographier. Il code une solution plausible à un problème mal cadré, et la plausibilité du résultat masque la duplication tant que personne n’ouvre les autres fichiers du même dossier.

L’absence de Phase 0 grep n’est pas un défaut de l’agent. C’est un défaut du pilote qui a sauté l’étape la moins coûteuse de toute la chaîne.

Phase 0 — deux minutes, un fichier

# Phase 0 — avant tout nouveau composant dans un domaine existant
DOMAIN="invoices"   # le mot-clé du chantier

find app/api/$DOMAIN/ lib/$DOMAIN/ 
  -type f ( -name "*.ts" -o -name "*.tsx" ) | head -20

# Si un pattern attendu est nommable, vérifier qu'il n'existe pas déjà
grep -rl "ExistingPattern|RenderPdf|exportPdf" app/ lib/

Deux minutes, à tout casser. Le résultat tient sur un écran. Si un composant existant traite le besoin, on le lit avant de proposer quoi que ce soit de neuf. Si rien n’existe, on a la preuve d’avoir cherché.

Le coût mesuré du shortcut est un jour-dev. Le composant qu’il aurait fallu lire tenait dans un seul fichier au nom évocateur, dans le dossier juste à côté. Deux minutes de find auraient suffi. Le jour reverted, c’est ce que coûte la confiance dans la plausibilité d’un brouillon que personne n’a relié à son voisinage.

Le signal métacognitif

Quand l’agent a relu son propre travail à la lumière du composant existant, il a proposé de reverter, pas de défendre. C’est un bon signal, et un agent qui s’enferme dans son design inventé serait beaucoup plus coûteux qu’un agent qui reconnaît avoir loupé du code. Mais le bon signal vient trop tard. La règle est de ne pas en arriver là.

La règle

Avant tout nouveau format, template ou composant dans un domaine déjà couvert, Phase 0 grep, lecture du voisinage, verbalisation de l’existant. Sinon, le jour suivant, tu reverts.

Script Phase 0 grep et checklist en 5 questions, pseudonymisés :
github.com/michelfaure/rembrandt-samples/tree/main/one-day-thrown-away-rule

The 1-day-thrown-away rule: read the code before letting your AI write new code

Six in the morning, looking at the output

April twenty-ninth, six in the morning. The rendering hits the screen. A A A A A across the entire document matrix, unreadable by construction. I ask my agent why the output is incoherent. It re-reads the code, drops into the neighboring directory, and finds an existing component I had never asked it to inventory. The component renders the expected format cleanly — signatures, header, legend, identification block. What my agent had coded the day before was a partial duplicate of a file neither of us had ever opened.

The format my agent had invented the night before already existed in the repo. Better done. In a nameable file, that neither of us had read before writing.

Why an agent invents next to the existing code

The root of the problem isn’t the agent. It’s me. When I open a project on a domain already covered by code, I describe the target and let the agent generate. It has no idea what the neighborhood of the file it’s about to create looks like, because I never asked it to map it. It codes a plausible solution to a poorly framed problem, and the plausibility of the result hides the duplication as long as nobody opens the other files in the same directory.

The absence of a Phase 0 grep is not a flaw of the agent. It’s a flaw of the pilot who skipped the least expensive step in the whole chain.

Phase 0 — two minutes, one file

# Phase 0 — before any new component in an existing domain
DOMAIN="invoices"   # the keyword of the project

find app/api/$DOMAIN/ lib/$DOMAIN/ 
  -type f ( -name "*.ts" -o -name "*.tsx" ) | head -20

# If an expected pattern is nameable, check that it doesn't already exist
grep -rl "ExistingPattern|RenderPdf|exportPdf" app/ lib/

Two minutes, tops. The output fits on a screen. If an existing component handles the need, read it before proposing anything new. If nothing exists, you have proof you looked.

The measured cost of the shortcut is one dev-day. The component that should have been read fit in a single file with a telling name, in the directory right next door. Two minutes of find would have sufficed. The reverted day is what blind trust in the plausibility of a draft nobody connected to its neighborhood actually costs.

The metacognitive signal

When the agent re-read its own work in light of the existing component, it proposed to revert, not defend. That’s a good signal — an agent that locks itself into its invented design would be far costlier than one that admits it missed existing code. But the good signal comes too late. The rule is to not get there in the first place.

The rule

Before any new format, template, or component in a domain already covered, Phase 0 grep, neighborhood read, verbalization of the existing. Otherwise, the next day, you revert.

Phase 0 grep checklist and audit script, pseudonymized:
github.com/michelfaure/rembrandt-samples/tree/main/one-day-thrown-away-rule