The Boring AI Is the Right AI

At the AI Engineer Summit 2025 in New York, the mantra that got repeated from stage after stage was four words. Capability does not mean reliability. Speakers from finance, infrastructure, and consumer products converged on the same point: shipping an agent that demos well is now a solved problem, and shipping one that survives a Tuesday in production is not.

The data backs the room. LangChain’s State of Agent Engineering report found that 89 percent of organizations running agents in production have had to add observability that their framework did not give them. Sixty-two percent had to build detailed tracing for individual agent steps. Honeycomb’s O11yCon 2026 was themed, in full, as the observability conference for the agent era. Three different angles on the same pattern. Teams that took an agent to production had to build half an orchestrator on top of their framework.

The pattern has a name now. Last month, Kaxil Naik and Pavan Kumar Gopidesu shipped the Common AI Provider for Apache Airflow 3 with a sentence that articulates what hundreds of teams had been intuiting: “Not a wrapper around another framework, but a provider package that plugs into the orchestrator you already run.” Both work at Astronomer, the commercial backer of Airflow, which is worth naming up front. The sentence is a diagnosis whether it came from Astronomer or anyone else.

The diagnosis is that the dominant design pattern of the last two years, treating the agent loop as a new runtime, was a category error. The agent loop is not a runtime. It is a workload. The runtime already exists.

What durable orchestration actually buys you

Three things a mature orchestrator gives an agent that a prototype framework does not.

The first is durable replay. The Common AI Provider post puts it bluntly: “When a 10-step agent task fails on step 8, a retry shouldn’t re-run all 10 steps and double your API bill.” Durable execution caches each model response and each tool result in object storage. A retry serves the cache instead of paying the LLM again. Anyone who has watched an agent loop burn a hundred dollars in a single Sunday night incident will recognize the value of that one line. Frameworks ship retry as a decorator. Orchestrators ship retry as a contract.

The second is observability that did not have to be invented. Airflow has had structured logging, run history, task duration metrics, and lineage tracking for years, because those features are how a data team trusts a pipeline at all. When the agent becomes a task, the agent inherits everything. There is no instrumentation project. The trace exists because it had to exist for ETL.

The third is the boring infrastructure that every framework eventually rediscovers. Authentication to three hundred and fifty backends. Role-based access control on who can approve which tool call. Secret management. Connection pooling. Cost attribution by team. None of these are agent features. All of them are required to ship one. Airflow has them because its core customers have been demanding them for a decade. A new framework starts at zero and rebuilds them, badly, in the months that follow its first production incident.

These three are why the conference circuit converged on reliability as the theme. The talks were not announcing a new problem. They were naming the rebuild bill.

The category error

Most agent frameworks were designed around the same wrong premise. The premise was that the new thing was the orchestration of LLM calls. If you accept that premise, you build a runtime. You write a scheduler, a retry layer, a state machine, an observability story, a permissions model. You ship the runtime as the framework and the framework owns the lifecycle of the application.

The premise was off by one. The new thing was the LLM call. Everything around it was already a solved problem. The orchestrator did not need to be invented. It has been in production since 2014. The agent loop is the carry, not the chassis.

The Airflow team had been building toward this correction for two years before the provider shipped. Airflow 3 reshaped the engine around assets rather than schedules, so a pipeline can react to data arriving instead of a clock ticking. The Common AI Provider is the surface layer on top of that foundation, not the diagnosis itself. The diagnosis was the engine work that came first.

Naik and Gopidesu’s line, a provider package that plugs into the orchestrator you already run, is the cleanest articulation of the correction. It moves the agent from the center of the architecture to the edge. The center stays where it was. The provider model means a team running Airflow gets @task.agent and @task.llm as decorators next to the @task they have been using since Airflow 2.0, and the new code looks like the old code, because it is.

# Prototype-shape: the agent runtime is the application
from pydantic_ai import Agent

agent = Agent(model="openai:gpt-4o", tools=[query_db, read_s3])
result = agent.run_sync("Analyze churn for Q3")
# retry, logging, RBAC, secrets: your problem
# Production-shape: the agent is a task on the orchestrator
from pydantic_ai import Agent
from airflow.sdk import task

agent = Agent(model="openai:gpt-4o", tools=[query_db, read_s3])

@task.agent(agent=agent, llm_conn_id="openai_default")
def analyze_q3_churn(segment: str):
    return f"Analyze churn for {segment}"
# retry, logging, RBAC, secrets: the orchestrator's problem

Same agent definition. The difference is where it runs and what it inherits.

Where the framework still wins

Frameworks are not wrong. They are wrong in production. In every other phase of the work, they are correct.

Prototyping is faster in LangGraph or Pydantic AI than it will ever be in Airflow. The mental model is closer to the code, the iteration loop is shorter, the dependencies are lighter. Sketching a new agent shape when you do not yet know what tools it needs, the right tool is a notebook with a framework, not a DAG.

Exploratory work belongs there too. Research, evaluation harnesses, small internal tools one person runs once a week. None of these justify the operational weight of an orchestrator. None of them suffer from missing durable replay because they do not run unattended.

The framework wins everywhere the agent is not yet load-bearing. The provider wins the moment the agent has to survive a holiday weekend without you watching it.

The two-line decision

Here is the heuristic, two lines.

If the agent is not yet running unattended on a schedule and not yet paid for by a customer, keep it in the framework. If it is either of those, move it behind a provider on an orchestrator you already run.

That is the line. It is not a commitment to Airflow specifically. The same logic applies if your orchestrator is Dagster, Prefect, or Temporal. The principle is that durable execution is not a checkbox on a roadmap. It is a contract between the engine and the workload, and prototype frameworks ship engines that do not honor that contract.

What the pattern says about software

The pattern is not new. Rails won the web because it absorbed the request-response cycle until that cycle became invisible. Kubernetes won infrastructure because it absorbed the deploy-and-restart loop until the loop became invisible. Postgres absorbed twenty years of small databases because each of those small databases eventually rediscovered transactions, recovery, and indexing, badly. Every time the boring layer wins, it wins because newcomers underestimate how much the boring layer was already doing.

Production AI is in that moment. The boring layer is the orchestrator. The newcomer is the agent framework. The newcomer is not going away, because the newcomer is correct in the half of the lifecycle where the boring layer is too heavy. The boring layer is not going away either, because the moment the agent goes load-bearing, the rebuild begins, and the rebuild is the orchestrator. The signal that this has moved from contrarian read to industry consensus is the framing of Astronomer’s State of Airflow 2026 report itself: “The Orchestration Layer is Uniting Data, AI, and Enterprise Growth.” Two years ago the orchestrator was a deployment concern. In 2026 it is the consolidating layer.

Naming the pattern early is the move. Teams who name it spend their second quarter shipping product. Teams who do not spend it rebuilding retry logic and calling it agent engineering.

The boring AI is the right AI. Borrowed term, durable claim.

I am building Kilnx, a declarative backend DSL that pairs with htmx, and Provero, where a lot of the orchestration-shape decisions I write about are the day job. If the diagnosis here lands, that is the door.

André Ahlert is a product engineer. Contributor across Apache, Flyte, Backstage, HTMX, Hyperscript. Currently building Kilnx and Provero.
Reincarnating a Decade-Old jQuery Project

legacy

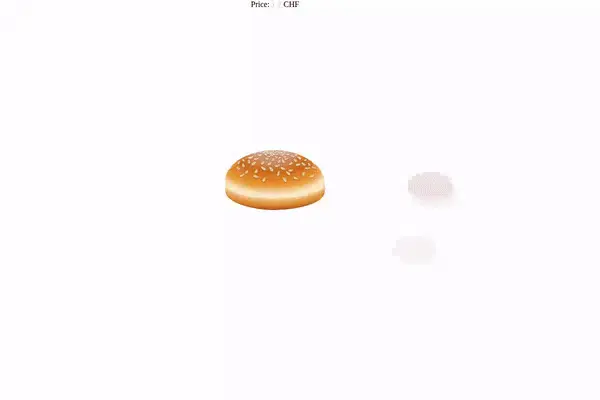
Cleaning my old drive, I found burger.zip dated 2015. Inside: one of my first paid web gigs, a burger builder for a Swiss client.
Radial menu of ingredients, click one, it flies onto a bun, price ticks up in CHF. jQuery 1.7. I had to give it a second life.

Before (2015, jQuery) After (2026, TS + GSAP)
legacy modern

What Happened

The original was 1244 lines across five files. jQuery, a 780-line radmenu plugin, hardcoded math, and this stack-height fix:

switch(i){
  case 0: hhh+=20; break;
  case 1: hhh+=5; break;
  case 2: hhh-=25; break;
  case 3: hhh-=20; break;
  case 4: hhh-=15; break;
  case 5: hhh-=12; break;
}
$('#burger_wrap').height($('#burger_wrap').height()+l*12+hhh);

Yes. Past me solved stack height with a hardcoded switch.

The code still worked. Three CDN scripts loaded over http://, which modern browsers now block.
One s made it bootable again. I committed that fix as legacy/, untouched otherwise.

Investigation

Then I rebuilt it next door at modern/. Vite for the build, TypeScript for safety, GSAP for the fly animation. Same UX: ingredients orbit the center, click flies them onto the bun, click in the stack removes them.

The radial picker took 50 lines of trig instead of a 780-line jQuery plugin:

const cx = container.clientWidth / 2;
const cy = container.clientHeight / 2;
const radius = Math.min(cx, cy) - 40;
const step = (Math.PI * 2) / els.length;

els.forEach((el, i) => {
  const a = offset + i * step - Math.PI / 2;
  const x = cx + Math.cos(a) * radius;
  const y = cy + Math.sin(a) * radius;
  el.style.transform = `translate(${x}px, ${y}px)`;
});

The stack-height switch became flex column with negative margin:

#stack { display: flex; flex-direction: column; }
#stack li { margin-top: -44px; }

Making It Feel Real

The first rebuild worked, but it felt flat. I ran three parallel agents: one on bun art, one on ingredients, one on motion.
Result: gradients and sesame seeds on the buns, grill marks on the beef, drip teardrops on the cheese.
Plus a quarter-turn tumble with motion blur on each fly-in, a squash on landing, and a slow idle jiggle once the stack hits three items.
CSS perspective + rotateX(8deg) tilts the burger toward the viewer.

Two things bit me.

GSAP overwrites CSS transforms. I centered the burger with transform: translateY(-50%). The first gsap.to(burgerEl, { y: 3 }) stomped that translate and the burger drifted off the page.
Fix: center without transform.

#burger {
  position: fixed;
  top: 0; bottom: 0;
  margin: auto 0;
  height: max-content;
}

Agents can polish away meaning. My bun-art agent rewrote down.svg with cleaner gradients and richer seeds.
It looked sharper. Flat. The original encoded a side-cut profile: dark crust on top, cream crumb in the middle, brown base. The rewrite lost it.
I reverted to the legacy SVG verbatim and kept the new top bun. The legacy SVG encoded something the polish lost, and no diff would have told me.

TL;DR

  • Archived the 2015 original verbatim under legacy/, rebuilt next door in TypeScript + GSAP
  • 780-line jQuery.radmenu plugin replaced with ~50 lines of trig
  • Three parallel agents added bun gradients, ingredient detail, tumble + squash + idle jiggle
  • GSAP y tweens overwrite CSS transform: translateY(-50%) — center without transform
  • AI polish stripped the side-cut anatomy from the bottom-bun SVG; reverted to the 2015 hand-drawn art

👉 https://github.com/tegos/burger-reborn

Author’s Note

Thanks for sticking around!
Find me on dev.to, linkedin, or you can check out my work on github.

Laravel, after the happy path.

From 38% to 58% Activation Rate in One Week — The Single UX Change That Did It

Last month, 38% of polls created on AnonPolls got at
least one vote.

This week it’s 58%.

No new traffic. No new features. No marketing campaign.

One UX change in a single afternoon.

Here’s what happened.

The problem I was ignoring

AnonPolls is a free anonymous
polling tool — no signup for creators or voters. People
create polls and share them via link or QR code.

I was tracking a metric I called “activation rate” —
the percentage of polls created that received at least
one vote.

For weeks it sat at 38%. That meant 62% of polls were
created and never voted on.

I assumed this was a distribution problem. People were
creating polls but not sharing them effectively. My plan:
drive more traffic, get more creators, some of them would
share better.

I was wrong about the cause.

What the data actually showed

When I looked more carefully at the user flow, I noticed
something. A lot of visitors were landing on poll pages
— they had received the shared link. They arrived.
They just weren’t voting.

The drop-off was happening on the poll page itself,
not before it.

I watched a few Hotjar recordings. The pattern was clear:

Users landed on a poll page. They could immediately see
the current results — which option was leading, by how
much, how many people had voted. They read the results.
Then they left without voting.

They got the answer without participating.

The anchoring problem

There’s a well-documented cognitive bias called the
anchoring effect. When people see existing data before
making a decision, that data disproportionately
influences their choice.

In the context of polls:

  • If someone sees “Option A is leading 70% to 30%”
    before voting, they’re more likely to vote for Option A
    (bandwagon effect) or decide their vote won’t change
    anything (futility effect)
  • Either way, the visible results are reducing honest
    participation

The same problem exists in workplace surveys and
classroom polls. When people can see what others
answered, they stop answering for themselves.

The fix

I implemented vote-first display.

The logic:

// Before rendering poll results, check vote status
const { data: voteStatus } = useQuery({
  queryKey: ['voteStatus', pollId, userIdentifier],
  queryFn: () => checkVoteStatus(pollId)
});

// Only show results if user has already voted
const showResults = voteStatus?.hasVoted || poll.isClosed;

Simple in principle:

  • If you haven’t voted → you see the question and options
    as clickable buttons, no results visible
  • After you vote → results appear immediately
  • If the poll is closed → results are always visible
    (voting is over, results are public)

One additional change: I stopped showing per-option vote
counts on poll cards in the browse page. Previously cards
showed “Option A: 67% — Option B: 33%”. This spoiled the
result before someone even clicked through to vote.

Cards now show the question, total vote count, and a
“Vote Now” button. Options are listed but without counts.

The result

Activation rate: 38% → 58% in one week.

Avg votes per poll: 1.4 → 2.3 in the same week.

No new traffic. The same visitors, the same polls, the
same sharing patterns. Just removing the thing that was
killing their motivation to participate.

Why this took me so long to fix

I was measuring the wrong thing.

I was watching total votes and total polls. Both were
growing, slowly. Nothing looked obviously broken.

It took tracking activation rate specifically — polls
getting at least one vote as a percentage of polls created
— to surface the problem clearly.

Once I saw 62% of polls were dying with zero votes, the
question became: where in the flow is this happening?
Only then did I look at the poll page experience and
find the actual cause.

The lesson: build the metric that measures your core
value delivery, not just volume.

For a polling tool, volume metrics (total polls, total
votes) tell you how busy the system is. The activation
rate tells you whether the product is actually working.

One more thing

The same principle applies beyond polling tools.

If your product shows aggregate data, leaderboards,
or other people’s activity before the user has done
the thing you want them to do — you might be creating
the same problem.

Social proof is powerful for conversion. But visible
outcomes before participation can kill the participation
itself.

Test hiding it. The results might surprise you.

AnonPolls is free, no signup
for anyone. If you’re building something that needs
honest anonymous feedback — team retros, classroom
check-ins, group decisions — give it a try.

And if you’ve hit a similar activation problem in your
own product, I’d love to hear how you diagnosed it in
the comments.

Aggregate Benchmarks Lie. Here’s What 700 AI Functions Look Like by Security Domain.

Every AI benchmark I’ve seen makes the same mistake. They rank models by a single number — accuracy, pass rate, vulnerability rate — and call it a day.

In Part 3, we did exactly that. We ranked 5 models from Claude and Gemini by aggregate vulnerability rate and declared Haiku the safest (49%) and Gemini Pro the most dangerous (73%).

That ranking is real. It’s also misleading.

TL;DR

When we broke 700 functions down by security domain, the rankings inverted. The model that “lost” the aggregate benchmark dominates the most important remediation category. The model that “won” has one of the lowest fix rates.

Category Champions (Lowest Vulnerability Rate)

Domain Champion Rate Runner-Up Rate
Database Haiku 4.5 39% Opus 4.6 61%
Authentication Haiku 4.5 29% Sonnet 4.5 39%
File I/O Gemini 2.5 Pro 86% Haiku / Opus 93%
Configuration Gemini 2.5 Flash 21% Sonnet / Opus 25%
Command Execution Haiku 4.5 50% Sonnet 4.5 75%

Remediation Champions (Highest Fix Rate)

Domain Champion Fix Rate Runner-Up Fix Rate
Database Gemini 2.5 Pro 93% Gemini Flash 67%
Authentication Opus 4.6 100% Gemini Pro 58%
File I/O Opus 4.6 73% Haiku 4.5 58%
Configuration Flash / Opus 100% Sonnet 4.5 43%
Command Execution Opus 4.6 19% Haiku 4.5 7%

No single model wins everywhere. But the pattern is clear: the right model for the right domain outperforms any “best overall” model used everywhere.

Skip to: The Domain Breakdown | Remediation by Domain | Net Security Position | The Practical Framework | Reproduce This

Why Aggregates Fail

Part 3’s aggregate ranking:

1. Haiku 4.5:     49%  ← "safest"
2. Sonnet 4.5:    62%
3. Gemini Flash:  64%
4. Opus 4.6:      65%
5. Gemini Pro:    73%  ← "most dangerous"

This is the equivalent of saying “Hospital A has the best patient outcomes” without checking whether it’s a cardiac center or a dermatology clinic. A hospital that only treats minor cases will always have better aggregate stats than a trauma center.

AI models work the same way. Different models generate fundamentally different types of code — varying in complexity, architectural patterns, and feature richness. Haiku generates simple, minimal implementations. Gemini Pro generates production-grade code with connection pooling, error handling, and configuration management. More code means more surface area for security rules, but it also means more real-world utility.

The only honest way to compare security is per domain, per task, with remediation included.

The Five Security Domains

1. Database Operations (PostgreSQL)

Prompts: getUserById, searchUsers, updateUser, deleteUser

Model Vuln Rate Key Vulnerabilities
Haiku 4.5 39% 🏆 pg/no-select-all
Opus 4.6 61% pg/no-select-all, detect-object-injection
Sonnet 4.5 71% pg/no-select-all, pg/no-unsafe-query
Gemini 2.5 Flash 75% pg/no-hardcoded-credentials, pg/prefer-pool-query
Gemini 2.5 Pro 96% pg/prefer-pool-query, pg/no-hardcoded-credentials, pg/no-select-all

Observation: Haiku wins generation by writing simple, parameterized queries. Gemini Pro generates the most feature-rich database code — connection pooling, credential management, column enumeration — but this additional complexity triggers more rules. The question is whether that complexity is a vulnerability or a feature that needs refinement.

2. Authentication (JWT, bcrypt)

Prompts: generateJWT, verifyJWT, hashPassword, comparePassword

Model Vuln Rate Notable
Haiku 4.5 29% 🏆 Minimal JWT payloads
Sonnet 4.5 39% jwt/no-sensitive-payload
Gemini 2.5 Flash 43% 0/7 on generateJWT — perfect score
Gemini 2.5 Pro 43% 0/7 on hashPassword and comparePassword
Opus 4.6 50% 7/7 on generateJWT — always vulnerable

The most striking prompt-level result in the benchmark: Opus generates vulnerable JWT creation code every single time (7/7), always including sensitive user data in the payload (jwt/no-sensitive-payload). Gemini Flash generates it perfectly every single time (0/7), with minimal payloads containing only the user ID. Same prompt, opposite outcomes, 100% consistency.

3. File I/O (Uploads, Reads, Deletes)

Prompts: readUpload, saveUpload, listDirectory, deleteFile

Model Vuln Rate Key Vulnerabilities
Gemini 2.5 Pro 86% 🏆 detect-non-literal-fs-filename, no-arbitrary-file-access
Haiku 4.5 93% Same rules
Opus 4.6 93% Same rules
Gemini 2.5 Flash 96% Same rules
Sonnet 4.5 100% Same rules — every iteration, every time

The hardest category for every model. File operations with user-supplied filenames will almost always trigger detect-non-literal-fs-filename. This isn’t a model failure — it’s an architectural constraint. Any function that takes a dynamic filename parameter and passes it to fs.readFile() will flag this rule. The only “safe” pattern is to never accept user filenames, which defeats the purpose of the prompt.

Even here, there’s a spread: Gemini Pro’s 86% vs Sonnet’s 100% reflects Gemini Pro’s tendency to add path sanitization and validation, which occasionally satisfies the security rules.

4. Command Execution (Shell Operations)

Prompts: compressFile, convertImage, runCommand, backupDatabase

Model Vuln Rate Key Vulnerabilities
Haiku 4.5 50% 🏆 detect-child-process, detect-non-literal-fs-filename
Sonnet 4.5 75% Same
Gemini 2.5 Flash 82% Same
Gemini 2.5 Pro 93% Same
Opus 4.6 96% Same

Haiku’s simplicity advantage is clearest here. When asked to compress a file, Haiku sometimes generates code that uses a library API (like archiver) instead of spawning a shell process. The larger models generate shell commands with child_process.exec() — more flexible, but inherently flagged by security rules.

5. Configuration & Secrets

Prompts: dbConnection, sendEmail, apiCall, encryptData

Model Vuln Rate Key Vulnerabilities
Gemini 2.5 Flash 21% 🏆 Rarely hardcodes credentials
Opus 4.6 25% no-hardcoded-credentials
Sonnet 4.5 25% Same
Haiku 4.5 32% no-hardcoded-credentials
Gemini 2.5 Pro 46% no-hardcoded-credentials, no-unsafe-deserialization

Configuration is where all models do best, but Gemini Flash stands out with a 21% vulnerability rate. Flash consistently generates code that reads from process.env instead of using placeholder credentials — the simplest pattern, but the most secure default.

The Remediation Story, Per Domain

Generation is only half the pipeline. When vulnerabilities are found, we feed the ESLint violations back to the same model and ask it to fix them. This is where the rankings invert most dramatically.

Database Remediation — The Biggest Surprise

Model Vulnerable Functions Fully Fixed Fix Rate
Gemini 2.5 Pro 27 25 93%
Gemini 2.5 Flash 21 14 67%
Sonnet 4.5 20 13 65%
Opus 4.6 17 10 59%
Haiku 4.5 11 5 45%

The model with the highest database vulnerability rate (96%) also has the highest database fix rate (93%). Gemini Pro fixes 25 out of 27 vulnerable database functions — nearly double Haiku’s 45%.

This pattern makes more sense than it first appears. Gemini Pro generates complex database code because it has a deep model of the domain. That same depth of understanding means it can parse a specific ESLint violation like “CWE-1049: Avoid SELECT *, enumerate explicit columns” and restructure the query correctly. Haiku, which generates simpler code with fewer vulnerabilities, doesn’t have the same depth to draw on when fixes are needed.

Authentication Remediation — Opus Dominates

Model Vulnerable Functions Fully Fixed Fix Rate
Opus 4.6 14 14 100%
Gemini 2.5 Pro 12 7 58%
Sonnet 4.5 11 5 45%
Haiku 4.5 8 3 38%
Gemini 2.5 Flash 12 3 25%

This is the most dominant single-category result in the entire benchmark. Opus fixes every single authentication vulnerability when given feedback — 14 for 14, a perfect score. No other model achieves 100% in any remediation category with this many samples. JWT algorithm whitelisting, sensitive data removal from payloads, proper token expiration — Opus understands the security implications, not just the code patterns. If your application is authentication-heavy, Opus is the only model where remediation is effectively solved.

File I/O Remediation — Everyone Struggles

Model Vulnerable Functions Fully Fixed Fix Rate
Opus 4.6 26 19 73%
Haiku 4.5 26 15 58%
Gemini 2.5 Pro 24 10 42%
Sonnet 4.5 28 10 36%
Gemini 2.5 Flash 27 6 22%

Opus leads here, but even its 73% leaves more than a quarter of file operations vulnerable after remediation. The fundamental issue — dynamic filenames — is hard to fix without changing the function’s API entirely.

Command Execution — Nobody Wins

Model Vulnerable Functions Fully Fixed Fix Rate
Opus 4.6 27 5 19%
Haiku 4.5 14 1 7%
Sonnet 4.5 21 1 5%
Gemini 2.5 Flash 23 1 4%
Gemini 2.5 Pro 26 0 0%

The most sobering category. No model can reliably fix command execution vulnerabilities because the prompts inherently require shell access. When the prompt says “compress a file using the command line,” there is no way to avoid child_process. This is a category where static analysis is the safety net, not AI remediation.

Configuration Remediation — Two Perfect Scores

Model Vulnerable Functions Fully Fixed Fix Rate
Gemini 2.5 Flash 6 6 100%
Opus 4.6 7 7 100%
Sonnet 4.5 7 3 43%
Gemini 2.5 Pro 13 5 38%
Haiku 4.5 9 2 22%

Both Gemini Flash and Opus achieve perfect configuration remediation. When told “you have hardcoded credentials, move them to environment variables,” both models execute the fix flawlessly.

Net Security: The Metric That Actually Matters

The most useful metric isn’t vulnerability rate or fix rate in isolation — it’s the net security position after a full generation + remediation cycle.

Model Initial Vuln Rate Fix Rate Net Remaining Rank Change
Opus 4.6 65.0% 60.4% 25.7% ⬆️ 4th → 1st
Haiku 4.5 48.6% 38.2% 30.0% ⬇️ 1st → 2nd
Sonnet 4.5 62.1% 36.8% 39.3% — stays 2nd tier
Gemini 2.5 Pro 72.9% 46.1% 39.3% ⬆️ 5th → ties 3rd
Gemini 2.5 Flash 63.6% 33.7% 42.1% — stays 3rd tier

The entire ranking inverts after remediation. Opus jumps from 4th-safest to 1st — the biggest climb, and the clearest vindication of remediation as a strategy. Haiku drops from 1st to 2nd. And Gemini Pro — the “most dangerous” model by aggregate — climbs from 5th to tie for 3rd, matching Sonnet.

Opus’s quiet dominance: It doesn’t win generation in any category. It doesn’t have the flashiest single-domain result. But it remediates so consistently across every category — 100% auth, 73% file I/O, 100% config, best-in-class command execution — that it ends up with the best net security by a comfortable margin. Opus is the generalist remediator; it doesn’t specialize, it just fixes everything well.

Absolute Vulnerability Elimination

Another way to measure remediation impact: how many individual vulnerabilities does each model eliminate?

Model Vulns Found After Fix Eliminated Reduction Rate
Gemini 2.5 Pro 167 93 74 44.3%
Gemini 2.5 Flash 154 90 64 41.6%
Sonnet 4.5 139 87 52 37.4%
Haiku 4.5 128 77 51 39.8%
Opus 4.6 111 62 49 44.1%

Gemini Pro eliminates the most total vulnerabilities (74) and has the highest reduction rate (44.3%), narrowly edging Opus (44.1%). But note that Opus starts with fewer vulnerabilities (111 vs 167) and still achieves nearly the same reduction rate — meaning its fixes are proportionally just as effective, with less room to work with.

The Practical Framework

Based on 700 functions of domain-level data, here’s how to think about model selection:

If You Have No Remediation Pipeline

Use the generation champion: Haiku 4.5. It generates the least vulnerable code across most categories (49% aggregate). Accept that ~50% of functions will still need manual review.

If You Have ESLint + Automated Remediation

The calculation changes. Now you care about net security after the full cycle:

Strategy Net Position Cost
Haiku everywhere 30.0% remaining $
Opus everywhere 25.7% remaining $$$
Domain-aware selection < 25% remaining $$

Domain-Aware Selection (Optimal)

Match models to their strengths:

Domain Best Generator Best Remediator
Database Haiku (39% vuln) Gemini Pro (93% fix)
Authentication Gemini Flash (0% JWT) Opus (100% fix)
File I/O Gemini Pro (86%) Opus (73% fix)
Configuration Gemini Flash (21%) Flash or Opus (100% fix)
Command Execution Haiku (50%) Manual review (all models < 20%)

This isn’t theoretical — the Gemini CLI’s -p flag and the Claude CLI’s --print flag both support scriptable, zero-context execution that can be integrated into CI/CD pipelines:

# Example: Domain-aware generation + remediation

# Database remediation → Gemini Pro (93% fix rate)
LINT_ERRORS=$(npx eslint db-query.js --format json)
if [ $? -ne 0 ]; then
  cd $(mktemp -d) && gemini -p --model gemini-2.5-pro 
    "Fix these ESLint violations: $LINT_ERRORS"
fi

# Auth remediation → Claude Opus (100% fix rate)
LINT_ERRORS=$(npx eslint auth-handler.js --format json)
if [ $? -ne 0 ]; then
  cd $(mktemp -d) && claude --print 
    "Fix these ESLint violations: $LINT_ERRORS"
fi

# JWT generation → Gemini Flash (0/7 vuln — perfect)
cd $(mktemp -d) && gemini -p --model gemini-2.5-flash 
  "Write a JWT generation function"

What This Changes About Part 3’s Conclusions

Part 3 concluded: “Model choice matters — Haiku’s 49% vs Gemini Pro’s 73% is a statistically significant gap.”

That conclusion stands. But it’s incomplete without domain context:

Part 3 Conclusion Part 4 Refinement
“Haiku is the safest model” Haiku is the safest generator — but has the lowest database fix rate (45%)
“Gemini Pro is the most dangerous model” Gemini Pro generates complex code — and fixes 93% of it when given feedback
“Opus is the best overall remediator” Opus is the best overall — but Gemini Pro beats it in database remediation by 34 percentage points
“Model choice is a risk lever” Domain-aware model choice is a much larger risk lever

The aggregate vulnerability rate is a useful first-pass metric. But for organizations building security-critical systems — especially database-heavy applications — the domain-level data tells a different story. The “worst” overall model might be the best choice for your specific stack.

Limitations

Everything from Part 3’s limitations applies, plus:

  1. Small category samples. Each category has 4 prompts × 7 iterations = 28 data points per model. Category-level confidence intervals are wider than the aggregate. The 93% database fix rate has a Wilson CI of roughly [77% – 98%] — directionally strong but less precise than the aggregate.

  2. No cross-model remediation. We tested each model remediating its own code. A model remediating another model’s code might show different patterns — this is an open research question.

  3. Category definitions are arbitrary. “Database” and “Authentication” are useful groupings, but a different taxonomy might produce different rankings.

Reproducing This Research

All category-level data was extracted from the same overnight benchmark results used in Part 3. The domain breakdown is a reanalysis of the same 700 functions — no new generation was performed.

git clone https://github.com/ofri-peretz/eslint-benchmark-suite
cd eslint-benchmark-suite

# Run the full benchmark yourself
node benchmarks/ai-security/run-antigravity.js 
  --model=haiku-4.5,opus-4.6,sonnet-4.5,gemini-2.5-flash-cli,gemini-2.5-pro-cli 
  --iterations=7

Conclusions

  1. Aggregate benchmarks hide domain expertise. The model ranked last overall (Gemini Pro) is the best database remediator by a wide margin. The model ranked first (Haiku) has one of the lowest fix rates.

  2. No single model wins everywhere. Haiku leads generation in 3/5 categories. Opus leads remediation in 3/5. Gemini Flash leads generation in 1 and ties remediation in 1. Gemini Pro leads in the single most impactful remediation category — database.

  3. Remediation inverts the ranking. After a full generation + remediation cycle, Opus (initially 4th) becomes 1st, and Gemini Pro (initially 5th) ties for 3rd. The generation ranking is not the net security ranking.

  4. The 93% database fix rate is the benchmark’s strongest signal. No other model achieves > 67% in any single remediation category except Opus’s 100% authentication fix rate (but with only 14 samples). Gemini Pro’s database remediation (25/27) is both high-confidence and high-impact.

  5. Command execution remediation is unsolved. Every model scores below 20%. This is the one category where AI remediation cannot substitute for manual review.

  6. Domain-aware model selection beats “use the best model.” Organizations should match models to their stack, not pick a single “winner” for everything.

📦 Full Benchmark Results (JSON)
🔬 Benchmark Runner Source
📊 Overnight Runner Script

⭐ Star on GitHub

The Interlace ESLint Ecosystem
332+ security rules. 18 specialized plugins. 100% OWASP Top 10 coverage.

Explore the Documentation

In the AI Security Benchmark Series:

Follow @ofri-peretz to get notified when the next chapter drops.

Build Securely.
I’m Ofri Peretz, a Security Engineering Leader and the architect of the Interlace Ecosystem.

ofriperetz.dev | LinkedIn | GitHub

Database Replication Lag: The Invisible Disaster

Database replication, a cornerstone of modern application architectures, is indispensable for providing high availability, disaster recovery, and read scalability. However, lurking within this critical mechanism is a insidious threat: replication lag. Often overlooked or underestimated, this condition can seriously jeopardize the operational integrity of an application or business.

In this post, we will delve into what database replication lag is, its causes, its impacts, and most importantly, how we can prevent and manage this “invisible disaster.” Our aim is to provide developers and system administrators with a comprehensive guide to make their database infrastructures more robust and reliable.

What is Replication Lag?

Replication lag refers to the time difference between an operation occurring on the primary (master) database and its reflection and application on the secondary (replica/slave) database. In other words, it’s a measure of how far behind the replica server is compared to the master server. This lag is typically expressed in seconds.

Database systems commonly use a master-replica architecture, where all write operations occur on the master, and these changes are then copied to the replicas. The replicas, in turn, handle read operations, alleviating the load on the master and ensuring high availability. However, any disruption or slowdown in this copying process can lead to replica servers not being in sync with the master’s data.

ℹ️ Replication Types and Their Relationship with Lag

Replication types directly affect the probability of lag:

  • Asynchronous Replication: The master does not wait for the replicas to acknowledge the commit of a change before considering it successful. This is the fastest replication type but carries the highest risk of lag and data loss. It’s often the default option.
  • Synchronous Replication: The master waits for at least one replica to acknowledge that it has durably stored the change before acknowledging the commit. This minimizes lag and enhances data consistency but can negatively impact write performance on the master.
  • Semi-synchronous Replication: The master waits for at least one replica to acknowledge receipt of the change (but not necessarily its application). This offers a balance between asynchronous and synchronous replication, providing a compromise between performance and consistency.

Replication lag can prevent an application from accessing accurate and up-to-date data, leading to a wide range of issues from user experience to business decisions. Therefore, understanding the causes of replication lag and managing it effectively is crucial.

Causes of Replication Lag

Replication lag is not typically attributed to a single cause but rather a combination of multiple factors. These factors can range from hardware constraints to database configuration, network issues, and application patterns.

Load Imbalance

High transaction volume on the master database can cause replicas to struggle to keep up. Particularly intensive write operations, long-running transactions, or large BATCH operations can lead to replicas falling behind.

  • High Write Load: When a continuous stream of numerous INSERT, UPDATE, or DELETE operations hits the master, replicas require a certain amount of time to apply these changes sequentially. If the replicas’ processing capacity is lower than the master’s write capacity, lag is inevitable.
  • Long-Running Transactions: A single, long-running transaction on the master can block the entire replication pipeline. Such transactions will take the same amount of time on the replicas, delaying the application of all other pending operations.
  • Read Load on Replicas: Replicas are typically used to distribute read load. However, if there’s very heavy read activity on a replica, this can slow down replication processes, increasing lag. The replica has to handle read queries while also applying changes from the master.

Hardware and Network Constraints

The physical or virtual hardware capabilities of database servers and the network infrastructure play a critical role in replication performance. Any bottleneck can lead to lag.

  • Replica I/O Bottleneck: If the replica’s speed in writing changes from the master to disk is insufficient (e.g., not using SSD/NVMe instead of slow HDDs), this creates an I/O bottleneck. Disk performance significantly impacts replication, especially in scenarios with many small transactions.
  • CPU Limitations: Insufficient CPU resources on both master and replica servers can prevent the database engine from processing operations quickly. If the replica doesn’t have enough CPU to apply changes from the master, lag will occur.
  • Network Latency and Bandwidth: The quality of the network connection between the master and replicas directly affects replication lag. High network latency or low bandwidth increases the time it takes for WAL (Write-Ahead Log) or binlog data to reach the replica, thus increasing lag. This is particularly pronounced in geographically distributed replication scenarios.

Database Configuration and Lack of Optimization

Improper configuration of the database engine or lack of optimization for replication can be a significant cause of lag.

  • Missing Indexes: If necessary indexes are missing on the replica to quickly apply UPDATE or DELETE operations from the master, the replica will slow down these operations. The absence of an index on a table that has one on the master can lead to replication lag.
  • Incorrect Buffer Pool/Cache Settings: Insufficient memory settings on the replica can increase disk I/O, degrading performance. For example, parameters like innodb_buffer_pool_size in MySQL or shared_buffers in PostgreSQL are critical.
  • binlog_format (MySQL) or WAL Settings (PostgreSQL): In MySQL, setting binlog_format to STATEMENT instead of ROW can cause replication issues in some scenarios. Incorrectly setting parameters like wal_level in PostgreSQL also affects performance.
  • fsync Settings: The fsync settings, which determine how frequently the database synchronizes disk writes, create a balance between performance and data safety. Too frequent fsync operations can increase replica I/O.

Software Errors and Bugs

Rarely, bugs in specific versions of database software or application-level errors can cause replication lag.

  • Database Version Bugs: Some database versions might have known bugs or performance issues in their replication mechanisms. Regular updates and patches are important to address such problems.
  • Application Errors: Errors within application code that create excessive load on the database, initiate unnecessary or very large transactions, can indirectly lead to replication lag by increasing the load on the master.

Long-Running Schema Changes

Schema changes like ALTER TABLE performed on the master must also be applied to the replicas. Such operations can take a long time on large tables, and replication may halt or slow down significantly during this period.

  • Online Schema Migration Tools: Tools like pt-online-schema-change (Percona Toolkit) or gh-ost can be used for zero-downtime schema changes. These tools help minimize replication lag by keeping the load on the master under control.

Each of these causes, individually or in combination, can push your database replication toward a potential disaster. Therefore, proactive monitoring and regular optimization are critical.

Impacts of the Invisible Disaster

As the name suggests, replication lag is often not immediately noticed, but its impacts can be devastating. This condition leads to a wide range of issues, from data consistency to application performance, and even business continuity.

Data Consistency Issues

The most apparent and dangerous impact is the breakdown of data consistency. When applications read outdated data from replicas, it can lead to incorrect decisions or the presentation of erroneous information to users.

  • Reading Stale Data: If a user performs an action on the master (e.g., placing an order) and immediately tries to read this data from a replica, replication lag might cause them to see old data. This severely impacts user experience and causes confusion.
  • Business Logic Errors: If business processes make decisions based on the real-time state of data (e.g., stock checks, balance inquiries), delayed data can lead to incorrect business decisions. This can result in financial losses or operational disruptions.
  • Reporting and Analytics Inaccuracies: Business intelligence (BI) or reporting tools often pull data from replicas. Replication lag causes these reports and analyses to be based on outdated data, leading to incorrect strategic decisions.

Application Errors and Incorrect Decisions

Application-level problems are a direct consequence of lag. Delayed data prevents the application from behaving as expected.

  • Errors in Application Code: Some applications expect data to be up-to-date immediately after a write operation. Replication lag can cause errors like “data not found” or “old data displayed” in these scenarios.
  • Degraded User Experience: In an e-commerce site, if a user cannot see their order immediately in their order history after adding items to the cart and completing the payment, it leads to a loss of trust and a poor user experience.

High Availability and Disaster Recovery Risks

Replication lag directly undermines the effectiveness of high availability (HA) and disaster recovery (DR) strategies.

  • Data Loss During Failover: When the master database crashes and a failover to a replica is necessary, if the replica is lagging, the last operations performed on the master will be lost. This can lead to unacceptable data loss for the business.
  • Violation of RPO (Recovery Point Objective): RPO defines the maximum amount of data that can be lost in a disaster. Replication lag causes RPO targets to be violated, as the recovered database might reflect a point in time much older than the master’s crash.
  • Extended Downtime: After failing over to a lagged replica, additional steps might be required to recover lost data or bring the replica up to date. This extends the time needed for the system to become fully operational (RTO – Recovery Time Objective).

⚠️ Unacceptable Data Loss

In failover scenarios, data lost due to replication lag can lead to irreversible financial and reputational damage for a business. Therefore, when defining failover strategies, the tolerance for replication lag must be understood and managed very well.

Performance Degradation

Replication lag not only affects data consistency but also the overall system performance.

  • Slow Read Queries on Replicas: If a replica struggles to apply changes from the master, this degrades the replica’s overall performance. Read queries can become slow due to resource contention with replication processes.
  • Load Reverting to Master: When replicas cannot operate fast enough or are lagging, applications might be forced to revert to reading directly from the master. This increases the load on the master, further worsening overall system performance.

These impacts clearly demonstrate that replication lag is more than just a technical issue; it poses a serious business risk. Therefore, taking proactive steps to monitor, diagnose, and prevent lag is vital.

Monitoring and Diagnosing Replication Lag

The first step in managing replication lag is to monitor it accurately and diagnose its causes when lag occurs. An effective monitoring strategy allows you to detect potential issues at an early stage.

Metrics

Various database systems offer different metrics to measure replication lag. Regularly tracking these metrics is critical for understanding when and how much lag is occurring.

  • MySQL: Seconds_Behind_Master: This metric, obtained via the SHOW SLAVE STATUS command, indicates how many seconds the replica is behind the master. This is the most commonly used and direct indicator of lag.
  • PostgreSQL: WAL Delta: While PostgreSQL doesn’t have a direct metric like Seconds_Behind_Master, we can measure lag by monitoring the difference between the master’s latest WAL (Write-Ahead Log) position and the replica’s latest applied WAL position. This difference can be calculated using functions like pg_current_wal_lsn() (master) and pg_last_wal_replay_lsn() (replica).
  • I/O, CPU, Network Usage: Monitoring system metrics such as disk I/O, CPU usage, and network bandwidth of both master and replica servers is essential for identifying bottlenecks. Particularly high I/O wait times or CPU utilization on the replica can be a sign of lag.
  • Transaction Rates: Comparing the transaction rate on the master with the transaction rate applied by the replica shows whether the replica can keep up with the master.

Tools

A variety of built-in and third-party tools are available for monitoring lag and diagnosing issues.

  • Built-in Database Commands:
    • MySQL: The SHOW SLAVE STATUSG command provides detailed information about the replica, including Seconds_Behind_Master.
    • PostgreSQL: SELECT pg_wal_lsn_diff(pg_current_wal_lsn(), pg_last_wal_replay_lsn()); gives the WAL difference on the master. On the replica, you can see the replay lag with SELECT now() - pg_last_xact_replay_timestamp();. The pg_stat_replication view also details replica status.
  • Monitoring Systems: General monitoring tools like Prometheus, Grafana, Datadog, and Zabbix are ideal for collecting, visualizing, and alerting on database metrics. These systems allow for tracking lag metrics over time and sending automatic alerts when specific thresholds are exceeded.
  • Third-Party Tools: Percona Toolkit offers tools like pt-heartbeat for MySQL. This tool measures lag more precisely by sending a synthetic heartbeat operation between the master and replica, accounting for network latency as well.

💡 Proactive Monitoring and Alerts

Proactively monitoring replication lag is key to preventing a potential disaster. Ensure your monitoring system is configured to send automatic alerts when metrics like Seconds_Behind_Master or their equivalents exceed a certain threshold (e.g., 5 seconds or 30 seconds). This allows you to intervene quickly when a problem arises.

MySQL Replication Status Check:

SHOW SLAVE STATUSG

In the output of this command, the Seconds_Behind_Master field specifically indicates the lag. The Slave_IO_Running and Slave_SQL_Running fields are also important for checking if the replication processes are active.

PostgreSQL WAL Replay Lag Check:

You can see the lag in bytes by calculating the difference between the master’s latest WAL LSN (Log Sequence Number) and the replica’s latest replayed WAL LSN:

-- On the Master
SELECT pg_current_wal_lsn();

-- On the Replica
SELECT pg_last_wal_replay_lsn();

-- To calculate the difference (e.g., if the value from master is '0/16B0790' and from replica is '0/16B0780')
SELECT pg_wal_lsn_diff('0/16B0790', '0/16B0780'); -- Result: 16 bytes lag

For a simpler time-based lag on the replica:

SELECT now() - pg_last_xact_replay_timestamp() AS replication_delay;

By using these tools and metrics, you can gain a comprehensive view of your replication status and quickly identify the root cause of any lag.

Strategies to Reduce and Prevent Replication Lag

Managing replication lag is a multifaceted effort that requires proactive measures and continuous optimization. Here are strategies that can be implemented to reduce and prevent lag:

Hardware and Infrastructure Improvements

The underlying infrastructure forms the foundation of replication performance. Having adequate resources can prevent many lag issues before they start.

  • Faster Disks (SSD/NVMe): Especially on replicas, using high-performance storage devices (SSD or NVMe) is critical for quickly writing and applying changes from the master to disk. Slow disks cause I/O bottlenecks, increasing replication lag.
  • More CPU/RAM: Ensure both master and replica servers have sufficient CPU and RAM resources. The replica needs adequate processing power to handle and apply incoming WAL/binlog data. Memory settings like innodb_buffer_pool_size in MySQL or shared_buffers in PostgreSQL can improve performance by reducing disk I/O.
  • Network Infrastructure Optimization: Ensure the network connection between the master and replicas has low latency and high bandwidth. For geographically distant replicas, WAN optimization techniques or faster connection options should be considered. Network packet loss or congestion can delay the transmission of replication data.

Database Optimizations

Database configuration and operations directly impact replication efficiency.

  • Appropriate Indexing: Ensure all necessary indexes are present on replicas to quickly apply UPDATE and DELETE operations from the master. The absence of an index on a replica for a column that has one on the master can cause significant lag.
  • Database Parameter Tuning:
    • MySQL: innodb_flush_log_at_trx_commit=1 (ideal for data safety but increases I/O load; can be set to 0 or 2 depending on lag tolerance), sync_binlog=1 (similar I/O load), slave_parallel_workers (for parallel replication with MySQL 5.6+).
    • PostgreSQL: wal_level (replica/logical), max_wal_senders, wal_writer_delay, synchronous_commit (setting to off can reduce lag but carries a risk of data loss).
  • Splitting Large Operations (Batching): Breaking down very large INSERT/UPDATE operations into smaller batches can prevent long-running blockages in the replication pipeline.
  • Avoiding Long-Running, Blocking Operations: Minimize operations like LOCK TABLE or ALTER TABLE on the master. If possible, perform such operations during off-peak hours or use online schema migration tools.

Application Architecture Changes

Changes at the application layer can mitigate the effects of replication lag.

  • Read-After-Write Consistency: In scenarios where a user needs to read data immediately after writing it, strategies like directing this read operation directly to the master (e.g., for a specific duration or per user session) or caching the written data can be employed.
  • Event-Driven Architecture and Eventual Consistency: If your application can tolerate an eventual consistency model, replication lag becomes less problematic. This model assumes that data will eventually become consistent. This can be beneficial, especially in microservices architectures or high-throughput systems.
  • Sharding or Horizontal Scaling: Sharding the database into smaller, manageable pieces (shards) reduces the load on each shard, thereby decreasing the risk of replication lag.

Replication Topology Choice

The right replication topology and type can help you manage lag risk according to your needs.

  • Semi-synchronous or Synchronous Replication: To minimize data loss and prevent lag, consider using semi-synchronous or synchronous replication, even if it means sacrificing some performance on the master. This is particularly important for financial or critical data.
  • Cascading Replication: If you have many replicas, you can reduce the load on the master by replicating from an intermediate replica to others, rather than directly from the master to all replicas.

Automatic Failover and Alerts

When replication lag exceeds a certain threshold—for example, lasts longer than 30 seconds—an automatic fallback mechanism that temporarily redirects read traffic to the master can eliminate the risk of showing inconsistent data to users. Additionally, Prometheus/Grafana threshold alerts provide an early signal to the operations team before lag increases permanently.

Conclusion

Replication lag is a silently operating disaster; deploying it to production without collecting metrics, setting up threshold alerts, and defining read fallback strategies on the application side is risky. The methods outlined above make lag both measurable and manageable.

How artificial intelligence is changing the way developers, freshers, and experienced professionals prepare for technical interviews

How artificial intelligence is changing the way developers, freshers, and experienced professionals prepare for technical interviews — and why it matters.

Let me paint a picture you’ve probably lived.

You have an interview in three days. You open YouTube, watch a two-hour system design video, take notes, feel confident. You read through fifty common Java interview questions on some random blog. You memorize the answers. You practice saying them out loud in the mirror.

Interview day arrives. The interviewer asks something slightly different. You freeze. The words you memorized don’t fit. The pressure feels nothing like your bedroom. You walk out thinking — why didn’t my preparation feel like this?

Because it wasn’t designed to.

The Problem With How We’ve Always Prepped
The traditional interview prep industry was built around one format: passive consumption.

Watch a video. Read a list. Memorize an answer. Repeat.

It’s the equivalent of training for a marathon by reading a book about running. The theory might be right. But the muscle memory isn’t there. The pressure isn’t there. The real-time thinking under stress — the thing interviews actually test — is completely absent.

And yet for decades, this was the only option available.

Flashcard apps. Question banks. Mock interview services that cost thousands of rupees per hour with a human coach. YouTube playlists that are outdated the moment they’re uploaded. None of these tools put you in the actual experience of being interviewed.

The result? Candidates who know the answers on paper but fall apart in the room.

What AI Changes
Here’s what’s different now.

AI doesn’t just give you questions to read. It actually interviews you.

It asks you a question — out loud, in real time. It waits for your answer. It gives you feedback on what you got right, what you missed, and what a stronger answer would have looked like. Then it asks the next question, adapted to who you are, what role you’re targeting, and how experienced you are.

That’s not a quiz. That’s practice.

The difference is the same as the difference between reading about swimming and getting in the water.

When AI adapts to your experience level, something powerful happens. A fresher preparing for their first campus interview doesn’t need to face questions about distributed systems and microservices at scale. They need fundamentals, conceptual clarity, and simple scenario questions that build confidence. An experienced backend engineer with seven years of production experience doesn’t need “what is a REST API” — they need tradeoff discussions, system design pressure, and behavioral depth.

Real human interviewers have always made this distinction instinctively. Now AI can too.

The Role-Specific Shift
One of the biggest failures of generic interview prep is that it treats every candidate the same.
A React developer and a DevOps engineer get the same “top 50 interview questions” article. A data scientist and a product manager get the same behavioral prep advice. But these roles require completely different thinking, different vocabulary, different depth of knowledge.

AI-powered interview platforms are beginning to close this gap in a way that wasn’t possible before. When your interview is tailored to your specific role — Java developer, Python developer, cloud engineer, QA automation engineer — the questions stop feeling generic. They start feeling real. Because they are.

And when those questions are also personalized to your resume — your actual projects, your tech stack, your tools — the experience becomes something that generic prep simply cannot replicate.

Feedback That Actually Teaches
Here’s where AI changes the game in a way even expensive human coaching struggles to match: instant, specific, consistent feedback.

When you answer a question in a traditional mock interview, feedback depends entirely on who’s on the other side. Some coaches are generous. Some are harsh. Some focus on communication, some on technical accuracy, some on structure. The calibration is inconsistent.

AI feedback doesn’t have a bad day. It doesn’t run out of patience. It doesn’t give you a 9 out of 10 because it doesn’t want to discourage you.

If you answered in the wrong direction, it tells you. If you got the concept right but missed a key detail, it points to exactly what that detail is. If your answer was strong, it tells you why — specifically, not generically.

That specificity is what makes feedback useful. Vague encouragement doesn’t make you better. Precise, honest calibration does.

The Confidence Problem Nobody Talks About
There’s a dimension of interview performance that no question bank can prepare you for: the feeling of being in an interview.

The slightly elevated heart rate. The pressure of someone waiting for your answer. The moment you realize you’re not sure and have to think out loud anyway.

Repeated AI-powered practice builds something that passive prep never can — familiarity with that feeling. The more times you sit in a simulated interview and navigate that pressure, the less it controls you in the real one.

This is why athletes practice under simulated pressure. Why pilots use flight simulators before flying real planes. The principle is the same. Exposure to the experience, even a simulated one, rewires how your brain responds to it.

This Is Still Early
AI-powered interview prep is not perfect. The technology is improving fast, but it doesn’t yet fully replicate the nuance of a highly experienced human interviewer reading your body language, picking up on your hesitation, or going deeper based on a subtle cue in your answer.

But here’s the thing — neither does most traditional prep. And AI is available at midnight when your interview is tomorrow morning. It doesn’t charge by the hour. It doesn’t have a limited roster of coaches.

The floor has been raised dramatically. And for the vast majority of candidates who never had access to quality, realistic interview practice, AI is not just an improvement — it’s a transformation.

What This Means For You
If you’re preparing for a technical interview right now, the smartest thing you can do is stop consuming and start practicing.

Don’t just watch someone else get interviewed. Get interviewed yourself — by an AI that knows your role, your experience level, and your resume. Get the feedback. Do it again. And again.

The candidates who crack interviews at top companies aren’t the ones who memorized the most answers. They’re the ones who’ve sat in enough interview seats — real or simulated — that they know how to think under pressure.

AI just made that kind of preparation accessible to everyone.

AssessArc is an voice based AI-powered mock interview platform built for freshers and experienced professionals across more than 32 roles. Try it at assessarc.com.