
 Mert
Trash Compactor
Part 1
Oh what fun! And a preview of Part 2?
This feels like an altogether new challenge. That is, the main part of separating each set of numbers and performing the math.
I also notice that in both the example input and my puzzle input the text alignment of vertical lists differ: some are left-justified, others are right-justified, and some contain numbers that are each the same length.
I have a hunch that Part 2 will require programmatically determining each justification…possibly in order to determine a subset of equations.
Until then, it’s time to talk through how I intend to solve Part 1.
Going from four lines to nested arrays
In my head, I want to go from this text string…
123 328  51 64
 45 64  387 23
  6 98  215 314
*   +   *   +
To this data structure:
[
    [[123, 45, 6], '*'],
    [[328, 64, 98], '+'],
    [[51, 387, 215], '*'],
    [[64, 23, 314], '+']
]
Taking this one step at a time…
I can split the string at each newline character:
let input = input.split('n')
That gets me a list with four strings. The last one is of the operators. They are all a single character, which should make it easy to isolate them:
let operators = input[input.length - 1].replaceAll(' ', '').split('')
I chose to remove all white space and make a list of each character.
As for the other lines, each number and the amount of space between numbers varies.
I want to use a regular expression in a split() to break up the string into a list of numbers with whitespace removed.
I suppose I could also:
-
split()at each character -
filter()out all space characters
That seems like a fine solution:
input = input.slice(0, -1).map(line => line.split('').filter(i => i !== ' '))
Does it work?
Sure doesn’t. Why not?
Because it chops each number up into digits.
Silly me.
New strategy: use regex.
I’ll extract each number from the string using a regular expression:
input = input.slice(0, -1).map(line => [...line.matchAll(/d+/g)].map(el => +el[0]))
It works! I have three lists, each with the numbers in a line.
Now I need to put the numbers in the same index but different lists together.
I’ll use a good-‘ol-fashioned nested for loop:
let equations = []
for (let i = 0; i < input[0].length; i++) {
    let eq = []
    for (let j = 0; j < input.length; j++) {
        eq.push(input[j][i])
    }
    equations.push([eq, operators[i]])
}
What this should do is:
- Create an empty array
- Iterate as many times as there are numbers in a line (the same for each line)
- Create an empty array
- Iterate as many times as there are lines – minus the last line which has been removed by now
- Add the number at the current index to the empty array
- Finally, add the empty array and the corresponding operator as a 2-item list to the other empty array
Does this work?
It does!
[
  [ [ 123, 45, 6 ], '*' ],
  [ [ 328, 64, 98 ], '+' ],
  [ [ 51, 387, 215 ], '*' ],
  [ [ 64, 23, 314 ], '+' ]
]
Woohoo!
Next up: Math!
Processing each equation and testing
I intend to use a reduce() and eval():
- The former as a convenient syntax to arrive at a single number
- The latter as a convenient method of performing math without having to map each string character to its programmatic operator
After a bit of debugging, my working algorithm looks like this:
let part1 = equations.reduce((answer, eq) => {
    return answer += eq[0].reduce((total, num) => {
        return eval(`${total} ${eq[1]} ${num}`)
    })
}, 0)
It generates the correct answer when runnning the example input.
Will it do the same when running my input?
…
It will! It did!
Woohoo!!
I’m glad Part 1 didn’t have any hidden tricks in the input.
Now, will Part 2 make use of the varying text alignment of each equation?
I can’t wait to find out.
Part 2
I knew it! Also, I had no clue.
I was right about the text alignment coming into play!
And yet the way it comes into play goes beyond what I imagined…
…into much cooler challenge territory.
This is gonna be a blast to solve…I hope.
Finding a new strategy for processing each column
The convenient thing is the operators are still in the last line.
The only difference is I’ll need to process them in reverse chronological order.
I think I can carry forward my code that extracted the last line of input:
input = input.split('n')
let operators = input[input.length - 1].replaceAll(' ', '').split('').reverse()
Visually, that statement should go like this:
input[input.length - 1]
*   +   *   +

.replaceAll(' ', '')
*+*+

.split('')
['*','+','*','+']

.reverse()
['+','*','+','*']
Now that the operators are removed, my input string looks like this:
123 328  51 64
 45 64  387 23
  6 98  215 314
I need to programmatically perform the equivalent of a 90-degree counterclockwise turn to get the numbers properly oriented, like this:
  4
431
623

175
581
 32

8
248
369

356
24
1
I plan to write another nested for loop to iterate backwards through the same index of each line and build a new array of numbers.
First, I need to walk through an example to understand how I will access each index.
To get the first number, 4, I need to access these indices:
input[0][input[0].length - 1]
input[1][input[1].length - 1]
input[2][input[2].length - 1]
I should be able to refer to my local loop variables instead of re-typing input[N].length - 1.
Now for the algorithm:
let equations = []
for (let i = input[0].length - 1; i >= 0; i--) {
    let eq = []
    for (let j = 0; j < input.length; j++) {
        eq.push(input[j][i])
    }
}
When I run it wth a logging statement, I see what I expected:
[ ' ', ' ', '4' ]
[ '4', '3', '1' ]
[ '6', '2', '3' ]
[ ' ', ' ', ' ' ]
// ...and so on
Next, I need to convert each list of strings into either a number or an indicator to start a new set of numbers.
So, in the case of the above output, turn those four list of strings into:
[ [4, 431, 623], ... ]
I’m confident I can concatenate the strings and convert to a number.
Except for the list of all space characters, as that may not be a number.
So I will need a condition to handle that case.
Here’s my algorithm:
let equations = [[]]
for (let i = input[0].length - 1; i >= 0; i--) {
    let eq = []
    for (let j = 0; j < input.length; j++) {
        eq.push(input[j][i])
    }
    let num = +eq.join('').trim()
    if (num == 0) {
        equations.push([])
    } else {
        equations[equations.length - 1].push(num)
    }
}
- I added a nested empty list to
equations - The second half of the nested
forloop is new -
numis the list of strings joined, with white space removed, then coerced to a number - The condition adds a new nested list when it sees a
0 - Otherwise it inserts the number at the end of the last list
Thankfully, I see the expected result:
[ [ 4, 431, 623 ], [ 175, 581, 32 ], [ 8, 248, 369 ], [ 356, 24, 1 ] ]
Now I need to reduce each sub-list by applying the correct operator to each, just like in Part 1.
That code with some minor tweaks to work with my updated data structure looks like:
let part2 = equations.reduce((answer, eq, idx) => {
    return answer += eq.reduce((total, num) => {
        return eval(`${total} ${operators[idx]} ${num}`)
    })
}, 0)
I think that’s it, since, when I run it, I see the expected answer for the example input!
But will it generate the correct answer for my puzzle input?
…
It does!
Woohoo!!!
That was such a fun 2-part challenge!
I just knew the varyied text alignment would come into play.
x64 Windows Assembly Fundamentals Part 1: What You Actually Need to Know
Hello everyone. Mirrai here as always. Today I decided to expand a bit more on low-level fundamentals. If you’ve spent any time in a debugger or reading shellcode you’ve probably stared at assembly and had no idea what was going on. That’s why I made this guide to demystify assembly. We’ll cover binary, registers, the Windows x64 calling convention, and how RSP and RIP actually work. By the end you’ll be able to read what a debugger is showing you and understand why things are where they are. With that out of the way lets begin with binary. Basic C knowledge will definitely help to understand assembly. I recommend you at least know how functions work in C or programming in general. With that, let’s start.
Binary and data storage
Everything your computer does comes down to binary. Text, pictures, videos, everything, all ones and zeros. A bit can store two values: 0 and 1. Two bits can store 4 values 0, 1, 2, 3 etc. Each bit doubles capacity. Eight bits make up a byte.
0000 0000 = 0
0000 0001 = 1
0000 0010 = 2
0000 0011 = 3
1111 1111 = 255
Now when we talk about a 64 bit register it means that register can store a value up the amount that 64 bits or 8 bytes can hold. For 64 the limit is (18,446,744,073,709,551,615). For 32 bit it’s (4,294,967,295). For 16 bits it’s (65,535). For 8 bits it’s (255). To clarify. While those are their max values they can represent numbers of those values +1. For example, 8 bits can hold 0-255 which is 256 max value but it can’t store the number 256.
You’ll rarely work with raw binary in practice. Hexadecimal is more common because it’s a cleaner representation of binary data. One hex digit represents exactly four bits.
0000 = 0x0
0001 = 0x1
1010 = 0xA
1111 = 0xF
1111 1111 = 0xFF = 255
In x64dbg and most debuggers memory is displayed in hex. When you see 41 in memory that’s 0x41 which is 65 in decimal which is the letter “A” in ASCII.
Registers
Registers are storage locations inside the CPU itself. They’re faster than RAM because they’re on the chip. On x64 the general purpose registers are:
RAX  RBX  RCX  RDX
RSI  RDI  RSP  RBP
R8   R9   R10  R11
R12  R13  R14  R15
Each holds 64 bits (8 bytes). You can also access the lower bits of the first eight registers.
RAX(64 bits)  →  EAX (lower 32 bits)  →  AX (lower 16)  →  AL (lower 8)
RBX  →  EBX  →  BX  →  BL
RCX  →  ECX  →  CX  →  CL
RDX  →  EDX  →  DX  →  DL`
You see ECX and lower registers even in x64 (also x86-64). This is because x64 is an extension of x86.
Now I want you to focus on these two registers.
RSP: the stack pointer. Always points to the top of the current stack. It grows down and fills upward. When we do sub rsp, 40 a bit later we are adding more space to the stack or in the specific example we are reserving shadow space and alignment (More on that later). Likewise add rsp, 40 will remove that space. RSP also changes when data is pushed (RSP is subtracted by 8, then the data is stored at the new top). and popped (loads the data from the top into a register, then adds 8 to RSP, effectively removing it)
RIP: the instruction pointer. Holds the address of the next instruction the CPU will execute. You can’t write to RIP directly in normal code but controlling it is the goal of most exploitation techniques. Wherever RIP points execution follows.
The Windows x64 Calling Convention
When a function is called in Windows x64, there are strict rules about how arguments are passed and how the stack is set up. This is called the calling convention and if you’re reading compiled code or writing shellcode you need to know it.
Integer and pointer arguments go in registers in this order:
1st argument → RCX
2nd argument → RDX
3rd argument → R8
4th argument → R9
5th and beyond → pushed onto the stack
Return values are then stored in RAX after the function ends. So if you see something like:
mov rcx, rax          ; first argument
mov rdx, 0            ; second argument
call SomeFunction
This code passes two arguments and calls the function. The result will be in RAX afterward.
Shadow space is the part that trips people up (Me included). Before any call the caller must allocate at least 32 bytes (0x20) on the stack even if the function takes fewer than four arguments. This is called the shadow space and it exists so the called function has somewhere to spill its register arguments if it needs to. We also allocate 8 bytes to align the stack because the winapi functions need the stack to be 16 byte aligned or the program crashes. BTW if you make your own functions you don’t have to follow these conventions but it’s wise to do so if you plan to use the winapi in anyway.
Let me give you a more practical example. A program that prints “Hello World” on a messagebox.
BITS 64
default rel
global main
extern ExitProcess
extern MessageBoxA


%define uType 1         ; MB_OKCANCEL

section .data
text_1  db "Hello World", 0
text_2  db "Hello from mirral", 0


section .text
main:
    sub rsp, 40                      ; shadow space + 8 byte alignment

    xor rcx, rcx                     ; hWnd
    lea rdx, text_1                  ; lpText
    lea r8, text_2                   ; lpCaption
    mov r9, uType                    ; uType
    call MessageBoxA

    xor rcx, rcx
    call ExitProcess
I’ll Explain basic assembly syntax like mov, lea, xor in my next post but for now I want you to look at the bigger picture.
If you wanna compile it:
nasm -f win64 "hello_world.nasm" -o "hello_world.obj"
gcc "hello_world.obj" -o "hello_world.exe" -lkernel32 -luser32 -mwindows -s -nostartfiles -nostdlib
This is the messagebox function definition from MSDN:
int MessageBoxA(
  [in, optional] HWND   hWnd,
  [in, optional] LPCSTR lpText,
  [in, optional] LPCSTR lpCaption,
  [in]           UINT   uType
);
You see how it maps to the asm code? The asm is zeroing out RCX, loading the pointer of the text_1 and text_2 to rdx and r8 respectively and moving the Utype value to r9 then calls MessageboxA Then RCX is zeroed and ExitProcess is called which just exits the process (duh). This is what C does under the hood.
Putting it Together
Open x64dbg or your debugger of choice and load any executable, step through with it and watch the registers panel. Every time you step over a call notice which registers change. Watch RSP decrease when something is pushed and increase when something is popped. Watch RIP change with every instruction.
Reading assembly gets easier fast once you can see it happening in real time. The concepts aren’t difficult but you might need a while to internalise them. Don’t give up though. Despite how it looks persistence is key to understanding assembly.
If you haven’t read the buffer overflow series this is a good foundation for it. Part 1 covers the stack in more depth and Part 2 puts all of this to practical use. For part 2 I’ll explain assembly syntax like mov, lea etc. Till then see ya. Also leave a comment if you have questions.
Ukrayna: İlk güdümlü bombamız muharebe kullanımına hazır
Gazze'deki Sağlık Bakanlığı tıbbi görüntüleme cihazları için acil çağrı yaptı
Gemini uygulamasına “daha uzun” düşünme modu geliyor
 Google’ın yapay zeka uygulaması Gemini, yeni özelliklere kavuşuyor. Aktarılanlara göre Google, Gemini’a daha fazla düşünme modu ekliyor ve ayrıca üçüncü taraf entegrasyonlarını artırıyor.
Elektrikli BMW 1 Serisi geliyor: Neue Klasse ile köklü değişim
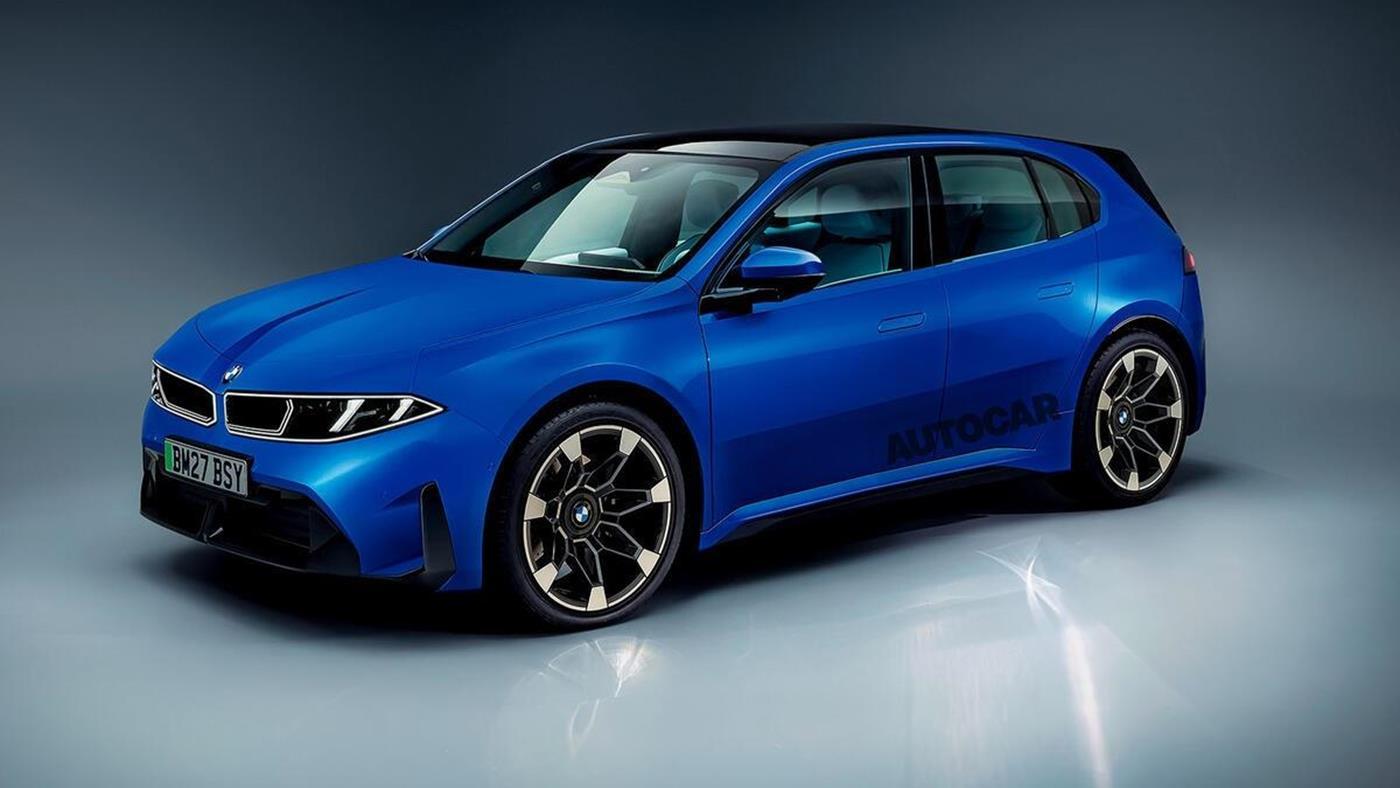
 BMW, kompakt hatchback modeli 1 Serisini yenilemeye hazırlanıyor. İçten yanmalı ve elektrikli versiyonlarla gelecek olan yeni model önemli dönüşüm geçirecek.
Çin, kömür santrali emisyonlarını gübreye dönüştürüyor
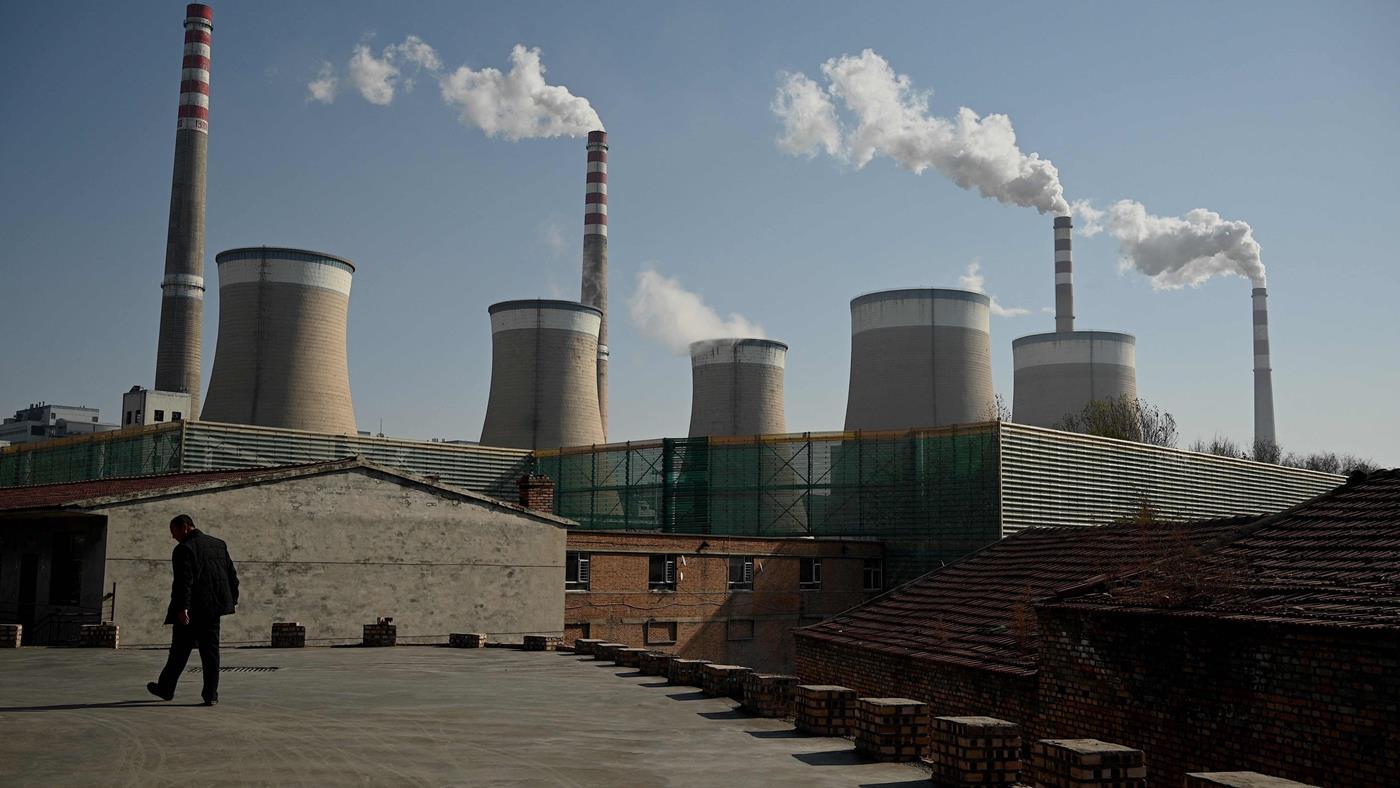
 Çin’de geliştirilen yeni sistem, kömür santrallerinden çıkan karbon emisyonlarını gübreye dönüştürüyor. Teknoloji hem CO2 salımını azaltıyor hem de tarımsal üretimde maliyet avantajı sunuyor.
PasteAI: One MCP Tool Call, One Shareable Link


Have you ever asked Claude to write up an analysis, then had no good place to put it?
I asked Claude to pull together a summary from a long Slack thread on a production incident. It wrote up the timeline, root cause, and action items in about thirty seconds. But it was sitting in a chat window, and sharing it meant copying the markdown somewhere else and hoping the formatting survived.
That is what prompted me to build PasteAI.
The Problem
When Claude produces something useful, the output lives in a chat window. If I want to share it, I am choosing between losing the formatting in a paste box, making the reader sign in somewhere, or screenshotting it and throwing away the text. None of those are right for a document that took thirty seconds to generate and five minutes to find a home for.
What I actually want is simple: Claude publishes a document, I get a link, and the link just works. No login for the reader, no third-party service, no reformatting.
What PasteAI Does
Think of it as a pastebin, but with properly rendered documents. Claude calls a tool, and the result is a clean URL with syntax highlighting and a readable layout, not raw markdown in a paste box.

Claude has two tools: publish_document, which takes a title and markdown content and returns a URL; and list_documents, which returns recent public documents.
The URL opens a rendered document with a themed UI and dark mode. The theme is saved in localStorage.
Documents are stored as plain markdown files in ~/.pasteai/documents/, with a metadata index at ~/.pasteai/documents.db. The content stays as plain files so you can grep them, back them up, or open them in any editor without the server running.
PasteAI is built for local use first, which makes it practical for solo developers and small teams without any infrastructure overhead.
Scripts and external tools can push documents without Claude via the REST API; protect writes with an API key.
Getting Started
The quickest way to install is:
curl -sSL https://raw.githubusercontent.com/pasteai/pasteai/main/install.sh | sh
This sets up the binary and configures Claude Code automatically. PasteAI is also available via Homebrew, Scoop, and on the releases page as .deb, .rpm, and Windows packages.
Run pasteai setup if you need to reconfigure, or pasteai doctor to check that everything is connected.
Three Modes
PasteAI can run in three modes depending on how you want to use it.
By default, when Claude Code launches the MCP server, PasteAI also starts an HTTP server inside the same process. No separate setup needed. This is embedded mode, and it is what I use day to day. The server runs while Claude Code is open and stops when you close it.
For a persistent server, run pasteai serve directly or via Docker Compose and point the MCP client at it with PASTEAI_URL. For sharing across devices or teams, deploy with -base-url and use Tailscale for private access.
The code is at github.com/pasteai/pasteai, MIT licensed. PRs are welcome.
If you are spending time finding a home for AI output that should take seconds to share, this might help.
How are you currently handling Claude’s output when you need to share it, what does your workflow look like?
Your Guide to Vibe Coding with a Local LLM
No API costs. No rate limits. No privacy concerns. Just you, your machine, and a model that thinks at the speed of flow. A complete setup guide for local AI-powered coding.
No API costs. No rate limits. No privacy concerns. Just you, your machine, and a model that thinks at the speed of flow.
The Problem with Cloud AI for Coding
You’re deep in a coding session. You’re in the zone. Then your AI assistant hits a rate limit, lags for 4 seconds, or you suddenly remember you just pasted a proprietary database schema into a third-party API.
Cloud-based LLMs are incredible — but for vibe coding, that fluid, almost meditative state of rapid prototyping and iterative thinking, they’re not always the right tool. Latency breaks flow. Rate limits kill momentum. Privacy is a legitimate concern for professional codebases.
The solution? Run the model locally. This guide sets up your machine as a fully self-contained AI coding environment, for free, forever.
01 — Choosing Your Runner: Why Ollama Wins
Your “runner” is the software that loads model weights and serves them via a local API. The three main contenders are Ollama, LM Studio, and llama.cpp.
| Runner | Best for | Tradeoff |
|---|---|---|
| Ollama | Integration, automation, IDE plugins | Minimal GUI |
| LM Studio | Discovering and testing models visually | Heavier, less scriptable |
| llama.cpp | Maximum performance tuning | Requires more configuration |
For vibe coding, Ollama wins. It exposes an OpenAI-compatible API at localhost:11434, which means every IDE plugin and chat UI that supports OpenAI can point straight at your local model — zero code changes required. It installs in one command and runs silently in the background.
02 — The Brain: Best Open-Weights Coding Models
Model choice depends on your hardware. Here’s the current state-of-the-art landscape for coding:
| Model | Size | Best for | Min VRAM | Speed |
|---|---|---|---|---|
| Qwen2.5-Coder | 7B | Autocomplete, quick edits | 8GB | ⚡ Fast |
| DeepSeek-Coder-V2 | 16B | Architecture, debugging | 12GB | ⚖️ Balanced |
| Qwen2.5-Coder | 32B | Complex reasoning, refactoring | 24GB | 🧠 Deep |
For most developers on 16–32GB unified memory (Apple Silicon) or a mid-range NVIDIA GPU, DeepSeek-Coder-V2 16B hits the sweet spot — fast enough for conversational flow, smart enough for non-trivial problems.
💡 Apple Silicon tip: Unified memory is a superpower here. A MacBook Pro M3 Max with 64GB can run a 32B model entirely in memory with impressive throughput. No discrete GPU needed.
03 — The Interface: Your Vibe Coding Cockpit
The model running in the background is just the engine. You need a cockpit. Here are the three layers:
Continue.dev (VS Code / JetBrains)
The best open-source AI coding assistant for local LLMs. Inline autocomplete, a chat sidebar, slash commands, and full Ollama support out of the box. This is your primary coding interface.
Open WebUI
A self-hosted, ChatGPT-like web interface that connects to Ollama. Perfect for longer architecture brainstorming sessions, explaining complex problems, or rubber-ducking system design — without leaving your local environment.
Aider (CLI)
A terminal-based AI pair programmer that edits your actual files and is commit-aware. Exceptional for bulk refactoring, large-scale changes across multiple files, and keeping a clean git history of AI-assisted edits.
Recommended combo: Ollama in the background → Continue.dev in VS Code for in-editor flow → Open WebUI in a browser tab for architecture chats.
04 — Step-by-Step Setup Checklist
Step 1 — Install Ollama
Visit ollama.com or run:
# macOS / Linux
curl -fsSL https://ollama.com/install.sh | sh

# Windows: download the installer from ollama.com
Ollama runs as a background service on port 11434.
Step 2 — Pull your first model
# Fast and lightweight (good starting point)
ollama pull qwen2.5-coder:7b

# Balanced power and speed (recommended for most setups)
ollama pull deepseek-coder-v2:16b

# Maximum capability (requires 24GB+ VRAM or unified memory)
ollama pull qwen2.5-coder:32b
Step 3 — Test the model
ollama run qwen2.5-coder:7b
# Type a prompt. If you get a response, your runner is working.
Step 4 — Install Continue.dev in VS Code
Open VS Code → Extensions (Cmd+Shift+X) → search “Continue” → Install.
Continue will auto-detect your running Ollama instance.
Step 5 — Configure Continue
Open ~/.continue/config.json and add your model:
{
  "models": [
    {
      "title": "DeepSeek Coder",
      "provider": "ollama",
      "model": "deepseek-coder-v2:16b",
      "apiBase": "http://localhost:11434"
    }
  ],
  "tabAutocompleteModel": {
    "title": "Qwen2.5 Coder 7B",
    "provider": "ollama",
    "model": "qwen2.5-coder:7b",
    "apiBase": "http://localhost:11434"
  }
}
Restart VS Code and hit Cmd+L (Mac) / Ctrl+L (Windows/Linux) to open the chat.
Step 6 — Install Open WebUI (optional, requires Docker)
docker run -d
  -p 3000:8080
  --add-host=host.docker.internal:host-gateway
  ghcr.io/open-webui/open-webui:main
Visit http://localhost:3000 and connect it to your Ollama instance.
Step 7 — Tune for speed
# Maximize GPU offloading (set in your shell profile)
export OLLAMA_NUM_GPU_LAYERS=-1

# Enable flash attention for faster inference (supported hardware)
export OLLAMA_FLASH_ATTENTION=1
On Apple Silicon, GPU offloading is automatic — no configuration needed.
Step 8 — Start vibe coding
Open a project in VS Code. Hit Cmd+L to open Continue. Ask it anything about your codebase. Feel the flow.
05 — Pro Tips for Maximum Performance
Use quantized models. A Q4_K_M quantized 14B model often runs faster than a Q8 7B model with comparable quality. You can specify the quantization level explicitly:
ollama pull qwen2.5-coder:14b-instruct-q4_K_M
Keep context windows tight. Shorter context = faster generation. In Continue, set "contextLength": 8192 unless you genuinely need more. Feeding 128K tokens to every autocomplete request will kill your latency.
Use a dedicated model per task. A small 3B model for tab-completion, a 16B model for chat. Continue supports multiple model configs and you can switch with a keyboard shortcut — this is one of its best features.
Pre-warm your model. On first load, models take a few seconds to initialize. Send a dummy request when your machine starts up to keep the model warm in memory.
The Vibe Is Yours to Own
Once this stack is running, you have a private, unlimited, cost-free AI coding environment that runs entirely on your hardware. No subscriptions. No outages. No one reading your code.
The future of AI-assisted development isn’t just in the cloud — it’s sitting on your desk, ready to go offline.