Porsche 911 Turbo S SADU Edition Tanıtıldı

Porsche, Orta Doğu’ya özel hazırladığı 911 Turbo S SADU Edition modelini resmi olarak tanıttı. Geleneksel Sadu dokuma sanatından ilham alan otomobil, özel tasarımı ve güçlü performansıyla dikkat çekiyor.

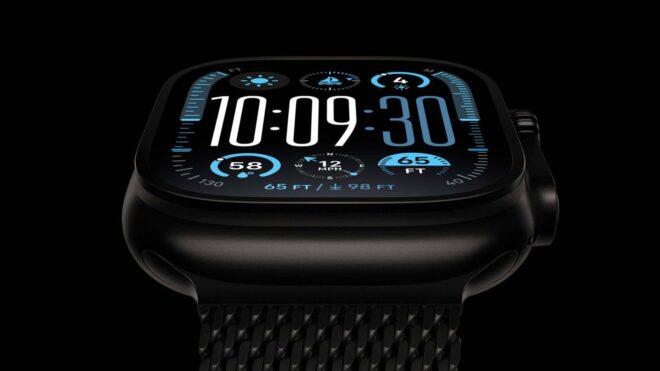
İddia: “Apple Watch Ultra 4, tamamen yeni bir tasarıma sahip olabilir”

İddia:

İddia: "Apple Watch Ultra 4, yeni bir tasarıma sahi olabilir"DigiTimes tarafından ortaya atılan iddiaya göre eylül ayında görücüye çıkarılacak Apple Watch Ultra 4, tamamen yeni bir tasarıma sahip olabilir. Watch Ultra’nın tasarımını çıkıştan bu yana değiştirmeyen Apple, yeni sürümde hatırı sayılır bir güncellemeye gidebilir. Teknoloji devinin eylül ayında Watch Ultra 4’e ek olarak Watch Series 12, iPhone 18 Pro, ‌iPhone 18 Pro‌ Max ve iPhone Ultra’yı da karşımıza çıkarması bekleniyor.

İddia: “Apple Watch Ultra 4, tamamen yeni bir tasarıma sahip olabilir” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Discovering Swift

A civilized programming language

Is Swift one of those so called “modern” languages trying to fix what C gave us for good? Or just something else? Well, for the ones who know me a bit, “modern” languages like Rust or Go are not really my friends. Swift, in other hands, is trying something that annoys me: mobile application development. Mobile applications are generarily using Java/Kotlin or C++. In some rare case, other languages, and sometime C. If you want to create your own application on both iOS and Android, the two main OS competitors, you should probably start to learn Java/Kotlin. Since its latest release though, Swift can now create applications for iOS and for Android…

A civilized programming language

For this first publication on Swift, I will publish only a list of resources. Indeed, after having tested it, this language currently does not fit all my requirements, and Dart/Flutter will be used instead. Anyway, it’s always a good thing to have a place to list some good references on the topic.

Books

Publications

Other

Cover Image by Pawel Czerwinski on Unsplash

The AI Coding Agent Workflow That Actually Works After 1,000 Hours

Linear flow from task spec → context loading → plan review → phase execution loop (execute → review → proceed or correct) → test run → diff review → commit

The first time I gave an AI agent real autonomy on a production codebase, it confidently refactored a utility method that happened to share a name with a method in a Feign client interface six modules away. The code compiled cleanly. My unit tests passed. Staging broke in a way that took two hours to trace because the JSON serialization behavior had subtly changed.

That was roughly hour 200. I’ve now crossed 1,000 hours of daily use across projects — Spring Boot microservices, a Flutter mobile app, Python data pipelines, some Go tooling. The workflow I use today is unrecognizable compared to what I started with, and most of what I thought I knew in those first few months was wrong.

The gap between “AI assistant that occasionally saves time” and “force multiplier that ships reliably” isn’t about which model you use or which IDE plugin you install. It’s almost entirely about how you structure the work before you hand it off.

I’m going to describe what actually works. Not the ideal case — the real case, including where it fails.

The task scoping problem nobody talks about

The most common mistake I see from developers new to agents is giving them goals instead of tasks. “Add authentication to this service” is a goal. An agent handed a goal will make dozens of implicit decisions: which library to use, where to put the filter, how to handle token expiry, whether to add a config property or hardcode something. Each decision is individually reasonable. Collectively, they often produce something that doesn’t fit your codebase at all.

The mental model shift that helped me most: treat the agent like an extremely fast junior developer who has read your entire codebase but has no knowledge of your team’s unwritten conventions. They’ll do exactly what you said, quickly, and be confused why you’re upset.

A well-scoped task has a specific file or class to modify, the exact behavior that needs to change (not the outcome you’re hoping for), explicit constraints (“don’t change the method signature”, “stay within this module”, “don’t add new dependencies”), and a clear definition of done you can verify yourself in under two minutes.

Instead of “add rate limiting to the user endpoints”, I write: “Add a rate limiting filter to UserController.java. Use Bucket4j — it’s already in the pom. Rate limit to 100 requests per minute per IP using the X-Forwarded-For header. Add a test in UserControllerTest that verifies a 429 is returned on the 101st request within a sliding window. Don’t touch any other controllers.” That’s a task. The first thing was a wish.

Loading context is not the same as prompting

Early on I treated context like a formality — paste in the file, ask the question. What I’ve learned is that the context you load shapes the entire response, not just the part you’re asking about.

For anything non-trivial, I now explicitly load the file being modified, its direct dependencies (the interfaces it implements, the classes it calls), the relevant test file, and any configuration that affects behavior — the relevant application.yml sections, env variables, that kind of thing.

I also say out loud what the agent should NOT need to look at. “Ignore the other controllers. The auth logic is handled upstream in the filter chain — you don’t need to worry about it.” This sounds redundant but it prevents the agent from going exploring in directions that add noise to the output.

When working in a large Spring Boot monolith, I’ll often start a session by describing the module structure explicitly: “This project has five modules. We’re only working in user-service. The common module has shared DTOs — you can read it but don’t modify it.” A few sentences of orientation saves many paragraphs of correction later.

Always plan before you code

The pattern that changed my output quality the most: never go straight to code on anything that touches more than one file.

With Claude Code I use /plan or just ask explicitly for a plan before any implementation. Not because I don’t trust the agent to code — but because catching a wrong assumption at the plan stage costs ten seconds. Catching it after the agent has modified seven files costs twenty minutes of untangling and a lot of git checkout.

A plan review also surfaces things I forgot to mention. If the agent’s plan includes “add a new UserRepository method”, I realize I forgot to say we use a custom JPQL query and we don’t add raw methods to the repository interface. That correction takes one sentence before coding. After coding, it’s a rewrite.

For tasks that span more than one logical step, I’ll ask for the plan broken into phases: “Phase 1: create the new DTO. Phase 2: update the service. Phase 3: update the controller. Phase 4: update the tests.” Then I review each phase before proceeding. This is slower than letting it run, but “slower” means an extra three minutes, and it eliminates the whole class of errors where step 4 assumes something about step 2 that’s already wrong.

What to never delegate

This is the part most productivity takes leave out.

Database migrations. I write every Flyway migration script myself. An agent will generate syntactically correct SQL that does the wrong thing to your data, and you often won’t catch it until you run it. The cost of a wrong migration is too high.

Security logic. JWT validation, permission checks, role hierarchies. I’ll let the agent scaffold the structure, but I write the actual predicate logic myself. It’s not that agents are bad at it — it’s that I need to understand every line of security-sensitive code personally, and “the agent wrote it and I reviewed it” isn’t the same as understanding it.

Anything touching shared state in a concurrent context. Thread pool sizing, cache invalidation, queue consumer configuration. I’ve watched agents write perfectly reasonable-looking code in this area that had subtle race conditions surfacing only under load. Spring’s @Async behavior has enough gotchas around exception handling and thread context propagation that I don’t trust generated code here without very careful review.

API contracts published to other teams. If I’m changing a REST endpoint or a Kafka message schema that another service consumes, I write the change myself. Contract changes need human intent.

The actual workflow

Here’s what a typical feature task looks like now:

1. Write the task spec (bounded, with explicit constraints)
2. Load relevant context explicitly
3. Ask for a plan — review it, correct it
4. Execute phase by phase, reviewing output between phases
5. Run the tests the agent wrote, then run the broader test suite
6. Read the diff, not the agent's summary
7. Commit with a message I write myself

Step 6 is worth repeating: read the actual diff, not the agent’s description of what it did. Agents are optimistic narrators. The diff is the ground truth.

Linear flow from task spec → context loading → plan review → phase execution loop (execute → review → proceed or correct) → test run → diff review → commit

The phase execution loop is where most of the real work happens. On a task touching four files, I’ll typically have one or two corrections mid-way. That’s normal. The correction looks like: “The service method is correct but don’t call userRepository.save() directly — use UserService.update() which already handles audit logging. Revise phase 3.”

Patterns that work in Java/Spring Boot land

Test first, always. When I ask an agent to add a feature, I almost always ask it to write the test first. Not for TDD philosophy — because a test forces the agent to think about the interface before the implementation. The test spec is a contract. I review it, approve it, then ask for the implementation.

// Ask for this first:
@Test
void shouldReturnUnauthorizedWhenTokenExpired() {
    String expiredToken = tokenGenerator.generateExpiredToken(userId);

    mockMvc.perform(get("/api/users/me")
            .header("Authorization", "Bearer " + expiredToken))
           .andExpect(status().isUnauthorized())
           .andExpect(jsonPath("$.code").value("TOKEN_EXPIRED"));
}

If the agent can write that test clearly, it understands the requirement. If it hedges or makes assumptions in the test itself, I go back and clarify before going further.

Name your constraints explicitly in the prompt. Spring’s ecosystem has a lot of ways to do the same thing. “Add caching” could mean @Cacheable, Redis directly, Caffeine, a manual ConcurrentHashMap. I name the technology: “Use @Cacheable with our existing Redis CacheManager bean. Cache name is user-profiles. TTL is already configured in CacheConfig.java.”

Ask for the unhappy path. Default agent output handles the happy path well and glosses over error cases. I ask explicitly: “Also handle the case where the external payment service returns a 503. Retry once after 500ms using @Retryable, then throw a PaymentServiceUnavailableException that the controller maps to a 502.”

When it breaks — and what to do

Agents go off-rails. It happens less at hour 1,000 than it did at hour 200, but it still happens. The failure modes I see most:

Scope creep. The agent “fixes” something nearby that it noticed while working. The fix is usually not wrong, but it’s unexpected and untested. My defense: explicit “do not change anything outside of [specific files]” language in the task, plus reading the diff carefully.

Hallucinated APIs. Especially in less-common libraries, agents will confidently use methods that don’t exist. In Spring, this tends to happen with newer APIs or module-specific features. Running the code is the only reliable check — code review misses it sometimes.

The test that tests nothing. An agent writes a test that passes trivially because it’s testing a mock returning a mock. I check by asking: “What production behavior would break this test if I deleted it?” If the answer is “nothing,” the test is useless.

When a session goes badly wrong — multiple phases deep into a mess — I don’t try to patch it. I discard, go back to the last clean commit, and restart with a more constrained task spec. Fighting a bad trajectory is slower than resetting. This took me too long to learn.

The honest productivity picture

After 1,000 hours, my throughput on certain task types is genuinely higher. Boilerplate-heavy work — DTOs, controller scaffolding, Flyway migration stubs, test setup code — goes roughly four times faster. Complex logic involving domain rules, concurrency, or security decisions goes maybe 20% faster because the agent handles the typing while I handle the thinking.

There’s also a category where it’s slower: anything where I spend more time specifying and reviewing than I’d spend just coding. For a ten-line method in a well-understood domain, writing a good prompt takes longer than writing the method. So I just write the method.

The productivity gains are real. They compound only when you stop treating the agent as a magic box and start treating it like a capable collaborator who needs clear direction, bounded scope, and explicit verification at each step.

What’s your experience with task scoping? I’m curious whether the “goals vs tasks” distinction resonates with other teams, or whether there’s a completely different framing that works better in your context.

Originally published on Medium.

Pourquoi ta requête Supabase s’arrête à exactement 1000 lignes (et ne te le dit jamais)

La nuit où un dropdown m’a menti

Vingt-trois heures, fin avril. Une utilisatrice de mon outil interne me signale un filtre incomplet sur un dropdown. Mon premier diagnostic accuse un sous-filtre côté interface. Je le démonte, j’isole la source du dataset, je relance sans filtre. Le compteur retourne mille pile. Or la table en porte mille deux cent trois. Je remonte le pipeline, niveau par niveau, jusqu’à la requête source. Quatre niveaux plus haut, le coupable apparaît : un .select() chaîné sur .from(), sans .order(), sans .limit(). La requête réussit. Elle ment.

Le mécanisme

Toute requête PostgREST qui ne déclare pas son ORDER BY reçoit en interne un tri par ctid, l’identifiant de tuple physique Postgres, et un plafond Range HTTP à 1000 lignes appliqué par Supabase. La requête réussit. Aucune exception, aucun warning, aucune trace dans Sentry. Le client reçoit un sous-ensemble dont l’ordre dépend de l’historique des UPDATE et DELETE de la table, rebrassé après un VACUUM FULL ou un pg_repack. Le bug n’existe qu’au-dessus de mille lignes en prod.

// silencieusement plafonné à 1000 lignes
await supabase.from('events').select('*').eq('type', 'login')

// le Range HTTP applique son LIMIT sur un tri stable
await supabase.from('events').select('*').eq('type', 'login').order('id')

La règle ESLint qui ferme la porte

Le pattern est trop discret pour tenir uniquement dans la revue de code. Je l’ai migré côté lint, en visitor AST sur CallExpression, qui exige qu’un .select() chaîné sur un .from() porte un .order() quelque part en aval, sauf lorsque la chaîne se termine par .single(), .maybeSingle(), ou un .limit() explicite à valeur inférieure ou égale à mille. C’est l’un des cinq garde-fous structurels d’une rule Supabase exploitable. Sans les autres, le bruit submerge la rule en moins d’une heure.

export default {
  meta: { type: 'problem', messages: { unordered:
    'select() without .order() falls back to ORDER BY ctid.' } },
  create(context) {
    return {
      CallExpression(node) {
        if (node.callee?.property?.name !== 'select') return
        if (!chainContainsFromCall(node.callee.object)) return
        if (chainHasSafeTerminator(node)) return        // .single, .order, .csv...
        if (selectOptsHasHeadTrue(node)) return         // count head
        if (chainEndsAtAssignment(node)) return         // let q = supabase...
        if (chainIsInsideHelper(node, 'fetchAll')) return
        context.report({ node, messageId: 'unordered' })
      },
    }
  },
}

L’ampleur réelle

Une fois la rule promue en error, le premier audit a remonté cent soixante-dix-huit alertes, étalées sur cinquante-six fichiers. Quarante pourcent étaient des faux positifs : variable réassignée à distance, write returning, helper de pagination qui injecte son propre .order(), count head, terminateur monoligne. Les cinq garde-fous structurels ont ramené le bruit à cent huit vraies cibles avant de toucher la moindre ligne applicative.

La règle

Toute chaîne .from(X).select(...) non triviale porte un .order() explicite. Pas d’option, pas de tiède.

Rule complète, paire avant/après et helper fetchAll pseudonymisés :
github.com/michelfaure/rembrandt-samples/tree/main/postgrest-row-cap

Ce default PostgREST silencieux est exactement le cas archétypal de R12 du Counterpart Toolkit (« cite the official text, materialise vendor defaults »). 14 règles, install en 1 commande : github.com/michelfaure/doctrine-counterpart

Why your Supabase query stops at exactly 1000 rows (and never tells you)

The night a dropdown lied to me

Eleven at night, late April. A user of my internal tool reports an incomplete filter on a dropdown. My first diagnosis blames a sub-filter on the UI side. I take it apart, I isolate the dataset source, I re-run without filters. The counter returns a thousand on the nose. The table holds one thousand two hundred and three rows. I walk up the pipeline, level by level, all the way to the source query. Four levels higher, the culprit appears: a .select() chained on .from(), no .order(), no .limit(). The query succeeds. It lies.

The mechanism

Any PostgREST query that doesn’t declare its ORDER BY receives an internal ctid sort — the physical tuple identifier in Postgres — plus a 1000-row Range HTTP cap applied by Supabase. The query succeeds. No exception, no warning, no Sentry breadcrumb. The client gets a subset whose order depends on the table’s UPDATE and DELETE history, reshuffled after a VACUUM FULL or pg_repack. The bug only exists above one thousand rows in production.

// silently capped at 1000 rows
await supabase.from('events').select('*').eq('type', 'login')

// the Range HTTP cap applies on a stable sort
await supabase.from('events').select('*').eq('type', 'login').order('id')

The ESLint rule that closes the door

The pattern is too quiet to live in code review alone. I moved it to lint, as an AST visitor on CallExpression, that requires a .select() chained on .from() to carry an .order() somewhere downstream, unless the chain terminates with .single(), .maybeSingle(), or an explicit .limit() below or equal to a thousand. It’s one of five structural guards a workable Supabase rule needs. Without the others, the noise drowns the rule in under an hour.

export default {
  meta: { type: 'problem', messages: { unordered:
    'select() without .order() falls back to ORDER BY ctid.' } },
  create(context) {
    return {
      CallExpression(node) {
        if (node.callee?.property?.name !== 'select') return
        if (!chainContainsFromCall(node.callee.object)) return
        if (chainHasSafeTerminator(node)) return        // .single, .order, .csv...
        if (selectOptsHasHeadTrue(node)) return         // count head
        if (chainEndsAtAssignment(node)) return         // let q = supabase...
        if (chainIsInsideHelper(node, 'fetchAll')) return
        context.report({ node, messageId: 'unordered' })
      },
    }
  },
}

The real scale

Once the rule was promoted to error, the first audit raised one hundred and seventy-eight alerts, spread over fifty-six files. Forty percent were false positives: variable reassigned at a distance, write returning, pagination helper injecting its own .order(), count head, single-row terminator. The five structural guards brought the noise down to one hundred and eight real targets before touching a single line of application code.

The rule

Every non-trivial .from(X).select(...) chain carries an explicit .order(). No option, no lukewarm.

Full rule, before/after pair and fetchAll helper, pseudonymized:
github.com/michelfaure/rembrandt-samples/tree/main/postgrest-row-cap

This silent PostgREST default is exactly the archetypal case of R12 of the Counterpart Toolkit (“cite the official text, materialise vendor defaults”). 14 rules, install in 1 command: github.com/michelfaure/doctrine-counterpart

Why AI coding agents fail with incomplete specs

GitHub logo

AI coding agents like Codex and Claude Code are getting surprisingly good at writing code.

But after using them in real projects, I noticed something:

Most failures were not caused by the model.

They were caused by incomplete specs.

When a specification has gaps, the AI fills them in with plausible assumptions. At first the generated code often looks correct, but over time the implementation slowly drifts away from the intended behavior.

I kept running into issues like:

  • missing auth boundaries
  • unclear tenant ownership rules
  • retry and race-condition problems
  • webhook duplication edge cases
  • requirements enforced only on the client side
  • implementation drift between spec and actual behavior

Eventually it becomes difficult to tell whether the bug is:

  • in the implementation,
  • in the specification,
  • or in the original requirement itself.

A Real Failure Case

One issue I repeatedly saw was missing tenant ownership validation.

A spec would describe:

  • authentication
  • API structure
  • expected responses

but never explicitly define ownership constraints.

The AI agent would generate code that correctly authenticated the user, but still allowed cross-tenant access because ownership validation was never part of the specification.

The implementation looked reasonable at first glance.

But the security boundary itself was undefined.

That was the moment I realized the problem was often not “bad code generation.”

It was ambiguous requirements.

The Idea

I started building an open-source tool called SpecGuard.

The goal is simple:

Review requirements before they become input to an AI coding agent.

Instead of reviewing generated code after implementation, SpecGuard tries to catch ambiguous or incomplete requirements earlier in the workflow.

This is heavily inspired by problems I encountered while experimenting with:

  • AI-assisted development
  • LLM coding agents
  • spec-driven development workflows

Intended Workflow

Write spec
    ↓
Run SpecGuard
    ↓
Fix NOT_READY findings
    ↓
Hand spec to AI coding agent

What SpecGuard Checks

Main validation areas

SpecGuard mainly looks for ambiguous or missing areas such as:

  • auth and permission boundaries
  • tenant ownership rules
  • idempotency and replay safety
  • race conditions
  • expiration and revocation handling
  • state transitions
  • webhook/background retry behavior
  • requirements relying only on client-side validation

The output is one of:

  • READY
  • READY_WITH_WARNINGS
  • NOT_READY

Why the Default Mode Does Not Use an LLM

I intentionally made the default path non-LLM.

I wanted spec validation to behave more like linting:

  • deterministic
  • reproducible
  • CI-friendly
  • cheap to run repeatedly

LLM-based review exists as an optional deeper layer, not the foundation.

There is also an optional OpenAI/Codex-based deeper review mode, but currently I treat that as a secondary layer rather than the default workflow.

Codex Plugin

In v0.4.0 I added an MVP Codex plugin.

Install:

pip install spec-guard
specguard --help

codex plugin marketplace add KoreaNirsa/spec-guard --ref main

Create an example spec package:

specguard example copy specs/your-feature-name --force

Inside Codex, the plugin can:

  • run SpecGuard analysis
  • read generated results
  • summarize READY/NOT_READY state
  • explain main findings and next actions

The plugin itself does not reimplement the engine.

It wraps the existing CLI workflow.

GitHub PR Review Workflow

SpecGuard also includes a GitHub Actions-based PR review workflow.

When a spec package changes in a PR, it can automatically run SpecGuard Review and leave findings directly on the PR.

The OpenAI review path currently uses GitHub secrets such as:

SPECGUARD_OPENAI_API_KEY
SPECGUARD_PR_REVIEW_MODEL
SPECGUARD_REVIEW_SPEC_PATHS

Current Status

This project is still very early and pre-beta.

I do not expect it to perfectly judge every specification.

Right now I am mainly interested in feedback around:

  • what kinds of specs this workflow fits well
  • where deterministic checks break down
  • which findings feel too noisy or too weak
  • whether PR enforcement would fit real engineering workflows

If you are already using AI coding agents in production workflows, I’d genuinely like to know:

  • what kinds of spec failures you see most often
  • where deterministic validation breaks down
  • and whether something like this would actually fit your development workflow

I’m especially interested in situations where the generated implementation looked correct, but the requirement itself was underspecified.

Feedback, issues, and PRs are all welcome.

GitHub logo

KoreaNirsa
/
spec-guard

Validation-First Workflow (VFW) for AI-assisted development

SpecGuard banner

SpecGuard

SpecGuard blocks weak specs before AI coding agents turn them into defective code.

SpecGuard is a Validation-First Workflow (VFW) for AI-assisted development
It turns specs into reviewed, testable, implementation-ready packages before AI coding begins.

It is not a prompt-to-code generator. SpecGuard helps you prepare an approved spec package before an external Codex, Claude Code, or another coding agent writes application code.

Demo Video

SpecGuard demo walkthrough

Watch the full-resolution MP4 demo

The demo follows this flow:

  1. Install SpecGuard with pip install spec-guard.
  2. Copy the example spec with specguard example copy your-feature-name --force.
  3. Insert a vulnerable spec. In v0.3.0, the packaged example intentionally includes a vulnerable spec by default so users can see a blocking SpecGuard Review.
  4. Review the SpecGuard findings.
  5. Fix the weak areas directly, or ask an AI assistant to strengthen the spec by giving it the SpecGuard Review findings.
  6. Run SpecGuard Review again and confirm it reaches READY…