iOS 27 ile iPhone’lara gelecek üç yeni özellik daha ortaya çıktı
 Apple, iOS 27 ve iPadOS 27’de yapay zeka araçlarını önemli ölçüde genişletmeye hazırlanıyor. Yeni özellikler, yazma, otomasyon ve kişiselleştirmeye odaklanıyor.

 Mert
Apple, iOS 27 ve iPadOS 27’de yapay zeka araçlarını önemli ölçüde genişletmeye hazırlanıyor. Yeni özellikler, yazma, otomasyon ve kişiselleştirmeye odaklanıyor.
A few weeks ago the folding roof on my 2010 Ford Focus CC stopped working.
The obvious suspect was the roof module, but FORScan showed nothing there: zero stored fault codes. The useful clues were somewhere else, in the passenger door module, and they didn’t look related at first glance.
I wanted to see whether Claude could work with that kind of diagnostic state directly instead of me copy-pasting screenshots from FORScan. So I built a small MCP server around an OBD-II adapter.
This is not a story about Claude magically fixing a car. It’s a story about giving an LLM a narrow, read-only set of tools, fighting a BLE adapter for a few hours, and seeing whether the model could produce a useful explanation from real diagnostic state.
The setup
┌──────────┐    Bluetooth    ┌───────────────┐    Python    ┌──────────────┐    MCP    ┌─────────┐
│   Car    │ ◄─────────────► │  vLinker FD   │ ◄──────────► │  MCP Server  │ ◄───────► │  Claude │
│  OBD-II  │                 │  ($15 dongle) │              │  (250 lines) │           │         │
└──────────┘                 └───────────────┘              └──────────────┘           └─────────┘
For this experiment I used only read-only tools:
| Tool | What it does |
|---|---|
read_dtc |
Read stored fault codes from all or specific modules |
get_live_data |
Real-time sensor readings (RPM, coolant temp, speed, etc.) |
get_vehicle_info |
VIN, calibration IDs, ECU name |
list_modules |
Enumerate all ECUs on the CAN bus |
get_freeze_frame |
Sensor snapshot from when a DTC was set |
explain_dtc |
Look up a code in the local DTC database |
There is a guarded clear_dtc command in the repo (requires explicit confirmation), but I didn’t use it for this experiment and wouldn’t include it in a truly read-only profile.
The server is about 250 lines of Python and intentionally boring. Claude helped with the Python boilerplate, but the useful work was figuring out the adapter behavior and the diagnostic boundaries.
The BLE problem (where most of the time went)
The car side was straightforward. Plug the Vgate vLinker FD into the OBD port, turn the ignition on, pair via Bluetooth (PIN is 1234, not the 0000 macOS suggests).
macOS created a serial port:
$ ls /dev/tty.*vLinker*
/dev/tty.vLinkerFD-Android
Looks good. Let’s talk to it:
import serial
conn = serial.Serial('/dev/tty.vLinkerFD-Android', baudrate=115200, timeout=2)
conn.write(b'ATZr')  # Reset the ELM327 chip
response = conn.read(100)
print(response)  # b''
Nothing. Empty bytes. I tried every common baud rate (9600, 38400, 115200, 500000). All of them opened the port without error, accepted writes, and returned nothing.
I spent a couple of hours on this. Tried different AT commands, reconnected the adapter, verified the ignition was on. The port was there, it opened cleanly, and nobody was home.
The actual problem: the vLinker FD is a BLE device, not classic Bluetooth. These are two completely different protocols. Classic Bluetooth creates a serial port (SPP/RFCOMM) and you talk to it like a USB cable. BLE uses GATT characteristics instead, small read/write endpoints organized into services.
When macOS paired with the vLinker, it created a serial port entry because that’s what macOS does with Bluetooth devices. But the adapter never actually serves data on RFCOMM. It only listens on its BLE GATT characteristics. The serial port was a phantom.
This is why FORScan works fine on iOS. It uses Core Bluetooth to talk BLE directly. It never tries the serial port.
The fix was the bleak library (Python BLE client). The adapter exposes a GATT service with specific characteristics for communication:
Service: 0000fff0-0000-1000-8000-00805f9b34fb
Write:   0000fff2-0000-1000-8000-00805f9b34fb
Notify:  0000fff1-0000-1000-8000-00805f9b34fb
You send ELM327 commands to the write characteristic and listen for responses on the notify characteristic:
async with BleakClient(address) as client:
    await client.start_notify(NOTIFY_UUID, on_response)
    await client.write_gatt_char(WRITE_UUID, b'ATZr')
First successful adapter interaction after hours of debugging:
> ATZ
ELM327 v1.5

> AT SP 6
OK

> 0100
41 00 BE 3E B8 13
The lesson I keep coming back to: the hard part of connecting an LLM to hardware was not the LLM. It was getting bytes from point A to point B through the correct abstraction layer.
Why MCP instead of just pasting logs?
The useful part of MCP here is not sophistication. It’s the boundary.
Claude doesn’t get arbitrary access to my laptop or the car. It gets a small set of named tools with typed inputs and outputs: list modules, read DTCs, explain one code, fetch freeze-frame data. That’s it.
That made the interaction auditable. I could see exactly what Claude asked for, what the adapter returned, and where the final explanation came from. If Claude produced a bad answer, I could trace it back to which tool call returned unexpected data versus where the model’s reasoning went wrong.
For a system that talks to actual hardware, that boundary matters more than convenience.
The DTC database
The car returns codes, not rich explanations. OBD-II gives you hex strings like B1310, but the standard doesn’t include descriptions. Manufacturer-specific codes aren’t in any universal reference.
For the prototype, I built a local lookup database from publicly available DTC references using an Apify crawler. It covers over 20 brands (Ford’s coverage is the deepest, with codes across powertrain, body, and chassis categories). The database is not authoritative, and I wouldn’t treat it as a replacement for OEM service data. The point was to avoid asking Claude to invent meanings for manufacturer-specific codes from memory.
What Claude actually did
Here’s the context I hadn’t explained yet. The passenger window regulator on the car is broken: the motor spins, but the glass doesn’t move. On a convertible, that matters because the roof sequence depends on the side windows dropping before the roof panels can fold over them.
The interesting diagnostic puzzle was that the folding top module had no stored DTCs. The only relevant faults were in the passenger door module.
Important caveat: the Focus CC module scan shown below is reproduced in the mock adapter from my actual FORScan session. The MCP server can talk to the BLE adapter and read standard ELM327 responses, but full Ford MS-CAN module enumeration (which is where body modules like the roof controller live) needs extended commands beyond what generic OBD-II provides. The mock exists so the MCP workflow can be tested end-to-end without pretending that generic OBD-II gives you all body-module data for free.
Simplified scan output from mock mode (module addresses and fault codes match my real FORScan session):
Module                              Address    Protocol    DTCs
──────────────────────────────────────────────────────────────────
PCM (Powertrain Control)            0x7E0      HS-CAN      0
ABS Module                          0x760      HS-CAN      0
Instrument Cluster                  0x720      MS-CAN      0
Driver Door Control Unit            0x740      MS-CAN      0
Passenger Door Control Unit         0x741      MS-CAN      2
  → B1310: Power door unlock circuit failure
  → B166A: Heated mirror circuit open
Folding Top Control Module          0x750      MS-CAN      0
HVAC Module                         0x733      MS-CAN      0
Reconstructed tool-call sequence from the mock-mode run:
1. list_modules()             → found 7 ECUs
2. read_dtc()                 → scanned all modules, found 2 codes on passenger door
3. explain_dtc("B1310")       → "Power door unlock circuit failure"
4. explain_dtc("B166A")       → "Heated mirror circuit open"
5. get_freeze_frame("B1310")  → sensor snapshot from when the code was set
The codes themselves don’t say “broken window regulator.” B1310 and B166A point to passenger-door electrical faults. The missing piece was the symptom history: the window motor spins but the glass doesn’t move, and the roof stopped working around the same time.
I asked Claude: “The roof won’t operate but the roof module has no fault codes. Why?”
Claude’s hypothesis: the roof controller performs a live precondition check before the folding sequence. It asks the windows to move. If the passenger side doesn’t respond correctly (because the regulator is broken), the sequence aborts. Since the roof module itself isn’t failing, it doesn’t store a DTC. The relevant faults are on the door module, not the roof module.
The important connection was not B1310 specifically. It was that the only module with faults was in the same subsystem the roof controller depends on for its pre-flight sequence.
That matched what I later found in Ford service documentation. I haven’t replaced the regulator yet, so this is still a high-confidence hypothesis rather than a confirmed repair. But it was useful novice-level triage: connecting live module state, symptom history, and reference data into a coherent next thing to check. That’s more than I had before building this.
What this did not prove
This didn’t prove that Claude can diagnose cars. It proved something narrower:
What I intentionally didn’t build
The server is read-only. I didn’t expose actuator tests, module coding, service resets, or anything that can change vehicle state.
The DTC database includes diagnostic procedures for each brand: how to run self-tests, cycle actuators, reset service intervals. In theory, you could wrap those as MCP tools. I chose not to.
I’m a developer, not a car mechanic. Reading fault codes is passive, you’re just asking the car what it already knows. But sending active commands to modules is a different thing entirely. A wrong routine ID, a command sent at the wrong time, or an actuator test while someone’s hand is near a moving part. That’s real risk. The gap between “technically possible via UDS Service $31” and “safe to let an LLM trigger autonomously” is enormous.
Honest limitations
Standard OBD-II is limited. The OBD-II standard only covers emissions-related PIDs. Body modules (roof controllers, door modules) live on manufacturer-specific CAN buses. The python-obd library doesn’t natively scan Ford’s MS-CAN bus. The mock adapter simulates this based on real FORScan data, but real MS-CAN scanning from the MCP server needs FORScan-level extended commands that aren’t implemented yet.
The DTC database is scraped, not authoritative. It’s built from publicly available references, not Ford’s official FRIDA/DRIS database. Some descriptions may be incomplete or outdated.
Claude can hallucinate. It produced a plausible explanation for my roof problem, but LLMs can also produce confident-sounding nonsense. This is an explanation layer, not a repair manual. Verify anything it says against actual service documentation before acting on it.
The repo
The code is here: github.com/petrpatek/obd2-mcp-server
git clone https://github.com/petrpatek/obd2-mcp-server.git
cd obd2-mcp-server
./setup.sh
source .venv/bin/activate
obd2-mcp --mock  # runs with simulated car data, no hardware needed
The mock simulates the Focus CC scenario with the same module addresses and fault codes I saw in FORScan. If you have an ELM327-compatible adapter, swap --mock for --ble (or --port for USB) and point it at a real car.
It passes 28 tests and works for the narrow path I built it for, but it’s a prototype. I wouldn’t rely on it for real diagnostics without verifying the output against proper service documentation.
What’s next
I’m working on dynamic PID discovery (asking each ECU what standard PIDs it supports), live data streaming, and better brand coverage for the DTC database. All read-only.
The pattern I care about is narrower than “AI for every industry”: take a system that already exposes diagnostic state, wrap a few safe read-only queries as tools, and let the model explain what it sees without letting it push buttons.
That seems useful beyond cars, but only if the boring parts are done well: protocol quirks, incomplete documentation, adapter weirdness, safety boundaries, and knowing when not to let the model act.
If you’ve tried similar MCP wrappers for CAN, Modbus, or other diagnostic protocols, I’d be curious to compare notes.
The hinge squeaks when you open it.
Not loudly. Just enough to sound mechanical in a way modern laptops rarely do anymore. The plastic has that strange soft texture that only older electronics seem to develop after years of heat, nicotine, backpacks, coffee spills, basement air, and human skin. The keyboard flexes slightly under pressure. Somewhere inside the machine, a tiny fan spins like an exhausted surveillance drone trying to stay awake.
And despite all of that, the thing boots.
Maybe not quickly. Maybe not gracefully. But it boots every single time.
There is a reason old ThinkPads keep appearing in hacker spaces, Linux meetups, IRC screenshots, darknet documentaries, and grainy YouTube videos filmed under red LEDs at 2am. Once you spend enough time around people who break systems for curiosity or survival, you start noticing the same black rectangle appearing over and over again. Like a recurring symbol in dreams.
Eventually, you understand why.
The Modern Laptop Feels Hostile
A lot of modern hardware feels emotionally distant. Sealed shut. Sanitized. Built to discourage contact.
You pick up a new ultrabook and it feels less like a machine and more like an appliance leased to you temporarily by a corporation that assumes you will behave incorrectly. The screws are proprietary. The keyboard is flat and lifeless. The BIOS looks like a toy menu from a smart refrigerator. RAM is soldered directly to the board because apparently upgrading your own hardware became culturally suspicious at some point.
Even the aesthetics changed. Everything became silver. Rounded. Softened. Minimalist in the same way luxury condos are minimalist. Expensive emptiness.
Old ThinkPads feel different.
They feel built by engineers who assumed the user might eventually need to survive something.
Not aesthetically. Structurally.
You can open many of them with a screwdriver from a gas station multitool. Parts are replaceable. Documentation exists. Linux usually works without ritual sacrifice. Some models still have removable batteries, physical latches, proper keyboards with travel deep enough to feel intentional. They were made during a strange era where computers still resembled equipment instead of lifestyle accessories.
That distinction matters more than people realize.
Especially to hackers.
The Keyboard Changes Your Brain Slightly
This sounds irrational until you spend a few weeks typing on one.
Then you notice it.
The older ThinkPad keyboards, especially the classic seven row layouts, create a strange psychological effect where writing commands starts feeling tactile again. Not metaphorically tactile. Physically tactile. You can feel force transfer through the chassis. The keys have weight and resistance. Certain shortcuts become muscle memory faster because your fingers receive actual feedback instead of tapping on polished chiclet glass tiles pretending to be keys.
It changes terminal use.
You stop feeling like you’re interacting through a layer of abstraction and start feeling mechanically connected to the system itself. Tiny thing. Hard to quantify. But it accumulates over time.
A lot of hackers become obsessed with efficiency, but eventually many drift toward something else entirely: intimacy with tools.
That is what the ThinkPad provides.
An intimacy modern hardware often destroys.
They Look Like Devices That Belong Somewhere Underground
There is also the visual component. People pretend aesthetics are superficial, then spend ten thousand dollars decorating rooms to influence mood.
Old ThinkPads look correct.
Not flashy. Not “retro” in the forced neon nostalgia way companies try to market now. They look industrial. Severe. Utilitarian. Like something recovered from an archive bunker beneath an abandoned telecommunications facility.
A scratched X220 sitting on a diner table beside a black coffee and tangled USB adapters looks more believable than most “cyberpunk” props in movies.
Part of this comes from restraint. The matte black shell. The tiny red TrackPoint glowing in the center like an artificial pupil. Minimal branding. Almost military.
There is an accidental honesty to the design.
These machines were made before every object became desperate to signal status online.
Hackers notice that immediately.
Linux and ThinkPads Grew Together Like Mold and Concrete
Spend enough time in Linux circles and you start hearing the same sentences repeatedly.
“WiFi worked immediately.”
“Suspension actually works.”
“No weird driver issues.”
“It just runs stable.”
This relationship between ThinkPads and Linux became semi-mythological because it was earned slowly over decades. IBM and later Lenovo machines consistently had strong compatibility with Linux distributions, especially compared to consumer laptops that treated Linux support like an unfortunate accident.
And once someone installs Linux successfully on an old ThinkPad for the first time, something strange tends to happen.
The machine feels alive again.
A laptop abandoned by mainstream software ecosystems suddenly becomes lightweight, efficient, adaptable. Old hardware that struggled under bloated operating systems starts moving with eerie responsiveness under Arch, Debian, Void, Gentoo, or whatever strange handcrafted setup the user builds at 4am while listening to ambient drone music and reorganizing dotfiles.
You start seeing the machine less as obsolete hardware and more as reclaimed territory.
That feeling sticks.
The TrackPoint Becomes a Religion
People laugh about the red nub until they use it seriously for two weeks.
Then they start defending it with cult energy.
The TrackPoint looks ridiculous to outsiders because it violates modern interface expectations. But once your hands adapt, it becomes absurdly efficient. You move the cursor without lifting your fingers from the home row. Tiny adjustments become immediate. Navigating terminals, code editors, packet analysis tools, and browser tabs starts feeling strangely fluid.
It also changes posture.
A lot of heavy keyboard users quietly develop a rhythm where the TrackPoint reduces unnecessary hand movement enough to feel physically noticeable during long sessions. Less drifting toward touchpads. Less interruption.
There is a reason many programmers who abandon ThinkPads eventually miss the TrackPoint specifically.
It rewires workflow in subtle ways.
And subtle things are where obsession begins.
Old ThinkPads Reward Curiosity Instead of Punishing It
Modern devices increasingly discourage exploration.
Open the wrong thing, void the warranty.
Install the wrong OS, lose compatibility.
Replace the wrong component, trigger firmware complaints.
Old ThinkPads feel more permissive.
You can swap keyboards. Replace displays. Upgrade RAM. Install bizarre operating systems. Flash custom firmware. Turn one into a cyberdeck. Build a portable wardriving rig. Convert another into a dedicated writing machine disconnected from modern noise entirely.
People have mounted antennas onto them. Embedded SDR hardware inside them. Used them for car diagnostics, radio experiments, darknet servers, synth control systems, retro gaming, packet sniffing, field notes, war driving, and weird art installations.
The machines tolerate experimentation.
That tolerance creates attachment.
Hackers rarely fall in love with perfect systems. They fall in love with systems that invite participation.
The Scarcity Makes Them Feel Personal
A brand new MacBook feels interchangeable. Walk into any coffee shop and there are twelve identical silver slabs glowing like synchronized consumer mollusks.
Old ThinkPads develop individuality.
One has cigarette burns near the arrow keys. Another has faded stickers from defunct Linux conferences. Another arrived from a university surplus warehouse with mysterious BIOS passwords and an inventory tag from 2011 still attached.
Somebody used these machines before you. Hard.
And unlike modern devices, the wear improves the atmosphere instead of degrading it.
Scratches become history.
A dented ThinkPad with a battered shell and custom Linux setup feels less like a product and more like a companion object. Almost ritualistic. Like a field notebook or old camera body.
You begin configuring it slowly. Tweaking terminal colors. Changing bootloaders. Building tiny workflows nobody else understands. Naming scripts strange things. Organizing encrypted drives like hidden rooms inside a collapsing monastery.
After enough time, the machine starts reflecting the operator psychologically.
That is difficult to manufacture artificially.
They Resist Planned Obsolescence Better Than Expected
Some older ThinkPads simply refuse to die.
You still see X220s from 2011 running daily workloads. T420s upgraded with SSDs and extra RAM still handling development work. Ancient T60 machines turned into distraction free writing devices. X61 tablets repurposed into field terminals.
Modern tech culture constantly pushes replacement cycles. Faster. Thinner. Newer. AI-enabled toothbrush refrigerator ecosystems connected to six subscription services and an app that harvests behavioral telemetry while pretending to optimize hydration.
Meanwhile some dusty ThinkPad from the Obama administration is quietly running Debian in perfect silence.
There is something spiritually satisfying about that.
Especially for people already skeptical of corporate ecosystems.
Hackers Tend to Romanticize Functional Decay
This is probably the least discussed part.
Hackers, especially the underground-adjacent kind, often develop emotional attachment to imperfect infrastructure. Not because imperfection is objectively better, but because decay exposes system anatomy.
An old ThinkPad reveals itself constantly.
The battery weakens visibly.
The fan noise changes under load.
The chassis creaks.
The display yellows slightly.
Thermals become understandable instead of hidden behind optimization layers.
You become aware of the machine as a physical object instead of an invisible service portal.
That awareness creates respect.
And respect becomes affection faster than most people expect.
There Is a Certain Kind of Freedom in Using “Outdated” Hardware
Using old ThinkPads creates a subtle psychological separation from mainstream upgrade culture.
You stop caring about benchmarks as much.
You stop chasing aesthetic trends every six months. You stop optimizing for social signaling. The machine becomes a tool chosen intentionally instead of a status object inherited from algorithmic recommendation sludge.
Ironically, this often makes people more productive.
Constraints simplify behavior.
An old ThinkPad running a lean Linux environment with carefully selected software feels calm compared to the modern productivity carnival of AI assistants, telemetry dashboards, collaborative cloud overlays, subscription popups, and attention extraction systems disguised as workflows.
The machine becomes quiet.
Not silent technically. The fan probably sounds like a dying moth trapped in ductwork. But cognitively quiet.
That matters.
Especially now.
The Hacker and the ThinkPad Eventually Start Resembling Each Other
This sounds dramatic, but watch long term ThinkPad users carefully.
They tend to value repairability.
Self sufficiency.
Documentation.
Adaptability.
Durability over appearance.
Function over prestige.
Control over convenience.
The laptop becomes symbolic after a while.
Not in a cringe “elite hacker aesthetic” sense. More like an externalization of priorities. A machine aligned with a worldview where systems should remain understandable, modifiable, and personally owned.
A lot of people enter hacking through excitement. Exploits, gadgets, darknet mythology, terminal screenshots.
But if they stay long enough, many drift toward something quieter.
Sovereignty.
That is where the ThinkPad waits for them.
Usually scratched to hell. Running Linux. Covered in old stickers. Battery held in place with electrical tape. Sitting on a desk beside tangled adapters and a half finished cup of coffee gone cold three hours ago.
Still booting.
Still useful.
Still here.
A lot of the machines mentioned in this post are probably running custom Linux setups, strange automation scripts, local AI tooling, or heavily modified workflows stitched together over years.
If that world interests you, you might like my guide:
Claude Code for Developers: 21 Productivity Tricks That Save Hours
Built for people who treat computers less like appliances and more like environments worth shaping.
Most teams I speak with have Cloudflare in front of their site. That is usually a good thing — Cloudflare absorbs DDoS traffic, proxies requests, applies managed WAF rules, and makes a messy internet-facing stack much easier to operate.
But one dangerous assumption often follows:
“We are behind Cloudflare, so we are protected.”
That is not how it works. Cloudflare only protects traffic that actually flows through Cloudflare. And even when traffic does flow through it, a WAF does not automatically fix missing authentication, exposed development environments, broken authorization, SQL injection, or business logic flaws.
Here are two patterns we still find regularly during blackbox web application testing. What makes this more pressing today: with AI-assisted tooling, the reconnaissance and exploitation steps across both scenarios can be chained and executed in a matter of minutes — work that once took hours of manual effort.
1. The origin server is still reachable directly
A common Cloudflare mistake is moving DNS behind the orange cloud but leaving the origin server exposed to the public internet.
Attackers do not need magic to find this. They use the same passive sources defenders should already be checking:
# Certificate transparency logs
curl -s "https://crt.sh/?q=shop.example.com&output=json" | jq '.[].name_value' | sort -u

# Historical DNS from SecurityTrails, DNSDB, ViewDNS, etc.
# Look for old A records that pre-date the Cloudflare migration.

# Shodan check once an origin candidate is found
shodan host <origin-IP>
Once a candidate IP is identified, a direct request with the correct Host header can confirm whether Cloudflare is being bypassed. The -k flag is used here to skip certificate validation, since the origin cert may not match the hostname:
curl -vk --resolve shop.example.com:443:<origin-IP> https://shop.example.com/
The response headers tell you immediately where you are. Through Cloudflare, you would expect to see its fingerprints:
< Server: cloudflare
< CF-RAY: 7a1b2c3d4e5f6789-LHR
Direct to origin, you might instead see:
< HTTP/1.1 200 OK
< Server: nginx/1.22.1 (Ubuntu)
< X-Powered-By: PHP/8.1.2
< Content-Type: text/html; charset=UTF-8
At that point, the WAF is not in the path at all. Any exposed admin panel, forgotten upload endpoint, missing rate limit, or application bug is reachable directly.
Directory discovery against the origin might look like this. The Host header is required so the server routes the request correctly:
ffuf -w /usr/share/wordlists/dirb/common.txt
     -u https://<origin-IP>/FUZZ
     -H "Host: shop.example.com"
     -mc 200,301,302,403
     -o results.json
One recurring finding is an admin login that the team expected to be protected by Cloudflare, but is actually accessible directly on the origin. If the application also lacks login throttling, the risk compounds quickly:
for i in {1..20}; do
  curl -s -o /dev/null -w "%{http_code}n" -X POST https://<origin-IP>/admin/login
    -H "Host: shop.example.com"
    -d "username=admin&password=test$i"
done

# 200
# 200
# 200
# ...no 429, no lockout, no CAPTCHA
The important point here is not “Cloudflare failed.” Cloudflare was never in the request path to begin with.
2. Cloudflare is in the path, but the application is still vulnerable
The second pattern is subtler.
Sometimes Cloudflare is configured correctly. Production DNS is proxied. The origin firewall only allows Cloudflare IP ranges. Direct origin access is blocked.
But a development or staging subdomain is publicly reachable.
A typical discovery flow:
# Certificate transparency enumeration
curl -s "https://crt.sh/?q=%.example.com&output=json" | jq '.[].name_value' | sort -u

# Passive multi-source subdomain discovery
subfinder -d example.com -silent -o subdomains.txt

# HTTP host probing
ffuf -w /usr/share/wordlists/subdomains-top1million.txt
     -u https://FUZZ.example.com
     -mc 200,301,302,403
     -t 50
Then a hostname appears:
dev.example.com
It is orange-clouded. It resolves through Cloudflare. The origin is not directly reachable.
But the dev application loads with no VPN, no basic auth, no IP allowlist, and no authentication prompt.
At this point, Cloudflare is doing exactly what it was configured to do: proxy traffic to a publicly available hostname.
If that dev environment has debug mode enabled, the application may leak more than intended. A deliberately malformed request:
curl -s "https://dev.example.com/api/v1/accounts?account_id='"
Might return:
HTTP/1.1 500 Internal Server Error

Error: SQLSTATE[42000]: Syntax error or access violation near ''' at line 1
Query: SELECT * FROM users WHERE account_id = ''' AND status = 'active'
File: /var/www/dev/api/v1/accounts.php, Line 88
That single response exposes the stack, file paths, parameter names, and the full query shape.
A time-based injection check can then confirm exploitability. SLEEP() is MySQL-specific; adjust accordingly for other databases:
curl -s "https://dev.example.com/api/v1/accounts?account_id=1' AND SLEEP(5)-- -"
A WAF can catch some common SQL injection patterns. But it is not a replacement for parameterised queries, input validation, proper access control, and secure environment configuration. In this scenario, every request went through Cloudflare. The vulnerability still existed.
The shared lesson
These are different failure modes:
Both produce the same practical outcome: something sensitive is reachable from the public internet while the team assumes it is covered.
Checks worth running
If you operate a Cloudflare-protected application, these are a good starting point:
Cloudflare is a genuinely useful tool. WAFs are worth having.
But neither tells you what is actually reachable on your infrastructure, nor how your application behaves once an attacker gets there. That requires knowing your own attack surface — and testing it.
How to Build a REST API with Node.js and Express from Scratch
Create a production‑ready RESTful API step‑by‑step using Node.js, Express, and modern best practices
Before We Start: What You’ll Walk Away With
By the end of this guide you’ll be running a complete CRUD REST API on your laptop, just like having a personal kitchen where you can order, update, delete, or view any dish you’ve prepared.
We’ll walk you through the whole project layout, so you’ll know exactly why each folder exists—think of it as packing a suitcase where every item has its own compartment, making the trip smoother.
You’ll also get comfortable with middleware, routing, error handling, and a dash of security, similar to using Google Maps: the router tells requests where to go, middleware adds the traffic rules, and error handling warns you when you hit a dead end.
Spin up a Node.js server with Express and see it respond to HTTP verbs.
Organize code into controllers, routes, and models so future changes feel like swapping out a single ingredient.
Add basic protections—like checking a password before entering a club—to keep unwanted traffic out.
Node.js: the engine that runs your JavaScript on the server.
Express: the lightweight framework that routes requests, like a maître d’ directing guests to tables.
CRUD: Create, Read, Update, Delete – the four actions you’ll master.
When you clone the repo, you’ll see a ready‑made structure you can tweak: change a route, add a field, or point it at a cloud database without rebuilding from scratch.
In short, you’ll finish with a copy‑and‑paste‑ready API you can extend or deploy wherever you need it.
What a REST API Actually Is (No Jargon)
A REST API is simply a collection of URLs that accept HTTP verbs—GET, POST, PUT, DELETE—to let one program ask another for data or tell it to change something. Think of each URL as a door and the verb as the way you knock; the response is whatever the other side hands you back.
Picture a restaurant menu. The menu lists dishes (those are your resources). You, the diner, send a waiter a request: “I’d like the salad GET,” “Add a drink POST,” “Swap the fries for a side of veggies PUT,” or “Take the soup away DELETE.” The kitchen prepares the order and the waiter brings it back—that’s the API’s response.
Because the conversation follows a standard set of rules, any client that understands HTTP can “eat” at your API, whether it’s a web app, a mobile app, or a script you run from the command line. No need to share codebases or speak the same programming language; just follow the contract defined by the endpoints.
When you build REST API Node.js apps, you’re essentially drafting that menu, setting up the kitchen stations (routes), and training the waitstaff (middleware) so every request gets the right dish, quickly and predictably.
The 4 Mistakes Everyone Makes With REST APIs
Most of the pain you feel when a request blows up comes from a simple habit you’ve picked up early on.
Mixing business logic with routing code makes your server feel like a crowded kitchen where the chef also takes orders, washes dishes, and invoices the table. When the logic lives inside the route handler, any change forces you to rewrite the whole menu.
Ignoring proper error handling is like driving a car without a spare tire; a single flat punctures the whole journey. If a typo or missing DB field throws, the entire Node.js process exits and every client gets a 500.
Forgetting to validate input turns your API into an open‑door grocery store where anyone can walk in and dump anything on the shelves. Bad payloads slip into your database, open XSS doors, and corrupt analytics.
Not versioning the API is like packing a suitcase once and never checking the weight before a flight. The first time a client needs a new field, the whole bag shifts and the old travelers are forced to repack.
Spotting these four traps early saves you weeks of debugging when you build REST API Node.js projects.
Next, we’ll walk through the clean project layout that keeps each concern in its own drawer.
How to Build a REST API with Node.js and Express: Step‑by‑Step
Run npm init -y to create a package.json, then install the core tools:
express – the kitchen where your API is cooked
dotenv – the pantry that keeps secret ingredients safe
nodemon – the sous‑chef that restarts the server on every change
Lay out the project like a well‑organized toolbox:
/src
/src/routes
/src/controllers
/src/models
/src/middleware
In src/app.js, load environment variables, spin up an Express instance, and add app.use(express.json()) so the server can read JSON payloads.
Drop a quick health‑check route:
GET /api/health → returns { status: “OK” }
It’s like asking a waiter, “Is the kitchen open?”
Create src/routes/users.js and define the classic CRUD endpoints for a User resource.
Meet Alice. She can be created with POST /api/users, read with GET /api/users/:id, updated via PUT /api/users/:id, and removed with DELETE /api/users/:id.
Write matching functions in src/controllers/userController.js. Each controller receives req and res, performs the logic, then sends a JSON response.
Add a global error‑handling middleware at the bottom of app.js. It catches rejected promises and replies with a consistent error object.
Secure the API with a trio of middleware:
helmet – adds HTTP headers like a lock on the front door
cors – decides which origins can knock
express-rate-limit – prevents a rush of requests, similar to a line‑up manager
Validate input with joi before it reaches your controllers
Create a .env file containing PORT=3000 and any secret keys. dotenv.config() pulls these values into process.env.
Fire up the server with npm run start (script: nodemon src/app.js) and test each endpoint using Postman or curl. If everything responds, you’ve successfully built a REST API with Node.js.
A Real Example: Building a Todo List API for “Sam the Startup Founder”
Sam needs a tiny Todo API so he can demo his MVP to investors by Friday.
He follows the checklist from Section 4, turning a blank folder into a working service.
Project init: npm init -y, install express, dotenv, joi, express-rate-limit.
Folder layout: create src/ with routes/, controllers/, models/, and a root server.js.
Routes for /todos: one file todoRoutes.js that maps HTTP verbs to controller actions.
Controller logic: todoController.js handles create, read, update, delete, each returning JSON.
Validation schema: a Joi schema ensures every Todo has a title (string, required) and optional completed flag.
Rate limiting: a 100‑request‑per‑minute rule protects the public beta, just like a restaurant limits tables during rush hour.
Here’s what Sam’s files look like.
// src/routes/todoRoutes.js
const express = require(‘express’);
const router = express.Router();
const { getTodos, createTodo, updateTodo, deleteTodo } = require(‘../controllers/todoController’);
router.get(‘/’, getTodos);
router.post(‘/’, createTodo);
router.put(‘/:id’, updateTodo);
router.delete(‘/:id’, deleteTodo);
module.exports = router;
// src/controllers/todoController.js
const Joi = require(‘joi’);
const todos = []; // in‑memory store
const schema = Joi.object({
title: Joi.string().required(),
completed: Joi.boolean().default(false)
});
exports.getTodos = (req, res) => res.json(todos);
exports.createTodo = (req, res) => {
const { error, value } = schema.validate(req.body);
if (error) return res.status(400).json({ error: error.details[0].message });
const newTodo = { id: Date.now(), …value };
todos.push(newTodo);
res.status(201).json(newTodo);
};
exports.updateTodo = (req, res) => {
const todo = todos.find(t => t.id == req.params.id);
if (!todo) return res.status(404).end();
const { error, value } = schema.validate(req.body);
if (error) return res.status(400).json({ error: error.details[0].message });
Object.assign(todo, value);
res.json(todo);
};
exports.deleteTodo = (req, res) => {
const index = todos.findIndex(t => t.id == req.params.id);
if (index === -1) return res.status(404).end();
todos.splice(index, 1);
res.status(204).end();
};
.env
PORT=3000
RATE_LIMIT_WINDOW=60 # seconds
RATE_LIMIT_MAX=100
Sam now has a functional Todo list API he can point his front‑end at and start showing off.
The Tools That Make This Easier
Think of your development setup like a well‑organized kitchen – you need the right tools at hand so you don’t waste time chopping onions when you could be cooking the main dish.
Visual Studio Code with the ESLint and Prettier extensions – the chef’s knife and cutting board. VS Code’s built‑in terminal lets you stir the pot without opening another window, while ESLint catches syntax mistakes before they spoil the broth and Prettier keeps the code tidy.
Postman (free tier) – the taste‑tester. Just as you’d sample a sauce before serving, Postman lets you fire requests at each endpoint, view responses, and tweak headers without leaving the editor.
npm and npx – the pantry and instant‑cook packets. npm stores all your dependencies, and npx runs one‑off commands (like creating a new Express project) without cluttering your global install.
Swagger UI Express – the restaurant menu that updates itself. Write an OpenAPI spec and Swagger UI Express serves an interactive page where anyone can explore and try your API, just like a digital menu that lets diners see ingredients.
GitHub Codespaces – the portable kitchen. Spin up a cloud‑based VS Code instance that already has Node, npm, and the extensions you need, so you can start cooking from any laptop, any network.
These five tools cover code editing, testing, dependency management, documentation, and environment setup, giving you a streamlined workflow to build REST API Node.js projects without the usual setup headaches.
Quick Reference: REST API with Node.js Cheat Sheet
Grab this list whenever you need to spin up a new API—think of it as a quick‑order menu for your backend.
Project init: Run npm init -y, then install the core stack with npm i express dotenv cors helmet morgan. It’s like ordering the basic ingredients before cooking.
Folder layout: Create /src with subfolders routes, controllers, and middleware. Treat each folder as a separate kitchen station.
Core files:
app.js – sets up Express, middleware, and routes.
server.js – calls app.listen and reads the port.
routes/*.js – defines endpoint paths.
controllers/*.js – holds the business logic.
CRUD pattern: Map resources to the classic set—
GET /resources – list all.
GET /resources/:id – fetch one.
POST /resources – create.
PUT /resources/:id – replace.
DELETE /resources/:id – remove.
Like ordering a meal: you can view the menu, pick a dish, change it, or send it back.
Validation: Plug a Joi schema into route middleware. For example, Alex the travel blogger sends a new post; the schema checks title length, content presence, and date format before the controller runs.
Error handling: Wrap async handlers, call next(err), and let a global error middleware format the response. It’s the “Google Maps reroute” when something goes off‑track.
Security: Add helmet for headers, cors for cross‑origin rules, a rate‑limit middleware, and keep secrets in .env. Think of it as locking the kitchen door and only handing keys to trusted staff.
Docs: Generate live API docs with swagger-jsdoc + swagger-ui-express. Users can explore endpoints the way a menu lets diners see every option.
Keep this cheat sheet bookmarked and you’ll build a REST API with Node.js in no time.
What to Do Next
Grab the starter repo, fire it up, and you’ll have a working API in seconds.
Clone & run – Click the GitHub link at the top of the article, git clone it locally, then npm install followed by npm run dev. Think of this like ordering a ready‑made pizza: the dough and sauce are already prepared, you just heat it up and start eating.
Add JWT auth – Install jsonwebtoken, create a middleware that checks the token, and wrap your Todo routes with it. It’s similar to giving a valet key that only lets you open the right doors.
Deploy to the cloud – Sign up for a free tier on Render or Railway, push your code, set the same environment variables you used locally, and flip the switch for automatic HTTPS. Deploying is like packing a suitcase: you’ve already chosen what to bring, now you just zip it up and head out.
Quick tip: Keep your .env file out of version control; services provide a secure place to store those values.
Tool suggestion: Use nodemon during development so the server restarts whenever you save a file.
Cheat sheet: npm run dev → start locally; npm run build → prepare for production; npm start → run the built app.
Now you have a solid base, a layer of security, and a live endpoint you can share.
💬 Got stuck or added a cool feature? Drop a comment below—let’s discuss!
About the Author
Abdullah Sheikh is the Founder & CEO at Exteed, where he leads a team of skilled developers specializing in Web2 and Web3 applications, Custom Smart Contracts, and Blockchain solutions.
With 6+ years of experience, Abdullah has built CRMs, Crypto Wallets, DeFi Exchanges, E-Commerce Stores, HIPAA Compliant EMR Systems, and AI-powered systems that drive business efficiency and innovation.
His expertise spans Blockchain, Crypto & Tokenomics, Artificial Intelligence, and Web Applications — delivering scalable, secure, and high-performance solutions tailored to each client’s unique needs.
📧 [email protected] · 🔗 LinkedIn · 🌐 abdullah-sheikh.com
The Problem
You ask an LLM to review your code. It comes back with 30 findings. Half of them overlap. Some contradict each other. You spend more time triaging the audit output than you saved by automating it.
This is the fundamental problem with single-pass LLM code review: the model tries to check everything at once, with no clear boundaries on what it should and shouldn’t flag.
The Solution: Non-Overlapping Scopes
I solved this by splitting the audit into 6 specialized agents, each with an exclusive scope. The key is the “Does NOT Check” column:
| Auditor | Checks | Does NOT Check |
|---|---|---|
| Code Quality | Type safety, DRY, complexity, naming, dead code | Security, runtime bugs, performance |
| Bug Scanner | Null refs, error handling, race conditions, resource leaks | Security vulnerabilities, code style |
| Security | OWASP Top 10, injection, auth, secrets, CVEs | Runtime bugs, code quality |
| Performance | Slow queries, hot paths, memory, connection pools | Security, code style |
| Documentation | Missing docs, stale comments, type annotations | TODOs, debug statements |
| Environment | Config consistency, format validation, naming | Secrets (owned by Security) |
Security is the single authority for all security findings. The bug scanner handles runtime issues but explicitly avoids anything that’s a security vulnerability. This eliminates the most common source of duplicates.
The Pipeline
Step 0: Detect changed files. Works with uncommitted changes, specific commits, or explicit file lists.
Step 0.5: Auto-detect language. Detects Python, TypeScript, Go, Rust, Java, Ruby from file extensions. Also detects the test runner and linter so the pipeline can re-verify after fixing.
Step 1: 6 parallel auditors. All 6 launch simultaneously. Each gets the same file list and diff, but a different scope and checklist.
Step 2: Deduplicate. Same file:line across auditors = merge into one finding, keep the highest severity.
Step 3: Prioritize. P1 Critical (security, data corruption) = fix before deploy. P2 High (DRY violations, stale comments) = fix now. P3 Nice-to-have (cosmetic) = defer.
Step 4: Auto-fix. Implements P1 and P2 fixes with minimal diffs. No refactoring beyond what the audit found.
Step 5: Re-verify. Runs the detected test suite and linter. If tests fail, diagnoses and fixes before continuing.
Step 6: Architect review gate. A final reviewer agent assesses the full diff and gives a verdict: APPROVED, REVISE, or BLOCKED.
Step 7: Commit. Structured commit message with P1/P2/P3 breakdown and dedup stats.
The Two-Pass Workflow
One design choice that saved a lot of noise: defer cosmetic items to a separate pass.
Round 1 fixes P1 Critical and P2 High. Lists P3 items in the commit message under “Deferred.”
Round 2 (--deferred) reads the deferred list from the previous commit, checks each item is still relevant, fixes what remains, marks stale items. Commits separately.
This keeps your main PR focused on what matters, with a clean follow-up for cosmetic cleanup.
Three Ways to Use It
Claude Code (recommended)
curl -fsSL https://raw.githubusercontent.com/GiulioDER/cca-audit/main/claude-code/install.sh | bash
/audit-fix
Codex CLI
bash cca-audit.sh
Any model via OpenRouter
pip install cca-audit
cca-audit --model anthropic/claude-sonnet-4
Results
On a production codebase (Python, ~200 files), a typical run:
The non-overlapping scope design is what makes the output actionable. Every finding is unique, every fix is targeted.
Try It
MIT licensed: github.com/GiulioDER/cca-audit
Feedback welcome, especially on non-Python codebases. The language auto-detection is the newest part and I’d love to hear how it works for TypeScript, Go, and Rust projects.
LONDON — Data streaming provider Confluent today announced new capabilities in Confluent Intelligence and Confluent Cloud that streamline how real-time, artificial intelligence (AI) applications are built and secured. Confluent unifies the AI life cycle with tools developers already live in, integrating Apache Flink pipelines with dbt and introducing a fully managed Model Context Protocol (MCP) … continue reading
The post Confluent Makes it Easier to Build and Secure Real-Time AI at Scale appeared first on SD Times.
Merrin Kurian shares the architectural blueprints and organizational processes behind Intuit’s AI transformation. She explains the “fixed, flexible, free” framework used to scale GenOS across 8,000 developers, enabling 3,500+ production experiments. She discusses critical agent failure modes, the “LLM-as-a-judge” evaluation strategy, and how to build “tool-ready” APIs for the future.
By Merrin Kurian
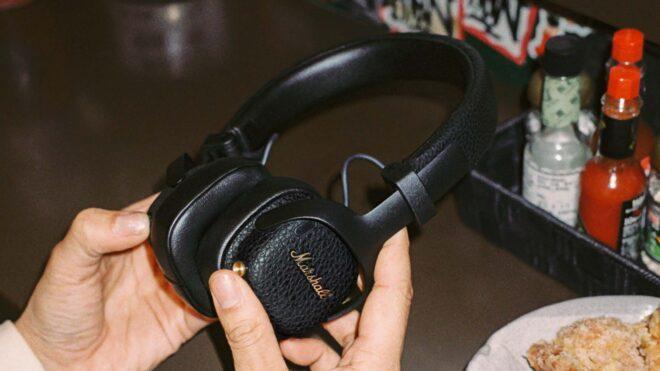
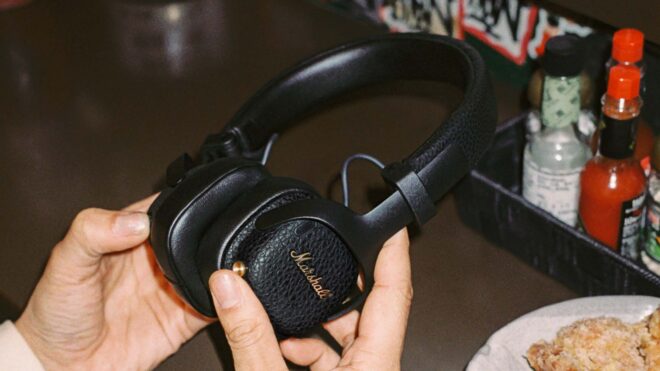 Marshall bugün “Milton A.N.C.” adını verdiği yeni kulak üstü kablosuz kulaklık modelini tanıttı. İsminin de işaret ettiği üzere ANC yani aktif gürültü engelleme özelliğine sahip olan ürün, şirketin Google ve Apple’ın “takip” ağlarına destek veren ilk modeli ve 230 dolarlık yurt dışı satış fiyatına sahip. Şirketin ikonik tasarım çizgisini benimseyen ürün, ANC ile 50 saat, ANC kapatıldığında ise tam 80 saat boyunca müzik keyfi yaşatabiliyor. Batarya değişimine izin veren üründe, 32 mm’lik dinamik sürücülere yer veriliyor. Kompakt bir seçenek olan ve taşıma kolaylığı için katlanabilir yapıda tasarlanan Milton A.N.C., Bluetooth 6.0 özelinde “LE Audio, SBC, AAC, LC3 ve LDAC” destekleriyle geliyor.
“Marshall Milton A.N.C.” kablosuz kulaklık modeli tanıtıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.