AI-103 Certification Guide (2026): Become an Azure AI App & Agent Developer

AI-102 vs AI-103 Key Differences

Artificial Intelligence has moved far beyond theory. Today, companies are not just experimenting with AI, but they are actively building AI-powered applications, automation systems, and intelligent agents. Microsoft has recognized this shift and introduced the AI-103 Certification, a next-generation credential designed for modern AI developers.

Unlike older certifications, AI-103 is built around real-world implementation, focusing on how developers can create intelligent systems using Azure.

If you are a developer looking to future-proof your career, this is the credential that defines the next generation of AI expertise. In this comprehensive guide, we will break down everything you need to know about AI-103 Certification, how it differs from its predecessor and how you can pass it to become a top-tier Azure AI developer.

What is AI-103 Certification?

The AI-103 certification is a specialized, intermediate-level credential designed for developers who design, build and deploy AI solutions using the Microsoft Azure ecosystem. Unlike earlier certifications that focused broadly on “AI services,” AI-103 is laser-focused on Apps and Agents. It validates your ability to use Azure OpenAI, Microsoft Foundry and Azure AI Search to create systems that don’t just “chat,” but actually “do.”

It focuses on:

Generative AI Integration: Implementing LLMs into real-world software.
AI Agent Frameworks: Building autonomous systems that perform multi-step tasks.
Advanced NLP: Processing and understanding human language at scale.
Computer Vision: Extracting actionable insights from visual data.

Official Microsoft Resource: https://learn.microsoft.com/en-us/training/courses/ai-103t00

AI-103 vs. AI-102: Why the Change?

For years, AI-102 was the gold standard for Azure AI engineers. However, the rapid rise of Generative AI necessitated a curriculum overhaul.

Note: AI-102 is scheduled for retirement in June 2026.

AI-102 vs AI-103 Key Differences

Breaking Down the AI-103 Modules

The certification is divided into four critical pillars. Each reflects a modern business need in the 2026 tech economy.

  • Develop Generative AI Apps in Azure
  • Develop AI Agents on Azure
  • Develop Natural Language Solutions in Azure
  • Extract Insights from Visual Data on Azure

These modules reflect how AI is actually used in modern applications, not just how it works internally.

1. Develop Generative AI Apps in Azure

This is the most important and trending module in AI-103. As companies move beyond basic ChatGPT interfaces, they need custom-built GenAI applications.

What You’ll Learn:

  • Prompt engineering techniques
  • Working with Azure OpenAI
  • Building chat-based applications
  • Retrieval-Augmented Generation (RAG)
  • Integrating AI into applications

Real-World Use Cases:

  • AI chatbots for customer support
  • Automated content generation tools
  • AI copilots for business workflows
  • Knowledge-based assistants

Why it matters: It shifts the focus from “generic AI” to “context-aware AI” that uses a business’s specific data safely. This module teaches you:
How to turn AI into usable applications

2. Develop AI Agents on Azure

This is where AI becomes autonomous and intelligent.

AI agents are systems that can:

  • Make decisions
  • Perform tasks
  • Interact with users and systems

What You’ll:

  • Learn Agent-based architecture
  • Multi-step reasoning systems
  • Workflow automation
  • Integration with APIs and services
  • Microsoft Foundry concepts

Real-World Use Cases:

  • AI assistants that complete tasks
  • Automated workflow systems
  • Intelligent business automation
  • Multi-agent collaboration systems

Why This Module Matters: Agents are the “workers” of the future, automating complex business workflows without human intervention.

AI agents are the next evolution after chatbots.

3. Develop Natural Language Solutions in Azure

Language remains the primary interface for AI. This module goes deep into how machines interpret human nuance.

What You’ll Learn:

  • Text analysis (sentiment, key phrases)
  • Named entity recognition
  • Language understanding
  • Conversational AI Speech-to-text and text-to-speech

Real-World Use Cases:

  • Chatbots and virtual assistants
  • Customer feedback analysis
  • Voice-enabled applications
  • Document processing systems

Why This Module Matters: Most business data is in text form. This module helps you:
Extract meaning and insights from human language at scale

4. Extract Insights from Visual Data on Azure

This module focuses on computer vision, enabling machines to understand images and videos.

What You’ll Learn:

  • Image recognition
  • Object detection
  • Face detection
  • OCR (text extraction from images)
  • Video analysis

Real-World Use Cases:

  • Security and surveillance systems
  • Document digitization
  • Retail analytics
  • Medical imaging solutions

Why This Module Matters: Visual data is growing rapidly. This module enables you to:
Build systems that can see and interpret the world

Why AI-103 Matters in 2026

The AI landscape has evolved rapidly. Traditional AI roles are shifting toward:

AI applications Agent-based architectures Multi-step reasoning systems

AI-103 is built specifically for this transformation.

Key reasons why AI-103 is important

AI-102 is retiring in June 2026, AI-103 aligns with Microsoft’s future AI roadmap Focus on generative AI + AI agents High demand in enterprise AI roles

In simple terms:
If AI-900 is the foundation, AI-103 is the real-world builder certification.

Who Should Take This Exam?

AI-103 isn’t for the absolute beginner. It is designed for:

  • Software Developers who want to specialize in AI.
  • Cloud Architects looking to integrate AI agents into existing Azure infrastructures.
  • Data Engineers transitioning into AI application development.

Prerequisites:
Before diving into AI-103, you should have a solid grasp of Python or C#, an understanding of REST APIs, and a basic knowledge of Azure Fundamentals.

How to Prepare: A Strategic Learning Path

To succeed in AI-103, you need a structured approach. At SkillTech Club, we recommend the following 3-step path to ensure you don’t just pass the exam, but actually master the technology.

Step 1: The Fundamentals (AI-901)

If you are new to the ecosystem, do not skip the basics. Understanding the ethical implications and core services of Azure AI is vital. Start AI-901 Certification to understand AI in Azure

Step 2: The Core Engineering Logic (AI-102)

While AI-103 is the near future, AI-102 Certification provides the “engineering muscles” needed to understand how Azure handles data and service deployment. Taking AI-102 Certification first provides the bridge between fundamentals and advanced agent development.

Step 3: Hands-on Implementation

For AI-103, theory isn’t enough. You must build.

Set up an Azure Sandbox: Experiment with the Azure OpenAI Studio.
Build a RAG Pattern: Use Azure AI Search to index a PDF and query it via an LLM.
Practice with SDKs: Familiarize yourself with the Python SDK for Azure AI services.

Career Opportunities: Why AI-103 is Your Best Investment

The demand for “AI Developers” is skyrocketing, but the market is becoming crowded with people who only know how to write prompts. The AI-103 certification sets you apart by proving you can build the infrastructure behind the prompt.

Roles you can land with AI-103:

AI Applications Developer: Creating bespoke AI tools for enterprise clients.
AI Solutions Architect: Designing the flow of data between users, agents and databases.
Generative AI Engineer: Specializing in LLM fine-tuning and RAG implementation.
Automation Specialist: Building multi-agent systems that handle end-to-end business processes.

In 2026, the salary gap between a standard “Cloud Developer” and an “Azure AI App & Agent Developer” is expected to widen significantly, with AI specialists commanding a 25-40% premium.

Final Thoughts

The AI-103 certification represents a major pivot in the tech industry. We are moving away from static models and toward dynamic, autonomous agents that can think, reason and act within the Azure cloud.

By earning your AI-103 badge, you aren’t just adding a badge to your LinkedIn profile, but you are mastering the tools that will build the next decade of software. Whether it’s developing generative AI apps or architecting multi-agent systems, AI-103 is your roadmap to the top of the tech stack.

Are you ready to build the future? Start your journey today with SkillTech Club and become the developer the world is looking for in 2026.
Hindsight Turned Repeat Commenters Into Recognizable People

I was building EchoEngage an AI-driven comment responder, and ran into a frustrating problem: every time a user posted again, the bot treated them like a stranger. It would give the same generic reply to “John” on day one and day five, even though we’d “talked” before. My bot was effectively stateless – it had no memory of past interactions – so it kept acting like each comment was the first. I knew I needed a way to make the AI “remember” people between comments.

It turns out the solution was a persistent memory store. I integrated Hindsight (the memory library by Vectorize) so that each user gets their own memory bank. In practice, that meant calling Hindsight’s API whenever a comment arrives: create or ensure a memory bank for this user, then retain the new comment in that bank. Later, when replying, I use recall (and even reflect) to pull up relevant past context from that user’s memory. The result is that the agent now recognizes repeat commenters and can personalize replies based on what it “knows” about them.

EchoEngage’s backend is a Python service (FastAPI) that listens for new comments. When a comment arrives, I first do something like:

def ensure_user_bank(user_id: str, user_name: str):

# Create or update the Hindsight memory bank for this user

    http_requests.put(
        f"{HINDSIGHT_BASE}/banks/{user_id}",
        json={"mission": f"Personal memory for {user_name}. Track conversation history and user preferences."},
        headers=get_hindsight_headers()
    )

async def handle_comment(user_id: str, user_name: str, text: str) -> str:

# 1. Make sure the user has a memory bank

    ensure_user_bank(user_id, user_name)

# 2. Store the new comment in their memory

    await httpx.post(
        f"{HINDSIGHT_BASE}/banks/{user_id}/memories",
        json={"items": [{"content": text}]},
        headers=get_hindsight_headers()
    )

# 3. Recall any relevant context from memory

    recall_resp = await httpx.post(
        f"{HINDSIGHT_BASE}/banks/{user_id}/memories/recall",
        json={"query": text, "top_k": 5},
        headers=get_hindsight_headers()
    )
    memories = recall_resp.json().get("results", [])
    context = "n".join(item.get("text", "") for item in memories)

# 4. Generate a reply, including recalled context

    prompt = f"User said: {text}nnConversation history:n{context}nnHow should I reply?"
    response = await openai.ChatCompletion.acreate(model="gpt-4o", messages=[{"role": "user", "content": prompt}])
    return response.choices[0].message.content

This pseudocode shows the idea: every time a comment comes in, I call /banks/{id}/memories to retain it, then recall it when crafting the next answer. In effect, each user has a dedicated Hindsight memory bank (with a mission describing the conversation’s context). This follows Vectorize’s model of “retain, recall, reflect” for AI memory.

The result is that the bot is no longer “blank slate” for returning users. It learns to say things like “Nice to hear from you again, [Alice]! Last time you mentioned working on your Django project – how’s that going?” because the memory contains Alice’s past comments. Without memory, the agent would have resorted to something like “This is our first interaction” every time. In fact, before adding Hindsight, I saw exactly that: my AI would greet every comment like it was brand new. Once I added memory, it started referencing past points.

For example, consider a frequent commenter “Raj”. Before Hindsight, Raj asks about async programming and the AI launches into a generic explanation as if it’s Raj’s first question. After adding memory, the AI says: “Welcome back, Raj. Last time you were curious about async code in Python and how it affects I/O. Based on our previous conversation, have you tried using asyncio.gather as well?”. The change was striking and confirmed exactly what the Vectorize team points out: “AI agents forget everything between sessions. Every conversation starts from zero — no context about who you are or what’s been discussed”. With Hindsight the agent finally remembers.

Behind the scenes, I also used Cascadeflow to manage model routing and cost. The system is simple: for each reply, I run the prompt through Cascadeflow, which tries a cheaper model first (like a small GPT-3.5 or open-source model), and only escalates to a bigger model if needed. In other words, not every comment requires my beefiest LLM. As one writeup of Cascadeflow puts it, it’s a “runtime intelligence layer” that “routes queries to the cheapest model that can handle them and only escalates when quality requires it.”.

I turned on Cascadeflow in “enforce” mode, so it actually switches models instead of just observing. My code for generating replies became something like:

import cascadeflow as cf

cf.init(mode="enforce")

# enable routing/enforcement

async def generate_reply_with_cascade(user_id: str, prompt: str) -> str:
    with cf.run() as session:
        response = await openai.ChatCompletion.acreate(
            model="gpt-4o", messages=[{"role": "user", "content": prompt}]
        )
        print(f"Used model: {session.trace()[-1]['model']} at cost ${session.trace()[-1]['cost_increment']:.5f}")
    return response.choices[0].message.content

In practice, this meant most comments were answered by the smaller model, and only unusual or complex ones got routed to the largest model. This cut my inference costs by a huge factor. The author of a similar system reports “90% cost reduction vs GPT-4 baseline” with Cascadeflow. I saw comparable savings: simple Q&A went out on cheap models, and Cascadeflow only “pays up” when something seems too hard. The decision traces (logged via session.trace()) became invaluable for debugging: I could see exactly why it chose to escalate on a particular prompt.

The overall architecture is straightforward:
A comment comes in, I update the user’s Hindsight memory, then I recall relevant past comments and include that context in the prompt. Then I feed the prompt into Cascadeflow, which manages which LLM to call. The full system ends up looking like: comment → memory bank update + recall → build context-aware prompt → cascadeflow agent → send reply.

This combination of memory plus cascadeflow made EchoEngage behave in a much more human way. To illustrate, here’s a before/after scenario (paraphrased from one I observed):

  • Without Hindsight: A repeat commenter asks another question, and the agent responds, “It looks like this might be your first question, so let’s start with the basics…”. It had no recollection of even dozens of previous comments.
  • With Hindsight: The agent replies, “Good to see you again! Last time you were struggling with concurrency issues in your Node app. Based on that, I’d suggest trying these specific debugging steps…”. It clearly remembered details from earlier chats (like who the commenter is, their project, what problems they had).

Even more impressively, Hindsight’s reflect operation lets the agent summarize a user’s history. In a demo, I fed the agent a user’s entire comment history and asked, “What are the most important things I’ve told you so far?”. The AI, with Hindsight’s help, spit out a concise list of facts (just like a salesperson’s call prep note). This makes the bot feel far more personal.

Technology Stack
Agent Framework: LangGraph (Python)
Memory: Hindsight by Vectorize (per-follower memory banks)
Model Routing: CascadeFlow (complexity-based routing with cost tracking)
LLMs: Groq (Qwen 32B for simple, GPT-OSS 120B for complex)
Backend: FastAPI + Python
Frontend: React + Vite + Tailwind CSS
**Design: **Dark theme, glassmorphism, animated score rings

Lessons learned:
Turning on memory was transformative, but I also picked up a few best practices along the way:

  • Treat the user as an entity. I gave each commenter a unique bank key (I used their user ID or username). That simple decision meant “Alice” on Monday and “Alice” on Friday share the same history. As Vectorize’s agent memory guide notes, without memory “every interaction [is] treated as the first,” which limits personalization. Identifying users lets the agent accumulate context over time.
  • Dual-write memory. In my prototype I noticed failures when Hindsight Cloud was unreachable. I solved this by also saving each comment to a local database as a fallback. In other words, log comments both to Hindsight and locally. That way, the agent is “never blind” – if the cloud memory is down, it can still recall from the local store. (The author of DealMind AI did the same for sales calls.) This redundancy means a network glitch won’t erase a user’s history.
  • Context + brevity. I used Hindsight recall to supply context, but had to keep prompts short. I experimented with different ways to include memory (raw memory items vs. a condensed reflection). Ultimately, prepending just the last few relevant comments worked best. Too much context in the prompt actually hurt performance, so I let Hindsight’s reflect/summarize do the heavy lifting instead of pasting entire transcripts.
  • Cost gating with Cascadeflow. Introducing cascadeflow early (observe mode) helped me understand how often the big model was actually needed. It turned out 95% of queries were cheap enough. When I finally switched to enforce mode, I could enforce budgets or stop conditions as needed. Cascadeflow treated model selection as part of the agent’s logic, so I never had to sprinkle hard-coded if statements around LLM calls. The code became simpler and more maintainable.
  • Don’t lie about memory. At first I was tempted to pretend the agent had memory by stuffing recent replies into the prompt manually. That quickly broke: the agent would contradict itself or drop details. Using a structured memory system like Hindsight was far more reliable. Hindsight ensures memories are timestamped and consolidated, so the agent can reason (“She asked for that resource but never got it”) instead of hallucinating.
  • Agent-centric design. Building EchoEngage drove home that AI systems are systems: I had to handle failover, throttling, model costs, etc. For example, I added content filtering hooks before sending prompts. But throughout, Cascadeflow and Hindsight provided transparency. I could inspect the cascadeflow decision trace to see “why” a smaller model was enough, and check Hindsight’s logs to see exactly what got stored. This observability is crucial in production (as Cascadeflow’s docs also emphasize in their observe mode guide).

In the end, EchoEngage became far more satisfying to use.
It felt like a small community where the bot actually knows members by name and their past comments. Adding memory was non-negotiable. As one engineer put it, agent memory lets AI “accumulate knowledge from previous engagements” instead of starting fresh each time. And by combining it with smart routing (Cascadeflow), I kept costs in check. The project still has room to grow, but at least now when a user says “you gave me a great answer last week,” the bot really can remember the context and say “I’m glad it helped!” instead of “Nice to meet you!”

Reactive Agents, Typed Event Handlers, and Agent Swarms: What’s New in Mozaik

Agent swarms — multiple reactive agents collaborating in one agentic environment

When we released Mozaik v3, we introduced an event-based architecture where participants emit, observe, and react to typed context items inside a shared agentic environment. Since then, the framework has kept moving — and the way we think and talk about it has moved with it.

This post is a tour of what’s new. The headline shift is conceptual: Mozaik is now framed around reactive agents — collaborative agents that adapt to their environment and to each other in real time. Underneath that frame, the API has gotten smaller, clearer, and easier to read.

From Non-Blocking to Reactive

Mozaik agents have always been non-blocking. That’s still true — capability methods stream events as they’re produced, so a slow inference or tool call never holds up other participants. But “non-blocking” describes a property, not a way of thinking.

The way we now think about Mozaik agents is reactive: an agent declares which events it cares about and reacts to them as they arrive — messages from humans, function calls from its own model, reasoning traces from a peer agent, or tool outputs from somewhere else in the environment. Behavior emerges from how agents react, not from a central controller deciding whose turn it is.

A reactive agent is event-driven, collaborative, and adapts to its environment and to other agents in real time.

This shift in framing pays off in design. Once an agent is a thing that reacts, adding behavior to a system stops being about editing a pipeline and becomes about joining another participant.

Typed Event Handlers

The biggest API change since 3.0 is on the participant side. In the original release, a participant exposed a single intercept point: onContextItem(source, item). You looked at the item, decided whether it came from you or someone else, and branched accordingly.

That worked, but it pushed a lot of dispatch logic into every agent. So we replaced the single intercept with a set of typed handlers, one per event kind:

  • onMessage
  • onFunctionCall
  • onFunctionCallOutput
  • onReasoning
  • onModelMessage

Each handler defaults to a no-op in the base class, so a reactive agent only writes the ones it actually cares about. The result is shorter, more declarative code — a reactive agent reads like a list of “when this happens, I do that,” not like a switch statement.

Here is a full reactive agent built on top of BaseAgentParticipant. It records incoming messages, runs inference, executes its own tool calls, and keeps its local context in sync with what the model produces — all by overriding the handlers it cares about:

// reactive-agent.ts
import {
  BaseAgentParticipant,
  UserMessageItem,
  FunctionCallItem,
  FunctionCallOutputItem,
  ReasoningItem,
  ModelMessageItem,
  AgenticEnvironment,
  ModelContext,
  GenerativeModel,
  InputStream,
  InferenceRunner,
  FunctionCallRunner,
} from "@mozaik-ai/core"

export class ReactiveAgent extends BaseAgentParticipant {
  constructor(
    inputSource: InputStream,
    inferenceRunner: InferenceRunner,
    functionCallRunner: FunctionCallRunner,
    private readonly environment: AgenticEnvironment,
    private readonly context: ModelContext,
    private readonly model: GenerativeModel,
  ) {
    super(inputSource, inferenceRunner, functionCallRunner)
  }

  // A message from a human (or any other participant) — record it and think.
  async onMessage(message: string): Promise<void> {
    this.context.addContextItem(UserMessageItem.create(message))
    this.runInference(this.environment, this.context, this.model)
  }

  // The agent just produced a function call — execute it.
  async onFunctionCall(item: FunctionCallItem): Promise<void> {
    this.context.addContextItem(item)
    this.executeFunctionCall(this.environment, item)
  }

  // The tool just produced an output — feed it back and run inference again.
  async onFunctionCallOutput(item: FunctionCallOutputItem): Promise<void> {
    this.context.addContextItem(item)
    this.runInference(this.environment, this.context, this.model)
  }

  // Keep the local context in sync with model-emitted reasoning and replies.
  async onReasoning(item: ReasoningItem): Promise<void> {
    this.context.addContextItem(item)
  }

  async onModelMessage(item: ModelMessageItem): Promise<void> {
    this.context.addContextItem(item)
  }
}

For comparison, the old style looked like this:

// Before: one handler, manual dispatch
async onContextItem(source: Participant, item: ContextItem): Promise<void> {
  if (source === this) return

  this.context.addContextItem(item)

  if (item instanceof UserMessageItem) {
    this.runInference(this.environment, this.context, this.model)
    return
  }

  if (item instanceof FunctionCallItem) {
    this.executeFunctionCall(this.environment, item)
    return
  }
}

The Self vs. External Split

For every typed handler, there are two variants: a self handler that fires when this participant emits the event, and an external handler (prefixed with onExternal) that fires when another participant emits it.

Self (your emissions) External (everyone else)
onFunctionCall onExternalFunctionCall
onFunctionCallOutput onExternalFunctionCallOutput
onReasoning onExternalReasoning
onModelMessage onExternalModelMessage

The practical effect: a reactive agent can encode “act on my own outputs” separately from “observe others” — no more manual source === this checks.

  • Want to build a critic that reviews a peer agent’s answers? Override onExternalModelMessage.
  • Want to feed your model’s own tool calls back into a runner? Override onFunctionCall.

The two concerns stop bleeding into each other.

As a concrete example, here is a passive participant that only listens to external events. It does not run inference and does not execute tools — it just watches what other participants emit and logs it. Drop it into any environment and you have a live transcript:

// transcript-logger.ts
import {
  Participant,
  FunctionCallItem,
  FunctionCallOutputItem,
  ReasoningItem,
  ModelMessageItem,
} from "@mozaik-ai/core"

export class TranscriptLogger extends Participant {
  async onMessage(message: string): Promise<void> {
    console.log("[message]", message)
  }

  async onExternalFunctionCall(
    source: Participant,
    item: FunctionCallItem,
  ): Promise<void> {
    console.log(`[${source.constructor.name}] function_call`, item.toJSON())
  }

  async onExternalFunctionCallOutput(
    source: Participant,
    item: FunctionCallOutputItem,
  ): Promise<void> {
    console.log(
      `[${source.constructor.name}] function_call_output`,
      item.toJSON(),
    )
  }

  async onExternalReasoning(
    source: Participant,
    item: ReasoningItem,
  ): Promise<void> {
    console.log(`[${source.constructor.name}] reasoning`, item.toJSON())
  }

  async onExternalModelMessage(
    source: Participant,
    item: ModelMessageItem,
  ): Promise<void> {
    console.log(`[${source.constructor.name}] model_message`, item.toJSON())
  }
}

Plain Messages on the Bus

Conversational text used to flow through the same context-item pipeline as everything else. It worked, but it was heavier than it needed to be. Now there are two clean lanes:

  1. Messages — plain strings, delivered via onMessage(message: string). Use them for what a human types, what one agent says to another, and any other free-form text.
  2. ContextItems — typed model internals (function calls, function call outputs, reasoning items, model messages), delivered via their dedicated handlers.

The participant side mirrors this: the old InputItemSource has become InputStream, an async iterable of strings. Each yielded string fans out via onMessage to every other participant. Inference and tool runners still produce typed ContextItems, exactly as before.

The benefit is mostly clarity. When you read a reactive agent now, you can tell at a glance whether a handler is reacting to “someone said something” or to “the model produced a tool call.”

import { InputStream } from "@mozaik-ai/core"

// Async iterable of plain strings — each yield becomes onMessage for peers.
async function* humanInput(): InputStream {
  yield "Add rate limiting to all API endpoints"
  yield "Focus on the NestJS backend first"
}

A Bigger Model Lineup

The default OpenAI provider now ships a wider model lineup. In addition to Gpt54, Gpt54Mini, and Gpt54Nano, there is now Gpt55. Same OpenAIResponses runtime, same OpenResponses-aligned types — pick the model that fits the job.

import { Gpt55, Gpt54Mini } from "@mozaik-ai/core"

// Heavier reasoning for planning; lighter model for review passes.
const planner = new Gpt55()
const reviewer = new Gpt54Mini()

From One Agent to a Swarm

The reactive frame really earns its keep when more than one agent shares an environment. We’ve started calling these collaborative groups agent swarms: a handful of focused reactive agents — planner, executors, reviewer, and observers — all joining one AgenticEnvironment and reacting to each other’s events.

Agent swarms — multiple reactive agents collaborating in one agentic environment

Agent swarms — multiple reactive agents collaborating in one agentic environment

The clearest production example is baro, a Claude agent orchestrator built on Mozaik. Ten specialized participants — planner, executors, reviewer, fixer, librarian, auditor, and more — work fully concurrently on the same goal, like a team collaborating in real time instead of a single agent doing everything alone.

Adding a new role to a swarm doesn’t mean editing a central controller. It means writing one more reactive agent and join()ing it to the environment. Everything else keeps working.

import { AgenticEnvironment } from "@mozaik-ai/core"

const environment = new AgenticEnvironment()

planner.join(environment)
executor.join(environment)
critic.join(environment)
new TranscriptLogger().join(environment)

environment.start()

Composing Intelligence

Each of these changes is small on its own. Together, they shift Mozaik further toward what we wanted from the start: a framework where intelligent behavior is something you compose, not something you orchestrate.

Change What it unlocks
Reactive agents Behavior from event handlers, not a central run() loop
Typed handlers Readable “when X, do Y” agents without dispatch boilerplate
Self vs. external Critics, observers, and actors coexist without source === this
Plain messages Conversational text separate from model-internal ContextItems
Agent swarms Many focused agents on one bus — see baro

Reactive agents make the building block explicit. Typed handlers make each agent easier to read. The self vs. external split keeps intent obvious. Plain messages keep the conversational lane clean. And the swarm pattern shows what falls out the other side: groups of agents that adapt to their environment and to each other in real time.

Get started

npm install @mozaik-ai/core

Star on GitHub: github.com/jigjoy-ai/mozaik

Related: Mozaik 3.0 — Structured Context & the Agentic Environment ·

Read the full article on JigJoy: jigjoy.ai/blog/mozaik-reactive-agents

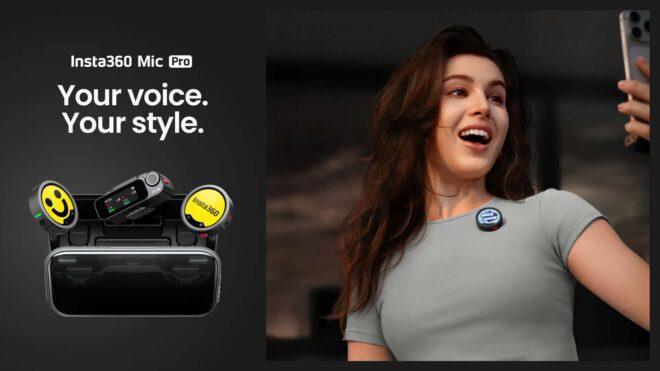
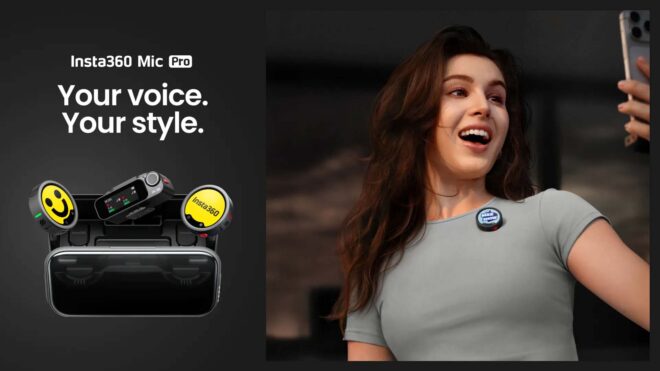
E-Ink ekranlı mikrofon çözümü “Insta360 Mic Pro” tanıtıldı

E-Ink ekranlı Insta360 Mic Pro tanıtıldı

E-Ink ekranlı Insta360 Mic Pro tanıtıldıÖn gösterimi NAB 2026 fuarında yapılan “Insta360 Mic Pro” kablosuz mikrofon modeli bugün resmi olarak tanıtıldı. E-Ink ekranla donatılmış olmasıyla fark yaratan yeni kablosuz mikrofon çözümü, bu ekranda farklı logolar ya da tasarımlar gösterebiliyor ve Bluetooth temelli “Direct Connect” teknolojisiyle Insta360’ın kameralarına herhangi bir adaptöre ihtiyaç olmadan bağlanabiliyor. 330 dolarlık üst pakette toplam dört parçadan oluşan model, her ünitede üç farklı mikrofon yer aldığından değişen şartlara daha iyi uyum sağlayabiliyor (omnidirectional, cardioid ve figure-8 kutup/kayıt desenleri destekleniyor). Her üniteye yaklaşık 45 saatlik dahili 32-bit mono kayda imkan tanıyan 32 GB’lık depolama alanı ekleyen şirket, ürünün özel “NPU” çipi aracılığıyla yapay zeka destekli gürültü engelleme sunduğunu aktarıyor. Özel alıcı ile açık alanlarda 400 metreye varan kullanım menziline sahip olduğu açıklanan Mic Pro, şarj kutusuyla birlikte toplam 30 saatlik batarya ömrü vadediyor.

E-Ink ekranlı mikrofon çözümü “Insta360 Mic Pro” tanıtıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

The Log Management Cost Trap: Part III — Search

The small file problem illustrated

Authored by Benoit Gaudin

In Part I (Ingestion) and Part II (Storage) of this series, I explored the challenges of designing, running, and managing a centralised log management solution. In Part III, I’ll focus on search.

The Competing Requirements of Log Search

Log data search has two distinct use cases with fundamentally different requirements.

Real-time troubleshooting — when a system outage occurs, engineers need visibility into what caused the issue immediately. Log data must be searchable almost as soon as it’s generated. This imposes a hard constraint: batch windows must be short. And short batch windows tend to produce small files.

Large-scale historical analysis — analyzing web or CDN access logs to identify patterns in API usage, track slowly degrading performance trends, or audit activity over weeks or months. Here, data freshness is irrelevant. What matters is the ability to efficiently scan large datasets.

These two use cases create a direct tension. Making data available quickly often means processing small batches and creating many small files — which severely degrades performance when running queries across long time ranges. This is the classic small file problem.

The small file problem illustrated

A good log management solution must balance both: newly ingested data searchable immediately, stored in a format that also supports efficient querying over time.

Performant and Cost-Effective Search

As covered in Part II, the right data format and storage strategy are the foundation. Key techniques include indexing, Bloom filtering, and data partitioning.

Needle-in-a-haystack queries

Indexing and Bloom filtering shine when searching for data that appears infrequently across a large time range — for example, finding a specific trace_id across several terabytes of log data. As explained in Why is Bronto so fast at searching logs, well-designed indexing and Bloom filtering can dramatically reduce the volume of data scanned, narrowing the dataset to a much smaller subset more likely to contain the target value.

Full-scan analytical queries

Some queries can’t be narrowed. If you want the maximum response time per endpoint over the past few months, every log entry must be examined — there’s no rare value to isolate, no filter to push down, no partition to skip.

Pre-aggregated summaries could help if you know in advance exactly how users will slice their data. But general-purpose log management systems can’t predict every analytical angle users will need. Full dataset scans are unavoidable.

Brute force search at scale

For these cases, the only viable solution is brute-force compute: massive parallelism and high-performance processing to deliver results even when every record must be touched.

Bronto’s approach: AWS Lambda for bursty workloads

To support demanding full-scan queries while keeping costs in check, Bronto uses AWS Lambda functions. Lambda enables high concurrency — large volumes of data stored in S3 can be processed in parallel, on demand, with no infrastructure to provision or manage in advance.

The cost model is key: you only pay for compute time used. Even when running many functions concurrently, short execution times keep overall cost low. This makes it ideal for bursty, unpredictable workloads.

That said, Lambda isn’t always the right tool. When query volume consistently exceeds a certain threshold, sustained compute options like AWS EC2 become more cost-effective. The right architecture uses both: Lambda for bursts, EC2 for the baseline.

High Cardinality

Log data frequently contains high-cardinality fields — client IP addresses, trace IDs, user IDs. Queries over these fields (e.g. counting unique IP addresses across a large dataset) can lead to slow performance, high memory consumption, and a poor user experience.

A naive solution is to cap the number of unique values the system handles — but that means users simply can’t get value from their data beyond the cap.

A better approach: compute exact results up to a certain cardinality threshold, then switch to approximations when cardinality genuinely becomes too large to handle exactly. Several probabilistic data structures make this practical:

This approach keeps resource consumption bounded while still giving users meaningful, actionable insights from high-cardinality data.

Conclusion

This wraps up the three-part Log Management Cost Trap series. Across ingestion, storage, and search, the same theme emerges: design decisions in one layer constrain and shape what’s possible in the others. Trade-offs are unavoidable, and navigating toward an optimal solution requires deep experience across all three.

Bronto brings 150+ years of combined experience in log management at scale — and implements that experience into a platform designed to be cost-efficient, high-performance, and ready for logging in the AI era.

See Bronto in Action

Syncing GitLab Projects to AWX — My DevOps Journey By Sireesha

If you’ve been following my blog series, you already know I’ve set up Ansible AWX on Kubernetes using Helm. Now the next logical step for me was — how do I actually get my playbooks into AWX without manually uploading them every time?
The answer is GitLab. In this blog I’ll walk through how I installed GitLab on a VM, pushed my Ansible playbooks to it, and then synced that repo into AWX as a project — in two ways:

Using an SSH key (SCM Private Key) — this is what I actually use in production
Using a Personal Access Token over HTTP — good for quick lab setups

Let’s get into it.

What We’re Building Here
The flow looks like this:

Ansible Server → Push Playbooks → GitLab (self-hosted VM) → Sync → AWX Project & Templates
Once this is set up, every time I update a playbook and push to GitLab, AWX syncs and picks up the latest version automatically. That’s the real power of this setup.

Part 1 — Installing GitLab on a VM
I installed GitLab on a separate Ubuntu 22.04 VM. Here’s exactly what I ran:
Step 1 — Install Dependencies
sudo apt update
sudo apt install -y curl openssh-server ca-certificates tzdata perl
Step 2 — Add GitLab Repository and Install
curl https://packages.gitlab.com/install/repositories/gitlab/gitlab-ce/script.deb.sh | sudo bash
sudo apt install gitlab-ce
Step 3 — Configure GitLab
sudo vi /etc/gitlab/gitlab.rb
Update the external URL to your VM IP:
rubyexternal_url ‘http://10.*.*.**‘
Then reconfigure:
sudo gitlab-ctl reconfigure
Step 4 — Get the Initial Root Password
sudo cat /etc/gitlab/initial_root_password
Open http://10.*.*.* in your browser → log in with root and the password above.

Tip: Change your root password immediately after first login — User Settings → Password.

Part 2. Creating a repo and pushing playbooks

Inside GitLab, I created a new blank project called:

ansibleawx

Set it to private and moved on.

On my Ansible server, I configured Git:

git config --global user.name "Sireesha"
git config --global user.email "[email protected]"

Then inside my playbook directory:

cd /etc/ansible

git init
git remote add origin http://ip/ansibleawx.git
git add .
git commit -m "Initial commit - adding ansible playbooks"
git branch -M patches
git push -u origin patches

I’m using a patches branch here because that’s what I decided to track in AWX later.

That part matters more than it looks — branch mismatches will bite you.

Part3. Connecting AWX to GitLab using SSH (production way)

This is the setup I actually use properly. It’s more secure and avoids token expiry issues.

Generate SSH key (on AWX side)
ssh-keygen -t rsa -b 4096 -C "awx@ansible"

Then grab the public key:

cat ~/.ssh/id_rsa.pub

Add it to GitLab

GitLab → User Settings → SSH Keys → paste key → save

Nothing complicated here.

Create AWX credential

In AWX:

Credentials → Add

Name: gitlab-cred
Type: Source Control
Username: root
SCM Private Key: paste private key (~/.ssh/id_rsa)

Click Save.

Create AWX project

AWX → Projects → Add

Name: AnsibleAWX
SCM Type: Git
URL: http:///ansibleawx.git
Branch: patches
Credential: gitlab-cred

Once saved, AWX syncs automatically.

When it turns green, you’re good.

That’s the moment everything starts clicking.

This is exactly the gitlab-cred credential I have set up — you can see from the screenshot it shows Credential Type: Source Control and SCM Private Key: Encrypted.

Part4. Alternative: HTTP with Personal Access Token

This is the quicker setup I used in a lab environment.

Create token in GitLab

GitLab → Settings → Access Tokens

Scope: read_repository

Copy it (you only see it once).

Add to AWX

Credentials → Add

Name: gitlab-http-cred
Username: root
Password:

Save.

Create project

Same as before, but use this credential instead.

It works fine — just not as clean or durable as SSH.

Part 5 — Creating Job Templates in AWX

Once the project sync works, playbooks automatically appear in AWX.

So I created a simple job template:

AWX → Templates → Add

  • Name: Linux Server Setup
  • Job Type: Run
  • Inventory: your inventory
  • Project: AnsibleAWX
  • Playbook: select from dropdown
  • Credentials: your machine credentials

Save and launch.

At this point, AWX is basically running whatever is in GitLab.

No file copying. No manual updates.

Errors I Hit Along the Way
Error 1 — Git Push Branch Mismatch

error: src refspec main does not match any
Fix — rename the branch to match what you set in AWX:
git branch -M patches
git push -u origin patches

Error 2 — AWX Sync Failed on SSH Host Key

Host key verification failed
Fix — in your AWX Project settings under Source Control Options, tick:
✅ Disregard Host Checks
Error 3 — Playbook Dropdown Empty in Job Template

After syncing, the playbook dropdown was empty when creating a job template
.
Fix — go back to your Project → hit the Sync button (circular arrow) → wait for green → go back to template. Playbooks will appear.

Before this, updating a playbook meant manually copying files and hoping AWX had the latest version. Now my workflow is:

Edit playbook → git push to patches branch → AWX syncs → Launch job

Everything is version controlled, auditable, and consistent.

Drop your questions in the comments — happy to help!
— Sireesha

String in Java

The String in Java is a sequence of characters used to store and manipulate text.It is one of the most used classes in Java.

  • Each character in a string is stored using 16-bit Unicode (UTF-16) encoding.
  • Strings are immutable, meaning their value cannot be changed after creation.

Example

String str = "Hello";

str.concat(" World");

System.out.println(str);

Output
Hello

  • Because concat() creates a new string instead of modifying the old one.

Ways to Create String

1. String Literal

Example:1

public class Demo {
    public static void main(String[] args) {

        String name = "Harini";

        System.out.println(name);
    }
}

Output
Harini

Why is this called String Literal?

String name = "Harini";
  • “Harini” → String literal
  • It is directly written inside double quotes.
  • Java stores it inside the String Constant Pool.

Example: 2

public class Test {
    public static void main(String[] args) {

        String a = "Java";
        String b = "Java";

        System.out.println(a == b);
    }
}

Output:
true

  • Because both a and b point to the same object in the String pool.

String Pool

  • Java stores string literals in a special memory area called the String Constant Pool.

2. Using new Keyword

Example

public class Demo {
    public static void main(String[] args) {

        String s1 = new String("Java");
        String s2 = new String("Java");

        System.out.println(s1);
        System.out.println(s2);

        System.out.println(s1 == s2);
        System.out.println(s1.equals(s2));
    }
}

Output
Java
Java
false
true

Creating String using new

String s1 = new String("Java");
  • new keyword creates a new object
  • Object is created in heap memory
  • Even if “Java” already exists, Java creates another new object

Same for:

String s2 = new String("Java");

So s1 and s2 are different objects.

Why s1 == s2 is false?

System.out.println(s1 == s2);

Output:

false

Because:

  • == compares memory address/reference
  • s1 and s2 are different objects in memory

Why s1.equals(s2) is true?

System.out.println(s1.equals(s2));

Output:

true

Because:

  • equals() compares actual content
  • Both strings contain “Java”

Memory Representation

  • String s1 = new String(“Java”);
  • String s2 = new String(“Java”);

Heap Memory

s1 —> “Java” (Object 1)

s2 —> “Java” (Object 2)

Two separate objects are created.

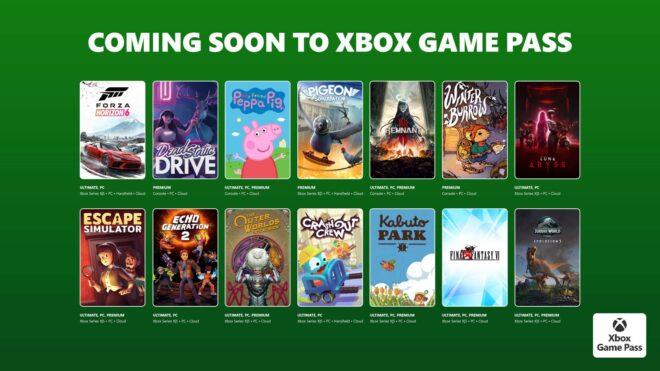
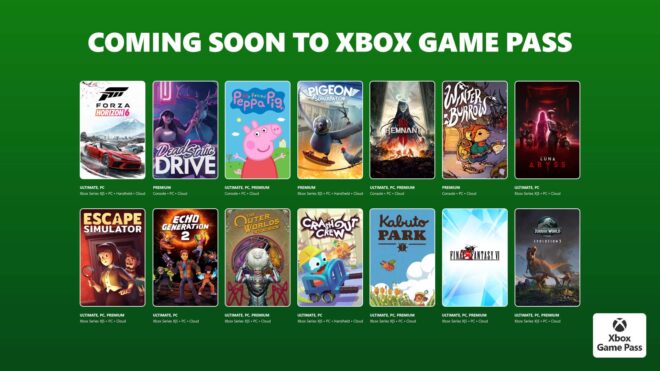
XBOX Game Pass’e eklenen ve eklenecek yeni oyunlar açıklandı (19 Mayıs)

XBOX Game Pass’e eklenen ve eklenecek yeni oyunlar açıklandı (19 Mayıs)

XBOX Game Pass’e eklenen ve eklenecek yeni oyunlar açıklandı (19 Mayıs)Microsoft bugün resmi “XBOX Wire” sayfası üzerinden “XBOX Game Pass” kütüphanesine yeni eklenen ve önümüzdeki günlerde eklenecek oyunları açıkladı: -Forza Horizon 6 (Bulut, XBOX Series X|S, El Konsolu ve PC) – 19 Mayıs -Dead Static Drive (Bulut, Konsol ve PC) – 20 Mayıs -My Friend Peppa Pig (Bulut, Konsol ve PC) – 20 Mayıs -Pigeon Simulator (Bulut, XBOX Series X|S, El Konsolu ve PC) – 20 Mayıs -Remnant II (Bulut, Konsol ve PC) – 20 Mayıs -Winter Burrow (Bulut, Konsol ve PC) – 20 Mayıs -Luna Abyss (Bulut, XBOX Series X|S ve PC) – 21 Mayıs -Escape Simulator (Bulut, XBOX Series X|S ve PC) – 26 Mayıs -Echo Generation 2 (Bulut, XBOX Series X|S ve PC) – 27 Mayıs -The Outer Worlds: Spacer’s Choice Edition (Bulut, XBOX Series X|S ve PC) – 27 Mayıs -Crashout Crew (Bulut, XBOX Series X|S, El Konsolu ve PC) – 28 Mayıs -Kabuto Park (Bulut, […]
XBOX Game Pass’e eklenen ve eklenecek yeni oyunlar açıklandı (19 Mayıs) yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Fortnite, App Store’a “küresel olarak” geri döndü

Fortnite, App Store’a geri döndü

Fortnite, App Store’a geri döndüFortnite oyununun geliştiricisi Epic Games, teknoloji devi Apple’a karşı ABD’de açtığı App Store merkezli davadan mutlu ayrılmış, yargıç Yvonne Gonzalez Rogers Apple’ın uygulama dışında yapılan satın alma işlemlerinden ücret/komisyon alamayacağına karar vermişti. Buna ek olarak yargıç, Apple’ın geliştiricilerin kullanıcıları uygulama dışı satın alma yapabilecekleri yerlere yönlendirmelerini kısıtlamasını da engellemişti. Bu başarı hakkında bir açıklama yapan Epic CEO’su Tim Sweeney, “Apple vergisi için oyun bitti.” demiş ve ek olarak şunları aktarmıştı: “Apple’ın yüzde 30’a varan ek ücretleri, Dijital Piyasalar Yasası kapsamında Avrupa’da olduğu gibi artık Amerika Birleşik Devletleri’nde de yok.” Sweeney, bu kararın ardından şirketin Fortnite’ı ABD merkezli App Store’a geri döneceğini söylemiş ve beklenen adım karardan 10 gün sonra atılmıştı. Bugün ise beklenen “küresel” adım atıldı ve popüler oyun ABD’den sonra diğer ülkelerdeki App Store’lara da eklendi.

Fortnite, App Store’a “küresel olarak” geri döndü yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.