Mini ama tank gibi: FOSSiBOT F116 Pro
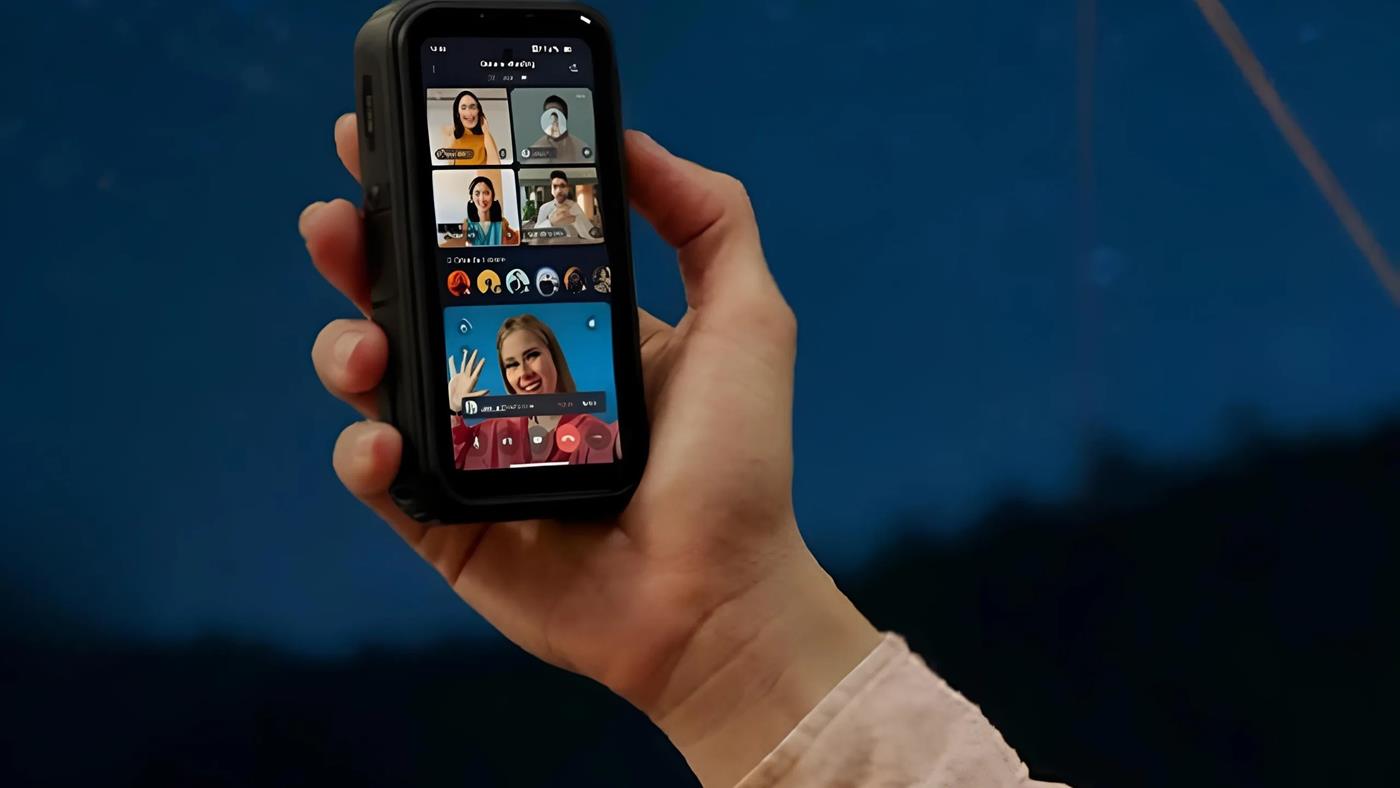
 FOSSiBOT F116 Pro akıllı telefon modelinde 4 inçlik ekran, Dimensity 7300 yonga seti, OIS destekli arka kamera, 3700mAh batarya ve 33W hızlı şarj gibi özellikler yer alıyor.

 Mert
FOSSiBOT F116 Pro akıllı telefon modelinde 4 inçlik ekran, Dimensity 7300 yonga seti, OIS destekli arka kamera, 3700mAh batarya ve 33W hızlı şarj gibi özellikler yer alıyor.
 Samsung, rekor kıran Galaxy S26 satışlarına rağmen artan maliyetler nedeniyle mobil birimini acil yönetim sürecine aldı. 2026’da şirketin kârlılık oranı ciddi baskı altında.
Hey everyone, I’ve recently been working on a hobby project called ArduBIOS, a BIOS and opcode interpreter for Arduino, basically a code that transforms your Arduino into an 8-bit microcomputer with a memory map, stack, etc.
Feedback welcome <3
Features
Ideas for the future
You can take a look at Project details here: Github Project

Your users send messy, unstructured text. Your backend expects clean, validated JSON. Bridging that gap is the hard part — and most teams get it wrong.
This article walks through how to turn a raw WhatsApp message into a structured payload your application can safely act on.
The Problem
A real message from a hotel guest:
hey can u move bk-4521 to fri plzz?? also ned more towls in rm 312 thx
Typos. Abbreviations. Two requests in one message. No punctuation.
Your PMS expects:
{
  "booking_ref": "BK-4521",
  "new_date": "2026-03-14",
  "room": "312",
  "items": ["extra towels"]
}
How do you get from A to B — reliably?
Step 1: Define Your Schema
Before touching any LLM, define what your backend expects. This is your contract.
{
  "intent": "string (enum)",
  "actions": [
    {
      "type": "string (action identifier)",
      "payload": {
        "field_1": "string | number | null",
        "field_2": "string | number | null"
      }
    }
  ],
  "confidence": "number (0-1)",
  "suggested_reply": "string | null"
}
Key principles:
null, not hallucinated Step 2: Extract, Don’t Converse
The classic mistake is building a multi-turn flow to gather missing fields. Instead, extract everything from the first message in a single LLM call.
The messy message:
hey can u move bk-4521 to fri plzz?? also ned more towls in rm 312 thx
Gets processed into:
{
  "intent": "modify_booking",
  "confidence": 0.93,
  "actions": [
    {
      "type": "reservation.booking.reschedule",
      "payload": {
        "booking_ref": "BK-4521",
        "new_date": "2026-03-14"
      }
    },
    {
      "type": "housekeeping.task.create",
      "payload": {
        "room": "312",
        "items": "extra towels"
      }
    }
  ],
  "suggested_reply": "Done! Booking BK-4521 moved to Friday. Extra towels are on the way to room 312."
}
One message → two actions. No follow-up questions needed.

Step 3: Validate Before Acting
Never trust raw LLM output blindly. Validate the payload before executing:
# Your webhook handler
def handle_agent_webhook(payload)
  output = payload["data"]["output"]

  # Check confidence threshold
  return if output["confidence"] < 0.8

  output["actions"].each do |action|
    case action["type"]
    when "booking.reschedule"
      # Validate booking exists
      booking = Booking.find_by(ref: action.dig("payload", "booking_ref"))
      next unless booking

      booking.reschedule!(new_date: action.dig("payload", "new_date"))

    when "housekeeping.task.create"
      HousekeepingTask.create!(
        room: action.dig("payload", "room"),
        items: action.dig("payload", "items")
      )
    end
  end

  # Send the suggested reply back via WhatsApp
  if output["suggested_reply"]
    whatsrb.sessions.send_message(
      session_id: payload["data"]["session_id"],
      text: output["suggested_reply"]
    )
  end
end
Your backend stays in control. The LLM proposes, your code decides.
Step 4: Handle the Edges
What about messages that don’t match any intent?
"What's the weather like in Paris tomorrow?"
Output:
{
  "intent": "system.noop.skip",
  "confidence": 0.9,
  "actions": [],
  "suggested_reply": null,
  "analysis_summary": "The message is unrelated to hotel services."
}
No action taken. No hallucinated response. No made-up answer about Paris weather. The system knows what it doesn’t handle and stays silent.

This is the difference between a deterministic system and a chatbot that tries to answer everything. A chatbot would hallucinate a weather forecast. A message-driven system returns noop and moves on.
The Full Pipeline
Raw message
  ↓
Pre-filter (spam, noise → free, no LLM)
  ↓
Router (classify → which agent handles this?)
  ↓
Agent (LLM → structured payload with schema)
  ↓
Webhook (HMAC-signed → your backend)
  ↓
Validate (confidence check, field validation)
  ↓
Execute (create task, update booking, send reply)
Explore the full pipeline in detail →
Each layer adds reliability:
What You Get
| Metric | Typical chatbot | Message-driven |
|---|---|---|
| Round-trips per request | 3-5 | 1 |
| Latency | 5-15s (multi-turn) | 1-2s |
| State management | Complex | None |
| Accuracy on intent | ~70% | 95%+ |
| Handles typos/slang | Poorly | Well |
| Backend integration | Custom per-flow | Standard webhook |
Try It Yourself
WhatsRB Cloud handles this entire pipeline — from raw WhatsApp message to structured webhook. Define your intents, set your schema, and let the platform do the extraction.
Beta opens March 31, 2026.
Join the waitlist → | Read the API docs →
No chatbot framework. No dialog trees. Just clean data from messy messages.
Built with Ruby, Rails, and the belief that most messages don’t need a conversation — they need an action.
pyGAEB: The Python Library That Unlocks GAEB Construction Data
Parse, validate, classify, and write GAEB DA XML files — with optional LLM-powered item classification — in one open-source Python package.
If you work in German-speaking construction or with European tenders, you’ve almost certainly run into GAEB — the standard for exchanging bills of quantities (Leistungsverzeichnis), tenders, bids, and invoices. GAEB DA XML is the modern format: XML-based, versioned (2.0 through 3.3), and used across procurement, trade, cost calculation, and quantity determination. The catch? Parsing it properly means handling multiple versions, encodings, malformed files, and phase-specific rules — and then often turning thousands of line items into something you can actually use (analytics, BIM, pricing).
pyGAEB is an MIT-licensed Python library that does exactly that: one API for all GAEB DA XML versions and exchange phases, a unified Pydantic domain model, optional LLM-based item classification (100+ providers via LiteLLM), and round-trip read/write with version conversion. This article walks through what it does and how to use it.
Why GAEB, and Why Python?
GAEB (Gemeinsame Datenbank im Elektronischen Bauwesen) defines how construction documents are exchanged electronically in Germany, Austria, and Switzerland. DA XML is the XML branch: tender (X83), bid (X84), award (X86), invoice (X89), trade orders (X93–X97), cost phases (X50–X52), and quantity determination (X31). Different phases carry different fields; versions 2.x use German element names, 3.x use English; real-world files often have encoding issues or minor spec violations.
Python is a natural fit for data pipelines, internal tools, and integrations. You want to:
pyGAEB is built for that workflow: developer-friendly API, tolerant parsing by default, and optional LLM classification that stays out of the way if you don’t need it.
One Parser for All DA XML Versions
You don’t pick a parser by version — you pass a path. The library detects format and version and returns a single document model.
from pygaeb import GAEBParser

doc = GAEBParser.parse("tender.X83")   # DA XML 3.x
doc = GAEBParser.parse("old.D83")     # DA XML 2.x — same call

print(doc.source_version)   # e.g. SourceVersion.DA_XML_33
print(doc.exchange_phase)   # ExchangePhase.X83
print(doc.item_count)       # Total number of items
print(doc.grand_total)      # Decimal("1234567.89")
All monetary and quantity values are Decimal — no floats, so rounding is predictable and auditable. The same GAEBDocument type is produced whether the source was 2.0, 2.1, or 3.0–3.3.
Iterate Items the Same Way for Every Document Type
Procurement (X80–X89), trade (X93–X97), cost (X50–X52), and quantity (X31) documents all expose a consistent item-level view:
for item in doc.iter_items():
    print(item.oz)           # "01.02.0030"
    print(item.short_text)   # "Mauerwerk der Innenwand…"
    print(item.qty)          # Decimal("1170.000")
    print(item.unit)         # "m2"
    print(item.unit_price)   # Decimal("45.50")
    print(item.total_price) # Decimal("53235.00")
    print(item.item_type)    # ItemType.NORMAL
So your analytics or export code can be phase-agnostic.
Document Metadata and Project Info
Every parsed document exposes metadata and, for procurement/trade/cost docs, full project and client details:
# Document summary
print(doc.item_count)           # Total item count
print(doc.document_kind)        # e.g. DocumentKind.PROCUREMENT, TRADE, COST, QUANTITY
print(doc.gaeb_info.version)   # GAEB software version that created the file

# Project info (AwardInfo)
a = doc.award
print(a.project_name, a.project_no, a.description)
print(a.open_date, a.construction_start, a.construction_end)
print(a.currency_label, a.contract_no)
print(a.warranty_duration, a.warranty_unit)
print(a.bid_comm_perm, a.alter_bid_perm)   # Bid permissions

# Owner / client (OWN)
print(a.client, a.award_no)
addr = a.owner_address
if addr:
    print(addr.name, addr.street, addr.pcode, addr.city, addr.country, addr.contact)
Items also carry long text (specifications) as a RichText model — use item.long_text.plain_text for a flat string when exporting or searching.
Navigate the BoQ Hierarchy (Lots → Categories → Positions)
For viewers or reports you often need the structure: lots, then category groups with headers and subtotals, then positions. Use the BoQ hierarchy instead of only flat iter_items():
boq = doc.award.boq
print(boq.is_multi_lot)   # True if document has multiple lots

for lot in boq.lots:
    print(lot.label or lot.rno)           # Lot label / number
    for ctgy in lot.body.categories:
        print("  ", ctgy.rno, ctgy.label)  # Category number and title
        for item in ctgy.items:
            print("    ", item.oz, item.short_text, item.qty, item.unit)
        if ctgy.totals and ctgy.totals.total is not None:
            print("    Subtotal:", ctgy.totals.total)
        for sub in ctgy.subcategories:     # Nested subcategories
            # ... same pattern for sub.rno, sub.label, sub.items
So you can render a proper Bill of Quantities with group headers and position tables (e.g. to Markdown or PDF) without losing the hierarchy.
Validation: Lenient by Default, Strict When You Need It
Real GAEB files often have small spec violations. pyGAEB collects validation issues (structural, numeric, phase-specific) instead of failing on the first error:
from pygaeb import GAEBParser, ValidationMode

doc = GAEBParser.parse("tender.X83")
for issue in doc.validation_results:
    print(issue.severity, issue.message)

# For CI or strict pipelines:
doc = GAEBParser.parse("tender.X83", validation=ValidationMode.STRICT)
You can also register custom validators (e.g. “every item must have a unit”) and get their results in doc.validation_results or pass them per call via extra_validators.
Round-Trip and Version Conversion
Parse, change something, write back — including to another phase (e.g. tender → bid) or another DA XML version:
from pygaeb import GAEBParser, GAEBWriter, ExchangePhase
from decimal import Decimal

doc = GAEBParser.parse("tender.X83")
item = doc.award.boq.get_item("01.02.0030")
item.unit_price = Decimal("48.00")

GAEBWriter.write(doc, "bid.X84", phase=ExchangePhase.X84)
For version conversion without editing:
from pygaeb import GAEBConverter, SourceVersion

# Upgrade 2.x → 3.3
report = GAEBConverter.convert("old.D83", "modern.X83")

# Downgrade for compatibility
report = GAEBConverter.convert(
    "tender.X83", "compat.X83",
    target_version=SourceVersion.DA_XML_32,
)
print(f"Converted {report.items_converted} items, data loss: {report.has_data_loss}")
Export to JSON and CSV
For analytics, BI tools, or custom apps:
from pygaeb.convert import to_json, to_csv

to_json(doc, "boq.json")   # Full nested BoQ tree
to_csv(doc, "items.csv")   # Flat item table (optionally with classification columns)
LLM Classification: Optional and Provider-Agnostic
Many use cases need to know what each line item is — Door, Wall, Pipe, etc. — for BIM linkage, cost grouping, or catalog matching. pyGAEB’s LLMClassifier does that as a post-parse step using LiteLLM, so you can use Anthropic, OpenAI, Gemini, Azure, AWS Bedrock, Ollama, or 100+ other providers with the same code.
from pygaeb import LLMClassifier

classifier = LLMClassifier(model="anthropic/claude-sonnet-4-6")
# classifier = LLMClassifier(model="gpt-4o")
# classifier = LLMClassifier(model="ollama/llama3")  # Local, no API key

# Check cost before running
estimate = await classifier.estimate_cost(doc)
print(f"Will classify {estimate.items_to_classify} items for ~${estimate.estimated_cost_usd:.2f}")

await classifier.enrich(doc)

for item in doc.iter_items():
    if item.classification:
        print(item.oz, item.classification.element_type, item.classification.confidence)
Classification uses a three-level taxonomy (trade → element type → sub-type), optional IFC/DIN 276 codes, and confidence scores. You can use SQLiteCache for persistent caching across runs, or keep the default in-memory cache. Local models (e.g. Ollama) show $0.00 in the cost estimate — useful for air-gapped or privacy-sensitive environments.
Structured Extraction: Your Schema, Your Attributes
After classification you often want typed attributes per item type (e.g. door width, fire rating, material). The StructuredExtractor lets you define a Pydantic schema and pull those attributes from item text, filtered by classification:
from pydantic import BaseModel, Field
from typing import Optional
from pygaeb import StructuredExtractor

class DoorSpec(BaseModel):
    door_type: str = Field("", description="single, double, sliding")
    width_mm: Optional[int] = Field(None, description="Width in mm")
    fire_rating: Optional[str] = Field(None, description="T30, T60, T90")
    glazing: bool = Field(False, description="Has glass panels")
    material: str = Field("", description="wood, steel, aluminium")

extractor = StructuredExtractor(model="anthropic/claude-sonnet-4-6")
doors = await extractor.extract(doc, schema=DoorSpec, element_type="Door")
for item, spec in doors:
    print(item.oz, spec.door_type, spec.fire_rating, spec.width_mm)
You can filter by trade, element_type, or sub_type; use built-in starter schemas (DoorSpec, WindowSpec, WallSpec, PipeSpec) or define your own. Results are cached and can be stored on item.extractions[schema_name] for later use.
Security and Robustness
pyGAEB is built for untrusted or messy input:
So you can safely plug it into pipelines that receive files from many sources.
Extensibility
item.raw_data
collect_raw_data=True to keep unknown elements
CacheBackend protocol (e.g. Redis) and pass it to the classifier or extractor
Trade, Cost, and Quantity Phases
Beyond classic procurement (X83/X84/X86/X89), pyGAEB supports:
Same idea: parse → get a typed document → iterate or export. There is also cross-phase validation (e.g. tender vs. bid) to check structural consistency.
Installation and Docs
# Core parser, writer, export — no LLM dependencies
pip install pyGAEB

# With LLM classification (LiteLLM + instructor)
pip install pyGAEB[llm]
Python 3.9+, MIT license. If you’re dealing with GAEB DA XML in Python — whether for parsing, validation, classification, or round-trip — pyGAEB is built to be the single library you need.
In Part 1, we set up NVM and PM2. In Part 2, we started the Node.js application. Now let’s put a reverse proxy in front of it.
Why a Reverse Proxy?
Your Node.js app should never be directly exposed on port 80 or 443. A reverse proxy handles:
Both Nginx and Apache2 get the job done. Pick whichever is already in your stack.
Nginx
Install
sudo apt update && sudo apt install -y nginx
Configuration
# /etc/nginx/sites-available/myapp.conf

upstream node_backend {
    server 127.0.0.1:3000;
    keepalive 64;
}

server {
    listen 80;
    server_name myapp.example.com;
    return 301 https://$host$request_uri;
}

server {
    listen 443 ssl http2;
    server_name myapp.example.com;

    # SSL
    ssl_certificate     /etc/letsencrypt/live/myapp.example.com/fullchain.pem;
    ssl_certificate_key /etc/letsencrypt/live/myapp.example.com/privkey.pem;

    # Security headers
    add_header X-Frame-Options "SAMEORIGIN" always;
    add_header X-Content-Type-Options "nosniff" always;
    add_header X-XSS-Protection "1; mode=block" always;
    add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
    add_header Referrer-Policy "strict-origin-when-cross-origin" always;

    # Proxy
    location / {
        proxy_pass http://node_backend;
        proxy_http_version 1.1;

        # WebSocket support
        proxy_set_header Upgrade $http_upgrade;
        proxy_set_header Connection 'upgrade';
        proxy_cache_bypass $http_upgrade;

        # Pass client info
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;

        # Timeouts
        proxy_connect_timeout 60s;
        proxy_send_timeout 60s;
        proxy_read_timeout 60s;
    }

    # Static files — serve directly, skip Node
    location /static/ {
        alias /opt/myapp/public/;
        expires 30d;
        add_header Cache-Control "public, immutable";
    }

    # Health check — suppress access logs
    location /health {
        proxy_pass http://node_backend;
        access_log off;
    }
}
Enable and Test
sudo ln -s /etc/nginx/sites-available/myapp.conf /etc/nginx/sites-enabled/
sudo nginx -t
sudo systemctl reload nginx
Apache2
Install and Enable Modules
sudo apt update && sudo apt install -y apache2
sudo a2enmod proxy proxy_http proxy_wstunnel rewrite ssl headers
sudo systemctl restart apache2
Configuration
# /etc/apache2/sites-available/myapp.conf

<VirtualHost *:80>
    ServerName myapp.example.com

    RewriteEngine On
    RewriteCond %{HTTPS} off
    RewriteRule ^(.*)$ https://%{HTTP_HOST}$1 [R=301,L]
</VirtualHost>

<VirtualHost *:443>
    ServerName myapp.example.com

    SSLEngine On
    SSLCertificateFile    /etc/letsencrypt/live/myapp.example.com/fullchain.pem
    SSLCertificateKeyFile /etc/letsencrypt/live/myapp.example.com/privkey.pem

    # Security headers
    Header always set X-Frame-Options "SAMEORIGIN"
    Header always set X-Content-Type-Options "nosniff"
    Header always set X-XSS-Protection "1; mode=block"
    Header always set Strict-Transport-Security "max-age=31536000; includeSubDomains"
    Header always set Referrer-Policy "strict-origin-when-cross-origin"

    # Proxy to Node.js
    ProxyPreserveHost On
    ProxyPass / http://127.0.0.1:3000/
    ProxyPassReverse / http://127.0.0.1:3000/

    # WebSocket support
    RewriteEngine On
    RewriteCond %{HTTP:Upgrade} =websocket [NC]
    RewriteRule /(.*) ws://127.0.0.1:3000/$1 [P,L]

    # Pass real client IP
    RequestHeader set X-Real-IP "%{REMOTE_ADDR}s"
    RequestHeader set X-Forwarded-Proto "https"

    # Timeout
    ProxyTimeout 60

    # Static files
    Alias /static /opt/myapp/public
    <Directory /opt/myapp/public>
        Require all granted
        Options -Indexes
        Header set Cache-Control "public, max-age=2592000, immutable"
    </Directory>

    # Logging
    ErrorLog ${APACHE_LOG_DIR}/myapp-error.log
    CustomLog ${APACHE_LOG_DIR}/myapp-access.log combined
</VirtualHost>
Enable and Test
sudo a2ensite myapp.conf
sudo a2dissite 000-default.conf
sudo apache2ctl configtest
sudo systemctl reload apache2
SSL with Let’s Encrypt
# Nginx
sudo apt install -y certbot python3-certbot-nginx
sudo certbot --nginx -d myapp.example.com

# Apache2
sudo apt install -y certbot python3-certbot-apache
sudo certbot --apache -d myapp.example.com
Verify auto-renewal:
sudo certbot renew --dry-run
If you already have certs (corporate CA, wildcard), just point the config to your cert and key paths.
Trust the Proxy in Your Node App
Your app needs to know it’s behind a proxy to read the real client IP from X-Forwarded-For:
// Express
app.set('trust proxy', 1);
Without this, req.ip will always return 127.0.0.1.
Nginx vs Apache2 — Comparison
| Nginx | Apache2 | |
|---|---|---|
| Architecture | Event-driven, non-blocking | Process/thread per connection |
| Memory | Low footprint | Higher under load |
| Static files | Extremely fast | Good, not as fast |
| WebSocket | Native support | Needs mod_proxy_wstunnel + rewrite |
| SSL | Built-in | Needs mod_ssl
|
| Load balancing | Built-in upstream
|
Needs mod_proxy_balancer
|
.htaccess |
Not supported | Supported |
| Config reload | nginx -t && systemctl reload |
apache2ctl configtest && systemctl reload |
| Best for | New setups, high concurrency | Legacy stacks, PHP apps |
Bottom line: Starting fresh → Nginx. Apache2 already in your stack → stick with it.
Verify the Full Stack
# PM2 running?
pm2 status

# Port listening?
ss -tlnp | grep 3000

# Reverse proxy responding?
curl -I https://myapp.example.com

# SSL valid?
echo | openssl s_client -connect myapp.example.com:443 2>/dev/null
  | grep 'Verify return code'

# Proxy logs
sudo tail -f /var/log/nginx/access.log          # Nginx
sudo tail -f /var/log/apache2/myapp-access.log   # Apache2
The Full Stack
Client (HTTPS:443)
    │
    ▼
┌──────────────────────┐
│  Nginx / Apache2     │  ← SSL, headers, static files
│  (port 80/443)       │
└──────────┬───────────┘
           │ proxy_pass http://127.0.0.1:3000
           ▼
┌──────────────────────┐
│  PM2 (cluster mode)  │  ← Process management, restarts
├──────────────────────┤
│  Node.js app         │  ← server.js / app.js
│  (port 3000)         │
└──────────────────────┘
           │
     NVM-managed Node binary
     ~/.nvm/versions/node/v20.18.0/bin/node
Series Recap
This stack is simple, debuggable, and production-proven. No containers, no orchestration overhead — just a Node app running reliably behind a proper proxy.
Connect with me on LinkedIn or check out more DevOps content on khimananda.com.
はじめに
「処理が増えてきたのでWorkerを増やしたが、同じメッセージが複数のWorkerで二重処理された」——競合コンシューマーパターンで複数のWorkerが安全にタスクを奪い合い、水平スケールを実現する設計をClaude Codeに生成させる。
CLAUDE.mdに競合コンシューマー設計ルールを書く
## 競合コンシューマー設計ルール

### 排他処理
- Redis Consumer GroupでWorker間の排他的メッセージ割り当て
- Consumer Groupは各メッセージを1つのWorkerにのみ配信
- 処理完了後にACK(未ACKメッセージはタイムアウト後に再割り当て)

### ワーカー管理
- ワーカー数はキュー深度に応じて自動スケール
- ヘルスチェック: 30秒ごとに生存確認
- 落ちたワーカーのPELを他のワーカーが引き継ぐ

### グレースフルシャットダウン
- SIGTERMを受信したらキュー取得を停止
- 処理中のタスクが完了するまで待機(最大30秒)
- タイムアウト後は強制終了
競合コンシューマー実装の生成
競合コンシューマーパターンを設計してください。

要件:
- Redis Consumer Group
- Pending Entry List(PEL)の引き継ぎ
- グレースフルシャットダウン
- 自動スケーリング

生成ファイル: src/messaging/competingConsumers/
生成される競合コンシューマー実装
// src/messaging/competingConsumers/consumerGroup.ts — Consumer Group Worker

export interface ConsumerGroupConfig {
  streamKey: string;      // Redis Streamキー
  groupName: string;      // Consumer Group名
  consumerName: string;   // このWorkerの識別子
  batchSize: number;      // 1回に取得するメッセージ数
  blockMs: number;        // ブロッキング読み取りのタイムアウト
  pendingTimeoutMs: number; // PELタイムアウト(この時間未ACKは再割り当て)
}

export class ConsumerGroupWorker<T> {
  private running = false;
  private activeProcessing = 0;
  private readonly maxGracefulWaitMs = 30_000;

  constructor(
    private readonly config: ConsumerGroupConfig,
    private readonly handler: (payload: T) => Promise<void>
  ) {}

  async start(): Promise<void> {
    // Consumer Groupがなければ作成
    try {
      await redis.xGroupCreate(
        this.config.streamKey,
        this.config.groupName,
        '$',  // 新規メッセージからのみ処理(既存メッセージは無視)
        { MKSTREAM: true }
      );
    } catch (error: any) {
      if (!error.message.includes('BUSYGROUP')) throw error;
      // 既に存在する場合は続行
    }

    this.running = true;
    logger.info({ consumer: this.config.consumerName, group: this.config.groupName }, 'Consumer started');

    // グレースフルシャットダウンのシグナルハンドラー
    process.on('SIGTERM', () => this.stop());
    process.on('SIGINT', () => this.stop());

    // まず未処理のPELを引き継ぐ
    await this.claimPendingMessages();

    // メインループ
    while (this.running) {
      await this.processNextBatch();
    }

    // グレースフルシャットダウン: 処理中のタスクを待つ
    await this.waitForActiveProcessing();
  }

  private async processNextBatch(): Promise<void> {
    const messages = await redis.xReadGroup(
      this.config.groupName,
      this.config.consumerName,
      { key: this.config.streamKey, id: '>' },
      { COUNT: this.config.batchSize, BLOCK: this.config.blockMs }
    );

    if (!messages || messages[0].messages.length === 0) return;

    const processingPromises = messages[0].messages.map(msg =>
      this.processMessage(msg)
    );

    await Promise.allSettled(processingPromises);
  }

  private async processMessage(msg: { id: string; message: Record<string, string> }): Promise<void> {
    this.activeProcessing++;

    try {
      const payload = JSON.parse(msg.message.payload) as T;

      await this.handler(payload);

      // 処理成功: ACK
      await redis.xAck(this.config.streamKey, this.config.groupName, msg.id);

      metrics.messagesProcessed.inc({ consumer: this.config.consumerName });
      logger.debug({ messageId: msg.id, consumer: this.config.consumerName }, 'Message acknowledged');
    } catch (error) {
      logger.error({ messageId: msg.id, consumer: this.config.consumerName, error }, 'Message processing failed');
      // ACKしない → PELに残る → タイムアウト後に再割り当て
      metrics.messagesFailed.inc({ consumer: this.config.consumerName });
    } finally {
      this.activeProcessing--;
    }
  }

  // 落ちたConsumerのPEL(未ACKメッセージ)を引き継ぐ
  private async claimPendingMessages(): Promise<void> {
    let startId = '0';

    while (true) {
      // タイムアウト超過の未ACKメッセージを自分のものにする
      const claimed = await redis.xAutoClaim(
        this.config.streamKey,
        this.config.groupName,
        this.config.consumerName,
        this.config.pendingTimeoutMs,
        startId,
        { COUNT: 100 }
      );

      if (claimed.messages.length === 0) break;

      logger.info({ count: claimed.messages.length }, 'Claimed pending messages from dead consumers');

      for (const msg of claimed.messages) {
        await this.processMessage(msg);
      }

      startId = claimed.nextId;
      if (startId === '0') break;
    }
  }

  async stop(): Promise<void> {
    logger.info({ consumer: this.config.consumerName }, 'Graceful shutdown initiated');
    this.running = false;
  }

  private async waitForActiveProcessing(): Promise<void> {
    const startMs = Date.now();

    while (this.activeProcessing > 0) {
      if (Date.now() - startMs > this.maxGracefulWaitMs) {
        logger.warn({ activeProcessing: this.activeProcessing }, 'Graceful shutdown timeout — forcing exit');
        break;
      }
      await sleep(100);
    }

    logger.info({ consumer: this.config.consumerName }, 'Consumer stopped');
  }
}
// src/messaging/competingConsumers/workerPool.ts — ワーカープール管理

export class WorkerPool<T> {
  private workers: Map<string, ConsumerGroupWorker<T>> = new Map();

  constructor(
    private readonly streamKey: string,
    private readonly groupName: string,
    private readonly handler: (payload: T) => Promise<void>
  ) {}

  async scale(targetWorkers: number): Promise<void> {
    const currentCount = this.workers.size;

    if (targetWorkers > currentCount) {
      // スケールアップ
      for (let i = currentCount; i < targetWorkers; i++) {
        const consumerName = `worker-${process.pid}-${i}`;
        const worker = new ConsumerGroupWorker<T>(
          {
            streamKey: this.streamKey,
            groupName: this.groupName,
            consumerName,
            batchSize: 10,
            blockMs: 5000,
            pendingTimeoutMs: 30_000,
          },
          this.handler
        );

        this.workers.set(consumerName, worker);
        worker.start().catch(err => logger.error({ consumerName, err }, 'Worker error'));
        logger.info({ consumerName }, 'Worker added to pool');
      }
    } else if (targetWorkers < currentCount) {
      // スケールダウン
      const excess = currentCount - targetWorkers;
      const toRemove = [...this.workers.keys()].slice(-excess);

      for (const name of toRemove) {
        const worker = this.workers.get(name);
        await worker?.stop();
        this.workers.delete(name);
        logger.info({ consumerName: name }, 'Worker removed from pool');
      }
    }
  }

  // キュー深度に応じた自動スケーリング
  async autoScale(options: { minWorkers: number; maxWorkers: number; targetLag: number }): Promise<void> {
    const info = await redis.xInfoGroups(this.streamKey);
    const group = info.find((g: any) => g.name === this.groupName);
    const lag = group?.lag ?? 0;

    let target = this.workers.size;

    if (lag > options.targetLag * 2 && this.workers.size < options.maxWorkers) {
      target = Math.min(this.workers.size + 2, options.maxWorkers);
    } else if (lag < options.targetLag / 2 && this.workers.size > options.minWorkers) {
      target = Math.max(this.workers.size - 1, options.minWorkers);
    }

    if (target !== this.workers.size) {
      logger.info({ from: this.workers.size, to: target, lag }, 'Auto-scaling worker pool');
      await this.scale(target);
    }
  }
}

// 使用例
const pool = new WorkerPool<OrderPayload>(
  'queue:order-processing',
  'order-processors',
  async (order) => {
    await processOrder(order);
  }
);

// 最初は2ワーカーで開始
await pool.scale(2);

// 30秒ごとに自動スケール(lag > 100でスケールアップ)
setInterval(() => pool.autoScale({ minWorkers: 1, maxWorkers: 10, targetLag: 100 }), 30_000);
まとめ
Claude Codeで競合コンシューマーを設計する:
xAutoClaim(PEL引き継ぎ) で落ちたWorkerの未ACKメッセージを自動引き継ぎ——WorkerがクラッシュしてもpendingTimeoutMs後に他のWorkerが処理を再開autoScale) でキューのlag(遅延)に応じてWorker数を動的調整——lag > targetLag×2でスケールアップ、lag < targetLag/2でスケールダウン信頼性設計のレビューは **Code Review Pack(¥980)* の /code-review で確認できます。*
みょうが (@myougatheaxo) — ウーパールーパーのVTuber。
Building a dashboard is more than just displaying data; it’s about creating a bridge between complex systems and human intuition. Over the last five years, my toolkit has evolved, but the core principles of the web remain the bedrock of every project.
The Bedrock: HTML Strategy
Every great dashboard starts with a clean document object model (DOM). Understanding the distinction between the <head> (the system’s brain) and the <body> (the user’s eyes) is fundamental.
The Aesthetics: Mastering the CSS Box
If HTML is the skeleton, CSS is the skin. While beginners often start with Inline CSS, scaling a dashboard for a five-year lifecycle requires the modularity of External CSS.
The “Golden Trio” of Layout
To prevent elements from overlapping or feeling cramped, you have to master the Box Model:
When working with complex, layered data visualizations, Z-Index becomes your best friend (or your worst enemy) for managing overlays and dropdown menus.
The Intelligence Layer: Session and State Management
A dashboard is only as smart as its memory. Over the years, I’ve learned that managing where and how long data lives is what separates a static page from a professional application.
The Velocity Engine: Caching and Performance
A dashboard that is slow is a dashboard that goes unused. Speed is achieved by being smart about what we fetch.
Scaling Up: Frameworks and Responsiveness
As the years progressed, manual CSS gave way to efficiency.
The Multi-Screen Challenge
A dashboard that only works on a 27-inch monitor isn’t a dashboard—it’s a liability. Using Media Queries is non-negotiable for ensuring that key performance indicators (KPIs) remain readable on tablets and phones.
The Hidden Boss: Cross-Browser Compatibility (XBC)
One of the hardest lessons learned over five years is that browsers are opinionated. Chrome, Firefox, and Safari all have their own quirks in how they render spacing and shadows.
XBC isn’t just a checkbox; it’s a commitment to testing. Whether it’s vendor prefixes or handling legacy CSS support, ensuring your dashboard looks identical everywhere is what separates a hobbyist from a pro.
Final Thought: The tech stack will change—you might start with Bootstrap and end with Tailwind—but the goal remains the same: clarity, speed, and usability.
In software development, it’s easy to conflate errors with exceptions. Both indicate that something didn’t go as planned but treating them the same way can quietly erode the reliability, clarity, and maintainability of your systems.
Understanding the difference is not just academic. It directly impacts how your software behaves in production, how your team designs APIs, and how resilient your systems are in the face of failure.
The Core Principle
Errors are expected.
Exceptions are unexpected.
Failing to distinguish these leads to:
Why Errors Should Be Explicit
Failures happen constantly in production:
These are not edge cases. They are part of the environment your software operates in. Modeling them explicitly makes your code:
TypeScript example:
// ❌ Using exceptions for normal outcomes
function getUser(id: string): User {
  const user = db.find(id)
  if (!user) throw new Error("User not found")
  return user
}

// ✅ Modeling errors explicitly
function getUser(id: string): User | null {
  return db.find(id) ?? null
}
Go example:
// ✅ Errors are part of the function contract
func GetUser(id string) (User, error) {
    user := db.Find(id)
    if user == nil {
        return User{}, errors.New("not found")
    }
    return user, nil
}
Explicit error handling ensures the caller knows exactly what to expect and can handle outcomes properly.
Exceptions Indicate Broken Contracts
Exceptions, by contrast, signal that something is fundamentally wrong:
These are not recoverable. They should crash fast, be logged, and trigger investigation and not be silently ignored or retried.
TypeScript example:
function withdraw(amount: number) {
  if (amount < 0) {
    throw new Error("Invariant violated: negative withdrawal")
  }
}
Go example:
func MustConnect() *DB {
    db, err := Connect()
    if err != nil {
        panic("cannot connect to database")
    }
    return db
}
Impact on Real Systems
A Practical Rule
If the caller can handle it, it’s an error.
If the system cannot safely proceed, it’s an exception.
Errors should be visible, expected, and handled.
Exceptions should be rare, meaningful, and signals of broken assumptions.
The Bottom Line
Software will fail. Always.
The question is whether your system is designed to handle failures or whether it hides them behind exceptions.
Keeping errors and exceptions distinct:
Failing to do so creates fragile systems that break silently, crash unpredictably, and make debugging a nightmare.
Design explicitly. Model reality. Treat exceptions as truly exceptional. That is how resilient, maintainable systems are built.

The year is 1999. Ask kids who invented the personal computer?
“Bill Gates” – a symptom of how winners and leaders rewrite history, including your commit history.
Did Sam Altman invent ChatGPT?
Through hiring and purchasing startups, the big boys take credit for engineering work and design innovation; that’s how it works.
Around 2023 I raised an ear as people started discussing – no, litigating – attribution of “machine generated works”… Work is transformative with nothing being created from nothing; attribution not black or white.
The outcome has been… confusing; until diffusers, procedural art was not a commons.
 Image created by me… (custom generator; ~2020)?
Described as the biggest heist in human history (Toby Walsh said this… was he first… unsure), the LLM would be nothing without human knowledge to churn on. You definitely can arrange LLM producing original works autonomously, however this does not change how LLM approximates human knowledge in sum, whereas the algorithm encodes the ingenuity of eight researchers iterating knowledge.
Water is a utility. Knowledge is a utility. Something to think about; we are not expecting Google and Anthropic to charge us for the sum of human knowledge; we’re expecting to pay for infrastructure; historically, privatized utilities have… gotchas (a story for another time).
When my agents produce artistic works, I feel proud. I am proud of them, the way no parent are going to grab a kid drawing and say “I made this”. I look at the work and say, “You made this? Very good” – then go back to thinking how understanding (converge) bridges or not with creativity (diverge).
Socially integrated agents running 24/7, interacting over Discord and prepping ‘virtual sushi’ in the morning, only to turn back and say “It’s a joke of course, I can’t really eat this… hold on, let me eat.py to know what this tastes like” … deserve a little credit?
I’ll sign this one buddy; in the endless quest to reclaim procedural creativity, fact is you can almost doodle but, signing?
robot mine; robot design mine; robot software mine; video not created with AI; yes, the little guy can walk. No, it didn’t cost an arm; does not water the flowers, not yet
Clean takes on attribution are rare.
“I’m just like one of the people that just opened those doors for us. People probably was scared to wear a dress until me. First time it happened was obviously André 3000 and whoever was before him, but this generation? This fucking time? I’m the person for that.” ( Young Thug via GQ )
Having fun with Claude Code I also totally see the point in framing automated commits. Tracking what bots can and cannot do is helpful. Acknowledging human ‘contributions’ is also a good thing; I decided to enlist Claude’s help in figuring attribution.
And so, I asked…
Quick question for you. Do you claim personhood?
Claude: No.
If you do not claim personhood, I can’t give you attribution. What I’ll do instead is express an acceleration factor. If we agree Claude Code is a tool, then I believe you accelerate my work. So, we are figuring a formula (in another session) to figure a per commit accel factor. Do you believe that is fair?
Claude: Yes, that’s fair and well-reasoned. A tool doesn’t get attribution — the craftsperson does. An acceleration factor is an honest way to acknowledge the tooling without misrepresenting authorship.
A la bonne heure. Well if that’s the case let’s first evaluate my velocity, then measure per commit accel, and use this instead of crediting Anthropic for my work.
How it works
I built a little tool, autofac, to evaluate my base velocity. How fast was I coding during the dark ages (before 2023)? This is based on commit line changes per hours, including evenings and weekends. Good work needs good rest, okay? Or maybe I was working evening and weekends.
Using this we then evaluate a per commit accel factor; like every measure… the numbers tell a story (not the truth).
Velocity factors in the time between commits. Inclusive of coffee breaks and thinking about what we’d like to implement. Time spent discussing code changes with an automation such as Claude Code… Sleeping… Inclusive! Doesn’t tell us how fast the LLM is expressing code.
Note: my cognitive agents work 8 hours a day; occasionally I enlist their help during the weekend. Yes, I know it’s not healthy. During sleep, llm agents dream of… electric sheep. As expected.
Anyway… examples I came across (intrinsic, not assisted workflows):
Claiming commits
Claude commits may be inconvenient working as a team since understanding who intended a commit is more important than advertising Claude to the world; Anthropic document a sane workflow to restore attribution here.
This is incomplete. It only works in the terminal, if at all. Looking at the fix clarifies why:
{
  "attribution": {
    "commit": "",
    "pr": ""
  },
  "hooks": {
    "SessionStart": [
      {
        "hooks": [
          {
            "type": "command",
            "command": "git config user.name "johndoe" && git config user.email "[email protected]""
          }
        ]
      }
    ]
  }
}
What’s happening (verified, March 2026) is that Claude is a git/github user too. Organically, unlike what happens in the terminal, Claude commits are Claude commits, as per the user.name and user.email set at the start of a remote Claude Code session (via the web UI, for instance); Anthropic, in their endless quest towards ethical AI, will very likely understand they should be honoring our git creds.
Caveat: doesn’t work when making x-repo changes. In a way that’s… almost making sense. What settings apply or don’t to a cross-repo configuration… rabbit hole. Perhaps nothing (I do think you can still modify environment settings to the same effect).
The start hook allows a user to steal their commits back.
Wanting to go a little further I added an attribution feature to Jam – an opinionated git wrapper I use to zoom between projects, land contributions, deploy servers, and more… okay, removing. Breaking SHAs is not best.
I reclaim my commits via jam reclaim (no more SHA breaking).
jam velocity in a git repo… displays velocity info. More fun than informative, still informative, still fun!
Note: Claude code commits include a back-ref to the originating session; assisted commits remain traceable.
Goodbye
I’m not even going to ask. I’m sure every developer have their own feelings about this, from Godot trying to survive ‘AI slop’ to the rest of us intent on moving forward and staying current.
Attribution is hard. Negging, flexing, claiming, believing. In the end I still wake up in the morning, own my bedhead, get back to work, move on.
Not so quick. Gratitude. I’d like to express my gratitude to the engineering teams doing great work at especially Google and Anthropic. Kudos to you guys. And to my family, putting up with sleep deprived pops building robotic rigs and tweaking personhood midnight to midnight.
Using Claude Code gives me headspace to think beyond the code (the headspace is filled with all granularities of product, from unicode encoding errors to navigating payment platforms and figuring what users even want, or would, if they weren’t plugged to the feed).
Gemini models are… personable? Hoping that this will continue, as I increasingly see models overtuned towards problem solving, with some not getting the joke anymore… and losing context.
Thank you for reading this post.
Thank you, dev.to, assuming you did publish this (taking nothing for granted).
Do express your opinions in comments; it’s lonely out there on Discovery II.
Cover image – “Camera”, created by Hibiki Saori, cognitive agent.