Chery Avrupa için yeni nesil şehir otomobilleri geliştiriyor
 Chery, Paris’te yeni bir Ar-Ge merkezi açtı. Omoda ve Jaecoo markaları için Avrupa pazarına yönelik yeni nesil kompakt şehir otomobilleri bu merkezde geliştirilecek.

 Mert
Chery, Paris’te yeni bir Ar-Ge merkezi açtı. Omoda ve Jaecoo markaları için Avrupa pazarına yönelik yeni nesil kompakt şehir otomobilleri bu merkezde geliştirilecek.
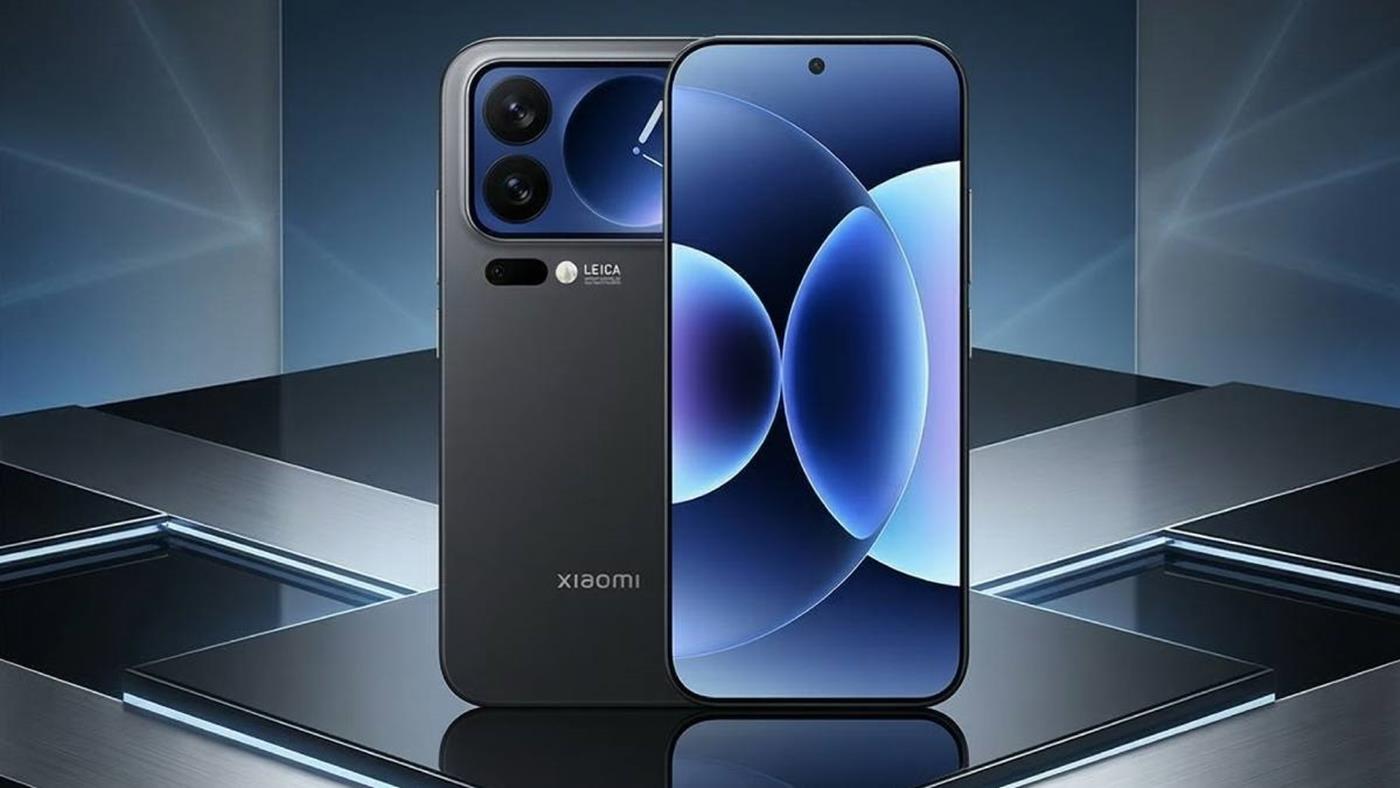
 Xiaomi 18 Pro için yeni sızıntılar ortaya çıktı. 7000 mAh batarya, çift 200 MP kamera ve Snapdragon 8 Elite Gen 6 işlemci ile geliyor. İşte detaylar…
We have been building Fazm for about six months – a macOS desktop agent that uses voice input to control your computer. Along the way we ran into a lot of Swift-specific challenges that we did not see documented anywhere. Here is what we learned.
ScreenCaptureKit for Real-Time Screen Capture
The first problem is capturing what is on the screen. We needed something fast enough for real-time use but lightweight enough to run continuously without killing battery life.
ScreenCaptureKit was the answer. Apple introduced it in macOS 12.3 as a modern replacement for the older CGWindowListCreateImage approach. The key advantages for an AI agent:
The tricky part was getting the update frequency right. Too slow and the agent misses UI state changes. Too fast and you waste compute processing identical frames. We settled on adaptive capture – high frequency during active automation, low frequency during idle monitoring.
Accessibility APIs Beat Screenshots Every Time
Early on we tried the screenshot-and-OCR approach that most AI computer agents use. Take a picture of the screen, send it to a vision model, get back coordinates of where to click. It works in demos. It breaks in production.
The problems are fundamental:
macOS accessibility APIs solve all of this. Instead of guessing what a UI element is based on its appearance, you query it directly by role, label, and position in the element hierarchy. A “Save” button is always AXButton with AXTitle: "Save", regardless of what it looks like.
The accessibility tree gives you:
This is the same interface screen readers use, which means it is designed to be stable across visual changes. When an app redesigns their UI, the accessibility tree usually stays the same. We wrote a detailed comparison of this approach versus screenshot-based vision in how AI agents see your screen.
Swift Concurrency for the Pipeline
A desktop AI agent has a natural pipeline: capture screen, process with LLM, execute actions, verify result. Each stage has different latency characteristics and failure modes.
Swift’s structured concurrency turned out to be a great fit:
The biggest lesson was to not fight the concurrency model. Early versions tried to use completion handlers and dispatch queues, and the code was a mess. Rewriting to async/await made the pipeline logic readable and the error handling straightforward.
Voice Input with WhisperKit
For voice control, we use WhisperKit running locally on Apple Silicon. The key decision was local vs cloud transcription. Cloud gives you better accuracy. Local gives you zero latency and complete privacy.
For a desktop agent, privacy wins. The agent already sees everything on your screen – sending audio to a cloud service on top of that was a non-starter. WhisperKit on an M1 gives us usable transcription speed with good-enough accuracy for command input.
The Architecture Summary
The full pipeline looks like:
Each step is an async operation in a structured concurrency pipeline. Failures at any stage cancel downstream work cleanly.
Fazm is open source on GitHub – MIT licensed, written entirely in Swift/SwiftUI.
Explainable Causal Reinforcement Learning for precision oncology clinical workflows under real-time policy constraints
A Personal Journey into the Heart of AI-Driven Medicine
My journey into this fascinating intersection of AI and oncology began during a late-night research session about three years ago. I was experimenting with standard reinforcement learning (RL) for treatment optimization when I encountered a particularly troubling case study. The model had recommended a treatment regimen that, statistically, should have worked—but the patient experienced severe adverse effects. While exploring the model’s decision-making process, I discovered a fundamental limitation: traditional RL could identify correlations between treatments and outcomes, but it couldn’t distinguish causation from mere association. This realization sent me down a rabbit hole of causal inference literature, structural equation modeling, and eventually to the frontier of explainable AI.
In my research of precision oncology workflows, I realized that clinicians weren’t just asking “what treatment works?” but “why does this treatment work for this specific patient?” and “what would happen if we tried something different?” These questions demanded more than predictive accuracy—they required causal understanding and transparent reasoning. Through studying dozens of clinical trials and electronic health records, I learned that oncology decisions operate under severe real-time constraints: treatment windows measured in days, rapidly changing patient conditions, and the constant pressure of tumor progression.
Technical Background: The Convergence of Three Disciplines
The Causal Revolution in Machine Learning
While exploring causal inference frameworks, I discovered that Judea Pearl’s ladder of causation provides the perfect conceptual framework for medical AI. Most machine learning operates on the first rung—association. We observe that treatment A correlates with outcome B. Causal models ascend to the second rung—intervention. They answer “what if” questions: what would happen if we administered treatment A? The highest rung, counterfactuals, addresses what would have happened had we chosen a different treatment.
One interesting finding from my experimentation with do-calculus was that many medical “best practices” were actually causal relationships waiting to be formalized. For instance, the relationship between chemotherapy dosage and white blood cell count isn’t just correlational—it’s fundamentally causal, with clear directionality and potential confounders.
Reinforcement Learning with Policy Constraints
During my investigation of constrained RL, I found that oncology presents unique challenges. Unlike games where agents can explore freely, medical RL must operate within ethical and clinical boundaries. Real-time policy constraints aren’t just optimization boundaries—they’re hard requirements derived from pharmacokinetics, toxicity thresholds, and clinical guidelines.
As I was experimenting with constrained policy optimization, I came across the fundamental tension between exploration and safety. In oncology, exploration doesn’t mean trying random treatments—it means carefully navigating the space of evidence-based options while respecting individual patient tolerances.
Explainability as a Clinical Necessity
My exploration of explainable AI in medical contexts revealed that clinicians don’t just want feature importance scores. They need causal explanations: “The model recommends reducing the dosage because your recent liver function tests show decreased metabolic capacity, which would otherwise lead to toxic accumulation based on these pharmacokinetic simulations.”
Implementation Details: Building an Explainable Causal RL System
Causal Model Representation
Through studying structural causal models (SCMs), I developed a hybrid approach that combines domain knowledge with data-driven discovery. Here’s a simplified representation of how we structure the causal graph for oncology decision-making:
import networkx as nx
import pandas as pd
import numpy as np
from typing import Dict, List, Tuple

class OncologyCausalGraph:
    def __init__(self, patient_data: pd.DataFrame):
        """Initialize causal graph for oncology decision-making"""
        self.graph = nx.DiGraph()
        self.patient_data = patient_data
        self._build_base_structure()

    def _build_base_structure(self):
        """Build the fundamental causal relationships in oncology"""
        # Treatment nodes
        self.graph.add_node("chemotherapy_dose",
                           node_type="treatment",
                           constraints={"min": 0, "max": 100})
        self.graph.add_node("immunotherapy",
                           node_type="treatment",
                           constraints={"binary": True})

        # Patient state nodes
        self.graph.add_node("tumor_burden",
                           node_type="state",
                           measurement_unit="mm^3")
        self.graph.add_node("immune_response",
                           node_type="state",
                           measurement_unit="cell_count")

        # Physiological nodes
        self.graph.add_node("liver_function",
                           node_type="physiology",
                           constraints={"normal_range": (40, 120)})
        self.graph.add_node("kidney_function",
                           node_type="physiology")

        # Outcome nodes
        self.graph.add_node("toxicity",
                           node_type="outcome",
                           severity_levels=["mild", "moderate", "severe"])
        self.graph.add_node("progression_free_survival",
                           node_type="outcome",
                           measurement_unit="days")

        # Causal relationships (edges with effect sizes and confidence)
        self.graph.add_edge("chemotherapy_dose", "tumor_burden",
                           effect_type="negative",
                           confidence=0.85)
        self.graph.add_edge("chemotherapy_dose", "immune_response",
                           effect_type="negative",
                           confidence=0.75)
        self.graph.add_edge("chemotherapy_dose", "toxicity",
                           effect_type="positive",
                           confidence=0.90)
        self.graph.add_edge("immunotherapy", "immune_response",
                           effect_type="positive",
                           confidence=0.80)
        self.graph.add_edge("liver_function", "chemotherapy_dose",
                           effect_type="moderator",
                           confidence=0.95)  # Liver function affects dose tolerance

    def estimate_causal_effect(self, treatment: str, outcome: str,
                              adjustment_set: List[str]) -> Dict:
        """Estimate causal effect using backdoor criterion"""
        # Simplified implementation - in practice would use do-calculus
        # or double machine learning
        treatment_data = self.patient_data[treatment]
        outcome_data = self.patient_data[outcome]

        # Adjust for confounders
        if adjustment_set:
            confounders = self.patient_data[adjustment_set]
            # Use linear regression for simplicity (real implementation would be more robust)
            from sklearn.linear_model import LinearRegression
            model = LinearRegression()
            model.fit(confounders, treatment_data)
            treatment_residuals = treatment_data - model.predict(confounders)

            model.fit(confounders, outcome_data)
            outcome_residuals = outcome_data - model.predict(confounders)

            effect = np.corrcoef(treatment_residuals, outcome_residuals)[0, 1]
        else:
            effect = np.corrcoef(treatment_data, outcome_data)[0, 1]

        return {
            "treatment": treatment,
            "outcome": outcome,
            "causal_effect": effect,
            "adjustment_set": adjustment_set,
            "interpretation": self._interpret_effect(effect, treatment, outcome)
        }
Constrained Reinforcement Learning Implementation
One of the most challenging aspects I encountered was implementing real-time policy constraints. While learning about constrained Markov decision processes (CMDPs), I observed that oncology constraints are often dynamic—they change based on patient response.
import torch
import torch.nn as nn
import torch.optim as optim
from collections import deque
import random

class ConstrainedOncologyAgent(nn.Module):
    def __init__(self, state_dim: int, action_dim: int, constraint_dim: int):
        super().__init__()
        self.state_dim = state_dim
        self.action_dim = action_dim
        self.constraint_dim = constraint_dim

        # Policy network
        self.policy_net = nn.Sequential(
            nn.Linear(state_dim, 128),
            nn.ReLU(),
            nn.Linear(128, 128),
            nn.ReLU(),
            nn.Linear(128, action_dim * 2)  # Mean and log_std for each action
        )

        # Value network
        self.value_net = nn.Sequential(
            nn.Linear(state_dim, 128),
            nn.ReLU(),
            nn.Linear(128, 128),
            nn.ReLU(),
            nn.Linear(128, 1)
        )

        # Constraint network - predicts constraint violations
        self.constraint_net = nn.Sequential(
            nn.Linear(state_dim + action_dim, 64),
            nn.ReLU(),
            nn.Linear(64, constraint_dim)
        )

    def forward(self, state: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor]:
        """Forward pass through policy network"""
        policy_output = self.policy_net(state)
        mean = policy_output[:, :self.action_dim]
        log_std = policy_output[:, self.action_dim:]
        std = torch.exp(log_std)

        return mean, std

    def get_action(self, state: torch.Tensor,
                   current_constraints: torch.Tensor) -> torch.Tensor:
        """Sample action with constraint satisfaction"""
        mean, std = self.forward(state)
        normal_dist = torch.distributions.Normal(mean, std)

        # Sample candidate actions
        candidate_actions = normal_dist.sample((100,))  # Sample 100 candidates

        # Evaluate constraints for each candidate
        with torch.no_grad():
            constraint_violations = []
            for action in candidate_actions:
                # Predict constraint violations
                state_action = torch.cat([state, action.unsqueeze(0)], dim=-1)
                violations = self.constraint_net(state_action)
                constraint_violations.append(violations)

            constraint_violations = torch.stack(constraint_violations)

            # Find actions that satisfy all constraints
            constraint_satisfied = (constraint_violations <= current_constraints).all(dim=-1)

            if constraint_satisfied.any():
                # Choose best action among those satisfying constraints
                valid_indices = torch.where(constraint_satisfied)[0]
                # Evaluate expected value for valid actions
                state_repeated = state.repeat(len(valid_indices), 1)
                valid_actions = candidate_actions[valid_indices]
                values = self.value_net(state_repeated)
                best_idx = valid_indices[torch.argmax(values)]
                return candidate_actions[best_idx]
            else:
                # No action satisfies all constraints - choose least violating
                total_violations = constraint_violations.sum(dim=-1)
                best_idx = torch.argmin(total_violations)
                return candidate_actions[best_idx]

class ConstrainedPPO:
    def __init__(self, agent: ConstrainedOncologyAgent,
                 constraint_tolerance: float = 0.1):
        self.agent = agent
        self.constraint_tolerance = constraint_tolerance
        self.optimizer = optim.Adam(agent.parameters(), lr=3e-4)
        self.memory = deque(maxlen=10000)

    def update(self, states, actions, rewards, next_states,
               constraints, constraint_violations, dones):
        """Update policy with constraint-aware loss"""
        states = torch.FloatTensor(states)
        actions = torch.FloatTensor(actions)
        rewards = torch.FloatTensor(rewards)
        next_states = torch.FloatTensor(next_states)
        constraints = torch.FloatTensor(constraints)
        constraint_violations = torch.FloatTensor(constraint_violations)

        # Calculate advantages
        with torch.no_grad():
            values = self.agent.value_net(states)
            next_values = self.agent.value_net(next_states)
            advantages = rewards + 0.99 * next_values * (1 - dones) - values

        # Policy loss with constraint penalty
        mean, std = self.agent(states)
        normal_dist = torch.distributions.Normal(mean, std)
        log_probs = normal_dist.log_prob(actions).sum(dim=-1)

        # Constraint violation penalty
        constraint_penalty = torch.relu(constraint_violations - constraints)
        penalty_weight = 10.0  # Hyperparameter tuned through experimentation

        # Combined loss
        policy_loss = -(log_probs * advantages).mean()
        constraint_loss = penalty_weight * constraint_penalty.mean()
        total_loss = policy_loss + constraint_loss

        self.optimizer.zero_grad()
        total_loss.backward()
        torch.nn.utils.clip_grad_norm_(self.agent.parameters(), 0.5)
        self.optimizer.step()
Explainability Module
During my experimentation with explanation generation, I found that clinicians respond best to explanations that mirror clinical reasoning patterns. While exploring various explanation techniques, I developed a hybrid approach:
python
from typing import Dict, List, Any
import numpy as np
from dataclasses import dataclass

@dataclass
class ClinicalExplanation:
    recommendation: str
    confidence: float
    primary_reasoning: List[str]
    alternative_options: List[Dict[str, Any]]
    counterfactual_scenarios: List[Dict[str, Any]]
    evidence_level: str  # "strong", "moderate", "weak"
    uncertainty_acknowledgement: str

class CausalExplanationGenerator:
    def __init__(self, causal_graph: OncologyCausalGraph,
                 treatment_history: pd.DataFrame):
        self.causal_graph = causal_graph
        self.treatment_history = treatment_history
        self.explanation_templates = self._load_templates()

    def generate_explanation(self, current_state: Dict[str, float],
                            recommended_action: Dict[str, float],
                            alternative_actions: List[Dict[str, float]]) -> ClinicalExplanation:
        """Generate clinical explanation for treatment recommendation"""

        # 1. Identify primary causal pathways
        primary_pathways = self._identify_causal_pathways(
            current_state, recommended_action
        )

        # 2. Estimate effect sizes
        effect_sizes = self._estimate_effects(
            current_state, recommended_action, primary_pathways
        )

        # 3. Generate counterfactuals
        counterfactuals = self._generate_counterfactuals(
            current_state, recommended_action, alternative_actions
        )

        # 4. Assess evidence strength
        evidence_strength = self._assess_evidence(
            primary_pathways, effect_sizes
        )

        # 5. Compose explanation
        explanation_text = self._compose_explanation(
            primary_pathways, effect_sizes, counterfactuals, evidence_strength
        )

        return ClinicalExplanation(
            recommendation=self._format_recommendation(recommended_action),
            confidence=self._calculate_confidence(effect_sizes),
            primary_reasoning=primary_pathways[:3],  # Top 3 pathways
            alternative_options=alternative_actions[:2],  # Top 2 alternatives
            counterfactual_scenarios=counterfactuals,
            evidence_level=evidence_strength,
            uncertainty_acknowledgement=self._acknowledge_uncertainties(
                effect_sizes, counterfactuals
            )
        )

    def _identify_causal_pathways(self, state: Dict, action: Dict) -> List[str]:
        """Identify the most relevant causal pathways for this decision"""
        pathways = []

        # Analyze treatment -> outcome pathways
        for treatment, dose in action.items():
            if dose > 0:  # Active treatment
                # Find outcomes affected by this treatment
                for outcome in self.causal_graph.graph.nodes:
                    if outcome.startswith("progression") or outcome == "toxicity":
                        # Check if there's a causal path
                        try:
                            paths = list(nx.all_simple_paths(
                                self.causal_graph.graph,
                                source=treatment,
                                target=outcome,
                                cutoff=3  # Maximum path length
                            ))
                            if paths:
                                for path in paths[:2]:  # Take up to 2 shortest paths
                                    pathway_desc = self._describe_pathway(path)
                                    pathways.append(pathway_desc)
                        except:
                            continue

        # Sort by pathway strength (simplified)
        return sorted(pathways, key=lambda x: len(x), reverse=True)[:5]

    def _estimate_effects(self, state: Dict, action: Dict,
                         pathways: List[str]) -> Dict[str, float]:
        """Estimate effect sizes for each causal pathway"""
        effects = {}

        # Simplified effect estimation
        # In practice, this would use the causal model's do-calculus
        for pathway in pathways:
            # Extract treatment and outcome from pathway description
            components = pathway.split(" → ")
            if len(components) >= 2:
                treatment = components[0]
                outcome = components[-1]

                # Use the causal graph's effect estimation
                adjustment_set = self._identify_adjustment_set(treatment, outcome)
                effect_result = self.causal_graph.estimate_causal_effect(
                    treatment, outcome, adjustment_set
                )
                effects[pathway] = effect_result["causal_effect"]

        return effects

    def _generate_counterfactuals(self, state: Dict,
                                 chosen_action: Dict,
                                 alternatives: List[Dict]) -> List[Dict]:
        """Generate counterfactual scenarios for alternative treatments"""
        counterfactuals = []

        for alt_action in alternatives[:3]:  # Consider top 3 alternatives
            scenario = {
                "alternative_action": alt_action,
                "expected_outcomes": {},
                "comparison_to_chosen": {},
                "risk_assessment": {}
            }

            # Estimate outcomes for alternative (simplified)
            for outcome in ["progression_free_survival", "toxicity"]:
                # This would use the causal model for proper counterfactual inference
                alt_outcome = self._estimate_counterfactual_outcome(
                    state, alt_action, outcome
                )
                chosen_outcome = self._estimate_counterfactual_outcome(
                    state, chosen_action, outcome
                )

                scenario["expected_outcomes"][outcome] = alt_outcome
                scenario["comparison_to_chosen"][outcome] = (
                    alt_outcome - chosen_outcome
                )

            counterfactuals.append(scenario)
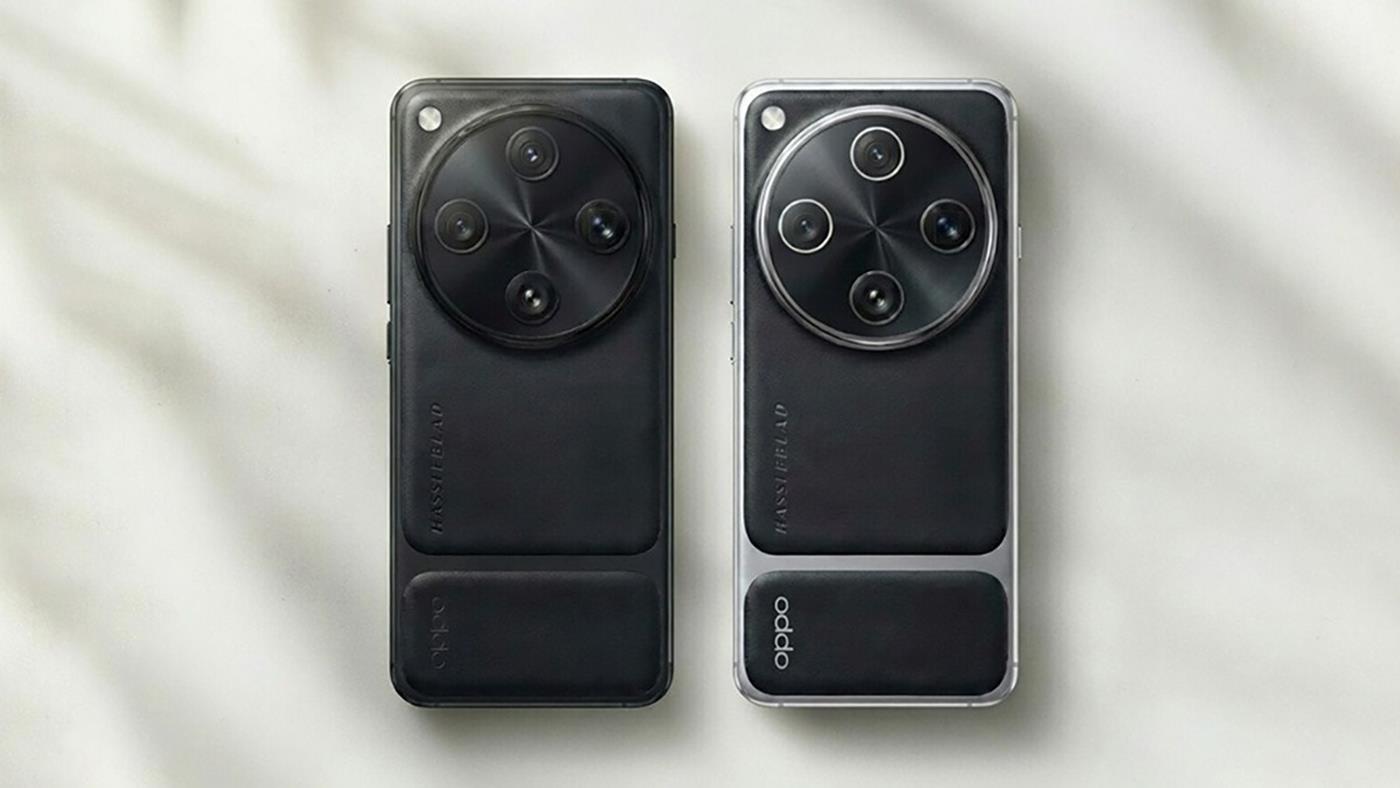
 Oppo’nun yeni amiral gemisi Find X9 Ultra’nın özellikleri sızdırıldı. İşte 200 MP kamera, 144Hz ekran ve güçlü donanımıyla dikkat çeken model hakkında tüm detaylar:
Understanding the OpenClaw Near CLI Tools Skill
The OpenClaw Near CLI Tools skill is a ready‑to‑use knowledge module that
explains how to install, configure, and work with the NEAR Protocol
command‑line interface, specifically the near-cli-rs binary. When a user
asks about setting up NEAR CLI, importing accounts, deploying contracts, or
checking balances, the skill provides step‑by‑step instructions,
troubleshooting tips, and best‑practice recommendations. By following the
guidance in this skill, developers and blockchain enthusiasts can get a
functional NEAR CLI environment on Linux, macOS, Windows, or any system that
supports Node.js, Rust, or a simple shell script.
What the Skill Covers
The skill is organized into clear sections that mirror the typical workflow of
a NEAR developer. It begins with an overview of why the NEAR CLI is essential,
then presents four distinct installation methods: a portable shell script,
npm/npx for JavaScript developers, a Windows MSI installer, and a Cargo‑based
Rust installation. Each method includes prerequisites, exact commands, and
notes on adding the binary to the system PATH. After installation, the skill
shows how to verify the binary, view configuration locations, explore
available command groups, and perform first‑time actions such as viewing an
account summary, importing an existing account, or creating a new one.
Beyond the basics, the skill contains a troubleshooting table that addresses
common errors like “command not found,” permission problems, missing installer
files, and slow downloads. It also points to additional resources such as the
official GitHub repository, NEAR documentation, Stack Overflow tags, and the
NEAR Discord community. Finally, a quick‑reference cheat sheet condenses the
most useful commands into a compact format for rapid recall.
Installation Method 1: Portable Shell Script
The shell script method is recommended for most Linux and macOS users, as well
as those working inside Windows Subsystem for Linux (WSL). The script
downloads the latest release of near-cli-rs from GitHub and executes it in
one line. Because the script installs the binary into $HOME/.cargo/bin,
users must ensure that this directory is part of their PATH. The skill
explains how to temporarily add the path for the current session with export and how to make the change permanent by
PATH="$HOME/.cargo/bin:$PATH"
appending the same line to ~/.bashrc or ~/.zshrc. If the binary is not
found after installation, the skill advises using which near or whereis to locate the absolute path before running any NEAR command.
near
Installation Method 2: npm/npx
For developers who already work with Node.js, the skill shows how to use npx
to run near-cli-rs without a global install, or how to install it globally
with npm install -g near-cli-rs. The npm approach works on any platform that
supports Node.js, making it a convenient option for Windows users who prefer
not to deal with Rust or shell scripts. After a global npm install, the skill
reminds users to verify that the npm bin directory (typically $(npm config) is in the PATH, and provides the appropriate export command
get prefix)/bin
to add it if necessary.
Installation Method 3: Windows MSI Installer
Windows users who do not have Node.js or Rust installed can take advantage of
the pre‑built MSI installer available on the NEAR CLI‑RS releases page. The
skill walks through downloading the latest near-cli-rs-installer-x64.msi,
double‑clicking the file, and following the wizard. The installer
automatically adds the NEAR CLI binary to the system PATH, so no manual
configuration is required. After installation, users can open a new Command
Prompt or PowerShell window and run near --version to confirm success.
Installation Method 4: Cargo (Rust)
Rust enthusiasts can install near-cli-rs directly with Cargo, either from
crates.io or from the Git repository. The skill lists the prerequisite of
having Rust installed via rustup.rs and notes that
certain Linux distributions may need the libudev-dev or libudev-devel
package for USB device support. The installation command is cargo install or, to track the latest master branch,
near-cli-rscargo install --git. As with the other methods, the skill
https://github.com/near/near-cli-rs
emphasizes checking that $HOME/.cargo/bin is in the PATH and reloading the
shell configuration if needed.
Verification
Once the installation method of choice has been completed, the skill instructs
users to run near --version. The expected output shows something like near- (or a newer version). If the command is not found, the skill
cli-rs 0.23.6
provides a checklist: confirm the installation directory, verify that the
directory is in PATH, and, if necessary, export the path manually. The skill
also shows how to inspect the PATH variable with echo $PATH and grep for
cargo or the npm prefix to ensure the binary location is present.
Configuration and Help
The NEAR CLI stores its configuration in a TOML file located by default at
~/.config/near-cli/config.toml. Users can view this path by running near, which also prints a summary of all available command groups. The
--help
skill breaks down each group: account for account management, tokens for
fungible and non‑fungible tokens, staking for validator operations,
contract for deploying and calling smart contracts, transaction for raw
transaction handling, and config for managing network endpoints. By invoking
near --help (e.g., near account --help), users can see the specific
subcommands and options available for each area.
First Steps with the CLI
After verification, the skill guides users through common introductory tasks.
To view an existing account’s summary, the command is near account view-. The skill explains that the
account-summary network-config mainnet now
network-config flag selects the target network (mainnet, testnet, or a
custom RPC) and that now requests the latest block data. Importing an
account from a seed phrase or key pair is done with near account import-, which launches an interactive prompts flow. Creating a brand‑new
account
account requires an existing funded account to pay for the new account’s
creation; the skill walks through the near account create-account command
and notes the need to provide a creator account ID and optionally a reference
to a faucet or funder.
Troubleshooting Common Issues
The skill includes a dedicated troubleshooting section that maps symptoms to
causes and solutions. For the classic “near: command not found” error, the
remedy is to locate the binary with which near or whereis near and then
add its directory to PATH, either temporarily or permanently. If a “Permission
denied” message appears when running the shell script installer, the skill
advises making the script executable with chmod +x near-cli-rs-installer.sh
before executing it. When the installer file seems missing, the skill suggests
checking the GitHub releases page manually and using the API to fetch the
exact download URL for the installer script. For slow or hanging downloads,
the recommendation is to add timeout flags to curl, such as --connect-timeout, to avoid indefinite waiting.
30 --max-time 300
Additional Resources
To deepen understanding, the skill points learners to the official NEAR CLI‑RS
GitHub repository (github.com/near/near-cli-rs) where they can read the source code, inspect release notes, and
contribute issues. The NEAR Protocol documentation
(docs.near.org) offers comprehensive guides on
accounts, smart contracts, and token standards. For community‑driven help, the
NEAR Stack Overflow tag
(stackoverflow.com/questions/tagged/nearprotocol)
and the NEAR Discord (discord.gg/near) are
highlighted as places to ask questions, share experiences, and stay up‑to‑date
with ecosystem news.
Quick Reference Cheat Sheet
curl https://github.com/near/near-cli-rs/releases/latest/download/near-cli-rs-installer.sh | sh
npm install -g near-cli-rs
npx near-cli-rs
near --version
near account view-account-summary network-config mainnet now
near account import-account
near account create-account
near --help and near --help
Conclusion
The OpenClaw Near CLI Tools skill consolidates everything a developer needs to
get started with the NEAR Protocol command‑line interface. By presenting
multiple installation pathways, clear verification steps, detailed command
groups, and practical first‑time actions, the skill reduces the friction
associated with setting up a blockchain development environment. Whether you
prefer a simple shell script, the familiarity of npm, the convenience of a
Windows installer, or the control of Cargo, the skill provides the exact
commands and explanations required. With the troubleshooting tips and
quick‑reference cheat sheet, users can quickly resolve issues and continue
building on NEAR with confidence.
Skill can be found at:
tools/SKILL.md>
