NASA yılın ilk uzay yürüyüşünü gerçekleştiriyor: Nasıl izlenir?
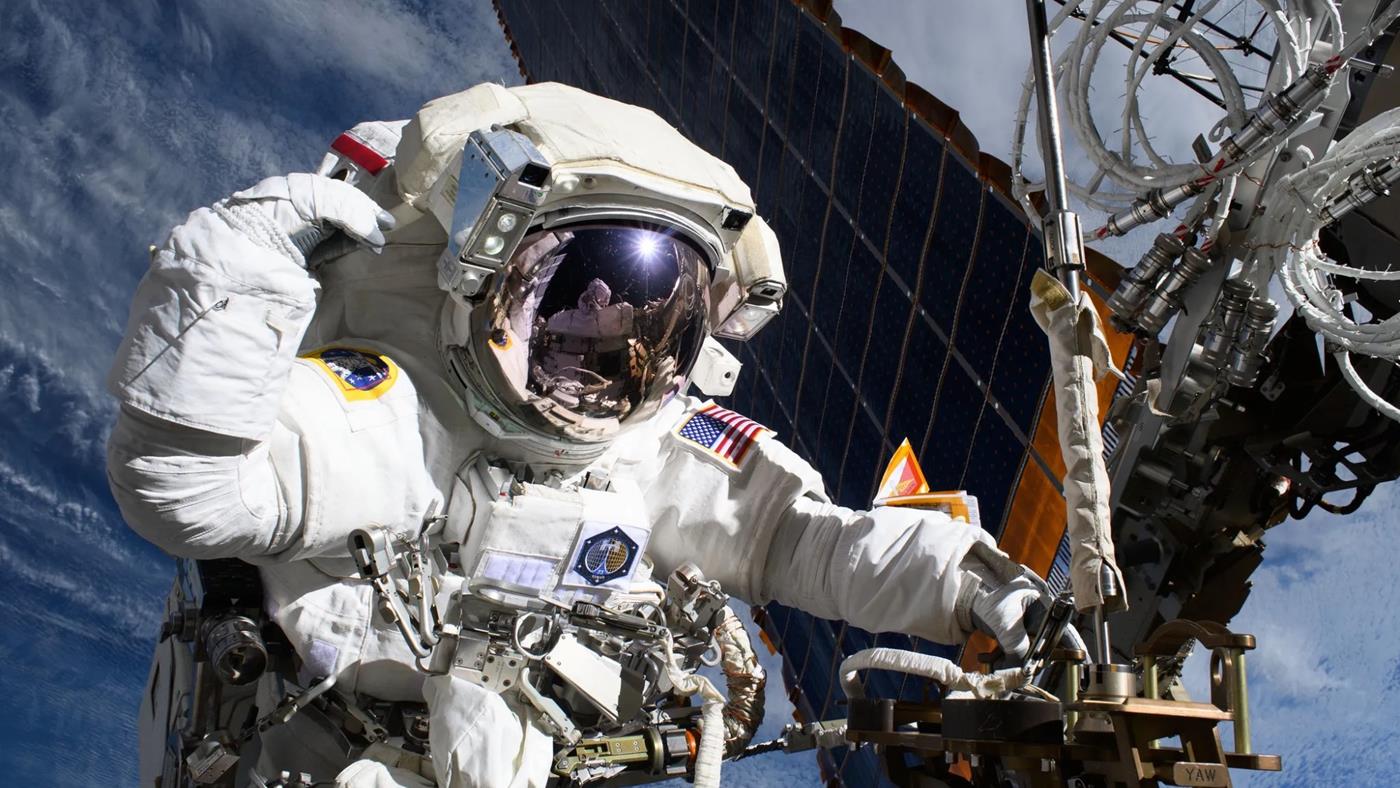
 NASA, 18 Mart’ta uzun süredir ertelenen uzay yürüyüşünü gerçekleştirecek. Astronot Jessica Meir ve Chris Williams, uzun soluklu görevde istasyonun dışında çalışacak.

 Mert
NASA, 18 Mart’ta uzun süredir ertelenen uzay yürüyüşünü gerçekleştirecek. Astronot Jessica Meir ve Chris Williams, uzun soluklu görevde istasyonun dışında çalışacak.
Look, I’m not gonna front like I came into this with some grand research agenda. I’m a CS student from Las Vegas. No lab backing me. No funding. No pedigree. Just a dude who got genuinely frustrated watching multi-agent AI systems fall apart at the seams and decided to do something about it.
What I built is called XP-Arc. Named after my daughters, Xyla and Peace. Public meaning: Exponential Architecture. Private meaning: it should outlast everything built on top of it.
Here’s the thing that nobody’s really solving right now —
Agent pipelines keep failing the same three ways and everyone acts surprised
First way: silent data loss. An agent hits an entity type it can’t process and just… drops it. No log. No flag. No signal. The intelligence map has a hole and nobody knows.
Second way: cascade corruption. One agent writes bad output. The next agent downstream eats it as gospel. By the time it hits the end of the pipeline the output is confidently, catastrophically wrong.
Third way: brittle orchestration. Everything works beautifully until one component hiccups — then the whole thing stalls. Because nobody planned for failure. They just planned for success.
This isn’t bad luck. This is what happens when you build agent systems as chains — A calls B calls C — instead of building them as actual systems with shared state, typed routing, and real degradation logic.
That’s what XP-Arc fixes. All three. By design, not by patch.
The blueprint came from a dead French chef Auguste Escoffier. 1900. The dude didn’t invent cooking — he invented the system that makes professional kitchens run under pressure. Defined roles. Clean handoffs. One person standing at the pass whose whole job is making sure nothing leaves the kitchen wrong.
When I found that system I didn’t see a restaurant. I saw a multi-agent architecture that had been battle-tested for 125 years.
The mapping isn’t a metaphor. It’s a spec.
Escoffier Role: XP-Arc Station
The Job: Garde Manger
The Forager: Raw intelligence acquisition
Saucier: The Analyst – Relationship inference
Entremetier: The Mapper – Structural intelligence
Rotisseur: The Chronicler – Temporal tracking
Poissonnier: The Sentinel – Anomaly detection
Aboyeur: The Aboyeur QA enforcement — nothing moves without clearance
*R&D Lateral Mesh: *– Stress-tests the system from outside the active brigade
The Aboyeur is the whole game. In Escoffier’s kitchen the expeditor stands at the pass and checks every single plate before it goes to the dining room. In XP-Arc the Aboyeur node validates every station output against a formal schema before anything propagates downstream.
Can’t bypass it. Can’t configure it away. It’s structural.
One shared surface instead of a chain.
Every agent in XP-Arc reads from and writes to a single SQLite state machine — the Intelligence Pool. Nobody talks directly to nobody else. Everything flows through the pool.
One seed URL hits the pool. The Executive wakes up, reads the entity type, routes it to the right station. That station extracts new entities, writes them back. Which wakes the Executive again. Which routes again.
One seed becomes a cascade. I call it the Exponential Snowball. You plant one thing and the whole intelligence picture assembles itself — automatically, recursively, without you touching it again.
What happens when things break — Fracture Protocol
When a primary station fails or comes back with low confidence output, XP-Arc doesn’t just hand the same task to a weaker agent and hope for the best.
It fractures the task.
Breaks it into atomic micro-tasks. Routes each one to a lightweight local model — Llama 3 8B, Mistral 7B — each one operating with a narrow, precisely scoped job. One question. One data source. One output format.
Small models choke on complex multi-dimensional tasks. But give them one thing to do and they perform. Shard the load, shard the requirement for expensive inference.
The pool tracks the whole lifecycle:
raw → processing → failed → fractured → stitchable → mapped
Downstream stations see one clean mapped entity. The whole fracture happened behind the scenes. Invisible.
Zoran’s Law
Every adaptive system has a tipping point. XP-Arc’s is this:
**S > 1: **When the correction rate outpaces the informational decay rate, the system self-heals.
When 70% or more of your stations are running primary roles — not fallbacks — the system hits coherent intelligence output. That’s the Zoran Threshold. Below it, the brigade degrades gracefully. The Sentinel watches this ratio live and tells you exactly where you stand.
The system knows its own health. That transparency is the feature.
You drop a seed URL in. Watch the graph build itself in real time. Nodes pop as entities get extracted. Edges draw themselves as relationships get inferred. The shadow infrastructure of any target just… maps itself. On screen. While you watch.
The stack
Python 3.12
Zero external dependencies — stdlib only, no installs, no lock files
SQLite state machine
Compatible with A2A and MCP by architecture, not retrofit
MIT licensed — take it, fork it, build on it
Real talk — what’s done and what isn’t
The PoC runs clean. The Snowball executes. The Forager extracts. DRAGON visualizes live.
What’s not done yet: full Aboyeur validation, pool authentication, production-scale benchmarks. I documented every one of those gaps openly in the whitepaper security section. Named my own vulnerabilities before anyone else got the chance.
A framework that can’t account for its own attack surface doesn’t deserve to be trusted with yours.
Come find the flaws:
Full whitepaper. Full source. Aboyeur Protocol schema. All of it open.
github.com/UnkleJack/xp-arc
Las Vegas-born CS student. No lab. No funding. No pedigree. Just a regular dude who built something real.
Go see it live: unklejack.zo.space/dragon
I recently hit a common architectural fork in the road while building my ADK (Agent Development Kit) application.
Initially, I was using Chroma as my RAG (Retrieval-Augmented Generation) backend. It works perfectly for local development, but things got complicated when moving to the cloud. I needed a production-ready, resilient solution that didn’t involve managing stateful assets on a Mac Mini or paying for a separate managed vector database.
The solution was already right in front of me: Postgres 🐘.
By using pgvector, you can turn your relational database into a powerful vector store. This is especially seamless if you use Supabase, which can host small databases for free or provide a “Pro” tier for a reasonable price.
Why I Swapped MCP for genai-toolbox
In my previous setup, I used an chroma mcp server. However, for my relational data, I was already relying heavily on genai-toolbox.
I realized I could simplify my architecture significantly by dropping the separate MCP server and Chroma dependency in favor of extending my tools.yaml. In engineering, if I can remove a dependency without losing functionality, I don’t hesitate.
Here is the configuration change:
embeddingModels:
  gemini-emb:
    type: gemini
    model: text-embedding-004
    dimension: 768

tools:
  add-document:
    kind: postgres-sql
    source: naati-db
    description: >-
      Adds a document to the RAG database. The 'content' will be automatically embedded.
    parameters:
      - name: content
        type: string
        description: The raw text content to be stored in the database.
      - name: vector_string
        type: string
        # This parameter is hidden from the LLM.
        # It automatically copies the value from 'content' and embeds it.
        valueFromParam: content
        embeddedBy: gemini-emb
        description: This parameter is hidden from the LLM.
      - name: metadata
        type: string
        description: >-
          JSON string representing metadata (e.g., '{"file_name": "tos.docx"}').

  query-documents:
    kind: postgres-sql
    source: naati-db
    description: >-
      Performs a semantic similarity search on the RAG database using the provided query text.
    parameters:
      - name: query
        type: string
        description: >-
          The search query text to embed and search for.
        embeddedBy: gemini-emb
      - name: limit
        type: integer
        description: >-
          Maximum number of results to return.
        default: 5
    statement: >-
      SELECT content, metadata
      FROM documents
      ORDER BY embedding <=> $1::vector
      LIMIT $2::int;
And it works like a dream. Access to data and knowledge is now unified and goes via genai-toolbox
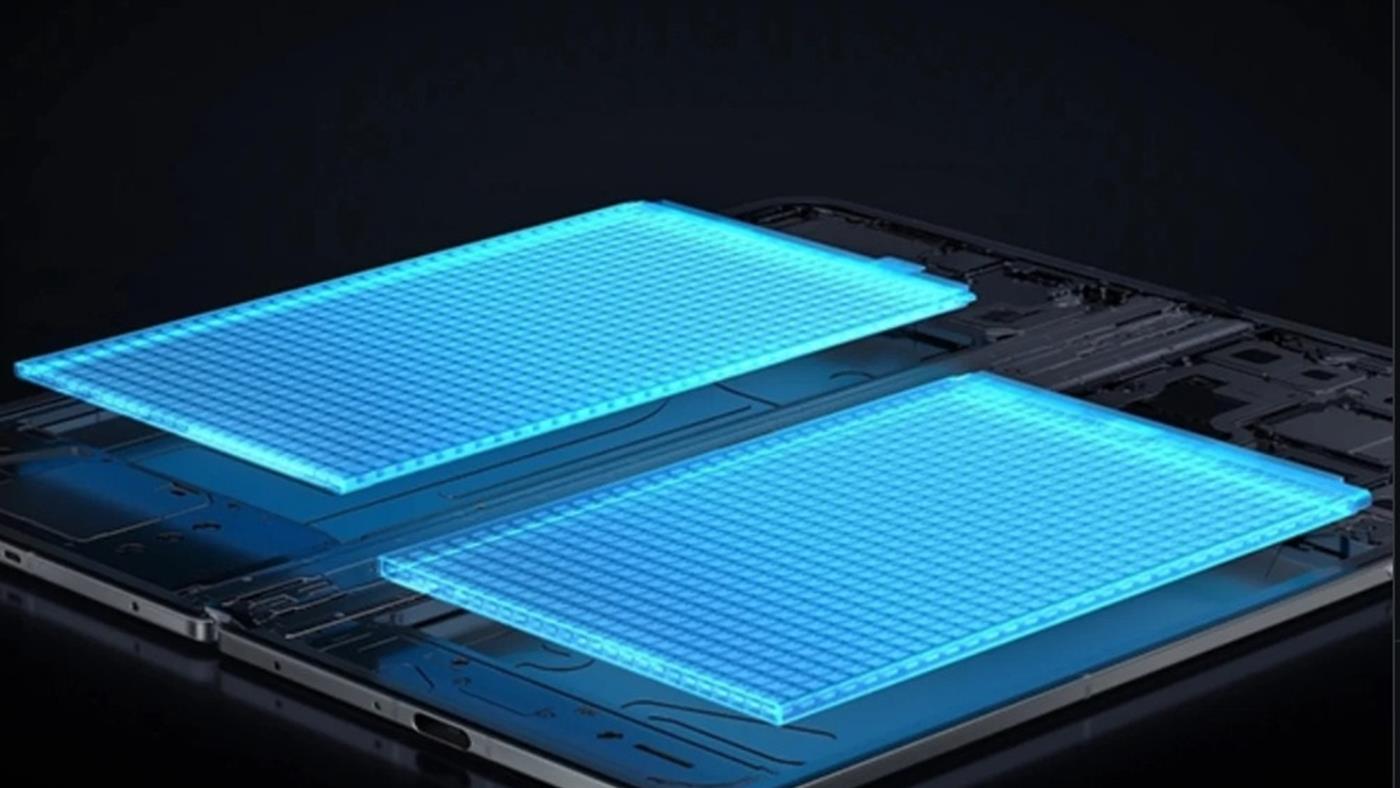
 Lenovo, dizüstü bilgisayarlar için geliştirdiği yeni batarya teknolojisini tanıttı. Şirket, 1.000Wh/L enerji yoğunluğuna sahip silikon anotlu bataryanın, bu alanda dünyada bir ilk olduğunu belirtiyor.
Model Context Protocol (MCP) has quickly moved from concept to conversation starter across the AI engineering community. The concept is promising — give your AI models structured access to real tools and watch them transform from chatbots into agents that get work done.
But introducing MCP introduces real complexity, costs, and risks that don’t appear in the initial stage. It’s powerful when your users need it, and expensive over-engineering when they don’t. In this post, we’ll cut through the hype to examine the trade-offs that matter in production: when benefits of MCP justify the costs, where simpler approaches work better, and what hidden challenges emerge once you move past the POC phase.
What is MCP and an MCP Server?
MCP is an emerging standard that helps large language models (LLMs) interact with external tools, services, and data in a consistent and predictable way. In simple terms, MCP gives AI models a common language for using tools.
Think of it like a universal plug adapter for AI. Instead of teaching every model how to talk to every API or database separately, MCP defines one standard way to do it. Once a tool is connected through MCP, different AI models can use it without needing custom integrations each time.
An MCP Server runs this protocol and acts as a middle layer between AI models and real-world systems like APIs, databases, or internal apps. Developers define tool connections once on the MCP server and can then reuse them across models from different providers, saving time and reducing duplicated work.
The architecture at a high level: the LLM talks to the MCP server using the MCP protocol, and the MCP server handles communication with the actual tools and data sources behind the scenes.
Benefits of Adding MCP Servers to Your Software
MCP servers provide a durable architectural layer that helps organizations scale AI capabilities without locking into specific models or vendors. They shift AI integrations from short-term hacks to long-term infrastructure.
Standardization and Interoperability
MCP introduces a unified, model-agnostic protocol for accessing tools and resources, allowing AI systems to interact with enterprise data and services through a consistent interface. This abstraction decouples AI applications from individual model providers, allowing organizations to integrate new models or switch providers without rewriting downstream integrations.
Developer Velocity and Resource Efficiency
By separating model reasoning from tool execution, MCP simplifies system design and reduces integration complexity. Tools implemented once on an MCP server can be reused across multiple applications, models, and teams — eliminating duplicated effort and accelerating delivery of new AI capabilities. Over time, this reuse compounds: each new tool becomes shared infrastructure, increasing overall development efficiency and lowering marginal costs for future AI initiatives.
Centralized Control and Governance
An MCP server provides a single point of control for managing tool behavior, permissions, updates, and access policies across all AI clients. This centralization makes it easier to enforce compliance requirements, maintain audit trails, and implement consistent security controls — while supporting multi-client and multi-model architectures.
Architectural Flexibility for Growth
MCP enables organizations to add, modify, or remove tools without redeploying AI applications, reducing operational risk and increasing adaptability. As business needs, workflows, and regulatory environments change, the architecture can evolve without costly rewrites. MCP becomes a durable foundation that grows alongside an organization’s AI maturity.
Hidden Costs: What MCP Adoption Really Means
While MCP promises elegant AI-tool integration, the path from proof-of-concept to production adds operational, performance, and organizational complexity that teams must be prepared to absorb.
Operational Burden and Complexity Tax
An MCP server is not a thin abstraction layer — it is a long-lived distributed system. It requires deployment pipelines, configuration management, backward-compatible schema evolution, and capacity planning. Unlike one-off integrations, MCP introduces ongoing responsibilities that scale with usage, appearing gradually during incident handling and dependency changes.
Performance Trade-offs
Introducing MCP adds an extra network hop for each tool invocation, often in the range of tens to hundreds of milliseconds, which can compound noticeably in multi-step or agentic workflows. Under high load, the MCP server can become a bottleneck if not properly scaled, cached, or tuned. Achieving acceptable performance typically requires additional engineering investment in concurrency management, caching strategies, and performance monitoring.
Security Risks if Misconfigured
MCP centralizes access to powerful tools and sensitive data, which increases the blast radius of configuration errors. Overexposed tools or overly permissive schemas can lead to unintended data access, while prompt-driven misuse can cause models to invoke tools in unsafe ways. Without carefully designed permission models, input validation, and guardrails, misconfigurations can be exploited either accidentally or maliciously.
A Nascent Ecosystem
MCP is still an evolving standard, with fewer mature, off-the-shelf tools compared to traditional API ecosystems. Best practices, architectural patterns, and operational playbooks are still emerging — which increases uncertainty and experimentation costs. For simple or single-purpose integrations, MCP may introduce more complexity than value.
Debugging and Observability Challenges
Failures in an MCP-based system often span multiple boundaries: model reasoning, protocol translation, network calls, and downstream services. Non-deterministic LLM behavior makes issues harder to reproduce and diagnose, increasing mean time to resolution. Effective operation requires sophisticated observability infrastructure — logging, tracing, and metrics — adding further tooling and operational investment.
When MCP Is the Wrong Choice: Critical Red Flags
Customer-Facing Latency Sensitivity
MCP introduces per-call overhead that degrades real-time UI experiences, where streaming connections amplify delays in interactive workflows. Transactional paths suffer from routing everything through the protocol, as burst requests from LLMs overwhelm simpler direct APIs. Sidecar integrations or non-blocking patterns deliver better responsiveness here.
Minimal Tool or Static Integrations
Stable, limited tools lead to bloated schemas repeated across interactions, wasting context without delivering dynamic benefits. Direct function calls or basic RAG pipelines handle these more efficiently. Short sessions accumulate unnecessary history, favoring prompt-level optimizations over protocol layers.
Regulated or Enterprise Security Gaps
Absence of built-in SSO, audit trails, and fine-grained authorization leaves regulated setups vulnerable to unmonitored shadow servers and injection risks in containerized deployments. Tool poisoning enables scope overrides, requiring custom gateways beyond the core spec.
Immature Teams or Shadow Deployments
When servers are set up without clear ownership or rules, it leads to inconsistent configurations, poor visibility, and slower troubleshooting. Teams without platform discipline may find that MCP increases complexity instead of improving efficiency. For smaller or early-stage use cases, simple direct LLM API calls are usually enough. You don’t need full orchestration until your AI usage becomes more central and complex.
AI as a Peripheral Feature
If AI is just an occasional enhancement — like “adding a chatbot to a settings page” — MCP’s architecture is overkill. In these cases, a simple call to your LLM provider’s API with some context from your database is enough. You don’t need servers, tool schemas, or protocol layers. MCP only makes sense when AI needs to orchestrate multiple tools or capabilities.
Decision Framework for Adopting MCP Servers
Complexity Assessment
Begin by assessing both current and anticipated AI requirements, including the number of models, tools, integrations, and teams involved. The key question is whether complexity is already causing friction or is credibly projected based on the roadmap — rather than being hypothetical. MCP introduces an abstraction layer, so ask yourself: does this layer solve a real coordination, scaling, or governance problem, or does it simply add unnecessary infrastructure?
Team Capability Audit
Evaluate whether your organization has the platform engineering maturity required to implement and operate an MCP server effectively. This includes operational capabilities such as monitoring, incident response, versioning, and access control — as well as a realistic skills gap analysis around distributed systems and API design. MCP can create long-term leverage, but only if the team can properly build, maintain, and evolve the platform without becoming a bottleneck.
Total Cost of Ownership (TCO) Calculation
Look beyond initial implementation costs to understand the full TCO over time. This should include migration effort, infrastructure and operational overhead, training or hiring costs, and opportunity costs. Weigh these against benefits in your specific context: reduced rework, faster delivery, improved governance, and increased vendor optionality.
Strategic Alignment
Assess whether MCP aligns with your broader business and AI strategy. Vendor optionality is most valuable when AI is central to your product or operating model, or when regulatory, cost, or performance considerations may force provider changes. Consider your risk tolerance for adopting an emerging standard and whether MCP supports your long-term AI roadmap rather than short-term experimentation.
Pilot Before Commitment
Before committing broadly, start with a constrained pilot using a non-critical application and a limited set of tools. This allows teams to validate assumptions, uncover operational challenges, and measure real-world benefits in their environment.
Common Pitfalls Organizations Fall Into
Exposing Overly Powerful Tools
A frequent mistake is exposing broad, high-privilege tools to models instead of narrowly scoped capabilities. This increases the risk of unintended actions, data leakage, or destructive operations — especially when models behave unpredictably or are influenced by ambiguous prompts.
Treating MCP As a Security Boundary By Itself
MCP is an integration protocol, not a security control. Relying on it as the sole line of defense — without downstream authorization, validation, and rate limiting — creates a false sense of safety and leaves systems vulnerable to misuse or exploitation.
Skipping Monitoring and Logging
Without comprehensive logging and monitoring, MCP-driven systems become opaque and difficult to debug. Teams often underestimate how essential visibility is for understanding tool usage, diagnosing failures, and responding quickly to incidents in non-deterministic AI workflows.
Allowing Unrestricted Model Access to Production Systems
Giving models direct, unrestricted access to production resources dramatically increases operational risk. Safe architectures enforce environment boundaries, approval gates, and least-privilege access — ensuring that models cannot independently execute high-impact actions without safeguards.
Conclusion
While MCP servers offer powerful capabilities for connecting AI models to tools and data, they also introduce trade-offs in complexity, performance, and operational overhead. Using them indiscriminately adds unnecessary costs and security risks — MCP may not be the right choice for every application. Success depends on careful design, strong security, and platform engineering maturity.
Organizations should evaluate MCP adoption based on their specific use cases, weighing benefits against operational and architectural costs. When in doubt, consult experts before making the decision.
Originally published on Improving.com
 OpenAI, GPT-5.4 mini ve nano modellerini tanıttı. Daha hızlı çalışan ve düşük maliyet sunan bu modeller, kodlama, ajan sistemleri ve çok modlu görevlerde yüksek verimlilik vadediyor.
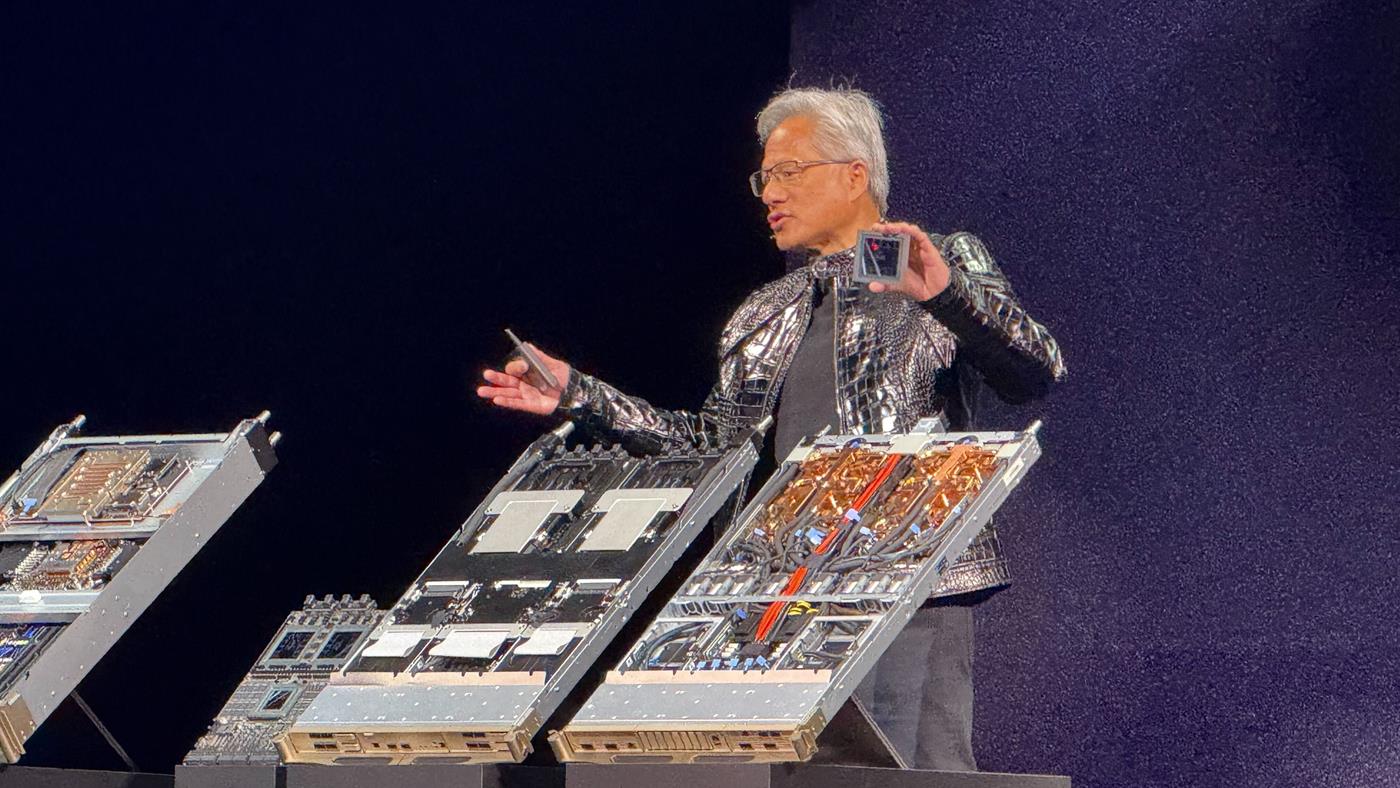
 Intel hisseleri, Nvidia GTC 2026 ve Xeon 6 duyurusu ile yükseliş gösterdi ancak gün içinde kâr alımları ve yatırımcıların temkinli yaklaşımıyla kazançlarının çoğunu geri verdi.
Oracle has released version 26 of the Java programming language and virtual machine. As the first non-LTS release since JDK 25, the final feature set includes 10 JEPs, five of which are still progressing through the preview and incubator stages. This release focuses on Java library improvements, language innovation, performance and security.
By Michael Redlich
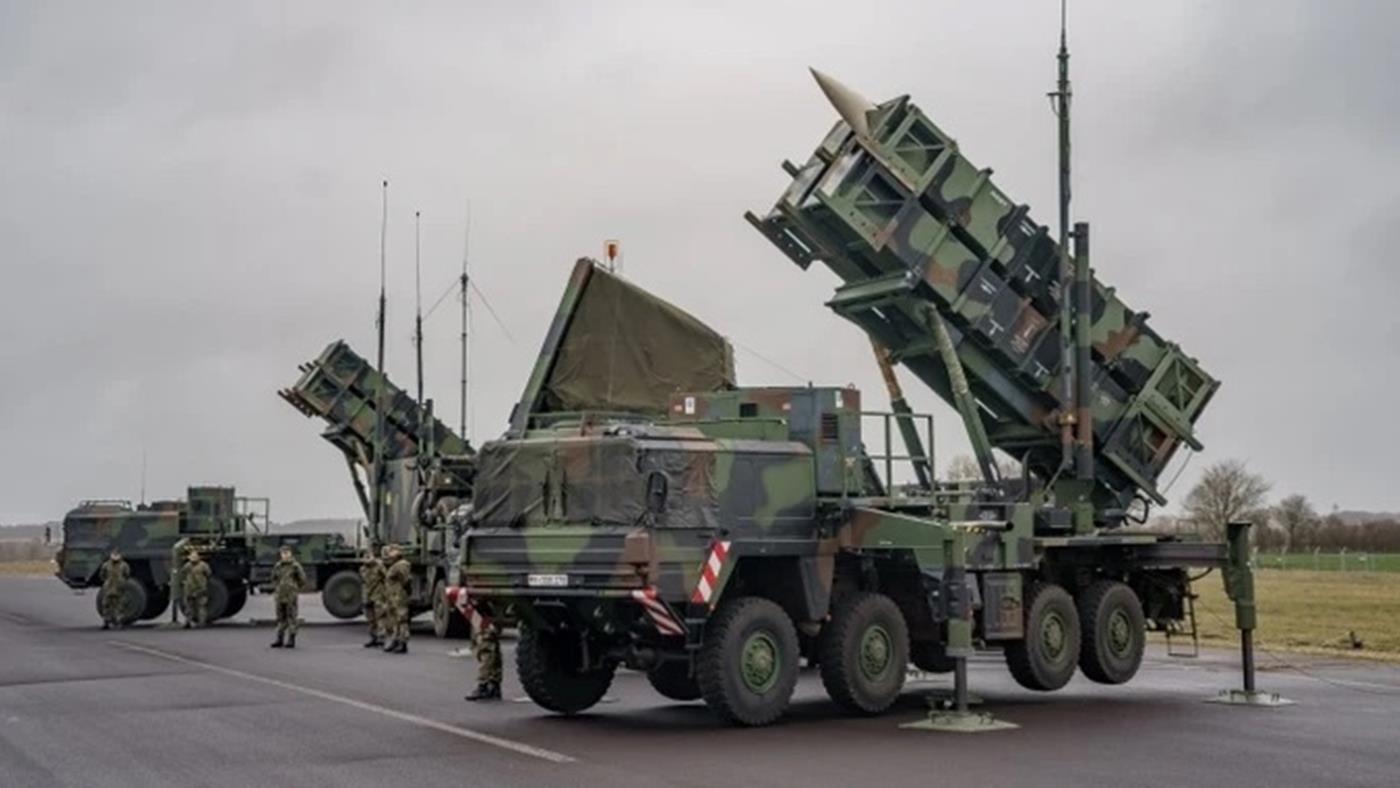
 Malatya’ya NATO tarafından kurulan Patriot hava savunma sistemine ek olarak şimdi de İncirlik Üssü’ne Almanya tarafından Patriot sistemi kuruluyor. Bu sistem, İncirlik’teki ikinci Patriot olacak.
 Intel, Core Ultra 200HX Plus işlemci serisini tanıttı. Yeni işlemciler, önceki nesle kıyasla küçük çaplı iyileştirmeler ve frekans artışı sunuyor. İşte özellikleri