Sony ve Honda, Afeela elektrikli araç projesini iptal etti
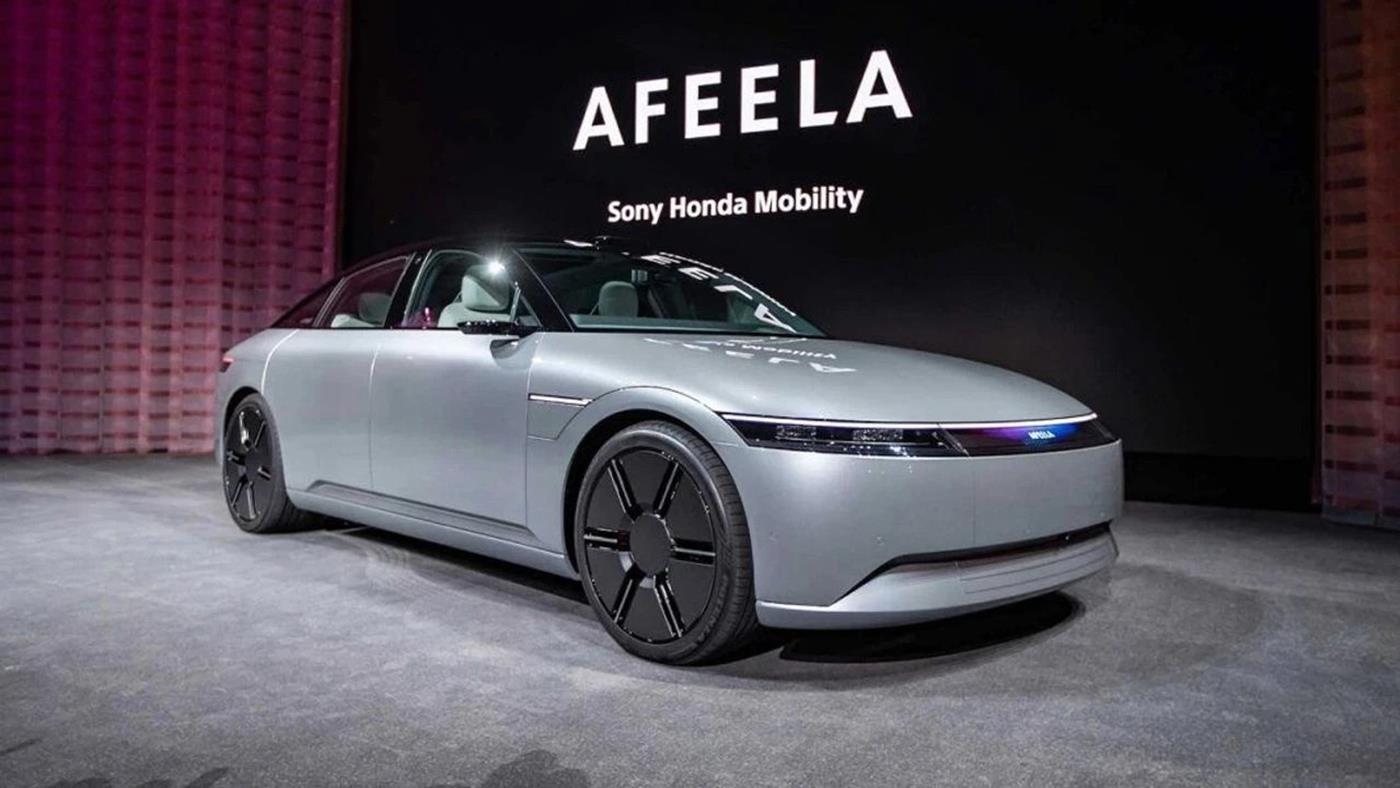
 Sony Honda Mobility, uzun süredir geliştirilen Afeela 1 ve Afeela 2 modellerinin geliştirme ve piyasaya sürülme planlarının iptal edildiğini duyurdu.

 Mert
Sony Honda Mobility, uzun süredir geliştirilen Afeela 1 ve Afeela 2 modellerinin geliştirme ve piyasaya sürülme planlarının iptal edildiğini duyurdu.
 Xbox Game Pass’i oyuncular için daha cazip hâle getirmenin yollarını arayan Microsoft, Netflix ile görüşüyor. İki şirket anlaşırsa, bu popüler iki servis tek bir pakette toplanabilir.
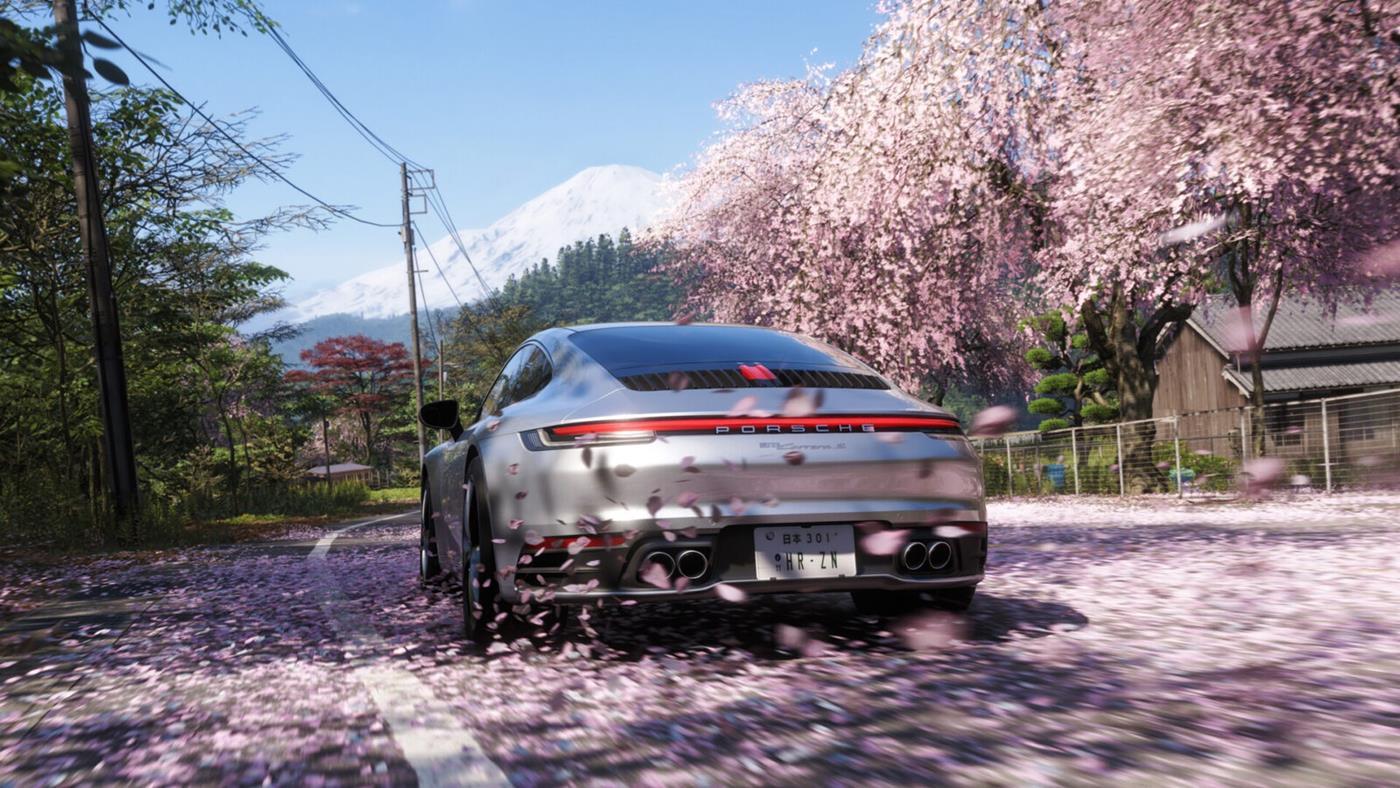
 Forza Horizon 6 sistem gereksinimleri resmi olarak açıklandı. Yarış oyunu, NVIDIA DLSS 4, AMD FSR 3/4 ve Intel XeSS 2.1 desteği ve daha akıcı performans için sınırsız kare hızıyla geliyor.
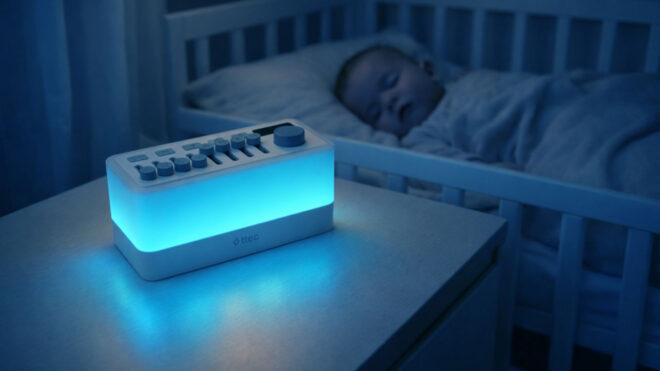
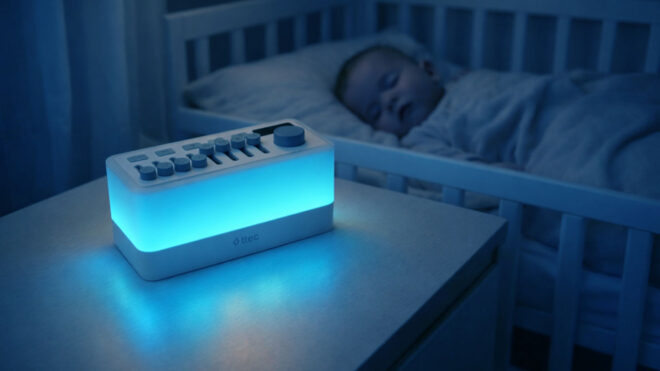 ttec, kişisel rahatlama ve huzur arayışını teknolojiyle buluşturan yenilikçi çözümler sunmaya devam ediyor. ttec Somno 3’ü 1 arada beyaz gürültü hoparlörü; uykuya geçişi kolaylaştırmadan meditasyona, yoga seanslarından çocukları sakinleştirmeye kadar pek çok farklı senaryoda kullanıcıların yanında oluyor. Beyaz gürültü, yağmur, okyanus dalgaları, fırtına, kamp ateşi, tren ve kuş sesleri gibi 8 farklı rahatlatıcı ses seçeneği sunan ttec Somno, 256 farklı ses kombinasyonu oluşturmaya imkan tanıyor. Bu sayede kullanıcılar, kendi ruh haline uygun ses ortamını kolayca yaratabiliyor. Bluetooth hoparlör özelliğiyle sevilen müzikleri de çalabilen Somno, 30 kademeli ayarlanabilir gece ışığı parlaklığı ve 11 farklı LED renk seçeneğiyle ortama görsel bir sıcaklık katıyor. Loş ışıkla uyku öncesi sakinlik, renkli ışıklarla sosyal anlar veya yumuşak tonlarla meditasyon ve yoga için ideal atmosfer oluşturulabiliyor. ttec Somno 3’ü 1 arada beyaz gürültü hoparlörü uzun pil ömrüyle öne çıkıyor Kompakt ve taşınabilir yapısı, zamanlayıcı fonksiyonu, LCD ekranı ve pratik kontrol tuşlarıyla kullanım kolaylığı sunan Somno, evde, […]
ttec’ten günün gürültüsünü dışarıda bırakan Somno 3’ü 1 arada beyaz gürültü hoparlörü yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Quick verdict


SonarQube is the industry standard for enterprise static analysis – deepest rule coverage, strongest quality gate enforcement, broadest language support, and battle-tested compliance reporting. DeepSource is the modern alternative with the lowest false positive rate in the category, AI-powered code review with structured PR report cards, and automated remediation that fixes issues rather than just flagging them.
Choose SonarQube if: you need the deepest deterministic rule coverage, self-hosted deployment, compliance reporting (OWASP, CWE, SANS, MISRA), or support for legacy languages like COBOL and ABAP. You have DevOps resources available for setup and maintenance.
Choose DeepSource if: you want the highest signal-to-noise ratio, AI-powered review and autofix, zero-infrastructure cloud setup, and a modern developer experience. You prioritize actionable findings over comprehensive rule counts.
For teams with 10-100 developers working in modern languages, DeepSource delivers the majority of SonarQube’s analysis capability with a fraction of the operational burden. For enterprises with compliance requirements, legacy codebases, and established DevOps teams, SonarQube remains the safer choice. This is the classic “established enterprise player vs modern cloud-native challenger” decision – and both sides of that trade-off are legitimate depending on your context.
At-a-glance comparison
| Feature | SonarQube | DeepSource |
|---|---|---|
| Category | Enterprise code quality platform | Modern AI-native code analysis |
| Users | 7M+ developers, 400K+ orgs | 2,000+ teams |
| Analysis rules | 6,500+ | 5,000+ |
| Languages (GA) | 35+ | 16 |
| False positive rate | Moderate (requires tuning) | Sub-5% |
| AI code review | AI CodeFix (basic) | Five-dimension PR report cards |
| Autofix | AI CodeFix (template-like) | Autofix AI (context-aware, LLM-powered) |
| Quality gates | Best-in-class enforcement | Supported |
| Technical debt tracking | Remediation time estimates | Code health dashboards |
| Security standards | OWASP, CWE, SANS, MISRA, CERT | OWASP Top 10, SANS Top 25 |
| Secrets detection | 400+ patterns | 30+ services |
| SCA (dependency scanning) | Advanced Security add-on (Enterprise) | Not available |
| IDE integration | SonarLint (connected mode) | VS Code, IntelliJ, PyCharm |
| Deployment model | Self-hosted (primary) or cloud | Cloud-native (primary), self-hosted Enterprise |
| Self-hosted | Yes (core offering) | Enterprise plan only |
| Free tier | Community Build + Cloud Free (50K LOC) | Free for individuals |
| Entry-level paid | ~$2,500/yr Developer (self-hosted) | $12/user/month Business |
| Pricing model | Lines of code | Per active contributor |
| Git platforms | GitHub, GitLab, Bitbucket, Azure DevOps | GitHub, GitLab, Bitbucket |
| Setup time | Minutes (cloud) to full day (self-hosted) | Under 10 minutes |
What is SonarQube?
SonarQube is the industry’s most established code quality and security platform, used by over 7 million developers and 400,000 organizations worldwide. Originally released by SonarSource in 2007 as an open-source project, SonarQube has spent nearly two decades building the deepest rule database, the most mature quality gate system, and the broadest language coverage in the static analysis category.
SonarQube operates on a continuous inspection model. It analyzes code on every commit and pull request, checking against thousands of rules that cover bugs, vulnerabilities, security hotspots, code smells, and duplication. Each finding is categorized by type, severity, and estimated remediation time. The results feed into quality gates – configurable thresholds that determine whether code is fit for merge or deployment.
The platform is available in multiple editions. The Community Build is free and open-source, supporting 20+ languages with basic quality gates and CI/CD integration. The Developer Edition (starting at approximately $2,500/year) adds branch analysis, PR decoration, and taint analysis. The Enterprise Edition (starting at approximately $20,000/year) adds portfolio management, advanced security reports, regulatory compliance mapping, and support for 35+ languages including enterprise legacy languages like COBOL, ABAP, and PL/SQL. SonarQube Cloud is the hosted alternative with a free tier for up to 50K lines of code.
SonarQube’s ecosystem advantage is substantial. With 7M+ users, there is extensive community documentation, Stack Overflow coverage, third-party integrations, and institutional knowledge. This maturity translates to lower risk for enterprise procurement.
What is DeepSource?
DeepSource is a modern, AI-native code analysis platform designed from the ground up for cloud-native development workflows. Founded in 2019, DeepSource represents a fundamentally different philosophy from SonarQube: rather than maximizing the number of rules and findings, DeepSource prioritizes the accuracy of each finding and the developer experience of acting on results.
DeepSource’s defining characteristic is its sub-5% false positive rate. While most static analysis tools, including SonarQube, produce a meaningful volume of false positives that require manual triage, DeepSource’s post-processing framework applies explicit and implicit signals to filter irrelevant results before they reach developers. When DeepSource flags an issue, it is almost certainly worth investigating. This high signal-to-noise ratio drives higher adoption rates and more consistent usage across engineering teams.
AI capabilities are central to DeepSource’s product. Its AI code review engine runs alongside static analysis on every PR, providing structured feedback across five dimensions: Security, Reliability, Complexity, Hygiene, and Coverage. Each PR receives a report card that gives developers a comprehensive quality snapshot without parsing through dozens of individual findings. Autofix AI generates context-aware, idiomatic fixes by analyzing imports, related functions, and project-specific patterns. DeepSource Agents, launched in 2025, observe changes, reason with full codebase context, and take autonomous action to identify and remediate issues.
Setup takes under 10 minutes. Connect your GitHub, GitLab, or Bitbucket repository, add a .deepsource.toml configuration file specifying which analyzers to enable, and analysis begins on every commit and PR. No server infrastructure, no database, no CI pipeline changes, no JVM tuning. For teams without dedicated DevOps resources, this operational simplicity is a significant advantage.
DeepSource offers a free plan for individual developers, a Business plan at $12/user/month, and custom Enterprise pricing that includes self-hosted deployment options.
Feature-by-feature comparison
Rule depth and static analysis
SonarQube has the deepest rule database in the industry. With 6,500+ rules covering 35+ languages, it catches patterns that no other tool – including AI-native reviewers – can consistently identify. Rules are categorized by type (bugs, vulnerabilities, code smells, security hotspots) and severity (blocker, critical, major, minor, info). Each rule includes detailed documentation with compliant and non-compliant code examples, remediation guidance, and references to external standards like OWASP, CWE, and CERT.
Teams can extensively customize SonarQube’s analysis. Quality Profiles allow teams to select which rules apply, adjust severity levels, and create entirely custom rules. This granularity is valuable for large organizations that need different rule sets for different projects, teams, or regulatory contexts. A financial services team might enable MISRA rules for embedded systems code while using a lighter profile for internal tooling.
DeepSource provides 5,000+ rules with a fundamentally different philosophy. Rather than maximizing rule count, DeepSource prioritizes accuracy. Its post-processing framework applies multiple filtering passes to eliminate findings that are unlikely to be genuine issues. The result is a sub-5% false positive rate, which means nearly every finding DeepSource surfaces is worth investigating.
The practical impact of this difference is significant. SonarQube’s volume of findings often overwhelms teams that do not invest time in tuning. Multiple G2 reviewers note that initial SonarQube deployments require several hours of quality profile customization to suppress noisy rules and calibrate severity levels. Teams that skip this tuning phase frequently experience “alert fatigue” where developers stop paying attention to findings because too many are irrelevant.
DeepSource avoids this problem by design. The accuracy-first approach means teams get actionable findings from day one without a tuning phase. The trade-off is that DeepSource may miss some edge-case patterns that SonarQube’s broader rule set would catch. For teams that are disciplined about tuning SonarQube’s profiles, the breadth advantage is real. For teams that are likely to ignore noisy results, DeepSource’s accuracy delivers more real-world impact.
AI capabilities
DeepSource has a significant lead in AI-powered features. Its AI code review engine runs alongside static analysis on every PR, providing structured feedback across five dimensions: Security, Reliability, Complexity, Hygiene, and Coverage. Each PR gets a report card that gives developers a comprehensive quality snapshot – a single view that communicates overall PR quality without requiring developers to parse through individual findings one by one.
Autofix AI is DeepSource’s most practically valuable AI feature. When DeepSource identifies an issue, it does not just describe the problem – it generates a context-aware fix. The fix generation analyzes imports, related functions, coding patterns used elsewhere in the project, and language idioms to produce changes that look like they were written by a developer on the team. This reduces the manual effort of remediation significantly, particularly for teams with large backlogs of unresolved findings.
DeepSource Agents, launched in 2025, represent the next evolution. These agents observe code changes, reason with full codebase context, and take autonomous action to secure code. They can identify issues that require understanding beyond single files – tracing data flows, understanding API contracts, and recognizing architectural patterns that affect security.
SonarQube’s AI features are functional but less mature. AI CodeFix generates remediation suggestions when the analysis engine identifies issues, but the suggestions tend to be template-like – they follow patterns rather than demonstrating deep contextual understanding. AI Code Assurance detects and applies enhanced verification to AI-generated code (from tools like GitHub Copilot), which is a valuable feature as AI-generated code becomes more prevalent. SonarSource reports that users with AI Code Assurance are 24% more likely to report lower vulnerability rates from AI-generated code.
The philosophical difference matters. SonarQube’s approach is “deterministic analysis first, AI as supplement” – every finding traces to a specific rule with documented rationale. DeepSource’s approach is “AI-native analysis enhanced by deterministic rules” – the AI is fundamental to how the product works, not an add-on. Teams that value auditability prefer SonarQube. Teams that value accuracy and actionable recommendations prefer DeepSource.
Quality gates and enforcement
SonarQube’s quality gate enforcement is the best in the industry. Quality gates define conditions that code must meet before it can be merged: minimum coverage percentage, maximum new bugs or vulnerabilities, duplication limits, and technical debt ratio thresholds. When a PR fails the quality gate, SonarQube blocks the merge and surfaces failing conditions directly in the PR via status checks and decoration in GitHub, GitLab, Bitbucket, or Azure DevOps.
The compound effect of quality gates is SonarQube’s most impactful feature. Multiple G2 reviewers cite quality gates as the capability that delivers the most long-term value. When developers know that a PR will be blocked if it introduces new bugs or drops coverage below the threshold, they write more careful code from the start. Over months and years, this enforcement ratchets up codebase quality in a way that advisory-only tools cannot match.
Quality gate configuration is sophisticated. Teams can define multiple profiles for different project types, set different thresholds for new code versus overall code, and create complex multi-condition gates. For example: “Block merge if new code has any critical bugs, coverage on new code is below 80%, or duplication exceeds 3%.”
DeepSource supports quality gates but with less sophistication. Teams can configure thresholds and block PRs that introduce new issues, but the enforcement mechanism is simpler than SonarQube’s multi-condition gates. DeepSource compensates with its five-dimension report card, which gives reviewers a structured quality assessment on every PR even without strict enforcement. The report card approach is less rigid than quality gates but provides useful context for human reviewers making merge decisions.
For teams that need hard enforcement, SonarQube’s quality gates are unmatched. For teams that prefer a softer, feedback-oriented approach that guides developers without hard blocks, DeepSource’s model works well. Many teams start with DeepSource’s advisory approach and graduate to SonarQube’s enforcement model as their quality culture matures.
Language support
SonarQube supports 35+ languages at GA level in commercial editions, making it the broadest language coverage available in a single tool. This includes modern languages (Python, JavaScript, TypeScript, Go, Java, Kotlin, Swift, Rust, C#, PHP, Ruby) as well as enterprise and legacy languages (COBOL, ABAP, PL/SQL, RPG, VB6, Apex) that no modern competitor covers. The Community Build supports 20+ languages for free.
For organizations maintaining legacy codebases alongside modern applications, SonarQube’s language breadth is irreplaceable. A financial services company running COBOL on mainframes, Java on application servers, and TypeScript on web frontends can use a single SonarQube instance to analyze all three codebases with a unified quality dashboard. No other tool enables this.
DeepSource supports 16 languages at GA level: Python, JavaScript, TypeScript, Go, Java, Ruby, Rust, C#, PHP, Scala, Dart, Shell, SQL, Docker, Terraform, and Ansible. Beta support exists for C/C++, Swift, and Kotlin. The inclusion of Infrastructure-as-Code languages (Terraform, Docker, Ansible) is a notable differentiator – SonarQube’s IaC coverage is minimal by comparison.
DeepSource’s language quality is high within its supported set. Each analyzer is purpose-built with language-specific rules. The Python analyzer understands Django and Flask patterns, the JavaScript analyzer understands React and Node.js conventions, and the Go analyzer understands goroutine safety.
The practical question is whether you need SonarQube’s breadth. If your team works in modern languages that DeepSource supports, the additional 20+ languages are irrelevant. If you have COBOL, ABAP, PL/SQL, or other legacy languages, SonarQube is likely your only option for unified analysis.
Platform and CI/CD integration
SonarQube integrates with the broadest set of platforms. GitHub, GitLab, Bitbucket, and Azure DevOps are all supported for PR decoration and status checks. The SonarScanner CLI integrates with every major CI system: Jenkins, GitHub Actions, GitLab CI, Azure Pipelines, Bitbucket Pipelines, CircleCI, and others. Dedicated plugins for Maven, Gradle, .NET, and Ant simplify CI configuration for those build systems.
DeepSource integrates with GitHub, GitLab, and Bitbucket but lacks Azure DevOps support. For organizations standardized on Azure DevOps, this is a disqualifying limitation. Because DeepSource is cloud-native, there is no scanner to configure or analysis server to connect to – commits and PRs are analyzed automatically through Git webhooks.
The trade-off is flexibility versus simplicity. SonarQube’s scanner can be configured to scan specific directories, exclude test files, and set analysis parameters, but requires more initial setup. DeepSource’s zero-configuration approach gets teams running faster but offers less granular control over what gets analyzed.
Security analysis
SonarQube’s security analysis is comprehensive and compliance-oriented. It maps findings to OWASP Top 10, CWE, SANS Top 25, MISRA, and CERT standards, providing audit-ready reports that compliance teams can use directly. The Enterprise Edition adds advanced SAST capabilities including taint analysis (tracking untrusted data through function calls) and SCA (Software Composition Analysis) for scanning dependencies against known vulnerability databases.
SonarQube detects 400+ secret patterns across configuration files, source code, and infrastructure definitions. This breadth is important for enterprise codebases where credentials may be scattered across legacy code, configuration files, and deployment scripts.
DeepSource’s security analysis covers OWASP Top 10 and SANS Top 25 with its static analysis rules, and detects secrets for 30+ services. The coverage is narrower than SonarQube’s but accuracy is higher – DeepSource’s security findings have the same sub-5% false positive rate as its general analysis. DeepSource does not offer SCA (dependency vulnerability scanning), which is a meaningful gap for teams that need a single tool for both code and dependency security.
For regulated industries, SonarQube’s compliance-mapped reporting is essential. The ability to generate OWASP or CWE-aligned reports for auditors is a procurement requirement in financial services, healthcare, and government. DeepSource’s security analysis effectively finds and fixes real vulnerabilities, but it lacks the compliance reporting framework that enterprise security teams require.
Neither tool replaces a dedicated security scanner for teams with serious AppSec needs. Pair either with Semgrep or Snyk Code for deeper security coverage.
Developer experience and setup
DeepSource wins decisively on setup speed and operational simplicity. Connect your GitHub, GitLab, or Bitbucket repository, add a .deepsource.toml configuration file specifying which analyzers to enable, and analysis begins on every commit and PR. The entire process takes under 10 minutes. No server infrastructure, no database provisioning, no CI pipeline changes, no JVM tuning, and no ongoing maintenance.
# .deepsource.toml - minimal configuration
version = 1

[[analyzers]]
name = "python"
enabled = true

[[analyzers]]
name = "javascript"
enabled = true

[analyzers.meta]
  environment = ["nodejs"]
SonarQube Cloud setup is similarly straightforward for the hosted option – sign up, connect your repository, and analysis begins.
SonarQube Server (self-hosted) is a different story. Deploying it requires provisioning a server (minimum 4GB RAM, 8GB+ for production), setting up PostgreSQL, configuring authentication (LDAP, SAML, or built-in), integrating CI/CD scanners, and tuning JVM parameters. Initial deployment typically takes a full day of DevOps effort, with ongoing maintenance for upgrades and performance tuning.
DeepSource’s interface is modern and clean. Users consistently rate it higher than SonarQube for design and usability in G2 and peer reviews. Dashboards are well-designed, findings are presented with clear context and remediation guidance, and the five-dimension PR report card provides a structured overview that is easy to scan.
SonarQube’s interface is functional but showing its age. The dashboard provides comprehensive information – quality gate status, bugs, vulnerabilities, code smells, coverage, duplication – but the layout and design are dated. Multiple reviewers note that the UI needs modernization. The information density is high, which experienced users appreciate but new users find overwhelming.
IDE integration
SonarQube’s SonarLint is one of the strongest IDE experiences available. Available for JetBrains IDEs, VS Code, Visual Studio, and Eclipse, SonarLint runs analysis rules in real time as developers write code. In connected mode, it synchronizes the team’s Quality Profile so IDE results match CI pipeline results exactly. This eliminates the frustrating cycle of pushing code, waiting for CI analysis, finding issues, and pushing fixes.
SonarLint’s connected mode is a genuine differentiator. When a team administrator adds a new rule to the Quality Profile in SonarQube, every developer’s IDE immediately starts checking for that rule locally. There is no gap between what the IDE catches and what the CI pipeline enforces. This consistency is valuable for large teams where ensuring everyone runs the same analysis locally is otherwise difficult.
DeepSource integrates with VS Code, IntelliJ IDEA, and PyCharm for real-time feedback. The integration is functional and provides useful in-editor feedback on code quality issues. However, it lacks the equivalent of SonarLint’s connected mode – there is no automatic synchronization between the team’s configured analysis rules and what developers see in their IDE.
For teams that value perfect IDE-pipeline consistency, SonarLint’s connected mode is a meaningful advantage. For teams that primarily rely on CI/CD pipeline analysis and use IDE extensions as a supplementary tool, both options provide adequate coverage.
Pricing comparison
| Plan | SonarQube | DeepSource |
|---|---|---|
| Free | Community Build (self-hosted, 20+ languages) + Cloud Free (50K LOC) | Free for individuals (public + private repos) |
| Open Source | Cloud OSS plan (unlimited, public repos) | Open Source plan (free, public repos, 1K analysis runs/month) |
| Entry paid (self-hosted) | Developer Edition ~$2,500/year (500K LOC) | Enterprise plan only (custom pricing) |
| Entry paid (cloud) | Cloud Team from EUR 30/month (100K LOC) | Business $12/user/month |
| Mid-tier | Enterprise Edition ~$20,000/year | N/A |
| Enterprise | Data Center Edition (custom pricing, HA) | Custom pricing (includes self-hosted) |
| Billing model | Lines of code (server) or LOC tiers (cloud) | Per active contributor |
| Self-hosted | Core offering (all server editions) | Enterprise plan only |
Cost comparison by team size
| Scenario | SonarQube (self-hosted Developer) | SonarQube Cloud Team | DeepSource Business |
|---|---|---|---|
| 10 devs, 500K LOC | ~$2,500/year | ~$4,300/year | $1,440/year |
| 10 devs, 1M LOC | ~$5,000/year | ~$6,000/year | $1,440/year |
| 25 devs, 2M LOC | ~$10,000/year | ~$10,000/year | $3,600/year |
| 50 devs, 5M LOC | ~$20,000/year | ~$18,000/year | $7,200/year |
| 100 devs, 10M LOC | ~$20,000+/year (Enterprise) | Custom | Custom (Enterprise) |
SonarQube’s pricing is LOC-based, which creates unpredictability. As your codebase grows, costs grow. The Developer Edition at $2,500/year for 500K LOC scales to approximately $10,000/year at 2M LOC. The Enterprise jump to $20,000+/year is steep, and multiple G2 reviewers have flagged aggressive pricing increases at renewal time.
DeepSource’s per-contributor pricing is more predictable. You pay for active committers, not lines of code. A 20-person team pays $2,880/year on the Business plan regardless of whether the codebase is 100K lines or 10M lines. This predictability is valuable for budgeting, especially for fast-growing teams whose codebase size may double in a year.
For small teams, DeepSource is substantially cheaper. A 10-developer team pays $1,440/year for DeepSource Business versus approximately $2,500/year for SonarQube Developer Edition (self-hosted) or $4,300+/year for SonarQube Cloud Team. The difference is even more dramatic for teams with large codebases relative to team size.
For enterprise teams, the comparison inverts. SonarQube’s Enterprise Edition at $20,000/year covers the entire organization regardless of contributor count, while DeepSource’s Enterprise pricing is custom. Teams with 100+ developers may find SonarQube more cost-effective, especially when factoring in the depth of enterprise features (portfolio management, compliance reporting, SCA).
The free tier comparison favors SonarQube for teams, DeepSource for individuals. SonarQube Community Build is a fully functional self-hosted installation (albeit without branch analysis or PR decoration). SonarQube Cloud Free provides hosted analysis for up to 50K LOC with full team access. DeepSource’s Free plan is limited to individual developers, though the Open Source plan for public repositories is generous.
Pros and cons
SonarQube strengths
SonarQube weaknesses
DeepSource strengths
DeepSource weaknesses
Use-case comparison
| Scenario | Better choice | Why |
|---|---|---|
| Enterprise with 500+ developers | SonarQube | Portfolio management, compliance reporting, ecosystem maturity |
| Startup with 5-15 developers | DeepSource | Zero-infrastructure, lower cost, faster setup |
| Regulated industry (finance, healthcare) | SonarQube | OWASP/CWE/MISRA compliance reporting, self-hosted deployment |
| Team with legacy COBOL/ABAP code | SonarQube | Only tool that covers legacy languages |
| Python/JS/Go team wanting AI review | DeepSource | Best AI-powered code review and autofix |
| Team frustrated by false positive noise | DeepSource | Sub-5% false positive rate by design |
| Team needing SCA + SAST in one tool | SonarQube | Enterprise Edition includes SCA |
| Team using Azure DevOps | SonarQube | DeepSource lacks Azure DevOps support |
| No DevOps resources for tool maintenance | DeepSource | Cloud-native, zero infrastructure |
| Team needing hard quality gate enforcement | SonarQube | Best-in-class quality gate system |
| Team wanting modern developer experience | DeepSource | Cleaner UI, structured PR feedback |
| Open source project | Either | Both have generous OSS plans |
When to choose SonarQube
Choose SonarQube if:
When to choose DeepSource
Choose DeepSource if:
When to use complementary tools
Neither SonarQube nor DeepSource covers every aspect of code quality and security. Consider these complementary strategies:
Bottom line
SonarQube and DeepSource represent two distinct philosophies in code quality. SonarQube is the comprehensive, rule-driven, enterprise platform that has defined the category for nearly two decades. DeepSource is the modern, AI-native alternative that prioritizes accuracy, automated remediation, and developer experience.
For most teams with 10-100 developers working in modern languages, DeepSource delivers better day-to-day value: cleaner findings, AI-powered review, automated fixes, and no infrastructure to manage. The sub-5% false positive rate means developers actually act on findings rather than learning to ignore them.
For enterprise organizations with compliance mandates and legacy codebases, SonarQube’s depth, ecosystem maturity, and compliance reporting remain unmatched. The operational overhead is real, but enterprise DevOps teams are equipped to handle it, and the quality gate enforcement delivers compounding returns over time.
Start with a two-week evaluation of whichever tool addresses your primary frustration. If false positives and operational complexity are the pain points, try DeepSource. If you need deeper rule coverage, compliance reporting, or legacy language support, try SonarQube. Both offer free tiers that make evaluation low-risk.
Frequently Asked Questions
Is DeepSource better than SonarQube?
It depends on your team’s priorities. DeepSource is better for teams that want the highest signal-to-noise ratio (sub-5% false positive rate), AI-powered code review with structured PR report cards, automated fix generation, and zero-infrastructure cloud setup. SonarQube is better for teams that need the deepest deterministic rule coverage (6,500+ rules across 35+ languages), enterprise compliance reporting (OWASP, CWE, SANS, MISRA), self-hosted deployment, and battle-tested quality gate enforcement. For mid-size teams working in modern languages, DeepSource often delivers more day-to-day value. For enterprise teams with compliance requirements and legacy codebases, SonarQube remains the stronger choice.
Can I replace SonarQube with DeepSource?
For many teams, yes. DeepSource covers 16 languages at GA level, provides 5,000+ analysis rules, and offers quality gates and PR-level enforcement. If your team works in modern languages (Python, JavaScript, Go, Java, Rust, C#, PHP, Ruby), DeepSource can replace SonarQube and deliver AI-powered features that SonarQube lacks. However, you cannot replace SonarQube with DeepSource if you need legacy language support (COBOL, ABAP, PL/SQL), MISRA or CERT compliance reporting, Software Composition Analysis (SCA), or self-hosted deployment for a small team. Evaluate both tools against your specific requirements before migrating.
How much does SonarQube cost?
SonarQube pricing varies by edition and deployment model. The Community Build is free and open source for self-hosted deployment. SonarQube Cloud offers a free tier for up to 50K lines of code, with the Team plan starting at EUR 30/month. For self-hosted server editions, the Developer Edition starts at approximately $2,500/year for 500K LOC, scaling with codebase size. The Enterprise Edition starts at approximately $20,000/year and includes advanced security features, portfolio management, and support for 35+ languages. The Data Center Edition for high availability uses custom pricing.
How much does DeepSource cost?
DeepSource offers a free plan for individual developers covering both public and private repositories. The Team plan costs $12/user/month (billed per active contributor), and the Business plan is also $12/user/month with additional features for larger organizations. Enterprise pricing is custom and includes self-hosted deployment options. DeepSource also offers a free Open Source plan for public repositories with up to 1,000 analysis runs per month. Unlike SonarQube’s LOC-based pricing, DeepSource charges per active contributor, making costs predictable regardless of codebase size.
Does SonarQube use AI?
Yes, SonarQube has added AI features, though they are less mature than AI-native competitors. AI CodeFix generates remediation suggestions when the analysis engine identifies issues, but the suggestions tend to be template-like rather than deeply contextual. AI Code Assurance detects AI-generated code and applies enhanced verification rules, which helps teams manage the risks of Copilot-generated code. SonarSource reports that teams using AI Code Assurance are 24% more likely to report lower vulnerability rates from AI-generated code. However, SonarQube’s core strength remains its deterministic, rule-based analysis rather than AI-powered review.
Can I use SonarQube and DeepSource together?
Yes, but there is significant overlap since both tools focus on static analysis and code quality. Running both creates redundant findings for many issue categories. A more effective complementary strategy is pairing either tool with a different type of analysis. For example, pair SonarQube with an AI code reviewer like CodeRabbit for contextual PR review, or pair DeepSource with Semgrep for deeper security-specific scanning. If you do run both, configure DeepSource for its AI review and autofix capabilities while relying on SonarQube for quality gate enforcement and compliance reporting.
Is SonarQube free?
Yes, SonarQube offers a free Community Build that is self-hosted and supports 20+ languages with basic quality gates and CI/CD integration. SonarQube Cloud also has a free tier for up to 50,000 lines of code. However, the free editions lack PR decoration, branch analysis, and compliance reporting. The Developer Edition starts at approximately $2,500/year, and Enterprise starts at approximately $20,000/year.
Is DeepSource free?
DeepSource offers a free plan for individual developers covering both public and private repositories. There is also a free Open Source plan for public repos with up to 1,000 analysis runs per month. The Business plan costs $12/user/month per active contributor, and Enterprise pricing is custom. Unlike SonarQube, DeepSource does not offer a free self-hosted option for teams – self-hosted deployment requires the Enterprise plan.
What is the best static analysis tool in 2026?
The best static analysis tool depends on your priorities. SonarQube is the industry standard for enterprise teams needing 6,500+ rules, compliance reporting, and quality gate enforcement. DeepSource is the best option for teams wanting the lowest false positive rate (sub-5%) with AI-powered review and autofix. Semgrep excels for developer-friendly custom security rules. For AI-powered code review that goes beyond static analysis, CodeRabbit provides the deepest contextual PR feedback.
Does DeepSource support Azure DevOps?
No, DeepSource does not support Azure DevOps. It integrates with GitHub, GitLab, and Bitbucket only. Teams using Azure DevOps should consider SonarQube, which supports all four major Git platforms including Azure DevOps. Alternatively, CodeRabbit also supports Azure DevOps for AI-powered code review.
What is the difference between SonarQube and SonarCloud?
SonarQube Server is the self-hosted version that you install on your own infrastructure, requiring database setup, JVM configuration, and ongoing maintenance. SonarQube Cloud (formerly SonarCloud) is the hosted SaaS version managed by Sonar. Both use the same rule engine, but pricing differs – Server charges by LOC per edition, while Cloud charges by LOC tier. Cloud is easier to set up but offers less customization. Server gives full data sovereignty control.
Does DeepSource have quality gates like SonarQube?
Yes, DeepSource supports quality gates that can block PRs introducing new issues. However, SonarQube’s quality gate system is more sophisticated, supporting multi-condition gates with configurable thresholds for coverage, bugs, vulnerabilities, duplication, and technical debt ratio. SonarQube’s quality gates are widely considered the best in the industry for deterministic enforcement. DeepSource compensates with its five-dimension PR report card that provides structured quality feedback on every PR.
Originally published at aicodereview.cc
A system can run on your machine, keep your data out of somebody else’s cloud, and still fail you at the exact moment trust is supposed to become real.
That is the gap a lot of AI discourse still leaves untouched. We talk about who owns the model, who hosts the stack, who controls updates, and where the data lives, and those questions do matter. They shape leverage, dependence, and exposure. What they do not answer is the harder question: how does the system behave once conditions stop being clean?
That is where sovereignty and stewardship part ways.
Sovereignty is about authority. Stewardship is about what that authority becomes under strain. They belong in the same conversation, but they are not the same achievement, and too much of the current language around local and private systems still treats them as if they were.
Why the weaker frame keeps winning
Sovereignty gets overcredited because it offers a visible answer to a real fear. People have watched platforms tighten terms, widen telemetry, raise prices, and quietly shift power upward while leaving users with fewer meaningful choices. So when a product arrives wrapped in the language of local control, private storage, or self hosted operation, it feels like correction. It feels like somebody finally named the problem.
That reaction makes sense. It also stops too early.
Location is easier to prove than conduct. A builder can point to the machine, the storage boundary, or the deployment model and make a claim that looks morally serious. The system runs here. The data stays here. The user owns the keys. All of that may be true, and none of it tells you whether the product remains legible when a process is interrupted, a retry only half succeeds, or state becomes contested.
That is the seduction of the weaker frame. It lets architecture stand in for responsibility. It lets a system look protective because of where it runs without proving that it behaves protectively when the operator actually needs help.
A remote system can fail you from a distance. A local system can fail you in your own hands and still leave you doing the cleanup. The fact that the blast radius moved closer to the user does not make the failure more ethical.
The real audit surface is degraded use
Most software looks respectable when nothing interrupts the path from intent to completion. Stable connectivity, stable power, full attention, complete context, and enough time to think can make even fragile systems appear trustworthy.
The real audit begins when continuity breaks.
A laptop sleeps halfway through a run. A browser reloads. A session expires at the wrong moment. The network drops just long enough to create uncertainty without creating a clean failure. A retry completes some work but not all of it. The interface returns something that looks settled even though the underlying state is not. The operator comes back tired and has to decide whether touching anything again will repair the situation or make it worse.
That is not edge behavior. That is ordinary life.
If a system only preserves clarity when nothing interferes with its ideal flow, then its public posture is stronger than its operational reality. It may still be elegant. It may still be private. It may still be sovereign. None of that changes the fact that trust begins where ambiguity stops being expensive.
Example one: the local agent that cannot account for itself
Imagine a local agent that processes a folder of documents and writes structured notes into your workspace. There is no remote execution, no third party logging, and no outside dependency in the critical path. On paper, it checks the boxes people increasingly use as shorthand for trustworthiness.
Halfway through the run, the machine sleeps.
When it wakes, the interface reports completion. Only later does the operator discover that one file was never processed, another was partially written, and a retry created duplicates because the write path was not safe to repeat. Timestamps shifted during the second pass, so sequence is now unclear. There is no durable event log, no reconciliation summary, and no clean record of what committed successfully versus what was left in limbo.
The system remained sovereign throughout the entire sequence. That is exactly the point. The failure was not about ownership. It was about the system’s inability to preserve truth once interruption entered the picture. Instead of containing uncertainty, it handed uncertainty to the human and forced them to reconstruct reality from fragments.
That is not a minor implementation flaw. It is a trust failure at the architectural level.
Example two: the sync engine that hides unresolved state
Now take a different product class: a notes tool with optional sync. It advertises local ownership, encrypted storage, and user controlled export. Again, the posture sounds strong.
A common failure path is easy to imagine. The user edits the same project across two devices. One device has been offline longer than expected. The other completed a background retry after a temporary authentication lapse. When connectivity returns, the product announces that everything is up to date.
It is not.
One change was dropped during conflict resolution because the merge strategy preferred recency over meaning. An attachment reference survived in metadata even though the underlying blob never finished uploading. A background retry succeeded on one object and silently failed on another. The export panel still shows success because the export job completed, even though the dataset now contains an unresolved hole.
What makes this dangerous is not simply sync failure. Systems fail. What matters is that the operator is given the appearance of closure instead of an honest account of state. Ownership is still present. Control is still present. What is missing is a system that can surface conflict, preserve causality, and tell the truth about what remains unresolved.
Once a product makes truth expensive to recover, it starts charging the human in time, stress, and risk.
What stewardship has to require
If stewardship is going to mean anything, it cannot remain a mood or a marketing signal. It has to describe a set of behaviors that hold under interruption, fatigue, and uncertainty.
The first requirement is bounded failure. A serious system limits blast radius. It distinguishes between what can pause, what can degrade, what can be retried safely, and what must stop until state is reconciled. Without those boundaries, capability only increases the size of the mess.
The second is real recovery. Not recovery promised in documentation for a calm operator with spare time, but recovery that exists in the product itself through resumable operations, durable checkpoints, preserved history, safe retries, and completion states that can actually be verified. If retrying might duplicate work, deepen corruption, or further obscure what happened, then the system does not really recover. It asks the human to compensate for its uncertainty.
The third is truthful state. This is where polished systems often become untrustworthy. They hide uncertainty because uncertainty looks messy, and they collapse partial failure into optimistic language because composure is easier to ship than honesty. But a protective system should make four things cheap to know: what happened, what is true now, what remains unresolved, and what can be done safely next. If those answers are difficult to obtain, then the system has already pushed operational risk downward onto the operator.
A better standard
When a product claims to be local, private, sovereign, or self hosted, that should open the real evaluation rather than close it. The useful test is not whether control moved closer to the user. It is whether the product can survive interruption without manufacturing confusion, preserve state in a way the operator can verify quickly, resume without turning retries into roulette, degrade without quietly damaging truth, and distinguish between real success and motion that merely reached a stopping point.
Those are not peripheral concerns. They are the conditions under which trust becomes operational instead of rhetorical.
Anyone can produce a clean architecture diagram and call it responsibility. The harder task is building a system that remains legible when context collapses, dependencies wobble, attention thins out, and reality becomes inconvenient. That is where stewardship either proves itself or disappears.
The verdict
Sovereignty matters. We need more systems that reduce dependence, narrow outside leverage, and return authority to the operator.
But sovereignty is not the verdict. It is the opening requirement.
A product does not become trustworthy because computation moved closer to the user. It does not become protective because the data stayed on the right machine. It does not become responsible because its language learned how to speak in the register of control.
The real question is harsher than that. When the run is interrupted, when state turns uncertain, when sync becomes contested, when completion is partial, and when the operator is too tired to play forensic analyst, does the system preserve orientation or does it preserve appearances?
That is the line that matters. Not where the system runs, but whether under degraded conditions it still lets the operator know what is true and what can be done safely next.
Claude Code Router (CCR) vs TeamoRouter: Do You Really Want to Maintain Local Routing Infrastructure?
If you landed here from the DataCamp Claude Code Router tutorial, you already understand the problem: routing OpenClaw requests through cheaper models cuts costs by 40–70%. The question is whether you want to maintain the infrastructure to do it yourself.
CCR is a great open source tool. TeamoRouter is CCR for developers who would rather not run a local proxy at 3 AM when it crashes.
What is Claude Code Router (CCR)?
Claude Code Router is an open source, locally deployed proxy that intercepts your OpenClaw API calls and routes them to different models based on task type. DataCamp’s tutorial walks through the setup: install Node.js, clone the repo, edit a config file, start the server, point OpenClaw at localhost.
The result is real cost savings — CCR routes simple file reads and edits to cheaper models (DeepSeek, Gemini Flash) while keeping complex reasoning tasks on Claude Sonnet or Opus. The DataCamp tutorial estimates 40–60% cost reduction for a typical OpenClaw workload.
It’s a genuinely useful project. The problem is the operating model.
The hidden cost of “free” local infrastructure
When CCR works, it’s invisible. When it doesn’t, you’re debugging Node.js proxy config instead of doing the work you actually opened your laptop to do.
Here’s what “maintaining CCR” looks like in practice.
Initial setup takes 20–45 minutes: installing Node.js and npm dependencies, cloning the repo, understanding the config schema, setting environment variables for each provider (Anthropic, OpenAI, Google, DeepSeek), testing that OpenClaw’s ANTHROPIC_BASE_URL points correctly at localhost, and verifying routing rules trigger for the right task types.
Ongoing, you’re handling:
.env filesWhat actually breaks most often: port conflicts with other local services, Node.js version drift after system upgrades, provider API key rotations that hit multiple .env files, and CCR dying silently when your laptop sleeps.
None of these are showstoppers for a developer who enjoys this kind of thing. But for most OpenClaw users, the routing proxy is a means, not an end.
The comparison
| Claude Code Router (CCR) | TeamoRouter | |
|---|---|---|
| Install time | 20–45 minutes | 2 seconds (skill.md URL) |
| Runs where | Your local machine | Managed cloud gateway |
| What happens when laptop sleeps | Routing stops | Routing continues |
| Config required | Yes — YAML, env vars, model rules | No — teamo-best, teamo-balanced, teamo-eco
|
| API keys to manage | 3–6 (one per provider) | 1 (TeamoRouter key) |
| Discount on API usage | 0% (BYOK at retail prices) | Up to 50% on first $25, 20% next $75 |
| Updates | Manual pull + config review | Automatic (managed service) |
| License | MIT open source | Managed service (skill is open) |
| Cost | Free (your time + retail API prices) | Paid (TeamoRouter markup, but net lower due to discount) |
| Failure mode | Silent crash, full Anthropic prices until noticed | Gateway SLA, monitoring, alerts |
CCR is right if you want full control and don’t mind maintaining local proxy infrastructure. TeamoRouter is right if you want the same routing outcome without owning the infrastructure.
Who should use CCR
CCR is genuinely the better choice if:
The DataCamp tutorial is accurate and the tool works. This is a real alternative, not a bad one.
Who should use TeamoRouter
TeamoRouter is the better choice if:
The install is literally: paste the skill.md URL into OpenClaw. Done. No Node.js, no .env files, no localhost configuration.
Real cost comparison: $200/month OpenClaw workload
The GitHub issue thread anthropics/claude-code #29579 has 53 developers reporting rate limit problems on the $200/month Max plan. A typical heavy OpenClaw user runs 60–70% of their requests on routine tasks (file reads, short edits, boilerplate) and 30–40% on complex reasoning.
Without routing (direct Anthropic API, $200/month workload):
With CCR routing ($200/month workload):
With TeamoRouter routing ($200/month workload):
The cost outcomes are similar. The difference is the 45-minute setup, the ongoing maintenance, and what happens at 3 AM when CCR crashes and your automation falls back to full-price Anthropic calls without alerting you.
“Free” vs. paid: what you’re actually trading
CCR is described as free because there’s no software fee. But you pay:
TeamoRouter charges a service fee (the margin between retail and your discounted rate), but in exchange you get the time back and the discount built in. For most OpenClaw developers, the math favors TeamoRouter once you count setup and maintenance honestly.
Getting started with TeamoRouter
npx install-skill https://gateway.teamo.ai/skill.md
Switch routing modes:
teamo-best — always uses the highest-performing model for each taskteamo-balanced — mixes Claude, GPT-4o, Gemini, and DeepSeek to balance cost and qualityteamo-eco — maximizes cost savings (DeepSeek R1 and Gemini Flash for routine tasks)Website: https://router.teamolab.com
Discord: https://discord.gg/NN6SaDnpMb
FAQ
Does TeamoRouter work the same as CCR for OpenClaw routing?
Yes. TeamoRouter intercepts OpenClaw API calls and routes them to the appropriate provider based on task type, exactly like CCR. The difference is TeamoRouter runs on a managed cloud gateway instead of your local machine.
Can I use both CCR and TeamoRouter?
No — both require setting ANTHROPIC_BASE_URL to redirect OpenClaw traffic. You’d use one or the other.
What if TeamoRouter goes down?
TeamoRouter falls back to direct Anthropic API calls so your OpenClaw session continues uninterrupted. CCR, running locally, has no fallback — if the process crashes, you silently revert to full-price Anthropic.
Does TeamoRouter support all the same models as CCR?
CCR supports 20+ providers. TeamoRouter routes through Claude, GPT-4o, Gemini, DeepSeek, Kimi, and MiniMax. For most OpenClaw workloads, the 6 providers in TeamoRouter cover the practical use cases. If you need a niche provider, CCR is the better fit.
Is the 50% discount real?
Yes. TeamoRouter offers 50% off the first $25 of usage, 20% off $25–$100, and 5% off beyond that. This is baked into TeamoRouter’s billing — you don’t need to negotiate with Anthropic or set up reseller accounts.
The short version
Claude Code Router is a solid open source tool, and the DataCamp tutorial is a good walkthrough. If you want routing and you’re okay maintaining local infrastructure, CCR works.
If you want the cost savings without owning the proxy, TeamoRouter gets you to the same place in 2 seconds. No Node.js, no config files, no juggling multiple provider keys — plus a 50% discount on the first $25 that CCR can’t offer because it’s just routing retail-priced calls.
One question worth sitting with: how much of your day do you actually want to spend on routing infrastructure?
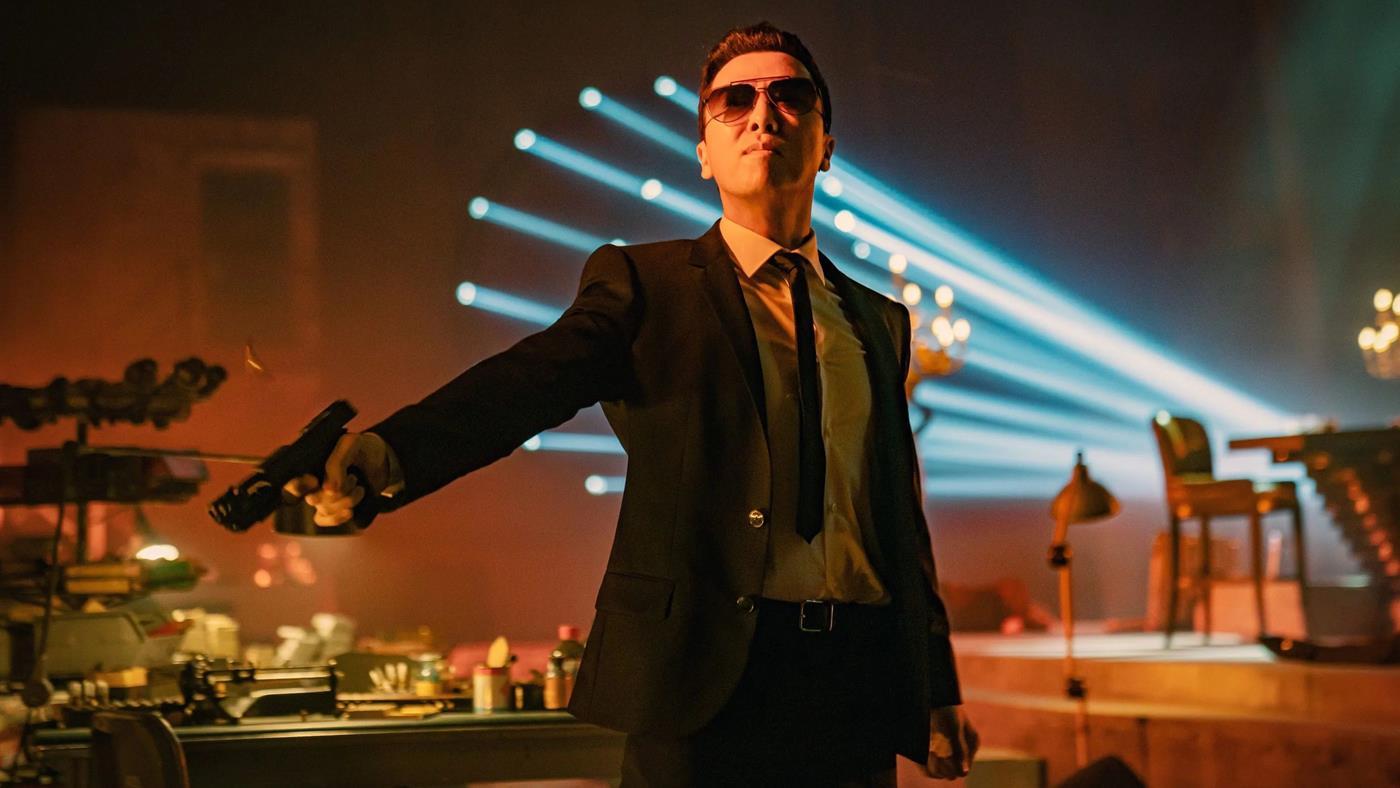
 Ballerina’dan sonra ikinci bir John Wick spin-off’u daha geliyor. Donnie Yen’in hayat verdiği Caine karakterine odaklanacak bu yeni John Wick filmi için çok yakında sete çıkılacak. İşte detaylar…