Forza Horizon 6 için resmi PC sistem gereksinimleri paylaşıldı

Forza Horizon 6 için resmi PC sistem gereksinimleri paylaşıldı

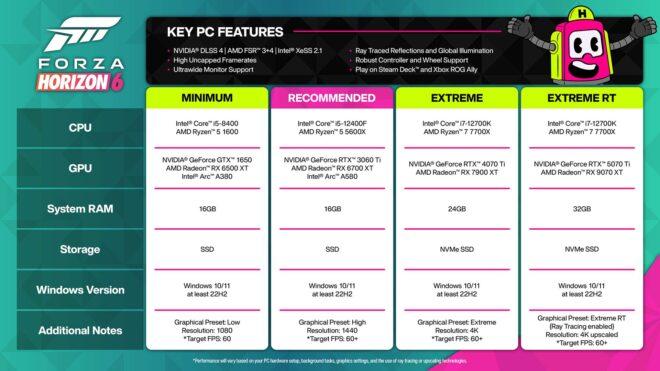
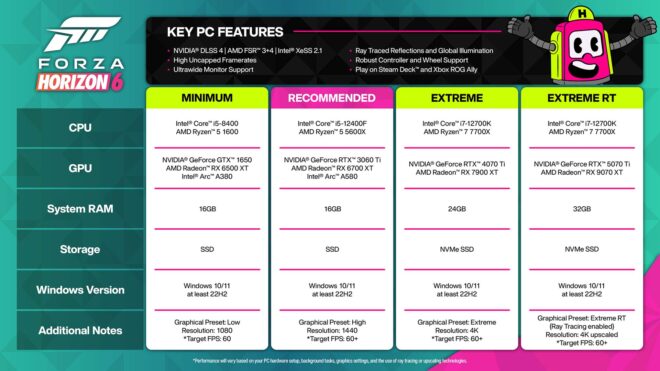
Forza Horizon 6 için resmi PC sistem gereksinimleri paylaşıldıForza Horizon 6 için merak edilen resmi PC sistem gereksinimleri bugün paylaşıldı. Japonya’da geçen yapım için 1440p / High / 60 FPS özelinde tavsiye edilen işlemciler i5-12400F ile Ryzen 5 5600X, tavsiye edilen ekran kartları ise RTX 3060 Ti, RX 6700 XT ve Arc A580 oldu. En az 16 GB RAM ve SSD depolama biriminin istendiği yapım, 4K / en yüksek grafik ayarları / Ray Tracing / 60 FPS özelindeyse i7-12700K ya da Ryzen 7 770X işlemci, RTX 5070 Ti ya da RX 9070 XT ekran kartı ve 32 GB RAM talep ediyor. Sistem gereksinimleri genel olarak iyi karşılanan yapım, 19 Mayıs’ta PC, Xbox Series X ve Xbox Series S için yayımlanacak ve yıl sonunda PlayStation 5’e de açılacak. Yakın zaman önce Steam ve Xbox Store üzerinden ön siparişe açılan Türkçe altyazı destekli Horizon 6, ilk günden 550’den fazla araçla gelecek: “Gerçek dünyadan 550’nin üzerinde araç ile Japonya’nın nefes kesici […]

Forza Horizon 6 için resmi PC sistem gereksinimleri paylaşıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Samsung Galaxy Wide Fold tam olarak bu tasarımla karşımıza çıkarılabilir

Samsung Galaxy Wide Fold, bu tasarımla karşımıza çıkarılabilir

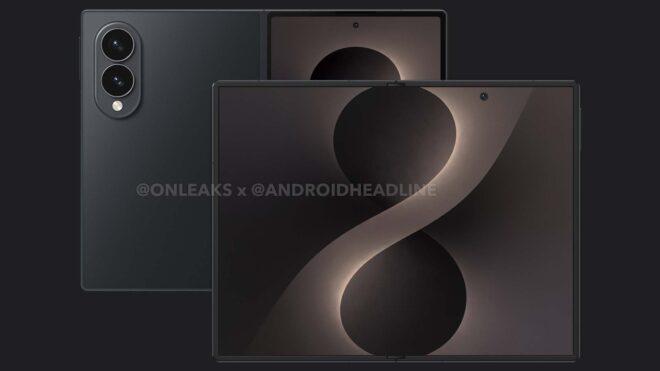
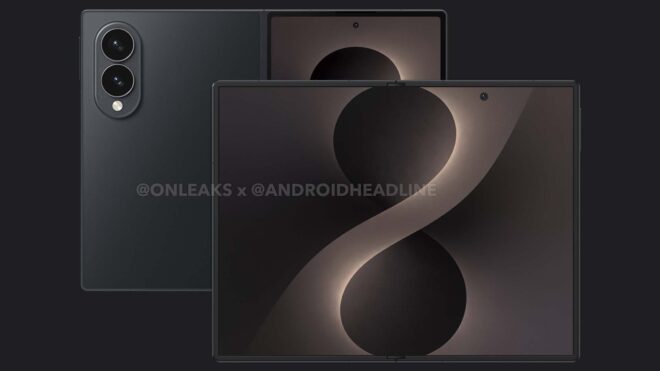
Samsung Galaxy Wide Fold, bu tasarımla karşımıza çıkarılabilirAndroid Headlines, bu yıl içerisinde tanıtılması beklenen “geniş” yapılı katlanabilir telefon modeli Samsung Galaxy Wide Fold (ticari adı farklı olabilir) için “CAD” dosyaları üzerinden bilgisayar ortamında hazırlanmış görseller paylaştı. Genel olarak Galaxy Z Fold serisinden farklı görünmeyecek model, eğer tasarım gerçekten doğruysa iki farklı arka kamera taşıyor. Fark yarattığı esas nokta normalden daha geniş olan dış ekranı olan telefon, iddiaya göre açık halde 4,9 mm, kapalı halde ise 9,8 mm gövde kalınlığına sahip olacak. Geçtiğimiz hafta yine bu yıl tanıtılacak Samsung Galaxy Z Fold 8, Galaxy Z Flip 8 ve Galaxy Wide Fold modelleri için ilk şarj detayları ortaya çıkmıştı. Çin merkezli 3C’den elde edilen resmi verilere göre yaz döneminde tanıtılacak yatay formlu katlanabilir telefon modeli Galaxy Z Fold 8’de 45W, dikey formlu Galaxy Z Flip 8 modelinde ise 25W şarj desteği sunulacak. Galaxy Wide Fold ise 45W şarj desteğiyle geliyor.

Samsung Galaxy Wide Fold tam olarak bu tasarımla karşımıza çıkarılabilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Google, Lyria 3 Pro ile müzik üretim süresini üç dakikaya çıkardı

Google

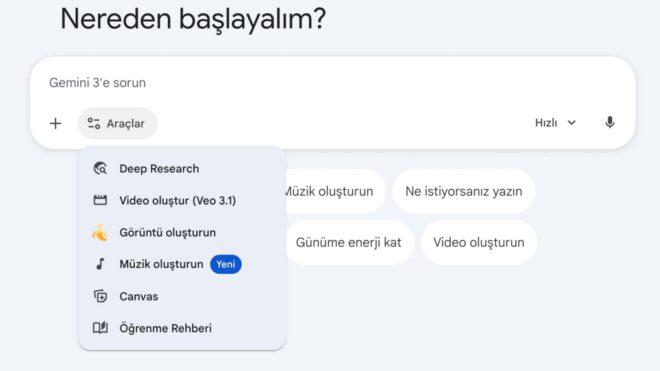
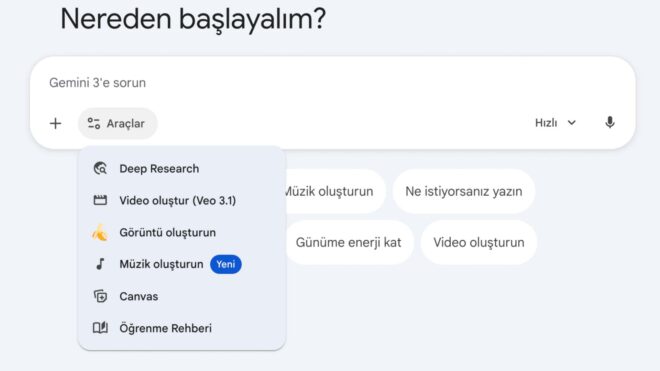
Google'dan müzik üretimine yönelik yeni yapay zeka sistemi: Lyria 3Google, geçtiğimiz aylarda karşımıza doğrudan müzik üretimine yönelik geliştirilen yapay zeka modeli Lyria 3 ile çıkmıştı. Gemini uygulaması (aynı zamanda web sürümü) üzerinden kullanılabilen Lyria 3, Google DeepMind’ın müzik üretimine yönelik en gelişmiş modeli olarak çok iyi sonuçlar ortaya koyabiliyor olmasıyla oldukça ses getirmişti. Türkiye’de de kullanıma açılan (araçlar menüsü altında Müzik Oluştur adıyla) hizmet; yazılı komutların yanı sıra video ve fotoğrafları kullanarak 30 saniyelik müzikler üretebiliyor. Türkçe destekli yapay zeka modeli bu sefer çıtayı daha da yükselten “Pro” sürümüyle gündeme geldi. Pro versiyonla birlikte tam 3 dakikalık müzikler oluşturulabiliyor ve kullanıcılara parçalar için daha fazla özelleştirme seçeneği sunuluyor. Google AI Plus aboneleri Lyria 3 Pro ile günde 10, AI Pro aboneleri günde 20 ve AI Ultra aboneleri ise günde 50 parça oluşturabiliyor.

Google, Lyria 3 Pro ile müzik üretim süresini üç dakikaya çıkardı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

[Guide] How to Bypass the Windows Security Warning to Play CIDER

In our previous update, we introduced the “Void Card” system, which lies at the core of this game’s mechanics.

We are incredibly grateful to see the number of downloads steadily increasing. However, there is a “high hurdle” that is almost inevitable for solo indie game developers: the security warning (such as Windows SmartScreen) that appears when opening an executable file on Windows, stating “Windows protected your PC.”

We understand that seeing an unfamiliar warning can make players hesitate to run the game. To ensure you can experience CIDER with peace of mind, we have released a video guide explaining the steps from download to launching the game.

YouTube Guide: How to Download & Run CIDER

Why does this warning appear?

This is a standard Windows behavior that occurs when an executable file does not have a “Digital Signature.” Obtaining these signatures requires developers to pay significant annual fees (ranging from hundreds to over a thousand dollars).

As CIDER is currently in its early stages and available for free on itch.io, we have not yet acquired this signature. Please be assured that the program does not contain any malicious code; however, the OS simply flags it as an “Unknown Publisher.”

3 Steps to Run the Game

As explained in the video, here is the process after downloading from itch.io:

  1. Extract the ZIP file: Right-click the downloaded file and select “Extract All.”
  2. Open the executable: Double-click CIDER.exe inside the extracted folder.
  3. Click “More info” on the warning screen: When the blue “Windows protected your PC” screen appears, click the “More info” link on the left. This will reveal the “Run anyway” button.

Building Trust

As mentioned previously, our ideal goal is to provide the game through platforms like Steam, where such warnings do not appear.

However, we are still in the middle of development. For now, we hope this guide removes any psychological barriers, allowing as many people as possible to experience the strategic depth of CIDER.

Play the CIDER Development Build on itch.io
Play CIDER on itch.io

We Value Your Feedback

If you successfully launch the game, or if you encounter any issues even after following these steps, please let us know via Discord or in the comments. Hearing “It worked!” from you is a huge motivation for our development.

Join our Discord Server for reports and community:
https://discord.gg/4HRQ6ppyaq

How to Find Divisors in Python, Java, and JavaScript

What is a Divisor?

A divisor is a number that divides another number completely without leaving a remainder.

For example:
Divisors of 10 → 1, 2, 5, 10

Flowchart Logic

The flowchart follows these steps:

  1. Start the program
  2. Initialize the number (Num = 100)
  3. Set divisor value (Div = 2)
  4. Check if Div is less than Num
  5. If true:
  6. Check if Num is divisible by Div
  7. If yes, print the divisor
  8. Increase Div by 1
  9. Repeat the process
  10. Stop when condition fails

Python Code

num = 100
div = 2

while div < num:
    if num % div == 0:
        print(div)
    div = div + 1

Java Code

public class Divisors {
    public static void main(String[] args) {
        int num = 100;
        int div = 2;

        while (div < num) {
            if (num % div == 0) {
                System.out.println(div);
            }
            div = div + 1;
        }
    }
}

JavaScript Code

let num = 100;
let div = 2;

while (div < num) {
    if (num % div === 0) {
        console.log(div);
    }
    div = div + 1;
}

Output


2
4
5
10
20
25
50

LLM Non-Determinism: What Providers Guarantee, and How to Build Around It

This post is based on sections 3–5 of “Understanding why deterministic output from LLMs is nearly impossible” by Shuveb Hussain at Unstract (Oct. 2025). The material has been rewritten and extended with practical code examples using Pydantic and Snowflake Cortex.

Motivation

When you build a pipeline that sends the same document through an LLM twice and expects the same structured output both times, you will eventually be surprised. Not because you’ve made a mistake, but because LLMs are fundamentally non-deterministic: the same prompt can produce different tokens across runs, even when you set temperature=0.

The root cause is that modern LLMs run on massively parallel GPU hardware, where floating-point arithmetic is not associative. The order in which thousands of parallel threads accumulate intermediate values is not guaranteed to be identical run-to-run, so the final token probability scores shift by tiny amounts. When two candidate tokens are close in probability, that tiny shift can flip which one gets selected. Because LLMs generate text auto-regressively — each token conditions all subsequent tokens — a single early flip can cascade into a structurally different response by the tenth token.

You cannot eliminate this. What you can do is design your system so that it is robust to it. The rest of this article shows you how, concretely, using Pydantic and Snowflake Cortex.

What Providers Actually Promise

No major LLM provider guarantees deterministic output. Snowflake Cortex, which hosts models like mistral-large2 and claude-3-5-sonnet via the complete function in snowflake-ml-python, is no exception. You can observe the problem directly:

from snowflake.cortex import complete
from snowflake.snowpark.context import get_active_session

session = get_active_session()

prompt = (
    "Extract the vendor name and total amount from this invoice: "
    "Acme Corp, Invoice #1042, Total: EUR 3,200.00. "
    "Respond in JSON."
)

run_1 = complete("mistral-large2", prompt, session=session)
run_2 = complete("mistrat-large2", prompt, session=session)

print(run_1)  # {"vendor": "Acme Corp", "total_amount": 3200.00}
print(run_2)  # {"vendor": "Acme Corp", "amount": 3200.0}  ← different field name

The values agree, but the field names differ. A downstream system parsing total_amount will fail silently on the second response.

The reasons providers haven’t solved this are pragmatic. Deterministic GPU operations are substantially slower, routing across a distributed fleet makes identical hardware execution nearly impossible, and most applications tolerate small variations gracefully. The seed parameter, where available, only controls sampling randomness — it does nothing about floating-point drift from parallel reductions, which is the dominant source of variation at temperature=0.

The practical takeaway: treat non-determinism as a fixed environmental property, like network latency. You don’t eliminate it; you engineer around it.

Best Practices for Structured Extraction

Enforce Structure with response_format and Pydantic

The most effective tool available is Snowflake Cortex’s structured output feature. You define your expected output as a Pydantic BaseModel, convert it to a JSON schema with .model_json_schema(), and pass it to complete via CompleteOptions. The model is then constrained to emit output conforming to that schema, and you validate the result back into your Pydantic object.

import json
from pydantic import BaseModel, Field
from snowflake.cortex import complete, CompleteOptions
from snowflake.snowpark.context import get_active_session

class InvoiceExtraction(BaseModel):
    vendor_name: str = Field(description="Full legal name of the vendor")
    invoice_number: str = Field(description="Invoice identifier, e.g. INV-1042")
    total_amount: float = Field(description="Total amount due, numeric only")
    currency: str = Field(description="ISO 4217 currency code, e.g. EUR")

session = get_active_session()

options = CompleteOptions(
    temperature=0,
    response_format={
        "type": "json",
        "schema": InvoiceExtraction.model_json_schema()
    }
)

prompt = "Extract structured data from: Acme Corp, Invoice #1042, Total: EUR 3,200.00"

raw = complete(
    model="mistral-large2",
    prompt=prompt,
    session=session,
    options=options,
)

result = InvoiceExtraction.model_validate_json(raw)

print(result.vendor_name)    # "Acme Corp"
print(result.total_amount)   # 3200.0
print(result.currency)       # "EUR"

The response_format eliminates the most common failure mode: field name variation. The model no longer chooses between total_amount, amount, and sum — the schema decides. The subsequent model_validate_json call gives you a fully typed Python object and raises a ValidationError if anything is malformed.

Write Unambiguous Schemas

The schema is a contract. Vague field descriptions produce vague outputs. Be explicit about types, formats, and what to do when data is missing. Note that Snowflake Cortex has some schema constraints — numeric range keywords like minimum/maximum are not supported, and property names may only contain letters, digits, hyphens, and underscores.

from pydantic import BaseModel, Field
from typing import Optional

class LineItem(BaseModel):
    description: str = Field(description="Product or service name, as written on the invoice")
    quantity: int = Field(description="Number of units. Convert 'dozen' to 12, 'pair' to 2.")
    unit_price: float = Field(description="Price per unit in the invoice currency, numeric only")

class InvoiceExtraction(BaseModel):
    vendor_name: str = Field(description="Full legal name of the vendor")
    invoice_date: str = Field(description="Invoice date in YYYY-MM-DD format. Convert all date formats.")
    total_amount: float = Field(description="Total amount due, numeric only, no currency symbol")
    currency: str = Field(description="ISO 4217 currency code, e.g. EUR, USD, GBP")
    line_items: list[LineItem] = Field(description="All line items listed on the invoice")
    purchase_order_number: Optional[str] = Field(
        default=None,
        description="PO reference number if present on the invoice, otherwise null"
    )

The Optional[str] with default=None on purchase_order_number is important. Without it, the model might hallucinate a PO number when none is present rather than omit the field — a subtle but production-breaking behavior.

Anchor Behavior with Few-Shot Examples

Schema constraints define the structure; few-shot examples define the behavior within that structure. They are especially valuable for edge cases: relative dates, quantity words like “dozen”, and optional fields that should be null. With a simple string prompt, the examples go directly into the prompt text.

from snowflake.cortex import complete, CompleteOptions
from snowflake.snowpark.context import get_active_session

session = get_active_session()

options = CompleteOptions(
    temperature=0,
    response_format={
        "type": "json",
        "schema": InvoiceExtraction.model_json_schema()
    }
)

def build_prompt(invoice_text: str) -> str:
    return f"""You extract structured invoice data. Respond in JSON.

Example 1:
Input: "From: Bolt GmbH | Ref: RE-2024-991 | Date: yesterday | 5x Widget A @ EUR 12.50 | Total: EUR 62.50"
Output: vendor_name="Bolt GmbH", invoice_date="2025-03-24", total_amount=62.50,
        currency="EUR", line_items=[{{description="Widget A", quantity=5, unit_price=12.50}}],
        purchase_order_number=null

Example 2:
Input: "DataPipe Inc | Invoice 5531 | PO: PO-8821 | 1 doz. API calls @ USD 0.01 | USD 0.12 total"
Output: vendor_name="DataPipe Inc", invoice_date=null, total_amount=0.12,
        currency="USD", line_items=[{{description="API calls", quantity=12, unit_price=0.01}}],
        purchase_order_number="PO-8821"

Now extract from:
{invoice_text}"""

raw = complete(
    model="mistral-large2",
    prompt=build_prompt(invoice_text),
    session=session,
    options=options,
)

result = InvoiceExtraction.model_validate_json(raw)

Without the “dozen → 12” example, the model might return quantity=1 with description="dozen API calls". With it, the conversion is consistent.

Measure Variance to Drive Improvement

Variance you don’t measure is variance you can’t improve. Run the same documents through your pipeline multiple times and compare the results. High variance on specific fields points directly at under-specified Field(description=...) strings or missing few-shot examples.

from collections import Counter

def measure_extraction_variance(
    invoice_text: str,
    n_runs: int = 5,
    session=None,
) -> dict:

    results = []
    for _ in range(n_runs):
        result = extract_with_retry(invoice_text, session=session)
        if result:
            results.append(result.model_dump())

    if not results:
        return {"error": "all runs failed"}

    variance_report = {}
    for field in results[0]:
        values = [str(r[field]) for r in results]
        top_value, top_count = Counter(values).most_common(1)[0]
        variance_report[field] = {
            "stable": len(set(values)) == 1,
            "unique_values": list(set(values)),
            "agreement_rate": top_count / n_runs,
        }

    return variance_report

# Example output:
# {
#   "vendor_name":  {"stable": True,  "agreement_rate": 1.0,  ...},
#   "invoice_date": {"stable": False, "agreement_rate": 0.6,  ...},  # ← needs attention
# }

A field with agreement_rate < 0.8 across five runs is a direct signal to improve its description or add a targeted few-shot example. This feedback loop is how schemas and prompts mature over time.

The Right Mental Model

The most useful shift you can make is to stop treating non-determinism as a bug waiting to be fixed and start treating it as a property of the environment — one you design around, not against.

The analogy from distributed systems is apt. TCP/IP is built on top of unreliable packet delivery; the reliability lives in the protocol layer, not in the assumption of a perfect physical network. A reliable LLM pipeline puts its correctness guarantees in the surrounding system — Pydantic validation, retry logic, normalization, business rules — not in the assumption that the model will always produce identical output.

With Snowflake Cortex and snowflake-ml-python, this maps to a clear, implementable layering:

Raw document
      ↓
complete(prompt=..., options=CompleteOptions(response_format=...))   ← flexibility lives here
      ↓
model_validate_json() + retry on ValidationError                     ← structure enforced here
      ↓
NormalizedInvoice model_validator                                    ← canonical field names here
      ↓
Business logic / Snowflake table                                     ← determinism lives here

The complete call is allowed to be flexible — that flexibility is precisely what lets it handle invoice formats you have never seen before. Every layer below it progressively tightens the guarantees, so that by the time data reaches a Snowflake table, it is in a predictable, validated shape regardless of what the model happened to call any given field on that particular run.

Non-determinism is not a problem to eliminate. It is the price of flexibility, and a reasonable one — as long as you don’t ask the model to be your schema enforcer, your validator, and your business-logic layer all at once. Those jobs belong to Pydantic.

Original article: Shuveb Hussain, “Understanding why deterministic output from LLMs is nearly impossible,” Unstract Blog, October 8, 2025. https://unstract.com/blog/understanding-why-deterministic-output-from-llms-is-nearly-impossible/

DB-TASK-002

Get all movies that have rental rate greater than 3
SELECT * FROM film
WHERE rental_rate > 3;

I used this to filter movies which are costly rental movies.

Movies rental rate > 3 and replacement cost < 20
SELECT * FROM film
WHERE rental_rate > 3 AND replacement_cost < 20;

Here I used AND because both condition must be true.

Movies rated PG or rental rate 0.99
SELECT * FROM film
WHERE rating = ‘PG’ OR rental_rate = 0.99;

I used OR because any one condition is enough.

First 10 movies sorted by rental rate highest first
SELECT title, rental_rate
FROM film
ORDER BY rental_rate DESC
LIMIT 10;

I sorted high price first then limited to 10.

Skip first 5 movies and get next 3 sorted by rental rate ascending
SELECT title, rental_rate
FROM film
ORDER BY rental_rate ASC
OFFSET 5
LIMIT 3;

OFFSET used to skip rows.

(same question again so same query)
SELECT title, rental_rate
FROM film
ORDER BY rental_rate ASC
OFFSET 5
LIMIT 3;
Movies with rental duration between 3 and 7
SELECT title, rental_duration
FROM film
WHERE rental_duration BETWEEN 3 AND 7;

BETWEEN is easier than writing >= and <=.

Movies title starts with A and ends with e
SELECT title
FROM film
WHERE title LIKE ‘A%e’;

LIKE used for pattern search.

Customers who do not have email
SELECT first_name, last_name
FROM customer
WHERE email IS NULL;

IS NULL used because = NULL will not work.

Movies released in 2006, rental rate 2.99 or 3.99 and title starts with S, top 5
SELECT title, rental_rate, release_year
FROM film
WHERE release_year = 2006
AND rental_rate IN (2.99, 3.99)
AND title LIKE ‘S%’
LIMIT 5;

IN used instead of multiple OR.

Display 10 customers after skipping first 20 sorted by last name
SELECT first_name, last_name
FROM customer
ORDER BY last_name
OFFSET 20
LIMIT 10;

Used for pagination type query.

Top 5 movies highest replacement cost skipping most expensive one
SELECT title, replacement_cost
FROM film
ORDER BY replacement_cost DESC
OFFSET 1
LIMIT 5;

Offset 1 skips most expensive movie.

Rentals between two dates
SELECT *
FROM rental
WHERE rental_date BETWEEN ‘2005-05-01’ AND ‘2005-06-01’;

Used BETWEEN for date range.

Actors last name contain “man”
SELECT first_name, last_name
FROM actor
WHERE last_name LIKE ‘%man%’;

%man% means contains man anywhere.

Movies where special features is NULL
SELECT title
FROM film
WHERE special_features IS NULL;
Movies where rental duration more than 7
SELECT title, rental_duration
FROM film
WHERE rental_duration > 7;
First 10 movies rental rate 2.99 or 4.99, rating R and title contains L
SELECT title, rental_rate, rating
FROM film
WHERE rental_rate IN (2.99, 4.99)
AND rating = ‘R’
AND title LIKE ‘%L%’
LIMIT 10;
Movies title starts with A or B and ends with s
SELECT title
FROM film
WHERE (title LIKE ‘A%s’ OR title LIKE ‘B%s’);
Movies title contains Man, Men or Woman
SELECT title
FROM film
WHERE title LIKE ‘%Man%’
OR title LIKE ‘%Men%’
OR title LIKE ‘%Woman%’;

Vercel vs Hetzner in 2026: Which Is Actually Worth It for Solo Developers?

Originally published at devtoolpicks.com

A tweet blew up this week asking a simple question: why do developers still pay for Vercel when a €3.79/month Hetzner VPS exists? Nine thousand developers had opinions. Most of them missed the point entirely.

The answer isn’t “Vercel is a scam” or “self-hosting always wins.” The honest answer is: it depends on what you’re building, how much your time is worth, and what stage your project is at.

I’ve deployed on all four of these platforms. Here’s the actual breakdown.

Quick verdict: If you’re shipping a Next.js frontend or a simple SaaS MVP, Vercel is genuinely worth the money. If you’re running a full Laravel or Node backend past early validation, Hetzner with Coolify makes you look silly for not switching. Railway and Render sit in between and serve a specific type of developer well.

Quick Comparison

Platform Starting Price Best For Free Tier
Vercel Free / $20/month Next.js, frontend, JAMstack Yes (non-commercial only)
Railway $5/month Full-stack apps, fast iteration $5 trial credit
Render $7/month Predictable costs, background workers Yes (static + limited web services)
Hetzner From €3.79/month Backend-heavy apps, maximum value No

Vercel

Vercel is the platform Next.js was built for. Literally. Vercel created Next.js. If you’re building anything in that ecosystem, the integration is unmatched.

What it actually costs:
The Hobby plan is free, but it comes with a hard restriction: no commercial use. The moment your project generates revenue, you’re required to upgrade. Pro costs $20 per user per month, with a $20 usage credit included. Add a co-founder and you’re at $40/month before you’ve written a line of code.

Beyond the base fee, you pay for overages. Bandwidth beyond 1 TB costs $0.15/GB. Serverless function execution is billed by CPU time. Image optimization costs extra past the included limit. For most solo projects, these limits are generous. For anything with real traffic or AI workloads, bills can surprise you.

The real pros:

  • Zero-config deploys from GitHub. Push and it’s live
  • Automatic preview URLs for every pull request, which is genuinely useful for client work
  • Global edge CDN with zero configuration required
  • Incremental Static Regeneration and Edge Functions work natively with Next.js
  • Best-in-class Next.js support without workarounds or surprises

The real cons:

  • $20/user/month adds up fast for a bootstrapped project with no revenue yet
  • Hobby plan commercial restriction is enforced via Terms of Service. Vercel does act on violations
  • Vendor lock-in is real. Some Next.js features only work properly on Vercel
  • Usage-based billing means costs get unpredictable at scale
  • It’s the wrong tool for full-stack apps that need persistent storage and background workers

Who should NOT use Vercel:
If you’re building a Laravel app, a Node backend with queues, or anything needing persistent storage and background processes, Vercel is the wrong choice. It’s a frontend-first platform. Forcing a full-stack backend onto Vercel’s serverless model creates complexity and cost that simply doesn’t exist on a VPS.

Railway

Railway is what Heroku should have become. It’s a modern PaaS that gives you the deployment simplicity of Vercel but for full-stack apps: backends, databases, workers, and cron jobs in one place.

What it actually costs:
The Hobby plan is $5/month, which includes $5 of resource usage. For very light projects, it’s effectively free. Pro is $20/month with a $20 usage credit. Railway bills by the minute for actual compute used. If your app idles, you pay almost nothing. The visual project canvas showing all your services connected together is one of the nicest developer interfaces available right now.

The real pros:

  • Fastest deploy experience of any platform on this list
  • Visual canvas shows your entire architecture (app, DB, workers) at a glance
  • Usage-based billing means low-traffic side projects cost almost nothing
  • Supports any language via Docker or Nixpacks
  • Excellent for Laravel, Node backends, Python APIs, anything full-stack

The real cons:

  • Pricing gets unpredictable as usage scales. Hard to budget to an exact number
  • Less mature than Render for multi-region setups
  • Free tier is a one-time $5 trial credit, not a permanent option
  • Documentation is thinner than Render’s

Who should NOT use Railway:
If you need predictable fixed monthly costs, Railway’s usage-based model requires active monitoring to avoid surprises. It’s also not ideal for static site hosting. Use Vercel or Netlify for that. And if you’re running a high-traffic production app needing multi-region redundancy, Railway isn’t ready for that yet.

Render

Render is the most Heroku-like option on this list. Fixed pricing tiers, a permanent free option for static sites, and a platform that’s been reliable for years. It’s not the cheapest or the most exciting, but it causes the least drama.

What it actually costs:
Static sites are free forever. Web services start at $7/month for the Starter tier (512MB RAM, 0.5 CPU). Standard is $25/month (2GB RAM, 1 CPU). For a solo dev running a web service plus a PostgreSQL database, expect to pay roughly $20-35/month depending on database size.

The real pros:

  • Permanent free tier for static sites, no 30-day expiry
  • Predictable pricing makes monthly budgeting straightforward
  • Built-in background workers, cron jobs, and PostgreSQL without extra configuration
  • More mature documentation than Railway
  • Better multi-region support than Railway

The real cons:

  • $7/month minimum for always-on backend services
  • Free PostgreSQL databases expire after 30 days. This catches people out more often than it should
  • Slower deployments than Railway in head-to-head tests
  • The interface feels more enterprise-y and less modern than Railway’s

Who should NOT use Render:
If deploy speed and iteration pace matter most (frequent changes, lots of preview environments), Railway feels sharper day-to-day. And if your primary workload is a Next.js frontend, just use Vercel. Render adds nothing in that scenario.

Hetzner

This is the option that started the Twitter debate. For the right developer at the right project stage, it’s not even close.

What it actually costs:
The CX22 gives you 2 vCPU, 4GB RAM, 40GB NVMe SSD, and 20TB monthly traffic for €3.79/month. The CX32 gives you 4 vCPU, 8GB RAM, and 80GB storage for €6.80/month. These aren’t cloud credits with usage surprises. They’re fixed specs that stay yours as long as you’re paying.

Pricing heads-up: Hetzner has confirmed a price increase effective April 1, 2026. Some plans will increase. Check the current pricing at hetzner.com/cloud before signing up. Even after the adjustment, Hetzner remains significantly cheaper than comparable specs on most platforms.

For comparison: a DigitalOcean 2 vCPU / 4GB droplet costs $24/month, roughly 4-6x more than Hetzner for equivalent specs. DigitalOcean wins on US-based support, better beginner documentation, and a larger tutorial ecosystem. If you’re new to self-hosting and based in the US, DigitalOcean is a gentler entry point. If you know what you’re doing, Hetzner is the obvious value choice.

The real pros:

  • Best price-to-spec ratio in the VPS market, full stop
  • 20TB monthly traffic included in EU regions. Competitors charge extra for this
  • GDPR-compliant EU data residency out of the box, relevant for EU founders
  • Pair it with Coolify and you get a self-hosted PaaS for about €4-7/month total
  • No vendor lock-in, no serverless limits, no surprise bills

The real cons:

  • You manage the server. Security patches, updates, monitoring are all on you
  • No managed database, no formal uptime SLA
  • Support is ticket-based only for cloud products. No live chat, no phone
  • US datacenter traffic drops to 1TB/month compared to 20TB in EU regions
  • Setup takes a few hours to go from fresh VPS to production-ready. Not minutes

Who should NOT use Hetzner:
If you’re shipping a Next.js frontend and iterating fast, the time saved with Vercel’s zero-config deploys is real. Hetzner is not for developers who want to avoid thinking about servers. If nginx configs make you uncomfortable, use a managed platform. Also not ideal if your users are primarily in the US and latency matters.

Head-to-Head: The Decision That Actually Matters

Most comparisons get this wrong by treating everyone as the same type of developer. The question isn’t “which platform is best” but “which platform is right for where you are right now.”

For a Next.js SaaS MVP in the first six months:
Vercel wins. Zero-config deploys, preview URLs, and native ISR save real time when you’re iterating daily. At $20/month, it’s cheaper than the hours you’d spend configuring a VPS for a frontend-heavy app. Reassess when you hit $1-2K MRR and the cost starts to feel meaningful.

For a full-stack Laravel or Node app:
Railway or Hetzner. Vercel is genuinely the wrong tool here. It’s built for serverless frontends, not persistent backends. Railway gets you to production faster. Hetzner gets you there cheaper once you’ve validated the idea.

For a bootstrapped SaaS past early validation:
Hetzner with Coolify. I covered the full setup in Laravel Forge vs Ploi vs Coolify. A €6.80/month CX32 running your app, database, queue worker, and reverse proxy is genuinely hard to justify moving away from. The Vercel equivalent would cost 4-5x more.

For a solo dev who hates DevOps:
Render. Not the cheapest or most exciting, but it’s the most reliable “just works” platform for full-stack apps if you don’t want to think about servers.

Final Recommendation

Use Vercel if you’re building a Next.js app, developer experience matters more than cost right now, and you’re in early validation mode where $20/month is irrelevant.

Use Railway if you want the managed PaaS experience for a full-stack app, you prefer paying for actual usage over a flat fee, and you value a modern, fast deploy workflow.

Use Render if you want predictable monthly costs, you’re running background workers or cron jobs, and you value platform stability and clear documentation over cutting-edge features.

Use Hetzner if you’re past early validation, comfortable with Linux, want the best raw compute value on the market, and are running a backend-heavy app that doesn’t need Vercel’s serverless features.

The viral debate framed this as “Vercel is wasteful.” That’s not quite right. Vercel is expensive for the wrong use case. For a Next.js app in early growth, it earns its cost. The mistake most indie hackers make is staying on Vercel well past the point where switching makes obvious financial sense.

FAQ

Is Vercel free for commercial use?
No. Vercel’s Hobby plan is free but explicitly restricted to personal, non-commercial projects. Any project that generates revenue requires the Pro plan at $20/user/month. Vercel enforces this through their Terms of Service.

Is Hetzner good for beginners?
Hetzner is a raw VPS. You configure it yourself. It’s not beginner-friendly out of the box. Pairing it with Coolify gives you a GUI for deployments, SSL, and database management that makes self-hosting far more approachable. DigitalOcean is also a gentler starting point if you’re new to servers.

What’s the cheapest way to host a Laravel app in 2026?
A Hetzner CX22 (check current pricing after the April 1 increase) with Coolify installed for free is the cheapest production-ready option. A CX32 handles most small-to-medium Laravel SaaS workloads comfortably for under €7/month.

Can Railway replace Vercel?
For Next.js apps specifically, no. Vercel’s native integration is too deep. For everything else, including Node backends, Laravel, Python, and Go, Railway is a legitimate and often better alternative with a great developer experience.

Does Hetzner have US data centres?
Yes. Hetzner has US servers in Ashburn, Virginia and Hillsboro, Oregon. The included monthly traffic drops from 20TB to 1TB in US regions compared to EU, which is worth factoring in for bandwidth-heavy applications.

Conclusion

This isn’t a fight between “Vercel is overpriced” and “self-hosting always wins.” It’s a question of stage, stack, and how you want to spend your time.

Use managed platforms early. They buy you speed when speed matters most. Switch to Hetzner when the savings become real money and your setup has stabilised. The tweet that went viral this week wasn’t wrong. But the 9,000 replies proved that context matters more than any single verdict.

Most indie hackers make that switch too late. Don’t be one of them.

Building a Production-Aware AI Backend with FastAPI

Most AI backend examples stop at one thing:

send a prompt, get a response.

That is fine for demos, but real systems usually need more than that.

Once you try to use AI inside an actual product, a few practical questions show up immediately:

  • How much does each request cost?
  • How long does each response take?
  • Can we stream output instead of waiting for a full response?
  • Can we reduce hallucinations by grounding responses in known data?
  • Can we log usage for billing and analytics?

I wanted to build something closer to that reality.

So instead of making another thin OpenAI wrapper, I built a FastAPI-based AI backend with:

  • synchronous responses
  • streaming responses
  • usage logging
  • token-based cost estimation
  • response time monitoring
  • lightweight context-based answering
  • Docker reproducibility

The result is a backend that feels much closer to something you could actually extend into an internal AI tool or SaaS feature.

Why I Built It This Way

A lot of AI tutorials focus on model output.

I wanted to focus on backend behavior.

That means:

  • responses should be explainable
  • system behavior should be predictable
  • logs should support observability
  • the backend should be structured for extension, not just for demo screenshots

In other words, I was less interested in “Can this call OpenAI?”
and more interested in “Can this behave like a real backend feature?”

Tech Stack

  • Python 3.11
  • FastAPI
  • SQLAlchemy 2.0
  • Alembic
  • OpenAI API
  • SQLite
  • Docker

What the Backend Does

The project currently includes:

  • POST /ai/test for standard AI responses
  • POST /ai/stream for streaming output
  • POST /ai/upload for adding text-based context data
  • POST /seed for inserting sample context
  • GET /ai/logs for inspecting stored usage logs

It also stores request-level data such as:

  • prompt
  • response
  • total tokens
  • estimated cost
  • response time
  • endpoint name
  • user id
  • timestamp

That logging layer turned out to be one of the most important parts of the project.

Because once you can see how AI is being used, the backend starts becoming operational instead of experimental.

Lightweight RAG-Style Answering

One of the goals was to reduce hallucinated answers.

Instead of letting the model answer freely from its general knowledge, I added a lightweight retrieval flow:

  1. search relevant records from the database
  2. inject the retrieved content into the prompt
  3. instruct the model to answer only from that context

This is not a full vector database setup.
It is intentionally lightweight.

The retrieval logic uses:

  • simple keyword-based matching
  • basic query pre-processing for Japanese text
  • AND search first
  • OR fallback if needed
  • safe fallback responses when no context is found

So the project is better described as a lightweight RAG-style backend rather than a full enterprise retrieval system.

That was deliberate.

I wanted something small enough to understand, but structured enough to feel useful.

Why Streaming Matters

Streaming changes the feel of an AI product a lot.

Without streaming, the user waits for the full answer.
With streaming, the user gets feedback immediately.

That makes the backend feel much closer to a real assistant feature.

So I added /ai/stream and then made sure streaming requests were not treated like second-class citizens.

I wanted them logged too.

That meant tracking:

  • total tokens
  • estimated cost
  • response time
  • endpoint name

This was important because a lot of examples show streaming output, but do not show how to observe or measure it properly.

In practice, that observability layer is what makes the feature maintainable.

Cost Tracking and Latency Monitoring

For regular /ai/test responses, token usage was straightforward to capture.

For streaming, it required a bit more work.

I refactored the provider layer so the streaming flow could still capture usage data at the end, then calculate an estimated cost and store it together with the final response log.

That gave me a much more useful log structure.

Instead of only storing “prompt” and “response,” I could now see:

  • how many tokens were used
  • how much the request approximately cost
  • how long the request took
  • which endpoint generated it

That is a much stronger foundation for:

  • cost visibility
  • future billing models
  • usage analytics
  • performance monitoring

One Practical Issue I Hit

Alembic autogeneration tried to include unrelated schema changes while I was extending the logging table.

It detected the new columns I wanted:

  • estimated_cost
  • response_time_ms
  • endpoint

But it also tried to remove an unrelated documents table.

That was a good reminder that migration generation is helpful, but not magical.

I manually cleaned the migration so it only included the actual intended schema change.

That was one of those small but very real backend moments:
not “how do I make the feature work?”
but “how do I make the change safe?”

Current Logging Model

The request log now stores:

  • prompt
  • response
  • total_tokens
  • estimated_cost
  • response_time_ms
  • endpoint
  • user_id
  • created_at

That makes the backend feel much more production-aware than a simple AI demo.

What This Project Is Really About

The most important thing I learned is that AI backend work is not just model integration.

It is also about:

  • structure
  • safety
  • logging
  • reproducibility
  • monitoring
  • extension paths

Calling an API is easy.

Building something that behaves predictably when it grows is the harder part.

That is what I wanted this project to reflect.

What I Would Add Next

The next natural steps would be:

  • JWT authentication
  • token quota control
  • admin-facing usage analytics
  • Stripe integration
  • richer retrieval strategies
  • vector-based search when the use case really needs it

But even in its current form, the backend already demonstrates something important:

AI features become much more valuable when they are treated as backend systems, not just model calls.

Repository

GitHub: fastapi-ai-core

The repository includes Docker setup, logging examples, and a lightweight context-retrieval flow.

If you are building AI-enabled backend systems with FastAPI, I think this kind of structure is worth caring about early.

Because once usage grows, observability stops being a nice-to-have.
It becomes part of the product itself.

WLBS + MoE: Finally, an AI that learns where the bug really lives

You’ve seen this happen.

An AI coding agent tries to fix an ImportError in rbac.py. It edits the file three times, five times, ten times. Nothing works.

The real bug is in roles.py—the file that rbac.py imports. The error shows downstream, but the cause lives upstream.

The AI keeps banging on the wrong file because its memory is temporal, not spatial. It remembers “I failed here” but not “this file depends on that one.”

We built a system that fixes this gap—and it works.

The core idea: keep information in its original shape
Most AI agents today store experience as text: rules extracted from logs, reflections written in natural language. Every translation discards structure. The call graph, the dependency chain, the propagation path—all flattened into words.

WLBS (World-Line Behavior Space) does the opposite.

  • Every function, module, or service node keeps a world-line—an append‑only log of every event that ever touched it. Task ID, action, result, reasoning, whether that reasoning was correct—all stored on the node itself.
  • When a test fails, a curvature increment propagates backward along the call graph. Nodes closer to the root cause get larger increments; after repeated failures, the upstream root cause accumulates the highest curvature.
  • A singularity flag appears on that node—no natural language, no parsing, just a typed attribute the decision layer reads directly.
  • Resolution decay (inspired by the biological fovea) feeds the LLM only what it needs: full history for nearby nodes, key events for the neighbourhood, just identifiers and curvature for distant parts. Context stays small—about 375 tokens for a real cross‑file bug.

No translation, no retrieval, no guesswork. The geometry of the dependency graph itself points to the root cause.

MoE meets WLBS: each node gets its own expert
WLBS gives the system structural memory. MoE (Mixture of Experts) gives it specialised intelligence.

We map every node in the behavior graph to a lightweight expert (a LoRA adapter). A tiny router reads the node’s curvature and world‑line summary, then activates the relevant experts—often the current node plus high‑curvature upstream nodes.

The loop:

  1. A test fails at node rbac.py.
  2. Curvature propagates upstream; roles.py gets a high curvature increment.
  3. Router sees the high curvature upstream and activates both the roles.py expert and the rbac.py expert.
  4. Experts produce a decision: modify roles.py (not rbac.py).
  5. Action is executed, feedback is written back to the world‑lines.
  6. Success → curvature decays for rbac.py and increments for roles.py are already there.
  7. Offline, high‑curvature nodes are fine‑tuned (LoRA) using their world‑line data—only the nodes that actually matter get updated.

The result: continuous improvement without full retraining. The system gets better at diagnosing similar issues every time it encounters them, and the learning is isolated to the nodes that actually need it.

Real numbers from a real bug
We tested on a cross‑file repair task (b‑16: roles.py → rbac.py).

  • Behavioral distance correctly identified as 1 hop.
  • Context assembly took 5–22 ms.
  • Gate prompt size ~375 tokens.
  • First effective write target was roles.py—the correct upstream file.
  • Passing tests went from 34/44 → 42/44.
  • Gate failure rate 4.76%.

And the improvement came without parameter updates—just from world‑line accumulation and curvature propagation.

Why this matters for developers

  • **No more chasing symptoms. **You get spatial root‑cause attribution without hand‑coded rules.
  • Low overhead. The routing prompt is tiny; the curvature propagation is pure arithmetic.
  • Works with existing LLMs. Gate is a standard LLM, fed structured data (graph + curvature + world‑line excerpts). You don’t need to retrain the model.
  • **Scales. **Resolution decay keeps context bounded; experts are updated only when their curvature spikes.
  • Opens the door to other domains. The same pattern works for microservices, supply chains, even clinical diagnosis—anywhere there’s a dependency graph and repeatable failures.

What’s next
We’ve filed two Chinese patents (CN 2026103746505 and CN 2026103756225) and are releasing the core implementation open‑source (repo to be announced). A preprint is on arXiv (cs.SE / cs.AI, March 25, 2026).

We’re actively looking for:

Early adopters to try WLBS on their own codebases or microservice topologies.

Contributors to help with runtime dependency tracking, large‑graph performance, and parameter auto‑tuning.

Researchers to extend the framework to new domains and formalise the curvature propagation theory.

Get involved

Watch the GitHub repo :https://github.com/val1813/wlbs-cli
Try the CLI prototype: pip install wlbs-scan

If you’ve ever spent hours chasing a bug that was upstream, or wished your AI agent had a sense of space, this is for you.

Let’s give AI a map—not just a timeline.