Hi, I’m Ryan Tsuji, CTO at airCloset — Japan’s leading fashion rental subscription service.
Today I want to share something I’m genuinely proud of: DB Graph and DB Graph MCP — a Model Context Protocol (MCP) server that lets anyone in our company search and query 15 schemas, 991 tables, 11 SQL databases, and 6 MongoDB instances using natural language through Claude Code.
You don’t need to know a single table name. Ask “find tables related to returns” and it gives you the answer — across schemas, across database engines. And yes, it can query production data safely.
In this post, I’ll walk through everything: what it does, how it works, the tool design, actual response formats, how we built the graph, how we operate it, and how we handle permissions and security.
The Problem: Nobody Knows All 991 Tables
airCloset has been running since 2015 — that’s 10 years of accumulated database schema.
| Resource |
Count |
| SQL Databases |
11 (MySQL 8 + PostgreSQL 3) |
| MongoDB Databases |
6 (DocumentDB 5 + Atlas 1) |
| Schemas |
15 |
| Tables/Collections |
991 |
| ORMs |
4 (TypeORM, Sequelize, Drizzle, Mongoose) |
| Repositories |
28 |
Nobody in the company knows all of them. Not even close.
Here’s a real scenario. Customer support asks: “This customer’s app shows the return as completed, but has the warehouse actually confirmed receiving it?”
Think about what you need to investigate this.
The app-side return status lives in the aircloset schema’s delivery order table. If the delivery status is “RETURNED”, the app considers it done. Some people might know this much.
But the warehouse-side confirmation lives in the bridge schema. A receive record table’s status being “COMPLETE” means the warehouse has physically processed the returned package.
The problem? These two live in completely separate databases. No foreign key connects them. To bridge the gap, there’s an intermediate mapping table in aircloset that holds a warehouse order code (varchar) — which corresponds to a shipping order code in bridge. No FK, just a varchar match across schemas.
aircloset delivery order table (status = RETURNED)
  ↓ order_id
aircloset warehouse mapping table
  ↓ warehouse_order_code (varchar)
bridge shipping order table (matched by code — no FK!)
  ↓ shipping_order_id
bridge receive record table (status = COMPLETE = warehouse confirmed)
Table names are generalized for this article.
Four tables, two schemas, a foreign-key-less varchar join. How many people in the company know this path? You could count them on one hand. And if they’re on vacation, the investigation stalls.
This is daily life in a 991-table × 15-schema world. It’s not just “I don’t know the table name.” It’s that the connections between schemas exist only in specific people’s heads. That was the real problem.
DB Graph MCP — The Big Picture
This is what we built to solve it.

Four components:
-
DB Dictionary Graph Builder — A daily batch job that parses ORM definitions from 28 repositories and stores table/column/relationship info as a graph in BigQuery
-
DB Dictionary Review UI — A web app where humans verify AI-generated descriptions, mark deprecated columns, and add annotations. Review data survives daily rebuilds
-
DB Graph MCP Server — An MCP server (Cloud Run) that combines graph search with live DB querying
-
DB Account Pipeline — Fully automated DB access provisioning: application → approval → account creation → notification
Seeing It in Action
Let’s solve the return investigation from above using DB Graph MCP.
Tool response examples below use generalized table/column names. The response format reflects actual output.
Step 1: Natural Language Table Search
Ask Claude Code: “Find tables related to return processing confirmation.” Under the hood, search_tables runs a semantic search.
> search_tables(query: "return processing confirmation", search_type: "semantic")

5 tables found (by vector similarity):

bridge.return_packages (postgresql) (distance: 0.2557)
bridge.receive_records (postgresql) (distance: 0.2720)
cella.receive_confirmation_results (mysql) (distance: 0.2921)
bridge.receive_record_details (postgresql) (distance: 0.2951)
aircloset.return_status_change_histories (mysql) (distance: 0.3170)
A single search returns tables across three schemas (bridge, cella, aircloset). The table name “receive_records” doesn’t contain the word “return” — but the AI-generated description includes “rental return processing” and “warehouse receiving”, so it matches semantically.
Step 2: Table Detail
The second hit in bridge looks promising. Let’s get the details.
> get_table_detail(table_name: "bridge.receive_records")

# bridge.receive_records
DB: POSTGRESQL / ORM: typeorm / Repository: bridge-api

## Columns (9)
- id: int [PK, AI, NOT NULL]
- code: varchar [NOT NULL]
- shipping_order_id: varchar [NOT NULL]
- status: enum [NOT NULL, default=IN_PROGRESS]
- type: enum [NOT NULL]
- receive_datetime: varchar [NOT NULL]
- operated_by: varchar [NOT NULL]
- created_at / updated_at: datetime

## References (2)
- shipping_order_id → bridge.shipping_orders.id (explicit)
- operated_by → bridge.users.id (explicit)

## Referenced By (1)
- bridge.receive_record_details.record_id → id (explicit)

## Enum Definitions (2)
- Status: COMPLETE=Received, IN_PROGRESS=Processing
- Type: RENTAL_RETURN=Rental return, BUSINESS_RETURN=Business return,
        RENTAL_RETURN_LACK=Rental return (missing items), BUSINESS_RETURN_LACK=Business return (missing items)
status = COMPLETE means “the warehouse has finished receiving.” Exactly what we needed. Plus type = RENTAL_RETURN distinguishes rental returns from business returns. Enum definitions with human-readable labels — visible at a glance.
Step 3: Discovering the Cross-Schema Path
Now the question: how do we connect the aircloset delivery order (app side) to the bridge receive record (warehouse side)? Let’s use trace_relationships.
> trace_relationships(table_name: "bridge.shipping_orders", direction: "both", max_depth: 1)

# Relationship trace: bridge.shipping_orders
Nodes: 23, Edges: 22

## Relationships (excerpt)
- shipping_orders.shop_id → shops.id (explicit)
- shipping_orders.warehouse_id → warehouses.id (explicit)
- receive_records.shipping_order_id → shipping_orders.id (explicit)     ← warehouse confirmation!
- return_packages.shipping_order_id → shipping_orders.id (explicit)     ← return shipment
- shipping_packages.shipping_order_id → shipping_orders.id (explicit)   ← outbound shipment
- shipping_inspections.shipping_order_id → shipping_orders.id (explicit) ← inspection
...
Found the path from bridge.shipping_orders to receive_records. Next, we find the mapping table connecting aircloset and bridge.
> search_tables(query: "warehouse_mapping", search_type: "table", adjacent_depth: 1)

aircloset.warehouse_shipping_relations (mysql)

### Related Tables
  → aircloset.delivery_orders (order_id → id)
> get_table_detail(table_name: "aircloset.warehouse_shipping_relations")

## Columns (4)
- order_id: int [PK, NOT NULL]              ← aircloset delivery order ID
- warehouse_order_code: varchar [NOT NULL]   ← bridge shipping order code
Found it. order_id links to the aircloset side, warehouse_order_code links to the bridge side. No FK, but this varchar is the only key connecting two schemas.
Step 4: Querying Real Data
Now we build cross-schema queries. First, get the delivery order and warehouse code from aircloset.
> sql_query_database(database: "aircloset", sql: "SELECT ... WHERE user_id = 12345 AND status = 'RETURNED'")

**aircloset** (staging) — 1 row

| id     | status   | returned_date       | warehouse_order_code |
|--------|----------|---------------------|----------------------|
| 98765  | RETURNED | 2026-03-20 10:30:00 | SO-2026-00012345     |

> **Table**: Manages the full lifecycle of delivery orders — styling → shipping → return status tracking

### Column Descriptions
- **status**: Delivery status (1=Awaiting shipment, 2=Ready, 3=Delivered, 4=Returned, 5=Cancelled)
- **returned_date**: Date/time the warehouse received the customer's return
- **warehouse_order_code**: Mapping code to bridge shipping order

### Related Tables
- → **aircloset.users** (user_id → id): Customer profile...
- → **aircloset.plans** (plan_id → id): Subscription plan definitions...
- ← **aircloset.styling_feedbacks** (delivery_id → id): Customer feedback on styling...
- ← **aircloset.rental_items** (delivery_id → id): Items in this order...
Notice that column descriptions and related tables are automatically appended below the query result. This metadata is pulled from the graph data cached in Redis (cache-invalidated on graph updates). AI can read this enrichment to determine its next step — like “use the warehouse code to query bridge.”
Now check the warehouse side:
> sql_query_database(database: "bridge", sql: "SELECT ... WHERE code = 'SO-2026-00012345'")

**bridge** (staging) — 1 row

| code             | status  | receive_status | type          | receive_datetime    |
|------------------|---------|---------------|---------------|---------------------|
| SO-2026-00012345 | SHIPPED | COMPLETE      | RENTAL_RETURN | 2026-03-21 14:22:00 |

> **Table**: Records warehouse receiving operations — arrival confirmation and inspection status

### Column Descriptions
- **status**: Shipping order status (ORDERED→ALLOCATED→PICKED→INSPECTED→SHIPPED→CANCELED)
- **receive_status**: Receive status (IN_PROGRESS=Processing, COMPLETE=Received)
- **type**: Receive type (RENTAL_RETURN=Rental return, BUSINESS_RETURN=Business return)

### Related Tables
- → **bridge.warehouses** (warehouse_id → id): Source warehouse...
- → **bridge.shops** (shop_id → id): Source shop...
- ← **bridge.receive_record_details** (record_id → id): Individual item details...
- ← **bridge.shipping_packages** (order_id → id): Outbound package info...
receive_status = COMPLETE — the warehouse has confirmed receipt. Both the app-side return status and the warehouse-side physical confirmation are verified.
This enrichment is the key to AI-powered investigation. Claude Code reads the column descriptions and related tables to autonomously decide “what to query next” and “how to interpret these values.” No human guidance needed.
Beyond Operations: Cross-Service Analytics
This isn’t limited to operational investigations. It works for business analytics too.
Try asking Claude Code:
How many customers used our spot rental service last week, what percentage of them are airCloset monthly subscribers, and how frequently do those subscribers use the main service?
Answering this requires crossing the spot rental order table (occasiondress schema) with the main service’s member and usage tables (aircloset schema).
Claude Code uses DB Graph MCP to identify the relevant tables via search_tables, discover join keys via trace_relationships, and run queries against both databases to produce the aggregated result. Cross-service analytics from a single natural language question — that’s the core value.
Without DB Graph MCP
Imagine doing these investigations without any tooling:
Return confirmation:
- You need to know the delivery order table exists in
aircloset
- You need to know about the warehouse mapping table that bridges schemas
- You need to know that a varchar warehouse code maps to
bridge‘s shipping code
- You need to know that
bridge‘s receive record table is the warehouse confirmation
- You need to know what enum values like COMPLETE and RENTAL_RETURN mean
Cross-service analytics:
- You need to know the spot rental DB schema name and table structure
- You need to know the join key to the main service’s member table
- You need connection credentials for both databases
- You need to correctly interpret member statuses and usage counts
In both cases, the required knowledge spans multiple services and schemas. Probably fewer than five people hold all of it in their heads. With DB Graph MCP, anyone can get there through natural language search → table detail → relationship tracing → live queries.
Now let’s dive into how this works.
Tool Design: 7 Tools in 3 Categories
Dictionary Tools (no DB credentials required)
| Tool |
Purpose |
search_tables |
Name search + vector similarity search across tables/columns |
get_table_detail |
Full table info: columns, FKs, enums, DEAD annotations |
trace_relationships |
BFS traversal of table relationships |
Dictionary tools read pre-built graph data from BigQuery — no individual DB credentials needed. Anyone with a Google OAuth login can use them immediately, with no access request.
Query Tools (DB credentials required)
| Tool |
Purpose |
list_databases |
List databases you have access to |
sql_query_database |
Execute SELECT queries against MySQL/PostgreSQL |
describe_database_table |
Get live schema from actual DB |
mongo_query_database |
Execute find/aggregate against DocumentDB/Atlas |
Query tools use per-user credentials stored in Firestore. You only see databases you’ve been granted access to.
This separation is intentional. The dictionary is open to everyone; data access is permission-controlled. “Everyone should know what tables exist, but accessing the data requires authorization.”
Why BigQuery? — Technology Choices
We use BigQuery as the graph store. “Shouldn’t a graph DB use Neo4j?” you might ask.
We chose BigQuery because one store handles graph + vector search + analytics:
-
VECTOR_SEARCH: Store 768-dimensional embeddings and run cosine similarity search natively. No separate vector DB needed
-
Graph traversal: Node + edge table design enables BFS traversal through simple recursive JOINs
-
JSON type:
JSON_SET on a properties column lets us flexibly append review data without schema changes
-
Serverless: No instance management. Pay only for queries, not idle time
-
Vertex AI integration: Gemini 3 Flash for description generation and embedding models connect seamlessly within GCP
-
Google Workspace integration: OAuth uses Google Accounts directly. Domain restriction, nickname resolution, and permission management all flow through the same identity — no separate IdP needed
A dedicated graph DB like Neo4j has superior traversal performance, but at 991 tables, BigQuery is more than sufficient. The operational simplicity of “vector search, JSON, analytics, and graph all in one place” far outweighs the performance difference.
How Natural Language Search Works
How does “return processing confirmation” find a receive records table?
Step 1: Generate Table Descriptions
The DB Dictionary Graph Builder runs daily at 6:00 AM JST, generating AI descriptions for each table using Gemini 3 Flash:
Example: bridge.receive_records
→ "Records warehouse receiving operations. Tracks rental returns
   and business returns with completion/in-progress status.
   Links to shipping orders to trace which order a return belongs to."
Step 2: Generate Embeddings
Each description is converted to a 768-dimensional vector using Vertex AI’s embedding model and stored in BigQuery.
Step 3: VECTOR_SEARCH
The user’s query is also converted to a 768-dimensional vector, then matched via BigQuery’s VECTOR_SEARCH using cosine distance:
SELECT base.qualifiedName, distance
FROM VECTOR_SEARCH(
  TABLE `project.db_graph_nodes`,
  'embedding',
  (SELECT @query_embedding AS embedding),
  top_k => 20,
  distance_type => 'COSINE'
)
WHERE base.nodeType = 'Table'
ORDER BY distance ASC
Even if “return” doesn’t appear in the table name, the AI description’s mention of “rental return processing” places it close in vector space. That’s the core of natural language search.
Building the Graph
6-Phase Pipeline
The builder runs six phases daily:
(See the Builder section of the diagram)
① ORM Parsing — Parse 4 ORM types (TypeORM, Sequelize, Drizzle, Mongoose) across 28 repositories to extract table definitions.
② Live DB Validation — Query actual staging DBs via Lambda to compare code definitions against real schemas. Auto-exclude tables that exist in code but not in the database.
③ AI Description — Generate table/column descriptions with Gemini 3 Flash. Incremental detection regenerates only changed tables to minimize AI cost.
④ Graph Construction — Generate 4 node types (Schema/Table/Column/Enum) and 5 edge types (HAS_TABLE/HAS_COLUMN/REFERENCES/USES_ENUM/SAME_ENTITY).
⑤ Embedding Generation — Generate 768-dimensional vectors per table via Vertex AI.
⑥ BQ MERGE — Load into BigQuery using MERGE, preserving human-written descriptions and DEAD flags. Auto-generated data never overwrites manual annotations.
Relationship Confidence Levels
Foreign key detection has varying confidence:
| Confidence |
Detection Method |
Reliability |
explicit |
Directly from ORM @JoinColumn() or belongsTo()
|
Certain |
inferred |
Naming convention: xxx_id → xxx table |
High probability |
manual |
Added by human reviewers |
Certain |
This lets AI judge the reliability of suggested JOIN conditions before using them.
SAME_ENTITY Edges
The same logical entity sometimes exists in both SQL and MongoDB — for example, a MySQL users table and a MongoDB user statistics collection both represent the same user. SAME_ENTITY edges express these cross-engine correspondences, enabling seamless cross-database discovery.
Human Review: AI Alone Isn’t Enough
“Are AI-generated descriptions actually accurate?” Honestly — not always.
Gemini 3 Flash produces decent high-level descriptions, but 10 years of business context — “this column was migrated 3 years ago but never dropped from the schema”, “enum value 5 is actually never used” — that kind of tacit knowledge can’t be filled by AI alone.
That’s why we built human review into the system from day one.
Review Web UI
We have a dedicated review web app for the DB Dictionary.
The schema list shows review progress bars. The table list supports filtering by “unchecked”, “checked”, and “has deprecated items.”
The table detail screen displays columns with type badges, FK targets, and enum definitions — with inline editing for descriptions and deprecation flags.

Review UI: FK targets and enum definitions shown as badges. Descriptions can be edited inline.
Available review actions:
| Action |
Description |
| Edit table description |
Supplement or rewrite the AI-generated description |
| Edit column description |
Per-column annotations (“deprecated”, “use XX instead”, etc.) |
| Mark as DEAD |
Deprecation flag + reason + empty percentage, at table or column level |
| Mark as Checked |
Review completion flag — records who checked and when |
| Bulk DEAD marking |
Mark up to 500 tables/columns as deprecated at once |
DEAD Flags: Surfacing 10 Years of Tacit Knowledge
After 10 years, deprecated columns accumulate. A flag that once represented member type — migrated years ago, now NULL in every row — still sits in the schema.
When a reviewer marks a column as deprecated, the MCP table detail shows:
- old_member_flag: int [NOT NULL, default=0, DEAD] ⚠ Deprecated. Use membership_status instead
- cancel_date: datetime [DEAD] ⚠ All rows NULL
- legacy_import_id: varchar [DEAD] ⚠ Legacy CSV import field. No longer used
This matters because it prevents AI from writing code that references the wrong column. When Claude Code loads table details into context and sees a DEAD flag, it knows to avoid that column.
Change Detection and Diff Review
When the daily build detects changes in table structure or AI descriptions, they’re recorded as “pending changes.” Reviewers can view before/after diffs in the web UI and mark them as reviewed.
This ensures nothing slips through — if yesterday’s build changed something, someone will see it.
Review Data Persistence
Review data is stored in Firestore and never overwritten by daily builds.
The daily build follows this sequence:
-
ORM parsing → graph construction — Re-extract table definitions from latest code
-
BQ MERGE — Merge while preserving human-written
textForEmbedding and embedding
-
Re-apply Firestore reviews — Write
humanDescription, isDead, deadNote, checkedAt back to BQ properties
Reviews survive unlimited daily rebuild cycles. Firestore is the source of truth; BQ is its reflection.
Crossing the VPC Wall: Cross-Cloud Architecture
Now for the security design I’m most proud of.
Problem: The MCP server runs on Google Cloud (Cloud Run). The databases are inside AWS VPCs. Cloud Run can’t directly reach VPC-internal RDS/DocumentDB instances.
Solution: A three-stage authentication chain — GCP OIDC → AWS STS → VPC Lambda — enables secure cross-cloud connectivity.

Authentication Flow
1. Cloud Run (GCP) → Get OIDC token from GCP metadata server
2. OIDC token → AWS STS AssumeRoleWithWebIdentity
3. STS → Return temporary AWS credentials (1-hour TTL)
4. Temporary credentials → Invoke VPC-internal Lambda
5. Lambda → Execute query against VPC-internal RDS/DocumentDB
Key points:
-
Zero static AWS credentials. Dynamically obtained from GCP service account.
-
Temporary credentials cached for 5 minutes. Avoids per-request STS overhead.
-
Lambda executes inside VPC. DB connections never leave the VPC.
-
Production queries use Read Replicas only. Never connects to the master.
SQL Validation (Defense in Depth)
Query safety is enforced at two layers:
MCP layer (1st):
Allowed: SELECT, SHOW, DESCRIBE, DESC, EXPLAIN, WITH...SELECT
Blocked: INSERT, UPDATE, DELETE, DROP, CREATE, ALTER, TRUNCATE, multi-statement via semicolons
Lambda layer (2nd):
The same validation runs inside Lambda. Even if the MCP layer is somehow bypassed, Lambda blocks it.
Protecting Production Data — PII Anonymization
Querying production data is powerful, but handling personally identifiable information (PII) requires the most care.
Automatic Anonymization Rules
For production + view permission queries, PII column values are automatically anonymized:
| Column Pattern |
Replacement |
| Email fields |
***@***.com |
| Name fields |
*** |
| Phone fields |
***-****-**** |
| Postal code fields |
***-**** |
| Address fields |
*** |
| Password fields |
[REDACTED] |
| Date of birth fields |
****-**-** |
| Card number fields |
[REDACTED] |
Table-specific rules handle ambiguous columns. For example, a generic name column isn’t PII globally, but users.name or orders.buyer_name clearly is. These are configured per-table.
Staging vs Production
| Environment |
PII Anonymization |
Connection Target |
| Staging |
None |
Master DB |
| Production (view) |
Auto-applied |
Read Replica |
| Production (edit) |
None |
Read Replica |
Staging uses test data, so no anonymization needed. Only production view queries get automatic PII protection.
Fully Automated Access Management — DB Account Pipeline
“Who do I talk to about getting database access?”
This question doesn’t get asked anymore. The DB Account Pipeline automates everything.

Flow
-
User submits a workflow request — nickname, email, desired databases (multiple allowed)
- Manager approves
-
Cloud Run Job processes automatically — reads approved requests, generates CREATE USER statements per DB, executes via Lambda
-
Credentials saved to Firestore + Secret Manager — passwords never stored in plaintext
-
Slack DM with connection info — includes bastion server guide
Zero Plaintext Passwords
Passwords are stored only in Secret Manager.
Firestore db_credentials:
  host: "xxx.rds.amazonaws.com"
  port: 3306
  username: "ryan_view_user"
  passwordSecretId: "db-cred-xxxxx"  ← Reference to Secret Manager only
  permLevel: "view"
When the MCP Server executes a query, it decrypts the password from Secret Manager via passwordSecretId and caches it in memory for 5 minutes. Cloud Run restarts clear the cache.
No plaintext password exists anywhere — this was a deliberate design decision we’re particularly proud of.
Operations
Daily Cron
A cron job fires at 6:00 AM JST daily, triggering a Cloud Run Job:
6:00 AM JST — Cron fires
├── ORM parsing (28 repos × 4 ORMs)
├── Live DB validation (11 staging DBs)
├── Gemini description generation (incremental only)
├── Graph construction + Embedding
├── BQ MERGE (preserving annotations)
└── Slack notification
Cost
| Resource |
Cost |
| Gemini 3 Flash (daily, incremental) |
~$0.10-0.20/day |
| Vertex AI Embedding |
~$0.01/day |
| Cloud Run Job |
Near-free (once daily) |
| BQ Storage |
A few GB |
| Lambda |
Shared with DB Account Pipeline |
Thanks to incremental detection, we maintain an AI-powered dictionary for 991 tables at under $10/month.
Incremental Detection
Regenerating all table descriptions daily would spike Gemini costs. So we introduced change detection:
1. Compare previous property hashes
2. Detect column structure changes (additions/removals/type changes)
3. Identify affected tables via enum dependency graph
→ Regenerate only changed tables
If a status enum changes, all tables using that enum are regenerated. No changes? Skip. This cuts AI costs by roughly 90%.
Security Summary
| Layer |
Protection |
| OAuth |
Google Account + corporate domain restriction |
| Credential Resolution |
email → nickname → per-user DB credentials |
| Permission Filter |
Per-user × database × environment × permission level |
| SQL Validation (MCP) |
SELECT-only enforcement |
| SQL Validation (Lambda) |
Same validation (defense in depth) |
| PII Anonymization |
Production + view queries only |
| Production Connection |
Read Replicas only |
| Passwords |
Secret Manager only, 5-min TTL memory cache |
| Cross-Cloud Auth |
GCP OIDC → AWS STS (zero static credentials) |
| Logging |
Passwords and query results never logged |
Takeaways
DB Graph MCP goes beyond solving the fundamental database problem of “you can’t use what you don’t know exists.” It enables anyone to search real data without knowing SQL at all.
-
As a dictionary — Search 991 tables’ structure, relationships, and enum definitions in natural language
-
As a query tool — Securely query staging and production data with automatic PII protection
-
As a knowledge base — DEAD flags and column annotations surface 10 years of tacit knowledge
The biggest lesson from building this: the real value of MCP is giving AI context. Table structure, relationships, enum definitions, column warnings — when these enter AI’s context window, the SQL and code Claude Code writes become dramatically more accurate.
Making that happen required building the graph, securing cross-cloud access, automating permission management, and protecting PII — unglamorous but essential infrastructure, built with care.
I hope this helps anyone wrestling with internal database management at scale.
I’m CTO at airCloset, a fashion rental subscription service in Japan. We’re building the future of AI-powered development. If you’re interested, check out our engineering careers page.


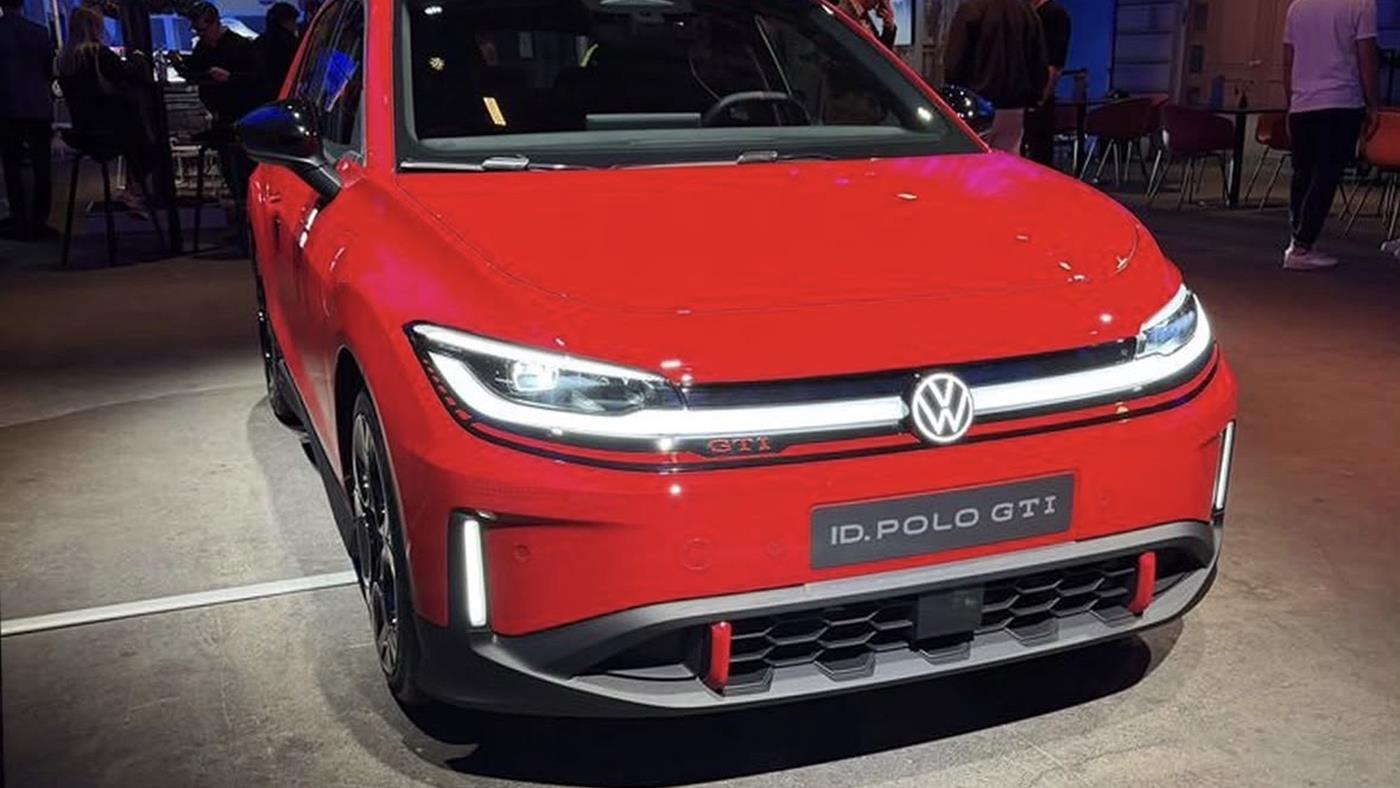
 Volkswagen’in merakla beklenen elektrikli modeli ID. Polo resmi tanıtımından önce internete sızdırıldı. Yayınlanan fotoğraflar yeni otomobilin ön yüzünü kamuflajsız şekilde gösteriliyor.
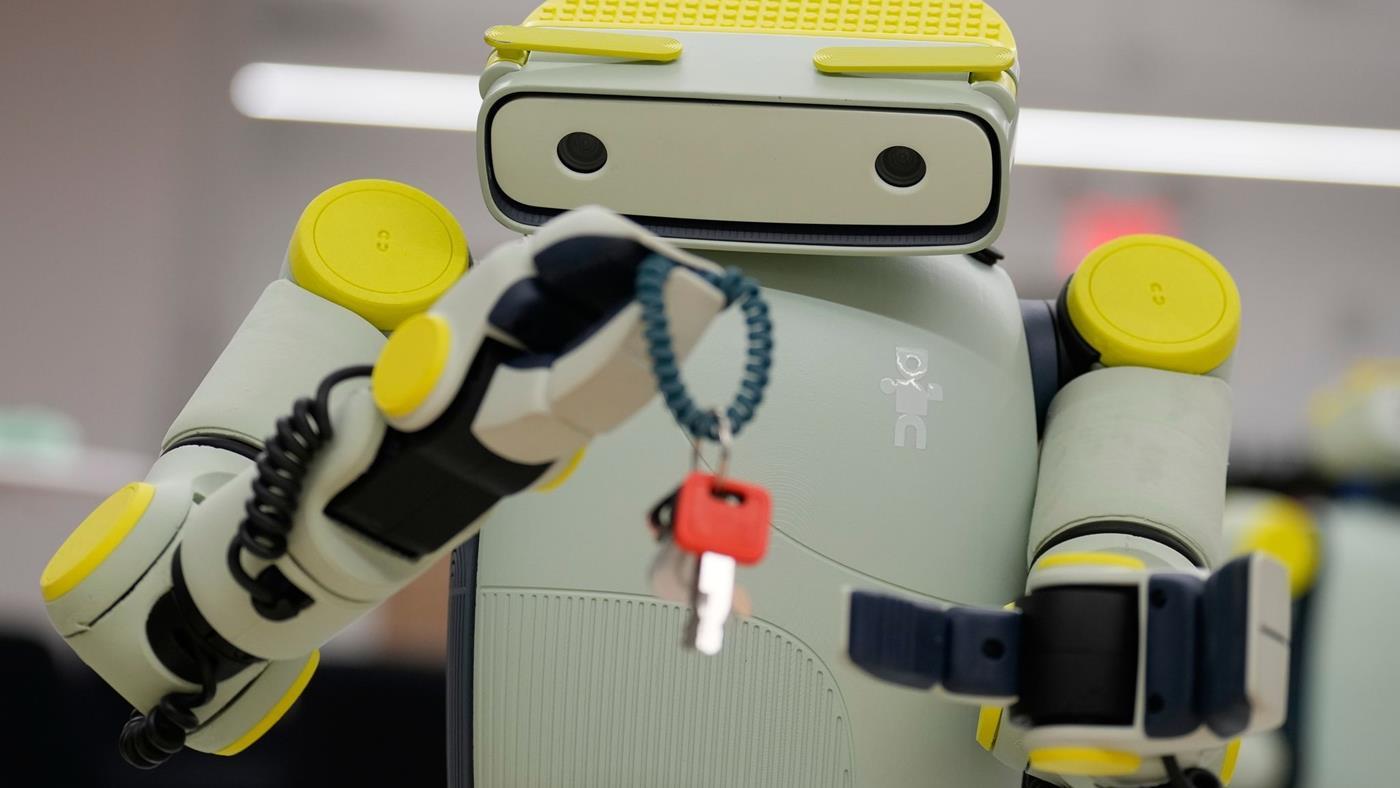
 Amazon, çocuk boyunda insansı robotlar üreten Fauna Robotics’i satın alarak kişisel robot pazarına güçlü bir giriş yaptı. Fauna, ultra sevimli Sprout robotu ile dikkat çekmişti.
 AMD ve Intel, artan talep ve tedarik sorunları nedeniyle işlemci fiyatlarını yükseltiyor. Ryzen ve diğer PC CPU’larda %15’e varan artış kısa vadede piyasaya yansıyacak.