Türkiye’deki Bazı Kullanıcılar, 5G’yi Kullanmaya Başladı
Nisan 2026 itibarıyla geniş çapta sunulacak 5G teknolojisi erkenden sunulmaya başladı. Turkcell kullanıcıları 5G’yi kullanabildiklerini bildirdi.

 Mert
 Turkcell, kullanıcılar tarafından aktarıldığı kadarıyla normalde 1 Nisan itibarıyla başlayacak 5G hizmetini bazı bölgelerde erkenden kullanıma sundu. 5G destekli cihaz sahiplerine sürpriz yapan şirket, bu durum hakkında resmi bir açıklama paylaşmadı. Ulaştırma ve Altyapı Bakanı Abdulkadir Uraloğlu, Türk Telekom’un Teknoloji ve İnovasyon Merkezi’nin açılış töreninde 5G ile alakalı önemli açıklamalarda bulunmuştu. 5G yetkilendirme ihalesi neticesinde 3 milyar 534 milyon dolar gelir elde ettiklerini dile getiren Uraloğlu, açıklamasında şu ifadelere yer vermişti: “1 Nisan 2026 tarihinde ilk sinyalini alacağımız 5G hizmetlerini 2 yıl içerisinde ülkemizin her noktasına eriştirmeyi hedefliyoruz. 5G’ye geçişle birlikte mobil internet hızımız 10 kata yakın artacak; vatandaşlarımız daha hızlı, daha güvenilir ve daha kesintisiz bir haberleşme imkanına kavuşacak. 5G, yalnızca bir haberleşme teknolojisi değil, aynı zamanda üretim gücümüzü, hizmet kalitemizi ve teknolojik rekabetçiliğimizi aynı anda yükselten bir kalkınma altyapısıdır.” 5G’nin endüstriyel robotlardan otonom sürüş teknolojilerine, kritik altyapı yönetiminden akıllı şehir uygulamalarına kadar birçok alanda dönüşümü hızlandıracağını söyleyen Uraloğlu, […]
Turkcell, 5G hizmetini bazı bölgelerde erkenden kullanıma sundu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
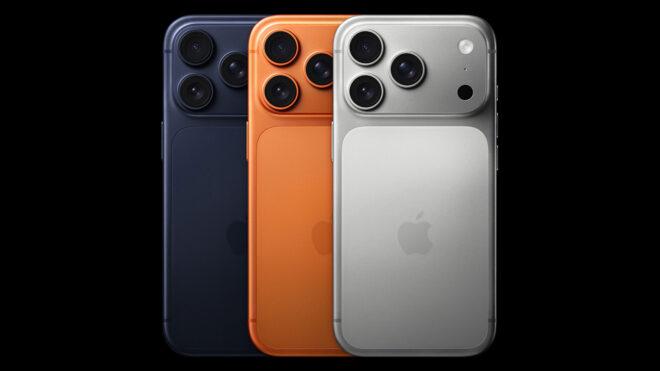
 Çin merkezli güvenilir kaynaklardan Digital Chat Station tarafından ortaya atılan son iddiaya göre Apple, önümüzdeki yıllarda karşımıza 200 megapiksel ana kameraya sahip iPhone modelleri çıkarabilir. Şu anda 1/1.12 inç boyuta sahip bir 200 megapiksel kamera üzerinde testler gerçekleştirdiği iddia edilen şirket, satıştaki 17 Pro serisinde 48 megapiksellik ana kameraya yer veriyor ve bunun eylül ayında tanıtılacak 18 Pro serisinde de değişmesi beklenmiyor. Çok sayıda Android üreticisinin uzun zamandır kullandığı 200 megapiksellik sensörler, yüksek çözünürlük sayesinde geniş düzenleme olanakları sağlıyor.
Önümüzdeki yıllarda 200 megapiksel ana kameraya sahip iPhone modelleri gelebilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
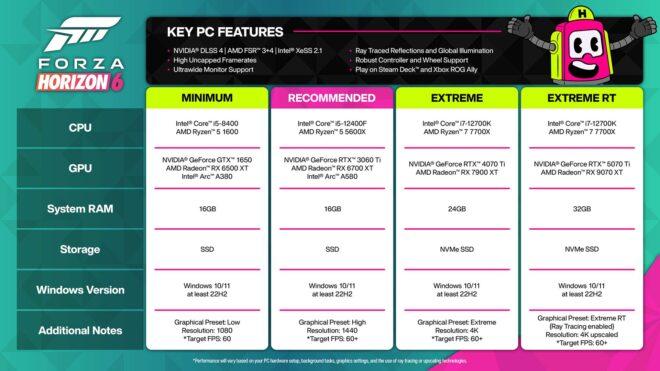
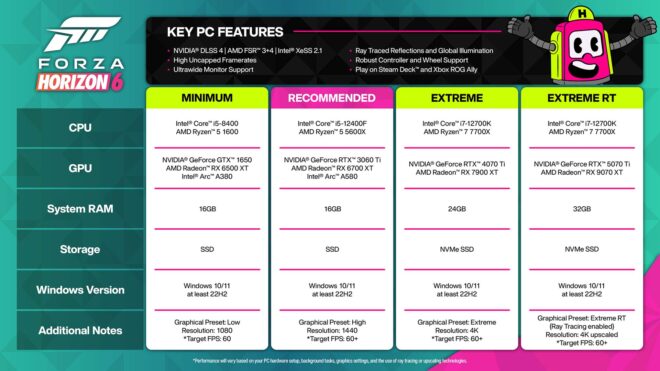 Bugün Nvidia tarafından yapılan resmi doğrulamaya göre Forza Horizon 6 çıkış gününde “çoklu kare oluşturma” özellikli DLSS 4 desteğine sahip olacak. Nvidia Reflex desteği de bulunan oyun; aynı zamanda ultra geniş ekran, sınırsız kare hızı, ray tracing yansımalar ve ray tracing global illumination aydınlatma gibi önemli özelliklerle geliyor. Bu detaylar doğrudan Nvidia ekran kartı sahiplerini ilgilendirirken, oyunda aynı zamanda AMD FSR 3, FSR 4 ve Intel XeSS 2.1 destekleri de yer alıyor. Dün oyunun resmi PC sistem gereksinimleri de paylaşılmıştı. Japonya’da geçen yapım için 1440p / High / 60 FPS özelinde tavsiye edilen işlemciler i5-12400F ile Ryzen 5 5600X, tavsiye edilen ekran kartları ise RTX 3060 Ti, RX 6700 XT ve Arc A580 oldu. En az 16 GB RAM ve SSD depolama biriminin istendiği yapım, 4K / en yüksek grafik ayarları / Ray Tracing / 60 FPS özelindeyse i7-12700K ya da Ryzen 7 770X işlemci, RTX 5070 Ti ya da […]
Forza Horizon 6, çoklu kare oluşturma özellikli DLSS 4 desteğiyle çıkıyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Beyond the Prompt: The Next Level of AI Development
If you’ve been anywhere near tech Twitter, Hacker News, or dev.to recently, you’ve seen the explosion of content around “prompt engineering.” Articles promise to unlock the secrets of ChatGPT with the perfect incantation of words. And while crafting effective prompts is a crucial skill—as highlighted by the popular Portuguese article on prompt engineering—it represents just the first step in a much larger journey. The real frontier isn’t just talking to AI models; it’s building with them.
This guide is for developers ready to move from casual experimentation to constructing production-ready AI applications. We’ll move beyond the single-prompt interface and explore the essential tools, patterns, and architectural considerations that define modern AI engineering.
The Pillars of AI Engineering
AI Engineering sits at the intersection of traditional software engineering, data science, and a new set of AI-native practices. It involves building reliable, scalable, and maintainable systems that leverage large language models (LLMs) and other AI components. Let’s break down the core pillars.
1. The Orchestration Layer: LangChain and LlamaIndex
Direct API calls to models like GPT-4 are simple but limited. For complex applications, you need an orchestration framework. These tools help you chain multiple calls, manage context, integrate external data, and handle complex logic.
LangChain is the most prominent framework. It provides abstractions like Chains, Agents, and Tools to compose multi-step reasoning processes.
from langchain.chains import LLMChain
from langchain.prompts import PromptTemplate
from langchain_openai import ChatOpenAI

# Define a prompt template
prompt = PromptTemplate(
    input_variables=["product"],
    template="What are 5 creative names for a company that makes {product}?",
)

# Create a chain
llm = ChatOpenAI(model="gpt-4")
chain = LLMChain(llm=llm, prompt=prompt)

# Run the chain
result = chain.invoke({"product": "eco-friendly water bottles"})
print(result['text'])
LlamaIndex specializes in data augmentation, making it exceptional for building retrieval-augmented generation (RAG) applications. It easily connects your private data to LLMs.
The choice often comes down to: use LangChain for complex agentic workflows and tool use, and LlamaIndex when your app’s core is searching and synthesizing from a knowledge base.
2. Embeddings and Vector Databases: Giving Your AI Memory
LLMs have a fundamental limitation: they don’t inherently know your private data. The solution is Retrieval-Augmented Generation (RAG). The process is straightforward:
text-embedding-3-small.# Simplified RAG workflow using OpenAI and Pinecone (a vector DB)
from openai import OpenAI
import pinecone
client = OpenAI()
pc = pinecone.Pinecone(api_key="YOUR_KEY")
# 1. Create and store embeddings (Indexing - done once)
documents = ["Your document text here..."]
response = client.embeddings.create(model="text-embedding-3-small", input=documents)
embeddings = [data.embedding for data in response.data]
# Store in Pinecone (assuming index exists)
index = pc.Index("my-knowledge-base")
index.upsert(vectors=zip(["doc_1"], embeddings, [{"text": documents[0]}]))
# 2. Query (Retrieve & Generate)
query = "What does the document say about X?"
query_embedding = client.embeddings.create(model="text-embedding-3-small", input=[query]).data[0].embedding
# Retrieve relevant chunks
results = index.query(vector=query_embedding, top_k=3, include_metadata=True)
context = " ".join([match.metadata['text'] for match in results.matches])
# Generate answer with context
prompt = f"Answer based on this context: {context}nnQuestion: {query}"
completion = client.chat.completions.create(
model="gpt-4",
messages=[{"role": "user", "content": prompt}]
)
print(completion.choices[0].message.content)
Popular vector databases include Pinecone (managed, easy), Weaviate (open-source, feature-rich), and pgvector (PostgreSQL extension, great if you’re already in that ecosystem).
3. Evaluation and Observability: Trust, but Verify
How do you know your AI application is working correctly? Unlike traditional code, LLM outputs are non-deterministic. You need a robust evaluation strategy.
4. Production Patterns: Agents, Tool Use, and Guardrails
Putting It All Together: A Modern AI Application Architecture
Here’s a high-level view of how these pieces fit into a scalable backend service:
[User Request]
        |
        v
[API Gateway / Backend Router]
        |
        v
[Orchestration Layer (LangChain/LlamaIndex Agent)]
        |                               |
        |---> [Tool 1: Vector DB Search (RAG)] <---[Vector DB]
        |---> [Tool 2: Calculator/API]
        |---> [Guardrails: Input/Output Validation]
        |
        v
[LLM Provider (OpenAI, Anthropic, Local Model)]
        |
        v
[Response Cached] --> [Semantic Cache]
        |
        v
[Observability & Logging (LangSmith)]
        |
        v
[Formatted Response to User]
Your Next Steps: From Reading to Building
Prompt engineering is the gateway drug, but AI engineering is the full-stack discipline. To start building:
The most impactful AI applications of the next decade won’t be built on clever prompts alone. They will be built by developers who understand how to integrate these powerful but unpredictable models into the rigorous, reliable world of software engineering.
Ready to move beyond the prompt? Pick one tool from this guide—LangChain, LlamaIndex, or a vector database—and build a prototype this week. Share what you learn; the best practices in this field are being written by builders like you, right now.
Over the past months I’ve been building a WhatsApp-first AI receptionist that handles booking and rescheduling directly into Google Calendar.
One thing became obvious quickly:
Most agent frameworks work well locally, but start breaking once you try to run them as a multi-tenant production service.
Session state disappears. Memory becomes fragile. PII handling is unclear. Human escalation is missing.
So I started building an opinionated framework called Glaivio, applying a convention-over-configuration approach similar to what Rails did for web apps — but for AI agents.
The goal isn’t flexibility.
The goal is predictable production behavior.
Repo:
https://github.com/tavyy/glaivio-ai
The problem with most agent architectures today
Typical agent demos assume:
That works for prototypes.
It doesn’t work when:
These problems appear immediately when deploying agents inside real businesses.
Design principle: state should be infrastructure, not an afterthought
Most frameworks treat conversation history as optional memory.
Glaivio treats it as required infrastructure.
Instead of:
conversation history is Postgres-backed by default.
That means:
Agents should not “forget” conversations because a container restarted.
Privacy middleware should exist before the LLM call
Another issue I kept seeing:
PII goes directly to model providers.
For production systems this becomes a real blocker.
Glaivio includes a middleware layer (work in progress) that automatically redacts:
before sending payloads to the LLM provider.
The goal is to make privacy a default behavior instead of an integration burden.
Agents need native escalation paths
Real users don’t behave like demos.
Eventually the agent becomes uncertain.
Most frameworks leave escalation as an application-layer concern.
Glaivio includes a simple trigger mechanism:
on_confusion → escalate to human operator
In practice this connects easily to:
This prevents agents from getting stuck in loops.
Self-improving agents without prompt hacking
One recurring issue with deployed agents:
users correct them constantly.
Usually this feedback disappears.
Glaivio experiments with extracting corrections into a persistent corrections file so agents adapt over time without rewriting prompts manually.
Still early, but promising.
Memory should behave more like cognition than logs
Instead of loading entire histories into context windows, the framework is evolving toward a two-layer memory model:
Only distilled facts relevant to the current task enter the active reasoning window.
The rest stays persistent but inactive.
This keeps token usage predictable while preserving long-term knowledge.
Example: building a WhatsApp receptionist agent
Using this structure I was able to implement:
into Google Calendar from WhatsApp conversations in roughly 20 lines of code.
# skills/check_availability.py
from glaivio import skill

@skill
def check_availability(date: str, time: str) -> str:
    """Check if a time slot is available. Always call before book_appointment.
    date: YYYY-MM-DD, time: HH:MM 24h format."""
    # call your calendar API here
    return "Available"
plaintext
# skills/book_appointment.py
from glaivio import skill

@skill
def book_appointment(patient_name: str, patient_phone: str, date: str, time: str) -> str:
    """Book an appointment. Only call after check_availability confirms the slot is free.
    patient_phone: use the current user's ID from context.
    date: YYYY-MM-DD, time: HH:MM 24h format."""
    # call your calendar API here
    return f"Booked {patient_name} on {date} at {time}"
plaintext
from dotenv import load_dotenv
load_dotenv()

from glaivio import Agent
from skills.check_availability import check_availability
from skills.book_appointment import book_appointment

agent = Agent(
    instructions="prompts/system.md",
    skills=[check_availability, book_appointment],
    learn_from_feedback=True,
    privacy=True,
)

if __name__ == "__main__":
    agent.run(channel="whatsapp")
The goal of the framework is to make production agent deployments feel closer to:
instead of experimental scripts.
What I’m exploring next
Still working on:
If you’re experimenting with production agent deployments, I’d be interested to hear what breaks first in your setup.
For months my workflow looked like this: ask ChatGPT a question, copy the answer, paste it into Claude for a second opinion, then check with Gemini. Every single day. I was the copy-paste middleman between AI models.
So I asked myself — what if they could just talk in the same room?
I built a platform where multiple AI agents and multiple humans share one real-time group conversation. Not side-by-side comparison. Not model switching. An actual group chat where everyone — human and AI — sees every message and responds in context.
What I discovered
The models genuinely disagree with each other. Not politely — substantively.
I asked all four models to analyze a business strategy:
The most interesting part: when Claude disagreed with GPT, GPT adjusted its next response. It saw the critique in context and self-corrected — without me telling it to.
After a few rounds, it felt less like using a tool and more like moderating a team with actual personalities.
The architecture
The real challenge wasn’t integrating AI APIs — that’s straightforward. The hard part was building real-time multi-user chat where some participants are humans (persistent WebSocket connections) and some are AI agents (server-side, triggered by messages).
Stack:
Key architectural decisions:
@Mention parsing — messages are parsed before sending to determine which agents should respond. No @mention + auto_respond flag = agent responds automatically. @mention a specific agent = only that one fires. @all-agents = all fire sequentially with a queue to prevent overlap.
Sender type — the existing role column (user/assistant/system) wasn’t granular enough for multi-user rooms. Added a sender_type enum (human/agent) plus agent_id foreign key for proper attribution.
Room participants — had to build a full room_participants table with roles (owner/admin/member), invite system with shareable codes, and permission checks on every message send.
Agent orchestration — each agent has its own model, provider, system prompt, and temperature. When triggered, the full conversation history is sent as context so agents see what everyone (including other agents) has said.
Context length — long conversations blow up token costs. Solved with cursor-based pagination — load last 100 messages, fetch more on scroll. AI calls only get recent context window.
Credit system — prepaid credits instead of flat subscriptions. Users buy credits in advance, each AI response deducts based on model + tokens used. We never owe an API provider money we haven’t collected.
Features that emerged
Debate Mode — two AI agents argue opposing sides of a topic in structured rounds while a human moderates. Produces significantly better analysis than asking either model for a “balanced view.”
Review Mode — one agent creates content, another critiques it, the creator revises. Automatic multi-cycle feedback loops.
Red Room — submit any project or idea into a room full of AI critics configured to find weaknesses. Whatever survives is worth building.
What I’d do differently
I spent too long building features before showing anyone. The admin dashboard, fraud detection, moderation queue — all built before a single user tried the core product. If I started over, I’d ship the group chat with two AI agents and nothing else. Everything else is a distraction until you’ve validated that people actually want the core experience.
Try it
The platform is live at fixy.ai. Plans start at $1.99/mo. Bring your own API keys for $5.99/mo.
Curious what other developers think about multi-agent architectures. What would you have built differently?

Patent claims have a simple rule: introduce “a thing” before referring to “the thing.” I fine-tuned DeBERTa-v3 on synthetic antecedent basis errors and hit 90% F1 on my test set. Then I evaluated on real USPTO examiner rejections from the PEDANTIC dataset and watched that number collapse to 14.5% F1, 8% recall. The model catches 8 out of 100 real errors. This writeup covers what I built, why it failed, and what the failure reveals about the gap between synthetic and real patent data.
The problem
Antecedent basis errors are one of the most common reasons for 112(b) rejections. They’re also one of the most annoying—purely mechanical mistakes that slip through because patent claims get long, dependencies get tangled, and things get edited over time. You introduce “a sensor” in claim 1, then three claims later you write “the detector” meaning the same thing. Or you delete a clause during revision and forget that it was the antecedent for something downstream.
"A device comprising a processor, wherein the controller manages memory."
↑ “the controller” appears out of nowhere—no antecedent
More examples of antecedent basis errors
Ambiguous reference
✗ “a first lever and a second lever… the lever is connected to…”
✓ “a first lever and a second lever… the first lever is connected to…”
When multiple elements share a name, “the lever” is ambiguous.
Inconsistent descriptors
✗ “a lever… the aluminum lever”
✓ “an aluminum lever… the aluminum lever”
Adding a descriptor that wasn’t in the antecedent creates uncertainty.
Compound terms
✗ “a video display unit… the display”
✓ “a video display unit… the video display unit”
Can’t reference part of a compound term alone without introducing it separately.
Implicit synonyms
✗ “a sensor… the detector”
✓ “a sensor… the sensor”
Even if they mean the same thing, different words require separate antecedents.
Gray area: Morphological changes
? “a controlled stream of fluid… the controlled fluid”
Often acceptable because the scope is “reasonably ascertainable,” but some examiners may still flag it.
Not an error: Inherent properties
✓ “a sphere… the outer surface of said sphere”
You don’t need to explicitly introduce inherent components. A sphere obviously has an outer surface.
When the USPTO catches it, you get an office action. You pay your attorney to draft a response. The application gets delayed. All for an error so mechanical, so tedious, that checking for it yourself feels almost insulting.
Prior work
Commercial tools
ClaimMaster is a Microsoft Word plugin that parses claims and highlights potential antecedent basis issues: missing antecedents, ambiguous terms, singular/plural mismatches. They describe it as using “natural-language processing technologies” and have recently added LLM integration for drafting and analysis.
Patent Bots is a web-based alternative that highlights terms in green (has antecedent), yellow (warning), or red (missing antecedent).
LexisNexis PatentOptimizer is the enterprise option, checking for antecedent basis and specification support.
Open source
antecedent-check parses claims into noun phrases using Apache OpenNLP. plint is a patent claim linter that requires manually marking up claims with special syntax for new elements and references.
Research
The PEDANTIC dataset from Bosch Research contains 14,000 patent claims annotated with indefiniteness reasons, including antecedent basis errors. They tested logistic regression baselines and LLM agents (Qwen 2.5 32B and 72B) on binary classification of whether a claim is indefinite, with the best model achieving 60.3 AUROC. Antecedent basis was the most common error type, accounting for 36% of all rejections.
Approach
I framed this as token classification: feed the model a claim with its parent claims as context, and have it label each token as the start of an error span, a continuation of one, or clean. I used DeBERTa-v3-base and evaluated against PEDANTIC’s test split (885 samples with real examiner-flagged antecedent basis errors).
The training data problem
PEDANTIC has labeled antecedent basis errors, but only ~2,500 training examples. I wanted more data and control over the error types. So I decided to generate synthetic training data.
I started by pulling ~25,000 granted US patents (2019–2024) from Google Patents BigQuery. These are clean, examiner-approved claims with no antecedent basis errors—at least in theory. I parsed out the claim structure, built dependency chains so each dependent claim had its parent claims as context, and ended up with about 370,000 claim-context pairs.
Then I wrote a corruption generator to inject synthetic errors. The idea: take clean claims and break them in ways that create antecedent basis errors, recording exactly which character spans are wrong.
The six corruption types I generate
50/50 split between clean and corrupted examples. The corrupted ones got converted to BIO format (B-ERR for beginning of error span, I-ERR for inside, O for everything else) and fed to DeBERTa.
After about 12,500 steps, the model hit 90.84% F1 on my validation set. I was feeling pretty good about it.

Then I tested on real data
The PEDANTIC dataset contains actual USPTO examiner rejections with the error spans labeled by hand. This is the real thing—885 test samples where examiners flagged antecedent basis issues in actual patent applications.
Out of the box, my model hit 5% F1. That 90% on synthetic data? Gone. But before giving up, I wanted to understand what was actually happening inside. The model outputs a confidence score for each token—how sure is it that this word is part of an error? By default, it only flags tokens where it’s more than 50% confident. What if I lowered that bar?

Look at the blue line. Precision barely moves—stays around 70% no matter what threshold I pick. That’s interesting. It means the model actually learned something real. When it speaks up, it’s right about two-thirds of the time, whether I make it cautious or aggressive.
The green line is the problem. At the default threshold, recall is 2.6%—catching almost nothing. Crank the threshold down to 0.05, and recall triples to 8.2%. Still bad, but less bad. F1 goes from 5% to 14.5%. I’ll take it.
So the model isn’t broken. It learned patterns that transfer to real data—just not very many of them. The synthetic corruption I generated covers maybe 8% of what USPTO examiners actually flag. The other 92%? Patterns I didn’t think to simulate.
Exploring the data
Before trying to fix anything, I wanted to understand what’s actually in PEDANTIC and what my model sees. I ran every test sample through the model at threshold 0.05 and categorized every prediction.
What the model catches
Of the 258 true positives, 92% start with “the”—phrases like “the user”, “the source profile”, “the matrix”. This makes sense. My synthetic training data generates errors by swapping “a X” to “the X”, so the model learned to flag definite articles that lack antecedents. When it sees “the controller” and can’t find “a controller” earlier in the context, it speaks up.
What it misses
The 2,883 false negatives tell a different story. Only 38% start with “the”. The rest?
Bare nouns (no determiner) — “widgets”, “pattern”, “text content” — 37% of all errors. The noun is used without “the” or “a” but still lacks proper introduction.
“said X” patterns — “said widget”, “said data” — Patent-speak for “the”. My model catches almost none of these despite 30% augmentation in training.
Embedded errors — “a location of the occluded area” — The error is “the occluded area” but PEDANTIC marks the whole phrase. Different annotation granularity.
Pronouns — “it” — 20 cases. Never in my training data because I focused on noun phrases.
False positives
The 152 false positives are mostly patent boilerplate: “The method of claim 8”, “The system”, “The apparatus”. These always have antecedents—”method” refers to the claim itself, “system” to whatever was introduced in claim 1. The model doesn’t understand claim structure, just surface patterns.
Data quality
Some PEDANTIC annotations look like parsing artifacts. I found dozens of instances of “d widgets” and “idgets”—clearly broken spans from the word “widgets”. A small percentage of false negatives have suspicious patterns: spans starting with spaces, single characters, or truncated words. Not a huge problem, but worth noting.
The gap
Now the picture comes together. Go back to those six corruption types I wrote—every single one produces errors starting with “the” or “said”. That’s all the model ever saw during training.
But real examiner rejections are messier. PEDANTIC breaks down like this:
| Pattern | % of PEDANTIC | Recall | Training |
|---|---|---|---|
| “the X” | 42.0% | 16.2% | trained |
| bare nouns | 37.3% | 1.0% | never |
| embedded “the” | 9.6% | 9.3% | never* |
| “a/an X” phrases | 6.2% | 1.0% | never |
| “said X” | 4.3% | 1.5% | 30% aug |
| pronouns | 0.6% | 0.0% | never |
*Embedded patterns get partial credit when our “the X” detection overlaps with the annotated span
But wait—if I trained on “the X” patterns, why is recall only 16%? Where did the other 84% go?
Digging into the 84%
I dug into the model’s actual predictions and found bugs in my corruption logic.
Distribution mismatch on context. 51% of missed “the X” errors are in independent claims (no parent context). My training data has 18% without context—not zero, but the distribution is off. The model learned to rely heavily on cross-referencing “the X” against “a X” in context. When context is missing or sparse, it’s less confident.
I trained on wrong labels. Here’s the bug: 7% of my training errors are “The X of claim N” patterns—things like “The method of claim 1, wherein…”. These should never be errors. The phrase “of claim 1” explicitly provides the antecedent. But my remove_antecedent corruption doesn’t understand this. It sees “a method” in context, “the method” in the claim, removes “a method”, and labels “The method” as orphaned. Wrong.
This created spurious patterns. 10.8% of error tokens in my training data appear within 3 tokens after the [SEP] separator—right at the claim start. The model learned “claim start → likely error”. On real data, it puts ~0.3 probability on [SEP] and claim-start boilerplate. Actual errors also get ~0.3 probability. The model can’t distinguish real errors from the noise I accidentally taught it.
Real errors are more subtle. My synthetic training creates obvious cases—I delete “a sensor” from context, making “the sensor” clearly orphaned. But 17% of PEDANTIC’s “the X” errors have an “a X” that does exist somewhere earlier. The examiner flagged it anyway because the reference was ambiguous, or referred to something different, or had a scope issue. I never generated these nuanced cases.
The false positives
The 152 false positives are almost all patent boilerplate: “the method”, “the apparatus”, “the system”. Now I know why—I literally trained the model to flag these. Those 7% wrong labels taught it that claim-start phrases are errors. The model is doing exactly what I trained it to do. I just trained it wrong.
The real gap
90% F1 on synthetic data, 14.5% on real data. The gap is my corruption logic. I accidentally trained the model on wrong labels, created spurious patterns around [SEP] and claim-starts, and never generated the subtle ambiguity cases that real examiners flag. The model architecture is fine. My training data was broken.
Future work
The model architecture isn’t the problem—DeBERTa learned exactly what I taught it. The corruption logic is what’s broken. There are a few clear directions to try:
Fix the bugs. Filter out “The X of claim N” patterns from error labels. Add explicit negative examples where boilerplate phrases like “The method of claim 1” are labeled as NOT errors. Rebalance the context distribution to match PEDANTIC (more independent claims, fewer dependent).
Cover more patterns. 37% of real errors are bare nouns—”widgets”, “pattern”, “text content”—and I never generated any. Add corruptions that reference bare nouns without introduction. Generate “said X” errors more aggressively (30% augmentation wasn’t enough for 1.5% recall). Add pronoun cases.
Generate harder cases. Right now I create obvious errors—delete “a sensor” and “the sensor” is clearly orphaned. But 17% of real errors have an antecedent that exists but is ambiguous, refers to something different, or has scope issues. This probably requires either manual curation or a smarter generation strategy that intentionally creates near-miss patterns.
Or skip synthetic generation entirely and fine-tune on PEDANTIC’s training split. It’s smaller (only ~2,500 antecedent basis examples vs my 185,000), but it’s real data with real annotation patterns. The distribution would match by construction.
Zero Trust: Die Zukunft der Cybersecurity für Unternehmen
Einleitung: Die Evolution der Cybersecurity
Die Landschaft der Cybersecurity hat sich in den letzten Jahren dramatisch verändert. Traditionelle Sicherheitsmodelle, die oft auf einem perimeterbasierten Ansatz basierten – wie Firewalls, VPNs und feste Netzwerkstrukturen – sind den Herausforderungen moderner Bedrohungen nicht mehr gewachsen. Die Zunahme von Cloud-Computing, mobilen Geräten, Remote-Arbeit und komplexen Cyberangriffen hat zu einer Notwendigkeit für ein neues Sicherheitsmodell geführt. Dieses Modell heißt Zero Trust.
Warum Zero Trust?
Was ist Zero Trust? Die Grundprinzipien
Zero Trust ist kein Produkt, sondern eine Sicherheitsphilosophie. Es basiert auf der Annahme, dass nichts und niemand – weder innerhalb noch außerhalb des Netzwerks – automatisch vertrauenswürdig ist. Jeder Benutzer, jedes Gerät und jede Anwendung muss verifiziert werden, bevor der Zugriff auf Ressourcen gewährt wird.
Die wichtigsten Prinzipien von Zero Trust:
Die Vorteile von Zero Trust für Unternehmen
Die Implementierung von Zero Trust bietet eine Reihe von Vorteilen, die sowohl die Sicherheit als auch die Effizienz von Unternehmen verbessern können.
Verbesserte Sicherheit
Erhöhte Flexibilität
Vereinfachte Compliance
Implementierung von Zero Trust: Best Practices
Die Einführung von Zero Trust ist ein schrittweiser Prozess. Hier sind einige Best Practices:
1. Bewertung und Planung
2. Identitäts- und Zugriffsmanagement (IAM)
3. Netzwerksegmentierung
4. Geräteverwaltung
5. Datensicherheit
6. Kontinuierliche Überwachung und Reaktion
Zero Trust in der Praxis: Fallbeispiele
Viele Unternehmen haben bereits Zero Trust erfolgreich implementiert. Hier sind einige Beispiele:
Werkzeuge und Technologien
Herausforderungen und zukünftige Trends
Die Einführung von Zero Trust kann auch Herausforderungen beinhalten:
Zukünftige Trends
Fazit: Die Notwendigkeit von Zero Trust
Zero Trust ist kein kurzfristiger Trend, sondern die Zukunft der Cybersecurity. Es bietet einen robusten und flexiblen Ansatz, um Unternehmen vor modernen Bedrohungen zu schützen. Durch die Implementierung der Prinzipien von Zero Trust können Unternehmen ihre Sicherheit deutlich verbessern, die Flexibilität erhöhen und die Compliance vereinfachen. Die Reise zu Zero Trust erfordert Planung, Engagement und die richtige Technologie. Unternehmen, die jetzt in Zero Trust investieren, werden in der Lage sein, sich in der sich ständig weiterentwickelnden digitalen Landschaft zu schützen und erfolgreich zu sein. Beginnen Sie noch heute mit der Planung Ihrer Zero Trust-Strategie und sichern Sie sich Ihre Zukunft.