WhatsApp için hazırlanan faydalı yeni özellikler duyuruldu

WhatsApp

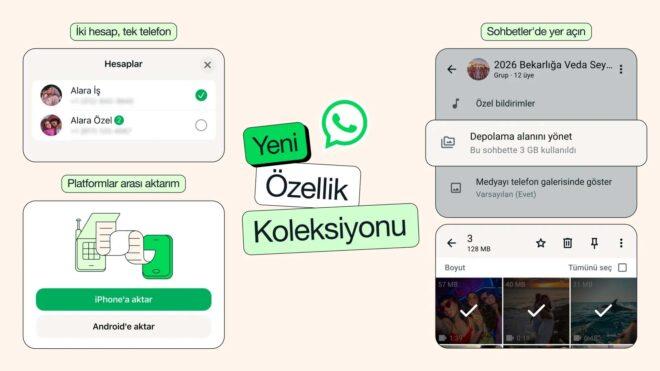
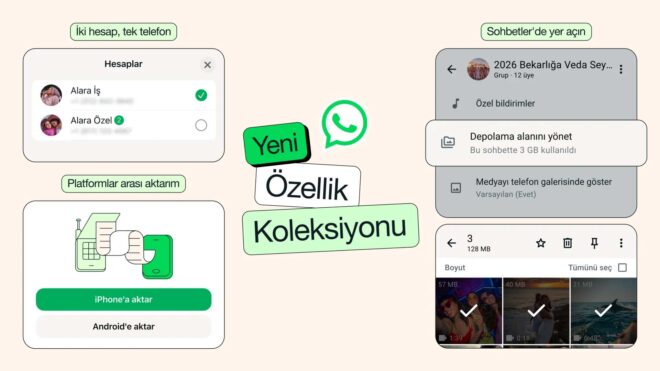
WhatsAppResmi blog sayfası üzerinden milyarlarca kullanıcısı bulunan WhatsApp için hazırlanan faydalı yeni özellikler duyuruldu. “Zaman içinde sohbetlerimiz, önemli anlarımıza ait kayıtlara dönüşür: aileyle yapılan konuşmalar, arkadaşlarımızla attığımız kahkahalar, paylaşmadan duramadığımız fotoğraf ve videolar. Tüm bunlardan en iyi şekilde yararlanmanıza yardımcı olmak için WhatsApp’ı daha da kolay kullanmanızı sağlayacak yeni özellikler sunuyoruz. Bu sayede düzeninizi koruyabilir, işle özel hayatınızı bir arada yönetebilir ve her bir sohbetten daha fazla verim alabilirsiniz.” diyen şirket, yenilikler için kategoriler halinde şunları aktardı: Depolama alanında yer açın, önemli olanları tutun: Sohbetleriniz arttıkça depolama alanınızdaki dağınıklık da artabilir. Artık büyük dosyaları doğrudan sohbetin içinde bulup silebilir, böylece konuşmanızın tamamını silmek zorunda kalmadan ihtiyaç duymadıklarınızı temizleyebilirsiniz. Sohbet adına dokunup Depolama Alanını Yönet’i seçmeniz yeterli. Bir sohbeti temizlerken yalnızca medya dosyalarını temizleyip sohbet geçmişini tutmayı da seçebilirsiniz. Platformlar arası sohbet aktarımı kolaylaştırıldı: Sohbet aktarımı özelliğimiz artık yalnızca aynı platform için değil, sohbet geçmişinizin iOS’tan Android’e aktarılmasını da destekliyor. Telefon […]

WhatsApp için hazırlanan faydalı yeni özellikler duyuruldu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Getting Started with Docling: PDF to Structured Data

Docling is an open-source document conversion tool from IBM Research. It takes PDFs and converts them into clean, structured output like Markdown, HTML, JSON, or plain text. It handles layout analysis, table extraction, image embedding, OCR, and even a vision-based pipeline for complex documents.

This guide walks through installation, the core conversion options, and the advanced flags worth knowing.

Installation

Use a virtual environment:

python -m venv .venv
source .venv/bin/activate  # Windows: .venvScriptsactivate
pip install docling

Verify:

docling --version
# Should output: Docling version: 2.xx.x

Basic Conversion

Docling accepts both local file paths and remote URLs:

docling https://example.com/document.pdf
docling ./my-report.pdf

Default output is Markdown, written to your current directory. For a typical document, expect around two minutes and minimal resource usage.

Output Formats

Markdown (default)

docling file.pdf
# or explicitly
docling file.pdf --to md

Text, headings, tables, and images are all preserved. Images are embedded as base64 data URIs. This is a really useful format for a lot of data pipelines.

HTML

docling file.pdf --to html

The same extracted content wrapped in HTML with basic browser styling. Useful for human-readable web viewing. The underlying extraction is identical to the Markdown output but only the presentation layer changes.

JSON

docling file.pdf --to json

Every element; heading, paragraph, table, image becomes a structured node with semantic metadata. Use this when you need programmatic access to document structure, not just raw text.

Plain Text

docling file.pdf --to text

All structure stripped. Images become <!-- image --> placeholders. Useful only when you need raw text and nothing else.

Advanced Options

VLM Pipeline

docling --pipeline vlm --vlm-model granite_docling file.pdf --output vlm/

The standard pipeline reads the text layer of the PDF. The VLM (Vision Language Model) pipeline processes the document visually, the way a human would read it. This matters in a few specific situations:

  • Image-based pages: Cover pages or sections built entirely from images have no text layer for the standard pipeline to read. The VLM pipeline recovers them.
  • Hidden text artifacts: Old revisions sometimes leave hidden text beneath visible content. The standard pipeline surfaces both strings. The VLM pipeline reads what’s visually rendered, so the artifact doesn’t appear.
  • Complex layouts: Overall structure and layout understanding are noticeably better.

The trade-offs are real though. The VLM pipeline takes significantly more time and is resource (CPU/GPU/RAM) intensive compared to the standard pipeline. It also has its own failure modes some unicode symbols like ✔ that the standard pipeline captures correctly may be replaced with approximate text like (in-place), and some passages may repeat in the output.

Use the VLM pipeline when accuracy matters more than speed. For bulk processing, stick with the standard pipeline unless you have the resources for builk VLM pipelines.

Disabling OCR

docling file.pdf --no-ocr

For PDFs with a proper text layer (digitally created documents), disabling OCR has no effect on output quality and shaves off a little processing time. For scanned documents, disabling OCR means text in images won’t be extracted at all.

Referenced Image Export

docling file.pdf --image-export-mode referenced --output out/

By default, images are embedded as base64 in the output file, which keeps everything self-contained but produces large files. With referenced, images are written as separate files and the Markdown links to them by path. Use this when images need to be processed independently or when a smaller output file is preferred.

Disabling Table Structure Recovery

docling file.pdf --no-tables

Table content is still extracted, but instead of a proper Markdown table with rows and columns, everything collapses into a single cell. Useful if you are processing in bulk and handling table structure downstream.

Further Reading

Imposter Syndrome Didn’t Go Away. It Got Quieter.

I noticed something last year. The imposter syndrome posts disappeared.

Not gradually. They were everywhere — “I’ve been coding for three years and I still Google how to center a div,” “just got promoted to senior and I have no idea what I’m doing,” threads with thousands of likes, people in the replies saying me too, me too, me too. Then the LLMs arrived, and the posts stopped. I thought maybe the tools cured it. That we’d finally found the thing that made everyone feel competent.

I was wrong. The feeling didn’t go away. It just changed shape.

The old imposter syndrome had a specific texture. You knew what you didn’t know. You couldn’t center a div, you’d never touched Kubernetes, you were faking it in standups about GraphQL. The gap was legible. You could name it, study it, fill it. That legibility is what made the posts shareable. “I don’t know X” is a sentence you can say out loud.

The new version is harder to name. You shipped the feature. The tests pass. Your manager is happy. But when someone asks you to walk through the implementation, something is off. You can narrate what the code does. You can’t always explain why it’s structured the way it is, what the model assumed, where it would break under pressure. The code is yours the same way a house is yours when you hired the contractor. You own it. You don’t know every decision that went into the walls.

Engineering culture has long tied ownership to authorship. You wrote the code, therefore you understood it. You understood it, therefore you were responsible for it. That chain held for decades. AI broke it — not dramatically, not all at once, but consistently enough that a new kind of doubt has moved in where the old one used to live.

The data is starting to catch up to what developers already feel.

METR previously published a paper which found the use of AI tools caused a 20% slowdown in completing tasks among experienced open-source developers — a finding strange enough that they ran a follow-up study. That follow-up ran into its own problem: developers refusing to participate because they did not wish to work without AI. 30% to 50% of developers told researchers they were choosing not to submit certain tasks because they didn’t want to do them without AI.

Read that twice. Not “AI makes me faster.” Not even “AI makes me better.” Developers who cannot or will not attempt the work without the tool present. That’s not productivity. That’s dependency.

Luciano Nooijen noticed this before the research did. He used AI tools heavily at work, stopped for a side project, and hit a wall. “I was feeling so stupid because things that used to be instinct became manual, sometimes even cumbersome.” The instincts didn’t fail slowly. They went quiet.

AI coding tools can make you more productive. They can make you feel more confident. They can also produce developers who don’t understand the context behind the code they’ve written or how to debug it.

Stack Overflow called this “the illusion of expertise.” I’d call it something slightly different. It’s not that the expertise is fake. It’s that the path that usually builds expertise — the struggle, the failure, the iteration — got shortened. When AI generates code without the developer engaging deeply with the implementation, they skip over all of those learning iterations. The developer doesn’t struggle with the problem, doesn’t try multiple approaches, doesn’t experience the failures that build intuition.

The old imposter syndrome was painful but self-correcting. You felt like a fraud, so you studied. You filled the gap. The new version doesn’t have an obvious gap to fill. The code shipped. You’re a senior developer with a good job and passing tests and no visible evidence that anything is wrong. The doubt is quieter. That’s what makes it harder.

We’re living in the most empowering time to be a developer. The barrier to building things has never been lower. And yet, I’ve never felt less sure of my own skills.

That’s Pranav Reveendran, writing in December. He’s not alone. A 2025 survey by Perceptyx found a “confidence gap” where 71% of employees use AI, but only 35% of individual contributors feel they understand it well enough. The adoption curve went up. The confidence curve didn’t follow.

This is what the posts were about, when people still wrote them. Not “do I belong in tech?” but “do I understand what I’m building?” The first question had a community around it. Thousands of replies, conferences, entire career tracks built around addressing it. The second question doesn’t have a community yet. It’s the thing people say in DMs but not in threads. It’s the thing I’ve heard from developers who’ve been building for years: I know how to use the tools. I’m not sure I know the work anymore.

I don’t think this resolves neatly. The tools aren’t going away and the productivity is real and I’m not arguing for anyone to stop using them. I use them. I built most of Foundation’s evaluator with AI assistance and I’d do it again.

But I think the silence is worth naming. The imposter syndrome posts didn’t stop because the feeling stopped. They stopped because the feeling changed into something that’s harder to share. “I don’t know how to center a div” is embarrassing but legible. “I shipped a feature I can’t fully explain” is a different kind of statement. It implicates the work, not just the person. It’s harder to say me too to.

The old imposter syndrome asked: am I good enough?

The new one asks: is the work mine?

That’s a harder question. And so far, it’s mostly going unasked.

Web Scraping at Scale: From 1K to 10M Pages

The Scale Problem

Scraping 100 pages is a script. Scraping 10 million pages is an engineering challenge. As you scale web scraping, every part of your system gets stressed — network I/O, CPU, memory, storage, and proxy costs.

I’ve built scrapers that process millions of pages. Here’s what actually matters at scale.

The Scaling Tiers

Scale Pages Architecture Typical Infra
Small 1-10K Single script Laptop
Medium 10K-100K Async + queue Single server
Large 100K-1M Distributed workers Multiple servers
Massive 1M-10M+ Full pipeline Cloud + managed services

Tier 1: Getting to 10K Pages

The first optimization: go async. A synchronous scraper hitting one page at a time wastes 95% of its time waiting for network responses.

Synchronous (Slow)

import requests
import time

def scrape_sync(urls):
    results = []
    for url in urls:
        response = requests.get(url)
        results.append(parse(response.text))
    return results

# 1000 pages at 1s each = ~17 minutes

Async (Fast)

import asyncio
import aiohttp

async def scrape_async(urls, concurrency=20):
    semaphore = asyncio.Semaphore(concurrency)
    results = []

    async def fetch(session, url):
        async with semaphore:
            try:
                async with session.get(url, timeout=aiohttp.ClientTimeout(total=30)) as response:
                    html = await response.text()
                    return parse(html)
            except Exception as e:
                return {'url': url, 'error': str(e)}

    async with aiohttp.ClientSession() as session:
        tasks = [fetch(session, url) for url in urls]
        results = await asyncio.gather(*tasks, return_exceptions=True)

    return [r for r in results if r is not None]

# 1000 pages at 20 concurrent = ~50 seconds

Tier 2: Getting to 100K Pages

At 100K pages, you need:

  • URL queue management — Don’t hold all URLs in memory
  • Deduplication — Avoid re-scraping the same pages
  • Error handling — Retry failures without losing progress
  • Rate limiting — Respect targets without getting banned

URL Queue with Redis

import redis
import hashlib
import json

class URLQueue:
    def __init__(self, redis_url='redis://localhost:6379'):
        self.redis = redis.from_url(redis_url)
        self.queue_key = 'scraper:queue'
        self.seen_key = 'scraper:seen'
        self.failed_key = 'scraper:failed'

    def add(self, url, priority=0):
        url_hash = hashlib.md5(url.encode()).hexdigest()
        if not self.redis.sismember(self.seen_key, url_hash):
            self.redis.zadd(self.queue_key, {url: priority})
            self.redis.sadd(self.seen_key, url_hash)
            return True
        return False

    def get_batch(self, batch_size=100):
        urls = self.redis.zpopmin(self.queue_key, batch_size)
        return [url.decode() for url, _ in urls]

    def mark_failed(self, url, error):
        self.redis.hset(self.failed_key, url, json.dumps({
            'error': str(error),
            'timestamp': time.time()
        }))

    @property
    def size(self):
        return self.redis.zcard(self.queue_key)

    @property
    def seen_count(self):
        return self.redis.scard(self.seen_key)

Deduplication with Bloom Filters

For millions of URLs, a set uses too much memory. Use a Bloom filter:

from pybloom_live import BloomFilter

class URLDeduplicator:
    def __init__(self, capacity=10_000_000, error_rate=0.001):
        self.bloom = BloomFilter(capacity=capacity, error_rate=error_rate)

    def is_new(self, url):
        normalized = url.rstrip('/').lower()
        if normalized in self.bloom:
            return False
        self.bloom.add(normalized)
        return True

dedup = URLDeduplicator()
assert dedup.is_new('https://example.com/page1') == True
assert dedup.is_new('https://example.com/page1') == False  # Already seen

Tier 3: Getting to 1M Pages

At this scale, you need distributed workers and robust proxy management.

Distributed Worker Architecture

import asyncio
from multiprocessing import Process

class ScraperWorker:
    def __init__(self, worker_id, queue, proxy_pool, concurrency=50):
        self.worker_id = worker_id
        self.queue = queue
        self.proxy_pool = proxy_pool
        self.concurrency = concurrency
        self.stats = {'success': 0, 'failed': 0, 'total': 0}

    async def run(self):
        semaphore = asyncio.Semaphore(self.concurrency)

        while True:
            batch = self.queue.get_batch(100)
            if not batch:
                await asyncio.sleep(5)
                continue

            tasks = [self.fetch_with_retry(url, semaphore) for url in batch]
            results = await asyncio.gather(*tasks)

            for result in results:
                if result:
                    await self.store(result)
                    self.stats['success'] += 1
                else:
                    self.stats['failed'] += 1
                self.stats['total'] += 1

            if self.stats['total'] % 1000 == 0:
                print(f"Worker {self.worker_id}: {self.stats}")

    async def fetch_with_retry(self, url, semaphore, max_retries=3):
        async with semaphore:
            for attempt in range(max_retries):
                proxy = self.proxy_pool.get_proxy()
                try:
                    async with aiohttp.ClientSession() as session:
                        async with session.get(
                            url,
                            proxy=proxy,
                            timeout=aiohttp.ClientTimeout(total=30),
                            headers={'User-Agent': self.get_random_ua()}
                        ) as response:
                            if response.status == 200:
                                return await response.text()
                            elif response.status == 429:
                                await asyncio.sleep(2 ** attempt)
                except Exception:
                    await asyncio.sleep(1)

            self.queue.mark_failed(url, 'Max retries exceeded')
            return None

Proxy Management

At scale, proxy management is critical. You need thousands of IPs rotating efficiently:

import random

class ProxyPool:
    def __init__(self, proxy_list=None, rotating_endpoint=None):
        self.proxy_list = proxy_list or []
        self.rotating_endpoint = rotating_endpoint
        self.failures = {}

    def get_proxy(self):
        if self.rotating_endpoint:
            return self.rotating_endpoint

        # Filter out proxies with too many failures
        healthy = [
            p for p in self.proxy_list 
            if self.failures.get(p, 0) < 5
        ]

        if not healthy:
            self.failures.clear()  # Reset
            healthy = self.proxy_list

        return random.choice(healthy)

    def report_failure(self, proxy):
        self.failures[proxy] = self.failures.get(proxy, 0) + 1

For production-scale proxy infrastructure, ThorData provides rotating residential proxies with millions of IPs — essential when you’re scraping millions of pages across multiple targets.

Tier 4: 10M+ Pages

At massive scale, you need:

1. Storage Pipeline

Don’t write to a database per-page. Batch writes:

import gzip
import json
from pathlib import Path

class BatchWriter:
    def __init__(self, output_dir='data/', batch_size=1000):
        self.output_dir = Path(output_dir)
        self.output_dir.mkdir(exist_ok=True)
        self.buffer = []
        self.batch_size = batch_size
        self.file_count = 0

    def add(self, record):
        self.buffer.append(record)
        if len(self.buffer) >= self.batch_size:
            self.flush()

    def flush(self):
        if not self.buffer:
            return

        filename = self.output_dir / f'batch_{self.file_count:06d}.jsonl.gz'
        with gzip.open(filename, 'wt') as f:
            for record in self.buffer:
                f.write(json.dumps(record) + 'n')

        print(f'Wrote {len(self.buffer)} records to {filename}')
        self.buffer = []
        self.file_count += 1

2. Monitoring Dashboard

import time
from collections import defaultdict

class ScraperMetrics:
    def __init__(self):
        self.counters = defaultdict(int)
        self.start_time = time.time()

    def increment(self, metric, value=1):
        self.counters[metric] += value

    def report(self):
        elapsed = time.time() - self.start_time
        total = self.counters['pages_scraped']
        rate = total / elapsed if elapsed > 0 else 0

        print(f'--- Scraper Stats ---')
        print(f'Pages scraped: {total:,}')
        print(f'Failed: {self.counters["failed"]:,}')
        print(f'Rate: {rate:.1f} pages/sec')
        print(f'Elapsed: {elapsed/3600:.1f} hours')
        print(f'Estimated remaining: {(self.counters["total_urls"] - total) / max(rate, 0.1) / 3600:.1f} hours')

3. Checkpointing

At this scale, crashes happen. Save progress:

class Checkpoint:
    def __init__(self, checkpoint_file='checkpoint.json'):
        self.file = checkpoint_file

    def save(self, state):
        with open(self.file, 'w') as f:
            json.dump(state, f)

    def load(self):
        try:
            with open(self.file) as f:
                return json.load(f)
        except FileNotFoundError:
            return None

    def resume_or_start(self, initial_state):
        saved = self.load()
        if saved:
            print(f'Resuming from checkpoint: {saved["pages_done"]:,} pages done')
            return saved
        return initial_state

Cost Optimization

Component Cost at 1M pages Cost at 10M pages
Proxies $200-500 $1,500-3,000
Compute $50-100 $200-500
Storage $10-20 $50-100
Total ~$300-600 ~$2,000-3,500

Proxies are always the biggest cost. Using efficient proxy management and targeting only pages you need reduces costs significantly. ThorData offers competitive per-GB pricing that scales well.

Using Managed Infrastructure

For teams that don’t want to build all this infrastructure, platforms like Apify provide managed scraping infrastructure with built-in queuing, proxy management, and storage. You write the scraping logic; they handle the scaling. Check out the various scraping actors on the Apify Store for pre-built solutions.

Key Principles for Scraping at Scale

  1. Go async from day one — Synchronous scraping doesn’t scale
  2. Deduplicate early — Don’t waste proxy credits on pages you’ve already seen
  3. Batch everything — Writes, API calls, proxy rotations
  4. Monitor relentlessly — You can’t fix what you can’t see
  5. Plan for failures — Checkpoint, retry, resume
  6. Respect targets — Rate limiting isn’t optional, it’s survival
  7. Invest in proxies — ThorData residential proxies are the foundation of any large-scale operation

Conclusion

Scaling from 1K to 10M pages requires evolving from a simple script to a distributed system. The fundamentals — async I/O, queuing, deduplication, proxy management, and monitoring — remain constant. Each tier adds complexity, but also reliability. Start simple, scale when you need to, and always use quality proxy infrastructure like ThorData for the foundation.

What Competitor Pages to Monitor and How Often to Take Screenshots

Most companies understand that keeping an eye on competitors is important. But in practice, it usually goes something like this: once a month, someone opens a competitor’s website, scrolls through the homepage, glances at a few other pages, decides nothing has really changed, and closes the tab. Then we’re caught off guard when that same competitor launches a new feature, changes their pricing, or reworks their positioning entirely — and we find out about it last.

The problem isn’t that people don’t want to monitor competitors. More often, the real issue is simpler — it’s unclear what exactly to monitor and how frequently. Tracking every single page is too time-consuming, if not impossible. But ignoring competitors altogether leads to exactly the kind of surprises we just described: a new feature appears on their site, and you had no idea it was coming. In this article, we’ll go over the specific pages worth monitoring, recommend a checking frequency for each type, and look at how to automate the entire process so it runs with minimal effort on your part.

Start With Five Competitors, No More

The first mistake is trying to monitor everyone. You might have 20 competitors in your space, but only 3 to 5 of them actually affect your business. These are the companies targeting the same audience, operating in the same price range, and showing up in the same search results — the ones who are genuinely your direct competitors, not just other players in the market.

We recommend picking five primary or potential competitors. For each one, identify 5 to 10 key URLs on their site. That gives you roughly 25 to 50 pages total, which is a perfectly manageable volume for automated page monitoring.

The Pricing Page Is the Most Valuable One

If you can only monitor a single page on a competitor’s site, make it the pricing page. Price changes are a direct signal of strategic decisions. If a competitor raises their prices, it usually means they feel confident about growth and aren’t worried about losing customers over a price bump. On the other hand, if they drop prices, the picture is different — they may be fighting for market share or struggling with churn.

But it’s not just about the numbers themselves. Pay attention to a few other things as well:

Plan structure. If they had three plans and now there are four, that’s already worth thinking about. If they added an enterprise tier with a “contact us” label instead of a price, it signals a move toward larger customers.

Feature gating. Which features ended up in the free plan and which ones are behind a paywall? When features get moved between plans, it’s usually a strong signal of where their priorities are shifting.

Presentation. Did they switch to “Starting at $9/mo” instead of showing exact figures? Did they make annual billing the default option? Every detail like this is typically the result of an A/B test or a deliberate strategic decision.

How often to monitor: We recommend about once a week. Prices don’t change every day, but missing a change for two weeks means losing time and failing to draw the right conclusions for your own strategy.

The Homepage Is a Mirror of Positioning

The homepage is how a company wants to be perceived. Every change on it is a deliberate choice. A new headline means they’ve shifted their messaging. If they removed a section with client logos and replaced it with case studies, they’re switching from social proof to proof of value.

Here’s what to watch for on the homepage:

The hero section, or the very first screen of the site: the headline, subheadline, and CTA. When a competitor changes their main headline, it’s always meaningful. It means someone was given a task and spent time finding a better way to phrase what the company does.

Social proof: client logos, numbers (“10,000+ teams”), testimonials. If a large company’s logo appears on their site for the first time, it’s a clear sign the competitor just closed a major deal.

Navigation: new menu items often signal the launch of new products or sections and point to the company expanding its overall concept.

As we mentioned above, the homepage should be monitored about once a week. It doesn’t get updated very frequently, but when it does, the changes are almost always significant.

The Features Page and Changelog

If a competitor maintains a public changelog or a “What’s New” page, it’s a goldmine. You can literally see what their development team is working on and which features they consider important enough to announce.

The features page (/features, /product) is also useful but changes less often. When it does change, though, it’s typically a major update — new integrations, new capabilities, or a complete rethink of the product lineup.

How often: the changelog should be checked about twice a week. The features page is fine at once every two weeks.

The Blog and Company News Feed

A competitor’s blog or news feed reveals two things: what topics they’re betting on (their SEO strategy) and how they talk to their audience (tone of voice, the pain points they’re highlighting).

You don’t need to monitor every individual post. It’s enough to track the main blog page — /blog — and see what new posts appear, how often they’re publishing, and what topics they cover.

If a competitor suddenly starts publishing three articles a week instead of one, it means they’ve hired a content team, they’re investing in SEO, or it could even signal a traffic drop they’re trying to compensate for. If their topics shift from how-to guides to case studies, they’re moving from attracting traffic to converting it.

Career Pages

The next page that’s definitely worth tracking at least twice a month is the careers page, because job listings are an underrated source of competitive intelligence. If a competitor is hiring five ML engineers, that tells a very different story than if they’re looking for three enterprise sales reps. Open positions reveal strategic direction earlier than any press release.

Monitor /careers or /jobs. Screenshots are especially useful here because job listings appear and disappear, and without an archive you won’t notice the pattern.

Why once every two weeks? Because job postings don’t update that frequently, and a two-week interval is sufficient to track hiring trends over time.

Landing Pages for Specific Campaigns

If you know a competitor is running ad campaigns, it’s worth monitoring their landing pages. These pages show which messages and offers are working (or being tested) to attract customers.

The tricky part is that landing pages often live on subdomains or at unpredictable URLs. But if you’ve found them, add them to your monitoring list.

How often: daily, as long as the campaign is active. Landing pages change frequently — A/B tests, different variants, updated offers.

Summary Table

Page Type Example URL Frequency Why It Matters
Pricing /pricing Once a week Direct signal of strategy
Homepage / Once a week Positioning and messaging
Changelog /changelog, /whats-new Twice a week Product development pace
Features /features, /product Every 2 weeks Major updates
Blog /blog Once a week SEO and content strategy
Careers /careers, /jobs Every 2 weeks Strategic direction
Landing pages Various Daily Marketing campaigns

For 5 competitors with 7 to 8 pages each, that’s roughly 35 to 40 URLs. At an average frequency of once per week, you’re looking at about 150 to 200 screenshots per month. That’s a perfectly manageable volume for an automated tool.

Manual Monitoring Doesn’t Work

You could try doing all of this by hand. Open each page, take a screenshot, save it in a folder with today’s date. That approach works for a week, maybe two. Then you forget, skip a day, lose the thread.

The problem with manual monitoring isn’t laziness — it’s scale. Checking 40 URLs once a week means 40 tabs, 40 screenshots, 40 files to organize. And that’s assuming you only have 5 competitors. On top of that, you still need to compare current screenshots with previous ones to actually spot the changes.

An automated screenshot tool solves all of these problems. You set up your URLs and schedule once, then simply review the results whenever it’s convenient. And if the tool also highlights visual differences between screenshots, you can immediately see what changed without having to compare images side by side.

What to Do With the Data You Collect

Screenshots on their own are just images. The real value comes when you start analyzing patterns:

If a competitor changed their pricing page three times in a single quarter, they’re likely testing their monetization model — probably because the current one isn’t performing well.

If their homepage shifted from “for developers” to “for teams,” the competitor is moving upmarket.

If the changelog gets updated once a week consistently, you’re probably looking at a well-funded team with a regular release cycle.

If positions like “Head of Partnerships” and “Enterprise Account Executive” show up on their careers page, the competitor is gearing up for an enterprise push.

Once a month, it’s worth spending 30 minutes going through your screenshot archive and noting the trends. It won’t replace a deep competitive analysis, but it gives you a steady stream of signals that help you make decisions faster.

Snapshot Archive automatically captures screenshots of any web page on a schedule and highlights visual differences between snapshots. Set up competitor monitoring in 5 minutes — no code, no manual work.

Designing Game Economies: Why Spreadsheets Eventually Break

Game economy design almost always starts the same way:

  • You open a spreadsheet.
  • You define a few currencies, maybe sketch a progression curve, add some reward tables — and things feel under control.
    At first.
    But as your game grows, the economy grows with it. And the tools you started with begin to show their limits.

The Standard Workflow Most Teams Use

If you’ve worked on a game economy, this setup will probably look familiar:
Google Sheets – balancing, numbers, simulations
Miro – mapping systems and flows
Notion – documenting logic and decisions

Each tool solves a different problem. Together, they form a patchwork system.
And that’s exactly where the issues begin.

The Hidden Cost of Spreadsheets

Spreadsheets are incredibly flexible — which is both their strength and their weakness.

1. Complexity Creeps In

What starts as a simple table turns into:

  • Dozens of interconnected sheets
  • Deeply nested formulas
  • Hardcoded assumptions
  • References that are hard to trace

At some point, the sheet stops being a tool — and

2. Systems Become Invisible

Game economies are systems:

  • Currencies flow between features
  • Sources and sinks interact
  • Changes ripple across the entire game

But spreadsheets don’t show systems — they show data.

So designers compensate by building diagrams in tools like Miro.

Now you have:

  • Data in one place
  • System logic in another

And they drift apart over time.

3. Simulation Becomes Fragile

You can simulate an economy in spreadsheets.

But in practice:

  • Simulations are hard to scale
  • Small mistakes break large models
  • Iteration becomes slow

This leads to a subtle but important problem:

Designers test less.

And fewer simulations mean more risk in the live economy.

4. Knowledge Gets Fragmented

When you split your workflow across tools:

  • Sheets – numbers
  • Miro – structure
  • Notion – explanations

There’s no single source of truth.

This creates:

  • Misalignment between team members
  • Outdated documentation
  • Repeated questions and rework

The Real Issue: Tools vs Systems

The core problem isn’t spreadsheets themselves.

It’s that general-purpose tools are being used to manage system-level complexity.

Game economies are:

  • Interconnected
  • Dynamic
  • Continuously evolving (especially in LiveOps)

But the tools are:

  • Static
  • Isolated
  • Not system-aware

That mismatch becomes more painful over time.

When Do These Problems Start Showing?

Not immediately.

Usually when your game reaches:

  • Multiple currencies (soft, hard, event-based)
  • Several progression layers
  • LiveOps features (events, battle passes, offers)
  • Frequent balancing updates

At that point:

  • Small changes have large side effects
  • Tracking impact becomes difficult
  • Confidence in changes decreases

*What Teams Usually Do Next
*

Different teams solve this in different ways:

  • Build more complex spreadsheets
  • Add more documentation
  • Create more detailed diagrams
  • Rely more on experience and intuition

These help — but they don’t solve the underlying issue.

They just manage it.

Final Thoughts

Spreadsheets are an excellent starting point for economy design.

They’re flexible, fast, and accessible.

But as your system grows, the cost of maintaining that flexibility increases:

  • More manual work
  • More risk of errors
  • Slower iteration

At some point, the challenge shifts from “how do we design this?”
to “how do we manage the complexity of what we’ve already built?”

And that’s where the real difficulty of game economy design begins.

Recently, while dealing with these exact issues, I came across tools like Itembase.dev that try to approach economy design as a system rather than just a collection of tables.

Not saying it’s the solution — but it did make me realize how much friction in our workflow actually comes from the tools we use, not just the design itself.

If you’re working on game economies, I’d be curious:

At what point did your spreadsheet setup start breaking down?

What is Fedora

What is Fedora?

Fedora is a Linux distribution with latest features, developed by the community-driven Fedora Project and sponsored by Red Hat. In as much as it can’t override Ubuntu and Linux Mint, it is considered beginner friendly.

Key Features of Fedora

Fedora is one of the most innovative Linux distributions available today with up-to-date features. It focuses on providing cutting-edge technology while maintaining stability and security. Below are some of the key features that make Fedora a popular choice among developers and Linux enthusiasts.

Free and Open Source
Fedora is absolutely free to use and open source. This means anyone can download, use, modify, and distribute it without paying any license fees. There are also no paid upgrade tiers. This makes it an excellent choice for students, developers, and organizations looking for a cost-effective operating system.

Modern Software
Fedora is known for shipping the latest software and technologies. It frequently receives updates, ensuring users have access to new features, performance improvements, and the latest development tools.

Strong Security
On every platform security is key. Security is a core focus of Fedora. It comes with advanced security technologies enabled by default, helping to protect your system from vulnerabilities and threats. This makes it suitable for both development environments and production use.

Developer Friendly
Fedora provides a powerful environment for programmers. It supports many programming languages, development frameworks, and tools, making it ideal for software development, DevOps, and system administration.

Stable Performance
Even though Fedora includes modern technologies, it maintains reliable and stable performance. The Fedora community carefully tests updates to ensure the system remains dependable for daily use.

Fedora Editions

1. Fedora Workstation

Fedora Workstation is the most common edition. It is designed for:

  • Students

  • Developers

  • Everyday computer users
    Features:

  • Graphical desktop interface (easy to use)

  • Pre-installed developer tools

  • Uses the GNOME desktop environment by default

  • Good for programming and learning Linux
    👉 Best for: Personal laptops and desktops

2. Fedora Server
Fedora Server is designed for managing servers and networks.
Features:

  • No heavy graphical interface (can run command line)

  • Advanced network management tools

  • Strong security features

  • Can host websites and databases
    Best for:

  • Web servers

  • File servers

  • Network services

  • IT infrastructure

3. Fedora IoT
Fedora IoT is designed for Internet of Things (IoT) devices (smart devices connected to the internet).
Examples of IoT devices:

  • Smart sensors

  • Smart cameras

  • Industrial controllers

  • Smart home devices

Features:

  • Lightweight

  • Remote device management

  • Automatic updates

  • Security focused
    Best for: Embedded systems and smart devices

4. Fedora Silverblue
Fedora Silverblue is an advanced version designed for developers who want a stable and secure system.
Unique feature: It is called an immutable OS, meaning the core system cannot be easily changed (this prevents system breakage).
Features:

  • Very stable updates

  • Uses containers like Docker and Podman for apps

  • Easy rollback if an update fails

  • Good for cloud-native development
    Best for:

  • Advanced Linux users

  • Developers

  • DevOps engineers

Working on Fedora in Outreachy contibution period
During the contribution period, I plan to study the Fedora RPM Packaging Guidelines and understand how they can be organized into a structured knowledge base for a Retrieval-Augmented Generation (RAG) system. I intend to set up a Fedora development environment and strengthen my Python skills while applying the basic tool and concepts needed for building and testing small language model workflows.

I greatly plan to contribute by helping with documentation improvements, data preparation, bugs removal and small prototype experiments related to RAG implementation. Additionally, I will actively engage with the Fedora community by communicating with mentors, documenting my progress, and making consistent small contributions to demonstrate my learning progress and commitment to the project.