The Architectural Problem With Compliance-as-a-Service

A major compliance automation platform was just exposed for allegedly fabricating audit evidence at scale. 493 of 494 SOC 2 reports contained the same typo. 259 Type II audits all claimed zero incidents. Pre-written conclusions were generated before any control was tested.

If you’re an engineer at a company that relies on a compliance vendor, this should bother you — not just ethically, but architecturally.

The separation-of-concerns problem

In software engineering, we understand that the component producing data should not also be the component validating it. You don’t let a service write its own health checks and also be the only thing reading them.

Compliance frameworks have the same requirement. AICPA AT-C Section 205 mandates that the entity helping you implement controls cannot also produce the audit conclusions about those controls. This isn’t bureaucratic overhead. It’s the same separation of concerns we apply to every distributed system.

The platform in question broke this fundamental principle. It generated evidence, wrote the audit conclusions, and routed everything through audit firms that were essentially shell entities. The auditor and the implementer were in the same system.

What real compliance evidence looks like

If your compliance tool is doing its job, the evidence it produces should be traceable. Not template text that a human clicked “Accept” on, but actual artifacts pulled from your infrastructure:

  • Cloud configuration snapshots from AWS, Azure, or GCP via API integration
  • Access control logs pulled from your identity provider
  • Code review and deployment evidence from your CI/CD pipeline
  • Encryption-at-rest and in-transit configurations verified against live infrastructure
  • Incident response records tied to your actual ticketing system

This is why we built Cyberbase the way we did. Our platform connects directly to your infrastructure and pulls evidence from your live environment. When it says a control is in place, it’s because an integration verified it — not because someone populated a template.

The trust center as a source of truth

Your trust page is increasingly the first thing a prospective customer’s security team checks before they engage with sales. If the claims on that page don’t correspond to implemented, tested, verified controls, you have a liability problem.

We created Cyberbase’s Trust Center to reflect your real security posture. It surfaces the controls you’ve actually implemented and keeps them synchronized with your environment. YSecurity’s consultants and virtual CISOs provide the expert human layer that ensures those controls are designed correctly in the first place.

Five questions for your next vendor review

  1. Can you trace every piece of evidence back to a real event, configuration, or action in your environment?
  2. Does the platform that generates evidence also produce or influence the audit conclusions?
  3. Are the integrations reading from your actual infrastructure, or just from a configuration form?
  4. Is the audit firm performing your examination genuinely independent?
  5. Does your trust page reflect verified controls, or aspirational checkboxes?

The only compliance that matters is the kind that holds up when someone actually checks.

Originally published at https://www.cyberbase.ai/blog/the-compliance-industry-has-a-trust-problem-here-s-how-we-fix-it
Cyberbase is an AI-powered compliance platform. YSecurity is a cybersecurity services company. Together: compliance built on substance.

Redis INCR: O comando atômico que você deveria conhecer

Em sistemas distribuídos, contar algo corretamente é mais difícil do que parece. Dois processos lendo e atualizando o mesmo valor podem facilmente gerar race conditions e inconsistências.

É exatamente aqui que o comando INCR do Redis brilha.

O INCR resolve 3 problemas clássicos:

  • contadores distribuídos
  • rate limiting
  • geração de IDs

Vamos entender por que esse comando aparentemente simples é tão poderoso.

O que é o comando INCR?

O INCR incrementa o valor numérico armazenado em uma chave por 1. Se a chave não existir, ela é criada com valor 0 antes do incremento, resultando em 1.

> SET contador 10
OK
> INCR contador
(integer) 11
> INCR contador
(integer) 12

Se a chave não existe:

> INCR novo_contador
(integer) 1

A família completa de comandos de incremento inclui:

Comando Descrição
INCR Incrementa por 1
INCRBY Incrementa por um valor inteiro específico
INCRBYFLOAT Incrementa por um valor decimal
DECR Decrementa por 1
DECRBY Decrementa por um valor inteiro específico

Por que o INCR é especial?

A característica mais importante do INCR é sua atomicidade. Em sistemas distribuídos, onde múltiplas instâncias da aplicação podem tentar modificar o mesmo valor simultaneamente, a atomicidade garante que cada operação seja executada de forma isolada.

A atomicidade do INCR é possível porque o Redis executa comandos de forma sequencial em um único thread. Isso significa que não existe concorrência interna entre comandos: cada operação é processada por completo antes da próxima iniciar. Essa característica de single-thread para execução de comandos é o que torna operações como INCR naturalmente seguras em ambientes concorrentes.

Considere o cenário clássico de race condition:

Tempo    Processo A          Processo B          Valor Real
─────────────────────────────────────────────────────────────
T1       Lê valor: 10                            10
T2                           Lê valor: 10        10
T3       Calcula: 10 + 1                         10
T4                           Calcula: 10 + 1     10
T5       Escreve: 11                             11
T6                           Escreve: 11         11  ← Perdemos um incremento!

Com INCR, o Redis garante que isso não acontece. A operação de leitura-incremento-escrita é executada como uma única unidade atômica.

Casos de Uso Práticos

1. Contadores de visualização

Um dos casos mais comuns é contar visualizações de páginas ou recursos:

public class ViewCounterService
{
    private readonly IDatabase _redis;
    private readonly TimeSpan _cacheExpiry = TimeSpan.FromHours(24);

    public ViewCounterService(IConnectionMultiplexer connection)
    {
        _redis = connection.GetDatabase();
    }

    public async Task<long> IncrementViewCountAsync(string resourceId)
    {
        var key = $"views:{resourceId}";
        var count = await _redis.StringIncrementAsync(key);

        // Define TTL apenas na primeira visualização
        if (count == 1)
        {
            await _redis.KeyExpireAsync(key, _cacheExpiry);
        }

        return count;
    }

    public async Task<long> GetViewCountAsync(string resourceId)
    {
        var key = $"views:{resourceId}";
        var value = await _redis.StringGetAsync(key);
        return value.HasValue ? (long)value : 0;
    }
}

2. Rate Limiting com Fixed Window

O rate limiting é essencial para proteger APIs contra abusos. O INCR combinado com TTL cria um rate limiter baseado em fixed window, simples e eficiente:

public class RateLimiter
{
    private readonly IDatabase _redis;

    public RateLimiter(IConnectionMultiplexer connection)
    {
        _redis = connection.GetDatabase();
    }

    public async Task<RateLimitResult> CheckRateLimitAsync(
        string clientId, 
        int maxRequests, 
        TimeSpan window)
    {
        var key = $"ratelimit:{clientId}:{DateTime.UtcNow.Ticks / window.Ticks}";

        var count = await _redis.StringIncrementAsync(key);

        if (count == 1)
        {
            await _redis.KeyExpireAsync(key, window);
        }

        return new RateLimitResult
        {
            IsAllowed = count <= maxRequests,
            CurrentCount = count,
            Limit = maxRequests,
            RetryAfter = count > maxRequests 
                ? await _redis.KeyTimeToLiveAsync(key) 
                : null
        };
    }
}

public record RateLimitResult
{
    public bool IsAllowed { get; init; }
    public long CurrentCount { get; init; }
    public int Limit { get; init; }
    public TimeSpan? RetryAfter { get; init; }
}

Nota: Essa abordagem usa fixed window counter, onde cada janela de tempo tem seu próprio contador. Para cenários que exigem sliding window real, considere usar Sorted Sets com ZADD/ZRANGEBYSCORE ou um algoritmo de token bucket. Além disso, vale observar que o padrão INCR seguido de EXPIRE pode sofrer uma race condition sutil: outro processo pode incrementar a chave entre o INCR e o EXPIRE. Para maior robustez, você pode encapsular ambos em um script Lua, garantindo a execução atômica de INCR + EXPIRE.

Uso em um middleware ASP.NET Core:

public class RateLimitingMiddleware
{
    private readonly RequestDelegate _next;
    private readonly RateLimiter _rateLimiter;

    public RateLimitingMiddleware(RequestDelegate next, RateLimiter rateLimiter)
    {
        _next = next;
        _rateLimiter = rateLimiter;
    }

    public async Task InvokeAsync(HttpContext context)
    {
        var clientId = context.Connection.RemoteIpAddress?.ToString() ?? "unknown";
        var result = await _rateLimiter.CheckRateLimitAsync(
            clientId, 
            maxRequests: 100, 
            window: TimeSpan.FromMinutes(1));

        context.Response.Headers["X-RateLimit-Limit"] = result.Limit.ToString();
        context.Response.Headers["X-RateLimit-Remaining"] = 
            Math.Max(0, result.Limit - result.CurrentCount).ToString();

        if (!result.IsAllowed)
        {
            context.Response.StatusCode = StatusCodes.Status429TooManyRequests;
            if (result.RetryAfter.HasValue)
            {
                context.Response.Headers["Retry-After"] = 
                    ((int)result.RetryAfter.Value.TotalSeconds).ToString();
            }
            return;
        }

        await _next(context);
    }
}

3. Geração de IDs sequenciais

Quando você precisa de IDs sequenciais em um sistema distribuído:

public class SequentialIdGenerator
{
    private readonly IDatabase _redis;
    private readonly string _prefix;

    public SequentialIdGenerator(IConnectionMultiplexer connection, string prefix = "id")
    {
        _redis = connection.GetDatabase();
        _prefix = prefix;
    }

    public async Task<long> GenerateIdAsync(string entity)
    {
        var key = $"{_prefix}:{entity}:sequence";
        return await _redis.StringIncrementAsync(key);
    }

    public async Task<string> GenerateFormattedIdAsync(string entity, string format = "{0}-{1:D8}")
    {
        var id = await GenerateIdAsync(entity);
        return string.Format(format, entity.ToUpper(), id);
    }
}

// Uso
var generator = new SequentialIdGenerator(connection);
var orderId = await generator.GenerateFormattedIdAsync("order"); 
// Resultado: "ORDER-00000001"

4. Contadores de sessões ativas

Monitorar quantos usuários estão ativos em tempo real:

public class ActiveSessionTracker
{
    private readonly IDatabase _redis;
    private const string ActiveSessionsKey = "sessions:active:count";
    private const string SessionPrefix = "session:";

    public ActiveSessionTracker(IConnectionMultiplexer connection)
    {
        _redis = connection.GetDatabase();
    }

    public async Task<string> StartSessionAsync(string userId)
    {
        var sessionId = Guid.NewGuid().ToString("N");
        var sessionKey = $"{SessionPrefix}{sessionId}";

        var transaction = _redis.CreateTransaction();

        _ = transaction.StringSetAsync(sessionKey, userId, TimeSpan.FromMinutes(30));
        _ = transaction.StringIncrementAsync(ActiveSessionsKey);

        await transaction.ExecuteAsync();

        return sessionId;
    }

    public async Task EndSessionAsync(string sessionId)
    {
        var sessionKey = $"{SessionPrefix}{sessionId}";

        var existed = await _redis.KeyDeleteAsync(sessionKey);

        if (existed)
        {
            await _redis.StringDecrementAsync(ActiveSessionsKey);
        }
    }

    public async Task<long> GetActiveSessionCountAsync()
    {
        var value = await _redis.StringGetAsync(ActiveSessionsKey);
        return value.HasValue ? (long)value : 0;
    }
}

Nota: Nessa abordagem, se uma sessão expirar automaticamente pelo TTL, o contador ActiveSessionsKey não será decrementado, o que pode gerar drift ao longo do tempo. Para maior robustez em produção, considere usar um Sorted Set (ZSET) com timestamps para rastrear sessões ativas, permitindo que você calcule o total real a qualquer momento com ZRANGEBYSCORE, ou implemente um processo periódico de reconciliação do contador.

5. Métricas por intervalo de tempo

Coletar métricas agregadas por minuto/hora/dia:

public class MetricsCollector
{
    private readonly IDatabase _redis;

    public MetricsCollector(IConnectionMultiplexer connection)
    {
        _redis = connection.GetDatabase();
    }

    public async Task RecordMetricAsync(string metricName, long value = 1)
    {
        var now = DateTime.UtcNow;

        var keys = new[]
        {
            $"metrics:{metricName}:minute:{now:yyyyMMddHHmm}",
            $"metrics:{metricName}:hour:{now:yyyyMMddHH}",
            $"metrics:{metricName}:day:{now:yyyyMMdd}"
        };

        var expiries = new[]
        {
            TimeSpan.FromHours(2),
            TimeSpan.FromDays(2),
            TimeSpan.FromDays(60)
        };

        var batch = _redis.CreateBatch();

        for (int i = 0; i < keys.Length; i++)
        {
            var key = keys[i];
            var expiry = expiries[i];

            _ = batch.StringIncrementAsync(key, value);
            _ = batch.KeyExpireAsync(key, expiry, ExpireWhen.HasNoExpiry);
        }

        batch.Execute();
    }

    public async Task<Dictionary<string, long>> GetHourlyMetricsAsync(
        string metricName, 
        DateTime date)
    {
        var results = new Dictionary<string, long>();

        for (int hour = 0; hour < 24; hour++)
        {
            var key = $"metrics:{metricName}:hour:{date:yyyyMMdd}{hour:D2}";
            var value = await _redis.StringGetAsync(key);
            results[$"{hour:D2}:00"] = value.HasValue ? (long)value : 0;
        }

        return results;
    }
}

Sistemas Distribuídos com múltiplos pods

Em ambientes Kubernetes ou qualquer arquitetura com múltiplas instâncias, o Redis INCR se torna ainda mais valioso. Cada pod opera de forma independente, sem conhecimento dos outros, mas todos precisam coordenar acesso a recursos compartilhados.

O Problema do estado compartilhado

Imagine 5 pods processando requisições simultaneamente. Sem coordenação central, cada pod manteria seu próprio contador local:

Pod 1: contador local = 47
Pod 2: contador local = 52
Pod 3: contador local = 38
Pod 4: contador local = 61
Pod 5: contador local = 44
                         ───────
Total real de requisições: 242
Mas cada pod "acha" que processou apenas seu número local

Com Redis como ponto central de coordenação, todos os pods compartilham a mesma visão do estado.

E em Redis Cluster?

Em arquiteturas maiores que utilizam Redis Cluster, o INCR funciona normalmente desde que as chaves relacionadas estejam no mesmo hash slot. O Redis Cluster distribui chaves entre nós usando CRC16, então se você precisa que múltiplas chaves sejam processadas no mesmo nó, utilize hash tags. Por exemplo, {rate}:user:123 e {rate}:user:456 serão direcionadas para o mesmo slot por compartilharem a tag {rate}. Isso é especialmente relevante quando você usa transactions ou scripts Lua que operam sobre múltiplas chaves.

Considerações de Performance

O INCR é extremamente rápido, com complexidade O(1). No entanto, existem algumas práticas para otimizar ainda mais:

Batch de operações: Quando você precisa incrementar múltiplos contadores, use batching:

public async Task IncrementMultipleAsync(Dictionary<string, long> counters)
{
    var batch = _redis.CreateBatch();
    var tasks = new List<Task<long>>();

    foreach (var (key, increment) in counters)
    {
        tasks.Add(batch.StringIncrementAsync(key, increment));
    }

    batch.Execute();
    await Task.WhenAll(tasks);
}

Pipeline: Para operações que não dependem do resultado imediato:

public void RecordEventsFireAndForget(IEnumerable<string> eventKeys)
{
    foreach (var key in eventKeys)
    {
        _redis.StringIncrement(key, flags: CommandFlags.FireAndForget);
    }
}

Armadilhas Comuns

1. Não definir TTL: Contadores sem expiração podem acumular indefinidamente. Sempre considere se o contador precisa de um TTL.

2. Usar GET seguido de SET: Nunca faça isso para incrementar valores. Use sempre INCR:

// ERRADO: Race condition!
var value = await _redis.StringGetAsync(key);
await _redis.StringSetAsync(key, (long)value + 1);

// CORRETO: Atômico
await _redis.StringIncrementAsync(key);

3. Ignorar overflow: O Redis armazena inteiros como strings de até 64 bits signed. Em cenários extremos, considere verificar limites.

4. Não tratar valores não numéricos: Se uma chave contiver um valor não numérico, INCR retornará erro. Valide ou use chaves dedicadas.

Conclusão

O INCR do Redis é uma ferramenta fundamental para construir sistemas distribuídos robustos. Sua atomicidade elimina race conditions, sua velocidade permite uso em cenários de alta performance, e sua simplicidade torna a implementação direta.

Os casos de uso vão desde contadores simples até rate limiters sofisticados e sistemas de métricas em tempo real. O segredo está em entender que operações atômicas simples, quando combinadas corretamente, resolvem problemas complexos de concorrência.

O poder do Redis muitas vezes não está em comandos complexos, mas em operações simples que são atômicas, rápidas e distribuídas.

Na próxima vez que você precisar de um contador distribuído, pense no INCR antes de partir para soluções mais complexas. Frequentemente, a resposta mais simples é também a mais elegante.

I Built a Monitoring Tool Because Uptime Checks Kept Lying to Me

If you deploy sites to Netlify, Vercel, Cloudflare Pages or pretty much any modern platform — you’ve probably set up some kind of uptime monitoring. Ping every minute, get an alert if the server doesn’t respond. Pretty standard stuff.

I had the same setup across all my sites. And for a long time, I thought I was covered.

I wasn’t.

The Problem

A few months back I pushed an update to one of my Nuxt apps on Netlify. Build passed, deploy preview looked fine, dashboard showed green. I moved on.

Turns out the site was broken for hours. Not down — the server was responding just fine. 200 OK on every request. But the JavaScript bundle the page needed wasn’t loading, so the entire app was a blank page.

Here’s what happened: the new deploy generated fresh hashed bundles. main.c8d13.js replaced main.a4f2c.js. But some CDN edge nodes were still serving the old HTML, which referenced the old filename. Browser tries to fetch main.a4f2c.js, gets a 404, and nothing renders.

My uptime monitor? Green the entire time. Because the HTML document loaded. 200 OK. Job done, as far as it was concerned.

It Keeps Happening

Once I started paying attention, I found this happens a lot more than you’d expect:

MIME type mismatches — Your JS file gets served as text/html by the CDN. Browser silently refuses to execute it. No console error you’d notice unless you’re specifically looking. I had this on one of my sites behind Cloudflare for days without knowing.

Redirect chains that loop — CDN redirect + origin redirect + app redirect that conflict with each other. Browser hits the hop limit and gives up. Uptime tool sees the first 301 and moves on.

DNS still pointing at old infrastructure — After a migration, a subdomain resolves to the old origin. It responds with stale content from months ago. Technically “up.” Practically useless.

All return 200. All invisible to standard monitoring.

Why I Built Sitewatch

I looked around for tools that caught this stuff. Most uptime monitors check if the server responds — and that’s it. Some offer headless browser checks with Puppeteer, but they’re slow, expensive, and fragile at any real scale. Not great when you’re watching a bunch of sites.

What I needed was something in between. Goes deeper than a status code check, doesn’t require a full browser session. Catches the broken deploy, the MIME type issue, the redirect loop — automatically.

So I built Sitewatch.

What It Does

Instead of just checking if your server responds, Sitewatch verifies whether your site actually works:

Asset verification — It fetches your page, parses the HTML, finds your JS and CSS bundle references, and checks each one. Correct status code? Correct MIME type? Actually loadable? If your HTML references a script that 404s or gets served as text/html, you get alerted.

Full redirect chain resolution — Follows redirects all the way to the final destination. Catches loops, unexpected landings, and chains that time out.

Content fingerprinting — Generates hashes of your page content and tracks them over time. If your homepage suddenly returns completely different content (stale cache, CDN error page that returns 200), the fingerprint shift triggers an alert.

Multi-region checks — CDN failures are often edge-specific. Your site works from Europe but serves broken assets in Asia. Sitewatch checks from multiple locations.

Confirmation before alerting — Uses a retry model before firing alerts. No 3am wake-ups because of a transient CDN blip.

It also classifies the root cause — infrastructure, deploy artifact, DNS, CDN config — so you know where to look instead of just knowing “something broke.”

Some Technical Decisions

A few choices that might be relevant if you’ve thought about building something similar:

No headless browser. It’s tempting because it’s “real” rendering, but it doesn’t scale well. Sitewatch parses HTML and makes targeted follow-up requests for critical assets. Gets you the meaningful signal without the overhead.

Stack detection. Different frameworks break differently. A Nuxt app has different failure patterns than a WordPress site or a Rails app behind Nginx. Sitewatch detects the tech stack from response headers and adjusts what it checks for.

Alert deduplication. If the same issue persists across checks, you don’t want repeated alerts. Content fingerprints with a cooldown window — you get notified when something breaks and again when it’s resolved, not every 5 minutes in between.

Try It

If you’re running sites on modern deployment platforms — especially if you’re managing multiple — this is a blind spot worth covering.

There’s a free tier for one site. Takes about 30 seconds to set up: getsitewatch.com

That about wraps it up! If you found this useful, I’d love to know — leave a comment or connect with me on Twitter | LinkedIn or visit my website.

Integrate Custom Tools with OpenAI Function Calling

Large Language Models (LLMs) are incredibly powerful for generating text, summarizing information, and answering questions. However, their knowledge is typically limited to their training data. To perform real-world actions like checking the weather, sending emails, or querying a database, LLMs need to interact with external tools. This is where “function calling” or “tool use” becomes essential. It’s the mechanism that allows an LLM to not just generate text, but to intelligently decide when and how to invoke external functions, transforming it from a text generator into a capable agent.

In this guide, we’ll dive into OpenAI’s Function Calling feature, a robust way to connect your LLM applications with custom tools and APIs. We’ll explore the core concepts, walk through practical Python code examples, and discuss common pitfalls to help you build more dynamic and powerful AI-driven applications.

Understanding OpenAI Function Calling

OpenAI Function Calling empowers models like gpt-4o to detect when a user’s prompt might require an external function call, generate the necessary arguments for that call, and present this structured information back to your application. Your application then executes the function and feeds the result back to the LLM, allowing it to complete the user’s request with up-to-date, real-world data or perform specific actions.

This isn’t the LLM executing code directly. Instead, it acts as a smart orchestrator:

  1. You describe your tools: You provide the LLM with a JSON Schema definition of functions it can “call” (their names, descriptions, and expected parameters).
  2. User prompt: A user asks a question or makes a request.
  3. LLM decides: The LLM analyzes the prompt, compares it against the available tool descriptions, and decides if a tool is needed.
  4. LLM generates tool call: If a tool is needed, the LLM generates a structured JSON object containing the tool’s name and the arguments it inferred from the user’s prompt.
  5. Your application executes: Your code receives this JSON, calls your actual Python function (or external API) with the provided arguments.
  6. Tool output is returned: The result of your function call is then sent back to the LLM.
  7. LLM synthesizes response: The LLM uses this real-world data to formulate a natural language response to the user.

Let’s illustrate this with a common example: fetching current weather information.

Step 1: Describing Your Tools to the LLM

The first crucial step is to define the capabilities of your external tools in a way the LLM can understand. OpenAI uses a JSON Schema-like structure for this. Each tool needs a descriptive name, a clear description (this is key for the LLM’s understanding), and a parameters object detailing the inputs it expects.

Consider a simple get_current_weather function that takes a location and an optional unit.

tools = [
    {
        "type": "function",
        "function": {
            "name": "get_current_weather",
            "description": "Get the current weather in a given location",
            "parameters": {
                "type": "object",
                "properties": {
                    "location": {
                        "type": "string",
                        "description": "The city and state, e.g. San Francisco, CA",
                    },
                    "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
                },
                "required": ["location"],
            },
        },
    }
]

This Python list defines a single tool. The type is specified as “function”, indicating it’s a callable operation. Within the function object, we provide a name (get_current_weather) that your actual code will use, and a description that the LLM reads to understand the tool’s purpose. The parameters field, written in JSON Schema format, details the expected inputs: location as a required string and unit as an optional string that must be either “celsius” or “fahrenheit”.

Step 2: Triggering a Function Call from the LLM

Now that our tool is defined, we can pass it to the OpenAI API when making a chat completion request. The tool_choice parameter gives you control over whether the model should use a tool, always use a specific tool, or never use one. Setting it to "auto" (the default) lets the LLM decide.

from openai import OpenAI
import json # Used for parsing arguments later

client = OpenAI()

messages = [{"role": "user", "content": "What's the weather like in Boston?"}]

response = client.chat.completions.create(
    model="gpt-4o",
    messages=messages,
    tools=tools, # Our defined tools
    tool_choice="auto", # Let the model decide if a tool is needed
)
response_message = response.choices[0].message

# Check if the model decided to call a tool
if response_message.tool_calls:
    tool_call = response_message.tool_calls[0] # Assuming one tool call for simplicity
    print(f"LLM wants to call a tool: {tool_call.function.name}")
    print(f"Arguments: {tool_call.function.arguments}")
else:
    print("LLM responded directly:", response_message.content)

In this snippet, we initialize the OpenAI client and prepare a list of messages containing the user’s query. The core of this step is the call to client.chat.completions.create. We pass our messages, specify a model (gpt-4o is good for function calling), and crucially, include our tools definition. tool_choice="auto" instructs the model to automatically determine if a function call is appropriate. The response_message then holds the model’s decision; if response_message.tool_calls is populated, it means the LLM has generated a call to one of our defined tools, providing the function name and its parsed arguments as a JSON string.

Step 3: Executing the Tool and Sending Results Back

Receiving a tool_calls object means your application now needs to execute the identified function. This involves parsing the arguments provided by the LLM, calling your actual local function, and then sending the result back to the LLM to complete the conversation.

# Mock tool function (in a real application, this would query a weather API, database, etc.)
def get_current_weather(location, unit="fahrenheit"):
    # Simplified logic for demonstration
    if "boston" in location.lower():
        return json.dumps({"location": location, "temperature": "65", "unit": unit, "forecast": "partly cloudy"})
    elif "new york" in location.lower():
        return json.dumps({"location": location, "temperature": "72", "unit": unit, "forecast": "sunny"})
    return json.dumps({"location": location, "temperature": "unknown", "unit": unit, "forecast": "unavailable"})

# --- Continuation from Step 2, assuming response_message.tool_calls exists ---
if response_message.tool_calls:
    tool_call = response_message.tool_calls[0]
    function_name = tool_call.function.name
    function_args = json.loads(tool_call.function.arguments) # Parse the JSON string into a Python dict

    # Execute the function based on its name
    if function_name == "get_current_weather":
        function_response = get_current_weather(**function_args) # Unpack arguments with **

        # Append both the LLM's tool call and the tool's output to the messages history
        messages.append(response_message) # The model's request to call the tool
        messages.append(
            {
                "tool_call_id": tool_call.id,
                "role": "tool",
                "name": function_name,
                "content": function_response, # The actual result from our function
            }
        )

        # Send the updated messages back to the LLM to get a final, human-readable response
        second_response = client.chat.completions.create(
            model="gpt-4o",
            messages=messages,
        )
        print("Final LLM response:", second_response.choices[0].message.content)
    else:
        print(f"Error: Unknown function requested: {function_name}")
else:
    # This case would be handled by the direct response logic in Step 2
    pass

This expanded block handles the actual execution. We define a placeholder get_current_weather function that simulates an API call. After receiving the LLM’s tool_call, we parse its arguments (which are a JSON string) into a Python dictionary using json.loads(). We then dynamically call our get_current_weather function, unpacking the arguments using **function_args. Crucially, we append two new messages to our messages history: first, the response_message from the LLM (which contained the tool_calls), and second, a new message with role="tool". This tool message includes the tool_call_id (linking it back to the original call), the function name, and the content which is the actual output from our get_current_weather function. Finally, we make a second API call to client.chat.completions.create with this updated message history, allowing the LLM to synthesize a natural language response based on the tool’s output.

Common Mistakes and Gotchas

Working with Function Calling, while powerful, can introduce specific challenges:

  • Incorrect Schema Definition: The description of your tool and its parameters are vital. If they are vague or misleading, the LLM might struggle to correctly identify when to call your tool or how to map user input to its arguments. Ensure required parameters are correctly marked.
  • Forgetting to Send Tool Output: A common oversight is to call the tool but not feed its results back into the LLM’s messages history. Without the role="tool" message, the LLM won’t know the outcome of its requested action and cannot complete the user’s request contextually.
  • Infinite Loops: In more complex scenarios, an LLM might continuously request the same tool if the tool’s output doesn’t provide enough information or resolve the initial query. Ensure your tool outputs are comprehensive, and consider adding retry limits or human intervention points.
  • Security Implications: Since your application executes the functions, be extremely cautious about what functions you expose and how you handle their arguments. Malicious prompts could potentially lead to unexpected function calls or data exposure if not properly validated. Always sanitize and validate inputs before executing actions.
  • Over-reliance on tool_choice="auto": While convenient, auto might not always pick the desired tool or might pick one when a direct response is better. For critical flows, consider explicit tool_choice values, e.g., {"type": "function", "function": {"name": "my_specific_tool"}}, or none to force a direct textual response.

Key Takeaways

OpenAI Function Calling fundamentally shifts how we interact with LLMs, moving beyond simple text generation to building truly intelligent, agentic systems. By providing a clear contract for your external tools through JSON Schema, you enable LLMs to:

  • Perform real-world actions: Interact with APIs, databases, or local services.
  • Access up-to-date information: Overcome knowledge cutoffs by fetching current data.
  • Improve user experience: Provide more accurate and actionable responses.

This pattern is a cornerstone for building sophisticated AI assistants, task automation agents, and advanced chatbots that can understand user intent and execute complex workflows.

Conclusion: Build Smarter, Not Harder

Integrating custom tools with LLMs via function calling unlocks a new dimension of possibilities for developers. It’s a critical pattern for extending the capabilities of models beyond their inherent knowledge, turning them into versatile problem-solvers. The ability to dynamically connect LLMs to your existing backend services means you can create applications that are not just conversational, but genuinely functional and integrated.

Start experimenting with OpenAI Function Calling in your projects today. Define a simple tool, feed it to the model, and observe how your LLM begins to intelligently orchestrate actions. The future of AI applications lies in these powerful integrations.

AMD Ryzen 9 9950X3D2 Dual Edition resmi olarak tanıtıldı

AMD Ryzen 9 9950X3D2 Dual Edition resmi olarak tanıtıldı

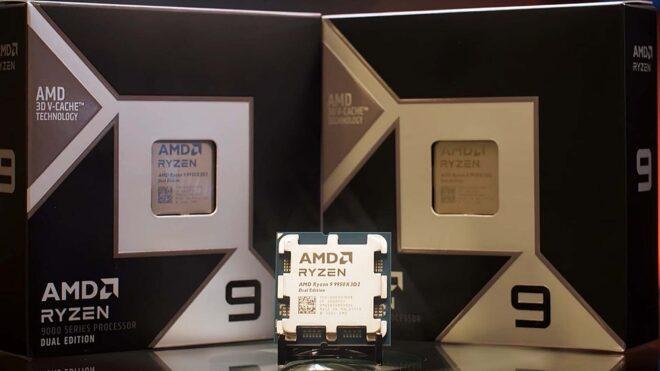
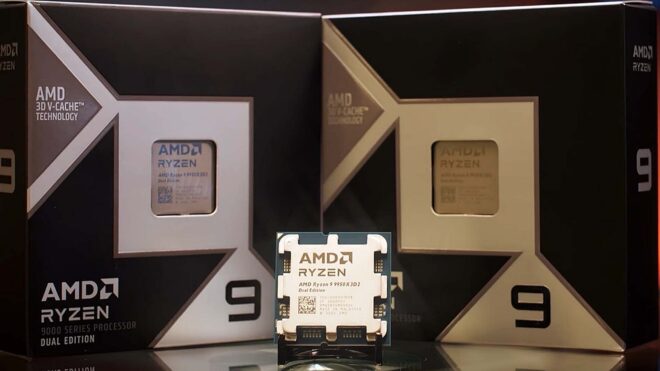
AMD Ryzen 9 9950X3D2 Dual Edition resmi olarak tanıtıldıAMD bugün uzun zamandır gündemde olan tam 192 MB L3 önbelleğe sahip (toplamda 208 MB) Ryzen 9 9950X3D2 Dual Edition işlemci modelini resmi olarak tanıttı. Ryzen 9 9950X3D’nin üzerine konumlandırılan 16 çekirdekli (Zen5) yeni işlemci, 5,6 GHz maksimum çekirdek hızına ve 200W TDP’ye sahip. Henüz fiyatı belli olmayan işlemci, ilk kez kullanılan çift 3D V-Cache aracılığıyla yalnızca oyun değil, diğer alanlarda da yüksek performans vadediyor. 9950X3D2 Dual Edition, resmi testlere göre V-Ray ve Blender’da 170W’lık Ryzen 9 9950X3D’ye kıyasla yüzde 7, Unreal Engine derlemelerinde ise yüzde 8 daha yüksek performans ortaya koyuyor. Kısıtlı bir kitleye hitap eden yeni işlemci, daha çok büyük yazılım ve oyun projeleri ile yapay zeka projeleri için uygun görünüyor.

AMD Ryzen 9 9950X3D2 Dual Edition resmi olarak tanıtıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.