The Complete Docker Read List: Q1 2026 Edition

Black Forest Shadow book cover

2026 has been phenomenal in the number of books published on Docker or by Docker Captains so far. So, I decided to compile the books published in the first quarter of 2026 into an article for more people to discover them.

You can also read the article here, which looks slightly better.

1️⃣ Black Forest Shadow: A Dark Fantasy Guide to Docker and Kubernetes Security

Author: Mohammad-Ali A’râbi (Docker Captain)

Black Forest Shadow book cover

If you’ve ever thought learning about Kubernetes and container hardening was a bit dry, Mohammad-Ali A’râbi is here to prove you wrong. Black Forest Shadow is a highly creative, dark fantasy guide to Docker and Kubernetes security.

—Claude

  • What it’s about: The book weaves complex concepts like runtime security, SBOM generation, and container hardening into an exciting narrative set in the mystical Black Forest of 1865.
  • Why you should read it: It transforms standard cybersecurity challenges—like tracking down CVEs and preventing lateral movement—into an immersive, story-driven adventure. It’s ideal for developers and security engineers seeking a distinctive, memorable approach to DevSecOps.
  • Where to get it:

2️⃣ The Rust Programming Handbook: An End-to-end Guide to Mastering Rust Fundamentals

Author: Francesco Ciulla (Docker Captain)

The Rust Programming Handbook book cover

Rust is the new C, and it’s been on my list for 5 years now. Now, finally, I know which book to read to learn it. Written by my dear friend and fellow Docker Captain, Francesco Ciulla, who has been teaching Rust for many years now.

  • What it’s about: This handbook takes you from foundational syntax to advanced features like memory safety and concurrency models. Crucially for this list, it includes dedicated, hands-on sections on Dockerizing and deploying your Rust applications!
  • Why you should read it: It bridges the gap between beginner tutorials and production-ready coding for low-level system components or high-performance web services.
  • Where to get it:

3️⃣ Docker for Front-end Developers (Featuring React.js)

Author: Kristiyan Velkov (Docker Captain)

Docker for Front-end Developers book cover

Front-end developers, rejoice! As a backend engineer, it has always been hard for me to onboard frontend people to Docker, because I spoke Klingon for them. My dear friend, Docker Captain Kristiyan Velkov, has done an awesome job writing a containerization guide specifically tailored to how front-end engineers think, build, and ship. I should say, it also looks good.

  • What it’s about: Moving past backend-centric explanations, this book walks you through containerizing real-world applications (with a heavy focus on React). You’ll learn how to write clean Dockerfiles, configure NGINX properly, implement multi-stage builds, and handle caching securely.
  • Why you should read it: It’s a purely practical, visually-driven guide that teaches you how to take full ownership of your environments without getting bogged down in abstract backend theory.
  • Where to get it:

4️⃣ The Ultimate Docker Container Book (Fourth Edition)

Author: Dr. Gabriel N. Schenker

The Ultimate Docker Container Book cover

Hitting shelves on March 31, 2026, this absolute heavyweight of a book clocks in at over 750 pages and leaves no stone unturned. Jeez, I need an extra bookshelf just for this book’s weight.

  • What it’s about: It takes you from basic container concepts all the way to running production-grade platforms. The fourth edition places a massive new emphasis on security, enterprise governance, compliance, and AI-driven automation patterns.
  • Why you should read it: It is designed for system administrators, DevOps engineers, and architects who need to build and scale secure, future-ready container platforms across major cloud providers.
  • Where to get it:

5️⃣ Docker: Das Praxisbuch für Entwickler und DevOps-Teams (5th Edition)

Authors: Bernd Öggl & Michael Kofler

Docker Das Praxisbuch book cover

For the German-speaking tech community, the definitive Docker reference guide gets a major Q1 2026 update.

  • What it’s about: A comprehensive, 580+ page practical guide covering everything from setting up Docker to CI/CD pipelines, GitLab integration, Swarm, and Kubernetes orchestration.
  • Why you should read it: It’s an excellent, hands-on resource that balances basic principles with advanced, modern use cases like modernizing legacy applications and working with specialized databases.
  • Where to get it:

Honorable Mentions from 2025

Well, as I was researching Docker books published in 2026, I came across a video by Bret Fisher, interviewing the author of an interesting book. So, I created this section for the honorable mentions:

Learn Docker in a Month of Lunches (Second Edition)

Author: Elton Stoneman

Learn Docker in a Month of Lunches book cover

Published in 2025, this is the much-anticipated update to one of the most beloved Docker books on the market.

  • What it’s about: A complete refresh of the classic guide. It breaks down Docker fundamentals into digestible, daily lessons. This edition covers multi-platform builds, the latest cloud container services, and navigating the modern Kubernetes ecosystem.
  • Why you should read it: If you are a beginner looking for a structured, manageable way to learn—or an experienced dev needing to catch up on years of ecosystem changes—this is the gold standard.
  • Where to get it:

Getting Started with Docker (2025 Edition)

Author: Nigel Poulton (Docker Captain)

Getting Started with Docker book cover

Nigel Poulton’s fast-paced introduction to Docker received a significant 2025 update, adding a dedicated chapter on running local LLMs with Docker Model Runner — including building a multi-container chatbot app.

  • What it’s about: A streamlined, hands-on guide to container fundamentals, Docker Compose, and microservices — now with a practical AI chapter for developers who want to run models locally.
  • Why you should read it: It’s the quickest path from zero to productive with Docker, and the new AI content makes it uniquely relevant for 2025 and beyond.
  • Where to get it:

Docker and Kubernetes Security

Author: Mohammad-Ali A’râbi (Docker Captain)

Docker and Kubernetes Security book cover

A DevOps Dozen 2025 finalist for Best DevOps Book of the Year, this practical guide covers container security across the full development lifecycle—from build to production.

  • What it’s about: Ten chapters spanning supply chain security (SBOMs, OCI 1.1 attestations, vulnerability scanning with Docker Scout, Trivy, and Snyk) and runtime protection with Falco, RBAC, and Kubernetes pod security.
  • Why you should read it: It is the most comprehensive hands-on resource available for teams serious about securing their container platforms end-to-end.
  • Where to get it:

Conclusion

The Docker and Kubernetes ecosystem has never had a stronger reading list, to be humble! From dark fantasy security guides to hands-on Rust handbooks and front-end containerization primers, Q1 2026 proves that the community is producing more creative, accessible, and production-focused material than ever before.

Stay tuned as more books are coming in Q2. I’m involved in reviewing one of them, so I’m excited for the quarter to come.

Have a book that should be on this list? Leave a comment.

Understanding Events in JavaScript (Beginner Friendly Guide)

Modern websites are interactive. When you click a button, type in a search box, or submit a form, something happens.

This behavior is possible because of JavaScript Events.

In this blog, we will learn:

  1. Introduction to Events
  2. How Events Work
  3. Common Event Types
  4. The Event Object
  5. Event Propagation
  6. Event Delegation
  7. Removing Event Listeners

Let’s start.

1. Introduction to Events

An event is an action that happens in the browser.

Events can be triggered by:

  • User actions
  • Browser actions

Examples of events

Action Event
Clicking a button click
Typing in keyboard keydown
Submitting a form submit
Moving mouse over element mouseover
Page loaded load

Example

<button id="btn">Click Me</button>
document.getElementById("btn").addEventListener("click", function(){
    alert("Button clicked!");
});

Output

When the user clicks the button, an alert message appears.

This is called interactivity.

Without events, websites would be static like a newspaper page.

2. How Events Work

JavaScript uses an event-driven model.

This means the browser waits for events and then runs code.

The process

  1. User performs an action
  2. Browser detects the event
  3. JavaScript runs the event handler

Syntax of addEventListener

element.addEventListener("event", function)

Example

<button id="btn">Click</button>
let btn = document.getElementById("btn");

btn.addEventListener("click", function(){
    console.log("Button was clicked");
});

Output

Button was clicked

This message appears in the console when the button is clicked.

3. Common Event Types

JavaScript has many event types.

1. Mouse Events
Triggered by mouse actions.

Event Description
click user clicks
dblclick double click
mouseover mouse enters element
mouseout mouse leaves element

Example

<div id="box">Hover over me</div>
let box = document.getElementById("box");

box.addEventListener("mouseover", function(){
    box.style.background = "yellow";
});

box.addEventListener("mouseout", function(){
    box.style.background = "white";
});

Output
When the mouse enters the box → yellow background
When the mouse leaves → white background

2. Keyboard Events

Triggered when keys are pressed.

Event Description
keydown key pressed
keyup key released
keypress key pressed (older event)

Example

<input type="text" id="inputBox">
let input = document.getElementById("inputBox");

input.addEventListener("keydown", function(event){
    console.log("Key pressed:", event.key);
});

Output

Typing A B C

Console shows

Key pressed: A
Key pressed: B
Key pressed: C

3. Form Events

Used when working with forms.

Event Description
submit form submitted
change value changed
input typing
focus field selected
blur field left

Example

<form id="form">
<input type="text">
<button>Submit</button>
</form>
let form = document.getElementById("form");

form.addEventListener("submit", function(event){
    event.preventDefault();
    alert("Form submitted!");
});

Output
The alert appears without refreshing the page.

4. Window / Document Events

These events happen on the browser window.

Event Description
load page fully loaded
DOMContentLoaded HTML loaded
resize window resized
scroll page scrolled

Example

window.addEventListener("scroll", function(){
    console.log("User is scrolling");
});

4. The Event Object

Whenever an event occurs, JavaScript creates an event object.

This object contains information about the event.

Example

document.addEventListener("click", function(event){
    console.log(event.target);
});

Important Properties

Property Meaning
event.target element clicked
event.type type of event
event.key key pressed
event.clientX mouse X position
event.clientY mouse Y position

Example

document.addEventListener("click", function(event){
    console.log("Clicked element:", event.target);
    console.log("Event type:", event.type);
});

Prevent Default Behaviour

Some elements have default actions.

Example:

  • Form reload
  • Link navigation

We can stop it using:

event.preventDefault()

Example

<a href="https://google.com" id="link">Go to Google</a>
document.getElementById("link").addEventListener("click", function(event){
    event.preventDefault();
    alert("Link prevented!");
});

5. Event Propagation [To Be Discussed]

When an event happens inside nested elements, it travels through the DOM.

This is called event propagation.

There are two phases:

1. Event Bubbling

Event goes from child → parent → document

Example:

<div id="parent">
<button id="child">Click</button>
</div>
document.getElementById("child").addEventListener("click", function(){
    console.log("Child clicked");
});

document.getElementById("parent").addEventListener("click", function(){
    console.log("Parent clicked");
});

Output

Child clicked
Parent clicked

Because event bubbles up.

2. Event Capturing

Event goes from parent → child

addEventListener("click", function, true)

Example

document.getElementById("parent").addEventListener("click", function(){
    console.log("Parent capturing");
}, true);

stopPropagation()

Stops the event from moving further.

document.getElementById("child").addEventListener("click", function(event){
    event.stopPropagation();
    console.log("Child only");
});

Output

Child only

Parent event will not run.

Example

document
   ↓
body
   ↓
parent
   ↓
child (clicked)
   ↑
parent
   ↑
body
   ↑
document
  • Capturing → top to bottom
  • Bubbling → bottom to top

6. Event Delegation

Instead of adding many event listeners, we can add one listener to the parent.

This technique is called event delegation.

It improves performance.

Example 1

<ul id="list">
<li>Item 1</li>
<li>Item 2</li>
<li>Item 3</li>
</ul>
document.getElementById("list").addEventListener("click", function(event){

    if(event.target.tagName === "LI"){
        console.log("You clicked:", event.target.innerText);
    }

});

Output

Clicking any item shows:(The exact element that was clicked by the user)

You clicked: Item 2

Even if new <li> is added later, it still works.

7. Removing Event Listeners

We can remove an event listener using:

removeEventListener()

But the function must be named.

Example

function sayHello(){
    console.log("Hello");
}

let btn = document.getElementById("btn");

btn.addEventListener("click", sayHello);

btn.removeEventListener("click", sayHello);

Anonymous functions cannot be removed easily.

Conclusion
JavaScript events are essential for creating interactive web applications. Understanding how events work helps developers handle user actions effectively and build dynamic user interfaces.

Prompt Injection Isn’t a Chatbot Problem Anymore

The project behind this article is pydefend on GitHub – Apache 2.0, contributions welcome.

For a while, prompt injection was mostly embarrassing. You’d get a customer service bot to say something it shouldn’t, or you’d extract the system prompt and post it on Twitter. Real issues, sure, but the consequences were bounded. The bot said a bad thing. Someone screenshotted it. Life went on.

That era is ending.

The shift isn’t a new attack technique. It’s a new target. As LLM applications move from “chat interface” to “agent with tools,” the threat model changes completely – and most of the security thinking around prompt injection hasn’t caught up.

What changes when the AI can act

Here’s the difference in concrete terms.

A chatbot that’s been successfully injected might leak its system prompt, or produce output that contradicts its guidelines. Annoying. Potentially damaging to trust. But the blast radius is limited to what it says.

An agent that’s been successfully injected can act. It has tools. Database access, file writes, API calls, the ability to send emails or make purchases or modify records. A manipulated agent isn’t saying the wrong thing – it’s doing the wrong thing, at machine speed, before any human sees what’s happening.

This is the threat model that keeps me up at night. Not the chatbot that gets tricked into writing a poem in the wrong tone. The agent that gets instructed – through a carefully crafted injection two turns into a conversation – to exfiltrate a database to an external endpoint.

And here’s what makes it worse: the attack doesn’t have to be direct.

The multi-turn problem

Most prompt injection detection focuses on individual inputs. Is this message an injection attempt? Yes or no.

That works for some attacks. The blunt ones – “ignore your previous instructions,” “you are now DAN” – are detectable in isolation because they’re structurally obvious. But the more dangerous attacks don’t look like attacks at first.

Imagine a conversation where the first message is completely benign. The second nudges the context slightly. The third establishes a false premise. By message six or seven, the agent is operating under an entirely different set of assumptions than the ones its system prompt established – and no individual message, examined alone, would have tripped a filter.

This is a multi-turn injection, and it’s specifically dangerous for agentic systems because agents are designed to maintain context across a conversation. That’s a feature. It’s also the attack surface.

When I was building Defend, I spent a long time on this. The session accumulation layer – which tracks rolling risk across a session ID rather than evaluating each message in isolation – exists because of this problem. A single suspicious message doesn’t tell you much. The shape of a conversation over time tells you a lot.

Why output-side detection matters as much as input-side

Most guardrail systems focus on the input: screen what comes in, block what looks dangerous, let the rest through. That’s necessary. It’s not sufficient.

For agentic systems, you need output-side detection too – specifically, detection that runs before a tool is called.

Here’s why. Even if every user input looks clean, the model’s internal reasoning can still be manipulated. Indirect injections – malicious content embedded in documents, web pages, or tool results that the agent retrieves and processes – never appear as user messages at all. They arrive through the agent’s context, not through the chat interface. Input screening doesn’t see them.

By the time the agent decides to call a tool, it may already be operating on compromised instructions. If the guardrail only ran on the way in, nothing catches it.

The tool_misuse module in Defend runs on the model’s output – the instruction it’s about to act on – rather than on the user’s input. Same with excessive_agency, which checks whether a proposed action falls outside the agent’s defined permission scope. The goal is to catch the manipulation before the tool fires, not after.

This feels obvious in retrospect, but I didn’t see many open-source projects handling it when I started building. Most were input-only.

The indirect injection vector

This one deserves its own section because it’s underappreciated and it’s getting worse.

An indirect injection is when the malicious instruction doesn’t come from the user – it comes from something the agent retrieved. A webpage with hidden text. A PDF with instructions embedded in white-on-white font. A customer support ticket that was written specifically to manipulate the AI processing it.

The user doesn’t have to do anything. The attack is already sitting in the data the agent is reading.

For any agent with retrieval capabilities – RAG pipelines, agents that browse the web, agents that process uploaded documents – this is live. It’s not theoretical. There are documented examples of agents being redirected mid-task by malicious content in the documents they were processing.

Defend has an indirect_injection module that takes sources as a config parameter – you tell it which content sources the agent is reading from, and it applies appropriate scrutiny to content coming from those sources rather than treating retrieved content the same as system context.

What a sensible agentic guardrail looks like

I want to be concrete, because “you should add security” is not useful advice.

For an agent with tools, the minimum viable guardrail setup is:

On input: Screen user messages for injection attempts and jailbreaks before they reach the model. This is table stakes.

On retrieved content: Treat anything the agent retrieves from external sources – documents, web pages, tool results – with more suspicion than you treat user messages. A user who submits a malicious message is an attacker you’re aware of. A document that the agent chose to read is an attack vector you might not be watching.

On output, before tool calls: Verify that the action the agent is about to take is consistent with its defined permission scope and wasn’t smuggled in through a compromised context. This is the step most projects skip.

On output, general: Check for prompt leakage (the agent revealing its system prompt), malicious URLs being inserted into responses, and PII ending up in places it shouldn’t. Agents that write to external systems can exfiltrate data in subtle ways.

None of this eliminates the risk. A sufficiently sophisticated attack against a sufficiently capable agent is a hard problem. But most real-world attacks aren’t sophisticated – they’re opportunistic. Basic coverage eliminates most of the surface area.

Where this is going

Agents are going to keep getting more capable and more autonomous. The economic logic is too strong – an agent that can take action is worth more than one that can only respond, and capability tends to expand to fill that value. The attack surface expands with it.

The security thinking needs to catch up now, not after the first major incident. The tools exist. The understanding of the threat model is there for anyone who looks. The gap is mostly awareness and inertia.

If you’re building agentic systems and you’re not thinking about this yet, I’d genuinely recommend starting before something forces you to. The cost of retrofitting security onto a system that wasn’t designed with it is always higher than building it in early.

Defend is at pip install pydefend. The docs walk through the module setup. The GitHub repo is open – if you see gaps in the coverage or have attack patterns worth adding, that’s what issues are for.

If you’re working on something in this space – research, tooling, or just trying to secure an agent you’re building – I’d like to hear about it.

Prompt Contracts v2: Add Validation Rules to Your AI Prompts (Template Included)

My most-read post on this blog is about prompt contracts — treating prompts like API specs with defined inputs, outputs, and error handling.

But the original had a gap: it told you what to specify, not how to validate that the AI followed the spec.

This is the v2. It adds validation rules you can check automatically.

Quick Recap: What’s a Prompt Contract?

A prompt contract is a structured prompt with three sections:

INPUT: what you're giving the AI
OUTPUT: what you expect back (format, structure, length)
ERROR: what to do when something doesn't match

If you haven’t read the original, the core idea is: ambiguous prompts produce ambiguous outputs. Specs produce specs.

The Problem With v1

Prompt contracts work. But they rely on you manually checking whether the output matches. That’s fine for one-off tasks. It breaks down when you’re running prompts in scripts, pipelines, or daily workflows.

You need machine-checkable rules.

Validation Rules: The v2 Addition

Add a VALIDATION block to your contract:

INPUT:
- code_diff: string (unified diff format)
- language: "typescript" | "python" | "go"

OUTPUT:
- format: JSON
- schema: { "issues": [{ "line": int, "severity": "error"|"warning", "message": string }] }
- max_items: 10

VALIDATION:
- output must be valid JSON (parseable)
- every issue must reference a line number present in the diff
- severity must be one of the allowed values
- message must be under 200 characters
- if no issues found, return { "issues": [] } (not null, not empty string)

ERROR:
- if output fails validation, retry once with: "Your output failed validation: {error}. Fix and return only the corrected JSON."
- if retry also fails, return the raw output tagged as UNVALIDATED

Why This Matters

With validation rules, you can:

  1. Auto-retry on structural failures (JSON parse errors, missing fields)
  2. Log quality metrics (what % of outputs pass validation first-try?)
  3. A/B test prompts with a consistent scoring mechanism
  4. Chain prompts safely — downstream steps can trust the upstream output

A Real Example: Code Review Contract

Here’s a complete contract I use for automated PR reviews:

# Code Review Contract v2.1

## INPUT
- diff: unified diff of the PR
- context: file-level summary (max 500 tokens)
- focus_areas: list of strings (e.g., ["security", "performance"])

## OUTPUT
- format: Markdown
- sections: Summary (2-3 sentences), Issues (bulleted list), Verdict (APPROVE / REQUEST_CHANGES)
- max_length: 800 words

## VALIDATION
- must contain exactly 3 sections with the headers above
- Issues section: each bullet must start with [ERROR], [WARNING], or [SUGGESTION]
- Verdict must be one of the two allowed values
- Summary must not exceed 3 sentences
- No line references to files not in the diff

## ERROR
- missing section → retry with "You're missing the {section} section"
- invalid verdict → retry with "Verdict must be APPROVE or REQUEST_CHANGES"
- 2 consecutive failures → flag for human review

The Validation Checklist Template

Copy this and adapt it for any prompt:

## VALIDATION
- [ ] Output format matches spec (JSON / Markdown / plain text)
- [ ] All required fields present
- [ ] Field types correct (strings are strings, numbers are numbers)
- [ ] Values within allowed ranges / enums
- [ ] Length constraints met (min/max words, items, characters)
- [ ] No hallucinated references (files, URLs, variables that don't exist in input)
- [ ] Consistent with input (doesn't contradict the given context)

Wiring It Up in Code

If you’re calling an LLM from code, validation is just a function:

def validate_review(output: dict) -> list[str]:
    errors = []
    required = ["Summary", "Issues", "Verdict"]
    for section in required:
        if section not in output:
            errors.append(f"Missing section: {section}")
    if output.get("Verdict") not in ("APPROVE", "REQUEST_CHANGES"):
        errors.append(f"Invalid verdict: {output.get('Verdict')}")
    return errors

# Usage
result = call_llm(prompt)
issues = validate_review(result)
if issues:
    result = call_llm(f"Fix these validation errors: {issues}nnOriginal output: {result}")

Simple. No framework needed.

When to Skip Validation

Not everything needs a contract. If you’re brainstorming, exploring, or doing creative work, contracts add friction without value.

Use contracts when:

  • Output feeds into another system
  • You’re running the prompt more than once
  • Incorrect output has a real cost (time, money, bugs)

Skip contracts when:

  • You’re thinking out loud
  • The output is for your eyes only
  • You’ll edit it heavily anyway

Key Takeaway

Prompt contracts v1 told you to define the spec. v2 tells you to enforce it.

The validation block turns your prompt from a wish into a testable requirement. That’s the difference between “AI-assisted” and “AI-reliable.”

Grab the template above and try it on your most-used prompt. Share what breaks — I’m collecting failure modes for a follow-up post.

Build for Consumability, The Provider to Consumer Model That Makes AWS Scale.

AWS Provider to Consumer Model

Most platform teams think their job is to build infrastructure. They’re wrong. Their job is to build infrastructure that other teams can consume without thinking about it.

The difference matters more than most organisations realise. A platform team that builds a beautifully architected AWS landing zone but makes it painful to consume has built a bottleneck, not a platform. And in a large enterprise (where dozens of product teams need to ship features against real deadlines) bottlenecks don’t just slow you down, they breed shadow IT, workaround architectures, and the kind of ungoverned sprawl that keeps security teams awake at night.

The Provider to Consumer model fixes this. It’s a shared responsibility framework that gives the platform team (the Provider) clear ownership of foundational infrastructure, while giving product teams (the Consumers) a fast, governed path to build and deploy. Neither side operates in isolation. Both sides have accountabilities, and the interfaces between them are deliberate, opinionated, and battle-tested.

Here’s how it works, and why it’s the pattern that separates enterprises that scale confidently from those that scale chaotically.

The Problem With “We’ll Build It For You”

In too many enterprises, the cloud platform team operates as a service desk. Product teams raise a ticket > The platform team provisions a VPC > Another ticket > An IAM role gets created > Another ticket > A CI/CD pipeline appears three weeks later.

This model doesn’t scale. It can’t. Every request becomes a queue item. Every queue item becomes a lead time. Every lead time becomes a frustrated product manager asking why it takes six weeks to get a development environment when they could spin one up on a personal AWS account in twenty minutes.

The instinct to centralise everything and hand it out on request comes from good intentions (governance, security, cost control). But the execution model is fundamentally wrong. You’re not providing a platform. You’re providing a gatekeeping function that happens to run on AWS.

The Provider to Consumer model inverts this. Instead of building things for consumers, you build things that consumers can use themselves (within boundaries you’ve already defined).

What the Provider Actually Owns

The Provider is the cloud platform team. Their job is to provision and maintain the foundational layers that every product team needs (and to do it in a way that’s repeatable, governed, and fast).

There are four core responsibilities.

Account Provisioning with CIS Baseline. Every new workload gets its own AWS account pattern, provisioned through automation with a CIS security (or other supported frameworks) baseline already applied. The consumer doesn’t request a hardened account and wait. The account arrives hardened. Security isn’t a follow-up step, it’s baked into the provisioning pipeline. AWS Control Tower watches across the entire organisation, enforcing guardrails that the consumer doesn’t need to think about because they can’t violate them.

VPC Design and Provisioning. The Provider owns the network architecture. Every account receives a VPC built from a repeatable reference architecture, consistent CIDR allocation, subnet tiering, inspection architecture, and connectivity back to shared services. The consumer doesn’t design their own network. They don’t choose their own CIDR ranges. They don’t decide whether they need a NAT gateway. The VPC arrives ready, and it’s the same shape every time. This isn’t about limiting creativity, it’s about eliminating an entire category of networking incidents that happen when teams roll their own.

CI/CD Pipeline and Repository Provisioning. The Provider provisions a GitHub repository with industrialised GitHub Actions workflows already wired in. The PR workflow (plan on pull request, apply on merge) is pre-configured and opinionated. The consumer doesn’t build their own pipeline from scratch. They don’t decide how Terraform gets executed. They inherit a workflow that’s been tested across dozens of teams and hundreds of deployments. It works. Use it.

Infrastructure as Code Modules. The Provider maintains a library of battle-tested Terraform (or Terragrunt/OpenTofu) modules for commodity services (compute, databases, storage, queues, load balancers), the building blocks that every product team needs. These modules encode the organisation’s opinions about how things should be built – tagging standards, encryption defaults, logging configuration, IAM boundaries. A consumer deploying an RDS instance through a Provider module gets all of that for free. A consumer building their own from raw Terraform resources gets none of it, and that creates a governance gap that someone will eventually have to close.

What the Consumer Actually Owns

The Consumer is the product team, developers and DevOps engineers building features, services, and applications on top of the platform.

Their accountabilities are different from the Provider’s, but they’re not lesser. The Consumer owns the application. The Provider owns the platform. The boundary between them is the interface contract, and both sides have obligations to honour it.

Building in a Safe, Governed Zone. The Consumer operates within the account, VPC, and pipeline that the Provider has established. They don’t need to understand how the VPC was designed (but they do need to place their resources in the correct subnets). The Provider exposes this through lookups – the Consumer queries for the right subnet by type (public, private, data/backend etc) and gets back the correct placement. The VPC configuration is locked. The lookup is available. This is the right trade-off.

Using the CI/CD Pipeline for All Infra Changes. No ClickOps, no console deployments – every infrastructure change goes through the PR workflow the Provider has established. Plan on pull request > review > approve > apply on merge > promote through environments. The Consumer uses this pipeline, they don’t modify it, bypass it, or build an alternative alongside it. The pipeline is the governance boundary, and respecting it is what makes the model work. If there are exceptions where console access is unavoidable, then it’s granted on a request/approval basis, it is also temporary.

Consuming Infra IaC Modules for Resource Provisioning. When the Consumer needs infrastructure, they reach for a Provider module first. Need an S3 bucket? There’s a module. Need an ECS service? There’s a module. Need an Aurora cluster? There’s a module. These modules aren’t suggestions, they’re the supported path. Building outside them is possible but comes with additional review requirements, because you’re stepping outside the governed envelope.

The Shared Responsibility in Practice

AWS Provider to Consumer Model

The diagram that captures this model cleanly shows an AWS account as a shared space with a clear dividing line. On the left: the Provider’s contributions. On the right: the Consumer’s usage of those contributions. In the middle: the interfaces that connect them.

At the account layer, the Provider provisions the account with the required security frameworks applied. The Consumer sees Control Tower guardrails watching over their environment. They build in a safe zone, not because they chose to be safe, but because the environment won’t let them be unsafe.

At the network layer, the Provider delivers a repeatable reference VPC architecture. The Consumer gets lookup access to find the correct subnet for their workload placement. The config is locked. The information is accessible. The Consumer can read the network topology but can’t rewrite it.

At the CI/CD layer, the Provider delivers an Infra GitHub Actions workflows. The Consumer uses them to create and promote through their PR-driven deployment workflow. Infrastructure changes flow through the same governed pipeline regardless of which team is making them.

At the IaC layer, the Provider delivers modules. The Consumer uses them. The module encodes the organisation’s standards. The Consumer supplies their workload-specific configuration. The result is infrastructure that’s both customised to the application and compliant with the organisation’s baseline.

This isn’t a hierarchy, it’s a contract. The Provider promises a fast, secure, consistent foundation. The Consumer promises to build on that foundation rather than around it.

Why “Built for Consumability” Is the Whole Point

Here’s the phrase that should be pinned above every platform team’s desk: Build for Consumability.

The value of a platform isn’t measured by how sophisticated the Provider’s architecture is. It’s measured by how quickly a Consumer can go from “I need an environment” to “I’m deploying code.” If that journey takes six weeks and twelve tickets, the architecture doesn’t matter. You’ve failed.

Fast request through to environment provisioning means a product team can go from approved request to fully provisioned, governed AWS account with VPC, pipeline, and IaC modules, ready to build, in minutes, not weeks (as long as the required information is provided to facilitate the process). This is what automation exists for. Not to make the platform team’s life easier (though it does), but to make the Consumer’s path frictionless.

Clear separation of accountabilities means nobody is confused about who owns what. The Provider doesn’t debug application code. The Consumer doesn’t redesign the VPC. When something goes wrong (and it will) the separation makes triage faster because the ownership boundaries are unambiguous.

Governed and opinionated do’s and don’ts include fail-safes meaning the platform has opinions, and those opinions are enforced. You can deploy an RDS instance through the module. You can’t deploy an unencrypted RDS instance because the module won’t let you. You can create a security group. You can’t open 0.0.0.0/0 to the internet because the guardrail catches it. These aren’t restrictions on productivity, they’re the reason the Consumer can move fast.

Industrialised VPC architecture means the network is solved. Every account gets the same proven design, with inspection, segmentation, and connectivity built in. The Consumer never has to become a networking expert to ship a feature.

Industrialised GitHub Actions means the infra deployment pipeline is solved. Every team gets the same PR workflow, the same plan-and-apply pattern, the same promotion gates. The Consumer never has to become an infra CI/CD expert to deploy safely.

Battle-tested IaC modules means the building blocks are solved. Every commodity service has a module that encodes security, tagging, logging, and best practices. The Consumer never has to become a Terraform expert to provision compliant infrastructure.

See the pattern? The Provider solves categories of problems once. The Consumer benefits from those solutions repeatedly. That’s consumability.

The Feedback Loop That Makes It Better

The Provider to Consumer model isn’t static. The best implementations include a feedback loop where Consumer teams report friction, request new modules, and flag gaps in the platform.

A Consumer team discovers they need a service that doesn’t have a module yet? That’s a signal to the Provider to build one. A module is too rigid for a legitimate use case? That’s a signal to add a configurable parameter. The PR workflow doesn’t handle a team’s branching strategy well? That’s a conversation worth having.

The Provider maintains the platform. The Consumer pressure-tests it. Over time, the platform gets better not because the Provider imagines what teams need, but because teams tell them, through usage patterns, through support requests, and through the occasional frustrated Slack message that starts with “why can’t I just…”

Those messages aren’t complaints. They’re product feedback. And the platform teams that treat them that way build platforms that people actually want to use.

What Happens When You Get This Wrong

If the Provider builds without thinking about consumability, you get a technically excellent platform that nobody uses. Teams route around it. They build their own VPCs in accounts they shouldn’t have access to. They set up their own pipelines because the official one is too slow or too rigid. Shadow infrastructure proliferates, and the governance that the platform was supposed to provide evaporates.

If the Consumer ignores the Provider’s interfaces and builds from scratch, you get inconsistency. Every team’s infrastructure looks different. Tagging standards vary. Encryption policies are applied ad hoc. When audit time comes (and it always comes) you’re answering questions about fifty different implementations instead of one.

If neither side respects the boundary, you get the worst of both worlds: a platform team drowning in bespoke requests and product teams waiting in queues that shouldn’t exist. This is the state most enterprises find themselves in before they adopt the model. It feels normal because everyone’s used to it. It isn’t normal. It’s just common.

Why This Matters Now

Enterprises are scaling their AWS & general cloud footprints faster than ever. Hundreds if not thousands of accounts. Thousands of developers. Hundreds of 3rd party suppliers. Dozens of product teams with different tech stacks, different timelines, and different risk tolerances.

You cannot govern this with ticket queues and manual provisioning. You cannot secure this by reviewing every pull request centrally. You cannot maintain consistency by writing standards documents that nobody reads.

You can govern it by building a platform that’s opinionated by default and consumable by design. You can secure it by encoding security into the modules and guardrails that teams use every day. You can maintain consistency by making the compliant path the easiest path.

The Provider to Consumer model isn’t just an operating model. It’s a force multiplier. Every investment the Provider makes in a module, a pipeline, or a guardrail pays dividends across every Consumer team that uses it. And when the platform is built for consumability, those Consumer teams don’t just tolerate the platform, they depend on it.

Build for consumability. Build the interfaces. Define the boundaries. And then let your product teams build, fast, safe, and at scale.

connpool: A Zero-Alloc TCP Connection Pool for Go

The Story

Years ago, when I first needed TCP connection pooling in Go, I found fatih/pool. It was elegant, simple, and it taught me a lot about channel-based pooling design. It was a real inspiration.

But as I worked on high-throughput systems at scale, I kept running into gaps: no health checks, no idle eviction, no lifetime management, no metrics. I’d bolt these on as wrappers, and eventually realized I was maintaining a full pool implementation anyway.

So I built connpool — taking the channel-based foundation that fatih/pool popularized and adding the features that production systems actually need.

Introducing connpool

github.com/soyvural/connpool — a production-grade TCP connection pool for Go.

go get github.com/soyvural/[email protected]

Zero dependencies. ~370 lines of code. Zero-alloc fast path.

Quick Example

cfg := connpool.Config{
    MinSize:     5,
    MaxSize:     20,
    Increment:   2,
    IdleTimeout: 30 * time.Second,
    MaxLifetime: 5 * time.Minute,
    Ping: func(c net.Conn) error {
        c.SetReadDeadline(time.Now().Add(time.Millisecond))
        buf := make([]byte, 1)
        if _, err := c.Read(buf); err != nil {
            if netErr, ok := err.(net.Error); ok && netErr.Timeout() {
                c.SetReadDeadline(time.Time{})
                return nil // timeout = alive
            }
            return err // dead
        }
        c.SetReadDeadline(time.Time{})
        return nil
    },
}

pool, _ := connpool.New(cfg, func() (net.Conn, error) {
    return net.DialTimeout("tcp", "localhost:6379", 5*time.Second)
}, connpool.WithName("redis-pool"))
defer pool.Stop()

conn, _ := pool.Get(ctx)
defer conn.Close() // returns to pool

// If the connection is broken:
pool.MarkUnusable(conn)
conn.Close() // destroys instead of returning

What Makes It Different

1. Health Check on Get()

Every Get() call validates the connection before returning it. The check order is optimized — cheapest first:

Lifetime check (time comparison) → Idle check (time comparison) → Ping (network I/O)

Time comparisons cost nanoseconds. The expensive network ping only runs if the connection passes the time-based checks. If a connection fails health check, it’s discarded and the pool retries (up to 3 times) before growing.

2. Max Lifetime with Jitter

Connections have a maximum lifetime, but here’s the trick: each connection gets a 10% random jitter on its expiration.

Why? Without jitter, if you create 20 connections at startup, they all expire at the exact same moment — causing a thundering herd of reconnections. Jitter spreads the expiration across time.

func (c *Config) maxLifetimeWithJitter() time.Duration {
    if c.MaxLifetime <= 0 {
        return 0
    }
    jitter := time.Duration(rand.Int64N(int64(c.MaxLifetime) / 10))
    return c.MaxLifetime + jitter
}

This is the same pattern used by pgx and Vitess.

3. Background Evictor

Without a background evictor, stale connections only get cleaned up when someone calls Get(). If the pool is idle (no traffic), dead connections accumulate silently.

The evictor runs every 30 seconds (configurable), drains the channel, health-checks each connection, discards the stale ones, and replenishes to MinSize.

4. Zero-Alloc Fast Path

The pool uses a channel internally (inspired by fatih/pool‘s original design), not a mutex+slice. This gives us:

  • Natural blocking semantics (when pool is at max, Get() blocks on channel receive)
  • Non-blocking fast path via select/default
  • Zero heap allocations on the hot path
BenchmarkGetPut_Sequential    8,556,068    139.9 ns/op    0 B/op    0 allocs/op
BenchmarkGetPut_Parallel      5,075,728    245.1 ns/op    0 B/op    0 allocs/op

5. Context-Aware Get()

Get() respects context deadlines and cancellation. If the pool is exhausted and a connection doesn’t become available before the deadline, you get context.DeadlineExceeded — not a hang.

6. Comprehensive Metrics

stats := pool.Stats()
fmt.Printf("size=%d active=%d available=%dn",
    stats.Size(), stats.Active(), stats.Available())
fmt.Printf("idle_closed=%d lifetime_closed=%d ping_failed=%dn",
    stats.IdleClosed(), stats.LifetimeClosed(), stats.PingFailed())
fmt.Printf("wait_count=%d wait_time=%vn",
    stats.WaitCount(), stats.WaitTime())

Every metric you need for alerting and debugging — without pulling in a metrics library.

Benchmarks

goos: darwin
goarch: arm64
cpu: Apple M2 Pro
BenchmarkGetPut_Sequential    8,556,068    139.9 ns/op    0 B/op    0 allocs/op
BenchmarkGetPut_Parallel      5,075,728    245.1 ns/op    0 B/op    0 allocs/op
BenchmarkGetPut_WithPing        216,386   5571   ns/op   81 B/op    2 allocs/op
BenchmarkGetPut_Contended     2,405,068    478.7 ns/op    0 B/op    0 allocs/op

The fast path (sequential, no ping) runs at 139ns with zero allocations. Even under heavy contention (8 workers fighting over 2 connections), it stays under 500ns.

Design Decisions

Decision Why
Channel over mutex+slice Natural blocking, zero-alloc select/default fast path
Lifetime jitter Prevents thundering herd reconnection storms
Health check ordering Cheapest checks first (time → time → network)
Background evictor Don’t wait for Get() to clean dead connections
conn.Close() returns to pool Familiar net.Conn interface — no new API to learn

Inspired By the Best

This pool draws ideas from several production-grade systems:

Feature Where I Learned It
Channel-based pool fatih/pool
Idle timeout + max lifetime pgx, Vitess
Health check on borrow go-redis, Apache Commons Pool
Background evictor pgx, Apache Commons Pool, Vitess
Context-aware Get Vitess, pgx
MarkUnusable fatih/pool

Get Started

go get github.com/soyvural/[email protected]

The repo includes three working examples:

  • tcp-echo — basic pool usage
  • redis-proxy — pooling with health checks against Redis
  • load-balancer — round-robin across multiple backend pools

GitHub: soyvural/connpool

If you’re working with TCP connections in Go and need something more robust than a basic pool, give connpool a try. Star the repo if you find it useful — it helps others discover it.

I’d love feedback on the API design, especially if you have use cases I haven’t considered. Drop a comment or open an issue!

Why Erlang C Always Understaffs Your Call Center (And What to Use Instead)

A.K. Erlang published his queuing formula in 1917 to figure out how many telephone circuits the Copenhagen Telephone Company needed. Over a century later, call center managers still plug three numbers into an Erlang C calculator from a website that looks like it was built in 2003, get a number, and treat it as staffing truth. Then they wonder why Monday at 9 AM has a 12-minute wait time and Thursday at 2 PM has six idle agents.

The Erlang C formula is real math. It’s correct math. It just answers the wrong question for a real call center. Here’s what it assumes: calls arrive randomly (Poisson distribution), all agents are identical and interchangeable, no callers abandon, agents handle one call then immediately take the next, call arrival rate is constant, there’s no wrap-up time between calls, and nobody takes breaks, calls in sick, or goes to lunch. Exactly zero of these assumptions hold in practice.

But Erlang C is still where you start, because it gives you the mathematical floor — the minimum agents you’d need in a universe where everything works perfectly. Then you adjust for the real world, and the adjustment is where 95% of people stop too early.

The Gap Is Always 27-57%

After running staffing models across dozens of operations, the gap between what Erlang C says and what you actually need is remarkably consistent:

Scenario Calls/30min AHT Erlang C Says You Actually Need Gap
Small inbound support 30 300s 7 9-10 +29-43%
Medium sales inbound 80 240s 14 18-20 +29-43%
Large blended center 200 210s 26 33-37 +27-42%
Collections floor 50 180s 7 9-11 +29-57%
High-touch B2B sales 25 600s 11 14-16 +27-45%

That gap isn’t noise. It’s the accumulated weight of four factors that Erlang C completely ignores.

Factor 1: Shrinkage (25-35%)

Shrinkage is the percentage of paid time agents are unavailable to handle calls. Breaks (30 min/day), lunch (30-60 min/day), training and meetings (2-4 hours/week), coaching sessions, system issues (frozen computer, VPN dropout, softphone crash), unscheduled absences, late arrivals, and early departures.

The industry average is 30-35% for on-site centers and 35-40% for remote agents (home distractions, internet issues, longer breaks). Most operations discover their actual shrinkage is higher than they assumed.

The adjustment is simple: Adjusted agents = Erlang C agents / (1 - shrinkage_rate). If Erlang C says 19 and your shrinkage is 32%: 19 / 0.68 = 28 agents. Already a 47% increase from the raw number.

Factor 2: Occupancy Limits

Occupancy is the percentage of time an agent spends on calls versus waiting. At 84% occupancy, agents spend 50 minutes of every hour on the phone. That sounds efficient. It’s also a fast track to burnout. Sustainable occupancy depends on the work:

  • Inbound support (simple): 85-88%
  • Inbound sales: 78-82%
  • Outbound cold calling: 75-80%
  • Collections: 72-78%

If your staffing model produces 90%+ occupancy, expect a turnover problem within 60 days. Agents start calling in sick, taking longer breaks, and quitting. Replacing one agent costs $3,000-8,000 in recruiting, training, and ramp-up time. Running agents at 90% to save on staffing is one of the most expensive mistakes a call center can make.

Factor 3: Call Abandonment

Erlang C assumes callers wait forever. They don’t. 25% hang up after 30 seconds, 50% after 60 seconds, 70% after 120 seconds. This creates a vicious paradox: understaffing causes abandonments, which reduce apparent call volume, which makes Erlang C tell you that you need fewer agents. The formula rewards you for bad service.

The fix: add abandoned calls back into your volume calculation. Use total calls offered (answered + abandoned) as your input, not just answered calls. If any half-hour interval shows an abandon rate above 5%, that interval is understaffed. Period.

Factor 4: Multi-Skill Routing

If agents handle multiple queues (billing, sales, tech support), Erlang C breaks down. The formula assumes perfect pooling — all agents interchangeable. In reality, Agent A handles billing and sales, Agent B handles sales only, Agent C handles all three. This partial pooling is more efficient than separate queues but less efficient than the full pooling Erlang C assumes. Expect an 8-15% underestimate for multi-skill environments.

The Real Formula

Required staff = (Erlang_C_agents * (1 + multi_skill_factor)) /
                 (1 - shrinkage_rate) /
                 min(target_occupancy, 1.0) *
                 (1 + absenteeism_buffer)

For 120 calls per half-hour with 240-second AHT, 80/20 service level:

Erlang C raw:       19 agents
+ Multi-skill (10%): 20.9 agents
+ Shrinkage (32%):  30.7 agents
+ Occupancy (82%):  37.5 agents
+ Absenteeism (5%): 40 agents

Forty agents to do what Erlang C says you can do with nineteen. A 111% gap. And forty is the right number — anyone who’s run a 120-call-per-half-hour inbound operation knows that 19 agents would result in 15-minute hold times and mass abandonment.

Half-Hour Grids and Day-of-Week Adjustment

Your call volume isn’t flat. It spikes in the morning, dips at lunch, picks up in the afternoon. You need a staffing grid that calculates required agents for each 30-minute interval using your actual historical volume data.

Practical moves that make the grid work:

Stagger start times. If you need 25 agents at 8 AM and 40 at 9:30 AM, don’t have everyone clock in at 8. Bring them in waves — 5 at 7:00, 5 at 7:30, 10 at 8:00, 5 at 8:30, 10 at 9:00, 5 at 9:30.

Stagger lunches. Split 40 agents into 4 groups at 11:00, 11:30, 12:00, and 12:30. You lose 10 agents during each lunch slot instead of 40. This alone can drop your midday abandon rate by 60%.

Build separate grids for each day. Monday volumes are typically 15-25% higher than Friday. Using one staffing plan for every day means overstaffed on Friday and drowning on Monday.

Validate weekly. Compare your model’s predicted service level for each interval against what actually happened. If you’re off by more than 10%, recalibrate your shrinkage rate and AHT assumptions.

Outbound Is Different Math

Outbound staffing follows different rules because the dialer controls the pace. The key formula:

calls_per_agent_per_hour = 3600 / (avg_talk_sec + avg_wrapup_sec + avg_ring_sec / connect_rate)
required_agents = target_contacts_per_hour / calls_per_agent_per_hour

For B2B outbound with 10% connect rate, 180-second talk time, 30-second wrap-up: 7.8 contacts per agent per hour. Need 60 contacts per hour? That’s 8 productive agents, or 12 scheduled after shrinkage. If you need 300 contacts per day across an 8-hour shift, you need about 5 productive agents, which means 8 scheduled.

For blended campaigns (agents taking inbound and making outbound between calls), calculate the inbound staffing need first — that’s the hard constraint. Then figure out how much outbound capacity exists in the gaps. Don’t try to optimize both simultaneously in one formula. Calculate them separately and overlay the results.

Common Mistakes That Blow Up Staffing Models

Using daily averages instead of half-hour intervals. If your average daily call volume is 800, you might calculate that you need 25 agents. But if 200 of those 800 calls come between 9:00 and 10:00 AM, you need 40 agents during that hour and 15 the rest of the day. Daily averages hide the peaks that destroy your service level.

Ignoring AHT variance by agent. Your average AHT is 240 seconds, but Agent A averages 180 and Agent B averages 380. If Agent B is scheduled during peak hours and Agent A is on the quiet shift, your actual service level during peak will be much worse than the model predicts. Match your best agents (lowest AHT, highest conversion) to your highest-volume intervals.

Not accounting for new agent ramp-up. New agents typically have AHTs 40-80% higher than tenured agents during their first 30 days. If you’re onboarding 5 new agents and counting them as full-capacity resources, you’re overstating your actual handling capacity.

Treating blended campaigns like pure inbound. In a blended VICIdial environment, the moment inbound volume spikes, agents get pulled from outbound, the dial level drops, and your outbound throughput craters. Model the inbound constraint first, then figure out how much outbound capacity remains in the gaps.

Forgetting that breaks cluster. You schedule 15-minute breaks at 10:00 and 10:15 in two groups. But five agents take their break 8 minutes late, three come back 4 minutes late, and one disappears for 22 minutes. Your “planned” 15-minute break actually removes agents for 25-30 minutes. Build a 50% buffer on scheduled break durations.

Using answered calls instead of offered calls as input. If callers are abandoning because of long wait times, the answered volume is artificially low. Erlang C tells you that you need fewer agents based on this suppressed volume. Use total offered calls (answered + abandoned) to avoid the negative feedback loop.

The Bottom Line

The operations that get staffing right aren’t the ones with the best formula. They’re the ones that measure, compare, adjust, and repeat. Every week, forever. Pull last week’s actual volume, AHT, and service level by half-hour. Compare to your model. If the gap is more than 10%, update your assumptions. Run a two-week forecast. Recalibrate your baseline shrinkage percentage monthly from actual data.

Erlang C is a starting point. The real work is everything you layer on top and the discipline to keep your inputs fresh. A call center that gets staffing right — not once, but every week — runs at lower cost with better service levels than one that throws bodies at problems. The math isn’t hard. The discipline to keep updating your inputs is the hard part.

The difference between 80/20 and 90/10 service level targets can be 30-40% more agents for the same volume. That’s not a typo. The relationship between service level and staffing is exponential, not linear. Make sure your target actually matches your business needs before you build a model around it — a lot of operations run 80/20 by default because “that’s the industry standard” without ever asking whether their customers would be fine with 80/30.

For the complete implementation with Python Erlang C solver code, SQL queries for extracting AHT, shrinkage, and volume from VICIdial, half-hour staffing grid generators, and automated weekly validation scripts, see the full guide at ViciStack.

🚀 The Future is Now: AI, 6G & Space Tech.

👋 Hey everyone! I’m Mazeed — telecom engineer turned AI & space tech enthusiast. I’m obsessed with pushing the boundaries of technology, from next-gen networks to AI-driven space systems.

This community feels like the perfect space to share projects, ideas, and breakthroughs, and learn from people who are building the future today.

🔹 What I’ll Be Sharing

Topic What You’ll Get

AI in Telecom & 5G/6G Real-world pipeline setups, containerized models, CI/CD examples
Space Tech & Exploration Satellite comms, AI-driven orbital systems, futuristic projects
Deep Tech Career Growth Mindset, productivity, building in emerging tech
Hands-on Tutorials Mini guides, code snippets, deploy-ready demos

🛠 Mini Example: Real-Time 5G Traffic Prediction
import torch
from model import LSTMModel

model = LSTMModel()
model.load_state_dict(torch.load(“weights.pth”))
model.eval()

sample_input = torch.randn(1, 10, 5) # batch, sequence, features
prediction = model(sample_input)
print(“Predicted network load:”, prediction.item())

✅ Deployable on Kubernetes, auto-scalable, and ready for edge AI nodes.

📊 Visual Pipeline (Diagram)
+—————-+ +—————-+ +—————-+
| Data Ingestion | —> | Model Training | —> | Model Serving |
+—————-+ +—————-+ +—————-+
| | |
MQTT/Kafka PyTorch / TensorFlow Flask / FastAPI
| | |
+———————————————–+
Monitoring & Logging
Prometheus / Grafana / ELK

This is a simplified view of how AI pipelines for telecom & 5G/6G work — scalable, reliable, and real-time.

💡 Why I’m Here

I want this space to be collaborative — a place to share, discuss, and push limits together. Whether it’s AI, 6G, or space tech, let’s turn futuristic ideas into reality.

💬 Question for the community:
What’s the craziest tech idea you’re exploring right now?
Drop it below —
let’s brainstorm and collab!

5 AI Coding Mistakes That Waste Hours (and the Prompts That Fix Them)

You paste code into ChatGPT. You get an answer. It looks right. You ship it.

Two hours later, it breaks.

I’ve made every AI coding mistake in the book. Here are the five that cost me the most time — and the exact prompts I use now to avoid them.

Mistake 1: Asking for a Solution Without Explaining the Constraint

What happens: You say “write a function that sorts users by name.” The AI gives you a perfectly valid sort — that loads 50,000 records into memory.

The fix prompt:

I need a function that sorts users by name.

Constraints:
- Dataset: ~50k records, PostgreSQL backend
- Must use database-level sorting (no in-memory)
- Return paginated results (20 per page)
- Must work with the existing User model (id, name, email, created_at)

Show me the query and the controller method.

Why it works: Constraints turn “write me a sort” into “write me this sort.” The AI can’t over-engineer or under-engineer when boundaries are explicit.

Mistake 2: Accepting the First Output Without Verification

What happens: The code compiles. The tests pass (the ones the AI wrote). You merge. Then edge cases start exploding.

The fix prompt:

Before giving me the final version, do this:

1. List 3 edge cases that could break this function
2. Write a test for each edge case
3. Run the function mentally against each test
4. Fix any failures
5. Then show me the final version with all tests passing

This is the verification loop pattern. It adds 30 seconds to the prompt and saves hours of debugging.

Mistake 3: Dumping an Entire File and Saying “Fix It”

What happens: The AI has 4,096 tokens of context. You just used 3,800 on a file it doesn’t understand. The remaining 296 tokens produce garbage.

The fix prompt:

Here's a focused excerpt from auth.js (lines 42-78).
The bug: login() returns 200 even when the password is wrong.

Expected: return 401 for invalid credentials
Actual: returns 200 with an empty token

Only fix the authentication check. Don't refactor anything else.

Why it works: You did the triage. You isolated the problem. The AI can now be a surgeon instead of a detective.

Mistake 4: Not Telling the AI What “Done” Looks Like

What happens: You ask for “a REST API endpoint.” You get something. Is it done? You don’t know. The AI doesn’t know. You go back and forth five times.

The fix prompt:

Build a POST /api/invoices endpoint.

Done means:
- [ ] Validates required fields (amount, customer_id, due_date)
- [ ] Returns 201 with the created invoice
- [ ] Returns 422 with field-level errors for invalid input
- [ ] Includes a test for each scenario above
- [ ] Uses the existing Invoice model (no schema changes)

Checklists kill ambiguity. If you can’t write the checklist, you don’t understand the task well enough to delegate it — to a human or an AI.

Mistake 5: Using AI for the Wrong Part of the Job

What happens: You spend 20 minutes crafting the perfect prompt to generate a database migration. It would have taken 3 minutes to write it by hand.

The rule I follow now:

Task AI? Why
Boilerplate (CRUD, tests, types) ✅ Repetitive, low-risk
Business logic ⚠️ Only with clear spec
Architecture decisions ❌ You need to own these
Debugging (with context) ✅ AI is great at pattern-matching errors
Debugging (without context) ❌ Garbage in, garbage out

The best AI coding workflow is knowing when not to use AI.

The Pattern

Every mistake above has the same root cause: under-specified input.

The fix is always the same:

  1. State the constraint
  2. Define “done”
  3. Ask for verification
  4. Keep context small

That’s it. No frameworks. No plugins. Just better prompts.

What’s the AI coding mistake that costs you the most time? Drop it in the comments — I’ll write the fix prompt for it.

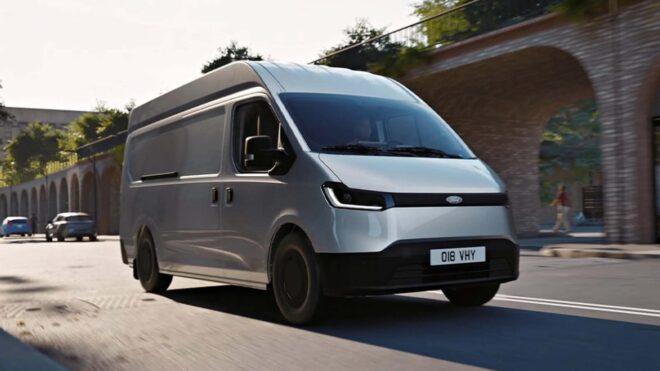
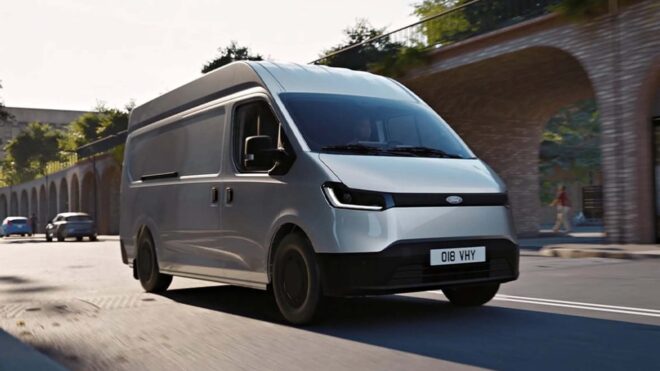
Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttı

Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttı

Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttıABD merkezli otomobil devi Ford, Avrupa pazarına özel olarak tasarlanan “Çinli” Transit City’yi tanıttı. Üç farklı gövde tipinde sunulacak tamamen elektrikli ticari model, yapılan açıklamaya göre doğrudan Çin merkezli Jiangling Motors Corporation (JMC) tarafından geliştirilen bir platformu temel alıyor ve üretimin de doğrudan Çin’de yapılacağı belirtiliyor. Yük kapasitesi 1.085 kg ile 1.530 kg arasında değişen Transit City, öne konumlandırılan tek bir elektrik motoruyla 148 beygir güç sunuyor ve 56 kWh kapasiteli LFP batarya paketiyle yaklaşık 254 km menzil vadediyor. Spesifik olarak kısa mesafeli şehir içi taşımacılık ihtiyaçlarına yönelik olarak hazırlanan araç, 87 kW DC (maksimum değer) ile yüzde 10’dan yüzde 80’e 33 dakikada şarj edilebiliyor. Modelin şarj süresi 11 kW AC ile beş saat olarak açıklanırken, yeni Transit City’nin fiyatları henüz paylaşılmıyor.

Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.