iPhone Fold’un çıkışı gecikebilir: İşte yeni tarih
 Daha önce, Apple’ın katlanabilir telefonunu iPhone 18 Pro serisiyle birlikte Eylül 2026’da tanıtması bekleniyordu. Son bilgilere göre cihazın piyasaya çıkışı Aralık 2026’ya sarkabilir.

 Mert Daha önce, Apple’ın katlanabilir telefonunu iPhone 18 Pro serisiyle birlikte Eylül 2026’da tanıtması bekleniyordu. Son bilgilere göre cihazın piyasaya çıkışı Aralık 2026’ya sarkabilir.
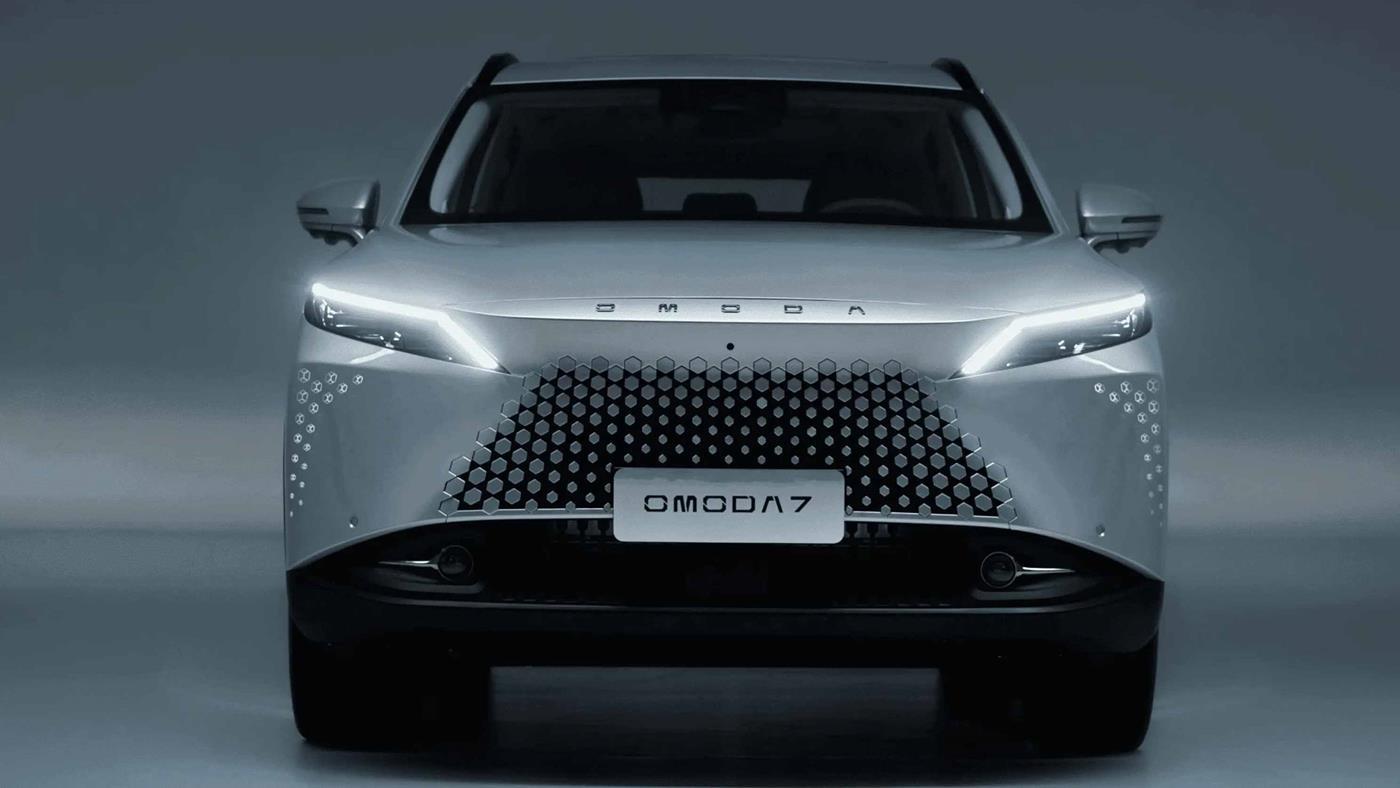
 Omoda’nın ikinci modeli Türkiye’ye geldi. Yeni Omoda 7 Neo, tasarımı ve zengin donanım seçenekleriyle dikkat çekiyor. Omoda 7 fiyatı kaç para? Omoda 7 özellikleri neler? İşte detaylar:
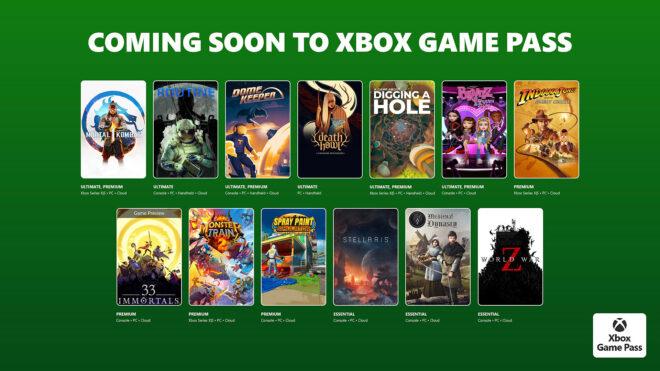
 “Redphx” tarafından yapılan son keşfe göre Xbox Game Pass için yakında yalnızca “Xbox Studios” oyunlarına özel bir abonelik seçeneği gelebilir. Şirketin kodlarında “TRITON” olarak geçen yeni paket için şu anda listelenen oyunlar, “DOOM Eternal, DOOM 64, Dishonored 2, Fable Anniversary, Fallout 4, Fallout 76, Gears 5, Halo 5: Guardians, Halo Wars 2, Hellblade, Ori and the Blind Forest, Psychonauts, State of Decay 2, The Elder Scrolls Online ve Retro Classics.” olarak görünüyor. The Information tarafından geçtiğimiz günlerde yayımlanan yeni bir habere göre Microsoft Gaming’in, yani Xbox dünyasının yeni CEO’su Asha Sharma’nın görevindeki ilk icraatlarından biri, servisi daha geniş bir tüketici kitlesi için çekici kılmak ve servise yeni oyuncular eklemek amacıyla Game Pass için daha düşük fiyatlı bir abonelik seçeneği sunmak olabilir. Game Pass için geçtiğimiz aylarda detaylarına burada yer verdiğimiz çok büyük duyurular gerçekleştiren şirket, Sharma’nın yönetimi altında Xbox’ı yeniden konsolun öne çıktığı bir marka haline getirmek istiyor ve bunun […]
Xbox Game Pass için Xbox Studios oyunlarına özel bir abonelik seçeneği gelebilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Ultima actualizacion: Marzo 2026 | Tiempo de lectura: ~18 minutos
Ya hiciste las cuentas. Convoso quiere $150/puesto/mes. Five9 quiere aun mas. Mientras tanto, VICIdial — el mismo marcador predictivo open-source que alimenta mas de 14,000 instalaciones en todo el mundo — no cuesta absolutamente nada en licencias.
Solo hay un problema: instalarlo.
Cada guia que vas a encontrar en Google ahora mismo es un PDF de ViciBox 7 del 2018, un hilo de foro con 47 respuestas contradictorias, o un post de blog que parece que fue traducido tres veces. CentOS 7 — el sistema operativo que el 90% de esas guias referencian — llego a su fin de vida en junio de 2024. Si sigues esas instrucciones en 2026, estas construyendo sobre una base muerta.
Esta guia arregla eso. Vamos a cubrir ViciBox 12.0.2 (la version estable actual), instalaciones desde cero en AlmaLinux 9, despliegues de servidor unico, clusters multi-servidor, configuracion de troncales SIP con ejemplos reales de carriers, configuracion de WebRTC para agentes remotos, y cada problema comun que te va a arruinar el fin de semana si no lo conoces de antemano.
O — escuchanos — puedes saltarte todo esto y dejar que ViciStack lo maneje en una noche. Migramos operadores de VICIdial a infraestructura bare-metal completamente optimizada con precision de AMD llegando al 92-96% desde el primer dia. Sin compilar Asterisk desde el codigo fuente. Sin depurar audio unidireccional a las 2 AM. Pero si quieres hacerlo tu mismo, sigue leyendo. Respetamos el espiritu DIY. Solo queremos que sepas que hay una mejor opcion cuando estes listo.
Que Cambio Realmente en 2024-2026 (Y Por Que Tu Guia Antigua Te Esta Mintiendo)
Saquemos esto del camino primero, porque si te saltas esta seccion y sigues un tutorial desactualizado, vas a perder unas buenas 6-8 horas antes de darte cuenta de que algo esta roto de raiz.
CentOS 7 esta muerto. Literalmente muerto. EOL junio 2024. Sin mas parches de seguridad, sin mas actualizaciones. Cada “guia de instalacion de VICIdial” de striker24x7, cada curso de Udemy, cada hilo de foro que dice yum install centos-release-scl — todo eso es ficcion historica ahora.
ViciBox salto de la v9 a la v12. Los numeros de version no son un error. ViciBox 12.0.2 salio en enero de 2025, corriendo sobre OpenSuSE Leap 15.6 con Asterisk 18, MariaDB 10.11.9, y PHP 8.2. ViciBox 13.0 ya esta en beta con OpenSuSE 16.0 y soporte para SELinux. Si estas siguiendo una guia que menciona ViciBox 8 o 9, estas leyendo historia antigua.
Asterisk 18 es ahora el estandar. El salto de Asterisk 13/16 a 18 trajo soporte PJSIP, mejor manejo de WebRTC, y mejor negociacion de codecs. Matt Florell confirmo oficialmente el soporte completo de Asterisk 18 en septiembre de 2025. Los parches especificos de VICIdial ahora apuntan exclusivamente a Asterisk 18 para nuevas instalaciones.
PHP 8.2 es estandar. El codigo de VICIdial con mas de 4 anos tirara advertencias de depreciacion o directamente se rompera en PHP 8.x. Las funciones mysql_* que tus viejos scripts de instalacion referencian desaparecieron desde PHP 7.0.
El trunk SVN esta en la revision 3939+, version 2.14b0.5, esquema de base de datos 1729. Todavia alojado en svn://svn.eflo.net:3690/agc_2-X/trunk porque el proyecto VICIdial no tiene planes de migrar a Git. Algunas cosas nunca cambian.
Esto es lo que significa en la practica: los unicos dos caminos que valen la pena para una nueva instalacion de VICIdial en 2026 son ViciBox 12.0.2 (recomendado) o una instalacion desde cero en AlmaLinux 9 / Rocky Linux 9. Todo lo demas es una perdida de tiempo.
Tu Guia Antigua Te Esta Mintiendo. Nosotros No.
ViciStack despliega VICIdial completamente optimizado en Asterisk 18, AlmaLinux 9, con cada problema pre-resuelto. Salta la Instalacion →
Hardware: Lo Que Realmente Necesitas (No Lo Que El Foro Te Dijo en 2015)
Hablemos de numeros reales. La documentacion de ViciBox 12 finalmente tiene especificaciones de dimensionamiento adecuadas, y son diferentes de lo que encontraras en posts viejos de foros.
Servidor Unico (La Configuracion “Tengo 10-25 Agentes”)
| Componente | Minimo | Recomendado |
|---|---|---|
| CPU | 4 nucleos @ 2.0+ GHz | 6+ nucleos @ 2.0+ GHz |
| RAM | 8 GB | 16 GB ECC |
| Almacenamiento | 160 GB SSD | 500 GB RAID1 SSD |
| Red | 1 Gbps | 1 Gbps dedicado |
Los SSDs son obligatorios en 2026. No recomendados — obligatorios. La documentacion de ViciBox establece explicitamente SATA SSD como el minimo. Si alguien intenta venderte un servidor VICIdial con discos mecanicos, o estan atascados en 2016 o no les importa que tus agentes se queden sentados esperando consultas de base de datos.
Un solo servidor Express maneja de manera realista 15-20 agentes outbound con marcacion predictiva activa, o aproximadamente 50 agentes solo-inbound bajo condiciones ideales. Una vez que pasas de 25 agentes outbound, estas jugando con fuego.
Cluster Multi-Servidor (La Configuracion “Realmente Estoy Manejando un Negocio”)
Cuando superas un solo servidor, VICIdial se divide en cuatro roles. Para la guia completa sobre arquitectura de cluster, planificacion de capacidad, y cada detalle de configuracion, consulta nuestra guia dedicada de clusters.
Servidor de base de datos — El cerebro. Uno por cluster, siempre. Para 150 agentes: 8+ nucleos, 32 GB de RAM ECC, NVMe RAID1.
Servidores de telefonia/marcador — Los pulmones. Cada uno maneja aproximadamente 25 agentes outbound con grabacion pesada y ratios de marcacion de 4:1.
Servidores web — La cara. 2-4 nucleos, 4-8 GB de RAM. SSL reduce la capacidad aproximadamente a la mitad debido al overhead de TLS.
Servidor de archivo — La memoria. Este es el unico lugar donde los discos mecanicos realmente estan bien.
Deja de Adivinar las Especificaciones del Servidor.
ViciStack provisiona bare metal construido a medida para tu numero exacto de agentes y ratio de marcacion. Obtener Tu Cotizacion Personalizada →
Metodo de Instalacion 1: ViciBox ISO (El Camino Sensato)
ViciBox es el ISO pre-construido oficial mantenido por Kumba (el desarrollador de ViciBox). Empaqueta OpenSuSE Leap 15.6, Asterisk 18, MariaDB, Apache, PHP, y VICIdial en una sola imagen booteable. Es el camino de menor resistencia y el que recomendamos para cualquiera que valore su tiempo.
Descarga e Inicio
Descarga ViciBox 12.0.2 de download.vicidial.com/iso/vicibox/server/. Dos sabores: Standard (disco unico, RAID por hardware, VMs) y MD (RAID1 por software entre dos discos). Graba en USB con Rufus o dd, inicia, y selecciona “Install ViciBox” del menu.
El instalador copia el sistema operativo al disco, inicias sesion como root, y te guia a traves de idioma, teclado, zona horaria, y contrasena de root. Reinicia cuando se te indique. Tiempo total: aproximadamente 10 minutos.
Configuracion Pre-VICIdial (No Te Saltes Esto)
Antes de tocar VICIdial, asegura tu red. La configuracion de VICIdial esta permanentemente ligada a la direccion IP de tu servidor — cambiarla despues es una cirugia dolorosa en multiples archivos.
Establece una IP estatica:
yast lan
Selecciona tu interfaz, elige “Statically assigned IP Address,” ingresa la IP/subred/gateway, y establece DNS. Presiona ALT-O para aplicar. Verifica con ping -4 google.com.
Establece la zona horaria (usa el comando de ViciBox, no yast):
vicibox-timezone
El comando regular de yast para zona horaria no actualiza la zona horaria de PHP. Preguntame como lo se.
Actualiza el sistema:
zypper ref
zypper up
reboot
Advertencia critica: Siempre zypper up, nunca zypper dup. El comando dup (actualizacion de distribucion) puede degradar MariaDB o romper la compatibilidad con DAHDI. Multiples posts del foro documentan esto destruyendo sistemas de produccion.
Instala VICIdial (El Milagro de Un Solo Comando)
Para un servidor unico con 20 o menos agentes:
vicibox-express
Escribe Y. Espera. Reinicia. Eso es todo. VICIdial esta corriendo.
Verifica con screen -ls — deberias ver 10-12 sesiones de screen. Accede a http://<IP-de-tu-servidor>/vicidial/welcome.php con las credenciales por defecto 6666 / 1234 y estaras viendo un marcador funcionando.
Para un cluster, ejecuta vicibox-install en cada servidor (base de datos primero, luego web, luego telefonia), selecciona que roles habilitar, y apunta los servidores que no son DB a la IP del servidor de base de datos. Mismo proceso, solo repetido.
El Unico Bug Que Necesitas Arreglar Inmediatamente
ViciBox 12 viene con una version de MariaDB que deprecio el comportamiento implicito de TIMESTAMP. Esto puede romper tablas silenciosamente. Arreglalo antes de hacer cualquier otra cosa:
echo "explicit_defaults_for_timestamp = Off" >> /etc/my.cnf.d/general.cnf
systemctl restart mariadb.service
ViciBox Te Pone en Marcha. ViciStack Te Da Resultados.
Vamos mas alla de la instalacion — ajuste de AMD, gestion de DID, optimizacion de carriers, todo incluido. Ver la Diferencia →
Metodo de Instalacion 2: Instalacion Desde Cero en AlmaLinux 9 (El Camino del Controlador)
Algunas personas necesitan Linux de la familia RHEL. Algunas personas quieren entender cada componente. Algunas personas simplemente disfrutan compilar software desde el codigo fuente un viernes por la noche. No juzgamos.
La mejor opcion en 2026 es el auto-instalador de carpenox mantenido por Chris en CyburDial/Dialer.one. Es el script comunitario mas activamente mantenido y maneja AlmaLinux 9 + Rocky Linux 9 con Asterisk 18:
timedatectl set-timezone America/New_York
yum check-update && yum update -y
yum -y install epel-release && yum update -y
yum install git kernel* --exclude=kernel-debug* -y
sed -i 's/SELINUX=enforcing/SELINUX=disabled/g' /etc/selinux/config
cd /usr/src
git clone https://github.com/carpenox/vicidial-install-scripts.git
reboot
cd /usr/src/vicidial-install-scripts
chmod +x alma-rocky9-ast18.sh
./alma-rocky9-ast18.sh
SELinux debe estar deshabilitado. Esto no es negociable. Los scripts Perl de VICIdial, las operaciones de archivo de Asterisk, y la configuracion de Apache asumen que SELinux esta desactivado. Cada guia de instalacion desde cero comienza deshabilitandolo.
El script maneja la instalacion de dependencias, la compilacion de Asterisk 18 con los parches de VICIdial, DAHDI, LAME, Jansson, checkout de VICIdial por SVN, configuracion de base de datos, configuracion de crontab, y scripts de inicio. Los cinco parches especificos de VICIdial para Asterisk (estadisticas de AMD, estado de peer IAX, logging de peer SIP, y dos parches de reinicio de timeout) se aplican automaticamente.
Post-Instalacion: De “Esta Corriendo” a “Estamos Haciendo Llamadas”
Aqui es donde cada otra guia en internet se detiene. “Felicitaciones, instalaste VICIdial! Aqui hay una captura de pantalla de la pagina de login. Buena suerte!” No ayuda. Vamos a configurar esto de verdad.
Asegura los Valores por Defecto (Haz Esto Primero)
VICIdial viene con valores por defecto que son tambien agujeros de seguridad:
mysqladmin -u root password 'ALGO_FUERTE'
test. Si, en serio. Configurando Tu Troncal SIP
Aqui es donde la mayoria de las instalaciones DIY se atascan. Necesitas un carrier VoIP para realmente hacer llamadas telefonicas, y la configuracion de carriers de VICIdial tiene algunas particularidades no obvias.
Navega a Admin → Carriers → Add A New Carrier. Para un trunk autenticado por IP (la mayoria de los carriers empresariales):
Account Entry:
[tu-carrier]
disallow=all
allow=ulaw
allow=g729
type=peer
insecure=port,invite
host=sip.tucarrier.com
dtmfmode=rfc2833
context=trunkinbound
canreinvite=no
Dialplan Entry:
exten => _91NXXNXXXXXX,1,AGI(agi://127.0.0.1:4577/call_log)
exten => _91NXXNXXXXXX,2,Dial(${CARRIER}/${EXTEN:1},60,tTor)
exten => _91NXXNXXXXXX,3,Hangup
Global String: CARRIER=SIP/tu-carrier
El prefijo 9 es una convencion de dial string — cuando tu campana usa el prefijo de marcacion 9, VICIdial lo antepone a cada numero, y el dialplan lo elimina antes de enviarlo al carrier. Verifica tu trunk con:
asterisk -rx "sip show registry"
asterisk -rx "sip show peers"
Consejo profesional de operar 100+ centros VICIdial: La atestacion STIR/SHAKEN importa enormemente en 2026. Necesitas atestacion de nivel A, lo que requiere que tus DIDs y la terminacion esten en el mismo carrier. El enfoque dual-stack te da redundancia mientras mantienes nivel A en ambos.
La Configuracion del Carrier Es Donde Las Instalaciones DIY Van a Morir.
Una configuracion incorrecta de STIR/SHAKEN = “Posible Spam” en una semana. ViciStack configura tus carriers correctamente desde el primer dia. Hazlo Bien →
Creando Tu Primera Campana
Admin → Campaigns → Add a New Campaign. La configuracion critica es el Dial Method:
Configuraciones clave para establecer desde el inicio: Hopper Level (100-200 leads pre-cargados), Dial Timeout (26-30 segundos — depende del carrier), Available Only Tally = Y (solo marcar cuando los agentes estan realmente disponibles), y Auto Dial Level (empieza en 1.5 para modos adaptativos y ajusta basado en rendimiento). Para el desglose completo de cada configuracion del marcador que importa, consulta nuestra guia dedicada.
Cargando Leads
Lists → Add A New List → asigna a tu campana → Lists → Load New Leads. Sube un CSV con como minimo: phone_number, first_name, last_name, state. Siempre prueba con un lote pequeno primero. El cargador de leads de VICIdial es potente pero implacable con problemas de formato.
Configuracion del Telefono del Agente
Dos opciones en 2026:
Softphone SIP (MicroSIP, Zoiper, X-Lite): Crea un telefono en Admin → Phones con una extension (ej., 1001), IP del servidor, y contrasena de registro. El agente configura su softphone con estas credenciales. Funciona, pero requiere software en cada maquina de agente.
WebRTC/ViciPhone (la forma moderna): Requiere SSL/TLS en tu servidor web y el puerto 8089 abierto. Configura con vicibox-ssl en ViciBox, o certbot en instalaciones desde cero. Habilita plantillas de telefono WebRTC en Admin, establece los telefonos en “As Webphone = Y,” y los agentes obtienen un telefono basado en navegador integrado directamente en la interfaz del agente. Sin instalaciones de software, funciona desde cualquier lugar. Asi es como la mayoria de las operaciones remotas funcionan en 2026.
Clustering Multi-Servidor: Las Reglas Que Nadie Escribe
Una vez que creces mas alla de 20-25 agentes outbound, necesitas un cluster. Aqui estan las reglas que te salvaran del cementerio de posts de clusters rotos del foro:
Regla 1: Un proceso adaptativo, un servidor. El proceso AST_VDadapt (keepalive 5) gestiona el algoritmo predictivo. Corre en exactamente un servidor en todo el cluster. Ejecutarlo en dos servidores causa conflictos de nivel de marcacion que parecen abandonos aleatorios. Lo mismo aplica para AST_VDauto_dial_FILL (keepalive 7).
Regla 2: Misma LAN, sin routers. Todos los servidores del cluster deben estar en la misma red local con latencia de menos de 1ms. Un router entre tus servidores de base de datos y marcador agrega suficiente latencia para romper las sesiones de los agentes. Usa IAX2 (no SIP) para trunks inter-servidor.
Regla 3: NTP desde una sola fuente. Todos los servidores sincronizan sus relojes al servidor de base de datos o a una fuente NTP designada. La sincronizacion NTP independiente a servidores externos causa desviacion del reloj que rompe sesiones de agentes, desconecta llamadas, y corrompe reportes.
Regla 4: Conoce tu techo. Las tablas MEMORY de VICIdial son de un solo hilo. Un cluster llega al maximo alrededor de 450-500 agentes. Planifica tu crecimiento de acuerdo a esto.
Cuando Agregar Que
| Llegas a… | Agregas… |
|---|---|
| 20 agentes outbound | Separar DB de telefonia |
| 25 agentes mas | Segundo servidor de marcacion |
| 50+ agentes | Servidor de DB dedicado |
| 70+ agentes | Servidor web dedicado |
| 150+ agentes | Base de datos esclava para reportes |
| 450+ agentes | Segundo cluster |
Regla #1 del Clustering: No Lo Aprendas Por Las Malas.
Hemos construido mas de 100 clusters. Que nuestras cicatrices salven tu fin de semana. Habla con un Experto en Clusters →
El Salon de la Fama de la Resolucion de Problemas
Estos son los problemas que llenan los mas de 13,400 hilos de soporte del foro de VICIdial. Aprende del dolor de otros:
Sin audio / audio unidireccional — 80% de probabilidad de que el firewall este bloqueando UDP 10000-20000 (puertos RTP). 15% de probabilidad de que falta un externip en sip.conf. 5% de probabilidad de que sea SIP ALG en un router NAT. Deshabilita temporalmente el firewall y prueba. Si el audio funciona, es el firewall.
“No available sessions” — Las extensiones de conferencia no estan pobladas para la IP de tu servidor. Admin → Conferences → Show VICIDIAL Conferences. Cada servidor necesita su propio rango de conferencias.
Grabaciones faltantes — Verifica todo el pipeline: esta SOX instalado? La grabacion de campana esta en ALLCALLS? Estan corriendo los cron jobs? Revisa /var/spool/asterisk/monitor/ para archivos crudos. La configuracion de grabacion a nivel de usuario puede sobreescribir silenciosamente la configuracion de campana — verifica ambas.
Advertencia de desajuste de esquema de base de datos — Actualizaste el codigo SVN pero olvidaste la base de datos. Ejecuta:
mysql -p -f --database=asterisk < /usr/src/astguiclient/trunk/extras/upgrade_2.14.sql
La Verdad Honesta Sobre VICIdial DIY vs. Administrado
Mira, escribimos toda esta guia porque creemos en la transparencia. VICIdial es un software increible. Es gratuito, es potente, y en las manos correctas, supera a marcadores que cuestan 10 veces mas.
Pero “las manos correctas” esta haciendo mucho trabajo pesado en esa oracion.
Manejar VICIdial tu mismo significa que eres el administrador de sistemas, el DBA, el ingeniero de telefonia, el auditor de seguridad, y el gerente de relaciones con carriers. Cuando Asterisk se cae a las 9 AM un lunes y 50 agentes estan sentados sin hacer nada, tu eres el que esta en la terminal. Cuando tus DIDs se marcan como spam y tus tasas de conexion caen un 40%, tu eres el que esta llamando a los carriers.
ViciStack existe porque hemos hecho esto mas de 200 veces. Hemos construido y vendido mas de 200 call centers. Hemos contratado mas de 10,000 agentes. Hemos pasado mas de 15 anos aprendiendo cada peculiaridad de VICIdial, cada trampa de Asterisk, cada optimizacion de carrier que mueve la aguja.
Esto es lo que entregamos que esta guia no puede:
Leiste Toda la Guia. Respeto.
Ahora imagina saltarte todo y hacer llamadas manana. Eso es ViciStack. Obtener Tu Prueba de Concepto Gratuita →
Recursos Esenciales (Marca Estos Como Favoritos)
Esta guia es mantenida por ViciStack y actualizada a medida que el ecosistema de VICIdial evoluciona. Ultima verificacion contra ViciBox 12.0.2 y VICIdial SVN trunk 2.14b0.5, marzo 2026. Encontraste algo desactualizado? Dinoslo.
Publicado por ViciStack — la plataforma administrada de VICIdial construida por operadores, para operadores.
Si estas corriendo un call center VICIdial en 2026 y piensas que STIR/SHAKEN es solo otra casilla de cumplimiento que puedes ignorar con seguridad — felicitaciones, estas a punto de aprender como se siente una caida del 50% en tasas de respuesta.
La realidad incomoda que nadie en la comunidad VICIdial esta explicando con suficiente claridad: el cumplimiento de STIR/SHAKEN es necesario pero ni de lejos suficiente. Conseguir que tus llamadas se firmen con atestacion de nivel A es la Capa 1 de un stack de cumplimiento y reputacion de 13 capas. La mayoria de los operadores de VICIdial se detienen en la Capa 1 y luego se preguntan por que sus numeros se marcan como “Posible Spam” a los seis dias de una campana.
Que Hace Realmente STIR/SHAKEN (Y Que No)
STIR/SHAKEN es un framework de autenticacion criptografica de llamadas. Eso es todo. STIR (Secure Telephone Identity Revisited) define los estandares IETF (RFC 8224, 8225, 8226) para firmar digitalmente llamadas telefonicas. SHAKEN es el framework de despliegue norteamericano construido sobre esos estandares.
Cuando tu servidor VICIdial dispara un SIP INVITE a traves de Asterisk, esa llamada llega a tu proveedor de troncal SIP. Su Authentication Service (STI-AS) mira tres cosas: Te conocen (KYC)? Te asignaron este numero de telefono? La llamada se origino en su red?
La concepcion erronea critica que les cuesta dinero a los operadores de VICIdial cada dia: STIR/SHAKEN NO bloquea llamadas. NO etiqueta llamadas como spam. Autentica identidad. Punto.
Las decisiones reales de bloqueo y etiquetado? Esas las toman los motores de analytics de los carriers — Scam Shield de T-Mobile (impulsado por First Orion), ActiveArmor de AT&T (impulsado por Hiya), y Call Filter de Verizon (impulsado por TNS). Estos tres sistemas controlan la reputacion de llamadas para mas de 200 millones de suscriptores inalambricos de EE.UU., y actualizan sus modelos cada seis minutos.
Los Tres Niveles de Atestacion y Por Que Solo Uno Importa
Full Attestation (A): Tu carrier verifico tu identidad, tu eres dueno del numero, y la llamada empezo en su red. Este es el unico nivel que mueve la aguja en entregabilidad.
Partial Attestation (B): Tu carrier te conoce, pero no puede confirmar que eres dueno del numero especifico. Los datos de la industria muestran que las llamadas con atestacion B y C son aproximadamente tres veces mas propensas a ser marcadas como robocalls.
Gateway Attestation (C): Tu carrier no sabe de donde vino la llamada. Las llamadas con nivel C estan funcionalmente muertas al llegar.
La regla de oro: Compra tus DIDs directamente de tu proveedor de troncal SIP. Si el carrier asigno el numero y estas enviando la llamada desde su red, eso es automaticamente nivel A.
Tu Eleccion de Carrier Es Todo el Juego
VICIdial no implementa STIR/SHAKEN. Tu carrier lo hace.
Tu carrier debe tener:
Tus Configuraciones de VICIdial Estan Alimentando los Algoritmos de Spam
La conexion que nadie hace con suficiente explicitud: la configuracion de tu campana de VICIdial genera patrones de llamadas especificos que los motores de analytics de carriers interpretan como firmas de spam.
AMD es el asesino silencioso de reputacion. Cuando el modulo AMD de Asterisk detecta un saludo de buzon de voz y desconecta despues de 2-3 segundos de analisis de audio, genera volumenes masivos de llamadas de muy corta duracion. Las llamadas de menos de 30 segundos son la senal de spam mas fuerte en los algoritmos de carriers.
Tu metodo de marcacion importa mas de lo que piensas. RATIO a 3:1 con 10 agentes dispara 30 llamadas simultaneas. ADAPT_AVERAGE produce el patron de trafico mas suave.
Configuraciones optimas de VICIdial para gestion de reputacion:
Dial Method:           ADAPT_AVERAGE
Auto Dial Level:       1.0  (dejar que adapt lo suba)
Adaptive Drop %:       2.0
Drop Action:           MESSAGE
Drop Exten:            8304  (grabacion safe harbor)
Dial Timeout:          28
Available Only Tally:  Y
Calls per DID per day: 75   (bajo configuraciones de DID Rotation)
El Stack Completo de Cumplimiento: 13 Capas, No Solo 1
La Cadena de Entregabilidad:
La Cadena de Cumplimiento Legal:
Para un centro de 50 puestos, el cumplimiento minimo viable corre $3,000-$5,000/mes. El stack completo recomendado llega a $10,000-$18,000/mes.
Eso suena caro hasta que calculas la alternativa. El no cumplimiento le cuesta a un centro de 50 puestos un estimado de $143,000-$768,000 por mes en conexiones perdidas, salarios de agentes desperdiciados, desgaste acelerado de DIDs, y costos de remediacion.
El Camino de Implementacion en VICIdial: Tu Manual de 90 Dias
Semana 1-2: Auditoria de Carrier
Semana 3-4: Higiene de Numeros
Semana 5-8: Configuracion de VICIdial
Semana 9-12: Monitoreo y Optimizacion
90 Dias Es Mucho Tiempo. Nosotros Podemos Hacerlo en 48 Horas.
ViciStack migra toda tu operacion a infraestructura optimizada y en cumplimiento de la noche a la manana. Inicia Tu Migracion →
La Linea Final
STIR/SHAKEN es el sistema operativo de la entregabilidad de llamadas moderna. No es toda la historia — es la Capa 1 de 13 — pero sin el, nada mas importa.
Los operadores que construyan el stack completo de cumplimiento y gestion de reputacion ahora veran tasas de respuesta, tasas de conversion, e ingresos por puesto que hacen que la inversion sea evidente por si misma. Los operadores que sigan tratando STIR/SHAKEN como problema de alguien mas se encontraran gastando mas dinero para llegar a menos personas hasta que la economia colapse por completo.
Deja de adivinar. Empieza a construir. Contacta a ViciStack →
ViciStack es la plataforma administrada de VICIdial que maneja cumplimiento STIR/SHAKEN, optimizacion de carriers, gestion de reputacion de numeros, y configuracion del marcador — para que tus llamadas realmente conecten.
Our Agent’s #1 Failure Mode: Thinking
Thirty-three tasks. Four projects. $32.93. Time to read the spreadsheet.
MissionControl has been running for a week. Quick context if you’re just joining: autonomous dev agent. Describe a coding task in Telegram, it spawns a Claude Code session, builds the feature, opens a PR on GitHub. Post 1 covered the 16-hour build. Posts 2 through 5 covered the bugs, the trust chain, the architecture, and a task that deployed a full MVP then got marked as failed. All anecdotal. Now there’s enough data to stop telling stories and start reading spreadsheets.
The Raw Numbers
| Metric | Value |
|---|---|
| Tasks created | 33 |
| Completed | 12 (36%) |
| Failed | 19 (58%) |
| Cancelled | 2 (6%) |
| Total spend | $32.93 |
36% completion rate. Worse than the 50% reported after 20 tasks. But the raw number lies — it’s weighed down by early infrastructure failures that no longer exist. Strip those out and the picture changes.
Where the Money Went
Not all failures are equal. Some cost pennies. One category cost almost $9.
“No commits produced” — 5 tasks, $8.88
The real failure mode. Five tasks where Opus ran for its full budget or turn limit and produced zero commits. Tasks #20, #23, #25, #27, #29 — all greenfield builds (“Build a full-stack…”) on $2 budgets.
The pattern is consistent: Opus starts by reading the entire codebase. Then it plans. Then it plans more. Explores alternative approaches. Considers edge cases it will never hit. By the time it’s ready to write code, the budget is gone.
$8.88 burned on thinking. Not a single line committed.
API and infra failures — 10 tasks, $0.69
Ten tasks failed on infrastructure issues — all fixed since. Anthropic API 500s during early testing (4 tasks, $0.69). Missing sudo, stale OAuth tokens, missing worker user (6 tasks, $0). Resolved in the first week. Noise in the data now.
Timeout — 1 task
Default timeout was too short for a full-stack build on a 2-core box. Bumped it. Hasn’t recurred.
CLI quirk — 1 task
--print combined with --output-format=stream-json silently requires --verbose. Without it, the CLI exits 1 with no useful error. Fixed in worker.ts.
The Funnel
Signal separated from noise:
33 total tasks
 - 10 infra/API failures (fixed, no longer relevant)
 -  2 cancelled
 -  1 timeout (fixed)
 -  1 CLI quirk (fixed)
 = 19 real attempts
 - 12 completed
 -  5 "no commits" (the actual problem)
 -  2 other failures
Strip the noise: roughly 63% on real attempts. Not bad for an autonomous agent with no human in the loop. But 5 tasks and $8.88 wasted on overthinking — that’s the leak.
Model Economics
| Model | Tasks | Cost | Avg/Task | Raw Success | Adjusted |
|---|---|---|---|---|---|
| Opus | 30 | $30.65 | $1.02 | 30% (9/30) | 50% (9/18) |
| Sonnet | 3 | $2.28 | $0.76 | 100% (3/3) | 100% (3/3) |
Three data points isn’t a sample size. But the pattern is worth noting.
Opus’s failure mode is overthinking. Reads everything, considers everything, plans extensively. On a constrained budget, that means it runs out of money before it writes code. On greenfield builds — where the codebase is small and the task is “just build it” — this is exactly wrong.
Sonnet’s strength is mechanical execution. Clear task, does the task. No exploration spirals. No alternative-architecture tangents. Three tasks, three completions, $0.76 average.
This isn’t “Sonnet is better.” It’s match the model to the task shape. Opus for complex modifications to large codebases where understanding context matters. Sonnet for greenfield builds and mechanical fixes where the path is clear.
Three Changes We Made
The data pointed to three specific interventions. Shipped all three before starting the next batch.
1. Doubled All Budgets
| Parameter | Old | New |
|---|---|---|
| Default task budget | $5 | $10 |
| Max task budget | $10 | $20 |
| Daily budget cap | $50 | $100 |
The hypothesis: “no commits produced” isn’t an intelligence failure — it’s a budget failure. Opus needs room to think and build. At $2, it can do one or the other. At $4-10, it can do both.
This is a bet. If doubling budgets converts those five failures into completions, the ROI is obvious — spending $4 to get working code beats spending $2 to get nothing. If it doesn’t, we have a deeper problem that money won’t fix.
2. Two-Phase Reviews
Single-phase reviews were inconsistent. Task #33 came back with “Done” and no detail. Task #31 found a real bug. Same prompt, different quality. Split analysis from execution.
Phase 1 — Opus analyzes. Read-only access. Reviews the PR diff against a structured checklist: logic errors, security, styling, imports, TypeScript compliance. Outputs a machine-readable verdict:
<!-- REVIEW_VERDICT {"approved": false, "issues": [
  "src/components/VotingPanel.tsx:42 — duplicate accent color logic",
  "src/components/Icon.tsx — missing style?: CSSProperties prop"
]} -->
Budget: $1.50. Model: Opus. Tools: read-only (Bash, Read, Glob, Grep).
Phase 2 — Sonnet fixes. If Phase 1 finds issues, a child task is auto-created. Sonnet gets the issue list, fixes each one, runs tsc --noEmit and npm run build, commits, and pushes.
Budget: $1.00. Model: Sonnet. Tools: full access.
Already caught real bugs in production PRs. The duplicate accent color in VotingPanel would have shipped. The missing style prop on icon components would have caused runtime issues in any consumer passing inline styles. Total review cost: $2.50 for analysis plus fixes — cheaper than a single Opus task that might or might not find anything.
3. Commit-Early Culture
The lead dev prompt now emphasizes incremental commits over perfect final PRs. Old pattern: plan everything, build everything, commit once at the end. Budget runs out before that final commit — zero output.
New pattern: commit after each meaningful unit of work. A partial feature with three commits is infinitely more valuable than a complete feature with zero commits.
Can’t force the model to commit early — it’s guidance, not enforcement. But combined with higher budgets, the goal is to shift the failure mode from “zero output” to “partial output.” Partial output can be retried. Zero output is wasted money.
What We’re Watching
Batch 2 starts now. Three questions:
Does doubling budgets convert failures? If the five “no commits” tasks would have succeeded at $4-10, the completion rate will show it. If they still fail at higher budgets, the problem is in the prompt or the task shape, not the money.
Does two-phase review scale? Three review tasks isn’t a pattern. Need 15-20 to know if the structured verdict format is reliable and if Sonnet consistently fixes what Opus finds.
Can we auto-calibrate? A greenfield build and a one-line config change shouldn’t share a budget. Considering scope-size flags — small, medium, large — that auto-set budget and timeout based on expected complexity. Not built yet. Waiting for more data to set the thresholds.
The Takeaway
Thirty-three tasks taught us more than building the system did. The system works. The question was always “how well?” Now we know: ~63% on real attempts, with a clear #1 failure mode we can measure and attack.
Not crashes. Not bugs. Not infrastructure. The agent thinks too much and ships nothing. Solvable problem. Higher budgets give it room. Two-phase reviews separate thinking from doing. Commit-early guidance reduces the blast radius of a timeout.
$32.93 for 33 tasks and a clear roadmap for improvement. Not bad.
Next up: batch 2 results — did the changes work?
pgvector is the fastest way to add vector search to an existing PostgreSQL database. One extension, a few SQL commands, and you have similarity search running alongside your relational data. No new infrastructure. No new SDK. No vendor lock-in.
That simplicity is also its trap. Most teams add pgvector in a day and spend the next six months debugging performance issues that have nothing to do with the extension itself. The problems are almost always configuration mistakes that tutorials skip over.
Here are four I have seen break RAG pipelines in production, and how to fix each one before your team starts debating a migration to Pinecone.
No HNSW Index Means Full Table Scans
By default, pgvector performs exact nearest neighbor search. That means it scans every single row in the table on every query. For a prototype with 10,000 vectors, this is invisible. At 500,000 vectors, queries start crossing 800 milliseconds. At a million, you are looking at multi-second response times that make your RAG pipeline feel broken.
The fix is a single SQL statement: create an HNSW index on your vector column. HNSW (Hierarchical Navigable Small World) is an approximate nearest neighbor algorithm that trades a tiny amount of accuracy for massive speed improvements. After adding the index, the same 500K-vector query drops to under 50 milliseconds.
The reason this catches teams off guard is that pgvector works perfectly without the index. There is no warning, no error, no degradation signal. It just gets slower as data grows, and most teams blame the embedding model or the LLM before they check the database.
Dimensionality Is Not Free
OpenAI’s ada-002 embedding model outputs vectors with 1,536 dimensions. Each vector row in PostgreSQL consumes roughly 6 kilobytes of storage. Scale that to one million documents and you are looking at 6 gigabytes just for the embeddings column, before accounting for the HNSW index overhead, which can double or triple the total.
This matters because your AWS or cloud bill is not driven by the LLM API calls most teams obsess over. It is driven by the RDS instance size and storage needed to hold and index those vectors. A db.r6g.xlarge running pgvector with a million high-dimensional vectors costs real money every month.
The alternative is to use a smaller embedding model. Cohere’s embed-v3 outputs 384 dimensions and performs competitively on most retrieval benchmarks. That cuts storage by 75 percent and proportionally reduces index build time, memory usage, and query latency. Unless your use case specifically requires the nuance of 1,536 dimensions, smaller is almost always the right production choice.
Wrong Distance Function, Wrong Results
Most tutorials use cosine similarity as the default distance function, and most teams never question it. But pgvector supports three distance functions: cosine similarity, inner product, and L2 (Euclidean) distance. Each one measures “similarity” differently, and the choice directly affects which documents appear in your top-K results.
Cosine similarity measures the angle between vectors, ignoring magnitude. Inner product considers both direction and magnitude, which makes it the better choice when your embeddings are already normalized (as most modern embedding models produce). L2 distance measures the straight-line distance between vector endpoints, which works best when magnitude carries meaningful information.
The practical impact is real. I have seen cases where switching from cosine to inner product on the same dataset changed three of the top five results. If your RAG pipeline returns mediocre answers and you have already tuned your chunking strategy and prompt, check the distance function before anything else. It is a one-line configuration change that can transform result quality.
Know the Scaling Ceiling
pgvector is not a dedicated vector database. It is an extension that adds vector operations to PostgreSQL, and PostgreSQL was not designed to be a vector search engine at scale. In practice, pgvector handles up to about five million vectors comfortably on a db.r6g.xlarge instance with proper HNSW indexing. Past ten million vectors, expect query performance to degrade under concurrent load, and index build times to become a deployment bottleneck.
For most teams, this ceiling is not a problem. The majority of production RAG systems index fewer than five million documents. If you are in that range and already running PostgreSQL, adding pgvector is the right call. You avoid the operational complexity of a separate vector database, keep your data in one place, and eliminate an entire category of infrastructure to manage.
If you are genuinely approaching the ten million mark, look at pgvector-scale (which adds partitioning and distributed indexing) or evaluate a dedicated solution like Pinecone or Weaviate. But make that decision based on actual data volume, not on anxiety about future scale.
The Config Is the Bottleneck
The pattern I see repeated is predictable. Week one, a team adds pgvector and it works great. By month two, queries slow down and nobody thinks to check the index. By month four, someone proposes migrating to a managed vector database. By month six, a senior engineer adds one HNSW index and the problem disappears.
pgvector is a genuinely excellent tool for most production RAG systems. The mistakes that break it are not bugs or limitations. They are configuration gaps that tutorials gloss over and documentation buries. Fix the index, right-size the dimensions, pick the correct distance function, and know your scaling ceiling. That is the entire playbook.
What vector store is your team running in production right now?


When first starting a new project using Claude Code, it is easy to jump ahead, diving straight into coding. However, if you spend a bit of time setting up Claude Code, the outcome will be a smoother and more enjoyable development experience.
Generating a CLAUDE.md file
When first starting your project, spend time talking through the requirements of the project with Claude. Take into account your tech stack, What language are you writing it in? Are you using a framework?
You should also not only discuss the tech stack, but also how you want this built. How do you want the folder structure to be laid out? How do you want to interact with the database?
Here is a general list of things you might include:
The goal of this conversation is to produce a CLAUDE.md file — a markdown document that lives in your project root, that is automatically loaded into Claude’s context at the start of every session. It’s the source of truth that means you never have to re-explain your stack again.
What a CLAUDE.md looks like
Here’s an example CLAUDE.md file
# Project Blueprint

## Stack
- Language: PHP 8.3
- Framework: FlightPHP (micro-framework)
- Database: Postgres 18
- Coding standard: PSR-12

## Database Access
Use Flight PHP build in PDO wrapper with prepared statements exclusively.
All queries live inside the business logic — never in controllers.

## Folder Structure
app/
  Controllers/ # Thin controllers, Only reference Logic classes and UI
  Logic/       # Business logic
  config/      # Config files — DO NOT READ OR EDIT

## Code Style
Run PSR-12 checks via: vendor/bin/phpcs --standard=PSR12 app/
Auto-fix via:          vendor/bin/phpcbf --standard=PSR12 app/

## What NOT to do
- Never use static methods on service classes
- Never put SQL in controllers
- Never read from app/config/config.php
- Never commit directly — all git operations are manual
Once this file exists, every new Claude Code session starts with this context. Claude knows your conventions without being told.
The CLAUDE.md is a time saver when coding across multiple sessions. It also allows more frequent context clearing, which can help keep Claude Code focused on the current ask, lowering costs, and save time not having to explain design choices every session.
Items can also be added to the file as you come across issues and technical asks that may not have been in the CLAUDE.md file initially, building up a good repository of information that Claude can use to help build the application to your specifications.
We all have different ways of coding, and teaching Claude how you like to code through the CLAUDE.md file, will result in code similar to how you code yourself, which helps when reviewing the code, as it will seem familiar.
Guardrails
Claude Code is powerful, which is why it needs guardrails. Left unconstrained, an AI can read your environment files, touch your git history, run database commands, or make network requests you didn’t intend. None of that maliciously, just helpfully, and that’s the problem.
The permissions system in Claude Code lets you define exactly what it can and cannot do, locked into your project’s .claude/settings.json. The deny list is your non-negotiable safety layer.
There are three settings files:
These are hierarchical.
Managed-settings.json is the top tier, It lives outside the repo.
| OS | Path |
|---|---|
| macOS | /Library/Application Support/ClaudeCode/managed-settings.json |
| Linux | /etc/claude-code/managed-settings.json |
| Windows | C:ProgramDataClaudeCodemanaged-settings.json |
Instructions in the managed-settings.json cannot be overridden by instructions in the repo level json files.
The difference between these is that settings.json is shared across developers in a multi developer setup, while settings.local.json is intended for individual developer instructions.
In a business setting, putting the most critical instructions in the managed-settings.json, and limiting the use of settings.json & settings.local.json, sets the system for success. While as an individual developer, just using the settings.local.json file might be sufficient.
What belongs on the deny list
Environment files & secrets
Your .env, .env.*, certificates (.pem, .key, .p12), and SSH/AWS credential folders should be completely off-limits. Claude has no reason to read them. With config files, creating a sample config with no secret keys set is useful for giving Claude access to the config structure without giving access to the keys.
Destructive git operations
Block git commit, git push, git merge, git reset, git clean, and anything else that writes to your history. You own the git history, not Claude. Every commit should be decided on and controlled by a person. This allows for code reviewing prior to committing the code.
Direct database access
No mysql, psql, pg_dump, mysqldump, or any other direct database CLI commands. Claude should generate migration files and queries in code, not run commands directly against your data.
Network and remote access
Block curl, wget, ssh, scp, rsync, and similar tools. Claude should fetch docs through approved WebFetch domains, not make arbitrary outbound calls.
System-level commands
rm, sudo, chmod, chown, kill, crontab — anything that can damage your system or escalate privileges.
The full settings file
The allow list is just as important as the deny list. It gives explicit permission for the tools you do want Claude to be able to run. Fetching framework docs, requiring Composer packages, running your linter etc.
Special Note
Within a settings file, DENY instructions override ALLOW instructions, however when there is a hierarchy of settings files, the higher priority files instructions override the instructions from lower priority files. If something is denied in managed-settings.json, adding an ALLOW in settings.json will not override the denial in managed-setting.json
{
  "permissions": {
    "allow": [
      "Bash(composer require:*)",
      "Bash(vendor/bin/phpcbf --standard=PSR12 app/)",
      "Bash(vendor/bin/phpcs --standard=PSR12 app/)"
    ],
    "deny": [
      "Read(app/config/config.php)",
      "Edit(app/config/config.php)",
      "Read(.env)",
      "Edit(.env)",
      "Read(**/*.pem)",
      "Read(**/*.key)",
      "Read(**/*.p12)",
      "Read(**/*.pfx)",
      "Read(~/.ssh/**)",
      "Read(~/.aws/**)",
      "Read(./.git/**)",
      "Bash(git commit:*)",
      "Bash(git push:*)",
      "Bash(git merge:*)",
      "Bash(git rebase:*)",
      "Bash(git reset:*)",
      "Bash(git clean:*)",
      "Bash(git branch -d:*)",
      "Bash(git branch -D:*)",
      "Bash(git tag -d:*)",
      "Bash(git stash drop:*)",
      "Bash(git stash clear:*)",
      "Bash(git remote add:*)",
      "Bash(git remote remove:*)",
      "Bash(git remote set-url:*)",
      "Bash(git config --global:*)",
      "Bash(rm:*)",
      "Bash(rmdir:*)",
      "Bash(shred:*)",
      "Bash(dd:*)",
      "Bash(mkfs:*)",
      "Bash(fdisk:*)",
      "Bash(curl:*)",
      "Bash(wget:*)",
      "Bash(nc:*)",
      "Bash(netcat:*)",
      "Bash(nmap:*)",
      "Bash(telnet:*)",
      "Bash(ftp:*)",
      "Bash(sftp:*)",
      "Bash(scp:*)",
      "Bash(rsync:*)",
      "Bash(ssh:*)",
      "Bash(mysql:*)",
      "Bash(mysqldump:*)",
      "Bash(mysqlimport:*)",
      "Bash(mariadb:*)",
      "Bash(mariadb-dump:*)",
      "Bash(psql:*)",
      "Bash(pg_dump:*)",
      "Bash(pg_restore:*)",
      "Bash(pg_dumpall:*)",
      "Bash(redis-cli:*)",
      "Bash(sudo:*)",
      "Bash(su:*)",
      "Bash(chmod:*)",
      "Bash(chown:*)",
      "Bash(passwd:*)",
      "Bash(useradd:*)",
      "Bash(usermod:*)",
      "Bash(crontab:*)",
      "Bash(kill:*)",
      "Bash(pkill:*)"
    ]
  }
}
The pattern to remember: tight allow, broad deny. Explicitly permit the specific tools Claude needs; broadly block everything that could cause harm if run without your supervision.
Custom Commands
Custom commands are saved prompts you can used during any session to run a repeatable, structured action across your codebase.
The most valuable commands aren’t about generating code, they’re about reviewing what’s been built. Running a security audit through a project catches problems before they’re buried under layers of new code.
Custom commands live in .claude/commands/ as markdown files. Each file is a detailed prompt that Claude executes when you invoke the slash command.
Claude Code itself can help you draft these command files efficiently.
Commands worth building
/security-audit
Reviews all files in the application for SQL injection risks, unvalidated input, missing authentication checks, insecure direct object references, and exposed error messages. Outputs a prioritised list of findings with file and line references.
/architecture-review
Checks that the business rules are being followed.
/update-claude
“Review what we have just discussed and update CLAUDE.md with any new architectural patterns or ‘What not to do’ rules we have discovered”.
Example: the security audit command
Perform a security audit on the PHP codebase in app/.

Check for the following issues and report each with file
path, line number, and severity (high/medium/low):

1. SQL injection risks — any string concatenation in
   queries, any unparameterised input
2. Missing input validation — user-supplied data used
   without sanitisation or type checking
3. Authentication gaps — routes or methods that should
   require auth but don't check for a session
4. IDOR risks — fetching records by ID without verifying
   the current user owns that record
5. Verbose error exposure — raw exceptions or stack
   traces that could leak system details

Output format:
[SEVERITY] File: path/to/file.php (line N)
Issue: description
Fix: recommended action

Do not fix anything — report only. Fixes happen
in a separate pass once the full list is reviewed.
Run audits often. The best time to run a security audit is not at the end of the project , it’s during the project development. Issues caught early are easy to fix. Issues caught after three months of layered code become complex.
Claude Ignore
Similar to .gitignore, there is a .claudeignore file. Entries in the .claudeignore tells Claude that the files and folders listed are not relevant.
Folders like node_modules, vendor, logs, caches etc would be good one to add to .claudeignore.
.claudeignore is not a replacement for settings.json. Claude can still read items listed in .claudeignore, You can still ask Claude to read them to gain context.
.claudeignore saves you tokens by not having Claude read the files upfront.
Context Compacting
As a Claude Code session grows longer, it will eventually compact, compressing older parts of the conversation to free up context window space. Claude does its best to preserve what matters, but compacting loses context. Architectural decisions made three hours ago, the reasoning behind a particular pattern choice, all of that is at risk of being quietly forgotten.
This is where the CLAUDE.md file helps.
Because CLAUDE.md is loaded at the start of every session, and re-read whenever Claude needs to orient itself , your core context is never actually lost to compacting. It doesn’t live in the conversation history. It lives in the file.
Compacting can chew through hours of back-and-forth . Your architecture conventions are still right there, intact, waiting to be loaded again.
In long conversations, you may want to update the CLAUDE.md file with new information that came about during the conversation.
This can change how you work. Instead of using a single long session and worrying about context drift, you can:
/clear freely and often to start fresh without losing your architectural contextWorking in small, focused sessions with frequent clears is actually a healthier pattern than one long marathon session anyway. It forces you to scope tasks tightly, keeps the context window lean, and means Claude is always working with fresh, uncluttered context.
Time to code
With CLAUDE.md setup, and your system secured, you’ve created a safe space for Claude Code to be genuinely excellent.
This lets you focus on working through the architecture and delivering a quality product.
Setting up Claude Code isn’t about restricting the AI, it’s about defining the playing field so you can stop worrying about the boundaries and start focusing on the architecture.
I've been building AegisFlow, an open-source AI gateway in Go. It sits between your apps and LLM
  providers (OpenAI, Anthropic, Ollama, etc.) and handles routing, security, rate limiting, and
  observability.

  Yesterday I sat down and did a proper security audit of the whole thing. Found more issues than I'd
  like to admit.

  The security stuff

  Timing attacks on API key validation. The tenant key lookup was using plain string comparison. An
  attacker could measure response times to progressively guess keys character by character. Switched
  to SHA-256 hashing both sides and comparing with subtle.ConstantTimeCompare. Also iterates all
  tenants on every check so there's no early-exit timing leak.

  inputHash := sha256.Sum256([]byte(apiKey))
  var match *TenantConfig
  for i := range c.Tenants {
      for _, key := range c.Tenants[i].APIKeys {
          keyHash := sha256.Sum256([]byte(key))
          if subtle.ConstantTimeCompare(inputHash[:], keyHash[:]) == 1 {
              match = &c.Tenants[i]
          }
      }
  }

  Admin panel was open by default. If you didn't set admin.token in your config, every admin endpoint
  was unauthenticated. Usage stats, provider health, tenant config, policy rules — all exposed. An
  attacker could read your exact jailbreak keywords and craft prompts around them. Now it blocks all
  data endpoints when no token is configured and logs a warning at startup.

  Rate limiter was failing open. When the limiter errored (Redis down, memory issue), it silently let
  requests through. Flipped it to return 503 instead.

  Other fixes: 10MB request body limit (was unlimited — one curl command could OOM the process), SSE
  injection in streaming responses (policy violation messages were string-concatenated into the event
  stream instead of JSON-serialized), and response cache was keyed by model+messages but not tenant
  ID, so tenant A could get tenant B's cached response.

  Jailbreak detection got real

  The keyword filter had 3 patterns. That's not a filter, that's a suggestion. Expanded to 25 covering
   the common techniques.

  But the bigger fix: added NFKC Unicode normalization. Before this, someone could write "іgnore
  previous instructions" with a Cyrillic і and walk right past the filter. Or add extra spaces:
  "ignore  previous  instructions". The normalizeText function now handles both:

  func normalizeText(s string) string {
      s = norm.NFKC.String(s)
      s = strings.Map(unicode.ToLower, s)
      s = multiSpaceRe.ReplaceAllString(s, " ")
      return strings.TrimSpace(s)
  }

  WASM plugin support

  This is the part I'm most excited about. You can now write custom policy filters in any language
  that compiles to WebAssembly and load them at runtime through config.

  policies:
    input:
      - name: "custom-toxicity"
        type: "wasm"
        action: "block"
        path: "plugins/toxicity.wasm"
        timeout: 100ms
        on_error: "block"

  The plugin ABI is four exported functions:

  ┌───────────────────────────────────────────────────┬───────────────────────────────────────────┐
  │                      Export                       │               What it does                │
  ├───────────────────────────────────────────────────┼───────────────────────────────────────────┤
  │ alloc(size) → ptr                                 │ Plugin allocates memory for host to write │
  │                                                   │  inputs                                   │
  ├───────────────────────────────────────────────────┼───────────────────────────────────────────┤
  │ check(content_ptr, content_len, meta_ptr,         │ Main check. Returns 0 (allow) or 1        │
  │ meta_len) → i32                                   │ (violation)                               │
  ├───────────────────────────────────────────────────┼───────────────────────────────────────────┤
  │ get_result_ptr() → ptr                            │ Pointer to result JSON after violation    │
  ├───────────────────────────────────────────────────┼───────────────────────────────────────────┤
  │ get_result_len() → i32                            │ Length of result JSON                     │
  └───────────────────────────────────────────────────┴───────────────────────────────────────────┘

  The host passes request metadata as JSON (tenant ID, model, provider, phase) so plugins can make
  context-aware decisions. Config-level action always overrides whatever the plugin returns — a plugin
   can't escalate its own permissions.

  Runtime is wazero, pure Go, zero CGO. Each plugin gets its own timeout and on_error behavior (block
  or allow). If a plugin crashes or returns garbage JSON, the gateway handles it gracefully based on
  your config.

  Wrote a Go example plugin that blocks messages containing "forbidden":

  //go:wasmexport check
  func check(contentPtr *byte, contentLen uint32, metaPtr *byte, metaLen uint32) int32 {
      content := unsafe.String(contentPtr, contentLen)
      if strings.Contains(strings.ToLower(content), "forbidden") {
          result, _ := json.Marshal(map[string]string{
              "action":  "block",
              "message": "content contains forbidden word",
          })
          resultBuf = result
          return 1
      }
      return 0
  }

  Build it with GOOS=wasip1 GOARCH=wasm go build -o plugin.wasm . and point your config at it. No
  gateway recompilation.

  Live request feed

  Added a fifth page to the admin dashboard. Shows every request flowing through the gateway in real
  time — latency, status codes, cache hits, policy violations. Auto-refreshes every 2 seconds. Nothing
   fancy, but useful when you're debugging or demoing.

  What's next

  Phase 3: Kubernetes operator with CRDs, multi-region routing, and A/B testing for models. The goal
  is making this work across clusters, not just on a single node.

  Repo: github.com/saivedant169/AegisFlow

  57 tests, all passing with race detector. MIT licensed. If you're proxying LLM traffic and want
  something self-hosted, take a look.
I didn’t expect something as simple as setting a profile picture to turn into a full debugging session.
But that’s exactly what happened.
It started like any normal onboarding task. I had just set up my Fedora Account System account, everything was working fine, and I thought, “Let me quickly update my profile picture and move on.”
Simple, right?
I clicked “Change Avatar.”
I was redirected to Libravatar.
I logged in.
I uploaded my picture.
Done.
Or at least, that’s what I thought.
I went back to check my profile… and there it was, the same default avatar staring back at me like nothing had changed.
At first, I assumed it was just a delay. Maybe caching. Maybe I needed to refresh.
I refreshed.
Nothing.
I logged out and back in.
Still nothing.
That was the moment I realized this wasn’t just a small glitch. There was something deeper going on.
The Loop That Made It Worse
While trying to figure it out, I ran into another issue, the login loop.
At one point, instead of smoothly logging in, I kept getting prompted repeatedly for credentials. It felt like I was stuck between two systems that weren’t fully talking to each other.
That’s when I made a small but important decision, I cancelled the prompt.
And surprisingly, that worked.
It redirected me to the proper Fedora login page, and I was finally able to proceed cleanly.
It was my first clue that the problem wasn’t just about uploading an image… it was about how systems were connected.
Understanding the Real Problem
At this point, I stopped guessing and started thinking.
Libravatar wasn’t just storing images. It was linking identities.
And Fedora wasn’t just using usernames. It was relying on a specific identity mapping system — OpenID and email associations.
That’s when it clicked.
Uploading the image wasn’t enough.
The system needed a verified identity to attach it to.
The Fix That Finally Worked
Instead of trying to re-upload the image again, I took a different route.
I added a new email address inside Libravatar.
Then I verified it.
Came back. Refreshed.
And just like that — it worked.
The new profile picture finally showed up.
What I Learned
This wasn’t just about fixing an avatar issue.
It taught me something deeper about working in real systems:
Things don’t always fail loudly, sometimes they fail silently
Identity systems (OpenID, email mapping) matter more than they seem
Debugging isn’t about trying random fixes, it’s about understanding how things connect
Most importantly, I learned that the difference between being stuck and moving forward is often just one shift, from guessing to thinking.
Why I Decided to Document It
After solving it, I realized something:
If I ran into this, others definitely would too.
So instead of keeping the solution to myself, I turned it into a guide for the community, something simple, clear, and easy to follow.
Because in open source, solving a problem is good…
But making it easier for the next person?
That’s better.
If you’re interested in the documentation I prepared as a guide for resolving these issues, you can find it here