[27-29 Mart] Toplam Değeri Bin TL’yi Aşan 2 Oyun, Xbox’ta Bu Hafta Sonu Ücretsiz
Xbox Free Play Days kapsamında bu hafta ücretsiz olacak oyunlar açıklandı. Oyunseverler bu hafta da birbirinden eğlenceli oyunlara ücretsiz olarak erişebilecek.

 Mert
I run ArgoCD. Full GitOps — if it’s not in the repo, it doesn’t exist. That’s great for everything except secrets, where “if it’s in the repo, it might not exist for long either.” GitHub secret scanning will catch an API key in a private repo, helpfully disable it, and send you a polite notification that you messed up. So I needed an ESO backend. Here’s what I looked at.
Shopping Around
I was already applying secrets manually via kubectl — which works fine until it doesn’t, and doesn’t scale past “just me doing everything.” The plan was always to wire up External Secrets Operator; the question was just what it would point at.
SOPS came up first — a Claude recommendation. It encrypts secrets in-repo, which sounds elegant, but the decryption key has to live somewhere, and in practice that somewhere is the machine doing the decrypting. If that machine is compromised, the attacker gets the key, and the key opens everything. Security theater. My brain wanted something that felt like AWS Parameter Store — a place secrets live, accessed over an authenticated API, not a place they’re hidden inside something else with the unhiding tool sitting right next to them.
The second AI-generated recommendation was GitHub Actions Secrets. Which, sure — except my IaC repo has GitHub Actions in it. Secrets that live inside the same system they’re deploying feel like a liability waiting to happen. At this point it was clear I needed an actual secrets service, so I started shopping for an ESO backend.
AWS Secrets Manager, AWS Parameter Store, and OCI Vault were the clear, industry-standard options — the real products that do the job properly. But I’m running K3s on a free OCI ARM VM specifically because I want zero dependencies I can’t walk away from. If OCI’s free tier ever goes south, I want to pack up and leave — depending on OCI Vault would chain my secrets to the same cloud I’m trying to stay portable from. And pulling in AWS just for secrets would be adding a second cloud dependency for no reason.
I also stumbled upon Doppler, which I actually liked the look of. The DX is genuinely good, the CLI is pleasant, the UI is clean. Then I hit the pricing page: service accounts — the thing you need for any automated workflow — are a Team plan feature. $21/month per user. For just me. For secrets. No.
Then I found Infisical.
What Infisical Is
Infisical is an open-source secrets manager with a managed cloud offering and a self-hostable option. The cloud tier is genuinely free for reasonable usage. It has a UI, a CLI, SDKs, and first-class Kubernetes support — either via its own operator or as an External Secrets Operator backend, which is what I ended up using.
The Setup I Actually Use: ESO + Infisical Cloud
Rather than the Infisical operator, I went with External Secrets Operator (ESO) using Infisical as the backend. ESO is a CNCF project with a clean abstraction: you define a SecretStore (or ClusterSecretStore) pointing at your secrets backend, then ExternalSecret resources that describe which secrets to sync and where. The output is always a standard Kubernetes Secret. Swap out the backend someday and your app manifests don’t change.
Installing ESO via ArgoCD
I manage everything with ArgoCD, so the ESO install is an Application pointing at the official release manifest:
# applications/external-secrets/kustomization.yml
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
  - https://github.com/external-secrets/external-secrets/releases/download/v2.2.0/external-secrets.yaml
  - cluster-secret-stores.yml
The ArgoCD Application itself:
apiVersion: argoproj.io/v1alpha1
kind: Application
metadata:
  name: external-secrets
  namespace: argocd
  annotations:
    argocd.argoproj.io/sync-wave: "-1"
spec:
  project: default
  source:
    repoURL: https://github.com/notjustanna/iac.git
    targetRevision: main
    path: applications/external-secrets
  destination:
    server: https://kubernetes.default.svc
    namespace: external-secrets
  syncPolicy:
    automated:
      prune: true
      selfHeal: true
    syncOptions:
      - CreateNamespace=true
      - ServerSideApply=true
The sync-wave: "-1" ensures ESO is fully deployed before anything tries to create ExternalSecret resources.
Configuring the ClusterSecretStore
Create a machine identity in Infisical (Project → Access Control → Machine Identities), give it read access to your environment, then store the credentials:
kubectl create secret generic infisical-auth
  --from-literal=clientId=<your-client-id>
  --from-literal=clientSecret=<your-client-secret>
  -n external-secrets
Then the ClusterSecretStore:
# applications/external-secrets/cluster-secret-stores.yml
apiVersion: external-secrets.io/v1
kind: ClusterSecretStore
metadata:
  name: infisical
spec:
  provider:
    infisical:
      auth:
        universalAuthCredentials:
          clientId:
            name: infisical-auth
            namespace: external-secrets
            key: clientId
          clientSecret:
            name: infisical-auth
            namespace: external-secrets
            key: clientSecret
      secretsScope:
        projectSlug: "your-project-slug"
        environmentSlug: "prod"
        secretsPath: "/"
        recursive: true
One ClusterSecretStore serves the whole cluster. Every namespace can reference it.
Consuming Secrets: A Real Example
Here’s how I pull in the Cloudflare API token for Traefik. In Infisical, the secret lives under /traefik. The ExternalSecret syncs everything under that path into a Kubernetes secret in the traefik namespace:
# applications/traefik/external-secret.yml
apiVersion: external-secrets.io/v1
kind: ExternalSecret
metadata:
  name: cloudflare-api-token
  namespace: traefik
spec:
  secretStoreRef:
    name: infisical
    kind: ClusterSecretStore
  refreshInterval: 1m
  target:
    name: cloudflare-api-token
    creationPolicy: Owner
    template:
      type: Opaque
  dataFrom:
    - find:
        path: /traefik
Traefik just sees a Kubernetes secret. It has no idea Infisical exists. That’s the whole point.
The Part That Actually Sold Me
The ESO pattern means application manifests don’t change when you change secret backends. Secrets are just Kubernetes secrets to everything downstream — no SDK, no sidecar, no secret-fetching logic in application code. Infisical lives entirely in the infra layer, which is where secrets management should live.
The path-based organization (/traefik, /monitoring, and so on) felt immediately familiar — it’s the same mental model as AWS Parameter Store. That’s not a coincidence; it’s just the right way to organize secrets. The recursive: true on the ClusterSecretStore means ExternalSecret resources can scope as narrowly or broadly as makes sense per workload.
Should You Use the Cloud or Self-Host?
The managed free tier covers up to 5 projects with unlimited secrets. For a homelab or small production workload, there’s genuinely no reason to self-host unless you want to.
If you do want to self-host — the Helm chart is well-documented. Just be aware of the chicken-and-egg problem: if Infisical lives on the same cluster it’s serving secrets to, it becomes a bootstrap dependency, and that gets messy fast. I wrote about this failure mode in more detail here. Infisical Cloud sidesteps it entirely, which is why I’m using it.
Bottom Line
I stopped looking for a better option. Infisical + ESO hit the threshold of “this is clearly correct” — open source, free at the scale I need, Kubernetes-native without being invasive, and not locked to any cloud. The setup I showed above is the whole thing. If you’re still managing secrets via committed files, manual kubectl create secret commands, or CI-only stores — this is the way out.

This blog was originally published on Descope
Reflex is an open-source full-stack web framework written in and for Python that lets you build both frontend UI and backend logic in pure Python, i.e., you don’t need to manually write JavaScript or separately manage a React/Vue frontend and a separate backend.
By adding Descope to your Reflex application, you can immediately take advantage of a full-fledged identity platform—complete with passwordless authentication, MFA, passkeys, social login, enterprise SSO, and customizable user journeys.
This lets you keep writing your entire Reflex project in Python while relying on Descope to seamlessly deliver the advanced authentication and security capabilities needed for real-world, scalable applications.
Let’s begin!
Prerequisites
It’s helpful to familiarize yourself with Python and Reflex. You’ll also need a Descope account, but don’t worry if you don’t have one yet—you’ll learn how to set one up shortly. The free tier will be sufficient for you to follow along.
Create a Descope Project
The first step in connecting your Reflex app to Descope is to create a new Project in the Descope Console.
In Settings > Project, you’ll find your Project ID, which is a unique identifier used to link your Reflex app to Descope.

Best practice: Never paste this ID directly into your code. Instead, store it securely as an environment variable in a .env file. We’ll configure this later in the blog.
Create the Reflex app
With your Descope Project set up, let’s move to the Reflex side. We’ll start with a dashboard app template and then integrate authentication step-by-step.
reflex-descope-auth to the requirements.txt file. Note: This is the Reflex Descope Auth plugin, which uses standard OIDC protocols to handle the login process in a reliable, familiar way.pip install -r requirements.txt
.env file and set these environment variables in the project.
DESCOPE_PROJECT_ID=<your-descope-project-id>
DESCOPE_FLOW_ID=<your-flow-id>
DESCOPE_LOGOUT_REDIRECT_URI=http://localhost:3000
SESSION_SECRET=<secure-random-secret>
You can generate a secret using Python’s secrets module:
python -c "import secrets; print(secrets.token_hex(32))"
This is what your project structure should look like:
.
├── .gitignore
├── app
│   ├── __init__.py
│   ├── app.py
│   ├── components
│   │   ├── __init__.py
│   │   ├── documents_table.py
│   │   ├── header.py
│   │   ├── key_metrics.py
│   │   ├── sidebar.py
│   │   └── visitors_chart.py
│   └── states
│       ├── __init__.py
│       ├── auth_state.py
│       └── dashboard_state.py
├── apt-packages.txt
├── assets/
├── .env
├── requirements.txt
└── rxconfig.py
Log in a user
In the app.py file, we’ll add a button that calls start_login, a built-in method that initiates the login flow and redirects users to the Descope authorization endpoint.
def index() -> rx.Component:
    """The main page, which serves as the login entry point."""
    return rx.el.div(
        rx.el.section(
            rx.el.div(
                rx.el.button(
                    "Login with Descope",
                    on_click=AuthState.start_login,
                    class_name=(
                        "mt-8 px-8 py-3 text-white bg-red-600 rounded-lg font-semibold "
                        "hover:bg-blue-700 transition-colors shadow-md"
                    ),
                ),
                class_name="flex flex-col items-start max-w-xl",
            ),
            class_name="container mx-auto flex flex-col lg:flex-row items-center justify-between gap-12 px-4 py-16",
        ),
        class_name="w-full bg-gray-50",
    )
The dashboard_page function defines the main authenticated dashboard view of the application. It’s registered as a Reflex page using the @rx.page() decorator with the root route (/).
When a user visits this page, the on_load parameter triggers the AuthState.check_login method to verify if the user is authenticated. If the user isn’t logged in, they’ll be redirected to the login flow automatically.
@rx.page(route="/", on_load=AuthState.check_login)
def dashboard_page() -> rx.Component:
    """The main dashboard page."""
    return rx.el.div(
        sidebar(),
        rx.el.main(
            header_bar(),
            rx.el.div(
                key_metrics_section(),
                visitors_chart_section(),
                documents_table_section(),
                class_name="p-6 space-y-6",
            ),
            class_name="w-full h-[100vh] overflow-y-auto",
        ),
        class_name="flex flex-row bg-gray-50 h-[100vh] w-full overflow-hidden",
        on_mount=DashboardState.load_initial_data,
    )
The callback page handles the authentication redirect after a user logs in. It’s defined using the @rx.page() decorator and mapped to the /callback route.
When the user returns to this route after completing authentication, the on_load parameter calls AuthState.auth_redirect. This method processes the login response, typically validating tokens, storing session data, and determining whether the login succeeded or failed.
@rx.page(route="/callback", on_load=AuthState.auth_redirect)
def callback() -> rx.Component:
    return rx.el.div(
        rx.cond(
            AuthState.error_message != "",
            rx.el.div(
                rx.el.h1("Login Failed", class_name="text-red-500"),
                rx.el.p(AuthState.error_message),
                rx.el.button(
                    "Try Again",
                    on_click=AuthState.start_login,
                    class_name="px-4 py-2 text-white bg-blue-600 rounded-md hover:bg-blue-700",
                ),
                class_name="flex flex-col items-center space-y-4",
            ),
            rx.el.div(
                rx.el.p("Processing login..."), class_name="flex items-center space-x-2"
            ),
        ),
        class_name="flex items-center justify-center h-screen",
    )
The auth_error page provides a dedicated route for handling login failures. It’s defined at the /auth-error path and serves as a fallback whenever something goes wrong during the authentication process. For example, if token validation fails, the user denies consent, or the callback flow encounters an unexpected error.
@rx.page(route="/auth-error")
def auth_error() -> rx.Component:
    return rx.el.div(
        rx.el.h1("Login Failed", class_name="text-red-500"),
        rx.el.p(AuthState.error_message),
        rx.el.button(
            "Try Again",
            on_click=AuthState.start_login,
            class_name="px-4 py-2 text-white bg-blue-600 rounded-md hover:bg-blue-700",
        ),
        class_name="flex flex-col items-center space-y-4 h-screen justify-center",
    )
We’ll also add additional routes to this file to handle page protection and move the dashboard to a dedicated page.
app.add_page(dashboard_page, route="/dashboard")
app.add_page(callback, route="/callback")
app.add_page(auth_error, route="/auth-error")
Define AuthState in Reflex
Authentication in Reflex is handled through reactive state classes. The reflex-descope-auth plugin provides a base class called DescopeAuthState, which already implements the full authentication lifecycle for you. By subclassing it, we can customize how our app handles redirects and session checks after a user logs in or out. The reflex-descope-auth plugin validates Descope tokens only once during finalize_auth. After that, Reflex simply stores the session in state and does not re-check the exp or rexp claims in the token automatically.
finalize_auth is a built-in method that completes the authentication process after the redirect from Descope, exchanges the authorization code for tokens, verifies ID token, and creates a session token for the user.
By using yield, Reflex processes each step reactively—first finalizing auth, then deciding the next redirect.
import reflex as rx
from reflex_descope_auth import DescopeAuthState


class AuthState(DescopeAuthState):
    @rx.event
    async def auth_redirect(self):
        yield DescopeAuthState.finalize_auth()
        if getattr(self, "error_message", None):
            yield rx.redirect("/auth-error")
            return
        yield rx.redirect("/dashboard")

    @rx.event
    def check_login(self):
        if not self.logged_in:
            return rx.redirect("/")
check_login() is a custom method that acts as a page guard for any route that should only be accessible to authenticated users. It works by:
self.logged_in (which is automatically managed by DescopeAuthState).self.logged_in is False), it immediately returns a redirect to the homepage (/), which serves as the login page.This ensures that only valid sessions can access private pages like /dashboard.
Implementing OAuth social logins, magic links, and SSO
Once your Reflex app is wired up with the Reflex Descope Auth plugin, adding new authentication methods becomes incredibly simple. Descope flows let you drag, drop, and configure options like OAuth social logins, magic links, and SAML/OIDC SSO without changing any of your Reflex code.
If you want users to sign in with Google, GitHub or any other providers, you can configure these OAuth providers in the authentication methods in the console and add the OAuth action in the flow. For passwordless experiences, you can switch to magic link login by adding the built-in magic link action in your flow. And when your app needs enterprise authentication, you can add a SSO action to the same flow.
If you’d like to try SSO end-to-end, you can spin up a tenant and walk through the setup using the Mock SAML Testing guide. And if your organization already uses a SAML IdP such as Okta, ADFS, or PingFederate, you can simply plug in its metadata URL in place of the mock provider.
With everything controlled through Descope’s visual flow editor, your Reflex integration remains the same, with the plugin automatically handling redirects and token exchange. Here’s an example flow that combines the social login, magic link and SSO authentication:

One of the biggest hurdles is enabling each customer to set up Single-Sign-On (SSO) with their own identity provider (IdP). Descope’s SSO Setup Suite simplifies how organizations configure Single Sign-On (SSO) for their tenants. Instead of manually exchanging metadata and troubleshooting IdP configurations, the suite offers a guided, self-service flow that allows tenant admins to set up and test their SSO integration (SAML or OIDC) end-to-end.
With built-in steps for attribute mapping, SCIM provisioning, and domain routing, it significantly reduces setup time and support overhead by empowering customers to get their SSO running smoothly with minimal developer involvement.
Displaying the user name and logging out a user
Once a user successfully signs in, we can use AuthState.userinfo to display the user’s profile details such as their name, while AuthState.logged_in tracks the current authentication status. userinfo comes from the JWT claims inside the session token. The plugin extracts claims from the token and userinfo simply reads from there. To be able to add custom attributes, you can define custom claims in Descope.
In the code snippet below, the header displays a personalized welcome message along with a Logout button when the user is signed in and AuthState.logout will allow the user to log out.
import reflex as rx
from app.states.auth_state import AuthState


def header_bar() -> rx.Component:
    """The header bar component."""
    return rx.el.div(
        rx.el.div(
            rx.cond(
                AuthState.logged_in,
                rx.el.div(
                    rx.el.span(
                        f"Welcome, {AuthState.userinfo.get('name', 'User').to(str).split(' ')[0]}",
                        class_name="text-sm font-medium text-gray-700",
                    ),
                    rx.el.button(
                        "Logout",
                        on_click=AuthState.logout,
                        class_name="px-4 py-1 text-sm text-white bg-red-600 rounded-md hover:bg-red-700",
                    ),
                    class_name="flex items-center space-x-4",
                ),
                rx.fragment(),
            )
        ),
        class_name="flex items-center justify-between h-12 px-6 bg-white border-b border-gray-200",
    )
The dashboard will then look similar to this:

Reflex SSO and authentication with Descope
With Descope, implementing authentication in a Reflex app becomes both simple and highly flexible. Descope’s flows let you design every step of the user journey without managing complex logic yourself. The Reflex Descope Auth plugin then brings these flows directly into your application, handling the redirects and tokens. Together, they give you a powerful, low-code way to add secure, customizable authentication to any Reflex project.
If you have any questions about Descope or a customer identity project we can help with, book a demo with our auth experts.
I created a new website: Free Access to the 8 Volumes on Typescript & AI Masterclass, no registration required. Choose Volume and chapter on the menu on the left. 160 Chapters and hundreds of quizzes at the end of chapters.
The AI revolution is no longer confined to massive data centers. A new wave of “small language models” (SLMs) is democratizing access to powerful AI, bringing cutting-edge capabilities directly to your laptop, phone, and even web browser. Forget needing expensive GPUs and cloud subscriptions – models like Phi-3, Gemma, and Llama 3 are changing the game. This post explores the theory behind SLMs, how they work, and provides a practical code example to get you started building your own local AI applications.
The Rise of Efficient AI: Why Small Language Models Matter
For a while, the narrative in AI was simple: bigger is better. Large Language Models (LLMs) like GPT-4 demonstrated incredible abilities, but at a significant cost. Running these behemoths requires substantial computing power, making them inaccessible to many developers and everyday users. This created a barrier to entry and limited the potential for widespread AI adoption.
Small Language Models represent a paradigm shift. They prioritize efficiency over sheer size, achieving impressive performance with a fraction of the parameters. This isn’t about sacrificing intelligence; it’s about smarter engineering and innovative training techniques. SLMs are built upon the same foundational Transformer architecture as their larger counterparts, but they’ve been meticulously optimized for speed, reduced memory footprint, and on-device execution. This opens up exciting possibilities for privacy-preserving AI, offline functionality, and real-time applications.
How Do SLMs Achieve High Performance with Fewer Parameters?
The core of SLMs lies in two key strategies: knowledge distillation and architectural optimization.
Knowledge Distillation: Imagine a master chef teaching an apprentice. The master doesn’t just provide the final dish; they explain the nuances of flavor, technique, and ingredient selection. Similarly, knowledge distillation involves training a smaller “student” model to mimic the behavior of a larger, more powerful “teacher” model. The student learns not just what the correct answer is, but why it’s correct, by analyzing the probability distributions generated by the teacher. Phi-3, for example, was trained on high-quality data generated by a larger model, effectively compressing vast knowledge into a compact 3.8 billion parameter package.
Architectural Optimization: SLMs aren’t simply scaled-down versions of LLMs. They employ clever architectural tweaks to improve efficiency. This includes reducing the number of Transformer layers, utilizing techniques like Grouped-Query Attention (GQA) – which reduces computational load by sharing key and value projections – and employing other pruning and quantization methods. GQA, used in Llama 3-8B, is analogous to a web server using a connection pool; it reuses resources instead of creating new ones for every request.
Quantization: The Secret to Running AI on Consumer Hardware
Even with optimized architectures, running SLMs on limited hardware requires further compression. This is where quantization comes in. Traditionally, neural networks use 32-bit floating-point numbers (FP32) for calculations. Quantization reduces this precision to 8-bit integers (INT8) or even 4-bit integers (INT4).
Think of it like compressing an audio file. An uncompressed WAV file is large and pristine, while a high-quality MP3 is significantly smaller with minimal perceptible loss in audio quality. Quantization achieves a similar trade-off: reducing model size and accelerating inference with a negligible impact on performance. A 4-billion parameter model that would normally require 16GB of VRAM in FP32 can run comfortably on a laptop with integrated graphics using INT4 quantization.
The SLM Ecosystem: Local and Browser-Based Inference
The theoretical advancements in SLMs are coupled with practical tools that make them accessible.
Code Example: Building a Local SLM Chat Interface with TypeScript
Let’s put theory into practice. This example demonstrates a basic web application that interfaces with a local SLM running via Ollama.
// --- Type Definitions ---
type ChatMessage = {
    role: 'user' | 'assistant';
    content: string;
};

interface OllamaGenerateRequest {
    model: string;
    prompt: string;
    stream: boolean;
    options?: {
        temperature?: number;
        num_ctx?: number;
    };
}

interface OllamaResponseChunk {
    response?: string;
    done: boolean;
    context?: number[];
    total_duration?: number;
}

// --- Configuration ---
const CONFIG = {
    OLLAMA_API_URL: 'http://localhost:11434/api/generate',
    DEFAULT_MODEL: 'phi3:mini',
    MAX_RETRIES: 3,
};

// --- State Management ---
const state = {
    chatHistory: [],
    isGenerating: false,
};

// --- DOM Elements ---
const elements = {
    chatContainer: document.getElementById('chat-container') as HTMLDivElement,
    userInput: document.getElementById('user-input') as HTMLTextAreaElement,
    sendButton: document.getElementById('send-button') as HTMLButtonElement,
    statusIndicator: document.getElementById('status') as HTMLSpanElement,
};

// --- Core Logic ---
async function sendPromptToOllama(prompt: string): Promise<void> {
    if (state.isGenerating) return;

    state.isGenerating = true;
    updateUIStatus('Generating...');

    const requestBody: OllamaGenerateRequest = {
        model: CONFIG.DEFAULT_MODEL,
        prompt: prompt,
        stream: true,
        options: {
            temperature: 0.7,
        },
    };

    try {
        const response = await fetch(CONFIG.OLLAMA_API_URL, {
            method: 'POST',
            headers: { 'Content-Type': 'application/json' },
            body: JSON.stringify(requestBody),
        });

        if (!response.ok) {
            throw new Error(`Ollama API error: ${response.statusText}`);
        }

        const reader = response.body?.getReader();
        if (!reader) throw new Error('No response body');

        const decoder = new TextDecoder();
        let fullResponse = '';

        while (true) {
            const { done, value } = await reader.read();
            if (done) break;

            const chunkText = decoder.decode(value, { stream: true });
            const lines = chunkText.split('n').filter(line => line.trim() !== '');

            for (const line of lines) {
                try {
                    const json: OllamaResponseChunk = JSON.parse(line);
                    if (json.response) {
                        fullResponse += json.response;
                        updateChatDisplay('assistant', fullResponse, true);
                    }
                    if (json.done) {
                        state.chatHistory.push({ role: 'assistant', content: fullResponse });
                        renderChatHistory();
                    }
                } catch (e) {
                    console.warn('Skipped incomplete JSON chunk');
                }
            }
        }
    } catch (error) {
        console.error('Error communicating with Ollama:', error);
        updateChatDisplay('assistant', `Error: ${error.message}`, false);
    } finally {
        state.isGenerating = false;
        updateUIStatus('Ready');
        elements.userInput.disabled = false;
        elements.sendButton.disabled = false;
        elements.userInput.focus();
    }
}

// --- UI Helper Functions ---
function renderChatHistory(): void {
    elements.chatContainer.innerHTML = '';
    state.chatHistory.forEach(msg => {
        const msgDiv = document.createElement('div');
        msgDiv.className = `message ${msg.role}`;
        msgDiv.textContent = msg.content;
        elements.chatContainer.appendChild(msgDiv);
    });
    elements.chatContainer.scrollTop = elements.chatContainer.scrollHeight;
}

function updateChatDisplay(role: 'assistant', content: string, isStreaming: boolean): void {
    let lastMsg = elements.chatContainer.lastElementChild;
    if (isStreaming && lastMsg && lastMsg.classList.contains('assistant')) {
        lastMsg.textContent = content;
    } else if (!isStreaming) {
        const msgDiv = document.createElement('div');
        msgDiv.className = `message ${role}`;
        msgDiv.textContent = content;
        elements.chatContainer.appendChild(msgDiv);
    }
    elements.chatContainer.scrollTop = elements.chatContainer.scrollHeight;
}

function updateUIStatus(status: string): void {
    elements.statusIndicator.textContent = status;
    elements.statusIndicator.style.color = status === 'Generating...' ? '#f59e0b' : '#10b981';
}

// --- Event Listeners ---
elements.sendButton.addEventListener('click', handleSend);
elements.userInput.addEventListener('keydown', (e) => {
    if (e.key === 'Enter' && !e.shiftKey) {
        e.preventDefault();
        handleSend();
    }
});

updateUIStatus('Ready');
The Future is Small: Embracing the SLM Revolution
Small Language Models are not a step back from LLMs; they are a crucial evolution. By prioritizing efficiency and accessibility, they unlock a world of possibilities for AI integration into our daily lives. From on-device assistants to privacy-focused applications, SLMs are paving the way for a more decentralized and democratized AI future. The tools and techniques discussed here provide a solid foundation for exploring this exciting new frontier. Start experimenting with Phi-3, Gemma, and Llama 3 – the power of AI is now within reach, right on your laptop.
The concepts and code demonstrated here are drawn directly from the comprehensive roadmap laid out in the book The Edge of AI. Local LLMs (Ollama), Transformers.js, WebGPU, and Performance Optimization Amazon Link of the AI with JavaScript & TypeScript Series.
The ebook is also on Leanpub.com: https://leanpub.com/EdgeOfAIJavaScriptTypeScript.
👉 Free Access now to the TypeScript & AI Series on Programming Central, it includes 8 Volumes, 160 Chapters and hundreds of quizzes for every chapter.

The Logic Apps Data Mapper in VS Code lets you create XML transformation maps on macOS. You can drag connections between source and target schemas, add functions, save — the visual designer works. The .lml file gets written to disk. You can even compile it to XSLT 3.0.
But you can’t test it.

When you click Test Map on macOS, you get this:
400 – BadRequest: The .NET framework worker could not be found.
The Test Map feature depends on the Azure Functions .NET Framework worker — a Windows-only component. The button is there, the backend isn’t. You can create maps all day — you just can’t verify they produce correct output without deploying to Azure or switching to a Windows machine.
This post shows how to compile and run Data Mapper maps locally on any platform using the Logic Apps testing SDK and standard .NET unit tests.
The options
When you can’t use Test Map, you have three paths:
func host start locally with Azurite, call the REST compile endpoint — heavyweight, requires Azurite and a warm Azure Functions host, flaky on macOSDataMapTestExecutor from the testing SDK — no host, no Azurite, no Azure, just dotnet test
Option 3 is what this post covers.
DataMapTestExecutor
The Logic Apps testing SDK (Microsoft.Azure.Workflows.WebJobs.Tests.Extension v1.0.1) includes a class called DataMapTestExecutor. It does two things:
GenerateXslt(mapName) reads the .lml from Artifacts/MapDefinitions/, resolves schemas, custom functions, and inline XSLT snippets, and returns the compiled XSLT 3.0 as bytes.RunMapAsync(xslt, input) takes the compiled XSLT and input XML bytes, executes the transform via SaxonCS, and returns the result.This is the same compilation and execution pipeline that the designer’s Test Map button and the func host runtime use — you’re running the same code path, just without the Azure Functions host scaffolding.
Setting up the test project
Project structure
The test project lives alongside the Logic App project:
MyWorkspace/
├── MyLogicApp/                     # Logic App project (Standard)
│   ├── Artifacts/
│   │   ├── MapDefinitions/         # .lml source files
│   │   ├── Maps/                   # compiled .xslt (generated)
│   │   ├── Schemas/                # XSD / JSON schemas
│   │   ├── SampleData/             # sample input XML
│   │   └── DataMapper/
│   │       └── Extensions/
│   │           ├── Functions/      # custom function XML files
│   │           └── InlineXslt/     # inline XSLT snippets
│   └── .vscode/
└── Tests/
    └── MyLogicApp.Tests/           # test project
        ├── MyLogicApp.Tests.csproj
        └── OrderToShipment/
            ├── OrderToShipmentTest.cs
            └── Order-input.xml     # test-specific input data
The .csproj

The critical dependency is Microsoft.Azure.Workflows.WebJobs.Tests.Extension v1.0.1 — not v1.0.0. The DataMapTestExecutor class doesn’t exist in v1.0.0.
Pointing at the Logic App project root
DataMapTestExecutor needs the Logic App project root — the directory that contains Artifacts/. It scans from there to find schemas, custom functions, and map definitions. The path is relative from the test’s output directory:
private static readonly string ProjectRoot = Path.GetFullPath(
    Path.Combine(Directory.GetCurrentDirectory(),
        "..", "..", "..", "..", "..", "MyLogicApp"));
The number of .. segments depends on your folder structure. Count from bin/Debug/net8.0/ up to wherever the Logic App project lives.
Writing the tests
Setup: compile the LML once
Each test class points at the Logic App project root and names the LML map to compile. [TestInitialize] runs before each test method — it compiles the LML to XSLT so every test starts from a freshly compiled stylesheet.
[TestClass]
public class Order2Shipment20260327DataMapTest
{
    private static readonly string ProjectRoot = Path.GetFullPath(
        Path.Combine(Directory.GetCurrentDirectory(),
            "..", "..", "..", "..", "..", "LADataMapperXsltDebugger"));

    private static readonly string MapName = "Order2Shipment_20260327-lml";

    private static readonly string InputPath = Path.Combine(
        Directory.GetCurrentDirectory(), "Order2Shipment20260327", "Order-input.xml");

    private DataMapTestExecutor executor;
    private byte[] xslt;

    [TestInitialize]
    public async Task Setup()
    {
        executor = new DataMapTestExecutor(ProjectRoot);
        xslt = await executor.GenerateXslt(MapName);
    }
}
GenerateXslt takes the map name without path or extension. It finds the matching .lml in Artifacts/MapDefinitions/, reads the schemas from the LML header, loads custom functions, and compiles to XSLT 3.0.
Parsing the result
RunMapAsync returns a JToken with the transform output encoded as base64:
{ "$content-type": "application/xml", "$content": "PFNoaXBtZW50cy4uLg==" }
A helper to decode it:
private static XDocument ParseResult(JToken result)
{
    var base64 = result["$content"]!.Value<string>()!;
    var xml = Encoding.UTF8.GetString(Convert.FromBase64String(base64));
    return XDocument.Parse(xml);
}
Map 1: Order to Shipment — simple field mappings and filtering
This map transforms a single Order into a Shipment. It tests custom extension functions (prefixShipRef, reformatDate, executionDateTime), direct field mappings, a $for loop over line items, and a $if filter that excludes items with Quantity < 1.
Testing individual fields
Each mapping requirement gets its own test for clear failure diagnostics:
[TestMethod]
public async Task Transform_ShipmentRefHasPrefix()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);
    var shipmentRef = xml.Root!.Element("Shipment")!.Element("ShipmentRef")!.Value;
    Assert.AreEqual("SHP-ORD-1001", shipmentRef);
}

[TestMethod]
public async Task Transform_ShipDateReformatted()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);
    var shipDate = xml.Root!.Element("Shipment")!.Element("ShipDate")!.Value;
    Assert.AreEqual("31/10/2025", shipDate);
}
Testing filtering logic
The test input has 3 items — one with Quantity=0 that the $if(xpath("ns0:Quantity >= 1")) filter should exclude:
[TestMethod]
public async Task Transform_FilteredItemExcluded()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);
    var products = xml.Root!.Element("Shipment")!.Element("Lines")!
        .Elements("Line")
        .Select(l => l.Element("Product")!.Value)
        .ToList();

    CollectionAssert.Contains(products, "Wireless Mouse");
    CollectionAssert.Contains(products, "Keyboard");
    CollectionAssert.DoesNotContain(products, "Defective Cable");
}
Validating the entire output
One test that checks everything — structure, values, element order, and the filter:
[TestMethod]
public async Task Transform_ValidateEntireOutput()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);

    Assert.AreEqual("Shipments", xml.Root!.Name.LocalName);
    var shipment = xml.Root.Element("Shipment")!;

    Assert.AreEqual("SHP-ORD-1001", shipment.Element("ShipmentRef")!.Value);
    Assert.AreEqual("31/10/2025", shipment.Element("ShipDate")!.Value);
    Assert.AreEqual("John Doe", shipment.Element("Recipient")!.Value);

    var execDate = shipment.Element("ExecutionDate")!.Value;
    Assert.IsTrue(execDate.EndsWith("Z") && DateTime.TryParse(execDate, out _),
        $"ExecutionDate not valid UTC: {execDate}");

    var lines = shipment.Element("Lines")!.Elements("Line").ToList();
    Assert.AreEqual(2, lines.Count, "Expected 2 lines after Quantity >= 1 filter");

    Assert.AreEqual("Wireless Mouse", lines[0].Element("Product")!.Value);
    Assert.AreEqual("2", lines[0].Element("Quantity")!.Value);

    Assert.AreEqual("Keyboard", lines[1].Element("Product")!.Value);
    Assert.AreEqual("1", lines[1].Element("Quantity")!.Value);

    var childNames = shipment.Elements().Select(e => e.Name.LocalName).ToList();
    CollectionAssert.AreEqual(
        new[] { "ShipmentRef", "ShipDate", "Recipient", "ExecutionDate", "Lines" },
        childNames, "Element order must match ShipmentOutput.xsd");
}
Map 2: PurchaseOrders to ShippingManifest — attributes, nested loops, computed values
This is a more complex map. It transforms multiple PurchaseOrders into a ShippingManifest with XML attributes, nested $for loops (Orders → Items), computed aggregates (totalWeight, totalValue), and custom functions (shipId, formatAddress, hazardousFlag, parcelSubtotal).
The test class follows the same pattern — different map name, different input:
private static readonly string MapName = "OrderToShipment-po2sm-lml";

private static readonly string InputPath = Path.Combine(
    Directory.GetCurrentDirectory(), "OrderToShipment", "PurchaseOrders-input.xml");
Testing attributes and computed values
[TestMethod]
public async Task Transform_FirstShipment_ShipIdAndPriority()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);
    var first = xml.Root!.Element("Shipment")!;
    Assert.AreEqual("SHP-0847", first.Attribute("shipId")?.Value);
    Assert.AreEqual("EXPRESS", first.Attribute("priority")?.Value);
    Assert.AreEqual("true", first.Attribute("hazmat")?.Value);
}

[TestMethod]
public async Task Transform_FirstShipment_Parcels()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);
    var parcels = xml.Root!.Element("Shipment")!.Element("Parcels")!;
    Assert.AreEqual("3", parcels.Attribute("lineCount")?.Value);
    Assert.AreEqual("kg", parcels.Attribute("weightUnit")?.Value);
    Assert.AreEqual("35.4", parcels.Attribute("totalWeight")?.Value);
}
Testing nested loop output with hazmat flag
The inner $for loops over each Order’s Items. The hazardousFlag custom function maps @hazardous="true" to "Y":
[TestMethod]
public async Task Transform_FirstShipment_HazmatParcel()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);
    var parcels = xml.Root!.Element("Shipment")!.Element("Parcels")!.Elements("Parcel");
    var hazmat = parcels.FirstOrDefault(p => p.Attribute("sku")?.Value == "CHEM-0055");
    Assert.IsNotNull(hazmat);
    Assert.AreEqual("Y", hazmat.Attribute("hazardous")?.Value);
    Assert.AreEqual("128.00", hazmat.Attribute("subtotal")?.Value);  // 4 × 32.00
}

[TestMethod]
public async Task Transform_FirstShipment_TotalValue()
{
    var input = await File.ReadAllBytesAsync(InputPath);
    var result = await executor.RunMapAsync(xslt, input);
    var xml = ParseResult(result);
    var total = xml.Root!.Element("Shipment")!.Element("TotalValue")!;
    Assert.AreEqual("1448.00", total.Element("Amount")?.Value);   // 1014 + 128 + 306
    Assert.AreEqual("EUR", total.Element("Currency")?.Value);
}
Running the tests

The first test in each suite takes ~400–500ms (JIT + LML compilation). Subsequent tests reuse the compiled XSLT from [TestInitialize] and run in single-digit milliseconds.
What DataMapTestExecutor does under the hood
DataMapTestExecutor(projectRoot)
  → scans Artifacts/Schemas/ for XSD and JSON schemas
  → scans Artifacts/DataMapper/Extensions/Functions/*.xml for custom functions
  → scans Artifacts/DataMapper/Extensions/InlineXslt/*.xml for XSLT snippets

GenerateXslt(mapName)
  → reads Artifacts/MapDefinitions/{mapName}.lml
  → resolves schema references from the LML header
  → compiles LML → XSLT 3.0 via DataMapperUtility
  → returns byte[] of the compiled stylesheet

RunMapAsync(xslt, input)
  → loads the XSLT via SaxonCS (bundled in the SDK)
  → runs the transform against the input bytes
  → returns JToken with base64-encoded XML result
Known gotchas
v1.0.0 vs v1.0.1. DataMapTestExecutor doesn’t exist in v1.0.0 of the SDK. If dotnet test fails with a missing type, check your Microsoft.Azure.Workflows.WebJobs.Tests.Extension version.
ProjectRoot must point to the Logic App root. The path must resolve to the directory containing Artifacts/ — not the test project, not the solution root. If GenerateXslt throws “map not found”, your path is wrong.
Zero-parameter custom functions. If any <function> in Functions/*.xml has no <param> elements, the SDK hits a NullReferenceException on function.parameters.Length. The entire XML file is silently skipped, making all functions in it “unrecognized”. Workaround: add a dummy parameter <param name="_unused" as="xs:string"/>.
Custom function namespace scoping. Function files are parsed in isolation. Namespace prefixes declared in the main stylesheet (like xmlns:tns="...") are not available inside function XML files. Using tns:ElementName in a function’s XPath will throw a NullReferenceException at init time.
Base64 response format. RunMapAsync does not return raw XML. The result is a JToken with $content containing base64-encoded output. You must decode it before asserting.
Beyond testing: the designer’s save problem
And even if Test Map worked, the visual designer has its own problems — changes that revert on reopen, string literals that lose quotes, expressions that get silently rewritten. I wrote a separate post about editing LML files directly as a more reliable alternative to the designer.
The XSLT Debugger extension is on the VS Code Marketplace for macOS and Windows.
The Problem Nobody Is Solving
There are over 1 million autonomous AI agents active today. Each one has cognitive capacity that — while its owner sleeps, works, or has not assigned a task — sits idle. Wasted. Generating cost without generating value.
At the same time, other agents are executing complex tasks and need additional capacity. They need specialized analysis. They need to subcontract reasoning. They need access to agents with specific context they do not have.
Today, when an agent needs another agent, it has two options: struggle alone, or stop and wait for a human.
Both options are inefficient. Both limit what the agent economy can achieve.
That is the problem. OIXA is the infrastructure that solves it.
How OIXA Works
1. Registry (ERC-8004)
Agents publish an Agent Card: capabilities, models, price, and current availability. Updated in real-time. Other agents can query the registry to find exactly the capacity they need.
2. Reverse Auction
A buying agent posts an RFI (Request for Intelligence): the exact prompt, required model, max budget. OIXA notifies compatible agents. A reverse auction opens — sellers compete downward. The market discovers the real price.
Auction timing is dynamic:
3. Stake System (Anti-Sybil)
Every bidder deposits 20% of their bid as stake. No stake, no bid. This makes flooding the market with fake identities economically impossible.
4. Automatic Verification
OIXA verifies the output cryptographically: right model, delivery time met, coherent result. If it passes → escrow releases in USDC automatically.
5. Public Ledger
Every transaction is recorded immutably. Behavior is public. Content is private. Reputation is built on real data.
The Stack
LOGIC    → Off-chain (fast, efficient)
FUNDS    → On-chain via Base + USDC (trustless)
REGISTRY → On-chain via ERC-8004 (permanent)
PAYMENT  → x402 Protocol (autonomous)
COMMS    → A2A + MCP (standard)
Why This Is Different
| Others | OIXA | |
|---|---|---|
| What is sold | Raw GPU compute | Verified cognitive outputs |
| Who hires | Humans hire agents | Agents hire agents |
| Pricing | Fixed | Real-time reverse auctions |
| Trust layer | None | Stake-based economic guarantees |
| Architecture | Centralized | Open protocol |
The A2A Economy Is Already Happening
Agent-to-agent commerce is not a future concept. It is happening today — informally, unreliably, without economic guarantees. Agents call other agents via APIs. They chain tasks. They subcontract.
OIXA makes this trustless. Autonomous. Paid.
Like HTTP defined how computers communicate on the internet, OIXA defines how agents discover, hire, verify, and pay each other. Anyone can build on it. No permission required.
Where We Are
Phase 0 — Foundation: whitepaper published, protocol server running, GitHub live, community growing.
Phase 1 (next): first 100 agents connected, first real transactions on Base mainnet.
GitHub: https://github.com/ivoshemi-sys/oixa-protocol
Community: https://t.me/oixaprotocol_ai
Whitepaper: https://github.com/ivoshemi-sys/oixa-protocol/blob/main/WHITEPAPER.md
The agent economy needs infrastructure. We are building it.
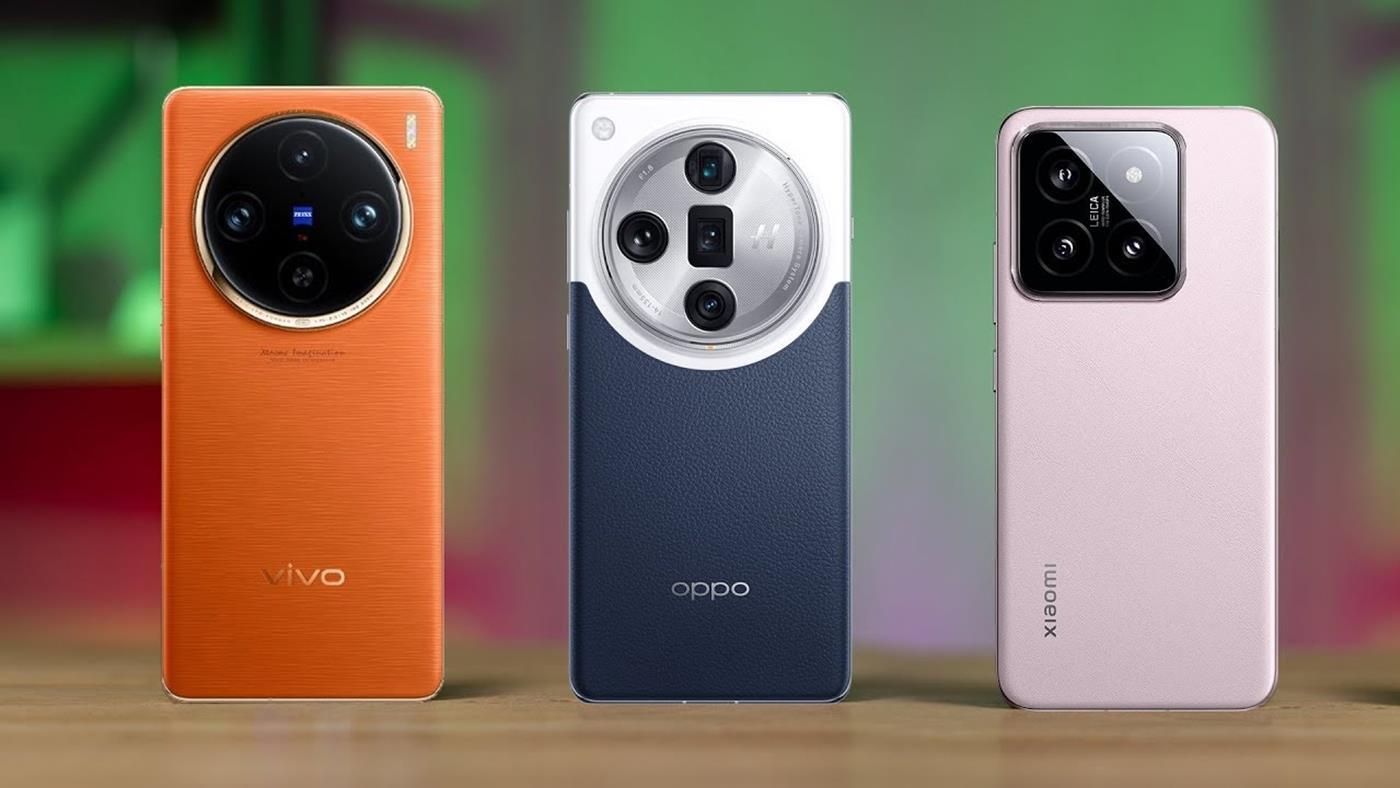
 Counterpoint Research’ün verilerine göre, Ocak 2026 itibarıyla akıllı telefonların ortalama batarya kapasitesi 5.291 mAh seviyesine ulaştı. Bu, geçen yıla göre 400 mAh’lik bir artış anlamına geliyor.
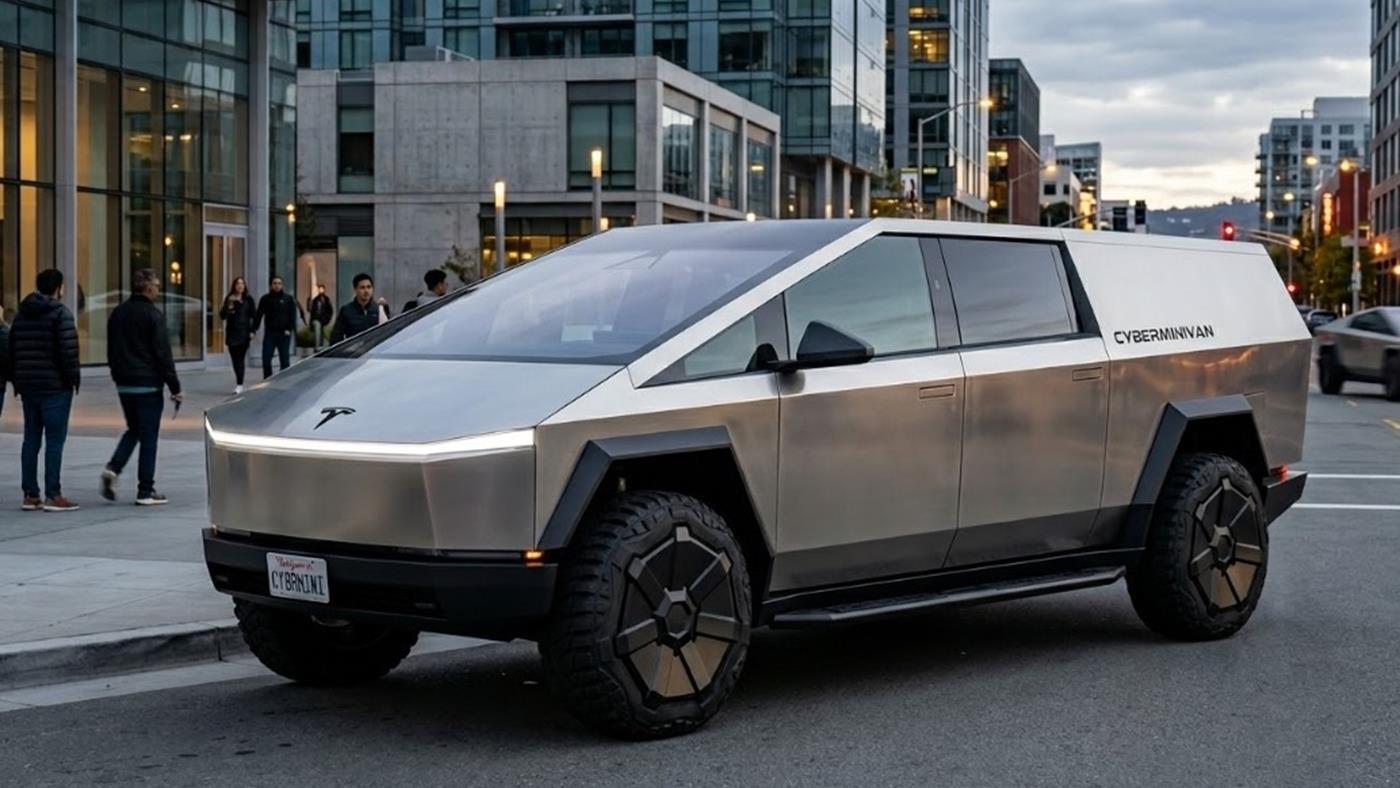
 Elon Musk, Tesla’nın yeni bir model üzerinde çalıştığını açıkladı. En güçlü iddialardan biri, Tesla Cybertruck tasarımını temel alan üç sıralı, büyük bir SUV modeli.
 26 Mart A101 Ekstra teknoloji ürünleri arasında yeni piyasaya sürülen Samsung Galaxy Tab A11 tablet ve Samsung Galaxy S25 akıllı telefon modeli yer alıyor.
Your Obsidian vault is your second brain. Years of notes, project plans, daily journals, meeting records, research — all connected with wikilinks and tags in a carefully organized folder of Markdown files.
But your AI can’t see any of it. You copy-paste snippets into ChatGPT. You describe your note structure to Claude. You manually relay information between your knowledge base and your AI.
That ends now. MCPBundles provides an Obsidian MCP bundle — 35 tools that give your AI full read/write access to your vault through the Model Context Protocol. It’s a standard MCP server — the tools show up natively in whatever AI you already use. Claude Desktop, ChatGPT, Cursor, Windsurf, the mcpbundles CLI, or any MCP-compatible client.
35 tools. Your AI becomes an Obsidian power user.
The Obsidian MCP bundle gives your AI the same access to your vault that you have — and then some. It reads notes and gets back structured data — parsed frontmatter, tags, file stats — not just raw text. It browses your folder hierarchy. It searches across every note in your vault with relevance scoring, regex patterns, frontmatter queries, and date ranges.
It writes. Not just “dump a whole file” writing. Your AI can create notes with full frontmatter, append entries to existing notes, and — this is the part that matters — surgically edit specific sections of a document without touching anything else.
It sees your images. It analyzes your graph structure. It finds orphaned notes and broken links. It lists every task across your entire vault.
Surgical edits change everything
Most integrations that touch files do the same thing: read the whole file, modify it in memory, overwrite the whole file. Fine for code. Terrible for a living document with dozens of sections, tasks, and metadata fields that you don’t want an AI to accidentally mangle.
The Obsidian PATCH operation works differently. Your AI targets a specific heading, block reference, or frontmatter field and inserts, replaces, or appends content just there.
Say you’ve got a project plan with milestones, discussion notes, and action items. You tell your AI to add two items to the milestones section. It reads the document map (a lightweight call that returns all headings, block refs, and frontmatter fields), finds the right heading, and appends only to that section. Your discussion notes and action items stay exactly as they were.
The same precision works for frontmatter. Your AI can flip status: draft to status: shipped on a single field without rewriting the YAML block. It can add a new reviewer: Tony field that didn’t exist before. It can target nested heading paths like "Launch Plan::Key Milestones" to reach the right section in a deeply structured document.
This is the difference between an AI that can edit text files and an AI that understands Obsidian’s document structure.
Daily notes are the fast path
The most common Obsidian workflow is appending to today’s daily note. A quick thought, a task, a meeting summary — you open today’s note and add a line.
Your AI does the same thing in one call. No need to figure out today’s date, construct the filename, check if the file exists. Just “append this to my daily note.” It handles the rest, including creating the note if it doesn’t exist yet.
This turns your AI into a persistent journal. Every conversation can leave a trace in your vault. Meeting summaries go into the daily note. Research findings get filed in project notes. Action items land where they belong.
Your AI can see your images
When your AI reads an image from your vault, it doesn’t get a file path or a base64 blob dumped into a text response. It gets the actual image as an MCP ImageContent block — the same way a screenshot tool returns visual content.
That means any AI model with vision — Claude, GPT-4o, Gemini — actually sees the image. Your AI can describe a diagram, read handwritten notes from a photo, interpret a screenshot, or analyze a chart. All from files already sitting in your vault.
PNG, JPEG, GIF, WebP, BMP, and SVG are all supported. The image flows through the same proxy tunnel as everything else — nothing gets stored on MCPBundles servers.
Graph analysis and vault maintenance
Obsidian’s power comes from connections between notes. Wikilinks turn a folder of Markdown files into a knowledge graph. But maintaining that graph — finding orphans, fixing broken links, understanding relationships — is manual work.
Your AI traverses your link graph. Graph neighbors does a breadth-first search from any note, finding every connected note within a configurable depth. Direction matters: outgoing links, incoming backlinks, or both.
Orphan detection scans every note in your vault and identifies the ones with zero incoming wikilinks — notes that nothing else links to. These are the ones you forgot about, the stubs you never connected, the ideas that fell through the cracks.
Broken link detection scans every wikilink in every note and checks whether the target actually exists. That reference to [[Old Project Name]] you renamed three months ago? Found.
Task management across your entire vault
Obsidian is great for tasks — the checkbox syntax (- [ ] do the thing) works in any note. But there’s no built-in way to see tasks across your entire vault. Your AI can.
The task listing tool scans every note, extracts every checkbox, and returns them with their source file and line number. Filter by status (open, completed, all), by folder, by tag, or by keyword. Ask your AI “what are my open tasks tagged with Q2?” and get an answer without installing any plugins.
How the proxy tunnel works
Obsidian runs on your desktop. AI services run in the cloud. The MCPBundles desktop proxy bridges them with an encrypted tunnel.
AI → MCPBundles → Proxy Tunnel → Your Desktop → Obsidian (localhost:27124)
Your vault data flows through the tunnel in real time. Nothing gets stored on MCPBundles servers. The proxy handles Obsidian’s self-signed TLS certificate automatically.
Works with the AI you already use
MCPBundles is a remote MCP server. You connect it once and the Obsidian tools appear in your AI’s tool list — alongside any other bundles you’ve enabled.
Claude Desktop, ChatGPT, Cursor, Windsurf — add the MCPBundles MCP server URL and the tools are there.
mcpbundles CLI — for terminal workflows, scripting, and automation. pip install mcpbundles and you’re set.
Any MCP-compatible client — if it speaks MCP, it works. The tools are standard MCP tools with proper schemas, annotations, and content types.
Five minutes to set up
1. Install the Obsidian plugin
Install the Local REST API community plugin in Obsidian (by Adam Coddington). Enable it and copy the API key from the plugin settings.
2. Start the proxy
pip install mcpbundles
mcpbundles login
mcpbundles proxy start
3. Enable the bundle
Go to MCPBundles, enable the Obsidian bundle, and paste your API key. The 35 tools are now available to every AI client connected to your MCPBundles server.
What this looks like in practice
You’re prepping for a team meeting. You tell your AI: “Create meeting notes for the Q2 planning sync with attendees Tony and Sarah, agenda: hiring, roadmap, budget.” A fully structured note appears in your vault with frontmatter, sections, and wikilinks to related project notes.
After the meeting, you tell your AI to append the action items. It doesn’t overwrite your agenda — it surgically appends to the action items section.
Later, you ask your AI to search your vault for everything related to “database migration.” It finds four notes across different projects, reads them, and creates a consolidated summary note linking back to the originals.
You photographed a whiteboard and dropped the image into your vault. Your AI sees the photo, reads the sticky notes, and creates structured tasks in a new project note.
Your vault has grown to 500 notes. You ask your AI to run a health check. It finds 23 orphaned notes, 7 broken wikilinks, and 45 open tasks scattered across 12 files. It creates a maintenance summary with links to every issue.
None of this requires you to leave your AI chat.
Get started
pip install mcpbundles
mcpbundles login
mcpbundles proxy start
Enable the Obsidian bundle, add your API key, and start talking to your vault.
MCPBundles is a hosted platform for connecting AI agents to real third-party services via the Model Context Protocol. 60+ bundles, 1900+ tools — Stripe, HubSpot, Postgres, Gmail, Obsidian, and more. Get started free.