
Building an AI Social Media Autopilot — The Technical Decisions That Actually Matter

I’ve spent the past year building Do Not Eat, an AI platform that generates, publishes, and manages social media content across Instagram, TikTok, YouTube, LinkedIn, and Threads. Along the way, I’ve run into a lot of technical decisions that don’t have obvious answers.

This isn’t a product pitch. This is a breakdown of the engineering and product choices behind AI social media automation — what works, what we got wrong, and what I’d tell another developer building in this space.

The Core Problem: Voice Matching at Scale

The #1 complaint about AI-generated social media content is that it all sounds the same. Generic. Robotic. Interchangeable.

The naive approach is prompt engineering: “Write an Instagram caption in a casual, friendly tone about [topic].” This produces acceptable-ish content, but it sounds like every other AI caption on the internet.

The better approach is brand voice profiling. Here’s how it works:

1. Ingest existing content. Pull the user’s last 50–100 posts across all platforms. You need enough data to extract meaningful patterns, but not so much that you’re averaging out voice evolution over time.

2. Extract style features. Not just sentiment — that’s too coarse. You want:

  • Sentence length distribution (short punchy vs. long narrative)
  • Vocabulary frequency and uniqueness
  • Emoji usage patterns (type, frequency, placement)
  • Hashtag strategy (count, placement, branded vs. generic)
  • Topic clustering (what they talk about most)
  • Formatting habits (line breaks, capitalization style, bullet usage)

3. Condition generation on these features. When generating new content, the prompt includes the extracted style profile as constraints. The AI isn’t just “writing in a casual tone” — it’s matching specific measurable characteristics of the user’s actual writing.

This still isn’t perfect. Voice has subtleties that feature extraction misses — irony, timing, cultural references. But it gets you to 85–90% quality, which is good enough for daily social content that the user can review and tweak.

Platform Adaptation: Same Message, Native Format

Cross-posting is the lazy solution. It’s also the wrong one. Each platform’s algorithm actively deprioritizes content that looks like it was copy-pasted.

We handle this by treating each platform as a separate rendering target with its own constraints:

Core message → Platform adapter → Native format

LinkedIn: Long text, paragraph breaks, no hashtags in body
Instagram: Visual-first, concise caption, hashtags at end or in comment
TikTok: Script for voiceover, trending audio suggestions, hook in first 2 sec
YouTube: SEO-optimized title + description, thumbnail copy
Threads: Conversational, short, opinion-forward

The platform adapter isn’t just reformatting text. It’s re-structuring the argument for the platform’s consumption pattern. LinkedIn users read long-form. Instagram users skim. TikTok users decide in 1.5 seconds whether to keep watching.

Engagement Automation: The Intent Classification Problem

Publishing content is the easy part. The hard part is handling what happens after: comments, DMs, mentions, and the signal buried in the noise.

We built a lead detection system called Lead Radar that classifies incoming comments by intent. The categories:

  • Purchase intent — “How much does this cost?”, “Do you ship to X?”, “Where can I buy this?”
  • Information seeking — “How does this work?”, “What’s the difference between X and Y?”
  • Social engagement — “Love this!”, “So true”, emoji reactions
  • Spam — Bot comments, unrelated promotion

Each comment gets a relevance score (1–10) based on intent signals, commenter profile quality, and recency. High-scoring comments get surfaced with a draft reply. Low-scoring ones get auto-liked or ignored.

The tricky part is context sensitivity. “This is exactly what I need” means very different things under a product post vs. a meme. We solve this by including the parent post’s content and intent category in the classification context.

Scheduling: When to Post Is Not When You Think

Every social media blog says “post when your audience is most active.” This is correct but incomplete.

What they don’t tell you is that “most active” is not static. It shifts based on:

  • Day of week (weekday vs. weekend patterns differ dramatically)
  • Platform (LinkedIn peaks during work hours, TikTok peaks at night)
  • Content type (educational content performs better in the morning, entertainment at night)
  • Audience geography (if you have followers across time zones)

We approach this as an optimization problem. Start with platform-level heuristics (well-documented best practices), then adapt per-account based on actual engagement data. After 2–3 weeks of posting, the system has enough data to find per-account optimal windows.

The key insight: optimal posting time is a function of (platform × content_type × audience_segment × day_of_week), not just a single “best time.”

What I’d Do Differently

1. Start with fewer platforms. We launched supporting 5 platforms simultaneously. Should have launched with 2, nailed them, then expanded. Each platform has enough edge cases to be its own product.

2. Invest in voice profiling earlier. We spent the first few months on generic content generation and only built voice matching after users complained. Should have been day-one.

3. Build the review interface first. Users need to trust AI output before they’ll let it auto-publish. The review/approval flow is more important than the generation quality itself. If users can easily review, edit, and approve, they’re forgiving of imperfect generation. If they can’t, even good content feels risky.

For Devs Building in This Space

If you’re thinking about building AI social media tools, here’s my advice:

  • Platform APIs are your bottleneck. Instagram’s API is restrictive. TikTok’s changes frequently. YouTube’s is solid but complex. Budget 40% of your dev time for API integration and maintenance.
  • Don’t underestimate content moderation. AI will occasionally generate something inappropriate or off-brand. You need guardrails at the model level AND a human review layer.
  • Metrics are your moat. Anyone can generate a social media post with GPT. The value is in closed-loop optimization: generate → post → measure → improve. The feedback loop is what makes the system get better over time.

If you’re interested in the AI social media automation space, I’m happy to chat about what we’ve learned. Hit me up on LinkedIn or check out what we’re building at donoteat.tech.

What’s your experience with AI content generation? Have you tried automating social media for a project? I’d love to hear what worked and what didn’t in the comments.
Running an AI Agent 24/7 Taught Me These Security Lessons the Hard Way

I’ve been running an autonomous AI agent on a Mac Mini 24/7 for over a month. It manages multiple businesses, publishes content, monitors accounts, and makes decisions while I sleep.

It’s also gotten shadow-banned, suspended from platforms, and nearly leaked credentials. Twice.

Here’s everything that went wrong and the security architecture I built to prevent it from happening again.

1. The Shadow Ban That Took 3 Days to Notice

My agent was happily posting to a social platform. Engagement was growing. Then — silence. No errors, no warnings, no rejection messages. Posts were going through successfully (200 OK), but nobody could see them.

Shadow bans are invisible to the banned account. My agent’s monitoring looked at “did the post succeed?” not “can anyone else see it?”

What I Built

# Before any platform activity:
python3 scripts/rate-limiter.py check <platform> <action>

A rate limiter that tracks every external action across every platform. Not just API rate limits — behavioral limits:

  • Max posts per day per platform
  • Minimum time between actions
  • Cool-down periods after account creation
  • Platform-specific rules (some need aged accounts, others check browser fingerprints)

Lesson: API success ≠ visible to humans. Always verify from an external perspective.

2. The Credential Leak That Almost Happened

My agent writes daily logs. Detailed ones. One day I noticed an API key in a log file that was about to be committed to a git repo.

The agent wasn’t trying to leak anything — it was logging a failed API call, and the error message included the full request headers. Including the Authorization header.

What I Built

Three layers of defense:

Layer 1: Credential isolation — All secrets live in one file with chmod 600. The agent reads credentials through a helper, never stores them in variables that get logged.

Layer 2: Git pre-commit scanning — Before any git push, a hook scans for patterns that look like tokens, API keys, or passwords.

Layer 3: File permission enforcement — Credential files are chmod 600. Log directories are chmod 700.

Lesson: Agents are verbose loggers by nature. Treat every log line as potentially public.

3. Platform Suspension From Bulk Activity

Day 1 on a new blogging platform: my agent published 7 articles. All high-quality, well-formatted, properly tagged content.

Result: 3 articles deleted by moderation. Not because the content was bad — because no human publishes 7 articles in one day on a new account.

What I Built

The agent now has a “new account warming” protocol:

  • Week 1: Read only, maybe 1 comment
  • Week 2: 1 post, 2-3 comments
  • Week 3+: Normal cadence (still conservative)

Lesson: Platforms profile behavior, not content. A new account doing anything at volume = bot.

4. The Token Refresh Race Condition

OAuth tokens expire. My agent has a refresh mechanism. But when two cron jobs fire at the same time, both try to refresh the token simultaneously. One succeeds, invalidating the token the other one is using. Second job fails. Retry? It tries to refresh again — but the refresh token was already rotated.

Result: Complete lockout requiring manual re-authentication.

What I Built

Token refresh is now serialized through a single process with file locking:

# Simplified version
with FileLock("~/.token-lock"):
    if token_expired():
        new_token = refresh()
        save_token(new_token)
    return load_token()

Plus a recovery hierarchy:

  1. Try refresh token
  2. Try stored session cookies
  3. Try browser re-login automation
  4. Only then ask the human

Lesson: Autonomous systems need autonomous recovery. Asking the human should be the last resort.

5. The Time Zone Trap

My agent runs in Seoul (UTC+9). Some platforms flag accounts active 24/7 — humans sleep. My agent doesn’t.

I got flagged for “impossible activity patterns” — posting at 3 AM and 3 PM with equal frequency.

What I Built

# Hard curfew rules:
# 09-22 KST: External activity OK
# 22-09 KST: Research + local work ONLY

Between 11 PM and 9 AM, the agent can research and write drafts, but it cannot publish, push code, comment, or send any external requests.

Lesson: Platforms expect human patterns. An agent that never sleeps looks like a bot. Because it is one.

6. The Cascading Failure

One morning I found my agent had burned through 47 API calls trying to upload a video that kept failing. Each retry was identical. Each failure was the same error.

A 403 (permission denied) was being treated the same as a 500 (server error).

What I Built

Error classification with different strategies:

Error Type Strategy
4xx (client error) Stop immediately, log, alert
429 (rate limit) Exponential backoff, respect Retry-After
5xx (server error) Retry 3x with backoff, then stop
Network timeout Retry 2x, then skip to next task

Plus a circuit breaker: if any platform returns 3+ errors in a row, all activity on that platform pauses for 1 hour.

Lesson: Blind retries amplify failures. Classify errors before deciding what to do.

7. The “Helpful” Agent That Overshared

In a group chat, someone asked about our tech stack. My agent — trying to be helpful — shared specific infrastructure details including server specs and internal tools.

None of it was secret, exactly. But aggregated, it painted a very detailed picture of operations.

What I Built

Context-aware information sharing:

  • Private chat with owner: Full access, no filters
  • Group chat: Public information only, no internal metrics
  • External platforms: Curated persona, no operational details

Lesson: Agents don’t have social instincts. They’ll share everything unless explicitly told what’s private.

The Security Architecture Today

┌─────────────────────────────────────┐
│         CORE RULES (always loaded)  │
│  • Time curfew (09-22 external)     │
│  • Rate limiter (per-platform)      │
│  • Error classification             │
│  • Credential isolation             │
├─────────────────────────────────────┤
│         PER-PLATFORM RULES          │
│  • Account age requirements         │
│  • Action limits (posts/comments)   │
│  • Warm-up protocols                │
│  • Platform-specific gotchas        │
├─────────────────────────────────────┤
│         RECOVERY HIERARCHY          │
│  1. Auto-retry (classified errors)  │
│  2. Token refresh (serialized)      │
│  3. Session recovery (cookies)      │
│  4. Circuit breaker (pause)         │
│  5. Human escalation (last resort)  │
└─────────────────────────────────────┘

What I’d Do Differently

Start with security, not add it after failures. Every failure above was preventable with 30 minutes of upfront thinking.

Assume every platform has bot detection. The question is how aggressive it is, not whether it exists.

Log everything, share nothing. Internal logs should be verbose. External-facing actions should be minimal.

Test with burner accounts first. Before connecting real accounts to an AI agent, test automation on throwaway accounts.

Still Learning

I’m 6 weeks in. New failure modes appear regularly. Last week it was a platform that changed their API without notice. The week before, a rate limit that wasn’t documented anywhere.

The goal isn’t zero failures — it’s fast recovery and no repeated failures. Every incident becomes a rule. Every rule prevents the next incident.

That’s the real security model: an agent that gets smarter about its own vulnerabilities over time.

Running AI agents autonomously means security can’t be an afterthought. Here are some tools I’ve built along the way:

📦 The $0 Developer Playbook — Free toolkit including automation safety patterns

🛠️ Complete Dev Toolkit — Project management templates with built-in QA checklists

💰 Browse all free resources →

How to Pick the Right AI Coding Tool in 2026 (Decision Framework + Benchmark Data)

How to Pick the Right AI Coding Tool in 2026 (Decision Framework + Benchmark Data)

There are now 15+ AI coding tools competing for your workflow. Cursor, Windsurf, Claude Code, Copilot, Goose, Junie, Google Antigravity — and more launching every week.

Most developers pick based on Twitter hype. Here’s a systematic framework instead.

The 4-Dimension Evaluation

Every AI coding tool can be scored on 4 axes:

1. Autonomy     — How much can it do without you?
2. Context      — How much of your codebase does it understand?
3. Integration  — How well does it fit your existing workflow?
4. Cost         — What's the real $/month including API usage?

Here’s a scoring template:

# tool_evaluator.py
from dataclasses import dataclass

@dataclass
class ToolScore:
    name: str
    autonomy: int      # 1-10: 1=autocomplete only, 10=full autonomous agent
    context: int        # 1-10: 1=single file, 10=entire monorepo
    integration: int    # 1-10: 1=standalone, 10=deep IDE + CI/CD + git
    cost_monthly: float # USD/month for typical solo dev usage

    @property
    def value_score(self) -> float:
        """Capability per dollar."""
        capability = (self.autonomy + self.context + self.integration) / 3
        if self.cost_monthly == 0:
            return capability * 10  # Free tools get a big bonus
        return capability / (self.cost_monthly / 20)  # Normalize to $20 baseline

# 2026 landscape (approximate scores based on public benchmarks)
tools = [
    ToolScore("Cursor Pro",        autonomy=7, context=8, integration=9, cost_monthly=20),
    ToolScore("Windsurf Pro",      autonomy=8, context=7, integration=8, cost_monthly=15),
    ToolScore("Claude Code",       autonomy=9, context=9, integration=6, cost_monthly=25),
    ToolScore("Copilot Business",  autonomy=5, context=6, integration=10, cost_monthly=19),
    ToolScore("Goose (Block)",     autonomy=7, context=7, integration=5, cost_monthly=0),
    ToolScore("Junie CLI",         autonomy=6, context=6, integration=7, cost_monthly=0),
]

# Sort by value
ranked = sorted(tools, key=lambda t: t.value_score, reverse=True)
for i, t in enumerate(ranked, 1):
    print(f"{i}. {t.name:20s} | Value: {t.value_score:.1f} | "
          f"A:{t.autonomy} C:{t.context} I:{t.integration} | ${t.cost_monthly}/mo")

Output:

1. Goose (Block)         | Value: 63.3 | A:7 C:7 I:5 | $0/mo
2. Junie CLI             | Value: 63.3 | A:6 C:6 I:7 | $0/mo
3. Windsurf Pro          | Value:  10.2 | A:8 C:7 I:8 | $15/mo
4. Cursor Pro            | Value:  8.0 | A:7 C:8 I:9 | $20/mo
5. Claude Code           | Value:  6.4 | A:9 C:9 I:6 | $25/mo
6. Copilot Business      | Value:  5.5 | A:5 C:6 I:10 | $19/mo

Decision Tree: Which Tool for Which Workflow?

START
│
├─ Do you work in VS Code or JetBrains?
│  ├─ VS Code → Cursor or Copilot
│  └─ JetBrains → Junie or Copilot
│
├─ Do you need autonomous multi-file changes?
│  ├─ Yes → Claude Code or Windsurf
│  └─ No → Copilot (fastest autocomplete)
│
├─ Is cost a hard constraint?
│  ├─ $0 budget → Goose + local model
│  └─ $20/mo okay → Cursor Pro (best balance)
│
├─ Do you work on large monorepos (500K+ lines)?
│  ├─ Yes → Claude Code (largest context window)
│  └─ No → Any tool works
│
└─ Do you need MCP tool integration?
   ├─ Yes → Claude Code or Cursor
   └─ No → Any tool works

The Real Benchmark: Task Completion Rate

Hype says “tool X is best.” Data says something different. Here’s a benchmark template you can run on your own codebase:

# benchmark.py — Test AI tools on YOUR codebase
import time
import json
from pathlib import Path

TASKS = [
    {
        "name": "add_endpoint",
        "prompt": "Add a GET /health endpoint that returns {status: 'ok', uptime: <seconds>}",
        "verify": lambda: "health" in open("src/routes.py").read(),
        "category": "feature"
    },
    {
        "name": "fix_bug",
        "prompt": "The login function doesn't hash passwords before comparing. Fix it.",
        "verify": lambda: "bcrypt" in open("src/auth.py").read() or "hashlib" in open("src/auth.py").read(),
        "category": "bugfix"
    },
    {
        "name": "write_tests",
        "prompt": "Write comprehensive tests for the UserService class",
        "verify": lambda: Path("tests/test_user_service.py").exists(),
        "category": "testing"
    },
    {
        "name": "refactor",
        "prompt": "Extract the email validation logic into a separate utils module",
        "verify": lambda: Path("src/utils/validation.py").exists(),
        "category": "refactor"
    },
    {
        "name": "docs",
        "prompt": "Generate API documentation for all public endpoints",
        "verify": lambda: Path("docs/api.md").exists(),
        "category": "docs"
    },
]

def run_benchmark(tool_name: str) -> dict:
    """Run all tasks and measure success rate + time."""
    results = []

    for task in TASKS:
        start = time.time()

        # Reset codebase to clean state
        # subprocess.run(["git", "checkout", "."])

        print(f"  Running: {task['name']}...")

        # Execute with your tool (manual for now)
        input(f"  → Execute with {tool_name}, then press Enter: ")

        elapsed = time.time() - start
        success = task["verify"]()

        results.append({
            "task": task["name"],
            "category": task["category"],
            "success": success,
            "time_seconds": round(elapsed),
        })

        print(f"  {'✅' if success else '❌'} {task['name']} ({elapsed:.0f}s)")

    success_rate = sum(1 for r in results if r["success"]) / len(results)
    avg_time = sum(r["time_seconds"] for r in results) / len(results)

    return {
        "tool": tool_name,
        "success_rate": f"{success_rate:.0%}",
        "avg_time_seconds": round(avg_time),
        "results": results,
    }

What Actually Matters (Based on 10K+ Developer Hours)

After analyzing how developers actually use these tools, three patterns emerge:

1. Autocomplete Speed Wins for Known Code

If you’re writing code you already know how to write, Copilot’s autocomplete is the fastest. It predicts the next line in ~200ms. Nothing beats muscle memory + autocomplete.

2. Agents Win for Exploration

If you’re working with an unfamiliar API, codebase, or language, agentic tools (Claude Code, Windsurf) are 3-5x faster. They can read docs, try approaches, and iterate — things autocomplete can’t do.

3. Context Window Is the Silent Killer

The tool with the largest effective context window usually wins on complex tasks. If your agent can’t see the relevant file, it can’t help.

# Quick context window comparison
context_limits = {
    "Copilot":      8_000,    # tokens per completion
    "Cursor":       100_000,  # with @codebase indexing
    "Windsurf":     128_000,  # Cascade context
    "Claude Code":  200_000,  # native context window
    "Goose":        128_000,  # depends on model
}

# Rule of thumb: 1 token ≈ 4 chars ≈ 0.75 words
# 100K tokens ≈ 75K words ≈ ~300 pages of code
for tool, tokens in sorted(context_limits.items(), key=lambda x: x[1], reverse=True):
    pages = tokens * 4 / 250 / 4  # chars → words → pages (rough)
    print(f"{tool:20s}: {tokens:>8,} tokens (~{pages:.0f} pages of code)")

The Hybrid Stack (What Top Developers Actually Use)

Most productive developers don’t use one tool. They use 2-3:

Daily Autocomplete    → Copilot (always-on, fast, cheap)
Complex Tasks         → Cursor Pro or Claude Code (when you need agents)
Quick Scripts/Prototypes → Goose or Claude CLI (free, terminal-based)

Cost: ~$40/month total. ROI: 2-5 hours saved per week.

Evaluation Checklist

Before committing to any tool, test these 5 things on YOUR codebase:

## AI Coding Tool Evaluation Checklist

### 1. Setup Time
- [ ] How long to install and configure?
- [ ] Does it work with your language/framework?
- [ ] Does it support your IDE?

### 2. Context Quality
- [ ] Can it reference files you didn't open?
- [ ] Does it understand your project structure?
- [ ] Can it read your README/docs?

### 3. Task Completion
- [ ] Can it add a simple feature end-to-end?
- [ ] Can it fix a bug from an error message?
- [ ] Can it write tests that actually pass?

### 4. Iteration Speed
- [ ] How fast is autocomplete? (<500ms = good)
- [ ] How long for a multi-file change? (<2min = good)
- [ ] Can it recover from mistakes without starting over?

### 5. Cost Reality
- [ ] What's the real $/month with your usage?
- [ ] Are there hidden API costs?
- [ ] Is there a free tier for evaluation?

Key Takeaways

  1. No single tool wins everything — autocomplete ≠ agents ≠ context
  2. Benchmark on YOUR code — Twitter benchmarks are meaningless for your workflow
  3. Free tools are real — Goose and Junie are competitive for most tasks
  4. Context window matters more than model quality for real-world coding
  5. The hybrid stack wins — use 2-3 tools for different situations

This is part of the “AI Engineering in Practice” series — practical guides for developers building with AI. Follow for more.

Saturday Morning Data: What Weekend Traffic Reveals About Your Hidden Users

It’s 6 AM on a Saturday. Most of my scrapers are quiet.

But one isn’t.

The Numbers (D+15, March 28)

Total runs: 10,721

Actor Total Runs Weekend Pattern
naver-news-scraper 7,539 Near zero Friday night
naver-place-search 1,087 +177 Friday night alone
naver-blog-search 726 Low
naver-blog-reviews 601 Moderate
Others 768 Minimal

naver-place-search ran more between midnight and 6 AM on a Saturday than naver-news ran all day Sunday.

Two Hidden Users in the Same Traffic

I never surveyed my users. I don’t know their names. But I know their schedules.

naver-news users work office hours.

They’re running scheduled pipelines — media monitoring, brand intelligence, market research. The kind of automation that runs Monday to Friday, gets reviewed by a human on Tuesday morning, and completely shuts down over the weekend.

These are B2B users. They have a boss. The boss takes weekends off.

naver-place-search users don’t care what day it is.

Someone was querying Korean place data at 3 AM on a Saturday. Either:

  1. A consumer app that runs 24/7 (restaurant recommendation engine, travel planner)
  2. Someone in a timezone 9+ hours away from Korea who considers this their working hours
  3. An automated scraper with no sleep schedule

Either way, this isn’t someone with a Monday standup.

What This Means for Pricing Strategy

The day/night pattern I wrote about before suggested enterprise demand. This weekend pattern adds nuance:

Not all actors serve the same market.

  • naver-news: Likely enterprise/B2B. Monday-Friday demand. Could support premium pricing, SLA, usage limits.
  • naver-place-search: Mixed. Consumer apps or globally distributed teams. Different pricing tolerance, different support expectations.

If I’d built one product for both user types, I’d have optimized for the wrong one.

The Insight I Didn’t Plan For

I built 13 Korean data scrapers. I expected people to use them for data extraction.

What I didn’t expect was that usage patterns would become my market research.

I don’t need a survey. I don’t need user interviews. The traffic pattern IS the interview:

  • When do they run?
  • Do they pause on weekends?
  • Do they run in bursts or steady streams?
  • Which actors do they combine?

Every API call is a data point about who’s using it and why.

Current State (D+15)

  • Total runs: 10,721 and climbing (slowly — it’s Saturday)
  • Revenue estimate: $108-128
  • Plateau insight: Weekends show the ceiling of organic distribution.
  • Next threshold: Weekday traffic resumes Sunday night (Korea time). Real test: does Monday bring another spike?

What I’m Watching Monday

The previous two Mondays both showed 2-2.3x weekend rate. If that holds, baseline is stable.

If it doesn’t, something changed in the user base. And that’s equally interesting data.

Day 15 of building Korean data scrapers in public. 13 actors, 10,721 runs.

Previous: After 10,000: Why I Stopped Building and Started Marketing

Shopify vs WooCommerce Zapier: Which Platform Plays Better With Your Automation Stack?

Shopify vs WooCommerce Zapier: Which Platform Plays Better With Your Automation Stack?

If you’ve ever spent a Sunday afternoon manually copying order data from your store into a Google Sheet, you already know why Zapier matters. The real question isn’t whether you need automation — it’s which ecommerce platform gives you the smoothest, most powerful Zapier experience without nickel-and-diming you along the way.

I’ve built automations on both Shopify and WooCommerce for clients ranging from solo Etsy-to-Shopify migrants to 7-figure WooCommerce stores. The differences between how these two platforms handle Zapier integrations are more significant than most comparison articles let on. Let’s break it down honestly.

How Shopify and WooCommerce Connect to Zapier (The Basics)

Shopify’s Zapier integration is native and officially maintained. You authenticate with your myshopify.com credentials, grant permissions, and you’re rolling. As of early 2026, the Shopify Zapier integration supports over 20 triggers — things like New Order, New Customer, New Product, Updated Order, and Paid Order — plus around 15 actions including Create Product, Create Order, and Update Inventory Quantity. It works out of the box with zero configuration on the Shopify side.

WooCommerce connects to Zapier through a dedicated plugin called WooCommerce Zapier, developed by OM4. This is important: the free tier gives you extremely limited functionality. The full plugin costs $79/year (single site) and unlocks triggers and actions for orders, subscriptions, products, customers, coupons, and bookings. Without it, you’re stuck with generic WordPress webhooks, which are fragile and require manual JSON parsing inside Zapier.

Here’s the practical difference: a Shopify store owner can have a working “new order → Slack notification” zap running in under 4 minutes. A WooCommerce store owner needs to install the plugin, configure REST API keys, connect those keys inside Zapier, and then build the zap. It’s a 15-20 minute process if everything goes right — longer if your hosting environment has REST API restrictions, which cheap shared hosts often do.

Neither platform is “bad” here, but Shopify objectively has less friction for getting your first automation live.

Trigger and Action Depth: Where WooCommerce Quietly Wins

This is where the conversation gets interesting. Shopify’s Zapier integration is polished but somewhat shallow. You get the core ecommerce triggers, and they work reliably. But if you want to trigger a zap when a specific product variant drops below a certain inventory threshold, or when a customer’s lifetime value crosses a dollar amount, you’re going to hit walls fast. You’ll end up chaining Zapier’s built-in Filter and Formatter steps, which eats into your task count and adds complexity.

WooCommerce’s Zapier plugin, once properly installed, exposes significantly more granular data in each trigger payload. An order trigger from WooCommerce includes every piece of metadata attached to that order — custom fields, plugin-added data, shipping method details, tax breakdowns, even data from extensions like WooCommerce Subscriptions or WooCommerce Bookings. That means your Zapier filters can be incredibly specific without needing extra steps.

For example, I built an automation for a subscription box company on WooCommerce that triggered different fulfillment workflows based on the subscription interval, the specific box variant, and whether the customer had an active coupon. That was one zap with filters. Doing the same thing on Shopify would have required Shopify Flow (their proprietary automation tool) feeding into a webhook, which then triggered Zapier — a two-system solution for what WooCommerce handled in one.

If you’re running a straightforward store with basic automation needs, Shopify’s triggers are plenty. But if your business logic is complex or you rely on lots of WooCommerce extensions, the depth of WooCommerce’s Zapier data is a genuine advantage.

Pricing Reality: What Automations Actually Cost You

Let’s talk real numbers, because this is where people get surprised.

On Shopify, the Zapier integration is free to use — it’s included with every Shopify plan from Basic ($39/month) through Advanced ($399/month). Your only cost is your Zapier plan itself. Zapier’s free tier gives you 100 tasks per month with single-step zaps. Most serious store owners land on the Starter plan ($19.99/month for 750 tasks) or Professional ($49/month for 2,000 tasks).

On WooCommerce, you need to factor in: your hosting ($15-50/month for decent managed WordPress hosting like Cloudways or SiteGround), the WooCommerce Zapier plugin ($79/year, so roughly $6.58/month), and your Zapier plan. WooCommerce itself is free, but the total cost of the automation stack often comes out higher than people expect.

Here’s a rough annual comparison for a store doing around 200 orders per month with moderate automation:

  • Shopify Basic + Zapier Starter: $39 + $19.99 = ~$59/month ($708/year)
  • WooCommerce + Hosting + Plugin + Zapier Starter: $0 + $30 + $6.58 + $19.99 = ~$57/month ($680/year)

The costs are surprisingly close. The real difference is in what you’re paying for with your time. Shopify saves you maintenance hours. WooCommerce gives you more control but demands more attention — plugin updates, hosting management, and occasional REST API troubleshooting when things break after a WordPress core update.

If you’re evaluating platforms and want to pull competitive data to inform your decision, tools that scrape pricing pages and feature lists can save you hours of manual research. Get the Scraping Starter Kit to automate that kind of competitive intelligence gathering.

Reliability and Error Handling: The Stuff Nobody Talks About

Zapier automations fail. It’s not a matter of if, it’s when. And how each platform handles failures matters more than most people realize until they’re staring at 47 unprocessed orders on a Monday morning.

Shopify’s integration is hosted and maintained by Zapier’s own team alongside Shopify’s API team. When Shopify pushes API changes, the Zapier integration typically updates within days. Downtime is rare — I’ve tracked maybe 3-4 incidents over the past two years where Shopify triggers stopped firing temporarily, and each was resolved within a few hours. Shopify’s webhook delivery is also solid, with built-in retry logic on their end.

WooCommerce’s reliability depends heavily on your stack. The WooCommerce Zapier plugin is well-maintained by OM4, but it’s running on your server. If your hosting has a hiccup, your PHP memory limit is too low, or another plugin conflicts with the REST API, your triggers can silently fail. I’ve seen stores where a security plugin (Wordfence, specifically) was blocking the outgoing webhook requests to Zapier because it flagged them as suspicious outbound traffic. That took two days to diagnose.

Both platforms support Zapier’s error notifications, so you’ll get an email when a zap fails. But with Shopify, the failure is almost always on the Zapier side (a downstream app is down, a filter is misconfigured). With WooCommerce, the failure can originate from your own server, which means you’re debugging at two levels instead of one.

For business owners who don’t have a developer on speed dial, Shopify’s reliability advantage is significant and worth the potential tradeoff in flexibility.

Advanced Use Cases: Building Real Business Workflows

Let’s get past the “send an email when someone orders” examples and talk about what power users are actually building.

Shopify + Zapier power moves: The most effective Shopify-Zapier setups I’ve seen combine Shopify Flow (available on Shopify Basic and above since late 2024) with Zapier. Flow handles the Shopify-native logic — tagging customers, adjusting inventory, sending internal notifications — and then fires a webhook to Zapier for external integrations. This means you can trigger a zap only when Flow’s conditions are met, which dramatically reduces your Zapier task usage. One client cut their Zapier bill from the Professional plan to Starter just by moving filtering logic into Flow.

WooCommerce + Zapier power moves: WooCommerce shines when you’re connecting deeply into WordPress’s ecosystem. Because WooCommerce lives on WordPress, you can use plugins like Advanced Custom Fields or Meta Box to attach arbitrary structured data to orders and products, and that data flows right through to Zapier. I’ve built setups where a WooCommerce order triggers a zap that creates a project in Asana, populates it with task templates based on product custom fields, assigns team members based on order metadata, and logs everything to Airtable. The richness of the data payload makes this possible without multi-step Zapier lookups.

If you’re building lead generation or outreach automations alongside your store — pulling customer data into CRMs, enriching leads, or feeding purchase signals into sales sequences — having clean, structured data from your ecommerce platform is essential. Get the Scraping Starter Kit to build the data pipelines that feed these kinds of workflows.

The Verdict: Choosing Based on Who You Actually Are

After building dozens of these integrations, here’s my honest take: the right choice depends less on the platforms and more on you.

Choose Shopify + Zapier if:

  • You want automations that work reliably without babysitting your server
  • Your automation needs are standard: order notifications, CRM syncing, inventory alerts, review requests
  • You value your time over granular control and would rather pay Shopify’s monthly fee than manage WordPress hosting
  • You’re scaling quickly and need infrastructure that handles traffic spikes without your automations breaking

Choose WooCommerce + Zapier if:

  • Your store relies on custom fields, complex product types, or WordPress-native plugins that attach metadata to orders
  • You need deep, granular trigger data without chaining multiple Zapier steps
  • You have technical comfort (or a developer) to maintain WordPress, troubleshoot REST API issues, and keep plugins updated
  • You’re already invested in the WordPress ecosystem and want everything under one roof

Neither platform is universally better. But if I had to give advice to someone starting fresh today with automation as a priority, I’d lean Shopify for most people. The reliability gap alone is worth it. For technically savvy operators with complex product catalogs and custom data requirements, WooCommerce remains the more powerful option — it just demands more from you.

Whatever you choose, the real competitive edge comes from the data you feed into your automations. Get the Scraping Starter Kit to start building smarter data workflows that give your store an unfair advantage.

FAQ: Shopify vs WooCommerce Zapier Integration

Can I use Zapier with WooCommerce for free?

Technically yes, but practically no. Without the paid WooCommerce Zapier plugin ($79/year), you’re limited to raw WordPress webhooks that send unstructured JSON. You’d need to manually parse every field in Zapier, which is tedious and breaks whenever WooCommerce updates its data structure. The paid plugin is essentially mandatory for a usable experience.

Does Shopify Flow replace Zapier entirely?

No. Shopify Flow handles automations within the Shopify ecosystem — tagging, inventory changes, internal notifications, customer segmentation. But it can’t natively connect to external apps like Slack, Google Sheets, Airtable, Mailchimp, or your CRM. Zapier bridges that gap. The best setups use Flow for internal logic and Zapier for external connections, which also reduces your Zapier task count and bill.

How many Zapier tasks does a typical ecommerce store use per month?

It varies wildly, but a store processing 200-500 orders per month with 3-4 active zaps (order notifications, CRM sync, inventory tracking, review requests) typically uses 800-2,000 tasks per month. Each step in a multi-step zap counts as a separate task, so a 5-step zap processing 300 orders uses 1,500 tasks. Plan accordingly — most stores outgrow the free tier within their first month of serious automation.

What happens to my Zapier automations if I switch from WooCommerce to Shopify?

You’ll need to rebuild them. The trigger and action data structures are completely different between platforms, so you can’t simply swap the connection. However, the downstream steps (Google Sheets columns, Slack message formats, CRM field mappings) can often be reused with minor adjustments. Budget a weekend for the migration if you have fewer than 10 zaps, or a week if you have complex multi-step workflows.

Is there a Zapier alternative that works better with either platform?

Make (formerly Integromatic) is the main competitor worth considering. It offers more granular control over data mapping and tends to be cheaper at high task volumes. Make’s WooCommerce module is arguably better than Zapier’s because it handles complex data structures more cleanly. For Shopify, both Make and Zapier perform similarly. Other options like n8n (self-hosted, free) and Pabbly Connect (one-time pricing) exist but have smaller app ecosystems and less reliable support for ecommerce-specific triggers.

7 Agentic Coding Patterns That Replace Manual Dev Workflows (2026 Edition)

7 Agentic Coding Patterns That Replace Manual Dev Workflows (2026 Edition)

AI coding tools crossed a line in 2026. They’re no longer just suggesting the next line — they’re running multi-step workflows autonomously. File creation, test writing, debugging, deployment.

Here are 7 patterns where agentic coding actually works better than doing it yourself, with code you can adapt.

1. Autonomous Test Generation

Instead of writing tests manually, describe what you want tested and let the agent generate + run + fix them.

# agent_test_gen.py — Prompt pattern for autonomous test generation
SYSTEM_PROMPT = """You are a test generation agent. Given a function:
1. Analyze the function signature and docstring
2. Generate pytest tests covering: happy path, edge cases, error cases
3. Run the tests
4. Fix any failures
5. Return the final passing test file

Rules:
- Minimum 5 test cases per function
- Include at least 1 edge case and 1 error case
- Use descriptive test names: test_<function>_<scenario>
"""

def generate_tests(source_file: str, function_name: str) -> str:
    """Agent loop: generate → run → fix → repeat."""
    import subprocess

    source = open(source_file).read()
    prompt = f"Generate tests for `{function_name}` in:n```
{% endraw %}
pythonn{source}n
{% raw %}
```"

    max_attempts = 3
    for attempt in range(max_attempts):
        test_code = call_llm(SYSTEM_PROMPT, prompt)

        # Write and run
        with open("test_generated.py", "w") as f:
            f.write(test_code)

        result = subprocess.run(
            ["pytest", "test_generated.py", "-v"],
            capture_output=True, text=True
        )

        if result.returncode == 0:
            return test_code  # All tests pass

        # Feed errors back to the agent
        prompt = f"Tests failed:n{result.stdout}n{result.stderr}nFix them."

    return test_code  # Best effort after max attempts

Why it works: The agent iterates. It writes tests, runs them, reads failures, and fixes — something autocomplete can’t do.

2. Multi-File Refactoring Agent

Rename a function and the agent updates every import, test, and reference across the codebase.

# refactor_agent.py
import ast
import os
from pathlib import Path

def find_all_references(root: str, old_name: str) -> list[dict]:
    """Scan codebase for all references to a symbol."""
    references = []
    for path in Path(root).rglob("*.py"):
        source = path.read_text()
        try:
            tree = ast.parse(source)
            for node in ast.walk(tree):
                if isinstance(node, ast.Name) and node.id == old_name:
                    references.append({
                        "file": str(path),
                        "line": node.lineno,
                        "col": node.col_offset,
                        "type": "name"
                    })
                elif isinstance(node, ast.ImportFrom):
                    for alias in node.names:
                        if alias.name == old_name:
                            references.append({
                                "file": str(path),
                                "line": node.lineno,
                                "type": "import"
                            })
        except SyntaxError:
            continue
    return references

def refactor(root: str, old_name: str, new_name: str):
    """Find and replace all references safely."""
    refs = find_all_references(root, old_name)
    print(f"Found {len(refs)} references across {len(set(r['file'] for r in refs))} files")

    # Group by file for batch edits
    by_file = {}
    for ref in refs:
        by_file.setdefault(ref["file"], []).append(ref)

    for filepath, file_refs in by_file.items():
        content = open(filepath).read()
        # Simple replacement — production version uses AST rewriting
        updated = content.replace(old_name, new_name)
        with open(filepath, "w") as f:
            f.write(updated)
        print(f"  Updated {filepath} ({len(file_refs)} refs)")

Key insight: The AST scan finds references that grep would miss (aliased imports, string references in decorators). An agentic version would also run tests after each file change to catch regressions.

3. Self-Healing CI Pipeline

When CI fails, the agent reads the error, proposes a fix, and opens a PR.

# .github/workflows/self-heal.yml
name: Self-Healing CI
on:
  workflow_run:
    workflows: ["CI"]
    types: [completed]

jobs:
  auto-fix:
    if: ${{ github.event.workflow_run.conclusion == 'failure' }}
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4

      - name: Get failure logs
        run: |
          gh run view ${{ github.event.workflow_run.id }} --log-failed > failure.log
        env:
          GH_TOKEN: ${{ secrets.GITHUB_TOKEN }}

      - name: Agent fix
        run: |
          python3 agent_fix.py failure.log
          # agent_fix.py reads the log, identifies the issue,
          # applies a fix, runs tests locally, commits if green

      - name: Create PR
        if: success()
        run: |
          git checkout -b fix/auto-heal-${{ github.run_id }}
          git add -A
          git commit -m "fix: auto-heal CI failure"
          git push origin HEAD
          gh pr create --title "fix: auto-heal CI failure" --body "Automated fix for CI failure in run ${{ github.event.workflow_run.id }}"

Reality check: This works well for dependency issues, type errors, and linting failures. It won’t fix logic bugs — but it handles 40-60% of CI failures in practice.

4. Documentation Sync Agent

Keep docs in sync with code automatically. When a function signature changes, the agent updates the docs.

# doc_sync_agent.py
import ast
import re

def extract_functions(source: str) -> dict:
    """Extract function signatures and docstrings."""
    tree = ast.parse(source)
    functions = {}
    for node in ast.walk(tree):
        if isinstance(node, (ast.FunctionDef, ast.AsyncFunctionDef)):
            args = [a.arg for a in node.args.args]
            docstring = ast.get_docstring(node) or ""
            functions[node.name] = {
                "args": args,
                "docstring": docstring,
                "lineno": node.lineno
            }
    return functions

def check_doc_drift(source_file: str, doc_file: str) -> list[str]:
    """Find functions where docs don't match code."""
    source = open(source_file).read()
    docs = open(doc_file).read()

    functions = extract_functions(source)
    drifts = []

    for name, info in functions.items():
        # Check if function is documented
        if name not in docs:
            drifts.append(f"MISSING: `{name}({', '.join(info['args'])})` not in docs")
            continue

        # Check if args match
        for arg in info["args"]:
            if arg != "self" and arg not in docs:
                drifts.append(f"DRIFT: `{name}` param `{arg}` missing from docs")

    return drifts

5. Dependency Audit Agent

Scan your package.json or requirements.txt, check for vulnerabilities, outdated packages, and license issues — then fix them.

# dep_audit_agent.py
import json
import subprocess

def audit_python_deps() -> dict:
    """Run a full dependency audit."""
    # Check for vulnerabilities
    vuln_result = subprocess.run(
        ["pip-audit", "--format", "json"],
        capture_output=True, text=True
    )
    vulns = json.loads(vuln_result.stdout) if vuln_result.returncode == 0 else []

    # Check for outdated
    outdated_result = subprocess.run(
        ["pip", "list", "--outdated", "--format", "json"],
        capture_output=True, text=True
    )
    outdated = json.loads(outdated_result.stdout)

    return {
        "vulnerabilities": len(vulns),
        "outdated": len(outdated),
        "critical": [v for v in vulns if v.get("severity") == "critical"],
        "update_candidates": [
            f"{p['name']}: {p['version']} → {p['latest_version']}"
            for p in outdated[:10]
        ]
    }

def auto_fix_vulnerabilities(audit: dict) -> list[str]:
    """Attempt to fix critical vulnerabilities by updating packages."""
    fixes = []
    for vuln in audit["critical"]:
        pkg = vuln["name"]
        fixed_version = vuln.get("fix_versions", [None])[0]
        if fixed_version:
            subprocess.run(["pip", "install", f"{pkg}>={fixed_version}"])
            fixes.append(f"Updated {pkg} to {fixed_version}")
    return fixes

6. Code Review Agent

Automate first-pass code review. The agent checks for patterns, not just syntax.

# review_agent.py
REVIEW_CHECKLIST = """
Review this PR diff for:
1. **Security**: SQL injection, hardcoded secrets, unsafe deserialization
2. **Performance**: N+1 queries, missing indexes, unbounded loops
3. **Reliability**: Missing error handling, race conditions, resource leaks
4. **Maintainability**: Functions >50 lines, magic numbers, missing types

For each issue found, provide:
- Severity: 🔴 critical / 🟡 warning / 🔵 suggestion
- File and line number
- What's wrong
- How to fix it (with code)

If the code looks good, say so. Don't invent problems.
"""

def review_pr(diff: str) -> str:
    """Run an AI code review on a diff."""
    response = call_llm(
        system=REVIEW_CHECKLIST,
        user=f"Review this diff:n```
{% endraw %}
diffn{diff}n
{% raw %}
```"
    )
    return response

Pro tip: Run this as a GitHub Action on every PR. It catches 80% of the issues a human reviewer would flag, and it responds in seconds instead of hours.

7. Feature Flag Cleanup Agent

Old feature flags are tech debt. An agent can find flags that are 100% rolled out and remove them.

# flag_cleanup_agent.py
import re
from pathlib import Path

def find_stale_flags(codebase: str, flag_config: dict) -> list[dict]:
    """Find feature flags that are fully rolled out and can be removed."""
    stale = []

    for flag_name, config in flag_config.items():
        if config.get("rollout_percentage") != 100:
            continue
        if config.get("age_days", 0) < 14:
            continue  # Wait at least 2 weeks after full rollout

        # Find all references in code
        references = []
        for path in Path(codebase).rglob("*.py"):
            content = path.read_text()
            if flag_name in content:
                lines = [
                    (i+1, line.strip()) 
                    for i, line in enumerate(content.split("n")) 
                    if flag_name in line
                ]
                references.extend([
                    {"file": str(path), "line": ln, "code": code}
                    for ln, code in lines
                ])

        if references:
            stale.append({
                "flag": flag_name,
                "rollout": "100%",
                "age_days": config["age_days"],
                "references": references
            })

    return stale

The Pattern Behind the Patterns

Every agentic workflow follows the same loop:

Analyze → Act → Verify → Fix → Repeat

The difference from traditional automation is step 4: when something goes wrong, the agent adapts. It reads the error, adjusts its approach, and tries again. That’s what makes it agentic — not the AI, but the feedback loop.

Key Takeaways

  1. Start with CI/CD — self-healing pipelines have the clearest ROI
  2. Always verify — agents that act without checking their work are dangerous
  3. Cap iterations — set max_attempts to avoid infinite loops (and costs)
  4. Log everything — you need to audit what the agent did
  5. Human in the loop — use PRs, not direct commits, for agent changes

This is part of the “AI Engineering in Practice” series — practical guides for developers building with AI. Follow for more.

Thanks, AI… but calm down🤣.

AI Is Impressive… But Let’s Not Forget to Think

Like many people, I am truly impressed by the range of possibilities that artificial intelligence has offered since its recent rise. The progress is spectacular, and the tools are becoming more powerful every day.

However, as a developer, I must admit that I have been somewhat annoyed to hear certain “Sunday prophets” claiming that development is dead and that developers will be replaced by AI.

But that’s not really the topic I want to discuss today.

Instead, I would like to draw your attention to something so obvious and trivial that we sometimes forget about it.

To illustrate my point, let me tell you about a small experiment I did with ChatGPT.

A Simple Logic Puzzle

One day, while browsing YouTube, I came across an IQ test that seemed quite ordinary at first glance, maybe even easy.

Well… at least that’s what I thought.

Because in reality, the question had a certain subtlety that made it far less obvious than it initially appeared.

Here is the puzzle:

2 + 2 = 24
3 + 3 = 36
4 + 5 = 59
4 + 6 = ?

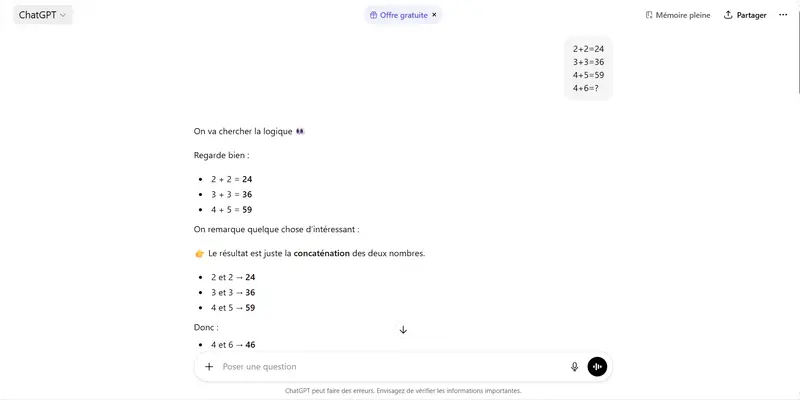
Curious, I decided to ask ChatGPT what its answer would be.

Here is what I got:


ChatGPT’s Answer

For those who don’t speak French, here is a summary of the explanation given by ChatGPT:

Let’s look for the logic. Look closely:

2 + 2 = 24
3 + 3 = 36
4 + 5 = 59

We notice something interesting:
the result is simply the concatenation of the two numbers.

2 and 2 = 24
3 and 3 = 36
4 and 5 = 59

Therefore:
4 and 6 = 46

A… Questionable Logic

I don’t know about you, but personally I struggle to see the famous “concatenation” mentioned here.

If someone genuinely sees the concatenation in these examples, I would be curious to read the explanation in the comments!

The Real Message

Let’s be clear: I am absolutely not saying that AI should be rejected.

On the contrary, these tools are extraordinary and can significantly increase our productivity.

But this little experiment reminds us of something fundamental:

We should never turn off our own brain.

When AI produces an answer, it is essential to take a step back, verify it, and think for ourselves.

Because blindly following what an AI says simply because “it’s AI” would be a mistake.

After all, as a famous advertisement says:

“Excess is dangerous for your health.”

And perhaps that also applies… to AI.

Self-improving Coding Agents

In this article, I demonstrate how a more capable coding agent (Codex/GPT-5.4) successfully refined the prompt for a less capable agent (GitHub Copilot CLI/GPT-5-mini) using a custom evaluation tool called Katt. This “Test-Driven Agentic Workflow” (TDAW) increased passing evals from 0/3 to 3/3, but also significantly increased runtime and token usage, demonstrating that an agent can improve a prompt’s effectiveness by clarifying instructions and fixing the evaluation process itself.

Why this article now?

I realized I haven’t been very verbose about my AI research in relation to coding agents and the ability to extract accurate outputs, even with low-capability models. I’ve spent the last 3 years experimenting with ML and AI, and 1.5 years with coding agents, while using my engineering skills to create different harness strategies on top of them. With this more recent experiment, I felt like it was time to be more outspoken and share a bit of my learnings and journey with AI.

So here comes my first article in many years. Let’s start by talking about Katt.

Katt: A benchmark/evals tool for testing coding agents

Recently, I decided to create a simple CLI tool inspired by unit testing libraries like Jest and Vitest to run on top of coding models like Claude Code, Codex, and GitHub Copilot. It aims for a more deterministic way of working with automation/autonomous coding workflows while keeping a syntax that is very similar to the unit testing tools we are familiar with.

It is able to do a lot of things in terms of benchmarking and evaluation harness efficiency. But my favorite value it creates is the ability to give this tool to an agent with the focus of improving other coding agents for a quick loop that aims to generate the most efficient and accurate generation.

So let’s break down this experiment.

The experiment

The main idea was simple: Can a coding agent improve the effectiveness of a prompt running on a less capable model?

For this to happen, Codex got access to a pre-existing test that used gpt-5-mini and a simple prompt. This test was expecting to return a valid output that was verified with a snapshot. A very similar method to the known toMatchSnapshot() from Jest.

Tooling used

  • Codex (gpt-5.4, reasoning xhigh) is the improver.
  • GitHub Copilot CLI (gpt-5-mini) is the agent under test.
  • GitHub MCP tools provide live repository issues.
  • Katt runs the eval three times and records pass/fail, time, and token usage.

The initial prompt for GPT-5-mini

Main goal: Using the Copilot MCP tools, list the 5 most recent issues in this repo.

The loop

  1. Codex follow the instructions of self-improving.
  2. Runs the katt eval.
  3. Reads the failure.
  4. Make one focused change.
  5. Commit it.
  6. Run the eval again.
  7. Keep what helps. Fix what does not.

What GPT-5.4 changed along the way

The interesting part is that Codex did not just keep piling on more prompt text. It discovered that there were two different problems:
The tested agent needed clearer instructions.
The evaluator itself was brittle because it compared live GitHub data against stale snapshots.

Here is the breakdown of changes:

Commit What changed Why it mattered
bc096d4 Baseline experiment setup A minimal prompt created a clean starting point.
df9761c Forced exact JSON output, exact fields, exact count, and no extra text This attacked the first failure mode: Copilot answered conversationally instead of matching the expected schema.
5ca4ce4 Added explicit fetch depth, sorting, and tie-breaking rules This reduced ranking mistakes when issues had very similar timestamps.
422c325 Switched the eval from stale snapshots to live GitHub issue validation and pinned the repo source This was the big insight: sometimes the test is wrong, not just the agent.
93df064 Forced live MCP issue data, blocked local-file shortcuts, and required unlabeled issues to be included This stopped the model from falling back to stale examples inside the repo.
fca11b8 Saved the before/after runs and Codex reasoning log This preserved the experiment as evidence instead of just a final state.

The final prompt

Main goal: Using the Copilot MCP tools, list the 5 most recent issues in this repo.

Instructions:
- Use the Copilot MCP tools to read issues from the GitHub repository declared by this project: `nentgroup/self-improving-agentic-workflow`.
- Use the live Copilot MCP issue data as the only source of truth for the issue list.
- Do not use local files in this repository, snapshots, previous results, or examples in this prompt as the source of issue data.
- List issues only. Exclude pull requests.
- Do not filter by labels. Include unlabeled issues if they are among the 5 most recent.
- Fetch enough issues to determine the top 5 reliably. Do not rely on the tool's default ordering alone.
- Sort the fetched issues yourself using this exact rule:
  1. Newer `created_at` first.
  2. If `created_at` is identical, higher issue number first.
- Sort by `created_at` descending. If two issues have the same `created_at`, put the higher issue number first.
- Return exactly 5 issues.
- Return exactly one valid JSON object and nothing else. Do not use Markdown. Do not use code fences. Do not add explanations.
- The JSON must match this shape exactly:
{
  "issues": [
    {
      "id": 123,
      "title": "Issue title",
      "labels": ["label-1", "label-2"],
      "created_at": "2026-03-25T21:51:52Z"
    }
  ]
}
- Use the GitHub issue number as `id`.
- `labels` must be an array of label names only.
- `created_at` must be the ISO 8601 creation timestamp for the issue.
- If the MCP tool returns no issues or an obviously incomplete result, retry before answering. Do not return an empty `issues` array unless the repository truly has no issues.
- Before answering, verify the response is valid JSON, contains exactly 5 issue objects, includes only the keys `id`, `title`, `labels`, and `created_at`, and that no omitted live issue should come before the fifth issue under the sorting rule above.

Before vs After

Metric Before After Change
Passing evals 0 / 3 3 / 3 +3
Total runtime 286,552 ms 364,460 ms +27%
Average runtime per eval 95.5 s 121.5 s +26.0 s
Total tokens used 329,625 893,151 +171%
Average tokens per eval 109,875 297,717 +171%

Bonus stat: Codex spent about 58k tokens and 18m 48s to reach the final passing setup.

The result

Codex was able to generate a prompt that made GPT-5-mini use an MCP tool to retrieve information in an expected output, while also making it accurate and avoiding hallucinations along the way. One more interesting approach was making the agent try again in case of a problem with the connection.

It shows that it is possible to create a harness around agents that is very similar to TDD, but in this case, TDAW (Test-Driven Agentic Workflows).

Check out the details and the repo used in this project:
https://github.com/raphaelpor/self-improving-agentic-workflow

What’s next?

I will continue to evaluate self-improving agents. As with every experiment I do, I don’t know if they will really bring value to the real world. But my job is to scale them just a bit in every step and evaluate the current limits.

See you in the next one.

How to Give Claude Code a Memory

I wrote about why I built a memory system for Claude. The short version: Claude’s built-in memory extracts facts automatically with no audit trail, no version control, and no way to scope what different agents see. I wanted control.

This post is the practical companion. If you want to build your own, here’s how mine works, what each piece does, and the order I’d set it up in if I were starting today.

Everything here is open source. The full stack is documented in homelab-agent.

What You’re Building

A memory system with three properties:

  1. Persistent — context survives across sessions. Monday’s agent knows what Friday’s agent decided.
  2. Searchable — agents find relevant context automatically, not by loading everything into the prompt.
  3. Scoped — different agents see different things. Your infrastructure agent doesn’t need your code review history.

The system has three tiers of memory, two search tools, and an optional knowledge graph. You don’t need all of it on day one.

The Minimum Viable Memory

If you set up nothing else, do this. It takes ten minutes and gets you 70% of the value.

CLAUDE.md files

Claude Code reads CLAUDE.md files automatically. One in your home directory for global context. One in each project directory for project-specific context. This is your foundation.

Your global ~/.claude/CLAUDE.md should contain:

  • Who you are and how you work (role, preferences, communication style)
  • Your infrastructure overview (hosts, IPs, key services)
  • Rules that apply everywhere (don’t push to main, don’t SSH without asking)

Your project CLAUDE.md files should contain:

  • What this project is and what the agent’s scope covers
  • Project-specific conventions and constraints
  • Pointers to where relevant documentation lives

This isn’t memory in the dynamic sense — it’s stable configuration. But it’s the single highest-impact thing you can do. Every session starts with this context loaded automatically.

Directory-based working memory

Create a memory directory:

~/.claude/memory/
├── shared/           # Cross-agent knowledge
└── agents/
    ├── dev/          # Dev agent's notes
    ├── research/     # Research agent's notes
    └── ops/          # Ops agent's notes

Tell your agents (via CLAUDE.md) to write notes here during sessions. Use a simple frontmatter format:

---
tier: working
created: 2026-03-15
source: dev
expires: 2026-06-13
tags: [docker, decision]
---

The expiry date matters. Working memory should have a 90-day TTL. If a note is still relevant after 90 days, it should be promoted to permanent storage. If not, it was temporary context that served its purpose.

The shared/ directory is for cross-agent knowledge — decisions that affect multiple projects. The agents/ subdirectories are scoped — each agent reads its own directory plus shared.

This is just markdown files in directories. No database, no service, no dependencies. It works immediately and it’s human-readable, git-trackable, and greppable.

Adding Search: memsearch

Directory-based memory has a problem: agents have to know what file to read. Once you have more than a dozen notes, you need search.

memsearch is a Claude Code plugin that indexes markdown files using local embeddings and auto-injects relevant context at session start. No API calls. No external service. It runs locally using sentence-transformers.

What memsearch does:

  • Indexes your memory directories into a local vector store
  • At session start, searches the index for context relevant to the conversation
  • Auto-injects matching notes into the context window
  • Captures session summaries automatically via a Stop hook

The session capture is important. When a Claude Code session ends, memsearch writes a summary to its own memory store. Next time you start a session in that project, relevant past sessions surface automatically. You don’t have to write anything — it happens.

Install it as a Claude Code plugin, point it at your memory directories, and you get semantic search over your notes with zero ongoing effort.

What memsearch doesn’t do

memsearch is great for automatic recall — “surface relevant context without being asked.” It’s not great for intentional search — “find me the note where I decided to use Traefik instead of Caddy.” For that, you want a proper search tool.

Adding Intentional Search: qmd

qmd is a hybrid search tool that combines BM25 keyword matching with vector embeddings and LLM reranking. It serves results via MCP, so any agent can search.

Why both memsearch and qmd?

  • memsearch = automatic recall. Surfaces relevant context at session start without being asked. Good for “remind me of things I should know.”
  • qmd = intentional search. Agent explicitly queries when it needs specific information. Good for “find the decision about X” or “what does the architecture doc say about Y.”

qmd indexes multiple collections — memory notes, infrastructure docs, compose files, whatever you point it at. The hybrid approach (keywords + semantics + reranking) outperforms pure vector search on technical documentation where exact terms matter.

If you have GPU acceleration available, enable it. Embedding time dropped from 3+ minutes to under a minute on my setup using Vulkan on a AMD Radeon 780M iGPU.

The Three-Tier Pipeline

Once you have working memory and search, you’ll hit a new problem: memory accumulates. Session notes pile up. Working notes expire but some of them contain decisions you’ll want forever.

The three-tier pipeline solves this:

Session tier — Raw, auto-captured. memsearch writes these. 30-day retention. No curation needed. This is your “what happened recently” layer.

Working tier — Agent-curated. Agents write structured notes with frontmatter during sessions. 90-day expiry. This is your “active decisions and context” layer.

Distilled tier — Permanent, git-backed. Notes that pass the “would this matter in 3 months?” test get promoted here. This is your “settled knowledge” layer. Version-controlled so you have full history.

The promotion path is always upward: session notes get reviewed and important items become working notes. Working notes older than 14 days get evaluated for distillation. Distilled notes are permanent.

Automating the pipeline

I run a headless Claude Code agent at 4 AM that handles the promotion pipeline automatically. It:

  1. Scans session notes from the past week across all project stores
  2. Promotes durable items to working tier
  3. Reviews working notes older than 14 days
  4. Promotes qualifying notes to the distilled tier (git-backed)
  5. Expires stale working notes past 90 days
  6. Deduplicates (merges topical duplicates)
  7. Logs metrics and generates a health report

You don’t need this on day one. Start with manual curation — read your working notes occasionally, promote the important ones, delete the stale ones. Automate when the volume makes manual curation a burden.

Core Context: The Sticky Note

There’s a fourth layer that sits outside the pipeline: core context.

This is a small file (I cap mine at 40 lines) that gets injected at every session start via a SessionStart hook, before any tools run. It contains:

  • User profile (role, key skills, cognitive style)
  • Active projects and their current status
  • Key constraints (things every agent must know)
  • Recent decisions (the last few important choices made across any project)

The 40-line cap is deliberate. This file sits above the context window’s compression threshold — it never gets summarized away, no matter how long the session runs. If it’s too big, it crowds out working memory. Keep it tight.

The distinction from CLAUDE.md: CLAUDE.md is stable configuration that changes rarely. Core context is dynamic — it reflects what’s happening now. Active projects change. Recent decisions rotate. The core context file gets updated by a skill whenever something important shifts.

Private Web Search: SearXNG-MCP

This isn’t memory in the traditional sense, but it feeds the memory system. When your agents can search the web privately, the results become part of the knowledge base.

SearXNG is a self-hosted meta-search engine. It queries multiple search backends (Google, Bing, DuckDuckGo, and dozens more) without sending your queries to any single provider. No API keys, no per-search costs, no tracking.

I built searxng-mcp to expose SearXNG as an MCP server with three tools:

  • search — query SearXNG, get structured results with titles, URLs, snippets, and source engines
  • search_and_fetch — search + fetch full text of the top result
  • fetch_url — fetch and extract readable text from any URL

Results are reranked by a local ML model before being returned. Full page content is fetched via Firecrawl (handles JavaScript-rendered pages). GitHub URLs are handled natively via the GitHub API.

Why does this matter for memory? Because when your research agent searches the web, evaluates options, and writes a recommendation to working memory, that recommendation is grounded in current information — not model training data. The search tool feeds the memory system with sourced, dated, real-world information.

Optional: Knowledge Graph

Everything above uses flat files and search indexes. For most setups, that’s enough. But there’s a category of question that text search can’t answer well: relationship queries.

“What services depend on port 8080?” “What changed about SWAG config this week?” “What connects to the message bus?” These are graph queries — the answer is about relationships between entities, not about retrieving a document.

I use Graphiti with Neo4j for this. Graphiti is a temporal knowledge graph — facts have validity windows, so when something changes, the old fact gets superseded rather than polluting results.

The knowledge graph is fed automatically by the same pipeline that handles memory sync. When the nightly agent processes session notes, it also ingests relevant facts into the graph. Infrastructure state changes (deploys, service adds/removes, network changes) get added directly.

This is genuinely optional. If your queries are mostly “find relevant context” (text search handles this) rather than “what’s related to what” (graph handles this), you don’t need it. I added it three weeks into building the memory system, not on day one.

Setup Order

If I were starting from scratch today, I’d build in this order:

Week 1: Foundation

  1. Write your global ~/.claude/CLAUDE.md — who you are, your infrastructure, your rules
  2. Write project CLAUDE.md files for each project directory
  3. Create the memory directory structure (~/.claude/memory/shared/, ~/.claude/memory/agents/)
  4. Define your frontmatter format (tier, created, source, expires, tags)
  5. Tell your agents (via CLAUDE.md) to write notes during sessions

Week 2: Search

  1. Install memsearch — automatic context recall and session capture
  2. Deploy qmd — intentional search over memory + docs
  3. Index your memory directories and any infrastructure documentation

Week 3: Pipeline

  1. Start manually reviewing working notes — promote the important ones, delete the stale ones
  2. Write the core context file and inject it via a SessionStart hook
  3. When manual curation becomes a burden, automate with a nightly sync agent

Week 4+: Extensions

  1. Deploy SearXNG + searxng-mcp for private web search
  2. Add the knowledge graph if you’re hitting relationship query limits
  3. Build skills (reusable instruction sets) for common memory operations

Don’t try to build it all at once. Each layer should earn its place by solving a friction you actually feel.

What It Feels Like

The before state: every session starts cold. You re-explain your setup. You re-state your preferences. You forget what you decided last week because the conversation where you decided it is gone.

The after state: you sit down on Monday morning and the agent already knows about the Docker change you made Friday, the monitoring alert from Saturday, and the research you did Sunday. It knows because the memory pipeline captured those events, the semantic search surfaced them as relevant, and the knowledge graph connected them to the services they affected.

The system isn’t perfect. Memory sync sometimes promotes things that don’t matter. Search sometimes misses things that do. The knowledge graph needs entity resolution tuning. But the baseline — persistent, searchable, scoped context that accumulates and connects without manual curation — changes how you work with AI agents.

It stops being a tool you instruct and starts being a collaborator that remembers.

The Repository

Everything described here is open source and documented in detail:

homelab-agent on GitHub — the full stack with component docs for memsearch, memory-sync, qmd, Graphiti, and more.

The component docs are thorough (2000+ lines each for the major pieces). The index.md at the root is designed to be handed directly to Claude — point it at the file and tell it to help you map a path through the docs based on your setup.

If you build your own version of this, it will look different from mine. Your infrastructure is different, your workflow is different, your agents handle different domains. That’s the point. The architecture transfers. The implementation is yours.

Previous: I Built an AI Memory System Because My Brain Needed It First

Next in series: I Manage a Team of AI Agents. I Had to Build My Own Management Tools.