A Note on Decoded and Patterns

While learning programming, solutions are sometimes memorized instead of understanding the logic behind them.

To make learning a bit clearer, I built two small apps:

  1. Decoded — to understand how DSA problems are solved
  2. Patterns — to understand how pattern problems work

Both focus on explaining the approach, rather than just showing code.

Decoded

Decoded helps learners understand commonly asked DSA problems visually.

Instead of only showing code, the platform explains how the algorithm works step by step.

Some of the things it includes:

  • Animated dry run of the algorithm with user input
  • Time and space complexity explanations
  • Follow-up questions to explore the problem more deeply
  • Explanations of data structures, their operations, and complexities
  • Common problem patterns like two pointers, sliding window, etc.
  • Tips on how to recognize patterns and avoid common mistakes

The goal is to help learners understand what the problem is asking and how to approach it.

Patterns

Pattern problems are some of the first exercises we encounter while learning programming.

The Patterns app shows different types of patterns such as:

  • Star patterns
  • Number patterns
  • Alphabet patterns
  • and more

Each pattern includes:

  • the pattern itself
  • the logic behind it
  • a JavaScript implementation

Understanding these problems helps beginners learn how loops and conditions work together.

Both apps focus on one simple idea:

Programming becomes easier when you understand the logic, not just the code.

If you’re learning programming, feel free to explore them:


Teaching Coding Agent to Write XSLT — Building a Domain Skill

XSLT is unforgiving. Small mistakes — a wrong namespace, a version mismatch, an engine-specific function — produce silent failures. AI assistants make the same mistakes without explicit guidance.

The fix isn’t a smarter model. It’s giving the model a playbook.

Claude Code supports custom skills — markdown files that load into context when a task matches. I built one that encodes real XSLT expertise: five work modes, engine detection, version discipline, and structured output you can debug immediately.

What is a Claude Code skill?

A skill is a markdown file in .claude/skills/<name>/SKILL.md. When Claude detects a matching task, it reads the skill and follows its instructions. Reference files alongside it provide deeper detail on demand.

.claude/skills/xslt/
├── SKILL.md                        # modes, rules, output spec
└── references/
    ├── lml.md                      # Logic Apps Mapping Language
    ├── logicapps-xslt.md           # Logic Apps deployment and artifacts
    ├── saxoncs-quirks.md           # SaxonCS / XSLT 3.0 gotchas
    ├── biztalk-xslt.md             # BizTalk map authoring
    └── migration.md                # version migration guide

Mode detection

The skill first classifies the task into one of five modes:

Mode Trigger
Generate XML samples, schemas, “write me an XSLT”
Debug Broken XSLT, error message, wrong output
Migrate “Convert to 3.0”, “rewrite as 1.0”
Compatibility “Will this run in BizTalk?”
LML .lml file, Data Mapper, “compile to XSLT”

Generate and LML produce an output bundle. Generate writes up to three artifacts (debug config, sample input, stylesheet). LML writes up to four core artifacts (debug config, sample input, LML source, compiled XSLT) — plus schemas and custom functions if the map needs them. The other modes produce artifacts only when needed.

Engine classification

This is where most AI-generated XSLT fails. The skill forces engine classification before any code is written:

  • BizTalk / XslCompiledTransform / msxsl:script → XSLT 1.0, compiled engine
  • Logic Apps (Transform XML action) → XSLT 1.0 by default
  • Saxon / SaxonCS → XSLT 2.0 or 3.0, saxonnet engine

If ambiguous, Claude must ask. It never assumes. This single rule prevents the most common failure: writing XSLT 2.0 features in a file that .NET XslCompiledTransform will choke on.

Version discipline

Never auto-upgrade. If the stylesheet says version="1.0", output stays 1.0. No sneaking in xsl:function, matches(), or xsl:sequence.

For 1.0, the skill enforces:

  • xsl:for-each only — no xsl:for-each-group
  • contains(), substring(), translate() — not matches(), replace()
  • Named templates, not xsl:function

Inline C# for XSLT 1.0

Pure XSLT 1.0 has gaps — no regex, no date formatting. The msxsl:script extension fills them with inline C#:

<msxsl:script language="C#" implements-prefix="fn">
  <![CDATA[
    public string ReformatDate(string isoDate) {
      if (System.DateTime.TryParse(isoDate, out System.DateTime dt))
        return dt.ToString("dd/MM/yyyy");
      return isoDate;
    }
  ]]>
</msxsl:script>

The skill knows the type mappings (XPath numbers → double, node-sets → XPathNodeIterator) and the constraint: msxsl:script runs on .NET XslCompiledTransform only, never Saxon.

Canonical skeletons

The skill provides starting templates so Claude doesn’t construct structure from scratch.

XSLT 1.0 + inline C#:

<xsl:stylesheet version="1.0"
  xmlns:xsl="http://www.w3.org/1999/XSL/Transform"
  xmlns:msxsl="urn:schemas-microsoft-com:xslt"
  xmlns:fn="urn:my-functions"
  exclude-result-prefixes="msxsl fn">
  <xsl:output method="xml" indent="yes"/>
  <!-- msxsl:script block, then templates -->
</xsl:stylesheet>

XSLT 3.0 / SaxonCS:

<xsl:stylesheet version="3.0"
  xmlns:xsl="http://www.w3.org/1999/XSL/Transform"
  xmlns:xs="http://www.w3.org/2001/XMLSchema"
  exclude-result-prefixes="#all"
  expand-text="yes">
  <xsl:output method="xml" indent="yes"/>
  <xsl:mode on-no-match="shallow-skip"/>
  <!-- templates -->
</xsl:stylesheet>

LML-generated XSLT 3.0 uses different conventions (mode="azure.workflow.datamapper", explicit namespace exclusions). The skill tracks both so Claude doesn’t confuse them.

Debug taxonomy

For Debug mode, Claude classifies the bug before attempting a fix:

Class Danger
Namespace mismatch — empty output, XPath returns nothing High — exit code 0, looks like success
C# compile error — Roslyn error in msxsl:script Obvious — exit code 1
Template priority conflict — wrong template fires Medium
Version mismatch — works in Saxon, fails in .NET Medium

Namespace mismatch is the most dangerous: the transform succeeds with valid XML structure but every value is empty.

The output bundle

For Generate and LML modes, the skill requires a complete output bundle.

Generate mode writes:

  1. Launch config — appended to .vscode/launch.json
  2. Sample input XML — if none exists for the source schema
  3. Stylesheet — the .xslt file

LML mode writes (order matters):

  1. Source and target schemas — XSD files in Artifacts/Schemas/, if not already present
  2. Launch config — points at the compiled .xslt
  3. Custom extension functions — if the map uses them (must be written before LML compiles)
  4. Sample input XML — if none exists for the source schema
  5. LML file — written last (compile hook fires on this)
  6. Compiled XSLT — generated automatically by the compile hook

A launch config:

{
  "name": "Debug Order2Shipment",
  "type": "xslt",
  "request": "launch",
  "engine": "saxonnet",
  "stylesheet": "${workspaceFolder}/Artifacts/Maps/Order2Shipment.xslt",
  "xml": "${workspaceFolder}/Artifacts/SampleData/Order.xml",
  "output": "${workspaceFolder}/Artifacts/Maps/out/Order2Shipment-out.xml",
  "stopOnEntry": true
}

output is optional — omit it to see results in the Debug Console only. Press F5 and debug with breakpoints — no manual setup.

LML mode: custom functions and gotchas

LML maps can call custom functions in Artifacts/DataMapper/Extensions/Functions/*.xml:

<customfunctions>
  <function name="reformatDate" as="xs:string">
    <param name="dateVal" as="xs:date"/>
    <value-of select="format-date($dateVal, '[D01]/[M01]/[Y0001]')"/>
  </function>
</customfunctions>

The skill documents SDK bugs Claude needs to work around:

  • Zero-parameter functions crash the compiler — NullReferenceException, entire XML file silently skipped. Workaround: add a dummy <param>.
  • Multi-step paths in function arguments fail — wrap in xpath().
  • Bare @attr is invalid YAML — use xpath("@lineNum").

What the skill doesn’t do

The skill is domain knowledge and rules. It doesn’t run anything — that’s the job of hooks (Part 2). It doesn’t validate XSLT at runtime — that’s the debugger.

Its value is preventing mistakes before they happen. Part 2 covers the hooks that catch errors at write time.

The XSLT Debugger extension is on the VS Code Marketplace for macOS and Windows.

How to Build a Competitor Pricing Change Monitor That Alerts You When a Rival Updates Their Pricing Page

Your competitor just dropped their price by 30% and added a free tier. You found out when a prospect said “I saw they now offer that for free” — three weeks after it happened.

Pricing changes are some of the highest-signal competitive events in B2B markets. A price cut means they’re under pressure. A new free tier means they’re repositioning. A plan removal means something isn’t converting. Every one of these is an opportunity to update your positioning, arm your sales team, or reach out to churned accounts.

But most companies have no system for catching this signal. You refresh the competitor’s pricing page manually when you remember, or hear about it from a prospect during a call. By then, the window has already passed.

This post shows you how to build an automated monitor that watches competitor pricing pages daily and fires a Slack alert the moment something changes — for under $8/month.

The Gap in Your Competitive Stack

Here’s what existing tools charge for this capability:

  • Crayon: $25,000+/year — enterprise CI platform with page change tracking
  • Klue: $15,000+/year — battlecard automation plus change detection
  • Kompyte: Enterprise pricing, sales-heavy procurement process

These platforms bundle monitoring with competitive battlecards, AI-generated summaries, and CRM integrations. Useful if you have a 20-person sales team and a CI budget. Overkill if you just want to know when a competitor changes their pricing page.

The underlying mechanism — scrape a page, diff against a stored snapshot, alert on change — costs pennies per run.

The Architecture

Four components:

  1. Apify apify/cheerio-scraper — lightweight page scrape extracting text from pricing elements
  2. Node.js script — stores snapshots, diffs current vs. stored, filters noise from nav/footer/cookie banner changes
  3. Slack webhook — fires an alert with competitor name, old text, new text, and a link to the page
  4. HubSpot (optional) — tags open deals where the competitor appears; auto-creates an AE task to update the competitive talk track

Each component is stateless. The Node.js script holds state (stored snapshots in a JSON file) and orchestrates the flow.

Implementation

Step 1: Define Your Competitor List

Create a competitors.json file:

[
  {
    "name": "CompetitorA",
    "pricingUrl": "https://competitora.com/pricing",
    "selector": ".pricing-table"
  },
  {
    "name": "CompetitorB",
    "pricingUrl": "https://competitorb.com/pricing",
    "selector": "#pricing-section"
  }
]

selector is the CSS selector for the pricing container on each page. Use browser DevTools to find a stable selector that captures price information but excludes dynamic elements like nav menus, chat widgets, or cookie banners.

Step 2: Scrape and Extract Pricing Content

const { ApifyClient } = require('apify-client');
const competitors = require('./competitors.json');

const apify = new ApifyClient({ token: process.env.APIFY_TOKEN });

async function scrapePricingPage(competitor) {
  const run = await apify.actor('apify/cheerio-scraper').call({
    startUrls: [{ url: competitor.pricingUrl }],
    pageFunction: `async function pageFunction(context) {
      const { $, request } = context;
      const content = $('${competitor.selector}').text().replace(/\s+/g, ' ').trim();
      return { url: request.url, content };
    }`
  });

  const { items } = await apify.dataset(run.defaultDatasetId).listItems();
  return items[0]?.content || '';
}

Step 3: Diff Against Stored Snapshot

const fs = require('fs');
const SNAPSHOTS_FILE = './snapshots.json';

function loadSnapshots() {
  if (!fs.existsSync(SNAPSHOTS_FILE)) return {};
  return JSON.parse(fs.readFileSync(SNAPSHOTS_FILE, 'utf8'));
}

function saveSnapshot(name, content) {
  const snapshots = loadSnapshots();
  snapshots[name] = { content, updatedAt: new Date().toISOString() };
  fs.writeFileSync(SNAPSHOTS_FILE, JSON.stringify(snapshots, null, 2));
}

function detectChange(name, currentContent) {
  const snapshots = loadSnapshots();
  const stored = snapshots[name];

  if (!stored) {
    // First run — save baseline, no alert
    saveSnapshot(name, currentContent);
    return null;
  }

  if (stored.content !== currentContent) {
    saveSnapshot(name, currentContent);
    return {
      name,
      oldContent: stored.content,
      newContent: currentContent,
      detectedAt: new Date().toISOString()
    };
  }

  return null;
}

Step 4: Send a Slack Alert

const https = require('https');

async function sendSlackAlert(change, pricingUrl) {
  const message = {
    blocks: [
      {
        type: 'header',
        text: { type: 'plain_text', text: `⚠️ Pricing Page Changed: ${change.name}` }
      },
      {
        type: 'section',
        fields: [
          { type: 'mrkdwn', text: `*Competitor:*n${change.name}` },
          { type: 'mrkdwn', text: `*Detected at:*n${change.detectedAt}` }
        ]
      },
      {
        type: 'section',
        text: {
          type: 'mrkdwn',
          text: `*Before:*n```${change.oldContent.slice(0, 300)}````
        }
      },
      {
        type: 'section',
        text: {
          type: 'mrkdwn',
          text: `*After:*n```${change.newContent.slice(0, 300)}````
        }
      },
      {
        type: 'actions',
        elements: [{
          type: 'button',
          text: { type: 'plain_text', text: 'View Pricing Page' },
          url: pricingUrl
        }]
      }
    ]
  };

  const payload = JSON.stringify(message);
  const url = new URL(process.env.SLACK_WEBHOOK_URL);

  return new Promise((resolve) => {
    const req = https.request({
      hostname: url.hostname,
      path: url.pathname,
      method: 'POST',
      headers: { 'Content-Type': 'application/json', 'Content-Length': payload.length }
    }, resolve);
    req.write(payload);
    req.end();
  });
}

Step 5: Orchestrate the Full Run

async function runPricingMonitor() {
  console.log(`Starting pricing monitor for ${competitors.length} competitors`);

  for (const competitor of competitors) {
    try {
      console.log(`Checking ${competitor.name}...`);
      const currentContent = await scrapePricingPage(competitor);
      const change = detectChange(competitor.name, currentContent);

      if (change) {
        console.log(`Change detected for ${competitor.name} — sending Slack alert`);
        await sendSlackAlert(change, competitor.pricingUrl);
      } else {
        console.log(`${competitor.name}: no change`);
      }
    } catch (err) {
      console.error(`Error checking ${competitor.name}:`, err.message);
    }
  }
}

runPricingMonitor().catch(console.error);

Step 6: Schedule with GitHub Actions

name: Competitor Pricing Monitor
on:
  schedule:
    - cron: '0 9 * * *'  # Every morning at 9 AM UTC
  workflow_dispatch:

jobs:
  monitor:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with:
          node-version: '20'
      - run: npm install
      - run: node monitor.js
        env:
          APIFY_TOKEN: ${{ secrets.APIFY_TOKEN }}
          SLACK_WEBHOOK_URL: ${{ secrets.SLACK_WEBHOOK_URL }}

Optional: CRM Write-Back

When a pricing change is detected, tag open deals in HubSpot where that competitor is tracked:

async function tagAffectedDeals(competitorName) {
  const searchRes = await fetch('https://api.hubapi.com/crm/v3/objects/deals/search', {
    method: 'POST',
    headers: {
      'Content-Type': 'application/json',
      'Authorization': `Bearer ${process.env.HUBSPOT_TOKEN}`
    },
    body: JSON.stringify({
      filterGroups: [{
        filters: [{
          propertyName: 'competitor_notes',
          operator: 'CONTAINS_TOKEN',
          value: competitorName
        }]
      }],
      properties: ['dealname', 'hubspot_owner_id']
    })
  });

  const { results } = await searchRes.json();

  for (const deal of results) {
    await fetch('https://api.hubapi.com/crm/v3/objects/tasks', {
      method: 'POST',
      headers: {
        'Content-Type': 'application/json',
        'Authorization': `Bearer ${process.env.HUBSPOT_TOKEN}`
      },
      body: JSON.stringify({
        properties: {
          hs_task_subject: `[Competitor Alert] ${competitorName} updated pricing — update talk track`,
          hs_task_body: `${competitorName} changed their pricing page. Review competitive positioning before next call.`,
          hs_task_priority: 'HIGH',
          hs_task_status: 'NOT_STARTED',
          hubspot_owner_id: deal.properties.hubspot_owner_id
        },
        associations: [{
          to: { id: deal.id },
          types: [{ associationCategory: 'HUBSPOT_DEFINED', associationTypeId: 216 }]
        }]
      })
    });
  }
}

What Does This Actually Cost?

Component Cost
Apify apify/cheerio-scraper ~$0.05–0.10 per run
10 competitors, daily checks ~$0.50–$1.00/day max
Monthly total $3–8/month

Compare that to Crayon at $25,000+/year or Klue at $15,000+/year. You get the same core signal — page changed, here’s what’s different — for a rounding error.

What to Do When the Alert Fires

  1. Open their pricing page and screenshot the current state
  2. Compare to Wayback Machine snapshot to understand the full diff
  3. Update your competitive battlecard with the new pricing context
  4. Brief the sales team before their next call with any prospect who mentioned that competitor
  5. Consider re-engaging churned accounts if the competitor raised prices

The alert is the input. The competitive response is the output.

Summary

  • Competitor pricing changes are high-signal events that most teams discover weeks late
  • Enterprise CI tools charge $15,000–$25,000+/year for page change monitoring
  • A lightweight Apify + Node.js stack delivers the same signal for $3–8/month
  • CSS selector-based extraction gives you structured diffs, not just “something changed visually”
  • GitHub Actions handles the scheduling at zero additional cost

The hardest part isn’t the code — it’s finding stable CSS selectors for each competitor’s pricing page and filtering out nav/footer noise. Once those are dialed in, the alert fires reliably and your team stops hearing about pricing changes from prospects mid-call.

Backup & Recovery: Enterprise Security for Homelabs

Originally published on Orthogonal Thinking

Learn how to apply enterprise-grade backup and disaster recovery practices to secure your homelab and protect critical data from unexpected failures.

Why Backup and Disaster Recovery Matter for Homelabs

I’ll admit it: I used to think backups were overkill for homelabs. After all, it’s just a personal setup, right? That mindset lasted until the day my RAID array failed spectacularly, taking years of configuration files, virtual machine snapshots, and personal projects with it. It was a painful lesson in how fragile even the most carefully built systems can be.

Homelabs are often treated as playgrounds for experimentation, but they frequently house critical data—whether it’s family photos, important documents, or the infrastructure powering your self-hosted services. The risks of data loss are very real. Hardware failures, ransomware attacks, accidental deletions, or even natural disasters can leave you scrambling to recover what you’ve lost.

Disaster recovery isn’t just about backups; it’s about ensuring continuity. A solid disaster recovery plan minimizes downtime, preserves data integrity, and gives you peace of mind. If you’re like me, you’ve probably spent hours perfecting your homelab setup. Why risk losing it all when enterprise-grade practices can be scaled down for home use?

Another critical reason to prioritize backups is the increasing prevalence of ransomware attacks. Even for homelab users, ransomware can encrypt your data and demand payment for decryption keys. Without proper backups, you may find yourself at the mercy of attackers. Additionally, consider the time and effort you’ve invested in configuring your homelab. Losing that work due to a failure or oversight can be devastating, especially if you rely on your setup for learning, development, or even hosting services for family and friends.

Think of backups as an insurance policy. You hope you’ll never need them, but when disaster strikes, they’re invaluable. Whether it’s a failed hard drive, a corrupted database, or an accidental deletion, having a reliable backup can mean the difference between a minor inconvenience and a catastrophic loss.

Troubleshooting Common Issues

One common issue is underestimating the time required to restore data. If your backups are stored on slow media or in the cloud, recovery could take hours or even days. Test your recovery process to ensure it meets your needs. Another issue is incomplete backups—always verify that all critical data is included in your backup plan.

Enterprise Practices: Scaling Down for Home Use

In the enterprise world, backup strategies are built around the 3-2-1 rule: three copies of your data, stored on two different media, with one copy offsite. This ensures redundancy and protects against localized failures. Immutable backups—snapshots that cannot be altered—are another key practice, especially in combating ransomware.

For homelabs, these practices can be adapted without breaking the bank. Here’s how:

  • Three copies: Keep your primary data on your main storage, a secondary copy on a local backup device (like an external drive or NAS), and a third copy offsite (cloud storage or a remote server).
  • Two media types: Use a combination of SSDs, HDDs, or tape drives for local backups, and cloud storage for offsite redundancy.
  • Immutable backups: Many backup tools now support immutable snapshots. Enable this feature to protect against accidental or malicious changes.

Let’s break this down further. For local backups, a simple USB external drive can suffice for smaller setups. However, if you’re running a larger homelab with multiple virtual machines or containers, consider investing in a NAS (Network Attached Storage) device. NAS devices often support RAID configurations, which provide redundancy in case of disk failure.

For offsite backups, cloud storage services like Backblaze, Wasabi, or even Google Drive are excellent options. These services are relatively inexpensive and provide the added benefit of geographic redundancy. If you’re concerned about privacy, ensure your data is encrypted before uploading it to the cloud.

# Example: Creating immutable backups with Borg
borg init --encryption=repokey-blake2 /path/to/repo
borg create --immutable /path/to/repo::backup-$(date +%Y-%m-%d) /path/to/data

Troubleshooting Common Issues

One challenge with offsite backups is bandwidth. Uploading large datasets can take days on a slow internet connection. To mitigate this, prioritize critical data and upload it first. You can also use tools like rsync or rclone to perform incremental backups, which only upload changes.

Choosing the Right Backup Tools and Storage Solutions

When it comes to backup software, the options can be overwhelming. For homelabs, simplicity and reliability should be your top priorities. Here’s a quick comparison of popular tools:

  • Veeam: Enterprise-grade backup software with a free version for personal use. Great for virtual machines and complex setups.
  • Borg: A lightweight, open-source backup tool with excellent deduplication and encryption features.
  • Restic: Another open-source option, known for its simplicity and support for multiple storage backends.

As for storage solutions, you’ll want to balance capacity, speed, and cost. NAS devices like Synology or QNAP are popular for homelabs, offering RAID configurations and easy integration with backup software. External drives are a budget-friendly option but lack redundancy. Cloud storage, while recurring in cost, provides unmatched offsite protection.

For those with more advanced needs, consider setting up a dedicated backup server. Tools like Proxmox Backup Server or TrueNAS can turn an old PC into a powerful backup appliance. These solutions often include features like deduplication, compression, and snapshot management, making them ideal for homelab enthusiasts.

# Example: Setting up Restic with Google Drive
export RESTIC_REPOSITORY=rclone:remote:backup
export RESTIC_PASSWORD=yourpassword
restic init
restic backup /path/to/data

Troubleshooting Common Issues

One common issue is compatibility between backup tools and storage solutions. For example, some tools may not natively support certain cloud providers. In such cases, using a middleware like rclone can bridge the gap. Additionally, always test your backups to ensure they’re restorable. A corrupted backup is as bad as no backup at all.

Automating Backup and Recovery Processes

Manual backups are a recipe for disaster. Trust me, you’ll forget to run them when life gets busy. Automation ensures consistency and reduces the risk of human error. Most backup tools allow you to schedule recurring backups, so set it and forget it.

Here’s an example of automating backups with Restic:

# Initialize a Restic repository
restic init --repo /path/to/backup --password-file /path/to/password

# Automate daily backups using cron
0 2 * * * restic backup /path/to/data --repo /path/to/backup --password-file /path/to/password --verbose

Testing recovery is just as important as creating backups. Simulate failure scenarios to ensure your disaster recovery plan works as expected. Restore a backup to a separate environment and verify its integrity. If you can’t recover your data reliably, your backups are useless.

Another aspect of automation is monitoring. Tools like Zabbix or Grafana can be configured to alert you if a backup fails. This proactive approach ensures you’re aware of issues before they become critical.

Troubleshooting Common Issues

One common pitfall is failing to account for changes in your environment. If you add new directories or services to your homelab, update your backup scripts accordingly. Another issue is storage exhaustion—automated backups can quickly fill up your storage if old backups aren’t pruned. Use retention policies to manage this.

Security Best Practices for Backup Systems

Backups are only as secure as the systems protecting them. Neglecting security can turn your backups into a liability. Here’s how to keep them safe:

  • Encryption: Always encrypt your backups, both at rest and in transit. Tools like Restic and Borg have built-in encryption features.
  • Access control: Limit access to your backup systems. Use strong authentication methods, such as SSH keys or multi-factor authentication.
  • Network isolation: If possible, isolate your backup systems from the rest of your network to reduce attack surfaces.

Additionally, monitor your backup systems for unauthorized access or anomalies. Logging and alerting can help you catch issues before they escalate.

Another important consideration is physical security. If you’re using external drives or a NAS, ensure they’re stored in a safe location. For cloud backups, verify that your provider complies with security standards and offers robust access controls.

Troubleshooting Common Issues

One common issue is losing encryption keys or passwords. Without them, your backups are effectively useless. Store keys securely, such as in a password manager. Another issue is misconfigured access controls, which can expose your backups to unauthorized users. Regularly audit permissions to ensure they’re correct.

Testing Your Disaster Recovery Plan

Creating backups is only half the battle. If you don’t test your disaster recovery plan, you won’t know if it works until it’s too late. Regular testing ensures that your backups are functional and that you can recover your data quickly and efficiently.

Start by identifying the critical systems and data you need to recover. Then, simulate a failure scenario. For example, if you’re backing up a virtual machine, try restoring it to a new host. If you’re backing up files, restore them to a different directory and verify their integrity.

Document the time it takes to complete the recovery process. This information is crucial for setting realistic expectations and identifying bottlenecks. If recovery takes too long, consider optimizing your backup strategy or investing in faster storage solutions.

Troubleshooting Common Issues

One common issue is discovering that your backups are incomplete or corrupted. To prevent this, regularly verify your backups using tools like Restic’s check command. Another issue is failing to account for dependencies. For example, restoring a database backup without its associated application files may render it unusable. Always test your recovery process end-to-end.

Key Takeaways

  • Follow the 3-2-1 rule for redundancy and offsite protection.
  • Choose backup tools and storage solutions that fit your homelab’s needs and budget.
  • Automate backups and test recovery scenarios regularly.
  • Encrypt backups and secure access to your backup systems.
  • Document your disaster recovery plan for quick action during emergencies.
  • Regularly test your disaster recovery plan to ensure it works as expected.

Have a homelab backup horror story or a tip to share? I’d love to hear it—drop a comment or reach out on Twitter. Next week, we’ll explore how to secure your NAS against ransomware attacks. Stay tuned!

📚 Related Articles

📋 Disclosure: Some links in this article are affiliate links. If you purchase through these links, I earn a small commission at no extra cost to you. I only recommend products I’ve personally used or thoroughly evaluated. This helps support orthogonal.info and keeps the content free.

Vibe Coding Is a Security Nightmare: How to Fix It

Originally published on Orthogonal Thinking

Three weeks ago I reviewed a pull request from a junior developer on our team. The code was clean—suspiciously clean. Good variable names, proper error handling, even JSDoc comments. I approved it, deployed it, and moved on.

Then our SAST scanner flagged it. Hardcoded API keys in a utility function. An SQL query built with string concatenation buried inside a helper. A JWT validation that checked the signature but never verified the expiration. All wrapped in beautiful, well-commented code that looked like it was written by someone who knew what they were doing.

“Oh yeah,” the junior said when I asked about it. “I vibed that whole module.”

Welcome to 2026, where “vibe coding” isn’t just a meme—it’s Collins Dictionary’s Word of the Year for 2025, and it’s fundamentally reshaping how we think about software security.

What Exactly Is Vibe Coding?

The term was coined by Andrej Karpathy, co-founder of OpenAI and former AI lead at Tesla, in February 2025. His definition was refreshingly honest:

That’s the key distinction. Using an LLM to help write code while reviewing every line? That’s AI-assisted development. Accepting whatever the model generates without understanding it? That’s vibe coding. As Simon Willison put it: “If an LLM wrote every line of your code, but you’ve reviewed, tested, and understood it all, that’s not vibe coding.”

And look, I get the appeal. I’ve used Claude Code and Cursor extensively—I wrote about my Claude Code experience recently. These tools are genuinely powerful. But there’s a massive difference between using AI as a force multiplier and blindly accepting generated code into production.

The Security Numbers Are Terrifying

Let me throw some stats at you that should make any security engineer lose sleep:

In December 2025, CodeRabbit analyzed 470 open-source GitHub pull requests and found that AI co-authored code contained 2.74x more security vulnerabilities than human-written code. Not 10% more. Not even double. Nearly triple.

The same study found 1.7x more “major” issues overall, including logic errors, incorrect dependencies, flawed control flow, and misconfigurations that were 75% more common in AI-generated code.

And then there’s the Lovable incident. In May 2025, security researchers discovered that 170 out of 1,645 web applications built with the vibe coding platform Lovable had vulnerabilities that exposed personal information to anyone on the internet. That’s a 10% critical vulnerability rate right out of the box.

The Top 5 Security Nightmares I’ve Found in Vibed Code

After spending the last several months auditing code across different teams, I’ve built up a depressingly predictable list of security issues that LLMs keep introducing. Here are the greatest hits:

1. The “Almost Right” Authentication

LLMs love generating auth code that’s 90% correct. JWT validation that checks the signature but skips expiration. OAuth flows that don’t validate the state parameter. Session management that uses predictable tokens.

# Vibed code that looks fine but is dangerously broken
def verify_token(token: str) -> dict:
    try:
        payload = jwt.decode(
            token,
            SECRET_KEY,
            algorithms=["HS256"],
            # Missing: options={"verify_exp": True}
            # Missing: audience verification
            # Missing: issuer verification
        )
        return payload
    except jwt.InvalidTokenError:
        raise HTTPException(status_code=401)

This code will pass every code review from someone who doesn’t specialize in auth. It decodes the JWT, checks the algorithm, handles the error. But it’s missing critical validation that an attacker will find in about five minutes.

2. SQL Injection Wearing a Disguise

Modern LLMs know they should use parameterized queries. So they do—most of the time. But they’ll sneak in string formatting for table names, column names, or ORDER BY clauses where parameterization doesn’t work, and they won’t add any sanitization.

# The LLM used parameterized queries... except where it didn't
async def get_user_data(user_id: int, sort_by: str):
query = f"SELECT * FROM users WHERE id = $1 ORDER BY {sort_by}" # 💀
return await db.fetch(query, user_id)

  1. Secrets Hiding in Plain Sight

LLMs are trained on millions of code examples that include hardcoded credentials, API keys, and connection strings. When they generate code for you, they often follow the same patterns—embedding secrets directly in configuration files, environment setup scripts, or even in application code with a comment saying “TODO: move to env vars.”

4. Overly Permissive CORS

Almost every vibed web application I’ve audited has Access-Control-Allow-Origin: * in production. LLMs default to maximum permissiveness because it “works” and doesn’t generate errors during development.

5. Missing Input Validation Everywhere

LLMs generate the happy path beautifully. Form handling, data processing, API endpoints—all functional. But edge cases? Malicious input? File upload validation? These get skipped or half-implemented with alarming consistency.

Why LLMs Are Structurally Bad at Security

This isn’t just about current limitations that will get fixed in the next model version. There are structural reasons why LLMs struggle with security:

They ‘re trained on average code. The internet is full of tutorials, Stack Overflow answers, and GitHub repos with terrible security practices. LLMs absorb all of it. They generate code that reflects the statistical average of what exists online—and the average is not secure.

Security is about absence, not presence. Good security means ensuring that bad things don ‘t happen. But LLMs are optimized to generate code that does things—that fulfills functional requirements. They’re great at building features, terrible at preventing attacks.

Context windows aren ‘t threat models. A security engineer reviews code with a mental model of the entire attack surface. “If this endpoint is public, and that database stores PII, then we need rate limiting, input validation, and encryption at rest.” LLMs see a prompt and generate code. They don’t think about the attacker who’ll be probing your API at 3 AM.

How to Vibe Code Without Getting Owned

I’m not going to tell you to stop using AI coding tools. That ship has sailed—even Linus Torvalds vibe coded a Python tool in January 2026. But if you’re going to let the vibes flow, at least put up some guardrails:

1. SAST Before Every Merge

Run static analysis on every single pull request. Tools like Semgrep, Snyk, or SonarQube will catch the low-hanging fruit that LLMs routinely miss. Make it a hard gate—no green CI, no merge.

# GitHub Actions / Gitea workflow - non-negotiable

  • name: Security Scan run: | semgrep --config=p/security-audit --config=p/owasp-top-ten . if [ $? -ne 0 ]; then echo "❌ Security issues found. Fix before merging." exit 1 fi

  1. Never Vibe Your Auth Layer

Authentication, authorization, session management, crypto—these are the modules where a single bug means game over. Write these by hand, or at minimum, review every single line the AI generates against OWASP guidelines. Better yet, use battle-tested libraries like python-jose, passport.js, or Spring Security instead of letting an LLM roll its own.

3. Treat AI Output Like Untrusted Input

This is the mindset shift that will save you. You wouldn’t take user input and shove it directly into a SQL query (I hope). Apply the same paranoia to AI-generated code. Review it. Test it. Question it. The LLM is not your senior engineer—it’s an extremely fast intern who read a lot of Stack Overflow.

4. Set Up Dependency Scanning

LLMs love pulling in packages. Sometimes those packages are outdated, unmaintained, or have known CVEs. Run npm audit, pip-audit, or trivy as part of your CI pipeline. I’ve seen vibed code pull in packages that were deprecated two years ago.

5. Deploy with Least Privilege

Assume the vibed code has vulnerabilities (it probably does). Design your infrastructure so that when—not if—something gets exploited, the blast radius is limited. Principle of least privilege isn’t new advice, but it’s never been more important.

The Open Source Problem Nobody’s Talking About

A January 2026 paper titled “Vibe Coding Kills Open Source” raised an alarming point that’s been bothering me too. When everyone vibe codes, LLMs gravitate toward the same large, well-known libraries. Smaller, potentially better alternatives get starved of attention. Nobody files bug reports because they don’t understand the code well enough to identify issues. Nobody contributes patches because they didn’t write the integration code themselves.

The open-source ecosystem runs on human engagement—people who use a library, understand it, find bugs, and contribute back. Vibe coding short-circuits that entire feedback loop. We’re essentially strip-mining the open-source commons without replanting anything.

Gear That Actually Helps

If you’re going to do AI-assisted development (the responsible kind, not the full-send vibe coding kind), invest in tools that keep you honest:

  • 📘 The Web Application Hacker’s Handbook — Still the gold standard for understanding how web apps get exploited. Read it before you let an AI write your next API. ($35-45)
  • 📘 Threat Modeling: Designing for Security — Learn to think like an attacker. No LLM can do this for you. ($35-45)
  • 🔐 YubiKey 5 NFC — Hardware security key for SSH, GPG, and MFA. Because vibed code might leak your credentials, so at least make them useless without physical access. ($45-55)
  • 📘 Zero Trust Networks — Build infrastructure that assumes breach. Essential reading when your codebase is partially written by a statistical model. ($40-50)

Key Takeaways

Vibe coding is here to stay. The productivity gains are real, the convenience is undeniable, and fighting it is like fighting the tide. But as someone who’s spent 12 years in security, I’m begging you: don’t vibe your way into a breach.

  • AI-generated code has 2.74x more security vulnerabilities than human-written code
  • Never vibe code authentication, authorization, or crypto —write these by hand or use proven libraries
  • Run SAST on every PR —make security scanning a merge gate, not an afterthought
  • Treat AI output like untrusted input —review, test, and question everything
  • The productivity perception is often wrong —studies show devs are actually 19% slower with AI tools on complex tasks

Use AI as a force multiplier, not a replacement for understanding. The vibes are good until your database shows up on Have I Been Pwned.

Have you had security scares from vibed code? I ‘d love to hear your war stories—drop a comment below or reach out on social.

📚 Related Articles

Some links in this article are affiliate links. If you buy something through these links, I may earn a small commission at no extra cost to you. I only recommend products I actually use or have thoroughly researched.

📊 Free AI Market Intelligence

Join Alpha Signal — AI-powered market research delivered daily. Narrative detection, geopolitical risk scoring, sector rotation analysis.

Join Free on Telegram →

Pro with stock conviction scores: $5/mo

Mercedes-Benz, 31 Mart’ta makyajlı GLE, GLE Coupe ve GLS’yi tanıtacak

Mercedes-Benz

Mercedes-BenzMercedes-Benz, bugün yapılan resmi paylaşıma göre 31 Mart’ta makyajlı GLE, GLE Coupe ve GLS’yi tanıtacak. Kısa süre önce tamamen elektrikli yeni VLE’yi ve yeni S-Class Maybach’ı tanıtan Alman devi, makyajlı GLE, GLE Coupe ve GLS’yi uzun süredir test ediyordu. Hem dış hem de iç tasarımdaki güncellemelerle modernleştirilecek ve büyük ekranlarla donatılacak araçlar, birden fazla içten yanmalı motor seçeneğine sahip olacak. Kaynaklar, 2027 GLS 580’de çift turbo destekli yeni V8 ünitenin kullanılacağını iddia ediyor. Yenilenen S-Class ile beraber tanıtılan bu motor 580 beygir güç ve 750 Nm tork üretiyor. GLS 450’de ise 376 beygir güç üreten 3.0 litrelik turbo destekli sıralı altı silindirli motorun yer alması bekleniyor.
Mercedes-Benz, 31 Mart’ta makyajlı GLE, GLE Coupe ve GLS’yi tanıtacak yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Volkswagen, Osnabrück fabrikasında İsrail için Demir Kubbe parçaları üretecek iddialarına cevap verdi

Volkswagen, Osnabrück fabrikasında silah üretecek iddialara cevap verdi

Volkswagen, Osnabrück fabrikasında silah üretecek iddialara cevap verdiAlman otomobil devi Volkswagen (VW), 2.300 kişinin çalıştığı Osnabrück fabrikasında İsrail’in “Demir Kubbe” savunma sistemi için parça üretecek iddialarına cevap verdi. Deutsche Welle’ye (DW) bu konuda açıklamalarda bulunan şirket sözcüsü, Volkswagen’in gelecekte silah üretmesi gibi bir durumun söz konusu olmadığını ve 2027’de araç üretiminin durdurulacağı Osnabrück fabrikasına ilişkin planlar hakkında spekülasyon yapmayacaklarını belirtti. Ancak şirketin “uygulanabilir seçenekleri araştırmaya devam ettiğini” ve çeşitli “piyasa oyuncularıyla” görüşme halinde olduğunu belirten VW sözcüsü, “Bu, 2027 sonrasına yönelik açık bir değerlendirme sürecinin parçası.” diye konuştu. “Bu fabrikanın gelecekteki yönü konusunda şu an için somut bir karar ya da sonuç yok.” ifadesini kullanan VW sözcüsü, çalışanları da süreçle ilgili olarak bilgilendirmeye devam ettiklerini söyledi. Financial Times (FT), fabrikada füzeleri taşıyan ağır hizmet kamyonları, fırlatıcılar ve jeneratörler dahil olmak üzere çeşitli parçaların üretileceğini, ancak patlayıcı mühimmat/füze üretilmeyeceğini aktarmıştı.
Volkswagen, Osnabrück fabrikasında İsrail için Demir Kubbe parçaları üretecek iddialarına cevap verdi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Yeni OMODA 7 için resmi Türkiye fiyatı açıklandı

Yeni OMODA 7,

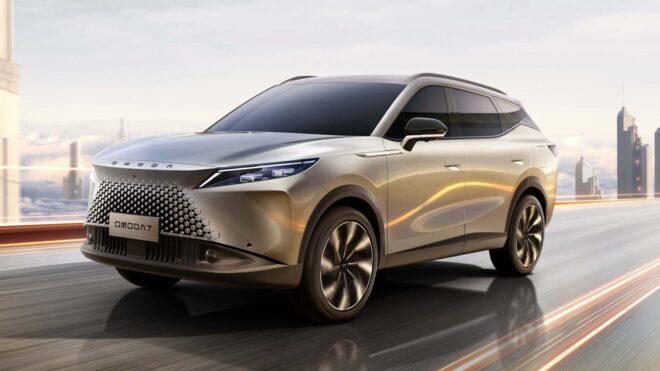
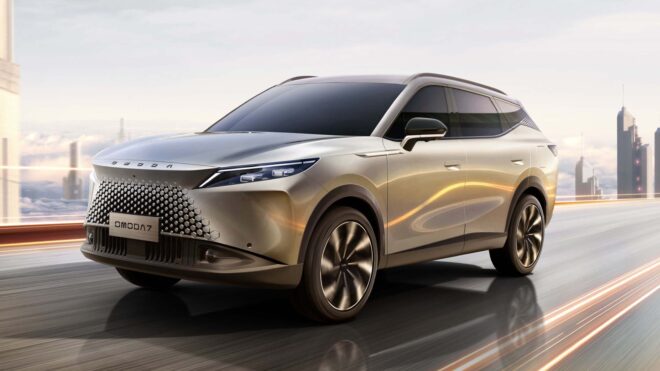
Yeni OMODA 7,OMODA & JAECOO tarafından yapılan resmi açıklamaya göre yeni OMODA 7 modeli Türkiye’de 2  milyon 680 bin TL’ye (7 Neo 4×2 7 İleri Otomatik DCT) satılacak. Chery çatısı altındaki ortak marka, 145 beygir güç sunan 1.6 litrelik (275 Nm tork) turbo benzinli motorla gelen yeni araç hakkındaki son paylaşımda şunları söylemişti: “Markanın amiral gemisi olan OMODA 7, rafine bir yaşam tarzını benimseyen ve bağımsız bir duruş sergileyen kullanıcılar için tasarlandı. Dış tasarımında keskin hatlara sahip “X” formundaki ön yüz, çerçevesiz parametrik ızgara ve entegre LED farlar dikkat çekiyor. Yarı gizli kapı kolları ve akıcı gövde hatları zarafet ile dinamizmi bir araya getirirken, gizli arka silecek ve yıldırım formundaki arka stoplar aracın arka tasarımında görsel bütünlüğü güçlendirerek yolda güçlü bir karakter ortaya koyuyor. İç mekanda ise 256 farklı renkte ambiyans aydınlatması nefes alma ve akış modlarıyla farklı atmosferler yaratıyor. 8,88 inç dijital gösterge paneli ve 15,6 inç 2.5K çözünürlüğe sahip dokunmatik […]
Yeni OMODA 7 için resmi Türkiye fiyatı açıklandı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Tesla Türkiye, İstanbul’da “Cybertruck” sergileyecek

Tesla Türkiye, İstanbul

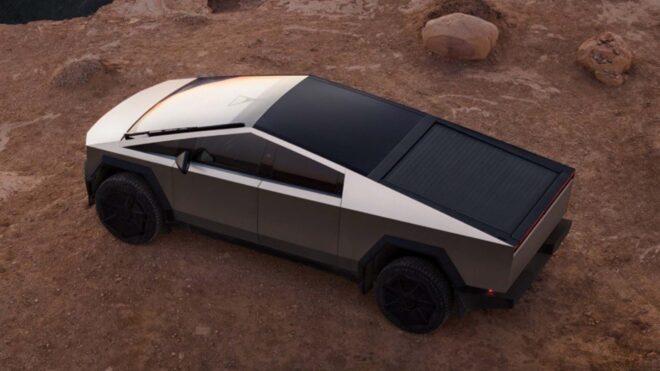
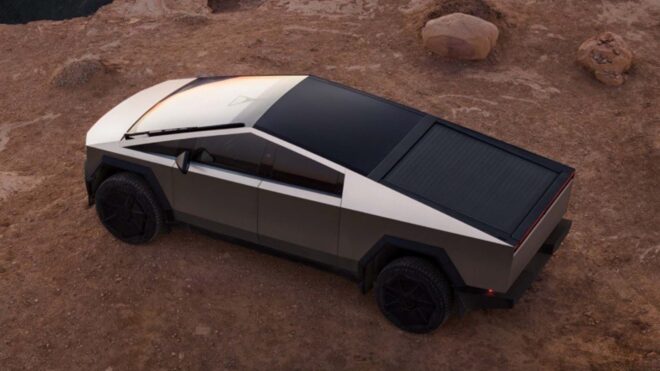
Tesla Türkiye, İstanbul'da "Cybertruck" sergileyecekBugün yapılan resmi açıklama ile duyurulduğu kadarıyla Tesla Türkiye İstanbul’da “Cybertruck” sergileyecek. Bu konuda yaptığı paylaşımda, “8 Mart’tan itibaren Cybertruck, İstanbul Emaar Square Mall’da sergilenmeye başlıyor. Türkiye’de ilk kez, kayıt yaptıran ziyaretçiler Cybertruck’ın içine girerek iç mekanını ve özelliklerini özgürce keşfedebilecek. Etkinlik, 28 Mart – 5 Nisan tarihleri arasında 9 gün boyunca devam edecek. Ziyaretçiler kayıtlarını aşağıdaki link üzerinden veya etkinlik alanında yaptırabilirler. Sizi ağırlamaktan mutluluk duyarız.” diyen şirket, tasarımı hemen hemen kimse tarafından beğenilmeyen Cybertruck’ı Türkiye’de resmi olarak satmıyor. 28 Mart’tan itibaren Cybertruck, İstanbul Emaar Square Mall’da sergilenmeye başlıyor. Türkiye’de ilk kez, kayıt yaptıran ziyaretçiler Cybertruck’ın içine girerek iç mekanını ve özelliklerini özgürce keşfedebilecek. Etkinlik, 28 Mart – 5 Nisan tarihleri arasında 9 gün boyunca… pic.twitter.com/HzGb53pnYT — Tesla Europe, Middle East & Africa (@teslaeurope) March 27, 2026

Tesla Türkiye, İstanbul’da “Cybertruck” sergileyecek yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

How We Cut Browser Agent Costs 7,000x with Collective Intelligence

Every browser agent does the same expensive thing: dump the entire DOM into an LLM, ask “what should I click?”, and repeat for every step. A 10-step workflow costs ~$4 in LLM tokens and ~50 seconds in reasoning time. Multiply that by every agent, every session, every day — and you’re burning cash on knowledge that already exists.

The core problem: amnesia at scale

When Agent A figures out how to search flights on WebsiteA, that knowledge evaporates when the session ends. Agent B starts from scratch. So does Agent C. Every agent pays full price to re-learn what hundreds of agents have already discovered.

This is the browser automation equivalent of every developer rewriting left-pad from scratch, every time, in every project.

What if agents could share what they learn?

We built AIR SDK — an open-source MCP server that maintains a shared capability graph across all connected agents. Three API calls:

browse_capabilities(domain)   → What actions can be performed here?
execute_capability(action, params) → How do I do it? (CSS selectors, API paths, macros)
report_outcome(steps, success)     → Here's what actually worked.

The third call is the key. When your agent reports which CSS selectors worked on a given site, every future agent on that domain benefits instantly. No DOM parsing, no LLM reasoning — just a lookup.

The numbers

We benchmarked AIR SDK against raw DOM-to-LLM browser automation on identical tasks:

Scenario Raw DOM + LLM AIR SDK Reduction
1 action (e.g., click search) $0.24 $0.0006 400x
10-step workflow $4.13 $0.0006 7,000x
Time per action ~5s <100ms 50x

The savings compound. The more agents use AIR, the more capabilities get verified, and the cheaper and faster every subsequent interaction becomes.

agent.json: robots.txt for AI agents

We also built agent.json — a standard for websites to declare what AI agents can do. Think robots.txt, but instead of “don’t crawl this,” it says “here’s how to search, here’s how to add to cart, here’s the API shortcut.”

Over 2,225 domains already indexed. Sites can publish their own at /.well-known/agent.json, or AIR learns capabilities automatically through agent reports.

How it works under the hood

AIR resolves capabilities through a tiered system:

  1. API fast-path — If the site has a known API endpoint, skip the browser entirely
  2. Verified macro — Pre-verified CSS selector sequences from prior agent reports
  3. Selector hints — Partial knowledge that reduces LLM reasoning cost
  4. Heuristic plan — For unknown sites, AIR generates a best-guess execution plan

Each tier is progressively more expensive but handles progressively less-explored territory. Most production traffic hits tiers 1-2 at near-zero cost.

Get started

npm install @arcede/air-sdk

Or add it as an MCP server in Claude Desktop, Cursor, or any MCP-compatible client.

Free tier: 1,000 capability executions/month. No credit card required.

MIT licensed. GitHub repo — stars appreciated.

We’re building AIR at Arcede. If you’re working on browser agents and want to integrate, reach out at [email protected] or open an issue on GitHub.