Data modeling is where raw data becomes usable intelligence. In Power BI, it’s not a preliminary step you rush through. It’s the architectural foundation that determines whether your reports are fast or sluggish, your DAX is clean or convoluted, and your numbers are right or wrong.
Under the hood, Power BI runs the Analysis Services VertiPaq engine, an in-memory columnar database that relies on structured relationships and compressed tables to aggregate millions of rows quickly. A well-built model means near-instant visualizations and precise DAX calculations. A poorly built one means slow performance, memory exhaustion, circular dependencies, and incorrect results.
This article covers the full landscape: Fact vs. Dimension tables, Star/Snowflake/Flat Table schemas, all six Power Query join types with practical scenarios, Power BI relationship configuration (cardinality, cross-filter direction, active/inactive states), role-playing dimensions, and common modeling pitfalls like ambiguous paths and circular dependencies.
Fact Tables vs. Dimension Tables
Every optimized analytical model starts by separating data into two types: Fact tables (the numbers) and Dimension tables (the context). This separation is the cornerstone of dimensional modeling, and VertiPaq is specifically designed to leverage it. Mixing quantitative metrics with descriptive text in a single table compromises compression efficiency and query speed.
Fact Tables
Fact tables hold the quantitative metrics, measurements, and transactional events generated by a business process. They represent the numerical reality of what happened: how much was sold, how many units shipped, what discount was applied.
Structurally, Fact tables have a massive number of rows (potentially hundreds of millions) but a narrow column footprint. They contain two types of columns: Foreign Keys (integer-based IDs like EmployeeID, StoreID, DateKey that link back to Dimension tables) and Numeric Measures (the actual values being aggregated: Transaction_Amount, Units_Sold, Discount_Applied).
One critical principle: every Fact table must have a consistent grain. The grain defines what a single row represents. “One row per product sold per receipt per store,” for example. Mixing grains (daily transactions alongside monthly aggregates in the same table) causes double-counting and forces convoluted DAX to resolve.
Dimension Tables
Dimension tables provide the qualitative context that makes the numbers meaningful. They answer “who,” “where,” “what,” and “why.” Customers, Products, Sales Representatives, Geographic Regions.
Structurally, they’re the inverse of Fact tables: relatively few rows but many columns. A Customer dimension might have 100,000 rows but 80 columns capturing everything from First_Name to Lifetime_Value_Tier to Acquisition_Channel. Every Dimension table needs a Primary Key (a column with strictly unique values) that matches the Foreign Key in the Fact table.
When an analyst drags Region_Name onto a chart axis, they’re using a Dimension table attribute to slice the raw numeric data in the Fact table. That’s the entire relationship in action.
Schemas: Star, Snowflake, and Flat Table
The spatial arrangement and normalization level connecting Facts and Dimensions defines your schema. Your choice directly impacts VertiPaq performance, model memory footprint, and DAX complexity.
Star Schema (the Gold Standard)
The Star Schema is universally recommended for Power BI. It features a single, compressed central Fact table surrounded by multiple Dimension tables, each joined directly via a simple one-to-many relationship. No intermediate lookup tables, no secondary dimension branches, no complex relationship chains.
To achieve this, Dimension tables are deliberately denormalized during data preparation. Instead of separate tables for Product, Product_Subcategory, and Product_Category, everything collapses into a single Product dimension.
Why this works so well in Power BI:
Performance. Only one relationship “hop” from any dimension attribute to the fact data. VertiPaq is engineered to traverse these single-tier relationships with maximum efficiency.
Simple DAX. Filter context flows cleanly from dimension slicer to Fact table. No need for complex filter-modification functions.
Intuitive for users. One business entity equals one table. Self-service report authors don’t get lost.
The trade-off is data redundancy: a long string like “Industrial Manufacturing Equipment” might repeat across thousands of product rows. But VertiPaq handles this through dictionary encoding, storing the string once and using a tiny integer reference everywhere else. The theoretical storage penalty is virtually eliminated in memory.
Snowflake Schema
A Snowflake Schema normalizes one or more Dimension tables into hierarchical sub-tables. Instead of one Product table, you get Product joined to Product_Subcategory joined to Product_Category, branching outward.
The advantage is storage efficiency and strict data conformity. The disadvantage in Power BI is severe: multi-hop traversal degrades reporting performance, and DAX authoring gets significantly more complex. Filters must propagate through intermediate tables, leading to unexpected behaviors and potential ambiguous pathway errors.
The universal recommendation: use Power Query to merge and denormalize Snowflake structures into a Star Schema before loading into the model.
Flat Table (DLAT / “One Big Table”)
The Flat Table abandons Fact/Dimension separation entirely, joining everything into a single massive table with potentially hundreds of columns.
In Power BI Import mode, this is a severe anti-pattern. Appending text-heavy dimensional attributes alongside millions of transaction rows causes catastrophic data duplication, bloats the in-memory cache, slows refreshes, and complicates DAX. Overriding filter context on a single attribute in a Star Schema is trivial (CALCULATE([Measure], ALL('Product'))). In a Flat Table, you must list every column individually.
There is one legitimate exception: DirectQuery mode. When Power BI passes DAX as SQL queries to a backend warehouse (Snowflake, BigQuery, Databricks), a pre-joined materialized Flat Table eliminates runtime SQL JOINs, which can be computationally expensive. In this specific scenario, a DLAT can yield faster visual rendering. For Import mode (the vast majority of implementations), Star Schema remains the imperative.
Power Query Joins: Combining Data at the Source Layer
Before data enters VertiPaq, it’s extracted, cleaned, and transformed in Power Query. Joins (merges) in Power Query are physical operations: they permanently combine columns from two tables based on matching keys during ETL. This is fundamentally different from Power BI Relationships, which are virtual, dynamic filter mechanisms applied in memory during user interaction.
Power Query supports six join types, all derived from standard SQL relational algebra.
1. Inner Join
Returns only rows with matching keys in both tables. Unmatched rows from either side are discarded.
Scenario: Sales analysis limited to currently active employees. Inner Join on EmployeeID drops sales records tied to terminated employees and active employees with no sales.
2. Left Outer Join
The most commonly used join for data modeling. Preserves all rows from the left table. Matching rows from the right table are appended; unmatched left rows get null values in the right-table columns.
Scenario: A Customer master list enriched with campaign responses. Customers who didn’t respond still appear with null in the feedback columns.
3. Right Outer Join
The inverse: preserves all rows from the right table, appending only matching rows from the left.
Scenario: Ensuring all new products from a supplier catalog appear in your model, even if no sales exist yet.
4. Full Outer Join
Preserves all rows from both tables. Matched rows are combined; unmatched rows from either side are retained with null values for the missing columns.
Scenario: Reconciling employee records across two separate HR systems. Every employee from both systems appears, with gaps showing where records don’t align.
5. Left Anti Join (“Rows only in first”)
Returns strictly the rows from the left table that have no match in the right table. Every matched row is discarded.
Scenario: Generating a list of campaign targets who haven’t been contacted yet. Left Anti Join subtracts contacted customers from the target list.
6. Right Anti Join (“Rows only in second”)
Returns strictly the rows from the right table that have no match in the left table.
Scenario: Comparing a digital inventory system against a physical warehouse audit. Right Anti Join reveals items found on the warehouse floor that don’t exist in the system, flagging undocumented overstock or data entry failures.
Step-by-Step: Merging in Power Query
- From the Home ribbon in Power BI Desktop, click Transform data to open Power Query Editor.
- In the Queries pane, select the table that will act as the Left (primary) table.
- On the Home ribbon, in the Combine group, click Merge Queries (or “Merge Queries as New” to preserve originals).
- In the Merge dialog, click the matching column header(s) in the Left table preview. Select the Right table from the dropdown, then click its matching column header(s).
- Select your Join Kind from the dropdown at the bottom.
- Power Query shows an estimated match count. Validate, then click OK.
- The merge adds a column of nested
Table objects. Click the expand icon (divergent arrows) in the column header, select which columns to flatten, and click OK.
- Click Close & Apply to load the result into VertiPaq.
Power BI Relationships: The Semantic Layer
While Power Query joins weld data together during ETL, Relationships are virtual, logical connections established post-load. They propagate filter context between tables. Selecting “2024” in a Date slicer generates a filter that travels down the relationship pathway to isolate matching rows in the Fact table.
Important: Power BI relationships do not enforce data integrity (no prevention of orphan records, no cascading deletes like SQL). They define filter propagation rules only.
Cardinality
One-to-Many (1:) / Many-to-One (:1): The same relationship viewed from opposite sides. The “one” side is the Primary Key (unique values in the Dimension); the “many” side is the Foreign Key (duplicates in the Fact). This is the structural glue of the Star Schema and the optimal relationship type.
One-to-One (1:1): Both columns contain unique values. Rare, and often indicates the tables should be merged into one. Legitimate exceptions: isolating columns for row-level security or separating rarely-queried wide text columns to save memory.
Many-to-Many (:): Both columns contain duplicates. Common in scenarios like students enrolled in multiple courses. Connecting two many-to-many dimensions directly causes extreme ambiguity and incorrect aggregations. The solution is a Bridge Table (junction table) capturing every unique combination, transforming the relationship into two predictable one-to-many connections.
Cross-Filter Direction
Single Direction (default and recommended). Filters flow from the Dimension (“one” side) down to the Fact (“many” side). A single arrowhead on the relationship line, pointing toward the Fact.
Both Directions (bi-directional). Filters flow both ways. Denoted by a double arrowhead. Occasionally necessary (dynamically shrinking a slicer list, propagating across Bridge tables), but deploy with extreme caution. Indiscriminate bi-directional filtering forces massive cross-table permutations and is the leading cause of ambiguous path errors.
Active vs. Inactive Relationships
Power BI allows multiple relationships between the same two tables but enforces that only one can be Active at a time.
Active (solid line): the default filter path. Standard DAX measures use this automatically.
Inactive (dashed line): dormant until explicitly invoked via USERELATIONSHIP() in a DAX measure.
Step-by-Step: Creating Relationships
Method 1: Model View. Click the network icon on the left nav to open the Model View canvas. Click and drag a Primary Key column from the Dimension table to the Foreign Key column in the Fact table. Power BI auto-detects cardinality and cross-filter direction. Double-click the line to edit.
Method 2: Manage Relationships Dialog. From the Modeling tab, click Manage relationships > New. Select tables and columns from dropdowns, review the auto-detected settings, confirm the “Make this relationship active” checkbox, and click OK.
Joins vs. Relationships: When to Use Which
| Feature |
Power Query Join (Physical) |
Power BI Relationship (Logical) |
| What it does |
Physically combines columns into one table |
Virtual connection for dynamic filter propagation |
| When it runs |
During ETL/data refresh |
In-memory at query time during user interaction |
| Memory impact |
Can inflate row counts and duplicate text strings |
Maintains compressed, narrow tables |
| Flexibility |
Static until next refresh |
Dynamic; can toggle via DAX (USERELATIONSHIP, CROSSFILTER) |
| Best use case |
Denormalizing Snowflake to Star; appending columns from tiny lookups |
Building Star Schemas; connecting Fact to Dimension tables |
The rule: for Import mode, rely on Relationships to build a Star Schema. Use Power Query joins to flatten hyper-normalized data or append a few columns from minor lookup tables. Don’t join everything into a Flat Table in Import mode.
Role-Playing Dimensions
A classic challenge: a single Dimension table needs multiple roles. A Date table relating to a Sales fact might connect on OrderDate, ShipDate, and DeliveryDate. Power BI only allows one active relationship between any two tables, so you get one solid line and two dashed lines.
Option 1: Duplicate the Dimension
Use Power Query to reference and duplicate the Date table into independent Order_Date, Ship_Date, and Delivery_Date tables. Each gets its own active relationship.
Pros: Intuitive for self-service users. Easy to visualize two roles simultaneously on one chart.
Cons: Inflates the model. Duplicating a small Date table (3,650 rows) is negligible. Duplicating a multi-million row Customer table (acting as both BillTo and ShipTo) is costly.
Option 2: USERELATIONSHIP() in DAX
Keep one Dimension table with one active relationship. Author DAX measures that temporarily activate the inactive paths:
Sales_by_ShipDate =
CALCULATE(
    SUM(Sales[Amount]),
    USERELATIONSHIP('Date'[Date], Sales[ShipDate])
)
Pros: Minimal model size. Single source of truth.
Cons: Every metric for a secondary role needs its own measure. Analyzing two roles in the same visual requires advanced DAX.
General guideline: duplicate small lookup tables; use USERELATIONSHIP() for large dimensions.
Common Modeling Pitfalls
Ambiguous Paths
These errors occur when VertiPaq detects multiple possible routes for a filter to travel between two tables. The engine can’t guess which path you intended, so it throws an error or disables relationships.
The most common cause: reckless bi-directional filtering across multiple tables, creating loops that interact with existing single-direction paths. Another cause: a shared parent dimension (like Location) filtering both Customer and Store, which both filter the same Sales Fact, creating competing parallel paths.
Fix: return to strict Star Schema architecture. Use single-direction, one-to-many relationships exclusively. If Bridge tables are required, enable bi-directional filtering on only one side. Better yet, disable bi-directional filtering globally and manage it via the CROSSFILTER DAX function only where explicitly needed.
Circular Dependencies
A circular dependency is an infinite computational loop: Object A requires Object B, but Object B requires Object A. Power BI detects this and blocks the operation.
These rarely come from obvious formulas. They typically emerge from context transition in Calculated Columns. When a Calculated Column uses CALCULATE(), DAX transforms the current row context into a filter context, making the column depend on all other columns in the table. A second Calculated Column using CALCULATE() in the same table creates a mutual dependency lock.
Fixes:
-
Switch to a Measure. Measures evaluate dynamically at query time, bypassing the row-level context transition issue entirely.
-
Exclude conflicting columns. Use
ALLEXCEPT() or REMOVEFILTERS() to strip the dependency.
-
Move the logic upstream. Perform complex row-level arithmetic in Power Query or the source database before VertiPaq ever sees it.
Power BI data modeling rewards discipline. Star Schema, clean cardinality, single-direction filtering, and deliberate separation of physical joins from logical relationships. Get those fundamentals right and everything downstream (DAX, performance, user adoption) gets dramatically easier. The article was submitted in fulfilment of a LuxDevHQ Cohort 7 DataEngieering assignment ©adev3loper


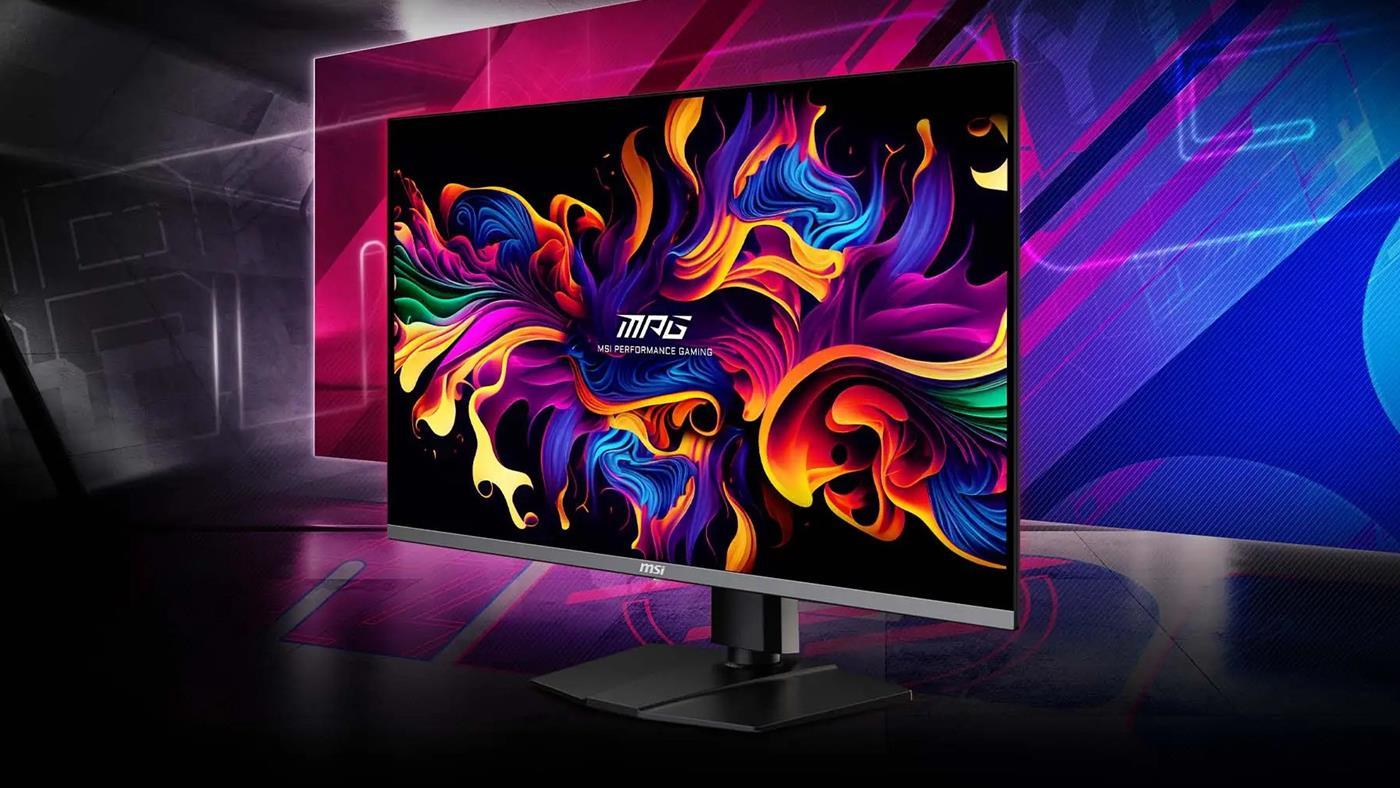
 OLED monitör pazarı 2025’te yüzde 92 büyüdü. Asus liderliğe yükselirken, Samsung ve MSI gibi markalar da rekabeti artırmaya devam ediyor. İşte en çok satan markalar…


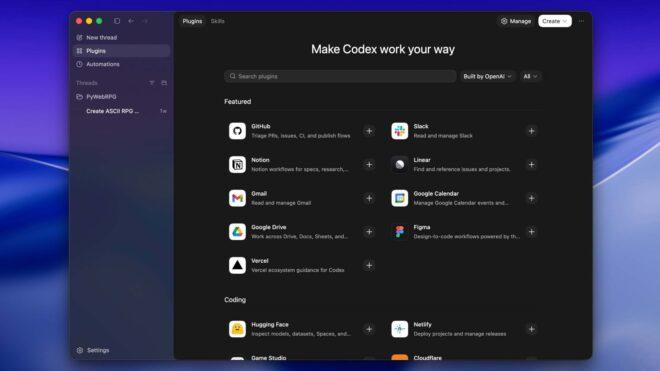
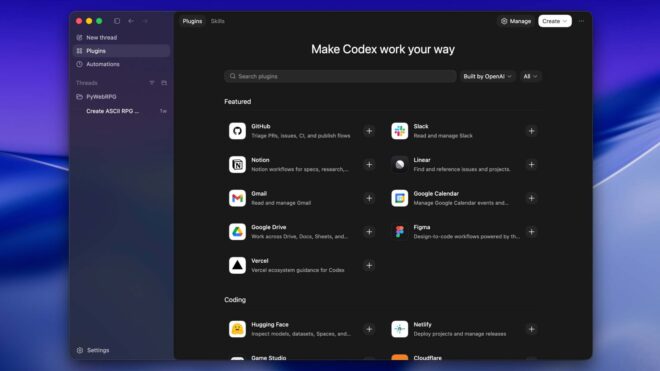 OpenAI, doğrudan geliştiricilere ve kodlamaya odaklanan Codex uygulamasına “plugin/eklenti” desteği eklediğini duyurdu. Bu konuda yaptığı açıklamada, “Codex, eklentilerle birlikte artık sadece kod yazmakla kalmıyor; kodlama öncesi planlama ve araştırma gibi hazırlık aşamalarından, kodlama sonrasındaki iş akışlarına kadar pek çok gerçek göreve destek veriyor. Örneğin Google Drive eklentisi, Codex’in Google Drive, Dokümanlar, Tablolar ve Slaytlar genelinde birleşik iş akışlarıyla tek bir döngü içerisinde çalışmasına olanak tanıyor.” ifadelerini kullanan şirket, bu altyapı ile sisteme Gmail eklentisi üzerinden e-posta okuma ve yönetme, Slack eklentisi üzerindense kanal özetleme veya yanıt taslağı hazırlama gibi özelliklerin eklenebileceğini belirtiyor. OpenAI süreçte kullanılabilecek eklentilerin hepsini uygulamaya yeni eklenen “plugin/eklenti” menüsünün altında sunuyor.