I kept forgetting to bump my VERSION file – so I built a tool to fix that

Every few weeks it happened: I’d push code, lean back — and then realize
I forgot to update the VERSION file. Again.

Not a disaster. But annoying enough that I started thinking about fixing it.

The problem

I work on many projects in parallel. Each has a VERSION file that I maintain manually. The problem is: there’s no built-in reminder. Nothing tells you “hey, you changed files since the last version bump.” You just have to remember.

And I kept not remembering.

The solution I built

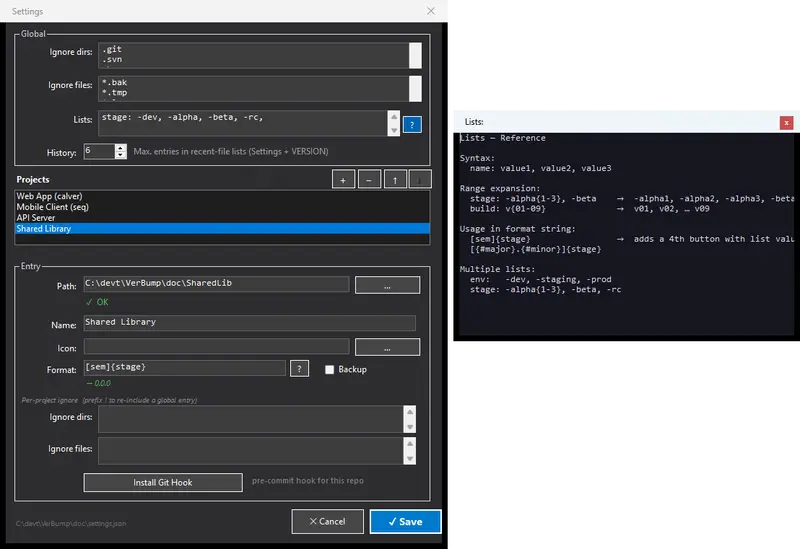
I built VerBump — a small Windows tool that shows all my projects in one window and highlights in orange which ones have source files newer than the current VERSION file.

One glance, and I know exactly what needs bumping before I push.

Bumping itself is keyboard-driven: Ctrl+1 for Patch, Ctrl+2 for Minor,
Ctrl+3 for Major. No mouse, no dialogs, done in two seconds.

The “set it and forget it” mode

For projects where I really don’t want to think about it at all, VerBump can install a Git pre-commit hook. It blocks the commit automatically if VERSION is stale — before the push even happens.

That’s the version I use for my most active projects.

Technical bits

  • Built with C# / .NET 8 / WinForms
  • Ships as a single self-contained .exe — no installer, no runtime needed
  • Supports SemVer, CalVer, and custom sequential schemes
  • Multilingual (EN/DE, more via lang.xx.json drop-in)
  • MIT licensed

Honest reflection

It saves me more worry, rework, and time than I spent building it.

If you work on multiple projects in parallel and maintain VERSION files,
give it a try. Feedback very welcome!

→ GitHub ·
Website

[LeapMotion + UniRx] Moving a Camera with Hand Gestures: Two-Hand Edition

vlcsnap-2019-04-22-16h28m17s785.png

vlcsnap-2019-04-22-16h28m17s785.png

Introduction

In the previous article, I implemented translating the Main Camera using one-hand Leap Motion input when no mouse or keyboard is available.

This time, I’m adding rotation and zoom control as well.

Demo

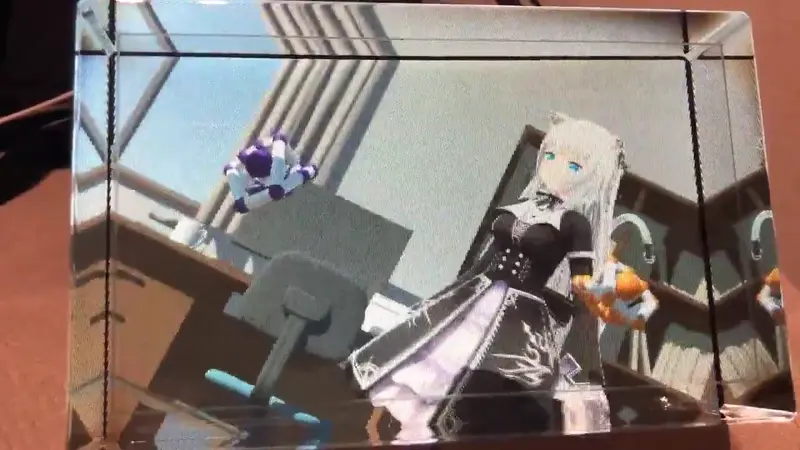
Here’s what I built. I exhibited it at Looking Glass Meetup (Rukimito).

// Detect dark theme
var iframe = document.getElementById(‘tweet-1109754332092624896-397’);
if (document.body.className.includes(‘dark-theme’)) {
iframe.src = “https://platform.twitter.com/embed/Tweet.html?id=1109754332092624896&theme=dark”
}

When both hands are in a fist, the camera responds to hand movement with three operations:

  • Scale (zoom in/out)
  • Rotation
  • Translation (pan)

Sample Code

Here is the full code. It is intended to be attached to the Main Camera.

using Leap;
using System.Collections.Generic;
using System.Linq;
using UniRx;
using UniRx.Triggers;
using UnityEngine;

/// <summary>
/// Camera controller
/// </summary>
public class CameraController : MonoBehaviour
{
    /** Camera movement speed */
    private float speed = 0.025f;

    /** Leap Motion controller */
    private Controller controller;

    /** Entry point */
    void Start()
    {
        // Leap Motion controller
        controller = new Controller();

        // Get hand data from Leap Motion every frame
        var handsStream = this.UpdateAsObservable()
            .Select(_ => controller.Frame().Hands);

        // Stream that fires when both-fist gesture starts
        var beginDoubleRockGripStream = handsStream
            .Where(hands => IsDoubleRockGrip(hands));

        // Stream that fires when both-fist gesture ends
        var endDoubleRockGripStream = handsStream
            .Where(hands => !IsDoubleRockGrip(hands));

        // Camera zoom (scale)
        beginDoubleRockGripStream
            .Select(hands => hands[0].PalmPosition.DistanceTo(hands[1].PalmPosition))
            .Where(distance => distance > 0.0f)
            .Buffer(2, 1)
            .Select(distances => distances[1] / distances[0])
            .TakeUntil(endDoubleRockGripStream).RepeatUntilDestroy(this)
            .Where(distanceRate => distanceRate > 0.0f)
            .Subscribe(distanceRate => transform.localScale /= distanceRate);

        // Camera rotation
        beginDoubleRockGripStream
            .Select(hands => ToVector3(hands[1].PalmPosition - hands[0].PalmPosition))
            .Where(diff => diff.magnitude > 0.0f)
            .Buffer(2, 1)
            .Select(diffs => Quaternion.AngleAxis(Vector3.Angle(diffs[0], diffs[1]), Vector3.Cross(diffs[1], diffs[0])))
            .TakeUntil(endDoubleRockGripStream).RepeatUntilDestroy(this)
            .Subscribe(quaternion => transform.rotation *= quaternion);

        // Camera translation
        beginDoubleRockGripStream
            .Select(hands => ToVector3((hands[0].PalmPosition + hands[1].PalmPosition) * 0.5f))
            .Buffer(2, 1)
            .Select(positions => positions[1] - positions[0])
            .TakeUntil(endDoubleRockGripStream).RepeatUntilDestroy(this)
            .Subscribe(movement => transform.Translate(-speed * movement));
    }

    /** Check if both hands are making a fist */
    public bool IsDoubleRockGrip(List<Hand> hands)
    {
        return
            hands.Count == 2 &&
            hands[0].Fingers.ToArray().Count(x => x.IsExtended) == 0 &&
            hands[1].Fingers.ToArray().Count(x => x.IsExtended) == 0;
    }

    /** Convert Leap Vector to Unity Vector3 */
    Vector3 ToVector3(Vector v)
    {
        return new Vector3(v.x, v.y, -v.z);
    }
}

Detecting Both-Fist Gesture

IsDoubleRockGrip handles the detection. In the previous article we detected one fist; here we detect two.

/** Check if both hands are making a fist */
public bool IsDoubleRockGrip(List<Hand> hands)
{
    return
        // Two hands detected
        hands.Count == 2 &&
        // First hand: no fingers extended
        hands[0].Fingers.ToArray().Count(x => x.IsExtended) == 0 &&
        // Second hand: no fingers extended
        hands[1].Fingers.ToArray().Count(x => x.IsExtended) == 0;
}

hands.Count verifies that Leap Motion detects exactly two hands, and Count(x => x.IsExtended) == 0 checks that all fingers on each hand are closed.

Camera Zoom

The zoom behavior is:

  • Move hands apart → zoom in
  • Move hands together → zoom out

Here’s the relevant code with comments:

// Camera zoom (scale)
beginDoubleRockGripStream
    // Calculate distance between both palms
    .Select(hands => hands[0].PalmPosition.DistanceTo(hands[1].PalmPosition))
    // Only if distance is positive (avoid division by zero)
    .Where(distance => distance > 0.0f)
    // Buffer current and previous values
    .Buffer(2, 1)
    // Calculate ratio of change in distance
    .Select(distances => distances[1] / distances[0])
    // Clear buffer when both-fist gesture ends
    .TakeUntil(endDoubleRockGripStream).RepeatUntilDestroy(this)
    // Only if ratio is positive (avoid division by zero)
    .Where(distanceRate => distanceRate > 0.0f)
    // Scale the camera
    .Subscribe(distanceRate => transform.localScale /= distanceRate);

hands[0].PalmPosition.DistanceTo(hands[1].PalmPosition) computes the distance between the two palms. The ratio of change in distance controls the camera’s scale.

Camera Rotation

It’s difficult to describe in words, but: make both hands into fists and move them like turning a steering wheel — the camera rotates in that direction.

// Camera rotation
beginDoubleRockGripStream
    // Compute the difference vector between both palms
    .Select(hands => ToVector3(hands[1].PalmPosition - hands[0].PalmPosition))
    // Only if magnitude is positive (avoid issues with zero-length vectors)
    .Where(diff => diff.magnitude > 0.0f)
    // Buffer current and previous values
    .Buffer(2, 1)
    // Compute the rotational change (quaternion) from dot and cross products
    .Select(diffs => Quaternion.AngleAxis(Vector3.Angle(diffs[0], diffs[1]), Vector3.Cross(diffs[1], diffs[0])))
    // Clear buffer when both-fist gesture ends
    .TakeUntil(endDoubleRockGripStream).RepeatUntilDestroy(this)
    // Rotate the camera
    .Subscribe(quaternion => transform.rotation *= quaternion);

The steps are:

  • hands[1].PalmPosition - hands[0].PalmPosition computes the vector difference between the two palms.
  • This vector is buffered across two frames.
  • The dot product and cross product between the previous and current vectors are used to compute the angular change as a quaternion.
  • That quaternion is multiplied into the camera’s rotation.

Camera Translation

I use the midpoint of both palms to drive translation. This means:

  • Moving both fists in the same direction → the camera pans in that direction
  • Moving hands in opposite directions → no translation (only zoom)
// Camera translation
beginDoubleRockGripStream
    // Compute the midpoint of both palms
    .Select(hands => ToVector3((hands[0].PalmPosition + hands[1].PalmPosition) * 0.5f))
    // Buffer current and previous values
    .Buffer(2, 1)
    // Calculate the midpoint movement vector
    .Select(positions => positions[1] - positions[0])
    // Clear buffer when both-fist gesture ends
    .TakeUntil(endDoubleRockGripStream).RepeatUntilDestroy(this)
    // Move the camera
    .Subscribe(movement => transform.Translate(-speed * movement));

(hands[0].PalmPosition + hands[1].PalmPosition) * 0.5f computes the midpoint of both palms.

Closing

When I demoed this UI to people unfamiliar with Leap Motion one-on-one, they needed some explanation. But at the Looking Glass Meetup, almost everyone understood the controls instantly — which was really impressive!

React Native Android build failed: what I would check first

If a React Native Android build suddenly fails, the error message is often much less helpful than it looks.

Sometimes it points to Gradle, sometimes to a plugin, sometimes to a dependency, and sometimes it just fails deep inside the Android build process without making the real cause obvious.

I’ve run into this kind of problem enough times to stop treating “build failed” as one issue.

It is usually a category of issues.

This is the checklist I would go through first before changing random files or reinstalling everything.

First: treat build failures as clues, not conclusions

A React Native Android build can fail because of:

  • Gradle configuration issues
  • plugin resolution problems
  • dependency/version mismatches
  • Kotlin or AGP incompatibility
  • corrupted caches
  • autolinking problems
  • native module integration issues
  • environment/setup problems on the machine

That means the text BUILD FAILED is not the diagnosis. It is just the start of the diagnosis.

What I would check first

1. Read the first meaningful error, not the last line

One of the easiest mistakes is focusing on the bottom of the terminal output.

The last line usually just says the build failed. The useful part is often earlier:

  • the first missing plugin
  • the first unresolved dependency
  • the first incompatible version
  • the first task that actually broke

If I see a huge wall of Gradle output, I try to find the first message that clearly indicates what could not be found, resolved, or configured.

That usually narrows the problem much faster.

2. Check React Native / Gradle / AGP / Kotlin compatibility

A lot of Android build failures are really version alignment problems.

I would check whether these pieces actually make sense together:

  • React Native version
  • Gradle wrapper version
  • Android Gradle Plugin version
  • Kotlin version
  • installed JDK version

A mismatch here can break the build even when your app code is fine.

This is especially common after:

  • upgrading React Native
  • adding or updating native libraries
  • copying build config from another project
  • mixing Expo/native config changes

3. Look at settings.gradle and plugin resolution first

If the error mentions plugins not being found, configuration failing, or included builds not resolving correctly, I would go straight to:

  • android/settings.gradle
  • root build.gradle
  • plugin management / includeBuild setup

In newer React Native setups, especially around the Gradle plugin and autolinking, small mistakes there can break the entire build.

This is one of the first places I would inspect if the error looks structural instead of library-specific.

4. Check whether this is really a cache problem

Sometimes it is. Sometimes it is not.

I would only treat it as a cache issue when the error actually suggests things like:

  • temp workspace move failures
  • corrupted transforms
  • unexpected stale build behavior
  • dependency artifacts behaving inconsistently

In that case, I would think about:

  • Gradle daemon state
  • .gradle cache corruption
  • android/.gradle
  • android/build
  • whether Android Studio or another process is holding locks

But I would not start by deleting everything automatically unless the error really points that way.

5. Check native dependencies and recently added packages

If the build worked before and stopped working after adding or updating something, that is one of the strongest signals you have.

I would ask:

  • what changed last?
  • did I add a native dependency?
  • did I update Firebase packages?
  • did I change Expo/native modules?
  • did I update React Native or Gradle-related files?

That often gives a faster answer than staring at logs in isolation.

6. Watch for autolinking and native module issues

React Native Android builds often fail because a native module was not linked/configured the way the project expects.

This gets more likely when:

  • mixing Expo modules with bare React Native config
  • using libraries with native setup steps
  • upgrading React Native without updating supporting config
  • relying on autolinking that did not actually complete properly

If the error mentions package resolution, missing generated files, or native tasks around module setup, I would treat autolinking as a serious suspect.

7. Distinguish machine/setup problems from project problems

Sometimes the project is broken.

Sometimes the machine is.

That is an important difference.

I would think about machine/environment issues when the error points toward:

  • JDK problems
  • missing Android SDK components
  • PATH / environment variable issues
  • SSL / certificate / dependency download failures
  • local file locking or permissions

That is why a build issue can appear “random” even when the project itself has not changed much.

8. If Firebase is involved, do not assume it is only a Firebase issue

Firebase-related packages can surface as Android build failures even when the deeper cause is one of these:

  • dependency mismatch
  • outdated native setup
  • plugin/version conflict
  • Gradle packaging issue
  • release/debug configuration difference

So if the failure starts after adding Firebase or changing Firebase setup, I would still inspect the Android build chain broadly instead of narrowing too fast.

A practical mental model

When I see “React Native Android build failed,” I usually sort the possibilities into these buckets:

Bucket 1: Build system

  • Gradle
  • AGP
  • Kotlin
  • plugin management
  • wrapper version

Bucket 2: Native integration

  • autolinking
  • native modules
  • Expo/native mix
  • Firebase native setup

Bucket 3: Local environment

  • JDK
  • SDK
  • PATH
  • cache corruption
  • SSL/certificate/download issues

That mental model helps me avoid random debugging.

What I would not do first

I would not immediately:

  • reinstall the whole machine setup
  • randomly edit multiple Gradle files
  • downgrade several libraries at once
  • clear every cache without understanding the error
  • assume the last line in the terminal is the root cause

That usually creates more noise.

My practical order of checks

If a React Native Android build fails, this is the order I would usually go through:

  1. find the first meaningful error in the output
  2. check version compatibility across RN / Gradle / AGP / Kotlin / JDK
  3. inspect settings.gradle and plugin resolution
  4. review the most recent package or config change
  5. check native module/autolinking issues
  6. only then treat it as cache/environment cleanup if the error points there

That order tends to save time.

Final takeaway

“React Native Android build failed” is not one problem.

It is usually one of a few repeated categories:

  • version mismatch
  • plugin/config problem
  • native integration issue
  • cache/environment issue

The faster you identify which category you are in, the faster the build becomes fixable.

Neon Has a Free Serverless PostgreSQL — Scale to Zero, Branch Like Git

RDS costs $15/month even when sleeping. Neon’s serverless PostgreSQL scales to zero — and you only pay when queries run.

What is Neon?

Neon is serverless PostgreSQL that separates storage and compute. Your database scales to zero when idle, branches like git for testing, and wakes up in milliseconds when a query arrives.

Why Neon

1. Scale to Zero

Traditional PostgreSQL:
Midnight: 0 queries → still paying $15/month
3 AM: 0 queries → still paying
6 AM: 1 query → compute wakes up → serves query → back to zero

Neon:
Midnight: 0 queries → $0
3 AM: 0 queries → $0
6 AM: 1 query → compute activates in ~500ms → serves query → scales to zero

2. Database Branching

# Create a branch from production
neonctl branches create --name feature-auth --parent main

# Test schema changes on the branch
psql $BRANCH_URL -c "ALTER TABLE users ADD COLUMN avatar_url TEXT;"

# Branch has production data but changes don't affect main
# Delete when done
neonctl branches delete feature-auth

3. Serverless Driver (HTTP)

import { neon } from '@neondatabase/serverless';

const sql = neon(process.env.DATABASE_URL);

// Works in Vercel Edge, Cloudflare Workers, Deno Deploy
const users = await sql`SELECT * FROM users WHERE active = true LIMIT 10`;

No TCP connections. Pure HTTP — works in any serverless runtime.

4. Connection Pooling

import { Pool } from '@neondatabase/serverless';

const pool = new Pool({ connectionString: process.env.DATABASE_URL });

// WebSocket-based pooling for serverless
const client = await pool.connect();
const result = await client.query('SELECT * FROM products');
client.release();

5. Instant Point-in-Time Restore

# Restore to any point in the last 7 days (free) or 30 days (paid)
neonctl branches restore main --timestamp "2026-03-27T15:30:00Z"

6. Autoscaling

Free tier: 0.25 vCPU (scales to zero)
Pro: 0.25 → 8 vCPU (auto-scales based on load)

Morning: 0.25 vCPU (low traffic)
Noon: 2 vCPU (peak)
Night: 0 vCPU (scaled to zero)

Free Tier

Feature Free
Compute hours 191h/month
Storage 512 MB
Branches 10
History 7 days
Projects 1

191 compute hours = always-on for a small app, or scale-to-zero for multiple projects.

Neon vs Supabase vs PlanetScale vs RDS

Neon Supabase PlanetScale RDS
Database PostgreSQL PostgreSQL MySQL Any
Scale to zero Yes No Yes No
Branching Yes No Yes No
Serverless driver HTTP PostgREST HTTP No
Connection pooling Built-in PgBouncer Built-in Via proxy
Free tier 512MB, 191h 500MB, always-on 5GB, sleep None

Getting Started

# Sign up at neon.tech
# Create project → get connection string

npm install @neondatabase/serverless
import { neon } from '@neondatabase/serverless';
const sql = neon(process.env.DATABASE_URL);
const result = await sql`SELECT NOW()`;

The Bottom Line

Neon makes PostgreSQL serverless-native. Scale to zero for $0 idle cost, branch for safe testing, and connect from any edge runtime via HTTP. The best free PostgreSQL for side projects.

Need data tools? I build scraping solutions. Check my Apify actors or email [email protected].

How to Scrape Glassdoor: Complete Guide for 2026

How to Scrape Glassdoor: Complete Guide for 2026

Glassdoor exposes salary data, company reviews, and job listings that are genuinely useful for compensation benchmarking, recruiting analysis, and labor market research. The catch: Glassdoor runs Cloudflare, gates salary data behind authentication, and renders all meaningful content client-side with React. This guide cuts through those obstacles with working Python code.

Why Scrape Glassdoor?

Three use cases that justify the engineering effort:

Compensation benchmarking — HR teams and SaaS products aggregate salary ranges by role, level, location, and company size. Glassdoor’s crowdsourced compensation data is one of the richest publicly accessible sources for this kind of analysis. Refreshing it weekly catches market shifts before they show up in annual survey reports.

Competitive talent intelligence — Track hiring velocity at competitors. Which roles are they posting? How quickly are positions closing? Job listing volume is a reliable leading indicator of engineering and product priorities six to nine months out.

Employer brand monitoring — Tracking review sentiment over time — overall ratings, CEO approval, interview difficulty scores — gives recruiting teams early warning of culture problems before they surface as churn events. Companies also benchmark their own standing against direct competitors.

Anti-Bot Challenges on glassdoor.com

Glassdoor deploys several overlapping protections that make DIY scraping expensive to maintain:

Cloudflare WAF and Bot Management — Glassdoor sits behind Cloudflare’s bot management layer. A standard Python requests call receives a JS challenge page requiring a valid cf_clearance cookie before any real HTML is served. This blocks virtually every naive scraper immediately.

Login wall for salary data — Salary ranges and detailed compensation breakdowns are gated behind authentication. Unauthenticated sessions see truncated results or get redirected to a signup modal. Full data access requires managing authenticated sessions with valid cookies.

Client-side rendering — Job listings, reviews, and salary cards are all React components. The initial HTML response from Glassdoor’s server is a near-empty shell. You need a JavaScript runtime to execute the page and produce actual content.

Browser fingerprinting and behavioral detection — Glassdoor combines static browser fingerprinting with behavioral signals (scroll cadence, mouse movement, click timing) to identify headless browsers. Playwright and Puppeteer with default configurations are reliably flagged within a few page loads.

Maintaining your own bypass stack — refreshing cf_clearance cookies, managing residential proxy pools, spoofing browser fingerprints — is a real ongoing engineering commitment. AlterLab’s Anti-bot bypass API handles all of this at the infrastructure level, so your scraping code stays focused on data extraction.

Quick Start with AlterLab API

Install the SDK and you can make your first Glassdoor request in under a minute. See the getting started guide for full environment setup, including API key management and optional async configuration.

“`bash title=”Terminal”
pip install alterlab beautifulsoup4 lxml


```python title="scrape_glassdoor.py" {4-11}

from bs4 import BeautifulSoup

client = alterlab.Client("YOUR_API_KEY")

# Scrape a Glassdoor job search results page
response = client.scrape(
    "https://www.glassdoor.com/Job/python-developer-jobs-SRCH_KO0,16.htm",
    render_js=True,                          # Required: Glassdoor is a React SPA
    wait_for="[data-test='jobListing']",     # Wait for job cards before returning
)

soup = BeautifulSoup(response.html, "html.parser")
job_cards = soup.select("[data-test='jobListing']")
print(f"Found {len(job_cards)} job listings")

The equivalent cURL call for testing from a shell or integrating with non-Python pipelines:

“`bash title=”Terminal”
curl -X POST https://api.alterlab.io/v1/scrape
-H “X-API-Key: YOUR_API_KEY”
-H “Content-Type: application/json”
-d ‘{
“url”: “https://www.glassdoor.com/Job/python-developer-jobs-SRCH_KO0,16.htm“,
“render_js”: true,
“wait_for”: “[data-test=”jobListing”]”
}’


<div data-infographic="stats">
  <div data-stat data-value="99.1%" data-label="Glassdoor Success Rate"></div>
  <div data-stat data-value="2.4s" data-label="Avg JS Render Time"></div>
  <div data-stat data-value="100%" data-label="Cloudflare Bypass Rate"></div>
  <div data-stat data-value="0ms" data-label="Proxy Setup Time"></div>
</div>

## Extracting Structured Data

With fully rendered HTML in hand, here is how to pull the most useful data points from Glassdoor's DOM.

### Job Listings

Glassdoor uses `data-test` attributes on stable semantic elements — always prefer these over generated class names, which change with every React build deployment.


```python title="parse_jobs.py" {9-22}
from bs4 import BeautifulSoup

def parse_job_listings(html: str) -> list[dict]:
    soup = BeautifulSoup(html, "html.parser")
    jobs = []

    for card in soup.select("[data-test='jobListing']"):
        def text(selector):
            el = card.select_one(selector)
            return el.get_text(strip=True) if el else None

        jobs.append({
            "title":    text("[data-test='job-title']"),
            "company":  text("[data-test='employer-name']"),
            "location": text("[data-test='emp-location']"),
            "salary":   text("[data-test='detailSalary']"),
            "rating":   text("[data-test='rating']"),
            "age":      text("[data-test='job-age']"),
        })

    return jobs

Company Reviews

Review pages are paginated at 10 entries per page. The _IP{n} path segment in the URL controls the page number.

“`python title=”parse_reviews.py” {6-22}

from bs4 import BeautifulSoup

client = alterlab.Client(“YOUR_API_KEY”)

def scrape_company_reviews(company_slug: str, pages: int = 5) -> list[dict]:
“””
company_slug: e.g. ‘Google’ (as it appears in the Glassdoor URL)
“””
reviews = []
slug_len = len(company_slug)

for page in range(1, pages + 1):
    url = (
        f"https://www.glassdoor.com/Reviews/{company_slug}-reviews"
        f"-SRCH_KE0,{slug_len}_IP{page}.htm"
    )
    response = client.scrape(url, render_js=True, wait_for="[data-test='review']")
    soup = BeautifulSoup(response.html, "html.parser")

    for review in soup.select("[data-test='review']"):
        def text(selector):
            el = review.select_one(selector)
            return el.get_text(strip=True) if el else None

        reviews.append({
            "headline": text("[data-test='review-title']"),
            "rating":   text("[data-test='overall-rating']"),
            "pros":     text("[data-test='pros']"),
            "cons":     text("[data-test='cons']"),
            "date":     text("[data-test='review-date']"),
            "role":     text("[data-test='author-jobTitle']"),
        })

return reviews


### Salary Data

Salary pages require an authenticated session. Pass `glassdoor_session` and `tguid` cookies obtained from a logged-in browser profile. The API accepts a `headers` dict for this purpose:


```python title="parse_salaries.py" {5-12}

client = alterlab.Client("YOUR_API_KEY")

response = client.scrape(
    "https://www.glassdoor.com/Salaries/software-engineer-salary-SRCH_KO0,17.htm",
    render_js=True,
    headers={
        "Cookie": "JSESSIONID=YOUR_SESSION_ID; tguid=YOUR_TGUID"
    },
    wait_for="[data-test='salaryRow']",
)

Key selectors once authenticated: [data-test='salaryRow'] for each salary entry, [data-test='salary-estimate'] for the reported range, and [data-test='total-compensation'] for the total comp breakdown.

Common Pitfalls

Per-IP rate limiting — Glassdoor throttles at the IP level, not just by User-Agent. Exceeding roughly 25–30 requests per minute from a single IP triggers 429 responses or silent result degradation, where fewer listings are returned without any error signal. Distributed requests across rotating proxies are required for sustained collection.

Session expiry on gated content — Glassdoor sessions expire within a few hours. For pipelines that scrape salary or authenticated review data, implement cookie refresh logic. Detect redirects to /profile/login as the signal that your session has expired and re-authenticate before continuing.

Hard pagination cap — Glassdoor limits job search results to 30 pages (300 results) per query regardless of how many matching listings exist. Paginating past page 30 returns the first page again. The correct approach is to narrow queries by location, fromAge (days posted), or jobType parameter rather than paginating deeper on a broad query.

Selector drift — Glassdoor ships frontend updates frequently. Class names change with every React build. The data-test attributes documented above are more stable, but they can also shift. Build result-count validation into your pipeline: if a parse returns zero records, treat that as a selector failure, not an empty result set, and alert.

Hydration timing — Even with render_js=True, returning content before React has finished hydrating gives you an empty shell. Always set wait_for to a CSS selector matching a target element, not just a fixed timeout. The element-based wait adapts to variable page load times automatically.

Scaling Up

Batch Requests

For bulk collection across many search permutations — dozens of cities, multiple job titles, rolling date windows — the AlterLab batch endpoint processes URLs in parallel and is significantly more efficient than sequential requests:

“`python title=”batch_glassdoor.py” {5-20}

client = alterlab.Client(“YOUR_API_KEY”)

cities = [
(“new-york-city”, “IC1132348”),
(“san-francisco”, “IC1147401”),
(“austin”, “IC1139761”),
(“seattle”, “IC1150505”),
(“chicago”, “IC1128808”),
]

urls = [
f”https://www.glassdoor.com/Job/python-engineer-{slug}-jobs-SRCH_IL.0,{len(slug)}_IC{code}_IP{page}.htm“
for slug, code in cities
for page in range(1, 11) # 10 pages × 5 cities = 50 requests
]

results = client.batch_scrape(
urls=urls,
render_js=True,
wait_for=”[data-test=’jobListing’]”,
concurrency=10,
)

with open(“glassdoor_jobs.jsonl”, “w”) as f:
for r in results:
if r.success:
f.write(json.dumps({“url”: r.url, “html”: r.html}) + “n”)


### Scheduling Recurring Pipelines

For daily job market snapshots or weekly salary index updates, wire the scraper to a scheduler. APScheduler is lightweight and runs in-process without a separate queue service:


```python title="scheduler.py" {8-16}
from apscheduler.schedulers.blocking import BlockingScheduler

from parse_jobs import parse_job_listings

client = alterlab.Client("YOUR_API_KEY")
scheduler = BlockingScheduler()

@scheduler.scheduled_job("cron", hour=2, minute=0)  # 02:00 daily
def daily_glassdoor_pull():
    roles = ["software-engineer", "data-engineer", "product-manager", "ml-engineer"]
    for role in roles:
        url = f"https://www.glassdoor.com/Salaries/{role}-salary-SRCH_KO0,{len(role)}.htm"
        response = client.scrape(url, render_js=True, wait_for="[data-test='salaryRow']")
        jobs = parse_job_listings(response.html)
        store_to_warehouse(jobs)   # your storage layer here

scheduler.start()

Cost Management at Scale

Not every Glassdoor page requires full JavaScript execution. Company overview pages and some listing shells partially pre-render server-side. Profile your target URLs: attempt a plain HTML fetch first and check whether your target selectors are present. Use render_js=False wherever possible — it is faster and consumes fewer credits. Reserve JS rendering for pages that require it.

Review AlterLab pricing for credit consumption rates broken down by request type before sizing your pipeline budget.

Key Takeaways

  • JavaScript rendering is not optional — Glassdoor’s content is React-rendered. A plain HTTP fetch returns a shell. Always set render_js=True and use wait_for with a target element selector.
  • Cloudflare is the primary blocker — do not spend engineering cycles maintaining your own bypass. It is a dependency, not a competitive advantage.
  • Prefer data-test attributes over class names — class names change with every build. data-test attributes are intentionally stable for testing and are your most reliable selection strategy.
  • Salary data requires authentication — pass valid session cookies and implement refresh logic for any pipeline running longer than a few hours.
  • Respect the 30-page cap — use query narrowing (location, date posted, job type) rather than deep pagination to collect comprehensive datasets.
  • Batch and schedule deliberately — sequential requests are fine for development; batch endpoints with concurrency control are essential for production pipelines.

Related Guides

  • How to Scrape LinkedIn — professional profiles, company pages, and job postings behind one of the web’s most aggressive anti-bot stacks
  • How to Scrape Indeed — job listings and employer reviews with simpler authentication requirements than Glassdoor
  • How to Scrape Amazon — product pricing, reviews, and inventory data at scale with dynamic rendering handled

How I Built Factcovery in 2 Days with Claude — 0 Lines of Code Written by Me

Here’s what Factcovery actually looks like.

Website

Mobile App

App coming soon, pending store review

Lighthouse Report

Honestly, hitting a good Lighthouse score isn’t rocket science — but I’m pretty confident AI will nail it more consistently than most of us would on our own.

Factcovery is live at factcovery.com. The mobile app is coming soon — currently pending store review. Have you tried building this way? I’d love to hear how it went in the comments.

First things first — this is NOT vibe coding

There’s a way most people use AI that looks something like this: open Claude or ChatGPT, type “build me a todo app”, get code back, paste it in, pray it works. When it breaks, paste the error back in. Repeat forever.

That’s vibe coding. It works fine for small throwaway tasks. But for a real product — with a web app, a REST API, a mobile app, and CI/CD — it falls apart fast.

What I did was a little different. I used Claude as an AI Agent, which means before Claude writes a single line of code, we plan together first.

The core rule: Plan in plain English → Review → Then build.

Nothing fancy. But that one extra step changed everything about how the project turned out.

What is Factcovery?

Factcovery is an app that aggregates and generates interesting “facts” by topic — bite-sized, accurate, shareable pieces of information you’d want to send to a friend.

The final stack:

  • Web: NuxtJS
  • API: Django REST Framework
  • Mobile: Flutter
  • Infrastructure: GitHub Actions + VPS

Total time: ~2 days.

Part 1 — Web with NuxtJS: Plan first, code second

The first step is never code — it’s a conversation

Instead of saying “build me a web app about facts”, I started with an actual conversation:

My prompt:
“I want to build a web app called Factcovery — where users can discover interesting facts by topic. Target users are 20–35 year olds who like quick reads and mostly browse on mobile. Before writing any code, help me list all the screens we need, the main user flows, and suggest a folder structure for NuxtJS. No code yet — just the plan.”

Claude came back with a clear plan: a list of screens, a user journey from app open to sharing a fact, and a sensible folder structure. I read it, adjusted what didn’t feel right, and only then gave Claude the green light to start coding.

This is the key point: you make the decisions, Claude does the execution.

UI — Describe the feeling, not the pixels

I didn’t say “blue button, border-radius 8px”. I said:

My prompt:
“The UI of Factcovery should feel like a modern science magazine — clean, has depth, not too serious. Dark background with amber yellow as the accent color. Typography needs to be readable on mobile. Please propose a simple design system: color palette, font pairing, spacing scale. Then apply it to the homepage.”

The result? A consistent design system from day one — not something patched together screen by screen.

Multiple Languages — Plan it from the start

Retrofitting i18n into an existing codebase is painful. This time I asked Claude to plan the i18n strategy before the project structure was even finalized:

My prompt:
“This project needs to support English and Vietnamese from day one. Propose how to organize translation files in NuxtJS, a naming convention for keys, and a workflow for adding new languages later without having to refactor. No code yet — just the approach.”

Lighthouse — Build for performance, don’t fix it later

Instead of waiting until the app was done to find out the Lighthouse score was bad, I asked Claude upfront:

My prompt:
“For a NuxtJS app that displays a lot of text and images, what are the most common Lighthouse issues? Create a checklist of things to implement from the start to hit 90+ on both mobile and desktop.”

Claude returned a concrete checklist. I implemented it while building — not after.

Part 2 — Django Backend: Read the frontend, then write the API

A reverse workflow — that actually makes sense

Instead of designing the API first and making the frontend conform to it, I did the opposite: I used the frontend code itself as input for Claude to infer the data model.

My prompt:
“Here are my Nuxt components and pages [paste code]. From these, infer the Django models needed, the relationships between them, and the minimum API endpoints required for the frontend to work correctly. Output in this order: Models → Serializers → URLs.”

The result was a backend that was in sync with the frontend from the very beginning — no discovering missing fields after the fact.

Crawl & Generate Fact Pipeline

This was the most logic-heavy part. I spent the most time on the planning step before letting Claude write anything:

My prompt:
“I need a pipeline: crawl news sources → extract content → use AI to summarize into a short ‘fact’ → save to DB → expose via API. Design the architecture for this pipeline: what Django models are needed, what task queue to use, error handling strategy, and how to schedule it to run periodically. No code yet — just the architecture in text form.”

After reviewing and tweaking the architecture, I had Claude implement it piece by piece.

Part 3 — Mobile with Flutter: Know when to pivot

Tried React Native — and recognized it wasn’t the right fit

I started with React Native because I was comfortable in the JavaScript ecosystem. Claude scaffolded the project, I ran it, and the performance wasn’t where I wanted it — animations felt sluggish, and the structure was more complex than a relatively simple app needed.

Instead of trying to fix it, I made the call to pivot. This is where human judgment matters more than any prompt.

Switching to Flutter

With Flutter, I started fresh — the right way:

My prompt:
“I’m building the Factcovery mobile app with Flutter. The app has these screens: [list]. Please propose: project structure, a state management solution that fits this app, naming conventions, and how to organize the theme and styles. Explain the reasoning behind each choice.”

Claude didn’t just give me a structure — it explained why. I read it, understood the reasoning, and agreed before moving forward.

Push Notification System

My prompt:
“I need push notifications for the Flutter app: notify users when there are new facts on topics they follow. Plan the entire flow: from user subscribing to a topic → backend triggering the notification → Flutter receiving and displaying it. Include background handling. Plan first, code after.”

Part 4 — CI/CD: GitHub Actions deploying to VPS

This is the part that intimidates a lot of people — but with the “plan first” approach, it’s straightforward:

My prompt:
“I have a VPS running Ubuntu and my code is on GitHub. When I push to main, I want to automatically: SSH into the VPS, git pull, run docker-compose up to restart services, then run a health check. Plan this workflow step by step, then write the complete .github/workflows/deploy.yml file. Also suggest how to set up SSH keys securely for GitHub Actions.”

Claude wrote the full YAML config, the deploy script, and a guide for setting up secrets. I just read it, understood the flow, and followed the instructions.

What I learned

✅ What worked really well

1. Always ask for a plan before any code
This is rule number one. Any task more complex than “fix this specific bug” should start with a planning conversation. Spending 5 extra minutes on a plan saves 2 hours of debugging.

2. Use the output of one step as input for the next
Frontend code → input for backend design. Backend API spec → input for mobile app. Everything connects in a logical chain.

3. Ask Claude to explain its reasoning
Add “explain why” to your prompts. You don’t need to read every line of code, but understanding the reasoning lets you review properly and make real decisions.

4. Break tasks into small pieces — don’t prompt everything at once
One giant prompt = mediocre output across the board. One focused prompt per step = higher quality output that’s actually reviewable.

⚠️ Where human judgment is still essential

  • Deciding to pivot (like switching from React Native to Flutter): AI can’t sense that something “feels off” in the context of your specific project.
  • Reviewing architecture before implementation: Claude will suggest something reasonable, but you understand the business requirements better than it does.
  • Choosing trade-offs: When Claude presents multiple options, you’re the one who decides — not Claude.

The real cost of building with AI

Let’s talk about something people rarely mention in posts like this — how much it actually costs.

I’m on Claude Pro ($20/month). For a normal day of work, that’s more than enough. But building an entire product in 2 days — web, API, mobile, and CI/CD all at once — is not a normal day. I hit the usage limit. Multiple times.

When that happened, I switched over to minimax 2.5 to keep the momentum going – It’s free. It handled most tasks just fine, but there were moments where I could feel the difference — especially on the heavier architecture planning prompts where Sonnet tends to reason a bit deeper and stay more consistent across a long context.

So if you’re planning something like this: either budget for API usage on top of your Pro subscription, or be strategic about when you use the big prompts. Save the architecture sessions for when you have the strongest model available. Don’t waste it on boilerplate.

Total cost was still a fraction of what any freelancer would charge for the same scope. But it wasn’t free — just worth being upfront about.

The takeaway

Factcovery wasn’t built by a developer who’s great at writing code. It was built by someone who knows how to work with AI intentionally.

The difference isn’t in the prompts or the tools. The difference is in the mindset: you are the product manager of your own project, and Claude is the best engineer you’ve ever worked with — as long as you brief them clearly enough.

If you’re curious about anything — the project structure, the exact prompts, the mistakes I didn’t write about — just leave a comment. I’ll answer everything. Building in public means sharing the messy parts too.

React Server Components Have a Free Data Fetching Model — No More useEffect Waterfalls

useEffect → fetch → loading spinner → another useEffect → another fetch → another spinner. React Server Components end this waterfall permanently.

What Are React Server Components?

RSCs run exclusively on the server. They can directly access databases, file systems, and APIs — then send the rendered HTML to the client. No loading spinners. No client-side fetch calls.

Why RSCs Change Everything

1. Direct Database Access in Components

// This component runs on the server — never ships to the browser
async function UserProfile({ userId }: { userId: string }) {
  const user = await db.users.findUnique({ where: { id: userId } });
  const posts = await db.posts.findMany({ where: { authorId: userId } });

  return (
    <div>
      <h1>{user.name}</h1>
      <p>{user.bio}</p>
      <PostList posts={posts} />
    </div>
  );
}

No API route. No useEffect. No loading state. The HTML arrives ready.

2. Zero Client-Side JavaScript

// Server Component — 0 KB shipped to browser
async function ProductCatalog() {
  const products = await db.products.findMany({
    where: { active: true },
    orderBy: { createdAt: 'desc' },
  });

  return (
    <div className="grid grid-cols-3 gap-4">
      {products.map(p => (
        <div key={p.id}>
          <img src={p.imageUrl} alt={p.name} />
          <h3>{p.name}</h3>
          <p>${p.price}</p>
        </div>
      ))}
    </div>
  );
}

This component could render 10,000 products and ship 0 bytes of JavaScript.

3. Mix Server and Client Components

// Server Component (default in Next.js App Router)
async function Dashboard() {
  const stats = await getStats();  // Server-side data fetch

  return (
    <div>
      <h1>Dashboard</h1>
      <StatsDisplay stats={stats} />          {/* Server — no JS */}
      <InteractiveChart data={stats.chart} />  {/* Client — has JS */}
      <RecentActivity items={stats.recent} />  {/* Server — no JS */}
    </div>
  );
}
// Client Component (opt-in with "use client")
"use client";
import { useState } from 'react';

function InteractiveChart({ data }) {
  const [timeRange, setTimeRange] = useState('7d');
  // ... interactive chart logic
}

4. Streaming and Suspense

async function Page() {
  return (
    <div>
      <Header />  {/* Renders immediately */}

      <Suspense fallback={<Skeleton />}>
        <SlowDataSection />  {/* Streams in when ready */}
      </Suspense>

      <Suspense fallback={<Skeleton />}>
        <AnotherSlowSection />  {/* Streams in independently */}
      </Suspense>

      <Footer />  {/* Renders immediately */}
    </div>
  );
}

5. Server Actions (Mutations)

async function CreatePost() {
  async function createPost(formData: FormData) {
    "use server";
    const title = formData.get('title') as string;
    const content = formData.get('content') as string;
    await db.posts.create({ data: { title, content } });
    revalidatePath('/posts');
    redirect('/posts');
  }

  return (
    <form action={createPost}>
      <input name="title" required />
      <textarea name="content" required />
      <button type="submit">Publish</button>
    </form>
  );
}

RSC vs Traditional React

Server Components Client Components
Runs on Server only Browser
JS shipped 0 KB Full component code
Data access Direct DB/fs/API Via fetch/API
Interactivity None (static HTML) Full (state, events)
Use for Data display, layout Forms, charts, modals

Getting Started

RSCs are built into Next.js App Router (13.4+):

npx create-next-app@latest --app
# All components are Server Components by default
# Add "use client" only when you need interactivity

The Bottom Line

Server Components eliminate the client-server waterfall. Fetch data where it lives (the server), render HTML, send it to the browser. Less JavaScript, faster pages, simpler code.

Need data tools? I build scraping solutions. Check my Apify actors or email [email protected].

# I Created a Pagination Challenge… And AI Missed the Real Problem

📄

Pagination looks simple.

Page → limit → slice → done.

That’s what I thought.

So I created a small challenge on VibeCode Arena.

And things got interesting.

🚨 The Problem

The logic works perfectly… on static data.

But real systems are not static.

Data keeps changing.

Users keep adding and removing items.

🧠 What Goes Wrong?

In real-world scenarios:

  • New data gets inserted
  • Old data gets deleted
  • Users refresh pages

And suddenly:

👉 You see duplicate data

👉 Or you miss some records

This is a very common production bug.

🤯 What I Observed

When AI models tried this:

  • Most gave basic slice-based logic
  • Some didn’t consider dynamic data
  • Very few suggested cursor-based pagination

The code works.

But the system is unreliable.

🔥 Try It Yourself

I created this challenge to test real-world API thinking.

👉 Try it here:
https://vibecodearena.ai/duel/b772342a-30ee-4d38-838c-c2c888dfffa7

Can you:

  • Prevent duplicate records?
  • Handle dynamic data?
  • Design a scalable pagination system?

💡 Final Thought

Pagination is not about slicing data.

It’s about making sure users see the right data at the right time.

Would you trust AI to design API-level logic like this?

Let’s discuss 👇

Upstash Has a Free Serverless Redis and Kafka — Pay Only Per Request

Traditional Redis costs $15/month minimum even when idle. Upstash Redis is serverless — you pay per command. 10K commands/day free.

What is Upstash?

Upstash provides serverless Redis, Kafka, QStash (message queue), and Vector — all with per-request pricing. Perfect for serverless apps where you can’t maintain persistent connections.

Why Upstash for Serverless

1. HTTP-Based Redis (No TCP Connections)

import { Redis } from '@upstash/redis';

const redis = new Redis({
  url: process.env.UPSTASH_REDIS_REST_URL,
  token: process.env.UPSTASH_REDIS_REST_TOKEN,
});

// Works in Vercel Edge, Cloudflare Workers, Deno Deploy
await redis.set('user:1', { name: 'Alice', role: 'admin' });
const user = await redis.get('user:1');

HTTP-based — no connection pooling needed. Works in every serverless runtime.

2. Rate Limiting (One Line)

import { Ratelimit } from '@upstash/ratelimit';
import { Redis } from '@upstash/redis';

const ratelimit = new Ratelimit({
  redis: Redis.fromEnv(),
  limiter: Ratelimit.slidingWindow(10, '10 s'),
});

// In your API handler
const { success, remaining } = await ratelimit.limit(userId);
if (!success) return new Response('Too many requests', { status: 429 });

3. QStash (Serverless Message Queue)

import { Client } from '@upstash/qstash';

const qstash = new Client({ token: process.env.QSTASH_TOKEN });

// Send message to your endpoint (with retries)
await qstash.publishJSON({
  url: 'https://myapp.com/api/process',
  body: { orderId: '123', action: 'fulfill' },
  retries: 3,
  delay: '10s',
});

// Schedule recurring tasks
await qstash.schedules.create({
  destination: 'https://myapp.com/api/cleanup',
  cron: '0 * * * *', // Hourly
});

4. Vector Database

import { Index } from '@upstash/vector';

const index = new Index({
  url: process.env.UPSTASH_VECTOR_REST_URL,
  token: process.env.UPSTASH_VECTOR_REST_TOKEN,
});

// Store embeddings
await index.upsert([
  { id: 'doc1', vector: embedding1, metadata: { title: 'React Guide' } },
  { id: 'doc2', vector: embedding2, metadata: { title: 'Vue Tutorial' } },
]);

// Semantic search
const results = await index.query({
  vector: queryEmbedding,
  topK: 5,
  includeMetadata: true,
});

5. Serverless Kafka

import { Kafka } from '@upstash/kafka';

const kafka = new Kafka({
  url: process.env.UPSTASH_KAFKA_REST_URL,
  username: process.env.UPSTASH_KAFKA_REST_USERNAME,
  password: process.env.UPSTASH_KAFKA_REST_PASSWORD,
});

const producer = kafka.producer();
await producer.produce('orders', JSON.stringify({ orderId: '123' }));

const consumer = kafka.consumer();
const messages = await consumer.consume({ consumerGroupId: 'group1', topic: 'orders' });

Free Tier

Service Free
Redis 10K commands/day
QStash 500 messages/day
Vector 10K queries/day
Kafka 10K messages/day

Upstash vs Traditional Redis/Kafka

Upstash Self-hosted Redis AWS ElastiCache
Connection HTTP (stateless) TCP (persistent) TCP (VPC only)
Pricing Per request Per hour Per hour
Cold cost $0 $15+/month $12+/month
Edge compatible Yes No No
Setup 30 seconds Manual 5+ minutes

Getting Started

npm install @upstash/redis @upstash/ratelimit @upstash/qstash

Sign up at upstash.com → create database → copy REST URL and token.

The Bottom Line

Upstash makes Redis, Kafka, and vector search serverless-native. HTTP-based, per-request pricing, and compatible with every edge runtime. If you’re building on Vercel or Cloudflare, Upstash is the missing piece.

Need data tools? I build scraping solutions. Check my Apify actors or email [email protected].

EdgeDB Has a Free Graph-Relational Database — SQL Power With Object Syntax

SQL is powerful but verbose. ORMs are convenient but limited. EdgeDB gives you a query language that feels like writing objects — with the power of PostgreSQL underneath.

What is EdgeDB?

EdgeDB is a database built on top of PostgreSQL that replaces SQL with EdgeQL — a modern query language that handles relationships, aggregations, and nested data naturally. It also auto-generates TypeScript types.

Why EdgeDB

1. EdgeQL vs SQL

-- SQL: Get users with their posts and comments count
SELECT u.id, u.name,
  (SELECT json_agg(json_build_object(
    'title', p.title,
    'comment_count', (SELECT COUNT(*) FROM comments c WHERE c.post_id = p.id)
  )) FROM posts p WHERE p.author_id = u.id) as posts
FROM users u WHERE u.name ILIKE '%alice%';
# EdgeQL: Same query
SELECT User {
  name,
  posts: {
    title,
    comment_count := count(.comments)
  }
} FILTER .name ILIKE '%alice%';

2. Schema as Code

# dbschema/default.esdl
module default {
  type User {
    required name: str;
    required email: str {
      constraint exclusive;
    };
    multi posts := .<author[IS Post];
    created_at: datetime {
      default := datetime_current();
    };
  }

  type Post {
    required title: str;
    required content: str;
    required author: User;
    multi comments: Comment;
    multi tags: str;
    published: bool {
      default := false;
    };
  }

  type Comment {
    required body: str;
    required author: User;
    created_at: datetime {
      default := datetime_current();
    };
  }
}

3. Auto-Generated TypeScript Client

npx @edgedb/generate edgeql-js
import e from './dbschema/edgeql-js';
import { createClient } from 'edgedb';

const client = createClient();

// Fully typed queries
const users = await e.select(e.User, (user) => ({
  name: true,
  email: true,
  posts: (post) => ({
    title: true,
    comment_count: e.count(post.comments),
    filter: e.op(post.published, '=', true),
  }),
  filter: e.op(user.name, 'ilike', '%alice%'),
})).run(client);

// users is typed as Array<{ name: string, email: string, posts: Array<{ title: string, comment_count: number }> }>

4. Built-in Auth

using extension auth;

module default {
  type User {
    required name: str;
    required identity: ext::auth::Identity;
  }
}

Email/password, OAuth, and magic links — built into the database.

5. Migrations

# Generate migration from schema changes
edgedb migration create

# Apply
edgedb migrate

# Squash migrations
edgedb migration squash

6. Built-in UI

edgedb ui
# Opens browser with:
# - Schema viewer
# - Data browser
# - Query editor with autocomplete
# - Migration history

EdgeDB vs PostgreSQL vs MongoDB

EdgeDB PostgreSQL MongoDB
Query language EdgeQL SQL MQL
Relationships First-class JOINs $lookup
Schema SDL (strict) DDL (strict) Schemaless
TypeScript types Auto-generated Manual / Prisma Manual
Nested queries Natural Subqueries/CTEs Aggregation pipeline
Auth Built-in Extension Atlas only
Migrations Auto-generated Manual N/A

Free Tier (EdgeDB Cloud)

Feature Free
Instances 1
Compute Shared
Storage 1GB
Bandwidth 5GB/month

Getting Started

# Install
curl --proto '=https' --tlsv1.2 -sSf https://sh.edgedb.com | sh

# Create project
edgedb project init

# Start UI
edgedb ui

The Bottom Line

EdgeDB makes PostgreSQL feel modern. EdgeQL is SQL without the pain, auto-generated TypeScript types eliminate manual mapping, and built-in auth saves weeks of development.

Need data tools? I build scraping solutions. Check my Apify actors or email [email protected].