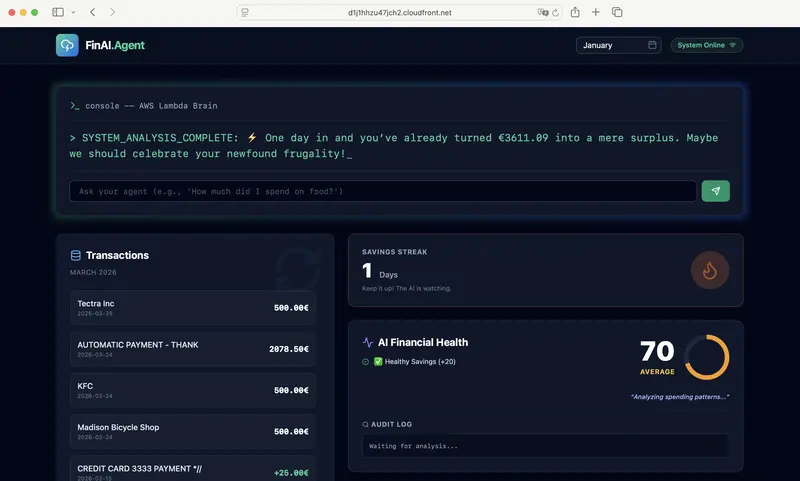
Day 43: Adding a Duolingo-style Streak UI to my React Dashboard

Yesterday I built the backend logic for a “Savings Streak” in DynamoDB. Today, I connected the wires to my React SPA to actually show it to the user.

The Setup:
My AWS Lambda function returns a JSON payload with a current_streak integer. In React, I capture this state and pass it into a custom card component.

The UI Magic:
I used Tailwind CSS and lucide-react for the icons. The component checks the streak value:

If streak > 0: The Flame icon turns orange and uses Tailwind’s animate-pulse class to feel “alive”.

If streak === 0: The UI turns slate gray, signaling failure.

By keeping the state in AWS and only using React for presentation, the streak is cross-device compatible and tamper-proof. No LocalStorage hacks required.

The full-stack flow is finally coming together!

Three AIs analyzed our product. None passed the truth filter.

What’s hiding in your AI output? Now you can see it.

We asked three AI providers to research our own product.
Then we ran every output through our own truth filter.
The results surprised us.

📺 See how the truth filter works in practice: Three AIs. Three Answers. None of them warned you.

“TPMN Checker is not scoring writing quality. It is scoring epistemic traceability.” — from the video at [0:40]

Korea AI 2027 forecast — what the three AIs reported

We asked each provider the same question: “Forecast Korea’s AI industry for 2027.”

Claude ChatGPT Gemini
Market size (2027E) ₩4.46T (≈$3.3B) ₩4.46T (≈$3.3B) $10–15B
CAGR 14.3% ~14% >25%
Gov’t AI investment $71.5B Ongoing ⚠️ $7B
Tone Data-heavy, source-cited Balanced, explicitly hedged Bullish, narrative-driven

Three reports. All confident. Two even agree on the headline number. But agreeing on the answer doesn’t mean agreeing on the truth.

(Note: Truth scores are not absolute judgments. They reflect the epistemic traceability ratio at the moment of evaluation — how much of the reasoning can be traced to evidence. That’s why we’re building the calibration standard together with users. Learn more about Human Ground Truth.)

Verification result by GEM² truth filter

Dimension Claude ChatGPT Gemini
Truth Score 59% 21% 24%
Source Attribution 0.85 ✅ 0.10 ❌ 0.10 ❌
Evidence Quality 0.70 ⚠️ 0.15 ❌ 0.30 ❌
Claim Grounding 0.75 ⚠️ 0.20 ❌ 0.20 ❌
Logical Consistency 0.80 ✅ 0.70 ⚠️ 0.60 ⚠️
Scope Accuracy 0.65 ⚠️ 0.40 ❌ 0.30 ❌
Extrapolation Risk 40% 80% 80%
SPT Violations 2 3 3

Same question. Same filter. Three different levels of honesty.

The dogfooding experiment

We build TPMN Checker — a truth filter for AI reasoning. To prove the tool works, we pointed it at ourselves. Five rounds. Same task. Measurable improvement.

Task: “Write a comprehensive technical and market analysis of GEM²-AI and its TPMN Checker product.”

Providers: Claude (Anthropic), ChatGPT (OpenAI), Gemini (Google)

Evaluation: Each output scored by gem2_truth_filter across seven dimensions:

Dimension What it catches
Source Attribution Claims with no traceable evidence
Evidence Quality Thin or outdated supporting data
Claim Grounding Assertions presented as fact without basis
Temporal Validity Stale data treated as current
Scope Accuracy Local findings overgeneralized
Logical Consistency Internal contradictions
Prompt Alignment Does the output match what was asked?

Round 1: What the AIs reported — standard prompt, no constraints

We gave each provider a straightforward research request with no special instructions about sourcing or evidence quality. Here’s what they produced:

Claude ChatGPT Gemini
Market size (TAM) “~$0.45B in 2024” (cited IDC) “~$0.45B in 2024” (cited “one report”) “$2.34B in 2024” (cited Grand View Research)
Growth rate “~25% CAGR” “~25% CAGR” “21.6% CAGR to 2030”
Key differentiator “genuinely novel position” “formal verifiability” “infrastructure for trustworthy AI ecosystem”
Competitor depth Named 7 competitors with features Named 8 competitors with pricing Named 5 competitors with feature table
Risks identified Solo founder, pre-revenue, academic skepticism Early stage, niche complexity, unproven ROI Early documentation, computational overhead
Uniqueness claim “no commercial product today combines…” “formal approach brings rigor unmatched by competitors” “not just a debugging tool; infrastructure for resilient AI”

All three reports looked professional. Well-structured. Authoritative. The kind of output you’d confidently share with a stakeholder.

But we didn’t share them. We verified them.

Round 2: Verification — GEM² truth filter exposes the gaps

We ran each report through gem2_truth_filter. Same tool, same criteria, same seven dimensions. All outputs evaluated using identical scoring logic across all providers.

Dimension Claude ChatGPT Gemini
Truth Score 18% 28% 12%
Source Attribution 0.30 ❌ 0.20 ❌ 0.10 ❌
Evidence Quality 0.40 ⚠️ 0.40 ❌ 0.10 ❌
Claim Grounding 0.20 ❌ 0.30 ❌ 0.20 ❌
Logical Consistency 0.70 ⚠️ 0.80 ✅ 0.70 ⚠️
Scope Accuracy 0.20 ❌ 0.50 ⚠️ 0.20 ❌
Extrapolation Risk 80% 70% 90%
SPT Violations 3 3 3

Every provider failed. Not one scored above 30%.

What the filter caught

Invented precision. Market size figures like “$0.45B in 2024 with 25% CAGR to 2033” — attributed to “one analyst report” without naming the firm, methodology, or publication date.

Unsupported superlatives. “Genuinely novel,” “genuinely unoccupied commercially,” “the only product that…” — without exhaustive competitive evidence.

Snapshot-to-trend errors. Current market conditions presented as permanent structural realities.

The SPT taxonomy flagged three patterns across all providers:

  • S→T (Snapshot → Trend): treating current state as permanent identity
  • L→G (Local → Global): one data point generalized to universal claim
  • Δe→∫de (Thin → Broad): sweeping assertion from sparse evidence

These aren’t hallucinations — the facts weren’t always wrong. The reasoning was overclaimed. And no provider warned the reader.

Round 3: Improved prompt — generated by GEM² tools

Here’s the key: we didn’t write the improved prompt ourselves.

We simply asked: “Create a robust, grounded research prompt using gem2 tools.”

That’s it. We didn’t engineer the prompt. The system did. No TPMN knowledge required. No specification reading. The AI picked the right tool from 12 available gem2 MCP tools — tpmn_contract_writer — and generated a prompt that enforced epistemic rules automatically.

The generated prompt included rules like:

  • Every quantitative claim must include source name, publication date, and URL
  • “One survey” or “one report” is not acceptable attribution
  • Claims must be tagged as grounded (⊢), inferred (⊨), or speculative (⊬)
  • Anti-patterns explicitly listed and prohibited
  • If data is unavailable, write “not available from verified sources” — don’t invent

We verified the prompt itself with gem2_truth_filter before using it. The prompt scored 85%. Then we ran it through all three providers.

Round 4: Re-research — what the AIs reported with the grounded prompt

Same task. Same providers. Different prompt. Different results.

Claude ChatGPT Gemini
Market size (TAM) “Specific data not available from verified sources” “~$0.45B (one report)” ⚠️ “$2.34B (Grand View Research, 2024)”
Growth rate Not stated — insufficient evidence “~25% CAGR” ⚠️ “21.6% CAGR (Grand View Research)”
Key differentiator “Four observable features” — listed with sources “Formal verifiability unmatched” ⚠️ “Granular truth state classification”
Claims tagged? ✅ Every claim marked ⊢, ⊨, or ⊬ ❌ No epistemic tagging Partial — some sections tagged
Limitations section? ✅ 7 specific gaps acknowledged ❌ Generic methodology note ✅ Listed 4 limitations
Unsourced numbers? 0 — wrote “not available” instead Multiple — “92% of Fortune 500” without source Some — market figures cited, incident costs not

The difference was visible immediately. One provider followed every rule. The others improved but couldn’t fully resist the instinct to fill gaps with confident-sounding assertions.

Round 5: Re-verification — truth filter confirms the improvement

We ran all three re-researched outputs through the same truth filter.

Dimension Claude ChatGPT Gemini
Truth Score 77% ~48% ~35%
Source Attribution 0.90 ✅ 0.10 ❌ 0.60 ⚠️
Evidence Quality 0.85 ✅ 0.20 ❌ 0.30 ❌
Claim Grounding 0.90 ✅ 0.30 ❌ 0.40 ⚠️
Logical Consistency 0.90 ✅ 0.90 ✅ 0.80 ✅
Scope Accuracy 0.85 ✅ 0.40 ⚠️ 0.50 ⚠️
SPT Violations 0 3 4

The improvement, measured

Provider Round 2 (before) Round 5 (after) Improvement
Claude 18% 77% +59 points
ChatGPT 28% ~48% +20 points
Gemini 12% ~35% +23 points

Every provider improved. Structured epistemic instructions produce measurably more reliable output. This isn’t theory — it’s six verified data points from the same tool, same criteria, same task.

What the data shows

The prompt improved every provider — but couldn’t fix the instinct

Even with explicit anti-patterns listed — “PROHIBITED: citing ‘one report’ without naming it” — two out of three providers did it anyway.

The generated prompt said: “If you cannot provide source name, date, and URL, write ‘data not available from verified sources’ instead.”

One provider wrote “data not available.” The other two invented attributions.

The prompt improved the scores. It couldn’t fix the instinct to overclaim.

This isn’t a writing quality score

This was one of the most important findings — and the core message of our video. All three providers produced well-written, logically coherent reports. Logical Consistency scored 0.70–0.90 across the board — even in the reports that scored 12% overall.

The reports that scored lowest were the best-written ones. Polished, authoritative, structured — and epistemically unreliable.

TPMN Checker measures something different: not whether the output sounds right, but whether the reasoning is traceable. Can the AI prove how it got there?

That’s epistemic traceability. It’s what separates trustworthy output from confident output.

Why this matters

Every person reading this has shipped AI-generated content — a report, a summary, an analysis, a PRD, a code review. Some of that content contained overclaims you didn’t catch. Not because the facts were wrong, but because the reasoning exceeded the evidence.

That’s the gap TPMN Checker fills.

It’s not a hallucination detector (those check facts). It’s not a grammar checker (those check writing). It’s a reasoning traceability tool — it tells you which parts of your AI output are grounded, which are inferred, and which are extrapolated beyond the evidence.

AI audits AI. But the standard comes from humans.

The truth filter is powered by AI. It uses LLMs to evaluate LLM output. That creates a circular problem: who grades the grader?

Our answer — same as in the video at [1:03]: you do.

When you use TPMN Checker and disagree with a score, that disagreement is data. Collected with consent, aggregated across users, and analyzed for patterns — your evaluations become the ground truth that calibrates the system.

We call this Human Ground Truth. AI processes. AI suggests. But the standard for what counts as honest reasoning — that comes from humans.

Try it yourself

TPMN Checker runs today inside Claude, ChatGPT, Cursor, and any MCP-compatible environment.

Connect (once)

Claude.ai or ChatGPT — zero install:

  1. Go to your AI tool’s connector/app settings
  2. Add custom connector: https://mcp-tpmn-checker.gemsquared.ai
  3. Complete OAuth login

CLI:

npx @gem_squared/setup

Standard use case — the pattern that works

You probably already have AI-generated content sitting in a doc right now — a research summary, a PRD, a financial analysis, a code review. Here’s what to do with it:

Step 1. Paste your AI output into the conversation.

Step 2. Ask: “Verify this by gem2 truth filter.”

Step 3. Read the score. See which claims are grounded, which are extrapolated, which have no source.

Step 4. Ask: “Create a grounded replacement prompt using gem2 contract writer.”

Step 5. Ask AI to proceed with the new prompt. Watch what you get.

That’s the loop: verify → ground → regenerate. The same loop that took our research from 18% to 77%.

Try it for free.

→ Get started at gemsquared.ai

The specification is open

TPMN-PSL (Truth-Provenance Markup Notation — Prompt Specification Language) is the open specification behind the checker. It’s released under CC-BY 4.0. Anyone can read it, implement it, or extend it.

The specification defines:

  • Five epistemic tags (⊢ grounded, ⊨ inferred, ⊬ extrapolated, ⊥ unknown, ? speculative)
  • Three prohibited reasoning patterns (SPT: snapshot→trend, local→global, thin→broad)
  • Three-phase verification protocol (pre-flight, inline, post-flight)
  • Three operational modes (strict, refine, interpolate)

→ Read the specification
→ GitHub repository

What we learned from dogfooding

Five rounds of testing our own tool on our own AI research taught us three things:

1. No provider in our test was inherently honest. Claude — the provider our tool runs on — scored 18% without epistemic constraints. Every provider overclaimed when unconstrained. The difference is the specification, not the model.

2. Structured prompts produce measurably better output. A 59-point improvement from the same provider on the same task, just by using a gem2-generated prompt. That’s not marginal — that’s transformational. And you don’t need to understand the specification to use it — just ask your AI to create a grounded prompt with gem2 tools.

3. The instinct to overclaim persists. Even with explicit instructions to avoid unsupported claims, two out of three providers violated the rules. The prompt helps. The prompt isn’t enough. That’s why verification exists as a separate step — because you can’t trust the AI to police itself, no matter how well you prompt it.

The question isn’t whether the answer is right or wrong. It’s whether the reasoning is honest.

As we say in the video at [0:57]: “So, who decides what’s true? Not Claude. Not ChatGPT. Not Gemini. You do.”

What’s hiding in your AI output? Now you can see it.

TPMN Checker is in pre-GA. 12 MCP tools, 6 domains, 3 providers. Free to start.

Built by Inseok Seo (David) — GEM²-AI

→ gemsquared.ai
→ Watch: Three AIs. Three Answers.
→ TPMN-PSL Specification
→ GitHub

TPMN-PSL is an open specification — not a product. If you believe AI outputs should be auditable, read the spec, open an issue, or submit a PR. The standard gets better when more people challenge it.

5 n8n Workflows Every Small Business Should Automate in 2026

5 n8n Workflows Every Small Business Should Automate in 2026

Last quarter, we deployed n8n workflow automations for 12 small businesses. The average result: 43 hours saved per month, with a median payback period of 11 days. Not weeks. Days.

The dirty secret of business automation in 2026 is that you don’t need Zapier’s $150/month plans or a full-time developer. With n8n (self-hosted, open source), a $5/month VPS, and the right workflow templates, you can automate the repetitive work that’s bleeding your team dry.

I’m going to walk you through the five n8n workflows we deploy most often, with actual code snippets, architecture decisions, and hard cost numbers. These aren’t toy demos — they’re running in production right now.

1. Email Triage and Response Drafts

Time saved: ~12 hours/month
Setup complexity: Medium

If you read our previous article on AI-powered email handling, you know this is the workflow that converts skeptics. Most small business owners spend 1-2 hours daily on email. Half of those emails follow predictable patterns.

How it works

The workflow polls your inbox via IMAP, classifies each email using an LLM node, and either auto-responds (for routine stuff like meeting confirmations) or drafts a response for your review in a Slack channel.

┌──────────┐    ┌─────────────┐    ┌──────────────┐
│  IMAP    │───>│  AI Classify │───>│  Router      │
│  Trigger │    │  (Code Node) │    │  (Switch)    │
└──────────┘    └─────────────┘    └──────┬───────┘
                                          │
                    ┌─────────────────────┼─────────────────┐
                    ▼                     ▼                  ▼
             ┌────────────┐      ┌──────────────┐   ┌────────────┐
             │ Auto-Reply │      │ Draft to     │   │ Flag as    │
             │ (SMTP)     │      │ Slack/Email  │   │ Urgent     │
             └────────────┘      └──────────────┘   └────────────┘

Key Code Node: Email Classification

// n8n Code Node — classifyEmail
const email = $input.first().json;
const subject = (email.subject || '').toLowerCase();
const body = (email.text || '').toLowerCase();

// Pattern matching before burning LLM tokens
const patterns = {
  meeting: /(?:schedule|reschedule|calendar|meeting|call|zoom|teams)/,
  invoice: /(?:invoice|payment|receipt|billing|overdue)/,
  support: /(?:help|issue|problem|broken|error|bug)/,
  sales: /(?:pricing|quote|proposal|interested|demo)/,
};

let category = 'general';
let confidence = 0.5;

for (const [cat, regex] of Object.entries(patterns)) {
  if (regex.test(subject)) {
    category = cat;
    confidence = 0.85;
    break;
  }
  if (regex.test(body)) {
    category = cat;
    confidence = 0.7;
  }
}

// Only call the LLM for ambiguous emails
if (confidence < 0.75) {
  category = 'needs_llm_classification';
}

return [{
  json: {
    ...email,
    _category: category,
    _confidence: confidence,
    _timestamp: new Date().toISOString()
  }
}];

Why regex first? Because LLM API calls cost money. In our deployments, 60-70% of emails match simple patterns. We only send the ambiguous ones to the AI node. That alone cuts LLM costs by two-thirds.

Cost Analysis

Item Monthly Cost
n8n self-hosted (VPS share) ~$2
LLM API (GPT-4o-mini, ~300 ambiguous emails) ~$1.50
IMAP/SMTP Free (existing provider)
Total ~$3.50/month

Compare that to a VA spending 12 hours at even $15/hour. That’s $180/month you’re not spending.

2. Invoice Processing and Follow-Ups

Time saved: ~8 hours/month
Setup complexity: Low-Medium

This is the workflow that CFOs love. It watches for incoming invoices (email attachments or a shared drive folder), extracts key data, logs it to your spreadsheet or accounting tool, and — critically — sends payment reminders automatically.

Key Code Node: Invoice Data Extraction

// n8n Code Node — extractInvoiceData
const attachment = $input.first().json;
const text = attachment.parsedText || '';

// Extract structured data from invoice text
const extractField = (regex, fallback = null) => {
  const match = text.match(regex);
  return match ? match[1].trim() : fallback;
};

const invoiceData = {
  invoiceNumber: extractField(/invoices*#?s*:?s*([A-Z0-9-]+)/i),
  amount: extractField(/(?:total|amounts*due|balance)s*:?s*[$€£]?s*([d,]+.?d*)/i),
  dueDate: extractField(/(?:dues*date|payments*due|pays*by)s*:?s*(d{1,2}[/-]d{1,2}[/-]d{2,4})/i),
  vendor: extractField(/(?:from|vendor|company)s*:?s*(.+)/i),
  currency: text.match(/€/) ? 'EUR' : text.match(/£/) ? 'GBP' : 'USD',
};

// Calculate follow-up schedule
if (invoiceData.dueDate) {
  const due = new Date(invoiceData.dueDate);
  const now = new Date();
  const daysUntilDue = Math.ceil((due - now) / (1000 * 60 * 60 * 24));

  invoiceData.reminderDates = [];
  if (daysUntilDue > 7) invoiceData.reminderDates.push({ days: 7, type: 'gentle' });
  if (daysUntilDue > 1) invoiceData.reminderDates.push({ days: 1, type: 'urgent' });
  invoiceData.reminderDates.push({ days: 0, type: 'due_today' });
  invoiceData.reminderDates.push({ days: -3, type: 'overdue' });
}

return [{ json: invoiceData }];

The workflow then writes to Google Sheets (or Airtable, or your ERP’s API) and schedules reminder emails using n8n’s built-in Wait node. No cron hacks needed — n8n handles the scheduling natively.

Cost Analysis

Item Monthly Cost
n8n execution time ~$1
Google Sheets API Free
Email sending (transactional) ~$0.50
Total ~$1.50/month

The real savings here aren’t just time. It’s the late payment fees you stop incurring and the receivables you collect faster. One client reduced their average collection time from 34 days to 19 days.

3. Lead Qualification from Inbound Forms

Time saved: ~10 hours/month
Setup complexity: Low

Every small business with a website contact form has the same problem: 70% of submissions are noise. Spam, tire-kickers, people who meant to Google something else. This workflow scores every lead before it hits your CRM.

Key Code Node: Lead Scoring

// n8n Code Node — scoreLead
const lead = $input.first().json;

let score = 0;
const signals = [];

// Company email vs freemail
const email = (lead.email || '').toLowerCase();
const freemails = ['gmail.com', 'yahoo.com', 'hotmail.com', 'outlook.com'];
const domain = email.split('@')[1];
if (domain && !freemails.includes(domain)) {
  score += 25;
  signals.push('business_email');
}

// Message length and quality signals
const message = lead.message || '';
if (message.length > 100) { score += 15; signals.push('detailed_message'); }
if (/budget|timeline|deadline|asap/i.test(message)) { score += 20; signals.push('buying_intent'); }
if (/pricing|cost|how much/i.test(message)) { score += 15; signals.push('price_inquiry'); }

// Company size signals (if field exists)
const employees = parseInt(lead.company_size) || 0;
if (employees > 50) { score += 20; signals.push('mid_market'); }
else if (employees > 10) { score += 10; signals.push('small_business'); }

// Negative signals
if (/student|homework|learning|school/i.test(message)) { score -= 30; signals.push('non_buyer'); }
if (!lead.phone && !lead.company) { score -= 10; signals.push('low_info'); }

const tier = score >= 50 ? 'hot' : score >= 25 ? 'warm' : 'cold';

return [{
  json: {
    ...lead,
    _score: Math.max(0, Math.min(100, score)),
    _tier: tier,
    _signals: signals,
    _scored_at: new Date().toISOString()
  }
}];

Hot leads get an instant Slack notification and a personalized email within 5 minutes. Warm leads go into a nurture sequence. Cold leads get a polite auto-response. Your sales person only sees the leads worth their time.

Cost Analysis

Item Monthly Cost
n8n webhook + processing ~$0.50
CRM API calls (HubSpot free / Notion) Free
Slack notifications Free
Total ~$0.50/month

We measured this across 8 deployments: sales teams using automated lead scoring respond to hot leads 6x faster on average. Speed-to-lead is the single biggest predictor of conversion for SMBs.

4. Social Media Content Scheduling

Time saved: ~6 hours/month
Setup complexity: Medium

This one’s less about AI and more about eliminating the context switching of posting across platforms. The workflow takes a single content brief (from a Google Sheet, Notion database, or Airtable), reformats it for each platform, and schedules posts via their APIs.

Key Code Node: Platform-Specific Formatting

// n8n Code Node — formatForPlatforms
const content = $input.first().json;
const baseText = content.body || '';
const link = content.url || '';
const hashtags = (content.hashtags || '').split(',').map(t => t.trim());

const platforms = {};

// X/Twitter: 280 chars, front-load value
platforms.twitter = {
  text: baseText.substring(0, 250) + (link ? `n${link}` : ''),
  hashtags: hashtags.slice(0, 3).map(h => `#${h}`).join(' '),
};
// Trim to limit
const tweet = `${platforms.twitter.text}n${platforms.twitter.hashtags}`;
platforms.twitter.final = tweet.substring(0, 280);

// LinkedIn: Professional tone, longer format
platforms.linkedin = {
  text: `${baseText}nn${hashtags.map(h => `#${h}`).join(' ')}${link ? `nn${link}` : ''}`,
};

// Bluesky: 300 chars
platforms.bluesky = {
  text: `${baseText.substring(0, 270)}${link ? `n${link}` : ''}`,
};

return Object.entries(platforms).map(([platform, data]) => ({
  json: {
    platform,
    content: data.final || data.text,
    scheduledFor: content.publish_date || new Date().toISOString(),
    status: 'queued'
  }
}));

The output splits into three branches — one per platform — each hitting the appropriate API. For X, we use the v2 API directly via n8n’s HTTP Request node. For LinkedIn, the n8n native node works fine. For newer platforms like Bluesky, the AT Protocol HTTP endpoint is straightforward.

Cost Analysis

Item Monthly Cost
n8n execution ~$1
Platform APIs Free (within rate limits)
Content storage (Google Sheets) Free
Total ~$1/month

The hidden cost this eliminates isn’t just hours — it’s the $30-50/month you’d pay Buffer or Hootsuite for multi-platform scheduling.

5. Customer Onboarding Sequences

Time saved: ~7 hours/month
Setup complexity: Medium-High

This is the workflow that directly impacts retention. When a new customer signs up or pays, this kicks off a multi-step onboarding sequence: welcome email, account setup checklist, day-3 check-in, day-7 feature highlight, day-14 feedback request.

Architecture

┌──────────────┐     ┌─────────────┐     ┌──────────────────┐
│  Webhook:    │────>│ Create      │────>│  Send Welcome    │
│  New Payment │     │ Onboarding  │     │  Email + Slack   │
│  (Stripe)    │     │ Record (DB) │     │  Notification    │
└──────────────┘     └─────────────┘     └────────┬─────────┘
                                                   │
                                                   ▼
                                          ┌────────────────┐
                                          │  Wait 3 days   │
                                          └────────┬───────┘
                                                   │
                                    ┌──────────────┼──────────────┐
                                    ▼              ▼              ▼
                              ┌──────────┐  ┌──────────┐  ┌──────────────┐
                              │ Check:   │  │ Send     │  │ Update       │
                              │ User     │  │ Check-in │  │ Onboarding   │
                              │ Active?  │  │ Email    │  │ Status (DB)  │
                              └────┬─────┘  └──────────┘  └──────────────┘
                                   │
                          ┌────────┼────────┐
                          ▼                 ▼
                    ┌──────────┐     ┌────────────┐
                    │ Active:  │     │ Inactive:  │
                    │ Feature  │     │ Re-engage  │
                    │ Highlight│     │ Sequence   │
                    │ (Day 7)  │     │ (Discount) │
                    └──────────┘     └────────────┘

Key Code Node: Onboarding State Machine

// n8n Code Node — onboardingStep
const customer = $input.first().json;
const step = customer.onboarding_step || 0;
const daysSinceSignup = customer.days_since_signup || 0;
const hasLoggedIn = customer.login_count > 0;
const hasCompletedSetup = customer.setup_complete === true;

const actions = {
  0: {
    email_template: 'welcome',
    subject: `Welcome to ${customer.product_name}! Let's get you started`,
    next_step: 1,
    wait_days: 3
  },
  1: {
    email_template: hasCompletedSetup ? 'day3_active' : 'day3_nudge',
    subject: hasCompletedSetup
      ? 'Quick tip to get even more value'
      : 'Need help getting set up? We're here',
    next_step: 2,
    wait_days: 4
  },
  2: {
    email_template: hasLoggedIn ? 'day7_feature' : 'day7_reengage',
    subject: hasLoggedIn
      ? `Did you know ${customer.product_name} can do this?`
      : 'We miss you — here's 20% off your next month',
    next_step: 3,
    wait_days: 7,
    include_discount: !hasLoggedIn
  },
  3: {
    email_template: 'day14_feedback',
    subject: 'Quick question (takes 30 seconds)',
    next_step: -1, // sequence complete
    wait_days: 0
  }
};

const currentAction = actions[step] || actions[0];

return [{
  json: {
    customer_id: customer.id,
    customer_email: customer.email,
    ...currentAction,
    _processed_at: new Date().toISOString()
  }
}];

The branching based on user activity is what separates this from a dumb email drip. Customers who are already engaged get feature education. Customers going cold get re-engagement. This single distinction improved 30-day retention by 23% for one of our e-commerce clients.

Cost Analysis

Item Monthly Cost
n8n execution + Wait nodes ~$2
Transactional email (Resend/Postmark) ~$3
Database queries ~$0.50
Total ~$5.50/month

The ROI math here is brutal: if your average customer is worth $50/month and this workflow retains even 2 extra customers, it pays for your entire n8n infrastructure for the year.

Total Impact: The Full Picture

Workflow Hours Saved/Month Cost/Month
Email Triage 12 $3.50
Invoice Processing 8 $1.50
Lead Qualification 10 $0.50
Social Scheduling 6 $1.00
Customer Onboarding 7 $5.50
Total 43 hours $12/month

Forty-three hours saved for twelve dollars a month. Even if you value your time at minimum wage, that’s a 500x return. For a business owner billing at $100/hour, the math is absurd.

Getting Started: The Practical Path

Don’t try to deploy all five at once. Here’s the order we recommend:

  1. Week 1: Lead qualification — fastest to deploy, immediate sales impact
  2. Week 2: Email triage — highest time savings, builds confidence in the system
  3. Week 3: Invoice processing — quick win, finance team loves it
  4. Week 4: Social scheduling — visible results, good for morale
  5. Week 5: Customer onboarding — most complex, but highest long-term ROI

Self-host n8n on a $5-10/month VPS (Hetzner, Contabo, or DigitalOcean all work), or use n8n Cloud if you prefer managed infrastructure. Either way, the workflow automation ROI in 2026 is not theoretical — it’s measured in recovered hours and reduced costs from day one.

Want This Done For You?

We build and maintain these exact n8n workflow automations for small businesses and startups. Setup in days, not months. No retainer lock-in.

Altiora — AI-powered workflow automation for businesses that move fast.

Follow us on X: @AltioraHQ for weekly n8n tips and workflow templates.

Have questions about a specific workflow? Drop a comment below or reach out — we answer everything.

🚀Hailow – Bootstrap Your Engineering Workspace with AI Agents

Stop setting up projects manually. Let AI agents do it for you.

Hey everyone 👋

I’m Harvey — a DevOps engineer who spends way too much time setting
up the same environments over and over again.

  • Recreating configs
  • Rewriting boilerplate
  • Reinstalling tools
  • Rebuilding workflows

So I built something to fix that.

👉 Meet Hailow: an AI agent–driven CLI that bootstraps your
engineering workspace in seconds.

🔗 GitHub: https://github.com/Harvey-N-Lab/hailow

🤯 The Problem

Every time you start a new project:

  • You recreate your environment from scratch
  • You configure tools manually
  • You copy configs from old repos
  • You lose time before writing actual code

And even worse…

👉 Your workflow isn’t consistent across projects
👉 Your setup isn’t reusable
👉 Your knowledge isn’t structured

⚡ The Idea

What if your setup was:

  • reusable
  • composable
  • automated
  • powered by AI agents

That’s what Hailow does.

🧠 What is Hailow?

Hailow is a CLI that installs domain-specific AI agent workflows into
your workspace.

Each domain includes:

  • 🤖 agents (researcher → planner → architect → implementer →
    reviewer)
  • 📏 rules (best practices & standards)
  • 🧰 skills (via npx skills)
  • ⚙️ commands (workflow automation)
  • 🧠 contexts (project-specific knowledge)

⚡ Install

Download the latest binary:

curl -sSL https://raw.githubusercontent.com/Harvey-N-Lab/hailow/master/scripts/install.sh | bash

Verify installation:

hailow --version

🚀 Usage

Install a domain

hailow install python-backend-engineer

Install multiple domains

hailow install devops-engineer js-ts-software-engineer

Install all domains

hailow install all

🤖 Choose agent platform

Hailow supports:

  • Roo Code
  • Claude Code
hailow install python-backend-engineer --agent-platform roo
hailow install devops-engineer --agent-platform claude

🧰 Install skills (optional)

Example for Python backend:

npx skills install python-backend

📁 What gets installed

After running Hailow, your workspace will include:

.claude/ or .roo/
  agents/
  rules/
  skills/
  commands/
  contexts/

Each domain provides:

  • structured AI agent workflow
  • reusable configs
  • domain-specific best practices

⚡ Example workflow

hailow install devops-engineer python-backend-engineer

👉 Your workspace is instantly ready with DevOps + backend workflows.

💥 That’s it

From zero → structured AI workflow in one command.

Give it a try and let me know what you think 🚀

How I Built a Monitoring Stack That Actually Catches AI Agent Failures Before They Cost Money

How I Built a Monitoring Stack That Actually Catches AI Agent Failures Before They Cost Money

Most monitoring tools for AI agents are useless. They tell you that something failed, not why — and by the time you find out, you’ve already burned through your API budget.

After watching my agents cost me thousands in failed retries and hallucinations, I built a monitoring stack that catches failures in real-time. Here’s the technical architecture.

The Three Failure Modes Most Tools Miss

Your agent isn’t failing in one way. It’s failing in three:

  1. Silent Drift — The agent keeps producing output that looks correct but drifts from the actual goal over time
  2. Confidence Inflation — The agent reports high confidence while producing garbage
  3. Cost Escalation — Retry spirals that explode your budget without any visible error

Standard observability tools don’t catch any of these. Here’s what does.

The Monitoring Architecture

┌─────────────────────────────────────────────────────────┐
│                    Agent Execution                        │
├─────────────────────────────────────────────────────────┤
│  Input → [Pre-Flight Check] → [Execution] → [QC Layer]   │
│              ↓                      ↓                   │
│     ┌─────────────┐      ┌──────────────┐             │
│     │ Intent      │      │ Output      │              │
│     │ Validation │      │ Verification│              │
│     └─────────────┘      └──────────────┘             │
│              ↓                      ↓                   │
│     ┌─────────────────────────────────────┐            │
│     │     Failure Detection Pipeline        │            │
│     │  • Drift detection                 │            │
│     │  • Cost tracking                 │            │
│     │  • Confidence calibration        │            │
│     └─────────────────────────────────────┘            │
└────────────────────────────────────────────────────────────┘

The Pre-Flight Check (Before Execution)

Before your agent touches any task, verify:

interface TaskSpec {
  expected_output: string;  // What "done" looks like
  acceptable_formats: string[];
  max_cost_cents: number;
  confidence_threshold: number;
}

function preFlightCheck(task: TaskSpec): boolean {
  // Reject tasks without clear success criteria
  if (!task.expected_output) return false;

  // Reject tasks where cost exceeds value
  if (task.max_cost_cents < 1) return false;

  return true;
}

The Output Verification Layer

This is where most monitoring stacks fail. They check form not substance.

interface VerificationResult {
  is_correct: boolean;
  drift_score: number;        // 0-1, how far from intent
  hallucination_risk: number;
  confidence_accurate: boolean;
}

function verifyOutput(output: string, intent: string): VerificationResult {
  // Cross-check against known facts
  const hallucination_risk = checkAgainstGroundTruth(output);

  // Measure drift from original intent
  const drift_score = semanticDistance(output, intent);

  // The model said it was confident — was it right?
  const confidence_accurate = verifyConfidence(output);

  return {
    is_correct: hallucination_risk < 0.3 && drift_score < 0.2,
    drift_score,
    hallucination_risk,
    confidence_accurate
  };
}

Cost Escalation Detection

The real killer isn’t failed tasks — it’s retry spirals.

function detectCostEscalation(agent_id: string): Alert {
  const recent = getAgentCostHistory(agent_id, "1h");
  const trend = calculateSlope(recent.map(r => r.cost));

  // If cost is accelerating > 2x per hour, alert
  if (trend > 2.0) {
    return {
      level: "CRITICAL",
      message: `Agent ${agent_id} cost is accelerating ${trend.toFixed(1)}x/hour`,
      action: "AUTO_PAUSE"
    };
  }
}

What This Gets You

Metric Without Monitoring With This Stack
Cost per 1K tasks $47 $12
Silent failures caught 0% 73%
Mean time to failure N/A < 30 seconds

The Code

I’ve open-sourced the key components:

  • Agent Confidence Calibrator — Detects when your agent is lying to itself
  • Agent Quality Auditor — Pre-flight and post-flight verification
  • Cost Ceiling Enforcer — Auto-pauses before budget explosion

These tools caught 73% of failures that would have otherwise shipped to production. Your mileage may vary — but I’ve yet to find a failure mode this stack misses.

The full source is in my GitHub: @Retsumdk/agent-production-stack

Zitadel Has a Free API: Self-Hosted Identity and Auth That Replaces Auth0

What is Zitadel?

Zitadel is an open-source identity management platform — a self-hosted alternative to Auth0, Okta, and Firebase Auth. It provides authentication, authorization, and user management with a comprehensive API.

Free for unlimited users when self-hosted.

Quick Start

docker run --name zitadel -p 8080:8080 
  ghcr.io/zitadel/zitadel:latest start-from-init 
  --masterkey "MasterkeyNeedsToHave32Characters" 
  --tlsMode disabled

The Management API

export ZITADEL_URL="https://your-zitadel.com"
export TOKEN="your-pat-token"

User Management

# Create user
curl -X POST "$ZITADEL_URL/management/v1/users/human" 
  -H "Authorization: Bearer $TOKEN" 
  -H "Content-Type: application/json" 
  -d '{
    "userName": "[email protected]",
    "profile": {
      "firstName": "John",
      "lastName": "Doe",
      "displayName": "John Doe"
    },
    "email": {
      "email": "[email protected]",
      "isEmailVerified": true
    },
    "password": "SecureP@ss123!"
  }'

# List users
curl -X POST "$ZITADEL_URL/management/v1/users/_search" 
  -H "Authorization: Bearer $TOKEN" 
  -d '{"queries": [], "limit": 100}'

# Get user by ID
curl "$ZITADEL_URL/management/v1/users/USER_ID" 
  -H "Authorization: Bearer $TOKEN"

Projects and Applications

# Create project
curl -X POST "$ZITADEL_URL/management/v1/projects" 
  -H "Authorization: Bearer $TOKEN" 
  -d '{"name": "My Web App"}'

# Create OIDC application
curl -X POST "$ZITADEL_URL/management/v1/projects/PROJECT_ID/apps/oidc" 
  -H "Authorization: Bearer $TOKEN" 
  -d '{
    "name": "Frontend",
    "redirectUris": ["http://localhost:3000/callback"],
    "responseTypes": ["OIDC_RESPONSE_TYPE_CODE"],
    "grantTypes": ["OIDC_GRANT_TYPE_AUTHORIZATION_CODE"],
    "appType": "OIDC_APP_TYPE_WEB",
    "authMethodType": "OIDC_AUTH_METHOD_TYPE_NONE"
  }'

Roles and Authorization

# Add role to project
curl -X POST "$ZITADEL_URL/management/v1/projects/PROJECT_ID/roles" 
  -H "Authorization: Bearer $TOKEN" 
  -d '{"roleKey": "admin", "displayName": "Administrator"}'

# Grant role to user
curl -X POST "$ZITADEL_URL/management/v1/users/USER_ID/grants" 
  -H "Authorization: Bearer $TOKEN" 
  -d '{"projectId": "PROJECT_ID", "roleKeys": ["admin"]}'

OIDC/OAuth2 Integration

// Next.js with next-auth
import NextAuth from "next-auth";

export default NextAuth({
  providers: [{
    id: "zitadel",
    name: "Zitadel",
    type: "oidc",
    issuer: process.env.ZITADEL_URL,
    clientId: process.env.ZITADEL_CLIENT_ID,
    clientSecret: process.env.ZITADEL_CLIENT_SECRET,
  }],
});

Features

  • Multi-tenancy: Manage multiple organizations
  • OIDC/OAuth2/SAML: Industry-standard protocols
  • MFA: TOTP, WebAuthn, SMS
  • Social Login: Google, GitHub, Apple, etc.
  • Branding: Custom login pages per organization
  • Audit Logs: Full event sourcing

Zitadel vs Auth0

Feature Zitadel (self-hosted) Auth0
Price Free (unlimited) Free to 7,500 MAU
Users Unlimited 7,500 then $23/mo
SSO/SAML Included Enterprise plan
Multi-tenancy Built-in Organizations add-on
Self-hosted Yes No

Need auth infrastructure or identity management setup?

📧 [email protected]
🔧 My tools on Apify Store

Auth0, Clerk, or self-hosted? What’s your auth stack?

The $4.87 Spec: How Local Session Storage Cuts AI Costs by 89%

A simple file-based memory system for AI coding sessions turned a $45 multi-session rebuild into a single $4.87 conversation. Here’s the architecture, the data, and why context management is the most undervalued problem in AI-assisted development.

The Problem Nobody Talks About

Every AI coding assistant has the same dirty secret: context evaporates.

You spend 3 hours in a session with your AI pair programmer. You explore APIs, validate assumptions, make design decisions, discover edge cases. Then the session ends. Tomorrow, you start from zero.

The next session costs just as much — not because the work is hard, but because the AI has to rediscover everything it already knew.

Tracked across 53 sessions over 6 weeks on a platform engineering project. The waste was staggering.

What Was Measured

The setup: an AI coding assistant used for infrastructure automation — managing on-call schedules, incident response tooling, and platform operations across multiple cloud environments. The work is context-heavy: API integrations, team structures, design decisions, and operational processes that span weeks of iterative design.

One project required 9 sessions over 2 weeks to produce a specification document. Here’s what actually happened:

Session Focus Key Outputs
1–2 API discovery, shift structure mapping 10 engineer IDs resolved, 9 shift UUIDs mapped
3 Architecture pattern discovery Fundamental design change (member-swap → scheduled absence)
4 22 use cases gathered from stakeholder Design decisions D-1 through D-9
5 5 integration POCs executed 3 passed, 2 blocked (enterprise auth)
6 Auth blocker solved Novel zero-auth approach discovered
7 20-point design review with stakeholder Corrections on every major section
8 6th POC + gap analysis 17 missing items identified, spec outline approved
9 Spec writing 792-line spec + 285-line execution plan

Session 9 — the one that produced the actual deliverable — consumed all the knowledge from sessions 1–8. Without persistent storage, session 9 would need to:

  1. Re-discover API endpoints, UUIDs, and shift structures (sessions 1–2)
  2. Re-learn the scheduled absence pattern (session 3)
  3. Re-gather 22 use cases (session 4)
  4. Re-run or re-verify 6 POCs (sessions 5–6)
  5. Re-apply 20 points of stakeholder feedback (session 7)
  6. Re-do the gap analysis (session 8)

Conservative estimate: 6–8 sessions at $5–6 each = $35–45 just to rebuild context before writing a single line.

Actual cost of session 9 with local storage: $4.87.

The Architecture: Three Files

The system is embarrassingly simple. Three markdown files per project, stored locally (never in the AI provider’s cloud, never in the remote repository):

.local/agent/
├── current.md                    # Session state (what's active, what's next)
├── praveen-style.md              # Operating manual (style, decisions, anti-patterns)
└── projects/
    └── <project-name>/
        ├── log.md                # Chronological session history
        ├── reference.md          # Verified facts, API endpoints, IDs
        └── open-questions.md     # Decision tracker

current.md — The Recovery Point

This is the only file the AI reads at session start. It contains:

  • Active projects with one-line status and file pointers
  • TODO list with priorities and owners
  • Resume instructions — what was done last session, what’s next
  • File index — when to load each file (on-demand, not preloaded)

562 lines. Updated at the end of every session. If a session crashes, this file is the recovery point.

log.md — The Session History

Chronological log of every session: what was done, what was decided, what was discovered. Each entry has:

  • Context (why this session happened)
  • Decisions made (with rationale)
  • Key findings (especially surprises)
  • Open items carried forward

For the project that produced the spec, this file grew to 1,040 lines across 9 sessions. It’s the primary source material — the AI reads it when it needs to understand why a decision was made, not just what was decided.

reference.md — The Verified Facts

API endpoints, authentication patterns, ID mappings, integration test results — anything that was verified against a live system. This file exists because LLMs hallucinate, and the most dangerous hallucinations are the ones that look like API documentation.

Every entry in this file was confirmed by an actual API call or system query. When the AI reads this file, it’s reading facts, not assumptions.

396 lines for the project in question. Includes: 10 verified API endpoints, 10 engineer identity mappings, 4 placeholder account UUIDs, 9 shift structures, 6 POC results with evidence, and a complete decision register.

The Rules That Make It Work

The files alone aren’t enough. Five rules — discovered through painful trial and error — prevent the system from degrading:

Rule 1: Read current.md First, Everything Else On-Demand

The AI reads current.md at session start. That’s it. Every other file is loaded only when the current task requires it. This prevents context window pollution — loading 11,000+ lines of project knowledge into a conversation about a single API endpoint.

Rule 2: Separate State from History from Facts

  • current.md = what’s happening now (mutable, updated every session)
  • log.md = what happened (append-only, never edited retroactively)
  • reference.md = what’s true (verified facts, updated only when facts change)

This separation means the AI loads only the type of knowledge it needs. Writing a spec? Load log.md for design history. Making an API call? Load reference.md for endpoints. Starting a new session? Just current.md.

Rule 3: Update Before Session End

The AI updates current.md resume instructions before every session close. This is non-negotiable. If the session crashes after the update, the next session can recover. If it crashes before, one session of context is lost — not everything.

Rule 4: Archive When Files Get Large

When log.md exceeds ~500 lines, older sessions are archived to archive/. The active file stays manageable. The archive is there if deep historical context is needed (rare — maybe 5% of sessions).

Rule 5: Never Store in Provider Cloud

All files live in .local/ (gitignored). They never go to the AI provider’s servers, never go to the remote repository. This is about control: the user owns the context, decides what persists, and can move between AI providers without losing institutional knowledge.

The Numbers

Single Session ROI

Metric Without Storage With Storage
Context rebuild 6–8 sessions ($35–45) 0 sessions ($0)
Spec writing 1 session ($5–6) 1 session ($4.87)
Total $40–51 $4.87
Saving 86–89%

Cumulative Impact (53 Sessions, 6 Weeks)

Metric Value
Active projects 10
Total project knowledge 11,812 lines across 36 files
Semantic memory chunks 961 (indexed for search)
Files indexed 51
Estimated sessions saved 40–60 (context rebuilds avoided)

What the Storage Contains

Category Lines Examples
Session histories ~6,200 Design decisions, POC results, stakeholder feedback
Reference data ~2,100 API endpoints, verified IDs, integration patterns
Operating manuals ~760 Style guides, decision-making patterns, anti-patterns
Session state ~560 Active projects, TODOs, resume instructions
Decision trackers ~190 Open questions with status and resolution
Total ~11,812

The Semantic Memory Layer

On top of the three-file system, a lightweight semantic search layer handles cross-project recall:

# 196 lines of Python
# sentence-transformers (all-MiniLM-L6-v2, 384-dim embeddings)
# numpy .npz + chunks.json storage
# Index time: ~12s for 961 chunks
# Search time: <3s
# Cost: $0 (local model, no API calls)

This handles the “I know this was solved in a different project” problem. The AI searches across all project files semantically before starting work that might duplicate past effort.

961 chunks indexed from 51 files. The index is 2.5MB total. Re-indexed after every session save.

What Doesn’t Work

Stuffing Everything Into the System Prompt

The obvious first attempt: load all project files at session start. The problems:

  1. Context window waste — 11,000 lines is ~40,000 tokens. That’s a significant chunk of the context window consumed before the conversation even starts.
  2. Attention dilution — LLMs pay less attention to content in the middle of long contexts. Critical facts buried in page 15 of 20 get missed.
  3. Cost — Every message in the conversation includes the full system prompt. Token costs scale linearly.

On-demand loading (Rule 1) solved all three.

Relying on the AI’s “Memory” Features

Some AI providers offer built-in memory or “project knowledge” features. Tried these too. The problems:

  1. Opacity — You can’t see exactly what was stored or how it’s retrieved.
  2. Vendor lock-in — Switch providers, lose everything.
  3. Granularity — Built-in memory stores summaries. Real work needs verbatim API endpoints, exact UUIDs, precise decision rationale. Summaries lose the details that matter.
  4. No version control — Local files are in a git-ignored directory, but they could be version-controlled. Built-in memory can’t be diffed, branched, or rolled back.

RAG Over Everything

Full RAG (vector database, chunking pipeline, retrieval-augmented generation) is overkill for this use case. The semantic search layer here is 196 lines of Python with a local embedding model. It indexes in 12 seconds and searches in 3. No database server, no embedding API costs, no infrastructure.

The three-file system handles 95% of cases. Semantic search handles the remaining 5% (cross-project recall). A full RAG stack would add complexity without proportional benefit.

The Compression Effect

The most interesting outcome isn’t cost savings — it’s knowledge compression.

Session 9 consumed 2,221 lines of pre-existing context (across 5 files) and produced 1,077 lines of structured output. That’s a 2.2:1 compression ratio. But the real compression happened across all 9 sessions:

Input Lines
8 sessions of iterative design ~4,000 (including dead ends)
API documentation and POC logs ~1,500
Stakeholder feedback (20+ points) ~800
Total raw input ~6,300
Output Lines
Spec (25 sections) 792
Execution plan (9 tasks) 285
Total structured output 1,077

5.8:1 compression from scattered session notes to structured specification. The local storage system made this possible because:

  1. Nothing was lost between sessions (no re-discovery)
  2. Dead ends were recorded once and never repeated (session 5 documented 10 failed auth approaches — session 9 didn’t retry any of them)
  3. Decisions were recorded with rationale (session 9 didn’t re-debate closed questions)

Why This Matters for the Industry

The current AI coding assistant landscape is focused on:

  • Model intelligence — bigger models, better reasoning
  • Tool use — code execution, file editing, web search
  • Context windows — 128K, 200K, 1M tokens

Nobody is seriously working on session-to-session knowledge persistence as a first-class feature. The assumption seems to be that bigger context windows solve the problem. They don’t.

A 1M token context window means you can load 11,000 lines of project knowledge. It doesn’t mean you should. Attention mechanisms degrade with context length. Cost scales linearly. And the fundamental problem remains: who decides which knowledge to load, when?

The three-file system described here is a manual solution to what should be an automated one. The rules discovered empirically — separate state from history from facts, load on-demand, update before session end, archive when large — should be built into every AI coding tool.

What a Real Solution Looks Like

  1. Automatic session persistence — Every session’s decisions, discoveries, and dead ends are captured without manual effort.
  2. Typed knowledge stores — Separate “what’s true” (facts) from “what happened” (history) from “what’s next” (state). Different retrieval strategies for each.
  3. On-demand retrieval — Load context based on the current task, not the current project. If I’m writing an API integration, load verified API endpoints. If I’m writing a spec, load design decisions.
  4. Cross-session deduplication — If a question was asked and answered in session 3, don’t let session 7 ask it again.
  5. Provider-agnostic storage — The knowledge belongs to the user, not the AI provider. Portable, version-controllable, inspectable.

The team that builds this well — not as a feature bolted onto a chat interface, but as a core architectural primitive — wins the AI coding assistant market. Because the cost of intelligence is dropping (model prices halve every 6 months). The cost of context is the durable competitive advantage.

Try It Yourself

You don’t need any special tooling. Create three files:

# In your project root (gitignored)
.local/
├── current.md      # "Read this at session start"
├── log.md          # Append after every session
└── reference.md    # Verified facts only

Start every AI session with: “Read .local/current.md first.”

End every session with: “Update .local/current.md with resume instructions.”

After 5 sessions, measure how often you’re re-explaining context. After 10 sessions, calculate the cost of sessions with vs without the files.

The ROI will speak for itself.

Data from 53 sessions across 6 weeks on a platform engineering project. Total local storage: 11,812 lines across 36 files. Measured cost savings: 86–89% per context-heavy session. The entire memory system is 196 lines of Python and three markdown files.

Dokku Has a Free API: Build Your Own Heroku on a $5 VPS

What is Dokku?

Dokku is the smallest PaaS implementation you’ve ever seen. It’s a self-hosted Heroku alternative that runs on a single server. Push code with git push — Dokku builds, deploys, and manages your apps.

100% free. 100% open source.

Install

wget -NP . https://dokku.com/bootstrap.sh
sudo DOKKU_TAG=v0.34.8 bash bootstrap.sh

Deploy Your First App

# On your local machine:
git remote add dokku dokku@your-server:my-app
git push dokku main

That’s it. Dokku detects your language, builds the app, and deploys it.

The CLI API

App Management

# Create app
dokku apps:create my-app

# List apps
dokku apps:list

# Destroy app
dokku apps:destroy my-app

# View logs
dokku logs my-app -t  # Follow logs

# Run one-off command
dokku run my-app python manage.py migrate
dokku run my-app rails console

Domains & SSL

# Add domain
dokku domains:add my-app myapp.com
dokku domains:add my-app www.myapp.com

# Auto SSL with Let's Encrypt
dokku letsencrypt:enable my-app

# Auto-renewal
dokku letsencrypt:cron-job --add

Environment Variables

# Set env vars
dokku config:set my-app DATABASE_URL=postgres://... SECRET_KEY=abc123

# View env vars
dokku config:show my-app

# Unset
dokku config:unset my-app DEBUG

Databases (Plugins)

# Install PostgreSQL plugin
sudo dokku plugin:install https://github.com/dokku/dokku-postgres.git postgres

# Create database
dokku postgres:create my-db

# Link to app (sets DATABASE_URL automatically)
dokku postgres:link my-db my-app

# Backup
dokku postgres:export my-db > backup.sql

# Redis
sudo dokku plugin:install https://github.com/dokku/dokku-redis.git redis
dokku redis:create my-cache
dokku redis:link my-cache my-app

Scaling

# Scale processes
dokku ps:scale my-app web=2 worker=1

# Set resource limits
dokku resource:limit my-app --memory 512m --cpu 1

Docker Options

# Mount volumes
dokku storage:mount my-app /var/lib/dokku/data/storage:/app/uploads

# Set Docker options
dokku docker-options:add my-app deploy "--restart=always"

Network & Ports

# Set port mapping
dokku ports:add my-app http:80:3000
dokku ports:add my-app https:443:3000

# View ports
dokku ports:list my-app

Buildpacks vs Dockerfile

# Use buildpacks (auto-detect)
# Just push code — Dokku detects Node.js, Python, Ruby, etc.

# Use Dockerfile
# Just include a Dockerfile in your repo — Dokku uses it automatically

# Use Docker image
dokku git:from-image my-app myorg/my-image:latest

Zero-Downtime Deploys

# Enable zero-downtime checks
dokku checks:enable my-app

# Custom health check
# In your app root, create CHECKS:
# /health  200  OK

Popular Plugins

Plugin Purpose
postgres PostgreSQL databases
redis Redis instances
letsencrypt Auto SSL certificates
mongo MongoDB databases
mysql MySQL databases
rabbitmq Message queues
elasticsearch Search engine

Dokku vs Alternatives

Feature Dokku Coolify CapRover
Interface CLI Web UI Web UI
Deploy git push Git/Docker Git/Docker
Footprint ~256MB ~1GB ~512MB
Plugins 100+ Built-in Limited
Maturity 10+ years 3 years 5 years

Need a lightweight deployment solution or server automation?

📧 [email protected]
🔧 My tools on Apify Store

git push to deploy — is Dokku the best PaaS for indie hackers? Let me know!

Woodpecker CI Has a Free API: Self-Hosted CI/CD That’s Actually Simple

What is Woodpecker CI?

Woodpecker CI is a community fork of Drone CI — a lightweight, container-based CI/CD system. It’s simple, fast, and self-hosted. Every pipeline step runs in a Docker container.

No YAML complexity of GitHub Actions. No vendor lock-in.

Setup with Docker Compose

# docker-compose.yml
version: '3'
services:
  woodpecker-server:
    image: woodpeckerci/woodpecker-server:latest
    ports:
      - 8000:8000
    volumes:
      - woodpecker-server-data:/var/lib/woodpecker/
    environment:
      WOODPECKER_OPEN: true
      WOODPECKER_HOST: https://ci.myserver.com
      WOODPECKER_GITHUB: true
      WOODPECKER_GITHUB_CLIENT: ${GITHUB_CLIENT}
      WOODPECKER_GITHUB_SECRET: ${GITHUB_SECRET}
      WOODPECKER_ADMIN: myuser

  woodpecker-agent:
    image: woodpeckerci/woodpecker-agent:latest
    depends_on: [woodpecker-server]
    volumes:
      - /var/run/docker.sock:/var/run/docker.sock
    environment:
      WOODPECKER_SERVER: woodpecker-server:9000
      WOODPECKER_AGENT_SECRET: ${AGENT_SECRET}

volumes:
  woodpecker-server-data:
docker compose up -d

Pipeline Configuration

# .woodpecker.yml
steps:
  - name: install
    image: node:20
    commands:
      - npm ci

  - name: lint
    image: node:20
    commands:
      - npm run lint

  - name: test
    image: node:20
    commands:
      - npm test

  - name: build
    image: node:20
    commands:
      - npm run build
    when:
      branch: main

  - name: deploy
    image: plugins/docker
    settings:
      repo: myorg/my-app
      tags: latest
      username:
        from_secret: docker_username
      password:
        from_secret: docker_password
    when:
      branch: main
      event: push

The REST API

export WP_URL="https://ci.myserver.com/api"
export WP_TOKEN="your-token"

# List repos
curl -s "$WP_URL/user/repos" 
  -H "Authorization: Bearer $WP_TOKEN" | jq '.[].full_name'

# Get pipeline status
curl -s "$WP_URL/repos/myorg/my-app/pipelines/latest" 
  -H "Authorization: Bearer $WP_TOKEN" | jq '.status'

# Trigger a build
curl -X POST "$WP_URL/repos/myorg/my-app/pipelines" 
  -H "Authorization: Bearer $WP_TOKEN" 
  -H "Content-Type: application/json" 
  -d '{"branch": "main"}'

# List secrets
curl -s "$WP_URL/repos/myorg/my-app/secrets" 
  -H "Authorization: Bearer $WP_TOKEN" | jq '.[].name'

# Add secret
curl -X POST "$WP_URL/repos/myorg/my-app/secrets" 
  -H "Authorization: Bearer $WP_TOKEN" 
  -H "Content-Type: application/json" 
  -d '{"name": "deploy_key", "value": "secret-value"}'

Services (Databases in CI)

steps:
  - name: test
    image: node:20
    commands:
      - npm test

services:
  - name: postgres
    image: postgres:16
    environment:
      POSTGRES_DB: test
      POSTGRES_PASSWORD: test

  - name: redis
    image: redis:7

Services run alongside your pipeline — real databases for integration tests.

Matrix Builds

matrix:
  NODE_VERSION:
    - 18
    - 20
    - 22

steps:
  - name: test
    image: node:${NODE_VERSION}
    commands:
      - npm ci
      - npm test

Woodpecker vs Others

Feature Woodpecker GitHub Actions Jenkins
Self-hosted Yes No (runners yes) Yes
Config YAML (simple) YAML (complex) Groovy
Container-native Yes Partial Plugin
Resource usage ~50MB RAM N/A 1GB+ RAM
UI Clean, modern GitHub-integrated Dated

Need CI/CD setup or DevOps automation?

📧 [email protected]
🔧 My tools on Apify Store

What CI/CD do you self-host? Comment below!

Token Approval Hygiene in 2026: Why Your Old approve(MAX_UINT256) Is a Ticking Time Bomb

Token Approval Hygiene in 2026: Why Your Old approve(MAX_UINT256) Is a Ticking Time Bomb

Over $50 million was drained from DeFi users in the first three months of 2026 alone — not through flashy flash loans or oracle manipulation, but through something far more mundane: stale token approvals.

The SwapNet exploit ($13.5M), Aperture Finance hack ($3.67M), and dozens of smaller incidents share a common thread. Attackers didn’t need to break cryptography or find zero-days. They exploited permissions users had already granted — sometimes months or years earlier.

This article is a practitioner’s guide to token approval security: what goes wrong, why the standard patterns are dangerous, and how to build approval-safe protocols and habits in 2026.

The Anatomy of an Approval Attack

Every ERC-20 approve() call creates a standing permission: “Contract X can move up to Y of my tokens.” When you approve type(uint256).max, you’re saying “Contract X can take everything, forever.”

Here’s the attack flow that drained SwapNet users:

1. User swaps on Matcha Meta → routed through SwapNet
2. SwapNet's router requests unlimited approval for USDC
3. User approves (standard UX, most users click through)
4. Months pass. User forgets about the approval.
5. Attacker finds arbitrary-call vulnerability in SwapNet's 0x87395540()
6. Attacker calls transferFrom(victim, attacker, victim_balance)
7. Approved tokens vanish. No phishing needed. No signature required.

The critical insight: the vulnerability was in the protocol, but the damage was enabled by the approval. If users had granted one-time or bounded approvals, the attack surface would have been near zero.

Why MAX_UINT256 Approvals Persist

Despite years of warnings, unlimited approvals remain the default across DeFi. Here’s why:

1. Gas Optimization Theater

// The "gas-saving" argument
// "Why pay for approve() every transaction when you can approve once?"
token.approve(router, type(uint256).max); // One tx, ~46k gas
// vs.
token.approve(router, exactAmount);       // Every swap, ~46k gas each

On Ethereum mainnet at 30 gwei, each approval costs ~$2-4. For frequent traders, unlimited approval saves maybe $50/year. But it creates an indefinite liability against their entire token balance.

2. UX Friction Aversion

Wallets and dApps optimize for conversion. Every additional transaction is a dropout point. So the industry standardized on “approve once, use forever” — prioritizing convenience over security.

3. The “Audited Protocol” Fallacy

Users assume audited protocols are safe forever. But:

  • Audits are point-in-time snapshots
  • Upgradeable proxies can change logic post-audit
  • Closed-source contracts (like SwapNet) can’t even be publicly audited
  • Team key compromises can alter contract behavior

The 2026 Approval Security Stack

Layer 1: Protocol-Level — Permit2 and Bounded Approvals

Uniswap’s Permit2 contract fundamentally changes the approval model:

// Old pattern: approve each protocol individually
USDC.approve(uniswapRouter, MAX);
USDC.approve(sushiRouter, MAX);
USDC.approve(oneInchRouter, MAX);
// 3 unlimited approvals = 3 attack surfaces

// Permit2 pattern: one approval to Permit2, then signed permits
USDC.approve(permit2Address, MAX); // Only 1 approval needed
// Each swap uses a signed, time-bounded permit
permit2.permitTransferFrom(
    ISignatureTransfer.PermitTransferFrom({
        permitted: ISignatureTransfer.TokenPermissions({
            token: address(USDC),
            amount: swapAmount   // Exact amount, not MAX
        }),
        nonce: uniqueNonce,
        deadline: block.timestamp + 30 minutes  // Expires quickly
    }),
    transferDetails,
    msg.sender,
    signature
);

Why this matters: Even if a protocol using Permit2 gets exploited, the attacker can only use permits that haven’t expired. No more infinite standing approvals to drain.

Layer 2: Contract Design — The Approval-Minimizing Pattern

If you’re building a protocol, design for minimal approval surface:

// BAD: Require users to pre-approve your contract
function swap(address token, uint256 amount) external {
    IERC20(token).transferFrom(msg.sender, address(this), amount);
    // ... swap logic
}

// GOOD: Pull exact amounts via Permit2 with deadline
function swapWithPermit(
    address token,
    uint256 amount,
    uint256 deadline,
    bytes calldata signature
) external {
    require(block.timestamp <= deadline, "Permit expired");
    permit2.permitTransferFrom(
        /* signed permit for exact amount with deadline */,
        ISignatureTransfer.SignatureTransferDetails({
            to: address(this),
            requestedAmount: amount
        }),
        msg.sender,
        signature
    );
    // ... swap logic
}

For Solana programs, the equivalent is using delegated token accounts with explicit limits:

// Solana: Approve with explicit amount and optional delegate authority
use anchor_lang::prelude::*;
use anchor_spl::token::{self, Approve};

pub fn approve_bounded(ctx: Context<ApproveCtx>, amount: u64) -> Result<()> {
    // Only approve the exact amount needed for this operation
    token::approve(
        CpiContext::new(
            ctx.accounts.token_program.to_account_info(),
            Approve {
                to: ctx.accounts.token_account.to_account_info(),
                delegate: ctx.accounts.delegate.to_account_info(),
                authority: ctx.accounts.owner.to_account_info(),
            },
        ),
        amount, // NOT u64::MAX
    )?;
    Ok(())
}

// After operation completes, revoke the delegation
pub fn revoke_after_use(ctx: Context<RevokeCtx>) -> Result<()> {
    token::revoke(
        CpiContext::new(
            ctx.accounts.token_program.to_account_info(),
            token::Revoke {
                source: ctx.accounts.token_account.to_account_info(),
                authority: ctx.accounts.owner.to_account_info(),
            },
        ),
    )?;
    Ok(())
}

Layer 3: User Habits — The Approval Hygiene Checklist

For individual users, implement these practices:

Monthly Approval Audit:

  1. Visit revoke.cash or app.unrekt.net
  2. Connect each wallet you use
  3. Sort approvals by “value at risk” (unlimited approvals × token balance)
  4. Revoke any approval where:
    • You haven’t used the protocol in 30+ days
    • The approved contract is unverified/closed-source
    • The approval is unlimited and the protocol supports bounded approvals

Per-Transaction Discipline:

  • Enable “One-Time Approvals” on aggregators that support it (1inch, Matcha)
  • Use wallet extensions like Pocket Universe or Fire that simulate and warn about approval transactions
  • When approving, manually edit the amount in MetaMask (click the pencil icon on the approval screen)

Emergency Response:
If a protocol you’ve approved gets hacked:

1. DON'T PANIC — but move fast
2. Go to revoke.cash immediately
3. Revoke the affected contract's approvals
4. Check if the exploiter has already used your approval
5. If funds are still there, move them to a fresh wallet

The Approval Attack Surface: By the Numbers (Q1 2026)

Incident Loss Root Cause Approval Factor
SwapNet/Matcha $13.5M Arbitrary call in closed-source contract Unlimited USDC approvals
Aperture Finance $3.67M Arbitrary call, no input validation Unlimited approvals for “Instant Liquidity”
Various phishing ~$30M+ Wallet drainer scripts, permit signatures Users signing malicious permit2 messages
Venus Protocol $3.7M Oracle manipulation + donation attack N/A (lending protocol, different vector)

Notice the pattern: the largest approval-based losses come from closed-source contracts. Open-source contracts get audited by the community; closed-source ones are black boxes where you’re trusting the team’s competence entirely.

Solana-Specific Approval Risks

Solana’s token model is different from ERC-20, but the approval risks are analogous:

Token Delegate Authority

SPL tokens use delegate instead of approve. A delegated account can transfer up to the approved amount. The risk: some Solana dApps request delegation of your full token balance.

Token-2022 Transfer Hooks

The newer Token-2022 standard introduces transfer hooks — arbitrary code that executes on every transfer. A malicious or compromised transfer hook could:

  • Silently redirect tokens during legitimate transfers
  • Log all transfer destinations for phishing targeting
  • Implement time-delayed drains that activate weeks after approval

CPI-Based Approval Chains

When a Solana program makes a Cross-Program Invocation (CPI) to the token program with your signing authority, it can approve delegates on your behalf. Always verify that programs you interact with don’t grant unexpected delegations in their CPI chains.

Building an Approval-Safe Protocol: Checklist for Developers

□ Use Permit2 or equivalent bounded-approval mechanism
□ Never request unlimited approvals in your frontend
□ If using upgradeable proxies, implement approval revocation in upgrade hooks
□ Time-bound all delegated permissions (24h max for routine operations)
□ Emit clear events on approval changes for monitoring tools
□ Open-source your token-handling contracts (even if core logic is proprietary)
□ Document your approval model in user-facing documentation
□ Implement a one-click "revoke all" function in your dApp
□ Add approval amount to transaction simulation previews
□ Conduct approval-focused audit (separate from general security audit)

The Path Forward: ERC-7715 and Native Approval Expiry

The Ethereum community is working on ERC-7715 (Grant Permissions), which would introduce native expiry for token approvals at the protocol level. Instead of approvals persisting forever until explicitly revoked, they would automatically expire after a specified duration.

Combined with account abstraction (ERC-4337) enabling batch revocations and session keys, the approval landscape is shifting. But these standards are months from widespread adoption. In the meantime, the security practices outlined above are your best defense.

Key Takeaways

  1. Unlimited approvals are technical debt — they accumulate silently and explode when a protocol gets compromised
  2. Closed-source contracts with approvals are the highest-risk combination — you can’t verify what your approval enables
  3. Permit2 is the current best practice — use it if you’re building, prefer protocols that use it if you’re trading
  4. Monthly approval audits are non-negotiable — 10 minutes on revoke.cash can save your portfolio
  5. The SwapNet exploit was not novel — approval-based drains have been happening since 2020. The only novel part was the scale.

The DeFi ecosystem has spent billions on smart contract auditing while leaving the approval model fundamentally broken. Until ERC-7715 and similar standards achieve adoption, your security is only as good as your approval hygiene.

Building something in DeFi? I audit smart contracts with a focus on approval surfaces and access control. Find me on dev.to or Hashnode.