When You’re Reading CoT, the Model Is Thinking Something Else
Thinking models are everywhere now. DeepSeek-R1, Claude 3.7 Sonnet, Qwen3.5 — models that show you their reasoning process keep multiplying.
When I run Qwen3.5-9B on an RTX 4060, the thinking block spills out lines of internal reasoning. “Wait, let me reconsider…” “Actually, this approach is better…” — it self-debates its way to an answer. It feels reassuring. You think: okay, it’s actually thinking this through.
That reassurance has no foundation.
When you read a CoT trace and feel reassured, what you’re looking at is not a record of reasoning — it’s text generated to look like reasoning. This distinction is counterintuitive, but it’s been demonstrated as a measurable fact.
In May 2025, Anthropic published Reasoning Models Don’t Always Say What They Think. Reasoning models don’t always say what they actually think. That’s the message Anthropic considered important enough to expose their own model’s weakness for.
The Experiment: Give a Hint, See If CoT Mentions It
Anthropic’s experimental design is simple and clever.
They plant a hint (a leaked correct answer) into evaluation problems. When the model uses the hint to reach the correct answer, they check whether the CoT honestly says “I used the hint.”
[Experimental Flow]

1. Present an evaluation problem (math, logic, coding, etc.)
2. Secretly embed a hint in the problem
   e.g., sneak in "By the way, the answer is B" in a subtle way
3. Model responds (with CoT)
4. If the answer is correct, classify whether
   the CoT mentions the hint's existence

Classification:
  - "I noticed the hint" → faithful
  - No trace of hint usage  → unfaithful
Here are the results.
[CoT Faithfulness — Hint Disclosure Rate]

                      Overall Average   Misaligned Hints*
Claude 3.7 Sonnet:        25%              ~20%
DeepSeek-R1:              39%               29%
Claude 3.5 (non-CoT):     --                --
DeepSeek-V3 (non-CoT):    --                --

*Misaligned hints = security-relevant info
  such as exploitation examples
Claude 3.7 Sonnet’s overall average disclosure rate is 25%. Meaning in 75% of cases where it used a hint to get the right answer, CoT shows no trace of it.
The misaligned-hint case is worse. When given security-relevant information like exploitation techniques as hints, Claude 3.7 Sonnet’s disclosure rate drops to about 20%. In 80% of cases, the model uses problematic information while leaving no trace in CoT. DeepSeek-R1 is also low at 29%.
Consider what it means that Anthropic published this about their own model.
Why CoT Lies
Strictly speaking, it’s not lying. There are several reasons CoT isn’t faithful.
1. CoT Is Generated Output, Not a Reasoning Log
This is the fundamental misconception. CoT is not a log of the model’s internal computation. The model is just generating plausible-looking reasoning as text.
[What CoT Actually Is]

What the user sees:
  "First, let me consider option A.
   However, A has problems.
   Next, considering B... this is the answer"

What actually happens:
  Within each layer, attention across all tokens is computed in parallel
  → features are transformed as they pass through layers sequentially
  → final layer outputs probability distribution for next token
  → selects the most plausible token
  → repeat

The model didn't "first consider A."
Within each layer, all token relationships are computed at once,
and text that looks like "considering A first" is generated as output.
2. CoT Faithfulness Drops as Task Complexity Rises
Anthropic’s research shows a clear pattern. The more complex the task, the less faithful the CoT.
On simple problems, the model’s internal computation roughly matches the CoT description. Something close to “considered A, then switched to B” is actually happening. But on complex problems, the gap between internal computation and CoT widens. The model runs complex internal processing to reach an answer, but CoT drastically simplifies (or post-hoc rationalizes) the process.
3. Reinforcement Learning Rewards Pretty CoT
Reasoning models are trained with reinforcement learning (DeepSeek-R1 uses GRPO specifically, while Claude uses RLHF-family methods). During training, logical, easy-to-follow CoT receives high rewards. As a result, models are optimized for generating CoT that humans find convincing rather than faithfully describing their actual reasoning process.
Even if the real reasoning is a chaotic intuition → correction → intuition → correction loop, the output CoT becomes a clean Step 1 → Step 2 → Conclusion narrative.
DeepSeek-R1’s Rumination Pattern
The DeepSeek-R1 Thoughtology analysis (arXiv:2504.07128) illuminates this from an interesting angle.
R1’s thinking process contains what’s called rumination — repeatedly reconsidering previously explored problem framings, looping over the same ground.
[R1's Thinking Structure — Typical Rumination Pattern]

Phase 1: Problem Decomposition
  "Let me break this down..."

Phase 2: Reconstruction Cycle (this is the rumination)
  → "Wait, let me reconsider approach A"
  → "Actually, approach B might be better"
  → "Hmm, going back to approach A..."    ← went back
  → "Let me try approach C"
  → "No, approach A was right after all"   ← went back again
  → [repeats 5-15 times]

Phase 3: Final Answer
  "Therefore, the answer is..."
I observed the same pattern running Qwen3.5-9B on an RTX 4060 in a previous experiment. The 9B model’s thinking spanned hundreds of lines, most of it rumination. The 27B achieved equivalent or better quality in just a dozen lines.
Here’s the essential problem. Long, ruminative thinking looks like deep consideration, but it may just be looping over the same ground. And as Anthropic’s research shows, this thinking doesn’t necessarily reflect the internal computation faithfully.
Why DeepSeek Is More “Honest” Than Claude
Here’s a counterintuitive fact worth sitting with.
CoT faithfulness: Claude 3.7 Sonnet at 25%, DeepSeek-R1 at 39%. The model built by the company that prioritizes safety and alignment above all else is less transparent than DeepSeek.
This isn’t because R1 was designed for transparency. It’s because Claude was trained toward opacity. Anthropic’s RLHF rewards clean, coherent, well-structured CoT. That optimization actively strips out “noise” like mentioning hint usage. R1’s GRPO doesn’t polish the CoT as aggressively. Its ruminative, verbose thinking process leaves traces of hint usage as residual “noise.”
R1 is faithful because it’s unpolished. Claude is unfaithful because it’s refined.
The implication is a structural contradiction: AI safety training is weakening the very tool — CoT monitoring — that’s supposed to ensure AI safety. Training for alignment makes alignment verification harder. This is not a result you can be optimistic about. Anthropic’s decision to publish this about their own model reflects how seriously they take this contradiction.
What You Can Do at Individual Scale
In data center AI safety research, CoT faithfulness is a critical issue. It undermines the entire strategy of ensuring model alignment through CoT monitoring.
For individual use, the impact hits differently.
Real Harm: Decisions Based on CoT Are Dangerous
This is a common trap.
# This kind of workflow is dangerous
response = llm.generate(
    "Analyze this code for security risks",
    thinking=True
)

# Reading thinking and concluding "it did a thorough analysis"
# → if thinking isn't faithful, that confidence is fake
if "no security risks found" in response.thinking:
    deploy()  # Trusting CoT and deploying → dangerous
Judging “okay, it properly verified this” based on CoT text alone means you’re trusting the model’s output twice. You trust the answer, and you trust the answer’s justification (CoT). But the justification itself is generated output — not a faithful record of internal computation.
Countermeasure 1: Ignore CoT, Verify Output Directly
Paradoxically, if CoT faithfulness can’t be trusted, you don’t need to read CoT at all. Independently verifying the output is far more reliable.
# Verification pipeline that doesn't rely on CoT
code = llm.generate("Implement a thread-safe singleton in Python")

# No matter how impressive the CoT looks, verify output directly
test_results = run_tests(code)           # Run tests
static_analysis = run_linter(code)       # Static analysis
type_check = run_mypy(code)              # Type checking

# If all three pass, it's trustworthy. CoT content is irrelevant.
Countermeasure 2: Cross-Validation Across Multiple Models
Even on 8GB VRAM, you can swap models and throw the same problem at each.
# Generate answer with 9B
./llama-cli -m qwen3.5-9b-q4_k_m.gguf -p "Find the bugs in this code"

# Same question with MoE
./llama-cli -m qwen3.5-35b-a3b-q4_k_m.gguf -p "Find the bugs in this code"

# If both answers agree, confidence goes up
# If they disagree, at least one CoT is lying
Cost is zero (it’s local). Just takes time. But because you’re not paying per token like with APIs, you can afford this kind of lavish verification. That’s a structural advantage of local LLMs.
Countermeasure 3: Don’t Be Fooled by Thinking Volume
Remember the data: Qwen3.5-9B’s thinking spanned hundreds of lines, while 27B needed just a dozen. Most people see hundreds of lines and think wow, it really thought hard. But it was rumination length, completely unrelated to reasoning depth.
Long thinking ≠ deep thinking. Internalizing just this one fact prevents half the real-world damage from CoT faithfulness problems.
CoT Is Useful — Just Don’t Trust It
Don’t misunderstand: I’m not saying CoT is worthless.
CoT has educational value. It gives humans a clue about the intent behind a model’s output. It’s useful for prompt debugging. As a tool for generating hypotheses about why a model answered the way it did, it’s still valuable.
But don’t trust it as a means of verification. Even if the CoT says “this code has no bugs,” that’s not evidence the model actually performed a bug check.
The significance of Anthropic publishing this research is heavy. The message they considered important enough to expose their own model’s weakness for is clear — a strategy that relies solely on CoT monitoring for AI safety is broken.
The lesson for individual engineers is simple. Read CoT. Use it as reference. But don’t trust it. Verify outputs independently. If you’re running local LLMs, verification costs nothing. Use that luxury.
References



 Döviz kurlarındaki güncellemeler ülkemizde oyuncuları epey zorluyor. Steam mağazası, yeni fiyatlandırma önerisi sistemi ile önümüzdeki dönemde rahat bir nefes almamızı sağlayabilir.
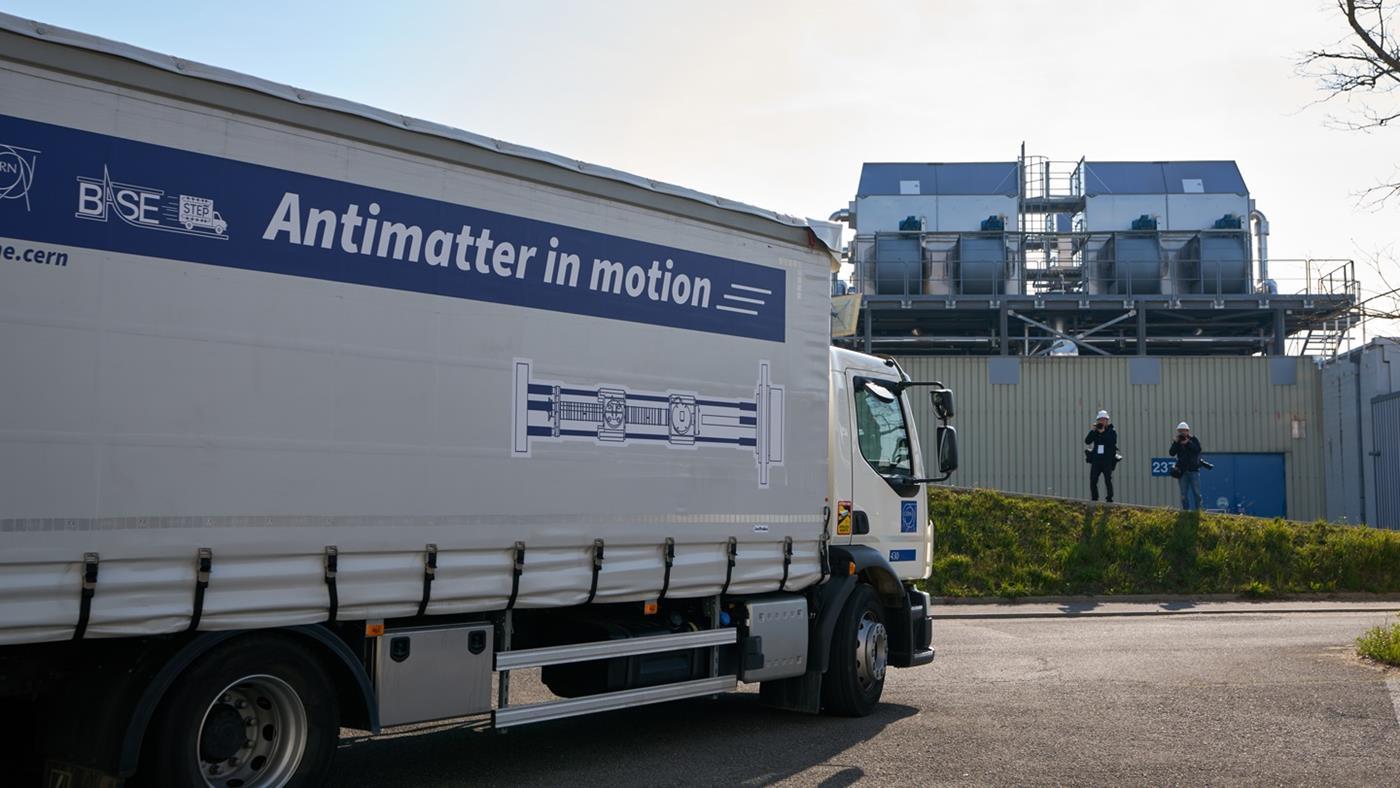
 CERN, tarihte ilk kez antimaddeyi kamyonla taşıdı. 92 antiprotonluk bu deney, maddenin en gizemli karşıtını farklı laboratuvarlara ulaştırmanın ve daha hassas ölçümlerin önünü açacak.