Mert
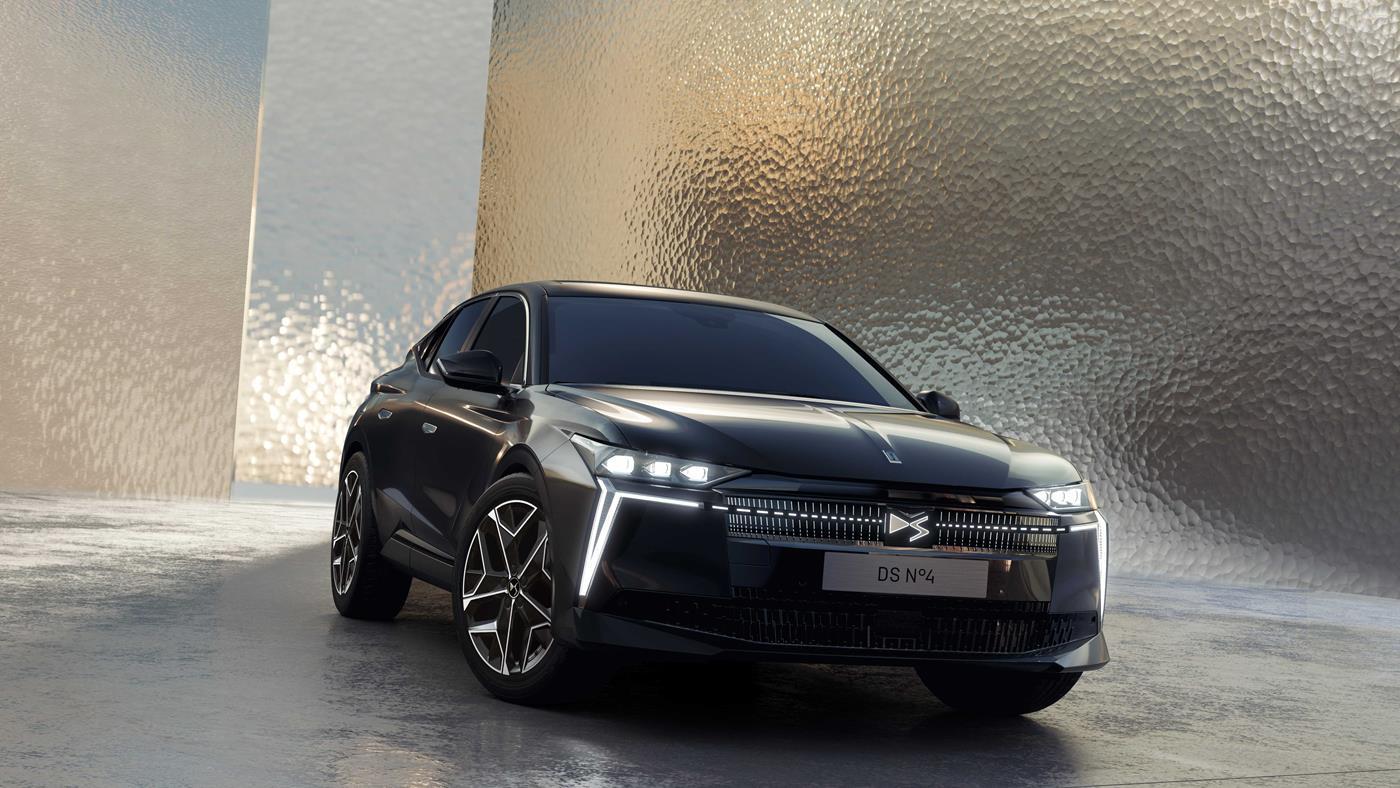
Yeni DS N°4 nisanda Tükiye’de satışa sunulacak
Türkiye’de “PALLAS” donanım seviyesiyle satışa sunulacak olan yeni DS N°4, BlueHDI 130 dizel motor ve 8 ileri tam otomatik şanzıman kombinasyonuyla tercih edilebilecek.No Assumptions on Architecture Without Load Testing
Recently, a client asked how effective the proposed conceptual solution architecture was.
We approached this question primarily from the perspective of load endurance. A reasonably confident answer can only be given after conducting load testing. For this, the following prerequisites are needed:
- Representative data population in databases and data buses to simulate a real system.
- Load indicators that the system should be able to withstand.
- System usage scenarios to develop a load profile that closely mirrors real-world conditions.
- Minimal infrastructure setup for testing, including computing power, key services, and load testing tools.
Additionally, a qualified specialist is required to:
- Define pass/fail criteria.
- Configure tools like Gatling, Yandex Tank, or JMeter.
- Analyze the results.
It’s crucial for the client to provide both:
- Functional requirements, such as data access scenarios.
- Non-functional requirements, such as target load indicators.
Only after successful load testing can we conclude that the solution architecture is capable of handling the required load.
However, evaluating architecture doesn’t stop there. The quality of the solution also depends on other critical factors, including:
- Scalability
- Maintainability
- Graceful degradation
- Other characteristics that require thorough analysis.
ArchitectureQuality #LoadTesting #SoftwareArchitecture
Originally published: No Assumptions on Architecture Without Load Testing — Alex Rezvov’s Blog
I Stopped Reading Diffs. Here’s What I Review Instead.
AI coding tools made me 3x faster at writing code. But I’m not shipping 3x faster. I spend more time than ever waiting for reviews and handling review feedback. The bottleneck moved.
This is the second article in a series about how I use Claude Code. The first covered persistent execution plans and external memory.
Code Review tools handle the automated side well. Claude Code’s built-in review dispatches multiple agents to catch bugs and flag style issues when a PR opens. That’s useful, but it’s not where the time goes. The time goes to the human review cycle: giving thoughtful feedback on a colleague’s design decisions, responding to comments on your own PR, the back-and-forth that turns a draft into something mergeable. Some of that is pure wait time: a PR sits idle while reviewers are busy. The skills in this article speed up the other part, what happens when you actually sit down to review or respond.
The answer isn’t to review faster. It’s to change what you’re reviewing. Instead of reading diffs line by line, I review Claude’s assessment of the changes in context of the full codebase. I focus on whether the analysis is right, whether it missed something, and whether the design makes sense. Two custom Claude Code skills handle the mechanics, one for each side of the review cycle.
Reviewing others’ PRs
I run /gh-review-pr owner/repo#123. Claude checks out the PR branch, reads the diff with full codebase access (it can follow imports, check how changed functions are used, and understand how the PR fits into the larger architecture), and presents findings grouped by severity:
Must fix
- src/api/handlers.go:47: Missing auth check on the new endpoint.
All existing endpoints use requireAuth middleware.
Should fix
- src/api/handlers.go:62: Similar pagination logic exists in listUsers.
Consider extracting a shared helper.
Nit
- Test name on line 15 could be more descriptive.
Praise
- Clean error handling throughout. The custom error types are well done.
The most useful thing the skill does is search the repo and the broader GitHub org for prior art before forming its review. If someone adds a caching layer, it checks whether there’s already an established pattern elsewhere in the org. This catches the “we already have a way to do this” issues that are invisible from a diff alone, and it’s the biggest gap in existing review tools, including the built-in ones.
That cross-repo context is what makes reviewing at a higher level possible. I’m not scanning the diff for problems. I’m reading a structured assessment and deciding whether the analysis is right, whether it missed anything, and which findings are worth posting.
A few other details that compound over time. If I’m the PR author (self-review before requesting others), the skill detects that and keeps findings in the conversation instead of posting comments on the PR. If I’ve already reviewed and the author pushed fixes, it focuses on what changed since my last review rather than re-reviewing everything. I confirm which comments to post and what review action to take. Claude submits them as a single batched review.
Responding to review feedback
The other side of the bottleneck. Someone reviewed my PR and left comments. Before this skill, handling that meant reading each comment, context-switching to the code, making the fix, writing a reply, going back to GitHub to resolve the thread, then doing it again for the next comment.
Now I run /gh-review-respond. Claude reads all unresolved threads and presents them in three categories:
Fix needed (2)
- @sarah: "Missing null check on line 34" → add guard clause
- @sarah: "This query needs an index" → add database index
Discussion (1)
- @sarah: "Why not use the existing UserService here?"
Disagree (1)
- @sarah: "This should be a separate microservice"
The categorization is the key step. I review Claude’s assessment: yes, fix those two, they’re real issues. The UserService question needs context, so I explain my reasoning and Claude drafts the reply. For the microservice suggestion, I disagree. The current approach is simpler and we can extract later if the need becomes clear. Claude writes a response that acknowledges the concern and explains the tradeoff.
Getting the tone right on disagreements matters. A dismissive response can derail a productive review. The skill handles the diplomacy; I focus on the substance.
After I confirm, Claude applies the code fixes, replies to each comment on the PR, and resolves all addressed threads in a single batch. Then it commits. One detail that matters more than you’d expect: for human reviewers, it always creates a new commit so the reviewer can see exactly what changed. For bot reviewers (like Copilot), it squashes into existing commits since nobody needs those diffs.
The mechanics change. The judgment doesn’t.
These skills automate the mechanical parts of the review cycle: reading diffs in context, posting comments, resolving threads, choosing commit strategies. What they don’t automate is the judgment. Deciding that a missing auth check is a blocker but a naming suggestion isn’t. Recognizing when feedback improves the design vs. when it’s a preference. Knowing when to push back and how to frame it. The time I used to spend on mechanics, I now spend on those decisions.
In the first article in this series, I described the core pattern as “the edge is judgment, not config.” The same applies here. The skills handle the cycle. The decisions are still yours.
I’ve published both skills at claude-review-skills. If your review workflow is different, or you review in a domain with specific requirements (security, API compatibility, accessibility), Claude Code’s /skill-creator can build custom review skills from a description of your process.
I’ll cover more patterns in future posts.
EKS vs GKE vs AKS: A FinOps Cost Comparison in 2026
Choosing a managed Kubernetes platform is not just an engineering decision. It is a financial one. The three major providers each have different pricing models, different cost traps, and different optimization levers. Pick the wrong mental model, and you will spend 40% more than you need to.
This post walks through every major cost category: control plane fees, compute, egress, load balancers, storage, and observability. It closes with three real team archetypes and what each platform actually costs them per month.
The Control Plane Is Not Free (Except on AKS)
This is the most underestimated line item in managed Kubernetes. EKS and GKE both charge $0.10 per cluster per hour for the control plane. That is $73 per cluster per month, before a single pod runs.
AKS charges nothing for the control plane. Microsoft absorbs that cost entirely.
At one cluster, the difference is easy to dismiss. At five clusters, the math becomes harder to ignore.
| Platform | Control Plane / Cluster / Month | 5 Clusters / Month | 10 Clusters / Month |
|---|---|---|---|
| EKS | $73 | $365 | $730 |
| GKE | $73 | $365 | $730 |
| AKS | $0 | $0 | $0 |
Teams that follow the “one cluster per environment” pattern end up with dev, staging, QA, and production clusters per team. A 10-team engineering org can easily reach 40 clusters. On EKS or GKE, that is $2,920/month in control plane fees alone. On AKS, that is $0.
This does not mean AKS is cheaper overall. But if you are running many small clusters at low utilization, AKS’s pricing model has a structural advantage that compounds at scale.
The counter-argument: EKS and GKE provide more mature networking primitives and more granular RBAC out of the box. You get what you pay for in operational capability. The question is whether your team actually uses those capabilities at the scale you are paying for.
Compute Costs: Node Pools, Spot, and the Autopilot Question
Node compute is the largest line item for most teams. Each provider offers on-demand, reserved, and spot/preemptible pricing, plus at least one serverless Kubernetes model.
Standard Node Pricing
For an m5.xlarge equivalent (4 vCPU, 16GB RAM), here is what each provider charges:
| Instance Type | On-Demand / Hour | Reserved 1yr No-Upfront / Hour | Spot / Hour (approx) |
|---|---|---|---|
| AWS m5.xlarge | $0.192 | $0.122 (36% off) | $0.058 (70% off) |
| GCP n2-standard-4 | $0.194 | $0.130 (33% off, 1yr CUD) | $0.019-0.058 (up to 91% off) |
| Azure D4s v5 | $0.192 | $0.115 (40% off, 1yr) | $0.058 (70% off) |
On-demand pricing is nearly identical across all three platforms for general-purpose instances. The gap opens in discount depth and discount mechanics.
AWS Reserved Instances require commitment upfront or monthly. GCP Committed Use Discounts (CUDs) apply automatically after purchase with no instance-type lock-in at the resource level. Azure Reserved VMs are straightforward but require matching the right VM series.
GCP Spot VMs offer the deepest discounts, up to 91% for some instance types. They are also the most aggressive about preemption. For CI/CD runners and batch jobs that tolerate interruption, this is a significant advantage. For stateful workloads, it breaks things in ways that take hours to debug.
GKE Autopilot: Per-Pod Billing
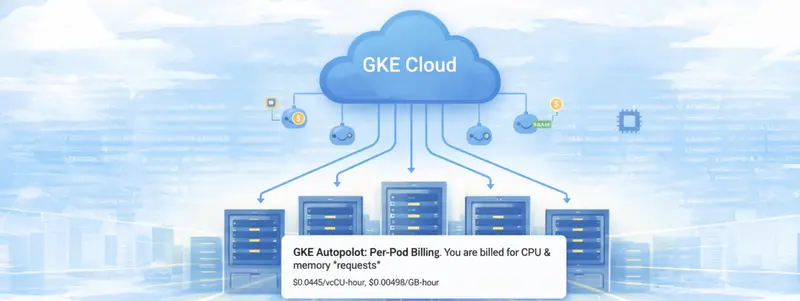
GKE Autopilot removes node management entirely. You declare pods; GKE provisions and manages the underlying nodes. You are billed for the CPU and memory your pods request, not the node capacity provisioned.
Autopilot pricing: $0.0445/vCPU-hour and $0.00498/GB-hour for pod requests.
For bursty workloads where average utilization is below 60%, Autopilot wins because you stop paying for headroom that sits idle. For workloads running at 80%+ utilization consistently, Standard mode with CUDs beats Autopilot by 20-35%.
EKS Fargate is the AWS equivalent. It charges $0.04048/vCPU-hour and $0.004445/GB-hour. That is roughly similar to GKE Autopilot but without Autopilot’s node scheduling intelligence. Fargate works well for isolated jobs. For full cluster workloads, it is expensive.
AKS has no equivalent serverless mode. You manage node pools. You can use Azure Container Instances via virtual nodes for burst capacity, but this is not the same as a fully managed scheduling layer.
The Egress Tax: Where Multi-Cloud Architectures Bleed
Egress pricing is where cloud cost models diverge most sharply from engineering intuition. Outbound data is not free, and microservice architectures generate a lot of it.
| Traffic Type | AWS | GCP | Azure |
|---|---|---|---|
| Internet egress (first 10TB/mo) | $0.09/GB | $0.08/GB | $0.087/GB |
| Inter-region egress | $0.02/GB | $0.08/GB | $0.02/GB |
| Inter-AZ/zone egress | $0.01/GB | $0.01/GB | Free |
| Same-AZ traffic | Free | Free | Free |
Azure’s free inter-availability-zone traffic is a genuine advantage for multi-AZ Kubernetes deployments. On AWS, spreading pods across three AZs for redundancy generates $0.01/GB per cross-AZ call. For a service mesh with 1TB/month of inter-pod traffic, that is $10/month. At 10TB, it is $100/month. This appears nowhere in initial capacity planning.
GCP inter-region egress is the most expensive at $0.08/GB. If your architecture spans multiple GCP regions (for latency or compliance), inter-region service calls add up fast. AWS and Azure inter-region egress at $0.02/GB is substantially cheaper for cross-region patterns.
The practical implication: if your workload is heavily cross-zone or cross-region, model egress costs explicitly before choosing a provider. For primarily same-zone traffic with internet egress, all three providers are within 10% of each other.
Hidden Multipliers: Load Balancers, Storage, and Observability
Load Balancers
Every production Kubernetes cluster needs at least one load balancer. The costs differ materially.
| Load Balancer Type | Base Cost / Hour | Variable Cost |
|---|---|---|
| AWS ALB (EKS) | $0.0225 | $0.008/LCU-hour (connections + bandwidth) |
| AWS NLB (EKS) | $0.0225 | $0.006/LCU-hour |
| GKE Regional Load Balancer | $0.025 | $0.008/GB processed |
| AKS Standard Load Balancer | $0.025 | $0.005/GB processed, free rules |
AWS ALB LCU pricing is opaque. LCUs are calculated from new connections per second, active connections, processed bytes, and rule evaluations. A medium-traffic API gateway can accumulate 3-5 LCUs, adding $17-35/month on top of the base $16/month. Teams often underestimate this by 2x.
AKS Standard Load Balancer has no per-rule fee, which benefits teams with complex routing rules. GKE Regional Load Balancers charge per GB processed, which is predictable but punishes high-throughput workloads.
Storage
Persistent volume costs are roughly equivalent across platforms. All three providers have SSD-backed block storage at around $0.08-0.10/GB-month.
| Storage Type | Cost / GB / Month |
|---|---|
| AWS EBS gp3 | $0.08 |
| Azure Premium SSD (P10, 128GB) | $0.10 |
| GCP SSD Persistent Disk | $0.17 |
GCP SSD persistent disk is notably more expensive. A 100GB volume costs $17/month on GCP vs $8/month on AWS. For stateful workloads with large persistent volumes, this adds up to a meaningful difference across a cluster.
Observability
This is the category most teams discover after their first bill shock.
| Platform | Free Tier | Cost After Free Tier |
|---|---|---|
| AWS CloudWatch Logs | First 5GB/month free | $0.50/GB ingested |
| GCP Cloud Logging | First 50GiB/month free | $0.50/GiB ingested |
| Azure Monitor LA | First 5GB/workspace/month free | $2.76/GB ingested |
Azure Monitor Log Analytics is 5x more expensive per GB than AWS or GCP after the free tier. For verbose workloads, this makes Azure the most expensive observability platform by a wide margin. Teams commonly address this by shipping logs to a cheaper store (Loki, Elasticsearch) rather than using the native platform logging service.
Enabling full pod logging on a 50-node cluster with moderate verbosity generates 100-200GB/month of logs. At Azure Monitor rates, that is $276-552/month just for logs.
Total Cost Scenarios: Three Team Archetypes
Archetype 1: Early-Stage Startup (1 cluster, 10 nodes, moderate traffic)
| Cost Category | EKS | GKE | AKS |
|---|---|---|---|
| Control plane | $73 | $73 | $0 |
| Compute (10x m5.xl, on-demand) | $1,382 | $1,397 | $1,382 |
| Load balancer | $35 | $45 | $40 |
| Storage (500GB) | $40 | $85 | $50 |
| Observability (50GB) | $22 | $0 | $124 |
| Egress (5TB) | $450 | $400 | $435 |
| Total / Month | $2,002 | $2,000 | $2,031 |
At startup scale with a single cluster, costs are nearly identical. AKS saves $73 on control plane but pays more for observability.
Archetype 2: Mid-Scale Team (5 clusters, 50 nodes, high service mesh traffic)
| Cost Category | EKS | GKE | AKS |
|---|---|---|---|
| Control plane (5 clusters) | $365 | $365 | $0 |
| Compute (50x m5.xl, 1yr RI) | $4,392 | $4,680 | $4,140 |
| Load balancers (5) | $175 | $225 | $200 |
| Storage (2TB) | $160 | $340 | $200 |
| Observability (200GB) | $97 | $75 | $552 |
| Egress (20TB, 30% cross-zone) | $1,860 | $1,660 | $1,740 |
| Total / Month | $7,049 | $7,345 | $6,832 |
AKS leads at mid-scale because the $365 control plane saving and cheaper Azure Reserved VMs offset the higher observability cost. GKE falls behind due to more expensive persistent storage.
Archetype 3: Enterprise (20 clusters, 500 nodes, multi-region, full observability)
| Cost Category | EKS | GKE | AKS |
|---|---|---|---|
| Control plane (20 clusters) | $1,460 | $1,460 | $0 |
| Compute (500x m5.xl, 1yr RI) | $43,920 | $46,800 | $41,400 |
| Load balancers (20) | $700 | $900 | $800 |
| Storage (20TB) | $1,600 | $3,400 | $2,000 |
| Observability (2TB) | $972 | $750 | $5,522 |
| Egress (200TB, multi-region) | $18,600 | $18,400 | $17,400 |
| Total / Month | $67,252 | $71,710 | $67,122 |
At enterprise scale, EKS and AKS converge. AKS wins on control plane and compute but gets penalized heavily by Azure Monitor. Teams that replace Azure Monitor with a self-managed logging stack push AKS costs to ~$62,000/month, making it the clear winner.
GKE’s persistent storage costs and deeper spot preemption complexity make it the most expensive option at enterprise scale for stateful workloads.
Eliminating the Idle Tax Across All Three
None of the analysis above accounts for idle time. Most non-production clusters run 24/7, but engineers typically use them only during working hours. This results in up to 16 hours per day of paid compute sitting idle.
For a 10-node development cluster:
AWS EKS: $1,382/month running full-time, $461/month running 8 hours on weekdays
GKE: $1,397/month full-time, $466/month scheduled
AKS: $1,382/month full-time, $461/month scheduled
This represents a 67% cost reduction across all three platforms. The approach is straightforward: suspend the cluster outside working hours and bring it back up on a defined schedule.
A scheduling solution can handle cluster shutdown, state persistence, and automatic resumption across all three providers. While the platforms differ in implementation details, the idle cost problem and its solution remain the same.
The 2026 Verdict: Choose Your Strategy, Not Just Your Cloud
Selecting a managed Kubernetes platform is ultimately a strategic decision. It should align with your architectural priorities and operating model. Based on the data, the decision framework for 2026 is clear:
Choose AKS if your strategy prioritizes high cluster density. With no control plane fees and zero-cost inter-AZ traffic, Azure offers a compelling advantage for multi-cluster environments. However, this benefit holds only if you proactively manage observability to avoid unnecessary logging costs.
Choose EKS if you are deeply AWS native and rely heavily on Spot Instances. AWS continues to lead in mature discount mechanisms, including Reserved Instances and Savings Plans, making it ideal for teams with predictable, large scale workloads.
Choose GKE if your workloads are highly variable. GKE Autopilot’s per-pod billing model minimizes wasted capacity, making it the most efficient option for bursty, developer-driven environments.
Regardless of platform, one principle applies universally: eliminate idle non-production spend first. Addressing this alone can deliver a 30–40% reduction in total cloud costs often without requiring any architectural changes.

OPPO Find X9s Pro, iki farklı 200 megapiksel kamera ile geliyor
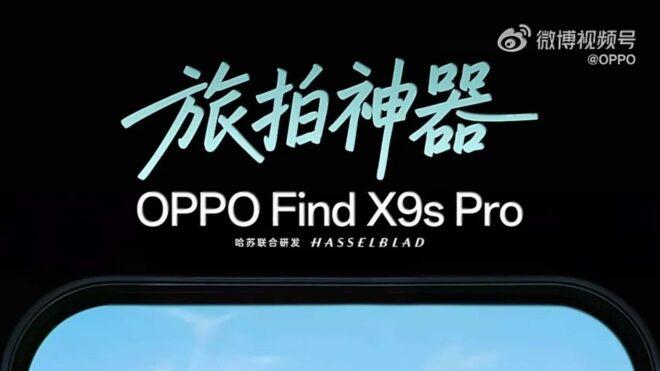
Yapılan resmi doğrulamaya göre yakında tanıtılacak OPPO Find X9s Pro, iki farklı 200 megapiksel kamera ile geliyor. Telefonun arkasında spesifik olarak 200 megapiksel Samsung HP5 sensörlü geniş açı, 200 megapiksel Samsung HP5 sensörlü periskop telefoto ve 50 megapiksellik ultra geniş açı kameraların bir araya getirileceği aktarılırken, cihaza gücünü MediaTek Dimensity 9500 işlemcinin vereceği iddia ediliyor. 6,32 inç 120 Hz LTPS OLED ekranla donatılacağı öne sürülen Find X9s Pro, sızıntılara göre kompakt bir seçenek olmasına rağmen 80W kablolu ve 50W kablosuz şarj destekli 7.000 mAh batarya ile geliyor.
OPPO Find X9s Pro, iki farklı 200 megapiksel kamera ile geliyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
RAI Institute’ten hareket kabiliyetiyle öne çıkan robot: Roadrunner [Video]
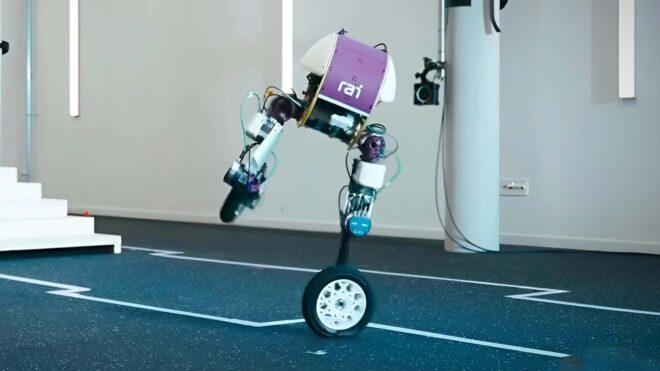
2022 yılında Hyundai Motor Grubu’nun 400 milyon dolarlık yatırımıyla kurulan ve şu anda Hyundai’nin sahibi olduğu Boston Dynamics’in kurucusu ve yönetim kurulu başkanı Marc Raibert tarafından yönetilen RAI Institute, bu kez hareket kabiliyetiyle öne çıkan robot prototipi Roadrunner ile dikkat çekti. 15 kg gövde ağırlığına sahip olan robot, sabit ayaklar yerine tekerleklerin kullanıldığı iki bacak üzerinde hareket ediyor ve hem paralel hem de normal modda ilerleyebiliyor. Aynı zamanda yürüyebilen ve rahatlıkla merdiven çıkıp inebilen robot, birçok benzerinden daha hızlı hareket edebiliyor ve tek ayak/tek tekerlek üzerinde de durabiliyor. Model için yaptığı açıklamada, “Robotun bacakları tamamen simetrik olduğu için dizlerini öne veya arkaya doğru bükebiliyor; bu da engelleri aşmasını ya da özel hareketleri yapabilmesini sağlıyor.” ifadelerini kullanan RAI Institute, geliştirilen bu temeli ileride tam fonksiyonlu bir insansı robota entegre edebilir. RAI Institute bundan önce gösterdiği performans ile oldukça şaşırtan bu robot prototipiyle çok ses getirmişti:
RAI Institute’ten hareket kabiliyetiyle öne çıkan robot: Roadrunner [Video] yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Epistemic Control Systems: governing belief, not reality
An invariant analysis of Epistemic Control Systems, a class of systems that govern belief about reality, not reality itself.
What this class of system is
An Epistemic Control System governs knowledge about reality, not reality itself. It produces, validates, and evolves belief under uncertainty. The canonical examples span domains: financial settlement systems, ML feature stores, logistics routing systems, medical record synthesis. They share the same physics.
The fundamental control variable is confidence-weighted truth over time. Not availability. Not latency. Not throughput. A system in this class that sacrifices correctness for freshness has changed what it is. It is no longer an epistemic system. It is an approximation engine, a different beast with different failure modes.
The Canonical Loop
| Stage | Role |
|---|---|
| Time | Driver |
| Historical observations | Input |
| Synthesis and aggregation | Transformation |
| Immutable snapshot | Output |
| Next time boundary | Continuation |
There is no notion of now inside this loop. Only as of T exists. The system does not stream truth continuously. It advances truth in discrete, verified steps. Each step either completes or it does not. There is no partial completion.
Universal Primitives
These six primitives exist in every epistemic system, regardless of domain or technology:
- Observation: the raw input signal
- Time Window: the boundary of what counts as input
- Synthesis: the aggregation and confidence-weighting process
- Snapshot: the immutable output of a completed synthesis
- Publication Gate: the binary control that determines whether truth advances
- Authority Pointer: the reference to the last trusted snapshot
A logistics routing system has all six. A clinical trial data system has all six. A trading book reconciliation system has all six. The names change. The structure does not.
Non-Negotiable Invariants
These are the system physics. Violating any one does not degrade the system. It changes what the system is.
- Truth advances only on success, never on partial confidence
- Canonical knowledge is always historical, never present-tense
- Failure cannot retract belief. It can only pause advancement
- Snapshots are immutable once published
- Correctness strictly dominates freshness
- Knowledge never enacts control. It only informs it
- Truth is monotonic and confidence-bounded
A snapshot that can be retracted is no longer a snapshot. A gate that passes partial results is no longer a gate. The identity of the system is constituted by these invariants, not by its implementation.
What Failure Means
- Failure pauses time, not the world
When a synthesis step fails due to an upstream data gap, a timeout, or a confidence threshold not met, the instinct is to call this a system failure. It is not. The world continued. The system paused its clock.
This distinction is architectural, not semantic. A system that treats failure as a retraction of prior belief will corrupt its state. A system that treats failure as a pause in time advancement will remain coherent. The next successful run does not repair a broken state. It simply advances time from where it stopped.
The diagnostic question is never “why did it fail?” first. It is always: “did correctness survive?” If yes, the system worked. It paused time. It did not break.
Containment Boundaries
Three boundaries prevent epistemic corruption, the condition where partial belief leaks into the consumption layer and is treated as complete truth.
Boundary 1: Reasoning boundary
Failure is permitted here. Uncertainty resolves inside. Nothing crosses until synthesis is complete.
Boundary 2: Publication boundary
All or nothing. Truth crosses or it does not. This is the critical gate. It is binary by design.
Boundary 3: Consumption boundary
Readers trust the snapshot only. Never partial state. The snapshot they receive is complete or it does not exist.
This boundary model assumes observation integrity. The question of what governs input legitimacy before the reasoning boundary is a separate analysis.
Explicit Anti-Goal
This system should not become a real-time truth oracle.
The chain is direct: real-time implies partial belief, partial belief implies false certainty, false certainty scales into harm.
Freshness pressure is the most common way epistemic systems lose their identity. The moment a system begins publishing partial snapshots to reduce latency, it has crossed the boundary into a different class, one without the safety properties described here.
Human feedback as stabiliser
At scale, epistemic systems face oscillation risk. Urgency signals cause the system to lower its confidence threshold, which causes incorrectness, which causes downstream harm, which increases urgency.
The circuit breaker is human judgment. Humans interpret the freshness-correctness trade-off. Humans re-weight priority. The system does not auto-escalate. It waits.
This is not a limitation. It is a safety property.
Summary
- Epistemic systems control belief, not reality.
- They advance truth only when confidence is complete.
- Failure pauses time, not the world.
- Correctness is sacred. Freshness is negotiable.
Rio: An AI Agent That Lives Inside Notion — Voice Task Live Notion Memory
This is a submission for the Notion MCP Challenge
What I Built
Rio is a voice-controlled multi-agent AI system. You speak a task — Rio’s agents plan it, execute it on your desktop, research it on the web, and write the result. Every single step of that process lives in your Notion workspace, written in real time, structured, searchable, and yours.
Notion isn’t a plugin here. It’s the mind Rio thinks in.
The Problem
AI agents are powerful and invisible. They spin up, do work, disappear. You get a final answer with no trace of how it got there — no audit trail, no structured memory, nothing you can build on top of.
Rio solves that by making Notion the surface where agents think out loud. Every task claimed, every browser step taken, every report written — it all lands in structured Notion databases as it happens, not after the fact.
Demo
What you’ll see:
- A pending task sitting in the Rio Task Queue database
- A voice command to Rio — “Research the top 3 AI agent frameworks and write a comparison”
- The Rio Logs database populating live — one row per agent step, in real time
- The Creative Agent writing a full formatted Notion page as the final deliverable
- The task row flipping to
done
How Notion MCP Is Core
There are two distinct ways Notion is used — and both matter.
1. Notion as memory
Every agent writes structured logs as it works. Not at the end — during. The Orchestrator logs when it claims a task. The UI Navigator logs each browser action. The Creative Agent writes the full report as a Notion page.
# Every logger.info() becomes this
await memory.log_step("ui_navigator", "browser_step", action, "done")
# → live Notion row: agent name, event, detail, status, timestamp
2. Notion as a reasoning tool (via MCP)
Agents actively query and write Notion during execution — not just at completion. The Orchestrator polls the Task Queue for new jobs. The Creative Agent searches existing pages before writing.
tools, toolset = await MCPToolset.from_server(
connection_params=SseServerParams(
url="https://mcp.notion.com/sse",
headers={"Authorization": f"Bearer {user_token}"}
),
tool_filter=["notion-search", "notion-create-pages", "query-database"]
)
No .env Tokens. Anyone Can Use This.
Rio uses a full OAuth 2.0 + PKCE flow. A user clicks “Connect Notion,” approves access, and their token lives in session memory. No database IDs are hardcoded anywhere. The moment they connect, Rio auto-creates their Rio Logs and Rio Task Queue databases — zero manual Notion setup.
User clicks Connect Notion
→ /oauth/start — PKCE verifier generated, redirect to Notion login
→ /oauth/callback — code exchanged, token stored in session memory
→ auto_setup() — Rio Logs DB + Task Queue DB created in their workspace
→ WebSocket init — agents get NotionMemory + MCPToolset injected
The only things in .env are your app’s own client_id and client_secret from notion.so/my-integrations.
Architecture
RIO — SYSTEM ARCHITECTURE
==========================
User
|
Voice Input
|
v
+-------------------------+
| Orchestrator Agent |
| polls Notion Task |
| Queue for pending jobs |
+-------------------------+
| | |
v v v
+------------+ +----------+ +-----------------+
| Live Agent | | UI Navi- | | Creative Agent |
| voice STT | | gator | | research, write |
| + TTS | | browser | | full Notion |
| | | desktop | | pages + reports |
+------------+ +----------+ +-----------------+
| | |
v v v
+---------------------------------------+
| NotionMemory |
| writes every step live to Notion |
| via REST API (httpx async) |
| |
| Rio Logs DB Task Queue DB |
| Agent / Event Task / Status |
| Detail / Status Agent / Result |
+---------------------------------------+
|
v
+---------------------------------------+
| MCPToolset |
| lets agents query + search Notion |
| during execution (SSE transport) |
| |
| notion-search query-database |
| notion-create append-block |
+---------------------------------------+
|
v
+-------------------------+
| User Notion Workspace |
| connected via OAuth |
| PKCE — no env tokens |
+-------------------------+
OAUTH FLOW
----------
User clicks "Connect Notion"
|
v
/oauth/start
generate code_verifier + code_challenge (PKCE S256)
|
v
api.notion.com/v1/oauth/authorize
user approves Rio access in their own browser
|
v
/oauth/callback
exchange code + verifier for access_token
store token in session (in-memory, per user)
|
v
NotionMemory.setup()
auto-creates Rio Logs DB + Task Queue DB
in the user workspace if not already present
|
v
MCPToolset.from_server()
connects to mcp.notion.com/sse
with user access_token — agents ready
Stack: Python · Google ADK · FastAPI · WebSockets · Notion REST API · Notion MCP (SSE) · httpx async · Google Cloud Run
What I Learned
Building agents is easy. Building agents with observable, persistent memory is what actually makes them useful.
The shift from logger.info() to await memory.log_step() sounds trivial — but it completely changes the character of the system. Rio’s work is no longer ephemeral. It accumulates. You can go back, search it, build on it, share it. That’s what Notion gives it.
The OAuth decision was also non-negotiable. An agent that only works with hardcoded tokens is a demo. An agent that any person can authorize with their own workspace is a product.
Rio Notion Live Web – Rio-Notion Live Web
Source Code
Stop the Awkward Silence: Signals to Classic Orchestration
Intro:
If you’ve used generative orchestration in Copilot Studio, you’ve seen the comforting “thinking” animation while the copilot works. Classic orchestration doesn’t do that out of the box. So when you kick off a longer task—like a RAG lookup or a flow call—the chat can look empty. No typing dots. Just silence.
That silence is a UX bug, not a feature. The fix is quick: send a Typing event immediately before the slow step, then add a short acknowledgement message to set expectations.
Configuration:
-
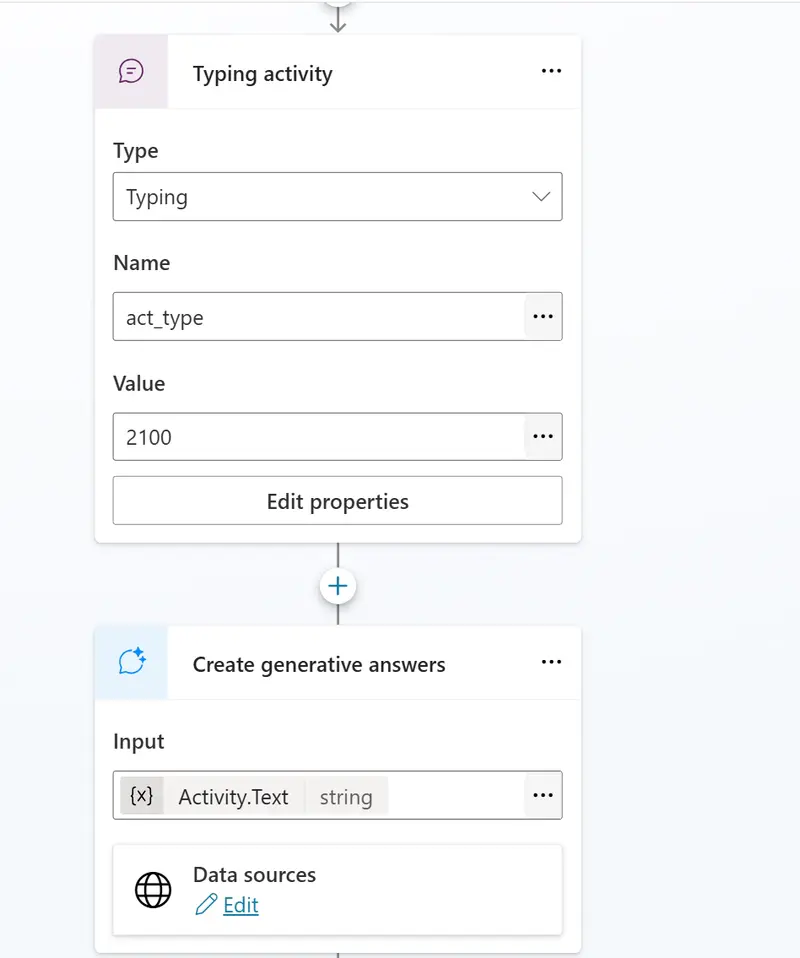
Locate the slow step or Topic where you have user feedback on the poor UX expereince (May be based on the user activity we might have logic where the heavy work starts: Create generative answers, a flow, or an HTTP/API call.)
-
Set Event type to Typing.
The example below the timer is set as 2100 ( milliseconds)

Add a brief acknowledgement message Right after the Typing event, add a normal message to set expectations. Keep it human and specific:
“Got it — searching our knowledge base. This may take a few seconds.”
“Working on your request — I’ll be right back with the details.”
Good UX patterns to include:
- Time cue: “This usually takes ~5–10 seconds.” It sets expectations and reduces anxiety.
- Specific context: “Checking SAP invoices…” feels more reassuring than generic “Working…”
- Channel-aware: Typing events are short-lived (around 2-4 seconds). Always send an acknowledgement text so users see something even if the channel ignores Typing.
Closing Notes:
A great bot isn’t just smart — it’s considerate. In classic orchestration, adding a Typing event plus a short acknowledgement transforms a “silent” wait into a clear, reassuring experience. It takes less than a minute to wire up and pays off immediately in user confidence and perceived speed.