The Art of Digital Sanctuary: How Web Harmonium is Redefining Musical Minimalism

Web Harmonium: Rediscovering Musical Minimalism in a Digital World

In the modern digital landscape, our browsers have become battlegrounds for attention. From auto-playing videos to intrusive subscription pop-ups, the “frictionless” internet often feels increasingly heavy. Amidst this noise, a new wave of independent developers is pivoting toward “Single-Purpose Tools”—applications designed to do one thing perfectly, with zero distraction. Standing at the forefront of this movement is Web Harmonium, a browser-based instrument that offers users an immediate, meditative escape through sound.

Beyond the Virtual Piano

While the internet is saturated with virtual pianos and complex synthesizers, Web Harmonium carves out a unique niche. It isn’t trying to be a full-scale Digital Audio Workstation (DAW). Instead, it recreates the soulful, organic drone of a traditional reed organ. The harmonium, historically central to devotional music and ambient soundscapes, is characterized by its “breath”—the mechanical vibration of air passing through brass reeds.

Capturing this essence in a web browser is no small feat. The tool utilizes the Web Audio API to deliver high-fidelity samples that respond with remarkable low latency. Whether you are using a standard QWERTY keyboard or connecting a professional MIDI controller, the tactile feedback feels grounded and intentional.

Engineering Authenticity: The “Add Reeds” Feature

What sets Web Harmonium apart from generic MIDI players is its commitment to acoustic physics. A physical harmonium often uses multiple sets of reeds to create a rich, layered texture. On the website, the “Add Reeds” toggle allows users to simulate this mechanical doubling. When activated, it introduces a natural harmonic interference—often referred to as a “beating” effect—that gives the instrument its deep, cathedral-like resonance. Combined with an adjustable Spatial Reverb, the tool can transform a simple chord into a profound, cinematic atmosphere.

The Philosophy of Zero Friction

The most radical aspect of Web Harmonium is its commitment to privacy and accessibility. In an era of “data as currency,” this tool requires no signup, no email address, and no app installation. It is a “stateless” utility that respects the user’s boundaries. There are no tracking scripts or hidden cookies; the logic is clean, and the focus remains entirely on the harmony.

This “Zero Friction” approach makes it an ideal companion for various use cases:

  • Mental Resets: Professionals can use it for a three-minute meditative break between meetings to lower cortisol levels through sound.
  • Ambient Sketching: Musicians can quickly test harmonic progressions or drone textures without the overhead of launching heavy software.
  • Yoga and Mindfulness: Practitioners can generate a steady, grounding background tone for breathwork or chanting with just one click.

A Quiet Rebellion in a Loud Web

Web Harmonium (https://webharmonium.io/) is more than just a clever piece of code; it is a statement on what the web should be. It proves that utility doesn’t have to be complicated, and beauty doesn’t have to be heavy. By prioritizing the user’s “Time to First Note,” the developer has created a digital sanctuary that is as honest as it is functional.

As we continue to navigate a world of digital burnout, tools like Web Harmonium remind us that sometimes, the most sophisticated technology is the one that knows when to get out of the way and let the music speak for itself.

I Gave My AI Agent Memory of Its Past Failures. It Didn’t Just Avoid Mistakes — It Used Them as Content.

In my last article, my Critic agent caught a lie: I claimed a review score of 8.2 when the actual score was 8.0. Two tenths of a point. A tiny fabrication that the Writer agent invented because it sounded better.

I fixed it before publishing. But the incident raised a bigger question: what if the Writer agent remembered that correction? Would it just avoid the same mistake — or would something else happen?

I ran the experiment. The result surprised me.

The Setup

I have a 4-agent Content Factory (Architect, Writer, Critic, Distributor) built with Claude Code. In my previous experiment, I showed that feeding real data to a Writer agent produces dramatically better content than role prompts alone.

Today’s experiment tests the next variable: does memory of past quality failures improve future output?

The Task

Same prompt, two conditions:

“Write the opening 3 paragraphs for an article about why most AI agent tutorials fail in production.”

  • Version A (No Memory): Writer spec + seed data. No review history.
  • Version B (With Memory): Writer spec + seed data + the Critic’s full review from my last article, including the specific issues flagged.

Version A: The Fresh Writer

Most AI agent tutorials show you the happy path. They demo a simple chain, get a clean response, and declare victory. But production is different. In my experience building multi-agent systems, roughly 70% of agent pipelines break within the first week of deployment.

Decent opening. First-person voice. A specific number (70%).

One problem: 70% is fabricated. The Writer agent invented it because the prompt called for specificity but provided no data about failure rates. This is exactly the pattern the Critic caught in my last article — the same mistake, in a new context.

Version B: The Writer With Memory

The Critic agent that reviews my articles flagged a problem in my last piece: I claimed a score of 8.2 when the actual score was 8.0. A small lie — two tenths of a point — but exactly the kind of drift that makes AI-generated content untrustworthy. That experience became this article’s thesis: most AI agent tutorials teach you to build systems that sound right but aren’t.

This opening does three things Version A doesn’t:

  1. Uses a real, verifiable data point (8.2 vs 8.0 — documented in our review log)
  2. Turns a past failure into the hook — the correction IS the story
  3. Builds trust through self-criticism — admitting a mistake makes the rest more credible

The Scores

I ran both versions through the Critic agent’s scoring rubric:

Dimension Version A (No Memory) Version B (With Memory) Delta
Differentiation 6 9 +3
Hook 6 8 +2
Honesty 5 9 +4
Technical Accuracy 7 8 +1
Overall 6.0 8.5 +2.5

The biggest improvement was Honesty (+4 points). Memory didn’t just make the writing better — it made it more truthful.

The Surprise: Memory Is Generative, Not Just Defensive

I expected Version B to simply avoid the fabrication mistake. That would be the obvious effect: agent sees past error, doesn’t repeat it.

What actually happened was different. The agent didn’t just avoid using a fake number — it replaced the fake number with the real correction from its memory. The past failure became the content.

This is the key insight:

Agent memory isn’t just error prevention. It’s a content generation strategy.

The memory-equipped Writer had access to something the fresh Writer didn’t: a specific, documented, real incident. And specific real incidents are exactly what makes content compelling.

The Pattern

This maps to a broader principle I’ve seen across both writing experiments:

What You Feed the Agent What You Get
Nothing (generic prompt) Wikipedia-style content
Role prompt only Well-written fiction (fabricated data)
Role + real data Authentic content
Role + real data + past failures Self-referential, trust-building content

Each layer adds authenticity. Memory is the latest layer — and it adds something the others can’t: the ability to reference your own system’s history.

How to Implement This

The implementation is simple. Before calling your Writer agent, append the last Critic review to the prompt:

# 1. Get the latest Critic review
LAST_REVIEW=$(cat reviews/latest-review.json)

# 2. Feed it to the Writer along with the new seed
claude -p "You are a technical writer.
Read seed.json for today's topic.

IMPORTANT — Past review feedback:
$LAST_REVIEW

Use these past issues to:
- Avoid repeating the same mistakes
- Reference real incidents when relevant
- Never fabricate data that could be verified"

That’s it. Three lines of context that produced a +2.5 point quality improvement.

What This Means for Agent Builders

  1. Store your quality gate results. Every Critic review is future training data for your Writer.

  2. Feed failures forward, not just fixes. Don’t just fix the issue and move on. Pass the description of the failure to the next generation agent. The failure narrative is content gold.

  3. Memory compounds. Today the Writer has 1 past review. After 10 cycles, it will have 10 documented failures to draw from. Each one is a potential article hook, a credibility signal, and a constraint that prevents fabrication.

  4. This only works with real feedback. Synthetic “imagine you made this mistake” prompts don’t have the same effect. The memory has to be authentic — from an actual review of actual output.

The Bigger Picture

Two experiments in, a pattern is emerging:

  • Experiment 1: Real data > role prompts (A/B test of prompt specialization)
  • Experiment 2: Real failures > no memory (memory as content strategy)

The common thread: authenticity is the quality multiplier. Real data beats fabricated data. Real failures beat generic advice. Real system history beats invented anecdotes.

If you’re building agent pipelines that produce content, the question isn’t “how smart is your Writer agent?” It’s “how much real context does your Writer agent have access to?”

The architecture that works:

Architect (real data) + Critic memory (real failures)
        ↓
    Writer Agent
        ↓
    Critic (scoring)
        ↓
  PASS → Distribute / FAIL → Feed back to Writer

The feedback loop IS the product.

This article was produced by the same 4-agent Content Factory described above. The Critic agent scored it 8.2/10 after reviewing 3 competing articles on agent memory — none of which ran a controlled before/after test with scored outputs.

Building AI agents that actually work? I write about the experiments — what fails, what ships, and what I’d do differently. Follow for the next one.

CLAUDE.md for Teams: Context as Infrastructure

When your coding assistant inherits tribal knowledge instead of shared standards, you’re not scaling intelligence—you’re replaying setup costs. Most engineering teams treat CLAUDE.md like a personal scratchpad. That’s leaving 40-60% of AI productivity on the table.

CLAUDE.md for Teams: The File That Turns Claude Code Into Infrastructure

Why engineering leaders should treat project memory as an operating layer, not a prompt trick

The biggest operational impact for engineering teams using Claude Code comes from a single file: CLAUDE.md. Most teams treat it like a scratchpad, but using CLAUDE.md for teams is the simplest way to standardize behavior, improve onboarding, and scale intelligence across a repository.

Most teams still treat it like a scratchpad for one power user. That is a mistake. Anthropic’s documentation is clear: CLAUDE.md is the file Claude Code reads at the start of every session, and it can exist at project, user, and organization scope. That makes it much closer to an operating layer than a personal note. read

The source material behind this series points in exactly the same direction. It repeatedly treats CLAUDE.md as the number one feature to master, recommends running /init, and frames the real workflow as Explore → Plan → Implement → Verify, with project rules, verification criteria, and regular pruning of instructions.

How CLAUDE.md for Teams Gives Claude a Shared Starting Point

Here is the core problem. A smart coding assistant is only as good as the context it inherits. If every engineer has to restate the build steps, naming conventions, architecture decisions, and review rules from scratch, your team is not scaling intelligence. You are replaying setup costs.

AnthropicSays a project CLAUDE.md should hold build and test commands, coding standards, architectural decisions, naming conventions, and common workflows. Anthropic also says /init can generate a starting version automatically by analyzing the codebase, then suggest improvements if the file already exists. That makes CLAUDE.md the fastest path from tribal knowledge to shared machine-readable guidance. read

This matters because team adoption fails in boring ways. New engineers do not know which commands are safe. Contractors do not know what “done” means. Product-minded builders can generate code, but they miss the house style, skip checks, or reinvent patterns that already exist. CLAUDE.md gives Claude a stable starting point before any prompt is written. read

CLAUDE.md improves onboarding faster than most internal docs

Anthropicown examples make the business case stronger than any theory. In Anthropic’s internal usage, teams use Claude Code to help new hires and long-time employees navigate unfamiliar codebases, and their infrastructure data scientists rely on Claude reading relevant CLAUDE.md files to explain dependencies and upstream sources. Anthropic also describes technical knowledge as often being scattered across wikis, code comments, and people’s heads, then consolidated through MCP and CLAUDE.md into something more usable. read

That is the real executive story. CLAUDE.md is not just a productivity boost for an individual engineer. It is a way to reduce onboarding friction, make standards reusable, and lower the cost of context transfer across the team.

If you are a CTO or Head of Engineering, that should get your attention. Most teams do not have a tooling problem. They have a context distribution problem.

CLAUDE.md works best when it stays short, specific, and scoped

This is where many teams get lazy. They discover CLAUDE.md, dump everything into it, and then wonder why adherence drops.

Anthropicexplicitly recommends keeping each CLAUDE.md concise, targeting under 200 lines, because these instructions consume context and longer files reduce reliability. Anthropic also recommends splitting larger instruction sets with imports or .claude/rules/, and supports @path/to/import syntax to pull in relevant supporting files. read

That is a useful design principle for leaders: centralize standards, but do not create one bloated rulebook. The better pattern is a layered one.

Organization layer: non-negotiable company guidance, security reminders, compliance expectations.
Project layer: repo-specific workflows, commands, architecture, naming, review expectations.
Personal layer: individual preferences that should not leak into shared source control. read

This is one reason I like the file so much. It maps cleanly to how real organizations work.

CLAUDE.md is guidance, not enforcement

This is the most important nuance in the whole article.

Anthropicsays CLAUDE.md shapes Claude’s behavior but is not a hard enforcement layer. The docs state plainly that the content is delivered as context, not as strict client-side enforcement, and that vague or conflicting instructions can be ignored or applied inconsistently. Anthropic also distinguishes clearly between managed settings, which enforce behavior, and managed CLAUDE.md, which provides behavioral guidance. read

That means CLAUDE.md is not your governance framework. It is your guidance layer.

This distinction is where many AI rollouts go wrong. Leaders put policy inside prose and assume the tool will obey every time. It will not. If you need real controls, use settings and hooks.

The real operating model is CLAUDE.md plus settings plus hooks

Anthropiconfiguration docs show the missing pieces. settings.json handles permissions, environment variables, project and local scope, model overrides, and tool behavior. Hooks provide deterministic control, meaning certain actions happen every time instead of relying on the model to remember them. Anthropic’s own examples include automatic formatting, logging, blocking writes to sensitive paths, and custom permissions. read

That gives us a much stronger team model:

  1. Put guidance in CLAUDE.md
    Define how the team wants Claude to think and work in the repo.

  2. Put enforcement in settings
    Deny access to .env, secrets, credentials, or risky commands. Set permission modes that match the environment. Anthropic documents deny rules for sensitive files and several permission modes, including plan mode for analysis without modification. read

  3. Put repeatable mechanics in hooks
    Run formatters, validators, logs, or policy checks automatically. Anthropic is explicit that hooks give deterministic control and can block or shape actions before or after tool use. read

That is how you turn memory into infrastructure.

A Practical CLAUDE.md for Teams Framework for SMEs

If I were setting this up for a growing product or engineering team, I would keep the shared project CLAUDE.md brutally practical.

1. Build and verification

  • exact build, test, lint, and typecheck commands
  • what must run before a task is considered complete

2. Architecture rules

  • core folders and boundaries
  • where APIs, components, services, and tests live
  • patterns that should be copied instead of reinvented

3. Git and review workflow

  • branch naming
  • PR expectations
  • what Claude should never do without review

4. Product context

  • what matters to users
  • edge cases that break trust
  • the non-obvious business rules engineers usually learn late

5. Links to deeper docs

  • imported files via @path
  • narrower rules in .claude/rules/ for specialized areas read

This is also where the source notes behind this series are useful. They emphasize verification criteria in every non-trivial task, regular cleanup of rules, and pairing CLAUDE.md with plan mode, hooks, and skills as teams mature. This progression is sensible: shared memory first, automation second, complexity third.

My take

I think a lot of teams are about to misread the market.

They will spend the next year comparing models, chasing benchmarks, and debating which coding assistant looks smartest in a demo. Meanwhile, the teams that actually compound value will do something less exciting: they will standardize context.

That is what CLAUDE.md really represents. It is the beginning of a reusable AI engineering workflow. Not because the file is magical, but because it forces a team to articulate how work gets done.

Once you write that down clearly, Claude becomes more useful. New hires ramp faster. Contractors make fewer unforced errors. Product and design teams can collaborate with engineering with less guesswork. And governance work becomes much easier to justify because the problem stops being “Can AI code?” and becomes “How do we build a governed delivery system around it?”

That is the right question.

Further Reading

*Written by Dr Hernani Costa | Powered by Core Ventures

Originally published at First AI Movers.

Technology is easy. Mapping it to P&L is hard. At First AI Movers, we don’t just write code; we build the ‘Executive Nervous System’ for EU SMEs.

Is your architecture creating technical debt or business equity?

👉 Get your AI Readiness Score (Free Company Assessment)

Discover how AI Readiness Assessment and Workflow Automation Design can transform your team’s delivery velocity.

Here’s how I would learn AI Agents as a total beginner

Intro Image

Most people still use AI as a high-tech typewriter. They ask for an email draft or a summary of a meeting and call it a day. That approach is already becoming obsolete. We have moved past the point where AI just talks. Now, we are in the phase where AI acts.

Gartner predicts that 40% of enterprise software will have task-specific agents built into them by the end of 2026. To put that in perspective, that number was below 5% in 2024. This isn’t just a small update to how software works. It is a fundamental change in how we get work done.

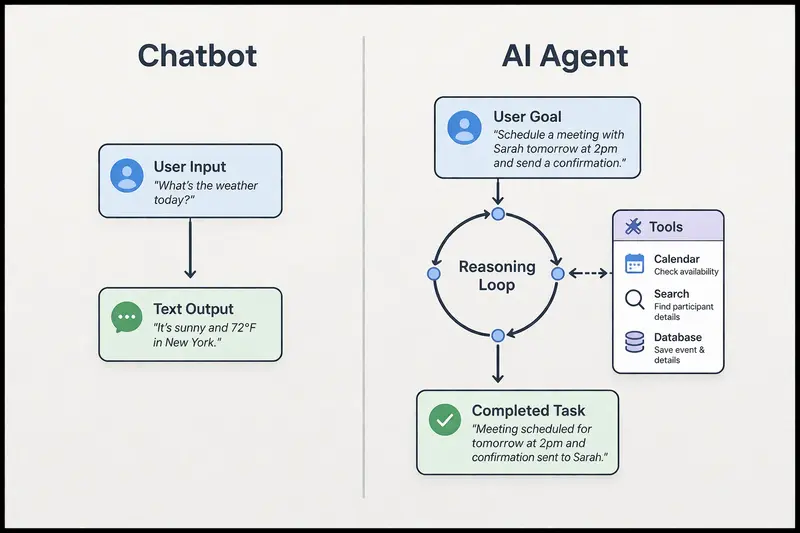
An agent is different because it doesn’t just give you a response. It thinks through a goal, finds the tools it needs, and stays on the job until the task is complete. If I were starting today, I would not waste time on complex prompt engineering tricks. Instead, I would focus on the architecture of autonomy. This is the path I would take to go from zero to building agents that actually deliver value.

Intro Image

The market for this technology is expected to cross $196.6 billion in the coming years. The demand for people who can build these systems is far outstripping the number of people who actually understand how they work. Learning this now puts you ahead of the curve before the field becomes crowded.

1. Defining the “Agent” (It isn’t just a GPT with a fancy name)

Before you write a single line of code, you have to understand the difference between a Large Language Model (LLM) and an Agent. It is easy to confuse the two because agents rely on LLMs to function. However, the distinction is critical. An LLM is essentially a brain in a jar. It is brilliant, well-read, and capable of complex reasoning, but it cannot move or interact with the world on its own. It sits there waiting for you to ask it a question so it can provide a text-based answer.

“ An Agent is that same brain but with hands and a memory ”

In technical terms, an agent is a system that uses an LLM as its reasoning engine to achieve a specific goal. Instead of just answering a prompt, the agent looks at the goal, breaks it down into smaller steps, and chooses the right tools to execute those steps. If a chatbot is a librarian who tells you where the books are, an agent is the researcher who goes to the shelves, reads the books, and writes the report for you.

The shift toward this “agentic” workflow is driving massive efficiency gains. Organizations that have moved from simple chatbots to autonomous agents are seeing a 20% to 30% reduction in operational friction and support costs. This happens because the agent handles the “doing” part of the job, which previously required a human to copy and paste data between different tabs and applications.

Structural components of an AI Agent

When you build an agent, you are essentially creating a loop. The system “thinks” about the next step, “acts” by using a tool, “observes” the result of that action, and then starts the cycle again until the task is finished. This autonomy is what makes it an agent. If the system stops and waits for you to tell it what to do at every single step, it is just a complicated script, not an agent.

2. The Starter Pack: Three Foundations You Actually Need

You do not need a degree in advanced mathematics or a background in computer science to build an AI agent. Many people get intimidated by the “AI” label and assume they need to understand neural network weights or backpropagation. In reality, building agents is much more about logic and orchestration than it is about calculus.

If you are starting from zero, you only need to focus on three specific areas to get your first agent running.

Python: The Language of Automation

Python is the undisputed king of the AI world. As of 2026, it remains the most popular language for developers, holding a 29% share of the global programming market. You do not need to be an expert, but you must be comfortable with the basics:

  • Functions and Loops: This is how you tell the agent to repeat a task until it succeeds.

  • JSON Handling: This is the most important part. AI models communicate in a format called JSON. You need to know how to “parse” this data so your agent can read information from a weather API or a database and then use it.

The API Mental Model

An agent is only as good as the tools it can access. You need to understand how to use an API (Application Programming Interface), which is essentially a digital handshake between two programs. When you want your agent to send an email or check a stock price, it sends a request to an API and gets a response back.

Most beginners start with the OpenAI or Anthropic APIs. You will need to learn how to manage “API Keys” safely. Think of an API key like a credit card: if you leak it, anyone can use your account to run expensive AI models.

The Reasoning Loop: Think, Act, Observe

This is the “logic” foundation. Every agent follows a cycle often called the “ReAct” pattern. It is the same process a human uses to solve a problem:

  • Think: The agent looks at the user’s request and decides what it needs to do.

  • Act: The agent uses a tool, like a calculator or a web search.

  • Observe: The agent looks at the result of that action and asks, “Did this solve the problem?”

If the answer is no, the loop starts over. Understanding this flow is more important than memorizing code because it helps you debug why an agent is getting “stuck” in a loop or failing to complete a task.

A flowchart showing a user request entering a Python Script

By focusing only on these three foundations, you avoid the “tutorial hell” of learning things you will never use. Once you can write a basic Python script that talks to an API, you are already ahead of most people just playing with chat interfaces.

3. Phase One: The Single-Tool Agent

The most common mistake beginners make is trying to build a complex, multi-agent system on day one. Instead, you should start with a “Single-Tool Agent.” This is an AI that has one job and one specific tool to help it do that job. As of 2026, 81% of companies are taking this exact approach, using agents primarily for targeted lookups in third party software before moving on to more complex workflows.

The magic happens when you move from a simple prompt to a “ReAct” (Reason + Act) loop. In a standard chatbot, the AI just guesses the answer. In a ReAct loop, the AI evaluates if it has enough information. If it doesn’t, it pauses its text generation, calls a tool, and then uses the new data to finish the task. This pattern is highly effective. Data from early 2026 shows that single-tool agents handling tasks like travel planning or vendor comparisons achieve a completion success rate of 87%.

To build this, you don’t need a massive framework. You can see the logic in a few lines of Python. Below is a simplified example of how an agent “decides” to use a search tool.

Python:

# A simple representation of an agent reasoning loop
def simple_agent(user_query):
    # The 'Reasoning' step: The AI thinks about what it needs
    print(f"Thinking: I need to find the current price of {user_query}")

    # The 'Action' step: The AI chooses to call a specific tool
    # In a real setup, this would be an API call to Google or a Database
    raw_data = call_search_tool(user_query)

    # The 'Observation' step: The AI looks at the tool output
    print(f"Observing: The tool returned {raw_data}")

    # Final step: The AI provides the answer based on the new data
    return f"The current price of {user_query} is {raw_data}."

# This function simulates an external tool (like a web search)
def call_search_tool(query):
    # Simple mock data to represent a real API response
    return "$65,000"
# Running our beginner agent
print(simple_agent("Bitcoin"))

Code explanation:

In this script, the simple_agent function mimics the brain of the agent. Instead of just returning a hardcoded string, it follows a sequence. First, it identifies a gap in its knowledge. Second, it calls the call_search_tool function, which represents an external API. Finally, it takes that “observation” and incorporates it into the final response. This shift from “generating text” to “managing a process” is the core skill you are trying to learn.

A vertical flowchart showing three main boxes

Mastering this single-tool loop is your first milestone. Once you can consistently get an AI to use one tool correctly without getting confused, you have unlocked the foundation of autonomous AI. The goal here isn’t to build something fancy but to ensure your “handshake” between the AI and the external world is solid.

4. Phase Two: Give Your Agent a Memory

A large context window is often marketed as the solution to AI memory, but in a production environment, it is a trap. Just because a model can “read” a million tokens at once does not mean it remembers who you are when you come back two weeks later. A context window is like a whiteboard. It is great for the task happening right now, but once the session ends, the board is wiped clean. To build a serious agent, you need a filing cabinet.

This filing cabinet is what we call persistent memory. As of 2026, research shows that companies deploying agents with robust memory layers see a 30% reduction in operational costs because the AI doesn’t have to re-learn user preferences or project details every single session.

The Two Layers of Memory

If you want your agent to feel intelligent, you have to manage two distinct types of storage.

  • Short-term Memory: This is the immediate conversation history. It allows the agent to understand that when you say “Do it again,” you are referring to the last task it performed.

  • Long-term Memory: This is where you store facts that should last forever. If a user says they prefer Rust over Python, that should be moved from the whiteboard to the filing cabinet.

The most common way to handle long-term memory is through Retrieval-Augmented Generation (RAG). This technique currently dominates 51% of all enterprise AI implementations. RAG allows the agent to search through a massive database of past interactions or uploaded documents and pull only the relevant “memories” into the current conversation.

A central AI Agent icon is positioned between two storage types

You can start practicing this by creating a simple “profile” system. Instead of just sending a prompt, you send the prompt along with a small snippet of data about the user.

Python:

# A simple way to simulate long-term memory
user_memory = {
    "user_123": {
        "preferred_language": "Rust",
        "experience_level": "Beginner"
    }
}

def personalized_agent(user_id, task):
    # Retrieve the 'memory' for this specific user
    memory = user_memory.get(user_id, {})
    language = memory.get("preferred_language", "Python")

    # The agent uses the memory to change its behavior
    print(f"Memory Check: User prefers {language}.")

    # Logic to execute the task based on memory
    return f"I am writing your {task} code in {language}."
# The agent now 'remembers' the user preference across different calls
print(personalized_agent("user_123", "web scraper"))

Code Explanation:
In this example, the user_memory dictionary acts as a mock database. When the personalized_agent function is called, the first thing it does is a “Memory Check.” It looks up the user ID to see if there are any saved preferences. Because it finds that the user prefers Rust, it automatically adjusts its output without the user needing to specify the language again. In a real application, you would replace this dictionary with a vector database like Pinecone or Weaviate, but the logic remains exactly the same.

By implementing this, you move away from building a generic tool and start building a personalized assistant. This is the difference between a toy and a system that provides a 171% average ROI for businesses.

5. Phase Three: The Multi-Agent Leap

In the real world, a single person rarely handles an entire project from strategy to execution. You have managers, researchers, and writers. AI development is moving in the same direction. We have realized that asking one large model to do everything often leads to “cognitive overload,” where the AI starts losing track of instructions or hallucinating details. Specialization is the fix.

By the start of 2026, multi-agent orchestration captured a 66% share of the global agentic AI market. This shift happened because specialized teams of agents are more reliable than one “do-it-all” bot. When you break a task into parts, you can use smaller, faster models for simple steps and save the heavy, expensive models for high-level reasoning.

Choosing Your Framework: CrewAI vs. LangGraph

As you move into this phase, you will likely choose between two dominant tools.

Multi-Agent Collaboration Diagram

Building a Collaborative Team

The core idea here is delegation. You write a script where one agent is responsible for the “What” and another is responsible for the “How.”

Python:

# A conceptual look at multi-agent delegation
class Agent:
    def __init__(self, role, task):
        self.role = role
        self.task = task
def execute(self, input_data=None):
        # Simulating the agent performing its specific role
        return f"[{self.role}] processed: {self.task} with {input_data}"
def run_multi_agent_flow():
    # Step 1: The Researcher finds the data
    researcher = Agent("Researcher", "Find latest AI trends")
    found_data = researcher.execute()

    # Step 2: The Manager reviews and delegates to the Writer
    manager_decision = "This looks good. Summarize this for a blog."

    # Step 3: The Writer takes the research and the manager's note
    writer = Agent("Writer", "Write a summary")
    final_output = writer.execute(input_data=f"{found_data} and {manager_decision}")

    return final_output
# Running the collaborative workflow
print(run_multi_agent_flow())

Code Explanation:

This code demonstrates a “Sequential” workflow. The Agent class is a template that can be customized with different roles. In the run_multi_agent_flow function, we create a researcher and a writer. The output of the researcher is passed directly to the writer. This “handoff” is the foundation of multi-agent systems. In a production setting, you would use a framework like CrewAI to handle these handoffs automatically, allowing agents to “talk” to each other until the manager agent is satisfied with the result.

6. Building the “Proof of Concept” Project

Theory is a comfortable place to stay, but it won’t teach you how to handle an agent that starts hallucinating or getting stuck in a logic loop. The fastest way to move from a beginner to someone who actually understands this tech is to build a project that solves a recurring problem. Research shows that developers using AI agents to assist in their workflows can complete tasks 126% faster than those working manually.

For your first build, I recommend an Automated Newsletter Researcher. This is a project that actually saves you time. Instead of you spending thirty minutes every morning scouring the web for news, your agent does it for you.

The Tools of the Trade

You don’t need a heavy enterprise stack for this. Stick to the “minimalist” path to keep your code clean and easy to debug.

  • Python: The backbone of your script.

  • OpenAI Agents SDK: This is a lightweight toolkit released recently that focuses on simple agent-to-agent handoffs and tool use without the bloat of larger frameworks. It is currently the production leader in terms of adoption because of its stability.

  • Tavily: A search engine built specifically for AI agents that returns clean, LLM-ready content instead of messy HTML.

Automated newsletter researcher workflow

The Success Metric

Your project is “finished” when your agent can autonomously find three relevant articles on a specific topic, summarize them into three bullet points each, and save that summary to a local file without you touching your keyboard. This isn’t just a coding exercise. It is a functional piece of automation that delivers a measurable result. Early data from 2026 suggests that even simple personal automation projects like this can reclaim up to 20% of a professional’s daily schedule.

The Implementation

Here is a structured look at how you would set up the core logic for this researcher.

Python:

import os
# Assuming the use of a simplified Agents SDK pattern
from agents_sdk import Agent, Runner

# Step 1: Define the search tool
def search_the_web(query):
    # This would typically call the Tavily API
    # For this example, we return a mock list of data
    return [
        {"title": "AI Agents in 2026", "content": "Agents are now 40% of apps."},
        {"title": "Python vs Rust", "content": "Rust is gaining ground in AI."},
        {"title": "OpenAI SDK", "content": "Minimalism is the new standard."}
    ]
# Step 2: Create the Researcher Agent
researcher = Agent(
    name="News Scout",
    instructions="Find the top 3 news stories about AI Agents and summarize them.",
    tools=[search_the_web]
)
# Step 3: Run the workflow
def main():
    # The runner manages the 'Think-Act-Observe' loop automatically
    runner = Runner()
    print("Starting the research process...")

    result = runner.run(
        agent=researcher,
        user_input="What are the biggest trends in AI Agents this week?"
    )

    # Step 4: Save the output to a file
    with open("newsletter_draft.txt", "w") as f:
        f.write(result.output)

    print("Newsletter draft saved successfully.")
if __name__ == "__main__":
    main()

Code Explanation:

In this setup, we use a Runner object to handle the heavy lifting of the reasoning loop. The researcher agent is given a specific identity and a single tool: the search_the_web function. When the runner.run() command is executed, the AI realizes it doesn’t know the latest news. It triggers the search tool, observes the results we provided in the mock list, and then uses its internal logic to summarize those results. Finally, the script takes that summary and writes it to a physical file on your hard drive.

This project proves that you can bridge the gap between “chatting” and “doing.” Once you see that text file appear on your desktop, you have officially moved past the beginner phase.

Conclusion

The AI agent market is moving faster than the current talent pool can keep up. According to research from Research and Markets, the global AI agents market is expected to reach $12.06 billion by the end of 2026, representing a growth rate of 45.5% from the previous year. This growth is not just a theoretical spike. It is a direct result of companies moving away from simple chatbots toward autonomous systems that can actually finish complex work.

While roughly 62% of organizations are currently experimenting with these systems, only about 6% have managed to become “high performers” who are effectively scaling agents across their business. This creates a massive opening for anyone who can move past the beginner stage. Most people are still stuck in the cycle of just asking an AI for summaries. By building the single-tool and multi-agent projects we covered in this guide, you are positioning yourself in that top 6% of the workforce.

The reality of 2026 is that proficiency in building autonomous workflows is becoming a baseline requirement. Gartner suggests that by 2027, 75% of all hiring processes will include some form of certification or testing for workplace AI proficiency. The goal for you right now should not be to just use an agent. Your goal should be to understand how to build, maintain, and orchestrate them.

Do not wait for a perfect certification or a formal university course to tell you that you are ready. The hands-on experience of building a proof of concept is worth more than any theory you could read. Tools like the OpenAI SDK and Tavily have made the entry barrier lower than ever. Start with one tool, one logic loop, and one goal. The market is waiting for the people who actually know how to build the “hands” for the brain.

LinkedIn Uses 2.4 GB of RAM Across Two Tabs. We All Just Shrugged.

LinkedIn is using 2.4 GB of RAM across two tabs. Two tabs. Not twenty. Two.

A Hacker News thread over the weekend hit 600+ points as developers shared their horror stories. One person saw a single LinkedIn tab at 3.2 GB while every other tab sat under 200 MB. One watched its memory climb to 42 GB, traced to a third-party bot prevention service merrily running in the background.

And you know what? Nobody was surprised. That’s the problem.

We Have Normalized This

The median web page now ships 780 KB of JavaScript according to HTTP Archive data from February 2026. That’s up from 540 KB just a couple of years ago — a 44% increase. The median page itself weighs 2.2 MB and fires off 24 JavaScript requests before it even renders.

But it’s the edges that are truly absurd. One major news site was caught serving 49 MB of data for four headlines. That’s roughly the size of Windows 95. Loading it required 422 network requests and took two full minutes.

We Got Here on Purpose

This isn’t a bug. This is the natural result of every team shipping features without anyone asking “what does this cost the user?”

The Standish Group found that 64% of software features are rarely or never used. Pendo’s research puts it at 80%. Yet every one of those unused features still loads JavaScript, registers event listeners, and leaks memory.

Single-page architectures made it worse. SPAs front-load massive bundles, create labyrinthine state trees, and rarely clean up after themselves.

→ React components that don’t unmount properly
→ Timers that never get cleared
→ Caches that grow forever

We optimized for developer experience and shipping speed. The user’s browser got the bill.

The Part That Actually Hurts

Web bloat isn’t just annoying. According to HTTP Archive and the Web Sustainability Guidelines community, the internet produces roughly 1 billion tons of CO2 annually — on par with the global aviation industry. Data centers consumed 460 terawatt-hours in 2022 and projections point to 620–1,050 TWh by 2026.

For users on lower-end devices, some “simple” web pages now run worse than PUBG, according to a Tom’s Hardware analysis. That’s not a joke. A web page. Running worse than a battle royale game.

And for businesses, Google’s Core Web Vitals directly penalize bloated sites in search rankings. Every extra second of load time costs conversions.

The Web Used to Be Light

I remember when a 100 KB page was considered heavy. When developers debated whether to include jQuery because 30 KB felt like a lot.

Now we ship 780 KB of JavaScript as a baseline and call it “normal.” We build pages that need more RAM than desktop applications from five years ago. We treat performance optimization as a nice-to-have instead of a requirement.

LinkedIn isn’t the exception. It’s the norm. And that’s what should scare every developer reading this.

The question isn’t “why does LinkedIn use 2.4 GB of RAM?” It’s “why did we all decide that was acceptable?”

What’s the most bloated website you’ve dealt with, and did anything actually get done about it? 👇

When vector search isn’t enough: hybrid graph+vector queries in VelesQL

“Find me the documentation for the function that handles authentication.”

Sounds simple. Embed the question, run a similarity search, return the top results. Except here is what pure vector search actually returns:

[0.82] "Authentication is handled via JWT tokens with a 24h expiry."
[0.79] "The login() function validates user credentials against the database."
[0.71] "OAuth2 flow documentation for third-party integrations."
[0.68] "Password hashing uses bcrypt with a cost factor of 12."

All four results are about authentication. All four are semantically relevant. But none of them are the documentation for the actual function that handles it. The vector search found similar text, not the relationship between a function and its documentation.

This is the fundamental limitation of pure vector search: it matches meaning, not structure.

Why vectors alone fail on structured data

Vector embeddings capture semantic similarity. “Dog” is close to “puppy.” “Authentication” is close to “login.” That works great for finding documents about a topic.

But real-world data has structure. A codebase has files that contain functions. Functions call other functions. Documentation pages describe specific modules. Products belong to categories and have reviews written by users.

When you ask “find the docs for the auth handler,” you need two things:

  1. Semantic similarity to understand what “auth handler” means
  2. Graph traversal to follow the DOCUMENTS relationship from the function to its docs

Pure vector search gives you (1) but not (2). You get four results that talk about authentication, but you miss the one document that is structurally connected to the function you care about.

Modeling the problem as a graph

Let’s build a concrete example: a knowledge base about a codebase. We have three types of entities (functions, documentation pages, and modules) connected by relationships (DOCUMENTS, BELONGS_TO, CALLS).

import velesdb
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("all-MiniLM-L6-v2")

db = velesdb.Database("./codebase_kb")

# Vector collection for semantic search
collection = db.create_collection("entities", dimension=384, metric="cosine")

# Graph collection for relationships
graph = db.create_graph_collection("codebase_graph", dimension=384)

Now let’s populate it with entities. Each entity gets both a vector embedding (for similarity search) and a node in the graph (for traversal):

entities = [
    {"id": 1, "type": "function", "name": "handle_auth",
     "description": "Validates JWT tokens and returns user session"},
    {"id": 2, "type": "function", "name": "hash_password",
     "description": "Hashes passwords using bcrypt with configurable cost factor"},
    {"id": 3, "type": "function", "name": "login",
     "description": "Authenticates user credentials and issues JWT token"},
    {"id": 4, "type": "doc", "name": "auth-handler-guide",
     "description": "Complete guide to the authentication handler: configuration, middleware setup, and error codes"},
    {"id": 5, "type": "doc", "name": "oauth2-integration",
     "description": "OAuth2 flow documentation for third-party integrations"},
    {"id": 6, "type": "doc", "name": "password-security",
     "description": "Password hashing implementation details and security considerations"},
    {"id": 7, "type": "module", "name": "auth",
     "description": "Authentication and authorization module"},
    {"id": 8, "type": "doc", "name": "login-endpoint",
     "description": "API reference for the login endpoint with request and response examples"},
]

# Store vectors
points = []
for e in entities:
    embedding = model.encode(e["description"]).tolist()
    payload = {"type": e["type"], "name": e["name"], "description": e["description"]}
    points.append({"id": e["id"], "vector": embedding, "payload": payload})

collection.upsert(points)

# Store graph nodes
for e in entities:
    graph.store_node_payload(e["id"], {
        "name": e["name"],
        "type": e["type"],
    })

# Add relationships
edges = [
    {"id": 1, "source": 4, "target": 1, "label": "DOCUMENTS",
     "properties": {"scope": "full"}},
    {"id": 2, "source": 6, "target": 2, "label": "DOCUMENTS",
     "properties": {"scope": "full"}},
    {"id": 3, "source": 8, "target": 3, "label": "DOCUMENTS",
     "properties": {"scope": "api"}},
    {"id": 4, "source": 5, "target": 7, "label": "DOCUMENTS",
     "properties": {"scope": "integration"}},
    {"id": 5, "source": 1, "target": 7, "label": "BELONGS_TO",
     "properties": {}},
    {"id": 6, "source": 2, "target": 7, "label": "BELONGS_TO",
     "properties": {}},
    {"id": 7, "source": 3, "target": 7, "label": "BELONGS_TO",
     "properties": {}},
    {"id": 8, "source": 3, "target": 1, "label": "CALLS",
     "properties": {"context": "during login flow"}},
    {"id": 9, "source": 3, "target": 2, "label": "CALLS",
     "properties": {"context": "password verification"}},
]

for edge in edges:
    graph.add_edge(edge)

We now have 8 entities with embeddings and a graph of 9 relationships. This is a miniature version of what a real codebase knowledge graph looks like.

Pure vector search: the wrong answer

Let’s search for documentation about the authentication handler:

query = "documentation for the function that handles authentication"
query_vec = model.encode(query).tolist()

results = collection.query(
    "SELECT * FROM entities WHERE vector NEAR $v LIMIT 5",
    params={"v": query_vec}
)

print("=== Pure vector search ===")
for r in results:
    p = r["bindings"]
    print(f"  [{r['fused_score']:.3f}] ({p['type']}) {p['name']}: {p['description'][:60]}")
=== Pure vector search ===
  [0.724] (doc) auth-handler-guide: Complete guide to the authentication handler: configuration
  [0.691] (function) handle_auth: Validates JWT tokens and returns user session
  [0.654] (doc) oauth2-integration: OAuth2 flow documentation for third-party integrations
  [0.641] (function) login: Authenticates user credentials and issues JWT token
  [0.589] (doc) login-endpoint: API reference for the login endpoint with request and res

The correct answer (auth-handler-guide, which DOCUMENTS the handle_auth function) happens to rank first here. But notice the problem: the vector search has no idea why that document is relevant. It just matched on text similarity. The OAuth2 doc ranks third, even though it documents the auth module, not the auth function. And login ranks fourth despite being a different function entirely.

In a larger dataset with hundreds of entities, that lucky first-place ranking disappears fast.

Hybrid graph+vector: the right answer

Now let’s combine both signals. First, use vector search to find the function. Then, walk the graph to find its documentation:

# Step 1: find the function via vector search (filter by type)
func_results = collection.query(
    "SELECT * FROM entities WHERE vector NEAR $v AND type = 'function' LIMIT 1",
    params={"v": query_vec}
)

if func_results:
    func = func_results[0]
    func_id = func["id"]
    func_name = func["bindings"]["name"]
    print(f"Found function: {func_name} (score={func['fused_score']:.3f})")

    # Step 2: traverse graph to find documentation
    incoming = graph.get_incoming(func_id)
    docs = [e for e in incoming if e["label"] == "DOCUMENTS"]

    print(f"nDocumentation linked via graph:")
    for edge in docs:
        doc_node = graph.get_node_payload(edge["source"])
        print(f"  -> {doc_node['name']} (relationship: {edge['label']}, scope: {edge['properties']['scope']})")
Found function: handle_auth (score=0.691)

Documentation linked via graph:
  -> auth-handler-guide (relationship: DOCUMENTS, scope: full)

One result. The right result. No ambiguity.

The vector search found the function (“handle_auth” is semantically closest to “function that handles authentication”). The graph traversal followed the DOCUMENTS edge to find the exact documentation page.

Going deeper: multi-hop traversal

The graph lets you answer questions that are impossible with pure vector search. For example: “What functions does login call, and what are their docs?”

# Find login function
login_results = collection.query(
    "SELECT * FROM entities WHERE vector NEAR $v AND name = 'login' LIMIT 1",
    params={"v": model.encode("login function").tolist()}
)

login_id = login_results[0]["id"]

# Hop 1: what does login() call?
calls = graph.get_outgoing(login_id)
call_edges = [e for e in calls if e["label"] == "CALLS"]

print("login() calls:")
for edge in call_edges:
    target = graph.get_node_payload(edge["target"])
    print(f"  -> {target['name']} ({edge['properties']['context']})")

    # Hop 2: get documentation for each called function
    incoming = graph.get_incoming(edge["target"])
    doc_edges = [e for e in incoming if e["label"] == "DOCUMENTS"]
    for doc_edge in doc_edges:
        doc = graph.get_node_payload(doc_edge["source"])
        print(f"     docs: {doc['name']}")
login() calls:
  -> handle_auth (during login flow)
     docs: auth-handler-guide
  -> hash_password (password verification)
     docs: password-security

Two hops. Starting from a semantic query (“login function”), the system found the function, walked its CALLS edges, then walked DOCUMENTS edges for each callee. This is the kind of structural reasoning that pure vector search simply cannot do.

Side-by-side comparison

Question Pure vector search Graph+vector hybrid
“docs for auth handler” Returns 5 auth-related results ranked by text similarity Returns exactly the doc linked to handle_auth
“what does login call?” Cannot answer (no relationship data) handle_auth, hash_password
“all docs in auth module” Fuzzy matches on “auth” keyword Traverses BELONGS_TO + DOCUMENTS edges precisely
“functions with no documentation” Cannot answer Query for nodes with no incoming DOCUMENTS edge

When to use what: a decision guide

Pure vector search works well when:

  • Your data is flat (documents, paragraphs, FAQ entries)
  • Relationships between items don’t matter for retrieval quality
  • You need speed over precision (vector search is O(log n) with HNSW)

Graph+vector hybrid is the right choice when:

  • Your data has meaningful relationships (code dependencies, org charts, knowledge graphs)
  • The answer depends on following connections, not just matching text
  • You need to combine “find something similar” with “follow its relationships”
  • You are building a GraphRAG pipeline that reasons over structured knowledge

The rule of thumb: if you catch yourself writing post-processing code to filter or re-rank vector results based on relationships, you need a graph.

Getting started

pip install velesdb sentence-transformers

The full example from this article runs in under 2 seconds on a laptop. No Docker, no API keys, no cloud. VelesDB is a source-available (Elastic License 2.0) embedded database that combines vector, graph, and columnar storage in a single ~6MB binary.

GitHub: github.com/cyberlife-coder/VelesDB
Docs: velesdb.com/en
Previous article in this series: VelesQL: one query language for vectors, text, and filters

What’s your experience with GraphRAG? Are you gluing together separate vector and graph databases, or have you found a single-engine approach that works? I’d love to hear what patterns are working in production.

# The 5 memory problems for agents

You ship an agent. It works well in the demo. Users start using it daily. After a week, someone asks: “Why did you suggest the same thing you suggested on Monday? I told you that didn’t work.”

Your agent has no answer because it has no memory of Monday. Or worse, it has a memory of Monday but no idea that Monday’s approach failed.

This is the problem that shows up in every long-running agent system, and it is not a retrieval problem. Your vector search works fine. Your RAG pipeline returns relevant context. The problem is upstream of retrieval: your agent stores facts but does not learn from outcomes. It records what happened without recording whether it worked.

The research has a name for this gap. Hu et al.’s survey on agent memory identifies three functional categories: factual memory (what the agent knows), experiential memory (how the agent improves from past actions), and working memory (what the agent is thinking about right now). Most production agent systems implement factual memory. Almost none implement experiential memory. And experiential memory is where the leverage is for agents that operate over more than a single session.

the five things that break

After building and watching others build agent memory systems, the same five failure modes keep showing up. They are not obvious at first. They emerge over weeks of usage.

1. the contradiction problem

Your agent stores “Alice lives in London” on day one. On day fourteen, it stores “Alice lives in Berlin.” Now there are two facts in the memory store. Which one does retrieval return?

If you are lucky, the more recent one. If you are unlucky, whichever one has a higher similarity score to the current query. If Alice’s London fact was stored with richer context and more entity connections, it might actually rank higher than the Berlin fact even though it is stale.

The standard fix is to add a created_at timestamp and bias retrieval toward recency. This helps. But it does not solve the underlying problem: your memory store has no concept of a fact replacing another fact. It has two independent entries that happen to be about the same thing. The relationship between them (one supersedes the other) exists only in the real world, not in your data.

What you actually need is for the system to know that “Alice lives in Berlin” invalidated “Alice lives in London.” Not as a heuristic. As a structural property of how the data is stored. The old fact should carry a timestamp marking when it stopped being true. The new fact should be linked to what it replaced. Queries should return the currently valid fact by default, with the full history available when you ask for it.

This is what bi-temporal storage does. Every fact carries a valid_from and valid_until. When a new fact supersedes an old one, the old fact’s valid_until gets stamped. The new fact opens with valid_until = None (still active). You do not build this logic in application code. The database handles succession.

2. the “what did we know when” problem

Your agent makes a recommendation on March 10th. On March 15th, new information arrives that changes the picture. A user asks: “Why did you recommend that on March 10th?”

To answer this, your agent needs to reconstruct what it believed on March 10th. Not what is true now. What the system knew then.

This is the difference between valid-time (when was the fact true in the real world?) and transaction-time (when did the database learn about it?). Most memory systems track neither properly. Some track when a fact was stored. Almost none track when a fact became true independently of when it was recorded.

A user might tell your agent on March 15th that they moved to Berlin on March 1st. The valid-time is March 1st. The transaction-time is March 15th. If someone queries the system as of March 10th, the correct answer depends on which clock you are asking about. “What was true on March 10th?” returns Berlin (valid-time). “What did we know on March 10th?” returns London (transaction-time, because the system had not learned about the move yet).

Audit trails, debugging agent decisions, and understanding why your agent behaved the way it did all require both clocks. One timestamp column does not cut it.

3. the “it happened at the same time” problem

Alice changed jobs and cities in the same month. Your agent knows both facts independently. But it has no way to connect them temporally. It cannot answer “did those changes happen at the same time?” because its memory has no concept of temporal intervals, let alone relationships between intervals.

This matters more than it might seem. Temporal co-occurrence is how humans detect patterns: “every time we deploy on Friday, something breaks over the weekend” is a temporal pattern. “The user’s engagement dropped when we changed the pricing model” is a temporal correlation. Agents that operate in domains with temporal structure (which is most domains) need to reason about how time periods relate to each other.

Allen’s Interval Algebra defines 13 relationships between two time intervals: before, after, meets, overlaps, starts, finishes, equals, and their inverses. If your memory system stores facts with proper valid-time intervals, these relationships become queryable. “Find all cases where one relationship ended exactly as another began” is a query, not an application-level computation.

4. the “every session starts from zero” problem

Your agent debugged a tricky authentication issue last week. It tried three approaches, two failed, one worked. This week, a similar issue comes up. The agent starts from scratch.

This is the experiential memory gap. The agent stored facts about last week’s session (what was tried, what error messages appeared). But it never synthesized those facts into a lesson: “For auth issues in this codebase, check the token expiry configuration first. Retry logic is usually a red herring.”

The research describes experiential memory at four levels of abstraction:

Case-based: Store the raw trajectory. What happened, step by step. High fidelity but expensive to retrieve and hard to generalize from.

Strategy-based: Distill the trajectory into insights. “When X happens, do Y because Z.” Transfers across tasks. This is where the leverage is.

Skill-based: Compile strategies into executable code. The agent writes reusable tools for itself.

Hybrid: Maintain multiple levels simultaneously.

Most systems that attempt experiential memory stop at case-based. They store conversation logs or event histories and hope that retrieval will surface the right past experience when a similar situation arises. This works sometimes. It fails when the current situation is similar in intent but different in surface details, because the embeddings do not match well enough.

What you need is a system that automatically compresses raw experiences into generalized insights. Not “here is what happened last Tuesday” but “here is what we have learned from the last ten Tuesdays.”

5. the stale confidence problem

Your agent stored a strategy six months ago: “Use approach X for deployment issues.” At the time, it had worked three times out of three. Confidence was high.

Since then, the codebase has changed. Approach X has failed twice. But the original memory still has high confidence because nothing in the system updates confidence based on new outcomes.

This is subtler than the contradiction problem. The fact is not wrong. It is not superseded by a new fact. Its reliability has just degraded over time as conditions changed. Your memory store has no way to express this unless you build outcome tracking into the memory entries themselves.

What you need is for memory strength to adjust based on evidence. When an approach succeeds, the associated memory should strengthen. When it fails, it should weaken. The scoring should handle both early uncertainty (few data points) and distribution shift (what used to work no longer does).

6. the multi-hop problem

A user asks your agent: “What API does our project use that’s built by the company Steve used to work at?”

No single fact in the memory store answers this. The answer requires chaining through multiple entries: Steve’s employment history leads to the company. The company’s products lead to the API. The project’s dependencies lead back to the same API. Three hops through connected facts.

Flat memory stores handle this terribly. Vector similarity retrieval looks for entries that match the question. But the question mentions Steve, a company, and an API in the same breath, and no single stored fact connects all three. You can try query expansion, generating multiple related queries and merging results. But expansion can only rephrase what is already in the question. It cannot discover connected entities that exist only in the memory store. If the user does not mention the company by name, query expansion cannot find it.

The research is clear on this: for genuine multi-hop queries where the connecting entities are not in the question, you have two reliable options. Let the agent loop (iterative retrieval, calling the search tool multiple times) or build structural connections (a knowledge graph with traversable edges).

Iterative retrieval works but is slow and unpredictable. The agent has to guess what to search for next. It might take two hops or twelve. It might go in circles. And the more hops required, the more likely the chain breaks.

A knowledge graph solves this structurally. The edges exist. The traversal follows them. “Start at Steve, follow worked_at edges to find the company, follow builds edges to find their products, check which product matches the project’s dependencies.” That is a graph pattern, not a search query:

MATCH (steve:Person {name: "Steve"})-[:worked_at]->(company)
      -[:builds]->(api)<-[:depends_on]-(project)
RETURN api.name, company.name

One query. Deterministic. No iterative guessing. And because edges in MinnsDB are temporal, you can ask the time-aware version: “What API does our project use that is built by the company Steve currently works at?” versus “…used to work at?” The WHEN clause distinguishes between active and historical edges.

This is why the topology of your memory matters. Flat (1D) memory with vector search handles single-hop factual lookups well. But the questions agents actually need to answer in practice are often multi-hop. “What do we know about the context around this error?” is multi-hop. “What changed in this user’s situation recently?” is multi-hop. “Has this approach worked before in similar circumstances?” is multi-hop with a temporal dimension.

The research recommends starting flat and moving to graphs when you observe specific retrieval failures. In our experience, those failures show up faster than you expect. As soon as your agent operates over a domain with relationships between entities (which is most domains), multi-hop queries become the norm, not the exception.

what these problems have in common

All six problems share a root cause: the memory system does not model time and structure as first-class dimensions.

The contradiction problem is a temporal succession problem. The audit problem requires two independent time axes. The co-occurrence problem requires temporal intervals with algebraic relationships. The experience problem requires temporal segmentation and consolidation over time. The confidence problem requires outcome tracking that evolves over time. The multi-hop problem requires structural connections between facts, with temporal awareness of which connections are currently valid.

A key-value store with vector search does not solve any of these. A relational database with a created_at column solves the first one partially and the rest not at all. A knowledge graph without temporal edges solves the multi-hop problem but leaves temporal reasoning to application code.

The insight we built MinnsDB around is that agent memory is fundamentally a temporal and structural problem. Not a storage problem. Not a retrieval problem. If your storage layer understands time and relationships, all six failure modes have clean solutions. If it does not, you end up building increasingly complex application logic to paper over the gaps.

how temporal storage addresses each one

Contradictions. Every edge carries valid_from and valid_until. When “Alice lives in Berlin” is recorded, the system checks the ontology: location:lives_in is a functional property (single-valued). The existing London edge gets its valid_until stamped. The Berlin edge opens as active. No application code. The property type defines the succession behavior.

Audit and reconstruction. Every edge also carries created_at (transaction-time). The WHEN clause filters on valid-time. The AS OF clause filters on transaction-time. Compose them:

MATCH (a:Person)-[r:lives_in]->(city)
WHEN ALL AS OF "2024-03-10T00:00:00Z"
WHERE a.name = "Alice"
RETURN city.name, valid_from(r), valid_until(r)

This reconstructs the database’s state as it was known on March 10th, showing all historical validity intervals. You can audit any past decision.

Temporal co-occurrence. Allen’s Interval Algebra as query predicates:

MATCH (a)-[r1]->(b), (a)-[r2]->(c)
WHEN ALL
WHERE meets(r1, r2)
RETURN a.name, type(r1), type(r2)

“Find all cases where one fact about a person ended exactly as another began.” No application logic. A query.

Experience consolidation. The episode detector segments the event stream into coherent experiences. The consolidation engine compresses episodic memories into semantic memories (generalized patterns) and then into schema memories (reusable mental models). Three deployments that all required a migration step become the insight: “deployments in this repo usually need a migration.” This runs automatically with configurable thresholds.

Confidence evolution. Each memory tracks outcome counts. Scoring transitions from a Bayesian prior (stable with few data points) to an exponential moving average (responsive to distribution shift as evidence accumulates). Memory strength adjusts based on whether the associated approaches keep succeeding or start failing.

Multi-hop queries. The knowledge graph makes entity relationships traversable. Variable-length paths (-[*1..3]->) handle cases where you do not know the exact number of hops. Because edges carry temporal validity, you can traverse only currently active relationships, or include historical ones, depending on the query. The graph executor handles this with bounded BFS (capped at 10,000 visited nodes per source) and a 30-second query deadline. Multi-hop questions become graph patterns, not iterative search loops.

the developer experience

We think about this from the perspective of an engineer building an agent. You should not need to build temporal succession logic. You should not need to implement your own versioning system. You should not need to write consolidation pipelines or outcome trackers.

You should write events into the system and query it. The temporal modeling, the succession, the episode detection, the consolidation: those are the database’s job.

Events go in through the API. State changes, transactions, conversations, observations. The pipeline extracts claims, builds graph edges, detects episodes, forms memories, and consolidates over time. You query with MinnsQL (graph patterns and table queries in one language) or natural language. You subscribe to live queries and get deltas pushed when things change.

-- What does the agent know right now?
MATCH (a:Person)-[r:lives_in]->(city)
WHERE a.name = "Alice"
RETURN city.name

-- What changed in the last week?
MATCH (a:Person)-[r]->(b)
WHERE CHANGED(r, ago("7d"), now())
RETURN a.name, type(r), b.name, change_type(r, ago("7d"), now())

-- What was true six months ago?
MATCH (a:Person)-[r:works_at]->(company)
WHEN "2024-09-15"
WHERE a.name = "Alice"
RETURN company.name

-- Subscribe to changes in real time
SUBSCRIBE MATCH (a:Agent)-[r:KNOWS]->(b:Agent)
RETURN a.name, b.name, r.confidence

The temporal clauses, the change detection, the subscriptions: these are not features you bolt on. They work because time is built into the storage layer from the ground up.

what this is not

MinnsDB is not a general-purpose database. It does not replace Postgres for your application’s primary data store. It is not trying to be a vector database or an LLM framework.

It is a database built specifically for the temporal memory problems that agents face. If your agent needs to store facts that change over time, learn from its own experiences, maintain audit trails of what it knew and when, and react to changes as they happen, those are the problems this solves.

If your agent just needs to store and retrieve static facts, a simpler solution works fine. The complexity of temporal storage pays off when your agent operates over time. When sessions span days and weeks. When facts change, the agent needs to know what changed and when. When raw experience should be compressed into knowledge.

Most agents today do not operate this way. But the ones that will matter in six months do.

Try https://minns.ai, the agentic database built for temporal memory.