Jaguar Land Rover ve Chery’den yeni marka: “Freelander”

Freelander

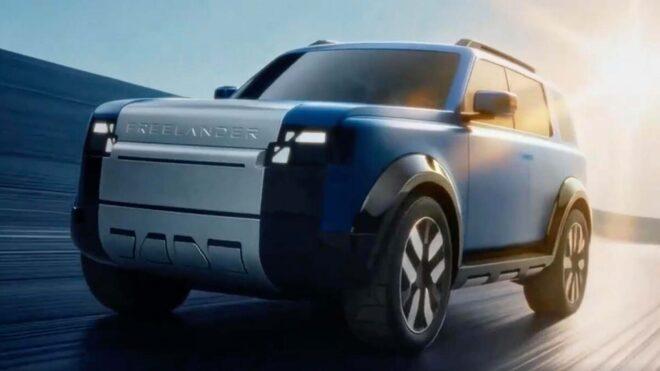
FreelanderJaguar Land Rover (JLR) ve Çinli otomobil devi Chery, “Freelander” markasını ve markanın çıkış aracını görücüye çıkardı. İlk aşamada Çin’de, daha sonra ise Avrupa’daki belirli pazarlarda satılacak araç, tamamen elektrikli ve hibrit tahrik sistemlerini temel alan yeni 800 voltluk mimari üzerine kuruluyor. Dikkat çekici bir tasarıma sahip olan 4×4 arazi aracı, yapılan açıklamaya göre JLR-Chery’nin Çin’deki Changshu fabrikasında Land Rover Discovery Sport ve Range Rover Evoque’un yerini alacak. Bugün itibarıyla son içten yanmalı Evoque’un üretimini tamamlayan fabrikada artık bu yeni model üretilecek. Tüm detayları önümüzdeki hafta paylaşılacak model, paylaşılan ilk görsellere bakılırsa “B” sütunu olmadan geliyor ve arka kapısı terse açılıyor. Freelander CEO’su Wei Lan, markanın önümüzdeki beş yıl boyunca pazara her altı ayda bir yeni otomobili sürmeyi planladığını aktarıyor.

Jaguar Land Rover ve Chery’den yeni marka: “Freelander” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

The WooCommerce UCP Guide: What Our Monitoring Data Reveals About WordPress Agent Commerce

WooCommerce UCP Architecture — how AI agents connect through the WordPress plugin layer

WooCommerce UCP adoption is in its very early stages. Our current monitoring dataset includes just 3 verified WooCommerce stores — a small fraction of the broader UCP ecosystem, where Shopify accounts for over 99% of verified merchants. Even with a limited dataset, the patterns we see are consistent with what you’d expect from WordPress-based infrastructure: more configuration complexity, more hosting variability, and more ways for things to silently break.

WooCommerce powers somewhere between 25% and 30% of all e-commerce stores globally, and WordPress’s plugin ecosystem means a UCP implementation can ship as a drop-in extension without Automattic needing to build it into core. That’s exactly the path adoption has started to take — but it’s early, and the infrastructure complexity means getting it right requires more deliberate effort than on managed platforms.

The picture is more complicated than Shopify. WooCommerce gives merchants complete control over their UCP implementation, which means more configuration flexibility — and far more ways to misconfigure it. This guide covers what we’ve learned monitoring WordPress-based stores: what you need to install and configure, what the manifests actually look like across our dataset, and what breaks in production agent sessions.

WooCommerce UCP Architecture — how AI agents connect through the WordPress plugin layer

What WooCommerce Requires (vs. What Shopify Provides Natively)

The first thing to understand about WooCommerce UCP is that nothing is automatic. Where Shopify generates and serves a UCP manifest the moment you install the Universal Commerce Agent app, WooCommerce requires a dedicated WordPress plugin that you install, configure, and maintain separately from your store.

The plugin handles three things: serving the /.well-known/ucp manifest file, registering a REST API endpoint that acts as your MCP transport, and exposing your WooCommerce product catalog, cart, and checkout flows as MCP tools.

The most established option we’ve validated in our testing is UCPReady by Zologic, which handles manifest generation, MCP transport, and automatic capability detection.

The installation process is straightforward — activate the plugin, generate your manifest keys, configure your capabilities. What catches merchants is everything after that: cache invalidation, security plugin whitelisting, PHP memory allocation, and making sure your REST API is actually accessible to external agents. Each of these is a WordPress infrastructure concern, not a WooCommerce one, which means the troubleshooting surface is larger than on managed platforms.

There is also no equivalent to Shopify’s automatic manifest updates when your payment stack changes. On WooCommerce, if you add a new payment gateway — WooCommerce supports over 100 via extensions — your manifest doesn’t automatically reflect the change. You need to resync it manually or configure the plugin to auto-regenerate on gateway change. We flag stale payment handler declarations in our monitoring data, and WooCommerce stores — given the manual update requirement — are more prone to this issue than Shopify stores.

The Manifest: What We See Across Our WooCommerce Dataset

Your UCP manifest is the JSON document at /.well-known/ucp that tells AI agents what your store supports and how to connect to it. On WooCommerce, this file is generated by the plugin and cached — how it is cached, and when that cache is invalidated, is one of the most consequential decisions in your setup.

The first thing we check is whether the manifest is reachable at all. A common issue on WooCommerce stores is the manifest returning a 404 or a cached HTML error page instead of valid JSON. This almost always traces to a caching plugin that has cached the /.well-known/ path as a static HTML page, or a security plugin that blocks direct file access to that path. Both are fixable but require explicit configuration.

The second is the protocol version. WooCommerce UCP deployments show more version fragmentation than Shopify, because plugin updates are not as seamless as platform updates. We see a meaningful share of WooCommerce stores still on 2026-01-11, and a small number on pre-release configurations that declare non-standard version strings. Agents with strict version negotiation will refuse to interact with these stores entirely.

Third is the capabilities array. A properly configured WooCommerce store should declare dev.ucp.shopping.checkout, dev.ucp.shopping.discovery, and — if configured — dev.ucp.shopping.discount. The discount capability is the most variable: WooCommerce handles discounts through a combination of coupon codes, cart rules, and extension-specific logic that doesn’t always map cleanly to the UCP discount model. Many stores declare it in the manifest but the actual MCP tool implementation is incomplete.

Fourth is the transports block. WooCommerce stores declare MCP over the WordPress REST API, typically at a path like /wp-json/ucp/v1/mcp. This is correct, but the REST API endpoint must be explicitly whitelisted in your security configuration. We see a significant share of WooCommerce stores where the manifest correctly declares the MCP transport but the endpoint itself returns a 401 or 403 for unauthenticated requests — which is what most agent clients send for initial tool discovery.

Common Manifest Issues We Flag

The most frequently flagged issues across our WooCommerce monitoring dataset: cached manifest serving stale content (the manifest was generated before a configuration change and the cache has not been busted), payment handlers out of sync (a gateway was added or removed without a manifest resync), REST API endpoint blocked (a security plugin or WAF rule is returning a non-JSON response to agent requests), and capabilities declared but not implemented (the discount tool is listed in the manifest but the endpoint returns an error when an agent calls it).

None of these cause a hard failure on a basic manifest fetch. A checker that only validates whether the JSON is well-formed will pass these stores. Our checks simulate what an agent actually does — fetch the manifest, enumerate the tools, call the endpoint — which is why we catch issues that a simple validation pass misses.

Runtime Performance: Hosting Matters Enormously

This is the biggest difference between WooCommerce and Shopify from a performance standpoint: on Shopify, your store runs on Shopify’s global infrastructure. On WooCommerce, your store runs on whatever you chose to host it on — and the performance range is enormous.

WooCommerce MCP response times by hosting type — shared hosting vs VPS vs managed WordPress

Across the WooCommerce stores in our dataset, MCP tool call response times ranged from 510ms to 1,593ms, with an average around 980ms — significantly slower than Shopify’s median of 146ms. Our sample is small, but this is consistent with what you’d expect from PHP-based self-hosted infrastructure. The spread in practice is likely much wider: well-configured managed WordPress hosts (WP Engine, Kinsta, Flywheel) can achieve sub-500ms response times, while stores on shared hosting with cold PHP processes can see latency well above 3 seconds.

Most agent frameworks have configurable timeouts, typically defaulting between 5 and 10 seconds. A store that responds in 4 seconds most of the time will occasionally spike to 8+ seconds when the PHP process is cold or the server is under load — and those spikes cause agent session failures that look like UCP implementation errors rather than hosting issues. The manifest validates fine, but the store cannot complete a real session reliably.

Specific hosting-related issues we flag frequently: PHP-FPM cold start latency on servers where PHP processes idle between requests (common on lower-tier shared hosting); object cache not configured (WooCommerce makes a large number of database queries per request — without Redis or Memcached, product catalog responses will be slow); and opcode cache absent (WooCommerce’s PHP footprint is substantial — OPcache is essential for acceptable performance and is missing on a surprising share of self-managed servers we monitor).

If you are on shared hosting and considering WooCommerce UCP, the performance characteristics alone are likely to produce poor agent experiences. Managed WordPress hosting starts at around $25–35/month and typically delivers 5–10× better MCP response times than budget shared hosting.

Configuration Checklist

Based on our monitoring data, here are the five configuration steps that separate WooCommerce stores that perform well in agent sessions from those that pass a manifest check but fail in production.

First, install and fully configure the WooCommerce UCP plugin. Do not stop at activation — complete the key generation step, review the capabilities configuration, and use the plugin’s built-in test to verify the manifest and MCP endpoint are both returning valid responses. Partial configurations are the most common source of manifest issues we see in WooCommerce stores.

Second, whitelist the UCP manifest and MCP endpoint in your caching and security plugins. Add /.well-known/ucp to your caching plugin’s exclusion list — agents need the current version on every request, not a cached copy. Add your MCP REST API path to your security plugin’s whitelist so it returns JSON, not a block page. This step is specific to WordPress and has no equivalent in managed platform setups.

Third, verify your store at ucpchecker.com/check. Run the check, but specifically look at whether the MCP endpoint is reachable and returning valid responses — not just whether the manifest JSON is well-formed. We check both, and MCP endpoint reachability failure is far more common on WooCommerce than on any other platform we monitor.

Fourth, configure a persistent object cache. WooCommerce’s database query load under agent traffic is significant — agents make tool calls in rapid succession, and without Redis or Memcached, each call triggers a full set of database queries. Most managed WordPress hosts include Redis as a one-click option; on self-managed servers, the Redis Object Cache plugin plus a running Redis server is the standard configuration.

Fifth, set up UCP Alerts. Plugin updates, security plugin config changes, and WordPress core updates can all affect your UCP configuration without any explicit notification. We have seen stores where a security plugin update changed the response format on the MCP endpoint and the merchant did not know for days. Alerts catch these changes the next time we check your store.

Plugin Compatibility: The WordPress Ecosystem Challenge

WooCommerce’s power comes from its plugin ecosystem — there are over 900 extensions on the WooCommerce Marketplace alone, plus thousands more on WordPress.org and third-party marketplaces. That ecosystem is also the primary source of UCP compatibility issues we see.

The highest-risk category is security and firewall plugins. Wordfence, iThemes Security, Sucuri, and similar plugins use aggressive bot-blocking rules that frequently misclassify AI agent requests. UCP agents typically identify themselves with specific user-agent strings; if your security plugin is configured to block non-browser user agents, it will block agent traffic before it ever reaches your UCP implementation. We see this as a 403 response on the MCP endpoint — the manifest is reachable, but actual agent sessions are blocked.

The second category is caching plugins. WP Super Cache, W3 Total Cache, WP Rocket, and LiteSpeed Cache all have different approaches to caching REST API responses. By default, some of them cache the MCP endpoint — which means agents receive a cached response from a previous session, including potentially stale cart or product data. Your MCP endpoint must return fresh responses on every request, which means explicitly excluding it from caching at both the plugin and server levels.

Third is checkout customization plugins. WooCommerce Checkout Field Editor, WooCommerce One Page Checkout, and similar plugins modify the checkout flow in ways the MCP checkout tool does not know about. A mandatory custom field that requires input before checkout can proceed will silently fail agent checkout attempts — the agent calls the checkout tool, server-side validation rejects it because the custom field is empty, and the response is an error the agent typically cannot resolve.

Fourth, for merchants using multi-currency or multi-language plugins (WPML, WooCommerce Multilingual, Currency Switcher), these add complexity with no equivalent on Shopify Markets. There is no standard way for a WooCommerce store to declare multi-currency support in its UCP manifest, which means agents accessing your store from different geographic contexts may get different pricing without the manifest indicating that variation exists.

Common Failure Modes

Common WooCommerce UCP failure modes — cache conflicts, security blocks, PHP limits, REST API disabled

Five failure patterns come up repeatedly across our WooCommerce monitoring data.

Caching plugin serving stale MCP responses. An agent requests the tools list and receives a cached response from a previous session — one that might include products now out of stock, prices that have been updated, or a cart session belonging to a different user. This is the most WooCommerce-specific failure mode we see and it is entirely a configuration issue, not a UCP implementation problem. The fix is always the same: explicitly exclude your MCP endpoint path from caching at every level (plugin, server, CDN).

Security plugin blocking agent user agents. The agent makes a request to the MCP endpoint and receives a 403 or a redirect to a CAPTCHA page. From the manifest perspective, everything looks fine. From the agent’s perspective, the store is inaccessible. We detect this during our endpoint reachability checks. The fix requires explicitly whitelisting UCP agent user-agent strings in your security plugin’s bot management configuration.

PHP memory exhaustion on large catalogs. WooCommerce stores with large catalogs (10,000+ SKUs) frequently hit PHP memory limits when the MCP discovery tool attempts to enumerate products. The default PHP memory limit on many hosts is 256MB — inadequate for large WooCommerce queries under agent access patterns. We see this as timeouts or 500 errors on the discovery tool while other tools work fine. Setting WP_MEMORY_LIMIT to 512M or higher and ensuring your PHP-FPM pool has sufficient memory allocation resolves it in most cases.

Payment gateway plugin conflicts at checkout. WooCommerce’s checkout flow is highly extensible — and that extensibility means payment plugins can add hooks that interfere with the MCP checkout tool’s assumptions about what happens at payment initiation. We have seen stores where a payment gateway plugin redirects to an external payment page the agent cannot follow, causing the session to terminate after cart completion but before payment. Test your specific gateway configuration explicitly with agent sessions before going live.

Variable product variant ID instability. On WooCommerce, variation IDs can change when products are edited, reimported, or synced from an external system like an ERP or inventory platform. Agents that cache a variation ID for a specific product configuration may find that ID invalid the next time they try to add it to a cart, because the variation was recreated with a new ID. For stores that use bulk product management or external sync tools, this is a persistent issue. SKU-based addressing where possible, and avoiding unnecessary variation recreation, significantly improve agent session reliability.

Product Feed Best Practices for WooCommerce

WooCommerce product data quality is more variable than Shopify’s because it is entirely merchant-managed. There is no platform-level enforcement of required fields, no structured data template, and no automatic format normalization. What agents see when they call the discovery tool depends entirely on how well your product catalog is maintained.

Variable products need complete, consistent attribute sets. WooCommerce’s variable product model lets you define any attributes you want as variation axes. But it does not enforce completeness. If some variations are missing attribute values — a color variation without a size, or a size variation with no price set — agents may discover the product but fail to add a specific variant to cart. Audit your variable products for incomplete variations before enabling UCP.

Custom fields require explicit plugin support. Many WooCommerce stores use Advanced Custom Fields (ACF), Meta Box, or WooCommerce’s own custom product tabs to store additional product data. By default, none of this data is exposed through the MCP discovery tool — the UCP plugin has to explicitly include it in the MCP product response. If your products have custom fields essential for purchasing decisions (technical specifications, compatibility matrices, bulk pricing tiers), verify your UCP plugin is configured to include them in discovery responses.

Set explicit currency on all prices. WooCommerce’s default product data model stores prices as raw numbers without currency. The currency is typically declared at the store level, but stores using multi-currency plugins may serve prices in different currencies for different contexts. Ensure your UCP plugin serializes prices with explicit currency codes — not just numeric values — in every product response. Agents guessing currency from context produce wrong price displays.

Stock status must be accurate and real-time. WooCommerce stock management is excellent when configured correctly, but many stores have products set to “In Stock” without managing actual inventory quantities. When an agent discovers a product, adds it to cart, and then hits an out-of-stock error at checkout, the session fails. Enable proper stock quantity management and ensure your stock sync — especially if you use a third-party inventory system — is near-real-time.

SKUs should be present, stable, and unique. WooCommerce SKUs are optional. Many stores, especially smaller ones, do not set them. But SKUs are the most reliable way for agents to reference specific products and variations across sessions — they are more stable than variation IDs and more portable than internal WooCommerce post IDs. Setting SKUs on all products and variations, and keeping them stable across product updates, is one of the highest-leverage improvements for agent session reliability.

Product descriptions should be agent-parseable. WooCommerce product descriptions are free-form HTML — great for human-readable storefront pages, but problematic for agents. The short description field (the excerpt) is typically what MCP discovery tools expose as the primary product description. Keep it clean, text-based, and specific to what an agent needs to understand about the product. Avoid shortcodes, embedded tables, or JavaScript-dependent content in the short description.

Structured data for web-crawling agents. Some agents discover products through web crawling before connecting via MCP. WooCommerce stores using Yoast WooCommerce SEO or Rank Math get reasonable schema.org/Product markup automatically. Verify your storefront product pages include at minimum: name, description, price with currency, availability, brand, SKU, and image. This creates a secondary discovery path for agents that do not connect via MCP directly.

What’s Coming

Two developments in the WooCommerce UCP ecosystem are worth watching in 2026.

The first is first-party plugin support from Automattic. The current WooCommerce UCP implementation is third-party. As WooCommerce’s UCP install base grows, there is meaningful pressure on Automattic to build UCP support directly into WooCommerce core or develop an official first-party plugin with automatic manifest updates on gateway and catalog changes. A first-party implementation would dramatically reduce the configuration burden and plugin compatibility surface we currently see across our monitoring dataset.

The second is better persistent identity support for logged-in WooCommerce customers. The current MCP authentication model does not leverage WordPress’s native user session infrastructure well — most agent sessions are unauthenticated, which means agents cannot access customer-specific pricing, loyalty balances, or saved addresses. As the UCP spec’s identity linking capability matures, WooCommerce stores with rich customer profiles stand to gain significantly from authenticated agent sessions that can personalize the shopping experience.

We track WooCommerce adoption trends through our stats dashboard and break down platform-by-platform analysis in the State of Agentic Commerce reports.

Check Your Store

If you are running a WooCommerce store and have not run a UCP check yet, start here. The check takes about 30 seconds and covers both manifest validity and MCP endpoint reachability — the two most common failure points on WordPress-based stores.

If you are already listed in our directory, set up UCP Alerts so you are notified when your configuration changes. A WordPress plugin update, security plugin tweak, or caching config change can silently break your UCP implementation. Alerts catch it before an agent session fails.

And if you want to see exactly how AI agents experience your WooCommerce store — variant resolution, cart building, checkout completion — UCP Playground runs real agent sessions against live stores. It is the fastest way to find the configuration issues that do not show up in manifest validation but break real transactions.

References & Official Resources

Further Reading

Related Platform Guides

Exploring UCP across other platforms? These guides cover what we’ve learned about each platform’s implementation:

How I Made Claude Code and GPT-5.4 Review Each Other’s Code

The Problem: Same Model Writes and Reviews

When Claude Code writes code and Claude reviews it, you get the AI equivalent of grading your own homework. Blind spots survive.

I wanted GPT-5.4 to review Claude’s code from a genuinely different perspective. So I built helix-codex — an MCP server that bridges Claude Code (Opus 4.6) to Codex CLI (GPT-5.4).

What Makes It Different

There are 6+ Codex MCP bridges on GitHub. They all do the same thing: call codex exec, return raw text. Claude has no idea what happened inside.

helix-codex parses the entire JSONL event stream and returns a structured report:

[Codex gpt-5.4] Completed

⏱ Execution time: 8.3s
🧵 Thread: 019d436e-4c39-...

📦 Tools used (3):
  ✅ read_file — src/auth.py
  ✅ edit_file — src/auth.py
  ✅ shell — python -m pytest tests/

📁 Files touched (1):
  • src/auth.py

━━━ Codex Response ━━━
Fixed the authentication logic.

The Self-Review Experiment

The most interesting test: I had GPT-5.4 review helix-codex’s own source code. It found 3 critical issues:

  1. Return code logic bug — returncode != 0 with partial output was treated as success
  2. Terminal injection vulnerability — No ANSI/OSC escape sanitization in output
  3. Path double-application — cwd passed to both -C flag and subprocess cwd=

Claude (the model that wrote the code) had missed all three. Different model, different blind spots.

Real Performance Numbers

Tool Time What It Does
explain 5.4s Full code explanation
review 15.7s CRITICAL/WARNING/INFO classified review
execute 2.8s Task delegation with structured trace
parallel_execute — Up to 6 simultaneous tasks

Cross-Model Comparison

I ran Claude Agent and Codex in parallel on the same question: “Best thread-safe singleton pattern in Python?”

  • Claude: Metaclass + Lock, module variable, __new__
  • Codex: Module variable, lru_cache, Lock + classmethod

The lru_cache approach was unique to Codex — Claude hadn’t considered it. Two models genuinely produce different solutions.

Key Features

  • Full JSONL trace parsing — tools, files, timing, errors
  • Parallel execution — up to 6 tasks via asyncio.gather
  • Session management — threadId persistence
  • Adversarial Review Loop — GPT-5.4 challenges Claude’s code
  • Sandbox security — 3-tier policy + terminal injection prevention
  • 56 tests — comprehensive coverage
  • Single file — ~820 lines, zero external deps beyond FastMCP

Get Started (3 Minutes)

npm install -g @openai/codex && codex login
git clone https://github.com/tsunamayo7/helix-codex.git
cd helix-codex && uv sync

Add to ~/.claude/settings.json and you’re done.

What I Learned

  1. Different models have different blind spots. Cross-model review catches things self-review misses.
  2. Structured traces change everything. Raw text is useless for programmatic decisions.
  3. Parallel execution is underrated. Analyzing 6 files simultaneously saves real time.

GitHub: tsunamayo7/helix-codex — MIT license, 56 tests, Python 3.12+.

Star if useful! Feedback welcome.

GameMaker setup with Typescript and VS Code

Create GameMaker object

I wrote my first line of code back in 2014, when I tried Unity 3D to create a simple game for fun. I didn’t have any programming experience at the time, but I loved video games. I made a couple of them back then, nothing commercial, just some simple games I could build in 4-5 days to play with friends for a few hours before moving on.

I eventually got into programming professionally and landed a job as a Software Engineer, which meant putting game dev aside and, plot twist, focusing on work.

Twelve years have passed since then (time flies), and the other day I was reading a book about the video game industry. Once I finished it, I decided to try making a game again. I didn’t want to use Unity or Godot, as they felt like “too much” for what I could realistically make. Instead, I leaned towards GameMaker, which helped limit any unrealistic scope of a “super insane 3D game” I might get tempted by later.

GameMaker was perfect for a simple 2D game (plus some of my favorite games are made in GM). I managed to put together a playable top-down shooter in just one evening. Since it is super focused on 2D development, everything is intuitive and easy to use. After spending a decade working as a full-stack dev doing hundreds of different things (writing code, optimizing SEO, CI/CD, DB migrations, analytics, scalability…), I fell in love with GameMaker. I could finally write code for fun again.

However, there were some trade-offs: GML.

GML is the programming language used in GameMaker. If I had to briefly describe it, I would say: “It’s an archaic version of JavaScript”. While I believe it is great for people who first start writing code, but for me there are some big no-go:

  • Typesafety: there are no types, you can use comments similarly to JSDoc, but I don’t think it is good.
  • Built-in code editor: this is the biggest issue for me personally. It is eons behind VS Code and **JetBrains **products in terms of DX experience.

As a certified “**TypeScript **lover” I said to myself: I can fix her this.

The idea was simple: “In and out, 20 minute adventure.” I would take TypeScript code, run it through a transpiler, and post-process whatever needed fixing (for example: thisdoes not exist in GML; it uses self).

Obviously, things weren’t that simple. But after a weekend (and a sleepless night), I managed to pull it off. I was finally able to write TypeScript code and make it work in GameMaker.

My initial PoC used a script in watch mode to compile TS code on the fly, but an incredible coincidence happened: two days after I started working on this tool, GameMaker released a new version of their IDE. It added support for build hooks, which allowed me to get rid of the “watcher” and simply transpile the code the moment you hit the “Run” button.

The actual thing

What I came up with is a CLI tool (open source, NPM) that can be installed globally.

Setup

Install the package globaly (-g):

npm i -g @odemian/gamemaker-typescript

It has 2 commands:

  • setup: Prepares the GameMaker project you are currently in to use TypeScript (creates tsconfig.json, links types, and configures pre_project_step to automatically transpile).
  • compile: Manually compiles the project. This is useful if you’ve added assets like sprites or sounds, as this command will generate their respective types.

Project configuration and the TS first object

After the library has been installed, open a GameMaker project in VS Code (or whatever code editor) and run:

gmts setup

Create an object:

Create GameMaker object

This will create a file at objects/obj_player/obj_player.yy. The .yy file contains the metadata for the object. Place your script in the same folder and give it any name (I call mine code.ts):

Write typescript code

You can think of objects/obj_player as folder-based routing: each object is a folder in the objects directory, and you write your code right there.

Here is the actual code if you want to copy it:

class Player extends GMObject {
  _movement_speed: number;

  // inside of the defineObject you can declare all of your events, like onCreate, onStep, onDraw etc...
  onCreate() {
    // use "this." keyword to access object properties in a safe fully typed way
    this._movement_speed = 2;
  }

  onStep() {
    var _hspd = keyboard_check(vk_right) - keyboard_check(vk_left);
    var _vspd = keyboard_check(vk_down) - keyboard_check(vk_up);

    if (_hspd != 0 || _vspd != 0) {
        var _dir = point_direction(0, 0, _hspd, _vspd);
        this.x = this.x + lengthdir_x(this._movement_speed, _dir);
        this.y = this.y + lengthdir_y(this._movement_speed, _dir);
    }
  }
}

If you’ve ever used GameMaker, you might wonder: “Wait, a Player class?” Yes, OOP baby.

Most other game engines (e.g., Unity, Godot) use this approach where each object’s code is encapsulated in a class. I experimented with different approaches, but I eventually settled on classes. They feel like the most natural way to write game code. In the ten years I’ve been working with TypeScript, I’ve almost never used the class keyword, it rarely feels right in modern front-end or back-end development. But for a game, it’s a perfect match.

The class inherits all the standard events from GMObject:

  • Create -> onCreate
  • Step -> onStep
  • Draw -> onDraw
  • and so on, you get the idea

Run it

After creating the Player object and writing the code, we can run it (I added a sprite to my obj_player behind the scenes):

Run game

How GameMaker understands TS

If you are into GameMaker, you might wonder if it uses the newest GMRT runtime. The short answer is no. As of the time of writing, GMRT is still in beta, and it is not clear when it will be released or in what form.

What currently happens is:

  • When you set up a project using gmts setup, it configures a pre_project_step script to run gmts compile before building the project.
  • When you press “Run”, it looks for all script and object resources and compiles any .ts files it finds in the resource folder.
  • Events like onCreate and onStep are extracted into Create_0.gml and Step_0.gml (scripts that GML understands). Other methods are then assigned to the instance in the Create event.
  • GameMaker builds the project by reading all of the generated .gml files.

The cool thing about this setup is that if you start your project with TS but at some point change the idea, you can simply remove .ts files, and keep .gml (they remain in readable form).

I built a context engine that saves Claude Code 73% of its tokens on large codebases

  1. The problem

    • LLM coding agents on large repos burn tokens scanning files. Claude Code on an 829-file codebase consumed 45K tokens just finding the right code. By turn 3 of a conversation, context is gone.
    • Token cost compounds. 20 questions in a session at 45K each is 900K tokens — nearly the entire 1M window. The agent degrades before your work is done.
  2. What Mnemosyne does

    • Sits between your codebase and your LLM. Indexes into SQLite, scores every chunk with 6 retrieval signals (BM25, TF-IDF, symbol search, usage frequency, predictive prefetch, optional dense embeddings), compresses with AST awareness, delivers exactly within your token budget.
    • Zero runtime dependencies. pip install mnemosyne-engine. No API keys, no cloud, no Docker. Works offline.
    • Drop-in integration: add 3 lines to your CLAUDE.md or .cursorrules and the agent queries Mnemosyne before reading files.
  3. The benchmarks

    • Include the full benchmark table from the README.
    • Be specific: “Claude Opus 4.6 with 1M context, tested against HCCValidatorAI (829 files, production codebase) and httpx (100 files, open-source).”
    • Include the honest finding: “Baseline produces slightly more detailed answers by reading source directly. The optimal workflow combines both: Mnemosyne finds the files, Claude reads them.”
    • This honesty is critical. The audience will find the benchmark report on GitHub. If the blog overstates, you lose credibility permanently.
  4. Quick start

   pip install mnemosyne-engine
   cd your-project
   mnemosyne init && mnemosyne ingest
   mnemosyne query "How does auth work?" --budget 8000
  1. How it retrieves

    • Six signals fused via Reciprocal Rank Fusion. Link to ALGORITHMS.md for the deep dive.
    • AST-aware chunking for Python, Go, Rust, C#, Java, Kotlin, JS/TS.
  2. Integration examples

    • Claude Code (CLAUDE.md snippet)
    • Cursor (.cursorrules snippet)
    • Any agent that can shell out
  3. What it does NOT do

    • Not a replacement for reading source files — it is a file finder that saves you from grep-scanning
    • Dense embeddings are optional (requires onnxruntime) — sparse retrieval handles most queries
    • Query latency is sub-500ms cold, sub-200ms warm — not instant
    • Small repos (under ~50 files) see marginal savings; the value scales with codebase size
  4. Conclusion

    • Open source, AGPL-3.0, commercial license available
    • Links: PyPI, GitHub, ALGORITHMS.md
    • “Try it on your codebase and tell me what breaks”

Deploying Poorly Packaged Applications with PowerShell and SCCM

In real-world environments, not all enterprise software comes with a proper installer.

Recently, I had to deploy a legacy DLP agent that had:

  • multiple versions across endpoints
  • different ProductCodes
  • the same display name
  • limited documentation
  • and no reliable upgrade path

Trying to handle this using standard logic in Microsoft SCCM (multiple detection rules, MSI-based upgrades, etc.) quickly became messy.

The Approach

Instead of relying on SCCM alone, I moved the logic into a PowerShell-based installer.

The idea is simple:

  • Detect if the application is installed
  • Check the installed version (via ProductCode)
  • Remove anything that doesn’t match the target version
  • Install the correct version with required parameters

In SCCM, the detection method stays clean — it only checks for the new version.

Why This Works Better

  • No need for multiple detection rules
  • No leftover versions after upgrades
  • Full control over install/uninstall logic
  • Works even with poorly packaged or legacy software

Key Idea

Instead of trying to model every scenario inside SCCM, centralize all logic in a script.

This makes deployments more predictable and much easier to maintain.

Full Breakdown

I wrote a detailed step-by-step guide here (including SCCM setup and scripts):

👉 https://www.hiddenobelisk.com/how-to-deploy-poorly-packaged-applications-using-powershell-and-microsoft-sccm/

PUBG: Battlegrounds’tan 1 Nisan’a özel “Dekor Avı” modu

PUBG Battlegrounds

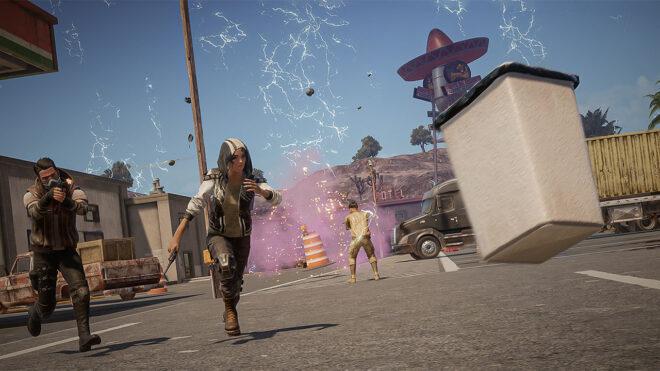
PUBG BattlegroundsKrafton, PUBG: Battlegrounds’un savaş alanlarını eğlenceye boğacak 1 Nisan etkinliği “Dekor Avı”nın bugün başladığını duyurdu. Dekor Avı modunda oyuncular iki role ayrılıyor. Avlar ve Avcılar. Avlar, haritaya dağılmış objelerin kılığına girerek gizleniyor; Avcılar ise alandaki şüpheli her şeyi arayarak süre dolmadan önce tüm obje kılığındaki Avları ortadan kaldırması gerekiyor. Bu oyun modu, gizlilik ve stratejiyi bir araya getirerek geleneksel savaş oyunlarının ötesinde yepyeni bir deneyim sunuyor. Her oyun toplamda 3 Avcı ve 9 Av olmak üzere 12 oyuncudan ve üç turdan oluşuyor. Her turun başında oyuncular tercih ettikleri rolü seçiyorlar; gerektiğinde takımlar otomatik olarak dengeleniyor. Oyun, birden fazla aşamadan oluşuyor. Hazırlık aşamasında, Avcılar kısıtlı bir alanda beklerken, Av rolündekiler kılık değiştirip saklanma yerlerini buluyor. Tur ilerledikçe, Avcılar obje kılığındaki Avları arayıp ortadan kaldırmaya başlıyorlar ancak oyuncu olmayan objelere ateş etmek Avcıların HP puanlarını düşürüyor. Bu nedenle alınan her karar beraberinde bir risk de taşıyor. Her turun sonuna doğru yaşanan kısa […]

PUBG: Battlegrounds’tan 1 Nisan’a özel “Dekor Avı” modu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

How to Get City, Postal Code, Address from Latitude and Longitude

Latitude and longitude grid

In many applications, you don’t start with an address — you start with coordinates.

A user clicks on a map, shares their GPS location, or your system receives latitude and longitude from a device. But raw coordinates like 40.748817, -73.985428 aren’t very useful on their own. Most applications need human-readable data: a city name, a postal code, or a full address.

This is where reverse geocoding comes in.

In this article, we’ll look at how to convert latitude and longitude into structured address data — including city, postal code, and formatted address — and, more importantly, what developers should be aware of when working with real-world location data.

To make things more practical, we’ll also use a simple interactive demo where you can click on a map and instantly get the corresponding address details:

Coordinates vs Address: Two Ways to Describe a Location

Latitude and longitude coordinates describe an exact point on Earth using a global grid system.

  • latitude defines how far north or south a location is
  • longitude defines how far east or west it is

Together, they pinpoint a precise location anywhere on the planet:

Latitude and longitude grid

For example, the coordinates 40.748817, -73.985428 represent a specific point in New York.

However, while coordinates are extremely precise, they are not very intuitive for humans. People naturally think of locations in terms of:

  • cities
  • streets
  • postal codes
  • full addresses

This creates a gap between how machines represent locations and how humans understand them.

So how do you convert coordinates into a readable address?

To do that, you need a process that maps latitude and longitude to real-world location data — such as city names and postal codes. This process is called reverse geocoding.

Reverse Geocoding: Convert Coordinates to City, Postal Code, and Address

Reverse geocoding is the process of converting geographic coordinates (latitude and longitude) into a human-readable address.

In practice, reverse geocoding is not something you implement locally. It requires access to large, constantly updated geographic datasets that map coordinates to real-world address data — including administrative boundaries, streets, buildings, and postal codes.

Because of this, reverse geocoding is typically provided as a service via APIs.

One example is the Geoapify Reverse Geocoding API, which allows you to send coordinates and receive structured address data in response.

Here is an example API Request:

https://api.geoapify.com/v1/geocode/reverse?lat=40.748817&lon=-73.985428&format=json&apiKey=YOUR_API_KEY

The response contains structured fields such as:

  • city, town, village
  • postcode
  • street, housenumber
  • formatted (full address)

You can also control the level of detail using the type parameter, which helps filter results by address level (for example: city, postcode, street, etc.).

Getting city from coordinates

To get the city from coordinates, you can use reverse geocoding with the type=city parameter. This tells the API to return results at the city level.

For example:

https://api.geoapify.com/v1/geocode/reverse?lat=40.719726903683636&lon=-74.04103305850015&format=json&type=city&apiKey=YOUR_API_KEY

A typical response looks like this:

{
  "results": [
    {
      "country": "United States",
      "state": "New Jersey",
      "city": "Jersey City",
      "lon": -74.047455,
      "lat": 40.7215682,
      "result_type": "city",
      "formatted": "Jersey City, NJ, United States of America",
      "address_line1": "Jersey City, NJ",
      "address_line2": "United States of America",
      ...
    }
  ]
}

Using type=city ensures that the response focuses on the city-level administrative area, rather than returning street-level or building-level details.

Getting postcode (ZIP code) from coordinates

To get the postal code from coordinates, you can use reverse geocoding with the type=postcode parameter. This ensures the API returns results at the postcode level.

For example:

https://api.geoapify.com/v1/geocode/reverse?lat=40.739501996228256&lon=-74.18542863164123&type=postcode&format=json&apiKey=YOUR_API_KEY

A typical response looks like this:

{
  "results": [
    {
      "country": "United States",
      "state": "New Jersey",
      "city": "Newark",
      "postcode": "07103",
      "result_type": "postcode",
      "formatted": "Newark, NJ 07103, United States of America",
      "address_line1": "Newark, NJ 07103",
      "address_line2": "United States of America"
    }
  ]
}

The key field here is:

  • postcode — contains the postal (ZIP) code for the given coordinates

Additional useful fields include:

  • city — the associated city
  • formatted — full human-readable address

Using type=postcode ensures that the response focuses specifically on postcode-level data.

Keep in mind that:

  • not all locations have postal codes
  • postal codes may represent areas rather than exact points
  • formats vary depending on the country

Getting address from coordinates

To get a full address from coordinates, you can use reverse geocoding without specifying a type, which returns the most relevant place for the given location (for example, a building, POI, or street address).

For example:

https://api.geoapify.com/v1/geocode/reverse?lat=40.68818115914695&lon=-73.99558678565592&format=json&apiKey=YOUR_API_KEY

A typical response looks like this:

{
  "results": [
    {
      "name": "Citi Bike - Congress St & Clinton St",
      "housenumber": "183",
      "street": "Congress Street",
      "city": "New York",
      "postcode": "11201",
      "state": "New York",
      "country": "United States",
      "result_type": "amenity",
      "formatted": "Citi Bike - Congress St & Clinton St, 183 Congress Street, New York, NY 11201, United States of America",
      "address_line1": "Citi Bike - Congress St & Clinton St",
      "address_line2": "183 Congress Street, New York, NY 11201, United States of America"
    }
  ]
}

The most useful field for display is:

  • formatted — a ready-to-use human-readable address

You can also access individual components such as:

  • name — place or POI name (if available)
  • housenumber and street
  • city, postcode, state, country

By default, reverse geocoding returns the most relevant result for the given coordinates, which may be a specific place (like a business or landmark), not just a street or city.

Common Pitfalls When Converting Coordinates to Address

Reverse geocoding is powerful, but working with real-world location data comes with a few important caveats.

Understanding these will help you avoid common mistakes and build more reliable applications.

City is not always available

Not every location has a city field. Depending on where the coordinates point, the response may include:

  • city
  • town
  • village
  • or no settlement at all

To handle this correctly, always implement a fallback strategy instead of relying on a single field.

The result depends on the exact point

Small changes in coordinates can lead to different results.

For example, clicking on:

  • a building → returns a specific address
  • a road → returns street-level data
  • a park → may return only city or district

This is expected behavior, not an error.

The closest result may not match expectations

Reverse geocoding returns the nearest known object.

This could be:

  • a building
  • a business (POI)
  • a street
  • an administrative area

If you need a specific level (e.g., city or postcode), use the type parameter to control the result.

Coordinates may need normalization

Coordinates should always be valid:

  • latitude must be between -90 and 90
  • longitude must be between -180 and 180

Try It Yourself: Interactive Reverse Geocoding Demo

To better understand how reverse geocoding works in practice, try this interactive demo:

Live Demo on CodePen

The demo also shows how different clicks can return different types of results depending on the location — for example, a building, a street, or an administrative area.

Summary

Converting latitude and longitude into a city, postal code, or full address is a common requirement in many applications — from delivery services to map-based interfaces.

In this article, we explored how reverse geocoding works and how to use it to extract meaningful location data from coordinates.

Key takeaways:

  • coordinates describe precise locations, but are not human-friendly
  • reverse geocoding bridges the gap between coordinates and real-world addresses
  • you can extract specific data like city and postcode using the type parameter
  • not all locations have complete address data, so fallback logic is important
  • results may vary depending on the exact coordinates and context

By understanding these concepts and handling edge cases properly, you can build reliable features that convert coordinates into usable address information.

Additional Resources

FAQ

Is reverse geocoding free?

Most reverse geocoding services offer a free tier with usage limits.

For example, Geoapify provides a free plan with 3000 requests per day and 5RPS. This is usually enough for testing and small applications. For production use or higher volumes, paid plans are available.

How do I get an API key?

To use a reverse geocoding service like Geoapify, you need an API key.

You can get one by registering at the website.

After creating a project, you’ll receive an API key that you can use in your requests.

How do I get the timezone from coordinates?

Reverse geocoding responses often include timezone information.

For example, Geoapify returns a timezone object with:

{
  "name": "America/New_York",
  "offset_STD": "-05:00",
  "offset_STD_seconds": -18000,
  "offset_DST": "-04:00",
  "offset_DST_seconds": -14400,
  "abbreviation_STD": "EST",
  "abbreviation_DST": "EDT"
}

You can extract this directly from the response without making a separate API call.

How do I get the state or region?

To get the state or region from coordinates, you can use reverse geocoding with the type=state parameter. This ensures the API returns results at the state level.

How can I understand the quality of the result?

You can estimate how accurate the result is using the distance field.

  • distance represents how far (in meters) the returned result is from the input coordinates
  • smaller values indicate higher accuracy

For example:

  • 0–10 meters → very precise (building-level)
  • 10–100 meters → good accuracy
  • 100+ meters → approximate result

Why do I sometimes get a place (POI) instead of an address?

By default, reverse geocoding returns the most relevant nearby object.

This could be:

  • a business or landmark (POI)
  • a building
  • a street
  • an administrative area

If you need a specific level (e.g., city or postcode), use the type parameter to control the result.

Can I use reverse geocoding offline?

In most cases, no.

Reverse geocoding requires large and frequently updated datasets, making it impractical to run locally. That’s why it is typically provided as an online API service.

What happens if there are no results?

In some cases, reverse geocoding may return no results:

  • remote areas
  • oceans or lakes
  • incomplete data coverage

Your application should handle this gracefully and provide fallback behavior.