Claude Code’un belirli kaynak kodları sızdırıldı

Anthropic Claude Code

Anthropic Claude CodeKodlama odaklanan popüler Anthropic hizmeti Claude Code için gönderilen 2.1.88 güncellemesi, açıkta unutulan bir “map” dosyası yüzünden önemli bir sızıntıya neden oldu. Aktarıldığı kadarıyla bu dosya 512.000 satırdan fazla kod içeriyor (model değil CLI özelinde) ve yapay zeka destekli kodlama aracının iç işleyişine dair önemli bilgiler veriyor. Gelişme hakkında bir açıklama yapan Anthropic sözcüsü Christopher Nulty, yayımlanan son Claude Code sürümünün bazı açık dahili kaynak kodlarını da içerdiğini kabul etti. Müşterilere ait hassas verilerin veya kimlik bilgilerinin bu durumdan etkilenmediğini ifade eden Nulty, olayın bir güvenlik ihlali değil, insan hatasından kaynaklanan bir paketleme sorunu olduğunu ve benzer durumun tekrar yaşanmaması için gerekli önlemleri aldıklarını ekledi. Bu sızıntı sayesinde şirketin Claude Code için geliştirdiği bazı dikkat çekici yeni özellikler de ortaya çıktı. Sızıntı kapsamında bulunanlar arasında Anthropic’in sistem için hazırladığı talimatlar, sistemin “bellek” yapısına dair detaylar, kod yazımına tepki veren Tamagotchi benzeri bir dijital canlı ve arka planda sürekli çalışabilecek “KAIROS” […]

Claude Code’un belirli kaynak kodları sızdırıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Your backend code is a black box. It doesn’t have to be.

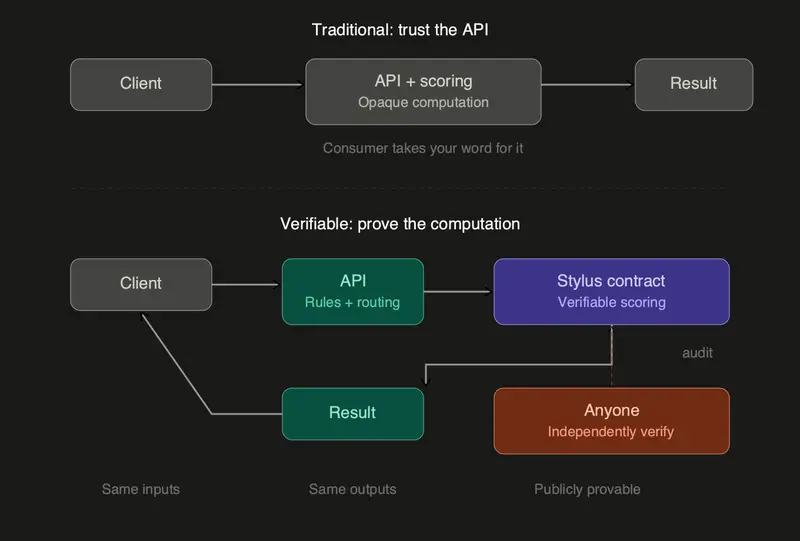
Black box vs verifiable compute

Your API takes inputs and returns outputs. The logic in between? Nobody outside your team can verify it. Regulators read documentation you wrote about it. Partners call your endpoint and trust the response. Users don’t even get that.

This has worked for decades. But there’s a growing category of backend logic where “trust us” isn’t enough. Scoring algorithms, compliance checks, eligibility rules, validation pipelines. Anywhere someone needs to independently confirm that your code does what you say it does.

You don’t have a code problem. You have a verifiability problem.

The case for publicly auditable code

Black box vs verifiable compute

Most backend engineers don’t think about code auditability because most code doesn’t need it. Your CRUD endpoints, your auth flows, your data transformations, those are internal concerns. Nobody outside your org needs to verify them.

But some functions carry weight. A scoring algorithm that determines loan eligibility. A validation pipeline that checks regulatory compliance. A pricing engine that partners depend on. For these functions, the standard answer is documentation: you write a spec, maybe you share pseudocode, and everyone agrees to trust that the running code matches the paper.

That’s not verification. That’s trust with extra steps.

Publicly auditable code means anyone can call the same function with the same inputs and confirm they get the same outputs. The logic is visible. Execution is deterministic. And the code can’t change silently after deployment.

This isn’t a new idea. Open source gives you code visibility. But open source doesn’t prove that the code running in production is the same code in the repo. You need a runtime where the deployed code is the source of truth, and where every execution is independently reproducible.

That runtime exists. And you don’t need to learn a new language to use it.

Rust in, verifiable execution out

When most engineers hear “deploy code onchain,” they picture learning Solidity, memorizing gas optimization tricks, and rewriting working logic in an unfamiliar language. That’s a reasonable reason to stop listening.

Arbitrum Stylus skips that detour. You write Rust, compile to WASM, and deploy it to a blockchain that’s optimized for low-cost computation. Your existing toolchain, your existing crates, your existing mental model. The contract runs alongside Solidity smart contracts with shared state, but you never need to touch Solidity yourself.

This isn’t about converting you to crypto. It’s about giving you a deployment target where execution is publicly verifiable by default.

Three properties matter here:

Every execution is independently auditable. Anyone can call the contract with the same inputs and confirm they get the same outputs. No trust required.

The logic is immutable. Once deployed, the code can’t change silently. If you push an update, that’s a new deployment with its own address and its own history. No “we patched it last Tuesday but forgot to tell you.”

Execution is deterministic. Same inputs, same outputs, every time, on every node. No environment-specific drift, no floating point surprises across hardware.

What the architecture looks like

Scoring engine architecture

I built a scoring engine to test this pattern. The architecture splits cleanly between what stays in your infrastructure and what moves onchain:

Your backend stays exactly where it is. An Axum API server handles business rules, authentication, request routing. Normal backend work. The only difference is that when the API needs a computation verified, it calls an onchain contract instead of a local function.

The onchain piece is a Stylus contract. It takes parameters, runs the calculation, and returns results. No state storage, just pure computation. Think of it as a function you deploy instead of host.

Shared crate compilation

A shared Rust crate holds the type definitions and compiles for both environments. The contract uses no_std for WASM. The API server uses std for native. Same types, both sides. The compiler guarantees they match. No serialization mismatches, no type drift between your API and your contract.

One language across the entire stack. The chain boundary becomes a function call, not a language barrier.

The performance question

The first objection any backend engineer raises: what’s the overhead?

Fair. Onchain computation has historically been expensive. That’s the whole reason Solidity exists. It was designed to minimize execution cost on the EVM.

Stylus changes the math. WASM execution on Arbitrum is dramatically cheaper than EVM execution for compute-heavy workloads. The scoring engine used over 90% less gas than the equivalent Solidity contract doing identical work:

Environment Score Gas Usage
Offchain Rust 953 n/a
Onchain Stylus (WASM) 953 76,048
Onchain Solidity (EVM) 810 1,027,635

Storage operations cost the same either way, but iterative math, weighted calculations, and loop-heavy logic is where WASM pulls ahead.

This isn’t a contrived benchmark. RedStone, an oracle provider, published similar results after porting their verification logic to Stylus. Compute-intensive work is where this architecture pays for itself.

Where auditable code matters

Not every function belongs onchain. But some backend logic sits in a category where “trust me” isn’t good enough:

Scoring and risk calculations, where regulators want to audit the exact computation, not a description of it. Eligibility determinations, where partners want to verify outcomes independently instead of trusting your API response. Compliance validation, where auditors want proof that the logic running today is the same logic approved last quarter. Data pipelines, where counterparties want to confirm their data passed through agreed-upon rules.

If you’ve ever written documentation explaining how your algorithm works so someone else could trust it, that’s the function that belongs onchain. Let them verify the code instead of reading your summary of the code.

The scoring engine I built is one example of this pattern. But the pattern is the point, not the example. Any pure function where independent verification adds value is a candidate.

What you’d actually do on a Monday morning

If you write Rust, the learning curve is smaller than you think.

Install cargo-stylus, which handles compilation and deployment. Write your function with #[entrypoint] and #[public] macros. Compile to WASM. Deploy to a testnet. Call it from your existing API using an RPC endpoint.

#[entrypoint]
#[storage]
pub struct ScoringEngine;

#[public]
impl ScoringEngine {
    pub fn score(&self, factors: Vec<Factor>, rules: Vec<Rule>) -> u32 {
        // Your computation logic here
        // Publicly verifiable, deterministic, immutable
    }
}

Your database, your auth, your business logic, none of that moves. You add one function that runs somewhere verifiable instead of somewhere trusted. Everything else stays the same.

The scoring engine repo has working code, setup instructions, and benchmarks comparing three execution paths: onchain Stylus, onchain Solidity, and offchain Rust. It’s a concrete starting point, but the approach applies anywhere you need auditable computation.

You’re adding a deployment target, not adopting a lifestyle

The shift is smaller than it sounds. The same way you might deploy a function to Lambda for serverless execution or to a TEE for confidential computing, you deploy to Arbitrum for verifiable execution.

Your Rust skills transfer directly. Your toolchain stays the same. The only thing that changes is who can verify your logic: everyone.

If you’ve been dismissing onchain as irrelevant to backend work, spend thirty minutes with the repo.

GitHub logo

hummusonrails
/
stylus-scoring-engine

Verifiable credit/risk scoring engine: Stylus (Rust/WASM) vs Solidity on Arbitrum with three-way gas benchmark

stylus-scoring-engine

License
Rust
Stylus SDK
Axum
PRs Welcome

Verifiable credit/risk scoring on Arbitrum with a three-way gas benchmark: offchain Rust vs onchain Stylus vs onchain Solidity.

Quick Start · Architecture · Report a Bug

What it does

  • Benchmarks the same scoring algorithm across three execution environments with real gas numbers
  • Scores entities against configurable weighted rules with iterative convergence and cross-factor correlation
  • Demonstrates Stylus gas savings on compute-heavy workloads (over 90% cheaper than Solidity)
  • Shares Rust types between the onchain contract and offchain API server from a single crate
  • Stores scoring rules in SQLite with full CRUD via REST endpoints

Deploy and benchmark demo

Quick Start

# clone and install
git clone https://github.com/hummusonrails/stylus-scoring-engine.git
cd stylus-scoring-engine
pnpm install

# start the local arbitrum devnode
pnpm devnode

# in a new terminal, deploy both contracts
pnpm deploy:all

# start the api server (reads .env written by deploy)
pnpm api

# in a new terminal, run the three-way benchmark
pnpm benchmark

Prerequisites

  • Rust 1.88+ with…

The gap between “interesting in theory” and “I could actually use this” is shorter than you expect.

I Built a Next.js-Inspired Web Framework in Go — Meet NexGo

Modern web development is dominated by tools like Next.js, but most of them rely heavily on Node.js, npm, and complex build systems.

I wanted something simpler. Faster. More efficient.

So I built NexGo — a Go-powered web framework inspired by Next.js.

⚡ What is NexGo?

NexGo brings the developer experience of Next.js into the Go ecosystem.

It allows you to build full-stack web applications using:

  • File-based routing
  • Server-side rendering (SSR)
  • API routes
  • Hot reload
  • Static site generation

All compiled into a single binary — no runtime dependencies, no Node.js.

🔥 Why NexGo?

Most modern frameworks come with overhead:

  • ❌ Node.js runtime
  • ❌ Heavy dependencies
  • ❌ Complex build pipelines

With NexGo:

  • ✅ No Node.js
  • ✅ No npm
  • ✅ Zero dependencies
  • ✅ Blazing fast performance (~50K req/sec)
  • ✅ Simple deployment (just one binary)

🧠 How It Works

NexGo uses a file-based routing system, similar to Next.js.

Example:

pages/
├── index.html        → /
├── about.html        → /about
├── blog/
│   └── [slug].html   → /blog/post-1

Just create files — NexGo automatically turns them into routes.

🚀 Getting Started

Install NexGo:

go install github.com/salmanfaris22/nexgo/cmd/nexgo@latest

Create a project:

nexgo create my-app
cd my-app
nexgo dev

Now open:

👉 http://localhost:3000

Your app is live with hot reload ⚡

⚡ Built for Performance

Because NexGo is written in Go:

  • It handles thousands of requests efficiently
  • Compiles into a small binary (~10MB)
  • Uses no external runtime

🌐 Live Demo

Check out NexGo in action:

👉 https://nexgo.up.railway.app/

💡 This entire website is built using NexGo itself.

🧩 Key Features

  • File-based routing
  • Layouts and reusable components
  • API routes using Go
  • Built-in middleware (CORS, logging, gzip)
  • Static asset support
  • Hot reload (HMR)
  • DevTools panel

⚖️ NexGo vs Next.js

Feature NexGo Next.js
Language Go JavaScript
Runtime None Node.js
Deployment Single binary Server / Vercel
Performance ⚡ Very high High

💡 Why I Built This

I wanted a framework that:

  • Combines simplicity + performance
  • Removes unnecessary complexity
  • Feels modern like Next.js
  • Runs entirely on Go

NexGo is my attempt to bring that vision to life.

🚀 What’s Next?

I’m actively improving NexGo and exploring:

  • Better developer tools
  • Plugin ecosystem
  • More advanced routing features

💬 Feedback Welcome

This is an open-source project, and I’d love your feedback.

👉 GitHub: https://github.com/salmanfaris22/nexgo
👉 Try it: https://nexgo.up.railway.app/

⭐ Support the Project

If you find NexGo interesting:

  • Give it a ⭐ on GitHub
  • Share it with other developers
  • Try building something with it

🚀 Built with Go. Inspired by Next.js. Powered by simplicity.

Check AI Builder Credits in Copilot Studio

To check the remaining AI Builder credits used by your Microsoft Copilot Studio, you need to check it from the Power Platform Admin Center, because AI Builder credits are managed at the tenant/environment level, not directly inside Copilot Studio.

Here is the step-by-step guide 👇

Method 1 — Check AI Builder Credits (Recommended)

Step 1: Open Power Platform Admin Center

Go to:
Power Platform Admin Center
https://admin.powerplatform.microsoft.com

Sign in with Admin or Environment Admin account.

Step 2: Go to Capacity

  1. Click Resources (Left menu)
  2. Click Capacity
  3. Select AI Builder tab

You will see:

  • Total AI Builder Credits
  • Used Credits
  • Remaining Credits
  • Consumption trend

Example:

Metric Value
Total Credits 1,000,000
Used 350,000
Remaining 650,000

Method 2 — Check by Environment

  1. Go to Environments
  2. Select your environment
  3. Click Capacity
  4. View AI Builder usage

This shows which environment (like Copilot Studio agent) is consuming credits.

Method 3 — Check from AI Builder Page

Go to
AI Builder

https://ai.builder.microsoft.com

Then:

  1. Click Usage
  2. View consumption by:
  • Model
  • Flow
  • Copilot
  • Environment

What Consumes AI Builder Credits in Copilot Studio

These features consume credits:

✅ Generative Answers
✅ AI Prompts
✅ Document Processing
✅ GPT-based Responses
✅ Data Extraction
✅ Image Generation

Example Credit Consumption

Feature Credit Usage
Generative Answer Medium
AI Prompt Medium
Document Processing High
GPT Content Generation Medium

Pro Tip (Important)

If you’re using:

  • Azure OpenAI Service
    instead of AI Builder

Then credits come from Azure, not AI Builder.

So check:

  • Azure Portal
  • Azure OpenAI Usage
  • Token consumption

Quick Troubleshooting

If you cannot see AI Builder capacity:

Possible reasons:

  • Not admin
  • No AI Builder license
  • No credits assigned
  • Wrong environment selected

Best Practice (Enterprise)

Monitor credits weekly:

  • Prevent agent failure
  • Avoid service interruption
  • Track usage by department

Hope you enjoy the session.

Please leave a comment below if you have any further questions.

Happy Sharing !!!
Keep Learning | Spread Knowledge | Stay blessed |

I Built a Free Prop Firm Risk Calculator — Here’s Why

I Built a Free Prop Firm Risk Calculator --- Here

If you’re trading with a prop firm, you already know the drill. Blow your daily drawdown, you’re done for the day. Hit your max drawdown, you’re done period. Miss the consistency rule, and somehow you still fail even though you were profitable.

The math isn’t hard, but keeping track of it all while you’re in the middle of a live session? That’s where things go sideways.

So I built a tool to handle it for me — and now I’m sharing it for free.

I Built a Free Prop Firm Risk Calculator --- Here's Why

What it does

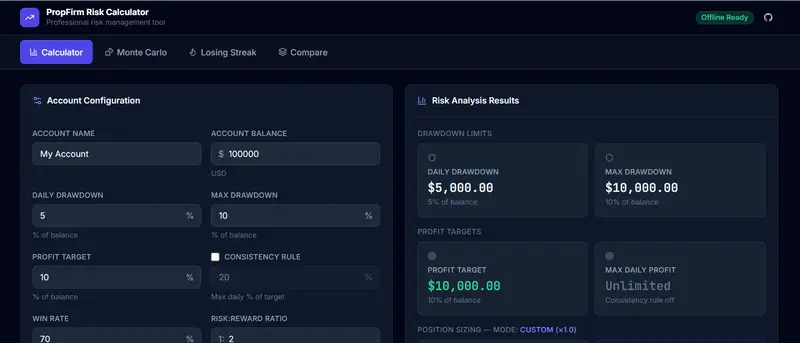
PropFirm Calculator is a web app (PWA, so you can install it on your phone or desktop) that helps you figure out exactly how much you should be risking per trade given your account rules.

You plug in:

  • Account balance
  • Daily drawdown limit
  • Max drawdown limit
  • Profit target
  • Consistency rule (if your firm has one)
  • Win rate & risk/reward ratio

And it spits out your safe risk per trade, max daily profit cap, estimated days to pass, expected value per trade — all the numbers you actually need before you click buy or sell.

It also runs a Monte Carlo simulation so you can see a range of possible outcomes based on your setup, not just the rosy best-case scenario. And there’s a Losing Streak Simulator that shows you how many losses in a row it takes before you’re in real trouble — useful for gut-checking your position size.

If you trade multiple accounts, there’s a multi-account comparison view so you can line them all up side by side.

Quick presets are built in for FTMO, Funded Trader, TopStep, and etc. so you don’t have to type everything in manually.

It’s free, no login required

No account. No email. No subscription. Just open it and use it.

👉 https://wteja.github.io/propfirm-calculator/

If you want to host your own version or add your firm’s rules, the source is open:

👉 https://github.com/wteja/propfirm-calculator

Fork it, tweak it, do whatever you want with it.

Why I made this

Honestly, I got tired of doing the same math on a notepad every morning before the session. One miscalculation and you’re overrisking without even realizing it. This just removes that friction.

If it helps even a handful of traders not blow their challenges over something avoidable like position sizing, that’s a win for me.

Give it a try and let me know what you think.

Why Apache IoTDB Is Written in Java: A Decade of Engineering Trade-offs

Since I started working on the development of the time-series database Apache IoTDB in 2016, I’ve been asked the same question again and again:

Why did you choose Java to build a database? Can Java really be used to write a database system?

In the early days, my standard answer was usually this:

When IoTDB was initiated in 2011, almost all influential distributed systems and databases were built in Java or on the JVM—such as Hadoop, HBase, Spark (Scala on JVM), Cassandra, Kafka, and Flink. To integrate deeply with the big data ecosystem, choosing Java was a natural decision.

That explanation is valid—but clearly insufficient.

What people really want to know is:

  • If you learn Java, do you actually have a chance to build a database?
  • Can Java be used to build a good database?
  • What does choosing Java really mean for a system like IoTDB?
  • …

These questions cannot be answered by theory alone. The relationship between programming languages and databases is not a matter of ideology—it is a practical trade-off among language characteristics, system complexity, engineering investment, and long-term returns.

After nearly ten years of real-world exploration, we believe we can now give a more grounded answer. Below are the eight key considerations behind IoTDB’s choice of Java.

A Mature and Comprehensive Java Ecosystem

Queues, maps, heaps, locks, thread scheduling—nearly every common data structure and concurrency primitive has mature, well-tested implementations in the Java ecosystem. This allows database developers to focus their energy on core database logic and performance optimizations, rather than repeatedly reinventing low-level infrastructure.

More importantly, Java is widely used across enterprise platforms and applications. Middleware components in the Java ecosystem integrate smoothly with each other, which significantly lowers the learning curve for developers adopting Java-based databases. As a result, Java developers can more easily understand, operate, and extend a Java-written database system.

Code Readability and Long-Term Maintainability

This factor is often overlooked, but for someone who has spent years working on database internals, it is critical.

Databases are inherently complex systems. That complexity brings enormous optimization potential—but also substantial risk. A single subtle mistake can introduce severe bugs, which is why newer versions of some databases occasionally perform worse or become less stable than older ones.

Java’s object-oriented design provides a natural advantage in code readability and conceptual clarity. In practice, we have found that many community contributors are able to ramp up quickly by understanding IoTDB’s design principles and abstractions.

Readable code is not just a matter of elegance—it is a system’s lifeline. Only readable and understandable codebases can sustain long-term evolution without collapsing under their own complexity.

Operability and Debugging Efficiency

Most Java developers are familiar with exception handling and detailed stack traces in logs—and those stack traces are invaluable.

In our experience, when users report bugs in IoTDB, engineers can often locate the root cause within the same day, and rarely does debugging exceed one day. The stack information alone usually provides enough context to pinpoint the issue.

By contrast, in discussions with developers of C-based databases, diagnosing production issues such as memory leaks can sometimes take weeks or even months.

No language-level advantage matters more than system stability and recoverability. There is nothing more painful than a production database failure that cannot be quickly diagnosed or fixed.

JVM tooling such as JProfiler and Arthas gives Java developers powerful observability into runtime behavior, enabling fast root-cause analysis and remediation.

Cross-Platform Portability

Today, this is often referred to as localization or hardware adaptation.

Java’s promise of “write once, run anywhere” has proven extremely valuable as domestic and heterogeneous hardware platforms have become more common. For IoTDB, we have rarely needed special platform-specific adaptations—if Java can run, IoTDB can run.

This allows us to concentrate on coredatabase logic and optimization, instead of spending engineering effort on platform compatibility.

Efficient Project and Dependency Management

For anyone joining the IoTDB project, the first essential skill is understanding Maven.

Nearly all Java projects—large or small—use Maven for project structure, dependency management, compilation, packaging, and release workflows. Advanced tasks such as code formatting and static analysis can be standardized through Maven profiles.

This consistency significantly reduces onboarding costs. In fact, my earliest blog posts about IoTDB were introductions to Maven-based release pipelines.

Performance: The Question Everyone Cares About

The most common concern is simple:

Can a database written in Java actually perform well?

Let’s start with facts.

In major public time-series database benchmarks—such as TPCx-IoT and benchANT—IoTDB ranks first in both read/write performance and cost efficiency. These benchmarks include databases written in:

  • Go (InfluxDB, VictoriaMetrics)
  • C (TimescaleDB)
  • C++ (ClickHouse)

IoTDB, written in Java, is not merely competitive—it leads.

Why?

Because databases are often described as the crown jewel of foundational software. Their difficulty does not come from language syntax or runtime mechanics, but from internal system complexity.

As database functionality grows, system complexity increases exponentially—much like governing a large city with countless departments, workflows, and dependencies. This complexity creates vast optimization opportunities: columnar storage, batching, pipelining, indexing, and more. Optimizing even a single execution path can yield order-of-magnitude performance gains.

Java’s garbage collection is frequently criticized, but in practice, it is a net positive feature—analogous to memory defragmentation at the OS level. Modern JVM GC algorithms are the result of decades of global engineering effort and perform remarkably well.

For special scenarios, databases can:

  • design smarter caching strategies
  • use off-heap memory
  • isolate memory-sensitive components

and do so transparently at the database layer.

In our production environments, we have never encountered a case where Java GC itself was the performance bottleneck. When serious GC pauses occur, they usually indicate either misconfiguration or memory leaks—issues typically identified and resolved during testing, often within the same day.

A database is a holistic system. No single technical advantage or disadvantage defines its success.

Lightweight Deployment Scenarios

Another frequent concern is whether Java databases can be deployed in edge or constrained environments.

There are two distinct scenarios:

Intelligent terminals

These devices may have limited resources (single-core CPU, 1–2 GB memory, tens of GB storage) but still support a full software stack. In such cases, Java poses no issue.

IoTDB can operate with memory footprints of just a few hundred megabytes, easily meeting edge read/write workloads. It is already running stably in satellite systems, airborne platforms, and power data collection terminals.

Embedded environments

Some embedded systems only support C/C++ runtimes, with tens of megabytes of memory and strict real-time constraints.

In many such cases, a full database is unnecessary; a lightweight file-based approach is often more appropriate. For this reason, we typically deploy the C++ implementation of TsFile, IoTDB’s time-series file format, on the device side and upload files upstream.

P.S. The C++ version of TsFile will be open-sourced soon.

Industrial control algorithms rarely require long-term historical data stored in databases. Real-time control logic prioritizes low time complexity and often keeps required historical data fully cached in memory.

As hardware capabilities improve, the focus should shift toward better data processing models, not merely raw resource constraints.

A Strong Java Talent Pool

A database company is not just about code—it depends on a reliable development and operations team.

Although database systems attracted significant attention during recent waves of innovation, participation remains relatively small compared to application-layer projects.

Our experience shows that excellent Java developers can successfully transition into database kernel development. They ramp up quickly, take ownership of modules, and begin contributing meaningful code in a short time.

So why does the perception persist that Java cannot be used to build databases?

Largely due to historical reasons.

Relational databases originated in the 1970s, while Java was introduced in 1995. By the time Java emerged, major databases had already been written in C for decades:

  • Oracle (1977)
  • PostgreSQL (1986)
  • MySQL (1995)

Early skepticism also surrounded the commercial viability of databases themselves—until Oracle proved otherwise.

Java followed a similar trajectory. Today, many high-performance middleware systems and databases—including IoTDB, Cassandra, and H2—demonstrate that Java performance is more than sufficient for database development.

Looking back over IoTDB’s decade-long journey, our ability to rapidly iterate on user demands while maintaining high stability and performance owes a great deal to Java.

Java is not only capable of building databases—it is well-suited for the task. This is not a theoretical claim, but a conclusion drawn from practice.

If you are a Java developer, you absolutely have the opportunity to build an excellent database.

If you’re curious about IoTDB, feel free to explore the project on GitHub—and join the community discussions and contributions.

Why Apache IoTDB Is Written in Java: A Decade of Engineering Trade-offs

Since I started working on the development of the time-series database Apache IoTDB in 2016, I’ve been asked the same question again and again:

Why did you choose Java to build a database? Can Java really be used to write a database system?

In the early days, my standard answer was usually this:

When IoTDB was initiated in 2011, almost all influential distributed systems and databases were built in Java or on the JVM—such as Hadoop, HBase, Spark (Scala on JVM), Cassandra, Kafka, and Flink. To integrate deeply with the big data ecosystem, choosing Java was a natural decision.

That explanation is valid—but clearly insufficient.

What people really want to know is:

  • If you learn Java, do you actually have a chance to build a database?
  • Can Java be used to build a good database?
  • What does choosing Java really mean for a system like IoTDB?
  • …

These questions cannot be answered by theory alone. The relationship between programming languages and databases is not a matter of ideology—it is a practical trade-off among language characteristics, system complexity, engineering investment, and long-term returns.

After nearly ten years of real-world exploration, we believe we can now give a more grounded answer. Below are the eight key considerations behind IoTDB’s choice of Java.

A Mature and Comprehensive Java Ecosystem

Queues, maps, heaps, locks, thread scheduling—nearly every common data structure and concurrency primitive has mature, well-tested implementations in the Java ecosystem. This allows database developers to focus their energy on core database logic and performance optimizations, rather than repeatedly reinventing low-level infrastructure.

More importantly, Java is widely used across enterprise platforms and applications. Middleware components in the Java ecosystem integrate smoothly with each other, which significantly lowers the learning curve for developers adopting Java-based databases. As a result, Java developers can more easily understand, operate, and extend a Java-written database system.

Code Readability and Long-Term Maintainability

This factor is often overlooked, but for someone who has spent years working on database internals, it is critical.

Databases are inherently complex systems. That complexity brings enormous optimization potential—but also substantial risk. A single subtle mistake can introduce severe bugs, which is why newer versions of some databases occasionally perform worse or become less stable than older ones.

Java’s object-oriented design provides a natural advantage in code readability and conceptual clarity. In practice, we have found that many community contributors are able to ramp up quickly by understanding IoTDB’s design principles and abstractions.

Readable code is not just a matter of elegance—it is a system’s lifeline. Only readable and understandable codebases can sustain long-term evolution without collapsing under their own complexity.

Operability and Debugging Efficiency

Most Java developers are familiar with exception handling and detailed stack traces in logs—and those stack traces are invaluable.

In our experience, when users report bugs in IoTDB, engineers can often locate the root cause within the same day, and rarely does debugging exceed one day. The stack information alone usually provides enough context to pinpoint the issue.

By contrast, in discussions with developers of C-based databases, diagnosing production issues such as memory leaks can sometimes take weeks or even months.

No language-level advantage matters more than system stability and recoverability. There is nothing more painful than a production database failure that cannot be quickly diagnosed or fixed.

JVM tooling such as JProfiler and Arthas gives Java developers powerful observability into runtime behavior, enabling fast root-cause analysis and remediation.

Cross-Platform Portability

Today, this is often referred to as localization or hardware adaptation.

Java’s promise of “write once, run anywhere” has proven extremely valuable as domestic and heterogeneous hardware platforms have become more common. For IoTDB, we have rarely needed special platform-specific adaptations—if Java can run, IoTDB can run.

This allows us to concentrate on coredatabase logic and optimization, instead of spending engineering effort on platform compatibility.

Efficient Project and Dependency Management

For anyone joining the IoTDB project, the first essential skill is understanding Maven.

Nearly all Java projects—large or small—use Maven for project structure, dependency management, compilation, packaging, and release workflows. Advanced tasks such as code formatting and static analysis can be standardized through Maven profiles.

This consistency significantly reduces onboarding costs. In fact, my earliest blog posts about IoTDB were introductions to Maven-based release pipelines.

Performance: The Question Everyone Cares About

The most common concern is simple:

Can a database written in Java actually perform well?

Let’s start with facts.

In major public time-series database benchmarks—such as TPCx-IoT and benchANT—IoTDB ranks first in both read/write performance and cost efficiency. These benchmarks include databases written in:

  • Go (InfluxDB, VictoriaMetrics)
  • C (TimescaleDB)
  • C++ (ClickHouse)

IoTDB, written in Java, is not merely competitive—it leads.

Why?

Because databases are often described as the crown jewel of foundational software. Their difficulty does not come from language syntax or runtime mechanics, but from internal system complexity.

As database functionality grows, system complexity increases exponentially—much like governing a large city with countless departments, workflows, and dependencies. This complexity creates vast optimization opportunities: columnar storage, batching, pipelining, indexing, and more. Optimizing even a single execution path can yield order-of-magnitude performance gains.

Java’s garbage collection is frequently criticized, but in practice, it is a net positive feature—analogous to memory defragmentation at the OS level. Modern JVM GC algorithms are the result of decades of global engineering effort and perform remarkably well.

For special scenarios, databases can:

  • design smarter caching strategies
  • use off-heap memory
  • isolate memory-sensitive components

and do so transparently at the database layer.

In our production environments, we have never encountered a case where Java GC itself was the performance bottleneck. When serious GC pauses occur, they usually indicate either misconfiguration or memory leaks—issues typically identified and resolved during testing, often within the same day.

A database is a holistic system. No single technical advantage or disadvantage defines its success.

Lightweight Deployment Scenarios

Another frequent concern is whether Java databases can be deployed in edge or constrained environments.

There are two distinct scenarios:

Intelligent terminals

These devices may have limited resources (single-core CPU, 1–2 GB memory, tens of GB storage) but still support a full software stack. In such cases, Java poses no issue.

IoTDB can operate with memory footprints of just a few hundred megabytes, easily meeting edge read/write workloads. It is already running stably in satellite systems, airborne platforms, and power data collection terminals.

Embedded environments

Some embedded systems only support C/C++ runtimes, with tens of megabytes of memory and strict real-time constraints.

In many such cases, a full database is unnecessary; a lightweight file-based approach is often more appropriate. For this reason, we typically deploy the C++ implementation of TsFile, IoTDB’s time-series file format, on the device side and upload files upstream.

P.S. The C++ version of TsFile will be open-sourced soon.

Industrial control algorithms rarely require long-term historical data stored in databases. Real-time control logic prioritizes low time complexity and often keeps required historical data fully cached in memory.

As hardware capabilities improve, the focus should shift toward better data processing models, not merely raw resource constraints.

A Strong Java Talent Pool

A database company is not just about code—it depends on a reliable development and operations team.

Although database systems attracted significant attention during recent waves of innovation, participation remains relatively small compared to application-layer projects.

Our experience shows that excellent Java developers can successfully transition into database kernel development. They ramp up quickly, take ownership of modules, and begin contributing meaningful code in a short time.

So why does the perception persist that Java cannot be used to build databases?

Largely due to historical reasons.

Relational databases originated in the 1970s, while Java was introduced in 1995. By the time Java emerged, major databases had already been written in C for decades:

  • Oracle (1977)
  • PostgreSQL (1986)
  • MySQL (1995)

Early skepticism also surrounded the commercial viability of databases themselves—until Oracle proved otherwise.

Java followed a similar trajectory. Today, many high-performance middleware systems and databases—including IoTDB, Cassandra, and H2—demonstrate that Java performance is more than sufficient for database development.

Looking back over IoTDB’s decade-long journey, our ability to rapidly iterate on user demands while maintaining high stability and performance owes a great deal to Java.

Java is not only capable of building databases—it is well-suited for the task. This is not a theoretical claim, but a conclusion drawn from practice.

If you are a Java developer, you absolutely have the opportunity to build an excellent database.

If you’re curious about IoTDB, feel free to explore the project on GitHub—and join the community discussions and contributions.

Looking for One Answer, Ending Up with Ten Tabs?

From Student to Apache IoTDB Committer

On September 9, 2025, following a community vote, Lin Xintao was officially elected as a Committer of the Apache IoTDB project.

Growing from a student contributor into a core committer of an Apache Top-Level Project, Lin describes his motivation in simple terms:

“Being able to contribute to a top-tier open source project, and seeing my work actually used in real production systems, gives me a strong sense of purpose and fulfillment.”

Lin earned his bachelor’s degree from the School of Software at Tsinghua University and is currently pursuing a master’s degree at the same institution. He began contributing to Apache IoTDB in April 2023 and has been an active contributor ever since.

About Apache IoTDB

Q: How did you first learn about Apache IoTDB?

I first encountered Apache IoTDB during my junior year as an undergraduate. In a database course taught by Professor Jianmin Wang, Tsinghua University, IoTDB was introduced as an Apache Top-Level Project incubated at the School of Software, Tsinghua University. That immediately caught my attention.

Later, I explored the IoTDB official website and its GitHub repositories in more depth. I became increasingly interested not only in its technical architecture, but also in how the community collaborates to drive feature iteration and long-term technical evolution.

Q: What made you decide to get involved in the Apache IoTDB project?

In April 2023, I joined the research team at the School of Software working on IoTDB as an intern. I was quickly drawn to the open and collaborative atmosphere, as well as the enthusiasm and mentorship from senior contributors.

Under the guidance of senior contributors Yukun Zhou and Yanze Chen, I began working on metadata management. Watching the system gradually improve through my own optimizations kept me deeply engaged and gave me a strong sense of achievement.

At the same time, I realized that IoTDB had already been deployed in many critical industrial scenarios. Being able to see my contributions run in real production environments through an open source community made the work feel genuinely meaningful. These experiences convinced me to continue contributing to Apache IoTDB through open source.

Q: Which areas of Apache IoTDB do you mainly work on?

My work primarily focuses on the query engine and metadata management engine, including:

  • Optimizing PBTree index concurrency and metadata storage structures to improve performance and scalability.
  • Implementing a set of SQL scalar functions, and refactoring the LIKE and regular expression matching engine.
  • Designing and implementing streaming time-series shape similarity search capabilities inspired by the Qetch approach.

Q: What have you gained from participating in the Apache IoTDB project?

Overall, contributing to IoTDB has been a very positive and rewarding experience👇

First, it strengthened my ability to think systematically. In production-grade infrastructure software, factors such as real-world requirements, architectural design, and operational stability all matter. Designing and implementing features in such an environment requires a much more holistic mindset.

Second, my collaboration and communication skills improved significantly. I’ve learned not only how to contribute as a team member, but also how to lead discussions, conduct reviews, and clearly communicate design decisions through documentation and technical discussions.

Third, it improved my time management skills and professional identity. Balancing academic work with a fast-paced open source project — while seeing my code used in real industrial systems — and being part of a high-quality technical community has given me a strong and lasting sense of accomplishment.

Q: Is there a memorable experience you’d like to share?

One particularly memorable experience was a collaboration with an airline company.

During the initial validation phase, we modeled their business data, developed efficient parsing and ingestion pipelines, and loaded the data into IoTDB. Compared with traditional solutions, both storage and query performance improved significantly.

However, once we entered their actual production environment, we realized that “whether a feature can be implemented” was not the top priority. Usability and stability were just as critical. Software not only needs to work — it needs to be easy to use and reliable in the long term.

After more than a month of continuous refinement, we delivered a complete IoTDB-based data management solution. It was highly recognized by the airline’s technical experts and has since played a real role in their digital transformation, data asset utilization, and intelligent analytics. For me, it was a grounded yet deeply rewarding experience.

Q: What helped you stay committed and eventually become a Committer?

What kept me going was a continuous sense of achievement and real-world impact.

On one hand, I could clearly see the system evolving — features improving, issues being fixed, and the project steadily becoming better. On the other hand, IoTDB supports real-world workloads for many well-known enterprises. Through ongoing collaboration, I gained deeper insights into system architecture and implementation details, and saw firsthand the value IoTDB delivers in critical industrial scenarios.

Apache IoTDB is not only an open source industrial database that is usable, reliable, and practical, but also a project with strong expectations around AI-driven capabilities and performance leadership. Contributing to such a project gives me a strong sense of pride and responsibility, which ultimately motivated me to take on the role of Committer.

About the Open Source Community

Q: Did you have any open source experience? Has your view of open source changed?

Before IoTDB, I had very limited experience with open source. Apache IoTDB was the first project where I truly participated deeply.

Through this experience, I came to appreciate how open source communities drive the evolution of foundational software like databases. Real feedback from users and developers in production environments allows features to adapt more quickly to real-world needs and helps the project mature continuously.

I also gained a deeper understanding of the Apache Software Foundation’s philosophy of “Community Over Code.” Open source is not just about making code public — it’s about collaborative innovation and knowledge sharing, bringing together people with shared goals to build high-quality software together.

Q: What value does the open source community bring to Apache IoTDB?

I think the community adds value in three key ways:

  • It significantly increases visibility and credibility, helping IoTDB be recognized as an open and trustworthy piece of infrastructure software.
  • It brings in real-world requirements and feedback from production environments, continuously driving feature evolution and ecosystem maturity.
  • It connects developers from different organizations and regions on a shared collaboration platform, enabling a level of cross-boundary cooperation that would be difficult for any single company to achieve alone.

Q: Any advice for newcomers who want to contribute to Apache IoTDB?

We warmly welcome anyone interested in contributing to Apache IoTDB.

My advice is to first get IoTDB running locally, use it actively, and ask questions. Raising issues on the mailing list or GitHub is both a learning process and a form of contribution.

For code contributions, beginners can start with documentation improvements, small bug fixes, or Good First Issues. Through code reviews, you’ll become familiar with the codebase and module structure before gradually taking on larger features.

Non-code contributions are equally important. Participating in technical discussions, sharing user experiences, or trying to answer questions can all help you integrate into the community more quickly.

Most importantly, don’t wait until you feel “ready” — just start contributing.

Becoming a Committer: Growing with the Apache IoTDB Community

For me, becoming an Apache IoTDB Committer is both an honor and a responsibility.

Since joining the community, I’ve benefited greatly from the patience and guidance of experienced contributors. Now, being able to help newcomers through reviews and discussions feels like both a continuation of that spirit and a new stage of growth.

The Committer role represents the community’s trust in my work and reminds me to hold myself to higher standards, continue contributing consistently, and give back to the community. I look forward to growing together with more contributors in the Apache IoTDB community over the long term.

Graph Databases for Travel: How Martin Tuncaydin Maps Routes, Hubs, and Connections

Graph Databases for Travel: How Maps Routes, Hubs and Connections

Over two decades working at the intersection of travel technology and data architecture, I’ve watched the industry wrestle with a fundamental challenge: how do you model the intricate web of connections that make modern travel possible? Traditional relational databases force us to flatten what is inherently a network problem—flights connecting airports, trains linking stations, buses bridging cities, all woven together into a tapestry of possible journeys.

The answer, I’ve found, lies in graph databases. Not as a trendy alternative to SQL, but as the natural data structure for representing how the world actually moves.

Why Travel Data Belongs in a Graph

When I first encountered graph databases in the early 2010s, I was skeptical. Another NoSQL movement promising to solve everything? But as I began modeling multi-modal journey planning scenarios, something clicked. The relationship between London Heathrow and Paris Charles de Gaulle isn’t just a row in a flights table—it’s a weighted edge in a living network, influenced by time, cost, carrier, and a dozen other factors.

In graph terminology, every airport, train station, bus terminal, and ferry port becomes a node. Every possible connection between them becomes an edge. Properties on those edges—duration, price, frequency, carbon footprint—become queryable attributes. Suddenly, questions like “What’s the fastest route from Barcelona to Copenhagen with no more than one connection?” transform from complex multi-table joins into elegant graph traversals.

I’ve worked with datasets containing millions of routes across air, rail, and ground transportation. In a relational model, even with careful indexing, these queries bog down. Graph databases like Neo4j treat relationships as first-class citizens, storing them in a way that makes traversal essentially constant time. The database doesn’t reconstruct the network at query time—it already is the network.

Neo4j: The Cypher Advantage

My first production graph deployment used Neo4j, and I chose it for one reason: Cypher. The query language feels like drawing on a whiteboard. When I need to find all routes from Amsterdam to Vienna that connect through major hubs, I can write a query that reads almost like plain English.

The pattern-matching syntax lets me express complex routing logic intuitively. I can specify that I want routes with exactly two segments, where the layover is between 45 minutes and 3 hours, and the total journey time doesn’t exceed eight hours. In SQL, this would span multiple CTEs and subqueries. In Cypher, it’s a single, readable pattern.

What I particularly value about Neo4j is its ACID compliance. Travel booking isn’t just about finding routes—it’s about transactional integrity. When a customer books a multi-leg journey, I need guarantees that the entire itinerary gets reserved atomically. Neo4j’s transactional model gives me that confidence while maintaining graph traversal performance.

The built-in graph algorithms have proven invaluable. Shortest path algorithms help find the quickest routes. PageRank-style centrality measures identify hub airports that matter most to network connectivity. Community detection reveals natural groupings of destinations that frequently get booked together, informing marketing strategies and partnership opportunities.

I’ve also appreciated Neo4j’s visualization tools during stakeholder presentations. Being able to render the actual network graph—showing how new routes integrate into existing infrastructure—makes strategic discussions far more concrete than spreadsheets ever could.

TigerGraph: Scale and Real-Time Analytics

As my work expanded to global-scale route optimization and real-time pricing scenarios, I encountered TigerGraph. While Neo4j excelled at transactional workloads and medium-scale analytics, TigerGraph brought a different strength: distributed graph processing at massive scale.

TigerGraph’s native parallel graph architecture means I can run deep graph analytics across billions of edges without the performance cliff I’d hit with single-server solutions. For travel networks spanning every commercial route globally, with historical data going back years, this matters enormously.

The GSQL query language took some adjustment—it’s more procedural than Cypher’s declarative style—but it unlocks powerful real-time analytics (a pattern I keep running into). I’ve built systems that continuously analyze route profitability by modeling not just direct connections but the ripple effects through the entire network. When a carrier adjusts pricing on one route, TigerGraph helps me understand the cascading impact across alternative routing options.

One project that stands out involved dynamic pricing optimization for multi-modal journeys. The graph represented every possible combination of air, rail, and bus segments across Europe. As demand shifted in real-time—say, a major conference announced in Berlin—TigerGraph’s streaming graph analytics recalculated optimal pricing across thousands of affected routes in seconds, not hours.

The distributed nature of TigerGraph also proved crucial for geographic redundancy and low-latency access. I could partition the graph so that European route queries hit servers in Frankfurt while Asian queries hit Singapore, all while maintaining a unified global network view.

Multi-Modal Journey Planning: Where Graphs Shine

The real test of any data architecture is how well it solves actual business problems. For multi-modal journey planning, graph databases aren’t just better than relational alternatives—they’re often the only practical solution.

Consider the problem of finding the most sustainable route from London to Edinburgh. In a graph model, I create nodes for every departure point and arrival point across all transport modes. Edges represent individual journey segments—a train from London King’s Cross, a bus from London Victoria, a flight from London Gatwick. Each edge carries properties: duration, cost, and critically, carbon emissions.

Now I can query for routes that minimize carbon footprint, perhaps with constraints on total journey time or cost. The graph database naturally handles the complexity of comparing a direct flight against a train journey against a combination of bus and rail. I’m not joining tables—I’m walking a network.

Layover optimization becomes equally elegant. In traditional systems, ensuring that a train arrival at Paris Gare du Nord allows sufficient time to reach Paris Charles de Gaulle for a flight requires careful temporal logic and distance calculations. In a graph, I model both locations as nodes, add an edge representing the transfer with its duration property, and let the graph algorithms handle the rest.

I’ve built systems where users specify soft preferences—”I prefer trains to planes,” “Avoid overnight layovers,” “Maximize time in daylight”—and the graph scoring functions weight edges accordingly. This turns journey planning from a binary optimization problem into a nuanced ranking exercise that reflects real human preferences.

Modeling Hub Dynamics and Network Effects

One of the most fascinating applications I’ve explored is using graph analytics to understand hub dynamics. In travel networks, not all connections are created equal. Frankfurt, Amsterdam Schiphol, and Dubai International aren’t just airports—they’re super-connectors whose operational efficiency affects the entire network.

Using graph centrality algorithms, I can quantify hub importance in ways that go beyond simple passenger volume. Betweenness centrality reveals which airports sit on the most shortest paths between other destinations. If that airport faces disruption, the cascading impact ripples through countless itineraries. No exceptions.

I’ve applied these insights to disruption management. When weather closes an airport, the graph database helps identify which alternative routes exist and what capacity they have. Instead of panicking rebooking agents searching manually, the system automatically proposes viable alternatives based on real network topology.

Community detection algorithms have revealed surprising patterns. I discovered that certain city pairs, despite being geographically distant, formed tight communities of frequent travelers—business corridors that warranted premium service even if raw passenger numbers didn’t obviously justify it. The graph saw what aggregated statistics missed.

Temporal graphs add another dimension. By modeling how the network changes throughout the day—when flights depart, when trains run, when buses operate—I can find routes that are theoretically possible but practically unavailable because timing doesn’t align. This prevents suggesting itineraries that look good on paper but can’t actually be booked.

Practical Considerations and Lessons Learned

Implementing graph databases in production isn’t without challenges, and I’ve learned several hard lessons along the way.

Data modeling requires different thinking. In relational design, I normalize aggressively to reduce redundancy. In graph design, I often denormalize deliberately, storing properties on edges that I might otherwise factor into separate entities. The goal is traversal efficiency, not storage efficiency.

Schema evolution is trickier than I initially appreciated. While graph databases are often marketed as “schema-less,” production systems need consistency. I’ve developed versioning strategies for node and edge types, ensuring that schema changes don’t break existing queries or corrupt data.

Performance tuning is different too. Relational database optimization focuses on indexes and query plans. Graph optimization centers on graph topology—minimizing the branching factor of traversals, choosing appropriate starting nodes, and leveraging graph-specific indexes on properties that guide path-finding.

I’ve also learned that graph databases complement rather than replace relational systems. For transactional booking data, customer profiles, and financial records, PostgreSQL remains my foundation. The graph database handles network analysis and route finding, then hands off to the relational system for the actual booking transaction.

Integration patterns matter enormously. I usually maintain a near-real-time sync from operational systems into the graph, using change data capture to update route availability, pricing, and capacity as they evolve. The graph is a living reflection of the bookable network, not a static snapshot.

The Strategic Value of Network Thinking

What excites me most about graph databases in travel isn’t the technology itself—it’s the shift in thinking they enable. When you start seeing your business as a network rather than a collection of tables, strategic questions change.

Instead of asking “How many passengers flew this route?” I ask “What role does this route play in the overall network?” Instead of “Which destinations are most popular?” I wonder “Which destinations unlock access to entire regions?”

This network perspective has informed partnership strategies. By modeling codeshare agreements and interline relationships as edges between carrier nodes, I can analyze which partnerships create the most new reachable destination pairs. Some partnerships look insignificant in isolation but become strategically vital when viewed through the network lens.

Revenue management transforms too. Traditional yield management optimizes individual route profitability. Network revenue management, powered by graph analytics, recognizes that a loss-leading route might feed highly profitable onward connections. The graph helps quantify that strategic value.

My View on the Future of Travel Data Architecture

I believe we’re still in the early innings of applying graph thinking to travel technology. The industry has barely scratched the surface of what’s possible when you model the full complexity of modern travel networks—not just routes, but passenger flows, luggage transfers, crew scheduling, maintenance dependencies, and more.

The convergence of graph databases with machine learning particularly excites me. Graph neural networks can learn patterns in route performance that traditional analytics miss. They can predict disruption cascades, recommend personalized itineraries, and optimize pricing in ways that account for the full network context.

As travel becomes increasingly multi-modal—with micro-mobility, ride-sharing, and autonomous vehicles adding new layers to traditional air-rail-bus networks—graph databases will become not just useful but essential. The complexity will exceed what relational models can tractably handle.

What I’ve learned through years of building these systems is that the best technology feels inevitable in hindsight. Once you model travel data as a graph, returning to relational tables feels like trying to describe a city using only a list of addresses. The connections are the story. The network is the reality. And graph databases are simply the most honest way to represent it.

About Martin Tuncaydin

Martin Tuncaydin is an AI and Data executive in the travel industry, with deep expertise spanning machine learning, data engineering, and the application of emerging AI technologies across travel platforms. Follow Martin Tuncaydin for more insights on graph databases, travel technology.

Your problem has been solved before. AI just can’t find it. (Chapter 1. The idea)

Like most IT people, I adopted AI tools early. I’m using it every day as part of my job, but due to the specificity of work tasks that I do as a System Engineer/DevOps, I’m still not fully confident in using AI agents on infrastructure or OS’s. That’s why I mostly use AI chatbots like Claude or ChatGPT which really helps. AI chat is great.

But being great doesn’t mean it’s perfect.

Years ago, before the AI era, while trying to solve complex tasks and you hit a wall, the most common source of information was Stackoverflow and forums with the help of Google search. AI replaced that today. But did it really replace it? How many times has happened to all of us that while solving problems with an AI chatbot it suddenly loops, repackaging the same ideas, repeating solutions and constant suggestions of what needs to be done, never ending? Sounds familiar? If you try to correct it and say: “Hey, that’s not true, not correct”, then you write why, it will confidently tell you: “You are absolutely right, here is why”. Frustrating, right? Even if you start a new session with a summarized current one you will probably find yourself in the same situation as before.

I’m aware of the fact that it’s just a tool without cognition, but knowing what frustrates me doesn’t make me less frustrated.

While AI tools are an inevitable thing in our work today, I’m still one of those who likes to think with their own brain and to critically approach a problem before making an important decision. I tried to use AI as advanced search like: ”Find me all posts from X forum that have Y tag in the last 2 months” (or years, or different parameters, doesn’t matter), it can’t, doesn’t work like that. Usually it offers like 10 random urls, if you prompt it again it will extract another 10 random urls and so on. Well, it’s understandable, it is pattern-based, not some scraping tool.

Then I got an idea.

What if an AI chatbot, instead of generic pattern-based response, can actually access real projects and pull out solutions? Imagine this, you complain to an AI chatbot that your Laravel project is slow. Any pattern-based AI chatbot is unaware of the real problem because you still haven’t provided it with information, so it will ask you for it, but at the same time it will bomb you with suggestions of where to look and what to fix. So, what if AI asks you to provide more information, the questions any IT expert would ask — what hardware you’re running, what kind of traffic you’re dealing with, whether other services are connected, bare metal or VM.

After you provided it with useful information, AI would search in the knowledge base and pull out all use-cases and case studies based on your prompts and results would be: “I’ve found 10 projects where 7 of them have solved the issue like yours” and then write down summarized solutions. Or it can be reversed: “ I’ve found 10 projects where 7 of them have failed with your suggestion and here is why”. It can also display posts, what people talked about, and provide urls if they exist…

So, why can this be important?

Well, with this real data type, statistical and precise, I would know if my way of finding a solution is right or wrong, it could solve a problem or just tell me that I’m going in the wrong direction, it would save me a lot of time. I liked this idea very much and I’m going to start developing this kind of tool. I personally never developed any type of AI tool and I think it’s going to be a great adventure.