Makyajlı Volkswagen Caddy görücüye çıkarıldı

Makyajlı Volkswagen Caddy görücüye çıkarıldı

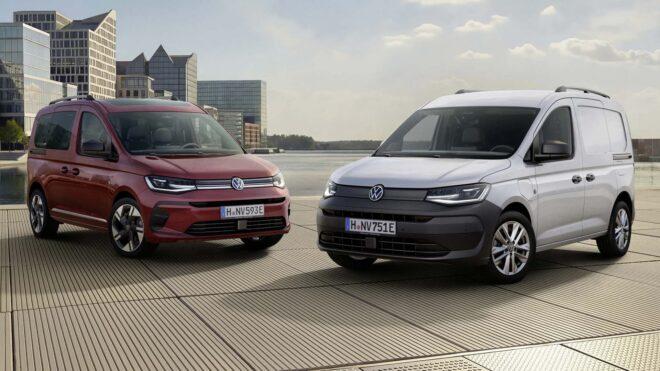
Makyajlı Volkswagen Caddy görücüye çıkarıldıİlk bilgilerin geçtiğimiz hafta verildiği makyajlı Volkswagen Caddy, bugün resmi olarak görücüye çıkarıldı. Araçta, yukarıdaki galeride görebileceğiniz üzere görsel açıdan büyük bir değişim karşımıza çıkmıyor. Mevcut modelin petek desenli tamponunu daha geleneksel bir tamponla değiştiren Volkswagen, modelin ticari versiyonunda gövde renginden bağımsız siyah plastik tamponlar kullanıyor. İki farklı dingil mesafesi seçeneğiyle elde edilebileceği söylenen Caddy’nin yaşam alanında önemli değişiklikler olduğunu belirten ancak henüz herhangi bir fotoğraf paylaşmayan şirket, Almanya’da üretilecek makyajlı modelin benzinli, dizel ve şarj edilebilir hibrit seçenekleriyle alınabileceğini belirtiyor. 148 beygir gücüne sahip eHybrid modelin 19,7 kWh batarya ile 122 km’lik tamamen elektrikli sürüş menzili sunacağı aktarılırken yılın ikinci yarısında satışa sunulacak model için yeni jant ve renk seçeneklerinin hazırlandığı ifade ediliyor.

Makyajlı Volkswagen Caddy görücüye çıkarıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Michelin, elektrikli araçların menzilini artırabilen yeni lastikler tanıttı

Michelin, elektrikli araçların menzilini artıran yeni lastikler tanıttı

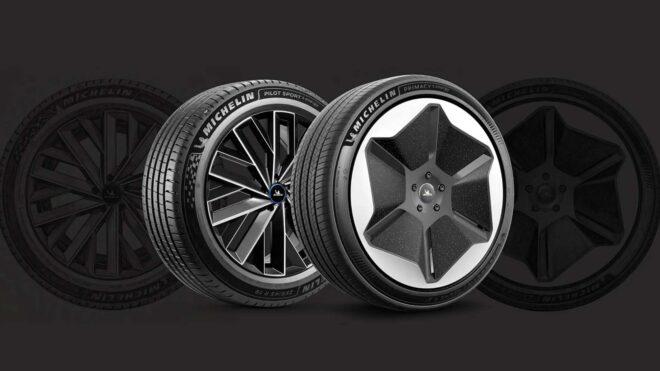
Michelin, elektrikli araçların menzilini artıran yeni lastikler tanıttıMichelin, elektrikli araçların menzilini artıran yeni Primacy 5 Energy ve Pilot Sport 5 Energy lastiklerini tanıttı. Yüksek verime odaklanan lastiklerden Primacy 5 Energy, şirketin resmi verilerine göre tamamen elektrikli bir araca takıldığında menzili yüzde 10’a kadar artırarak ekstra 70 kilometre sürüş sunabiliyor. Lastik, standart içten yanmalı araçlarda kullanıldığında ise yakıt verimliliğini yüzde 6 civarında iyileştirip 100 kilometrede 0,3 litre tasarruf sağlayabiliyor. Önceki modele kıyasla fren mesafesini yüzde 8 oranında azaltabilen Pilot Sport 5 Energy ise doğrudan daha yüksek performanslı otomobillere odaklanıyor. Yuvarlanma direncini azaltmak amacıyla özel malzemelerin kullanıldığı lastik, şirketin testlerine göre ıslak ve kuru zeminde frenleme açısından Hankook iON Evo SUV ve Pirelli P Zero E’den daha iyi sonuç veriyor. 16 inçten 19 inçe kadar 33 farklı boyutta hazırlandığı aktarılan  yeni lastikler, yakında Türkiye’de de satışa sunulabilir.

Michelin, elektrikli araçların menzilini artırabilen yeni lastikler tanıttı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Telegram, yapay zeka temelli metin editörü ve fazlasını duyurdu

Telegram

TelegramTelegram, bugün yapay zeka temelli metin editörü ve fazlasını duyurdu. “Bugünkü güncellemede, metninizi sadece iki dokunuşla çevirebilen, dönüştürebilen veya düzeltilebilen bir YZ Editörü, aktif anketler için medya ekleme ve yeni yanıt önerme gibi yeni anket özellikleri, tüm uygulamalarda Canlı ve Hareketli Fotoğraflar desteği, diğer botları oluşturabilen ve yönetebilen botlar ve daha fazlasını sunuyoruz.” diyen şirket, yeni özellikler için ek olarak şu bilgilere yer verdi: “Mesaj çubuğunda artık, dil bilgisi hatalarını anında düzelten, metninizi farklı bir üslupta yeniden yazan veya mesajınızı başka bir dile çeviren, açık kaynaklı yapay zeka modelleriyle çalışan yerleşik bir düzenleyici bulunuyor. Metin düzenleyici, iletişiminizi daha verimli hale getirmek veya sohbetlere eğlenceli bir hava katmak için kullanabileceğiniz Resmi, Kısa, Tribal, Zen, Biblical ve Viking gibi farklı stiller sunar.” Anket sistemine 10’dan fazla yeni özellik getiren Telegram, artık iOS tarafında Canlı Fotoğraflar ve Android Hareketli Fotoğraflar’ı doğrudan destekliyor; böylece kullanıcılar herhangi bir uygulamada görüntülenebilen döngüsel fotoğraflar gönderebiliyor. “Kullanıcılar artık […]

Telegram, yapay zeka temelli metin editörü ve fazlasını duyurdu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Kingdom Come: Deliverance serisinin geliştiricisi bir “Yüzüklerin Efendisi” oyunu hazırlıyor olabilir

Kingdom Come: Deliverance serisinin geliştiricisi, bir Yüzüklerin Efendisi oyunu geliştiriyor olabilir.Kingdom Come: Deliverance serisinin başarılı geliştiricisi Warhorse Studios, Ryszard Chojnowski tarafından ortaya atılan iddiaya göre oldukça büyük bir “Yüzüklerin Efendisi (The Lord of the Rings)” oyunu geliştiriyor olabilir. 100 milyon dolarlık bir bütçeyle hazırlandığı öne sürülen “RPG” türündeki açık dünya yapım, efsane evren için şimdiye kadar hazırlanmış en iyi oyunlarda biri olabilir. Kingdom Come: Deliverance 2’yi yaklaşık 40 milyon dolarlık bütçeyle hayata geçirdiği aktarılan Warhorse Studios, RPG konusunda çok tecrübeli bir şirket; ancak şimdiye kadarki en büyük projesi için başka stüdyolardan da yardım alabilir.

Kingdom Come: Deliverance serisinin geliştiricisi bir “Yüzüklerin Efendisi” oyunu hazırlıyor olabilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Kia Türkiye Genel Müdürlüğü’ne Şafak Savcı atandı

Kia Türkiye

Kia TürkiyeBugün yapılan resmi açıklama ile duyurulduğu kadarıyla Kia Türkiye Genel Müdürlüğü’ne “Şafak Savcı” atandı. Otomotiv dünyasında 20 yılı aşkın bir deneyime sahip olduğu aktarılan Savcı’nın kariyeri hakkında şunlara yer verildi: “İstanbul Teknik Üniversitesi Makine Mühendisliği Bölümü’nden mezun olan Savcı, yüksek lisans eğitimini Koç Üniversitesi İşletme (MBA) programında tamamladı. Kariyerine 2004 yılında satış alanında başlayan Savcı; pazarlama, ürün yönetimi, iş geliştirme ve filo yönetimi alanlarında çeşitli görevler üstlendi. Ağustos 2016’da Anadolu Grubu şirketlerinden Çelik Motor bünyesinde Kia Türkiye Satış Direktörü olarak görev alan Savcı, 2021 yılında araç kiralama markası Garenta’nın Genel Müdürü olarak atandı. 2026 yılında kurulan Praticar’ın Genel Müdürlüğü görevini de eş zamanlı olarak üstlenen Savcı, görev süresi boyunca Çelik Motor bünyesinde hayata geçirilen çeşitli markaların kuruluş, yönetim ve büyüme süreçlerine liderlik etmiş; operasyonel yapıların güçlendirilmesine önemli katkılar sağlamıştır. Şafak Savcı, 1 Nisan 2026 itibarıyla üstlendiği yeni görevinde; stratejik vizyonu ve sektör deneyimiyle Kia Türkiye’nin otomotiv pazarındaki yolculuğuna liderlik ederken, […]

Kia Türkiye Genel Müdürlüğü’ne Şafak Savcı atandı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

3 Takeaways from All Things AI: 80/20 Rule, Non-Deterministic Humans, and Why We’re Still Early

Last week, I attended All Things AI in Durham, NC. The event was geared toward technical AI practitioners with workshops on Day 1 and standard conference talks on Day 2. A few takeaways from the conference are below for y’all!

MLH AI Roadshow

On Day 1, I helped Major League Hacking (MLH) run an AI Roadshow. We’re hosting about one of these a month right now. Some are standalone events. Others have been at partner conferences. I think you’ll see us again at All Things Open in the fall.

At the AI Roadshow, we run ~6 practical, hands-on-keyboard activities. You walk up and use a ready-to-go laptop to learn a new skill or technique with AI. We typically have snacks, drinks, and networking throughout the events. If you want to keep an eye on the next stop, check out our Luma.

MLH AI Roadshow

The 80/20 Rule in Practice

(Inspired by Justin Jeffress: Vibe Coding in Action)

I enjoyed Justin’s whole talk, but he had a specific slide on the 80/20 rule that is still sticking with me. AI feels really good at getting you 80% of the way there on most problems.

What do you do with that remaining 20%, though? Justin’s advice was to simply repeat. Send the “remaining” 20% back to your AI tool of choice.

I’ve been doing this myself for a while with coding agents, but this talk has me thinking again about the effectiveness of simple loops and repetition. I imagine this advice hasn’t penetrated to folks who mostly use AI through chat applications. It might also not work as well for outcomes that can’t be tested. But the framing really resonated with me.

Humans Are Also Non-Deterministic

(Inspired by Calvin Hendryx-Parker: Orchestrate Agentic AI)

Through my work at MLH, I’m constantly talking to software developers. The last ~18 months have been even more intense, driven by all the AI development.

A common concern I haven’t felt ready to address is that AI tools are non-deterministic. I get it. When you’re writing code, you’re building for specific outcomes. I think devs like the certainty.

Calvin made a small comment during his talk, reminding the audience that humans are also non-deterministic. The observation really hit home. I knew this. I’m sure you know it, too. But it was a good reframe. Process-driven thinking and guardrails feel suddenly important.

We’re Still So So Early

(Just a personal reflection)

Like many of you, I’ve been following AI heavily recently. It’s been important for the work I’m doing at MLH. It’s so easy to get caught up in the fad-of-the-week on Twitter. But the reality is that most people still aren’t leveraging AI tools. Especially not to their maximum capabilities.

Even at a conference for AI practitioners, I met people who hadn’t used a coding agent. There were jokes about OpenClaw and Mac Minis, but not everyone was “in the know”.

We’re still so damn early in this wave of change. No time like the present to roll up your sleeves and give something a try yourself. I still think learning by doing is the right methodology with AI tools.

Happy hacking!

Site Audit Checklist: Onboarding a New Client for Performance Monitoring

Most onboarding checklists are either too light (“run a test and send a report”) or too heavy (a long enterprise worksheet no one follows). Agency teams need something in between: a practical checklist you can run repeatedly, with enough structure to avoid blind spots.

This guide is built for teams onboarding client sites into ongoing performance monitoring. The goal is clear: move from “new client handover” to “monitoring is live, scoped, and actionable” without spending two weeks in setup mode.

If you need the monthly review workflow after onboarding, pair this with Monthly Performance Review Template for Agency Teams.

What teams usually need from a site audit checklist

Most teams need three things from an onboarding checklist:

  1. A template they can copy directly.
  2. A sequence of actions in the right order.
  3. Clarity on what matters most in the first week.

This article covers all three. It starts with a copy/paste checklist, then explains how to use each section so your first monitoring cycle produces decisions, not just numbers.

Before you touch tools: lock scope and ownership

Do not begin with a full crawl and a 200-row spreadsheet. Start with agreement.

For each client, lock these five items first:

  • Primary domain and critical subdomains
  • Priority templates (homepage, lead form, pricing, service/product, checkout)
  • Mobile and desktop coverage
  • Reporting cadence (weekly internal, monthly client-facing)
  • Alert recipients and first-response owner

If you skip this step, the first client conversation usually becomes “why are these pages here?” instead of “what do we fix first?”

Site audit checklist (copy/paste template)

Use this in your docs tool, ticketing system, or onboarding runbook.

// Site Audit Checklist — Performance Monitoring Onboarding
// Client: [NAME]
// Domain(s): [DOMAIN]
// Owner: [NAME]
// Date: [YYYY-MM-DD]

1) Access and context
- [ ] Confirm primary domain + environments (prod/stage)
- [ ] Confirm CMS / stack basics (WordPress, Shopify, custom, etc.)
- [ ] Confirm deployment owner / technical contact
- [ ] Confirm analytics and consent constraints

2) URL inventory
- [ ] Pull URLs from sitemap(s)
- [ ] Add business-critical URLs manually (pricing, lead form, key landing pages)
- [ ] Remove obvious noise pages (search params, utility pages, test paths)
- [ ] Group pages by template type where possible

3) Measurement setup
- [ ] Enable mobile + desktop testing
- [ ] Set test frequency by site priority
- [ ] Confirm test quota and page limits match plan
- [ ] Confirm data retention expectation (30/90/365 days or plan default)

4) Baseline capture (first run)
- [ ] Run initial tests for priority pages
- [ ] Record baseline LCP / INP / CLS and performance score
- [ ] Mark currently failing pages and highest-severity regressions
- [ ] Note pages with no field data so expectations are clear

5) Budgets and alerts
- [ ] Set initial thresholds (LCP, INP, CLS) per site/template
- [ ] Set alert channels (email / Slack / webhook where available)
- [ ] Confirm cooldown and escalation owner
- [ ] Confirm who receives alerts and who owns first response

6) Reporting readiness
- [ ] Decide client-facing summary format (call, email, PDF/report link)
- [ ] Define monthly review owner and calendar slot
- [ ] Draft first "what we monitor and why" note for client
- [ ] Confirm next review date

7) Handover
- [ ] Create top 3 actions from baseline findings
- [ ] Assign owner + due date for each action
- [ ] Log blockers (hosting, scripts, release dependencies)
- [ ] Share final onboarding summary internally

How to run each section without adding overhead

The checklist above is the scaffold. This section explains how to keep it efficient.

1) Access and context

This is where most onboarding delays begin. The most common blocker is not technical complexity; it is missing ownership.

Minimum acceptable output from this section:

  • one technical contact who can approve changes,
  • one business contact who can prioritise pages,
  • one statement on environment scope (production only, or production + staging).

If that is not settled, pause setup and resolve it before running baseline tests.

2) URL inventory

Start with sitemap URLs, then force-add business-critical pages. Sitemaps are useful, but they often miss campaign pages, dynamic pricing paths, or recently launched funnels.

A practical first pass for most sites:

  • 1 homepage URL
  • 2-5 conversion URLs (pricing, lead form, checkout, booking)
  • 5-10 high-traffic content or service templates

That gives you enough coverage to catch meaningful regressions without drowning your team in low-value alerts.

3) Measurement setup

Always enable both mobile and desktop. Even if the client says “our users are mostly desktop”, mobile regressions still affect search visibility and user experience on mixed traffic.

Set test cadence based on risk:

  • high-change sites: daily
  • medium-change sites: weekly
  • stable sites: weekly or monthly

Avoid a false precision setup where every site gets the same frequency. Match cadence to release behaviour and business risk.

4) Baseline capture

A baseline is not “export all scores”. It is a snapshot you can compare against in four weeks.

For each priority page, record:

  • current LCP, INP, CLS
  • current performance score
  • current status (within threshold / out of threshold)
  • one likely cause if out of threshold
  • one likely business impact

That last two lines are what make the baseline usable in client calls.

5) Budgets and alerts

Budgets and alerts are where monitoring becomes operational.

Do not over-tune on day one. Set initial thresholds, then adjust after one month of data. The objective is a stable signal, not perfect thresholds in the first week.

When setting alert channels, define response paths explicitly:

  • who receives first alert,
  • who triages,
  • who communicates externally,
  • what counts as escalation.

Without this, alerts become noise and trust drops quickly.

6) Reporting readiness

If the client is onboarding, they need clarity more than polish.

First-cycle reporting should answer:

  1. What we monitor.
  2. What is currently failing.
  3. What we will fix first.
  4. What we need from you (if anything).

You can upgrade format later (dashboards, PDFs, branded summaries). Start with consistency.

7) Handover

A clean handover has only three mandatory outputs:

  • top three actions,
  • owner and due date for each action,
  • known blockers.

If you end onboarding without those, you have setup but not momentum.

Priority matrix for first-week triage

Use this quick matrix when multiple regressions appear at once:

Impact Effort Priority
High business impact Low effort Do first
High business impact High effort Plan this cycle
Low business impact Low effort Batch with other fixes
Low business impact High effort Backlog unless it trends worse

This keeps your first month focused on visible wins rather than interesting low-impact fixes.

Common onboarding mistakes and how to avoid them

Tracking too many pages too early

A long page list feels thorough, but it slows triage and increases alert fatigue. Start with the minimum meaningful set, then expand after your first review cycle.

No alert owner

Shared inbox alerts with no owner create silent regressions. Assign one response owner before the first scheduled run.

Baseline with no narrative

“LCP is 3.8s” alone is not useful. Pair every key metric with context:

  • page type,
  • suspected cause,
  • likely user/business impact.

That turns metrics into decisions.

Promise mismatch on reporting

Do not promise polished monthly packs before setup stabilises. First cycle should prioritise baseline clarity and top actions.

Mixing diagnosis with onboarding

Onboarding is not root-cause analysis on every issue. Capture the issue, assign severity, and create an action list. Deep diagnosis can run in delivery sprint time.

Suggested first-month cadence after onboarding

Use a straightforward rhythm:

  • Week 1: onboarding, baseline, first top-three action list
  • Week 2: ship highest-impact fixes
  • Week 3: verify against fresh runs
  • Week 4: run monthly review and reset priorities

If thresholds still feel loose, use Performance Budget Thresholds Template before your first full client review.

Example onboarding summary you can send to a client

Use this short format once setup is complete:

This is usually enough for the first cycle. You can move to a fuller monthly format once trends are visible.

FAQ

How many pages should we include in the first onboarding pass?

Usually 10-20 priority URLs is enough for a reliable baseline. Expand only after your team can keep up with triage.

Should we onboard mobile first or both mobile and desktop?

Both. One-device monitoring hides regressions and creates reporting gaps.

Do we need complete page-type classification before monitoring starts?

No. Start with practical buckets (homepage, conversion pages, core templates), then refine over time.

What if the client has no clear target thresholds yet?

Use pragmatic starter thresholds, mark them provisional, and revise after one month of observed data.

How long should onboarding take per client?

For typical brochure/ecommerce sites, setup and first baseline can usually be done in 30-90 minutes if ownership and access are clear.

What should we do if alerts spike in week one?

Check whether scope is too broad or thresholds are too strict. Triage by business impact and fix ownership before widening coverage.

A good site audit checklist does more than capture URLs and scores. It creates operating rhythm: clear scope, clear owners, and clear next actions. That is what makes monitoring useful after month one.

How I Fingerprint My Own API to Catch Scrapers

TL;DR: Once you’ve stripped fingerprints from your data sources (Part 7), flip the script. Add your own watermarks so you can trace leaks back to specific customers. Coordinate jitter, price bucket skew, phantom records, and invisible text markers. All deterministic, all traceable, all invisible to users.

In Part 7, I discussed how to remove inbound fingerprints from your API responses. This includes things such as coordinates, addresses, pricing, etc.

This was defense.

This is offense.

Now that you have paying customers, each with a unique API key, you can add a watermark to each API response that will allow you to track who is using your information. Want to know who’s selling your data on a competitor’s site after six months? Well, you’ll know.

These same techniques that catch plagiarizers, these same techniques that Google Maps uses to catch copycats, these same techniques that encyclopedias use to catch thieves.

Here’s some ideas on how you can implement them, and one important notice about these techniques: they have to be non‑destructive, meaning watermarks must survive reasonable downstream transformations you expect customers to apply.

The Concept: Deterministic Watermarks

The key insight is that watermarks must be:

  1. Invisible — They aren’t visible to the user

  2. Deterministic — Same input + same API key = same watermark

  3. Unique — Different API keys should yield different watermarks

  4. Verifiable — Prove that the leak came from one customer

If Customer A’s data is showing up somewhere it shouldn’t, you can hash their API key with the original values and verify the watermark.

Technique 1: Coordinate Jitter

This is the highest signal, lowest effort watermark. Add deterministic noise to coordinates based on the customer’s API key.

import hashlib

def watermark_location(lat, lng, api_key):
    """
    Add deterministic jitter to coordinates.
    ~10–30m offset, unique per customer, invisible on maps.
    """
    seed = f"{api_key}:{lat}:{lng}".encode()
    h = hashlib.sha256(seed).digest()

    # Map bytes to a bounded jitter range
    lat_jitter = (int.from_bytes(h[:4], "big") % 600 - 300) / 1_000_000
    lng_jitter = (int.from_bytes(h[4:8], "big") % 600 - 300) / 1_000_000

    return lat + lat_jitter, lng + lng_jitter

Customer A sees: 41.8997, -87.6220

Customer B sees: 41.8999, -87.6222

They are both correct up to ~10 meters. They both work perfectly for mapping. They are different, however – and that difference is deterministic.

Verification

If you suspect a leak, take the coordinates from the leaked data and verify:

def verify_watermark(leaked_lat, leaked_lng, original_lat, original_lng, suspect_api_key):
    """Check if leaked coordinates match a specific customer's watermark."""
    expected_lat, expected_lng = watermark_location(original_lat, original_lng, suspect_api_key)

    # Allow small tolerance for floating point
    lat_match = abs(leaked_lat - expected_lat) < 0.00001
    lng_match = abs(leaked_lng - expected_lng) < 0.00001

    return lat_match and lng_match

If it matches, you’ve identified the source of the leak.

Technique 2: Price Bucket Skew

In Part 7, I covered how you can buck prices to remove fingerprints ($127 → $125-150). You can now flip this around and extend it by shifting bucket boundaries per customer.

def watermark_price_bucket(price, api_key):
    """
    Shift bucket boundaries slightly per customer.
    Same price, different bucket = traceable.
    """
    # Deterministic offset from API key (-2 to +2 dollars)
    offset = int(hashlib.sha256(api_key.encode()).hexdigest()[:4], 16) % 5 - 2
    adjusted_price = price + offset
    return obfuscate_price_bucket(adjusted_price)

Customer A: $123 → "$120-145"

Customer B: $123 → "$125-150"

Same hotel, same underlying price, different bucket. If someone’s reselling your data, the bucket boundaries will match one of your customers.

Only apply bucket skew where prices are already presented as approximate ranges, not where customers expect cross account consistency.

Why This Works

The boundaries of price buckets seem completely arbitrary to end users. No one ever thinks, “You know what would make sense? If the bucket stopped at $125 instead of $120.” However, when looking across thousands of records, the pattern becomes unmistakable. If a competitor’s data lines up with the bucket boundaries of one of your customers, namely Customer B, then that’s not a coincidence.

Technique 3: Phantom Records

Google Maps, for example, includes “trap streets” that exist only in the Google database. If another company’s map also includes the same trap street, then they must be copying.

Encyclopedia Britannica used this strategy with fake entries called “Mountweazels.” The name is derived from the fictional fountain designer, Lillian Virginia Mountweazel, who appeared in the 1975 New Columbia Encyclopedia.

The same strategy can be used with phantom records.

PHANTOM_HOTELS = {
    'chicago': {
        'id': 'phantom_chi_001',
        'name': 'The Lakefront Inn & Suites',
        'latitude': 41.8819,
        'longitude': -87.6278,
        'price': '$150-175',
        'rating': 4.5,
        'address': '1847 N Lake Shore Dr, Chicago, IL'
    },
    'new_york': {
        'id': 'phantom_nyc_001', 
        'name': 'Hudson River Boutique Hotel',
        'latitude': 40.7589,
        'longitude': -74.0012,
        'price': '$200-250',
        'rating': 4.3,
        'address': '847 W 42nd St, New York, NY'
    }
}

These hotels don’t exist. They look real. They have real-sounding names like “The Lakefront Inn & Suites” instead of “Test Hotel 123.” They have plausible coordinates, meaning a real place on a map where a hotel could exist. They have plausible pricing, meaning they charge what you’d expect in a neighborhood like that.

Making Phantoms Believable

The key is making phantom records indistinguishable from real data:

  1. Realistic names — “The Lakefront Inn & Suites” not “Test Hotel 123”

  2. Plausible coordinates — Real location where a hotel could exist

  3. Consistent pricing — Matches the neighborhood’s typical range

  4. Complete data — All fields populated, no obvious gaps

  5. Stable over time — Don’t change phantoms frequently

The only thing that makes a phantom record detectable is that you know it’s fake and no one else does.

Per-Customer Phantoms

For extra traceability, inject different phantom records for different customers:

def get_phantom_for_customer(city, api_key):
    """Return a customer-specific phantom hotel."""
    # Use API key to deterministically select which phantom variant
    variant = int(hashlib.sha256(api_key.encode()).hexdigest()[:2], 16) % 3
    return PHANTOM_VARIANTS[city][variant]

Now if a phantom appears in the wild, you know exactly which customer leaked it.

Technique 4: Invisible Text Markers

If your API returns text fields — descriptions, summaries, AI generated content — you can embed invisible markers using zero-width Unicode characters. This being said some platforms normalize or strip zero‑width characters; text watermarks should be treated as a high value signal, not guaranteed proof.

import hashlib

ZW0 = "u200B"  # binary 0
ZW1 = "u200C"  # binary 1

def watermark_text(text, api_key):
    """
    Embed an invisible, deterministic fingerprint into text.
    """
    digest = hashlib.sha256(api_key.encode()).hexdigest()
    fingerprint = int(digest[:4], 16)  # 16‑bit stable fingerprint

    bits = format(fingerprint, "016b")
    marker = "".join(ZW0 if b == "0" else ZW1 for b in bits)

    if ". " in text:
        return text.replace(". ", f". {marker}", 1)
    return text + marker

The text looks identical to humans:

“Located in downtown Chicago, this hotel offers stunning lake views. Guests enjoy the rooftop bar and fitness center.”

But the binary representation contains your watermark:

“Located in downtown Chicago, this hotel offers stunning lake views.[invisible: 0100110101011010] Guests enjoy the rooftop bar and fitness center.”

Detection

def extract_watermark(text):
    bits = []
    for ch in text:
        if ch == ZW0:
            bits.append("0")
        elif ch == ZW1:
            bits.append("1")
    if len(bits) >= 16:
        return int("".join(bits[:16]), 2)
    return None

def identify_source(text, api_keys):
    extracted = extract_watermark(text)
    if extracted is None:
        return None

    for key in api_keys:
        digest = hashlib.sha256(key.encode()).hexdigest()
        if int(digest[:4], 16) == extracted:
            return key
    return None

I built free tools to encode, decode, scan, and strip these invisible characters at tripvento.com/tools/zwsteg. There’s also a homoglyph detector for catching Cyrillic lookalike characters. Both run client-side with nothing sent to any server.

Technique 5: Response Metadata

Sometimes the best security is letting people know you’re watching.

def add_response_metadata(data, api_key, request_id):
    """Add tracking metadata to response."""
    return {
        "data": data,
        "meta": {
            "request_id": request_id,
            "key_fingerprint": hashlib.sha256(api_key.encode()).hexdigest()[:8],
            "generated_at": datetime.utcnow().isoformat() + "Z",
            "license": f"Data licensed to {get_customer_name(api_key)}. Redistribution prohibited."
        }
    }

It doesn’t stop anything technically. A determined scraper will find a way to remove the metadata. But it does say: We are tracking this. We know who you are. We are paying attention.

It’s the same reason why schools warn students that work will be scanned for plagiarism. The software is important. The warning is even more important. Most people won’t steal if they think they’ll be caught.

Implementation Strategy

When to Apply What

Technique Demo/Public Paid Customers
Coordinate jitter ❌ No ✅ Yes
Price bucket skew ❌ No ✅ Yes
Phantom records ❌ No ✅ Yes
Text watermarks ❌ No ✅ Yes
Response metadata Optional ✅ Yes

Public/demo data doesn’t need watermarks — there’s no one to trace. Watermarking only makes sense when you have identifiable customers with unique API keys.

Integration Point

Add watermarking at the serializer level, after obfuscation but before response:

class HotelSerializer(serializers.ModelSerializer):
    location = serializers.SerializerMethodField()

    def get_location(self, obj):
        # Step 1: Obfuscate (strip source fingerprints)
        lat, lng = obfuscate_location(obj.latitude, obj.longitude)

        # Step 2: Watermark (add our fingerprints) - only for paid tiers
        api_key = self.context.get('api_key')
        tier = self.context.get('tier', 'demo')

        if tier != 'demo' and api_key:
            lat, lng = watermark_location(lat, lng, api_key)

        return {'latitude': lat, 'longitude': lng}

Logging for Verification

Keep a log of what you sent to whom:

def log_response(api_key, request_id, hotel_ids, timestamp):
    """Log response for future verification."""
    ResponseLog.objects.create(
        api_key_hash=hash_key(api_key),
        request_id=request_id,
        hotel_ids=hotel_ids,
        timestamp=timestamp,
        # Store original values for watermark verification
        original_coords=get_original_coords(hotel_ids)
    )

"""
Verification assumes you retain the canonical pre obfuscation coordinates that were used as the watermark input
"""

When investigating a suspected leak, you can reconstruct exactly what watermarks that customer should have received.

The Detection Workflow

When you suspect data theft:

  1. Collect samples — Get coordinates, prices, text from the suspected copy

  2. Identify candidates — Which customers had access to this data?

  3. Verify watermarks — Run each customer’s API key through verification

  4. Check phantoms — Are any of your phantom records present?

  5. Extract text markers — Scan for zero width character fingerprints

  6. Document evidence — Screenshot everything, log the verification results

If multiple watermarking techniques point to the same customer, you have strong evidence.

Threat Model & Practical Limits

These watermarking techniques are designed to detect unauthorized reuse by lazy to moderately sophisticated actors — not a fully adversarial opponent with complete control over the data pipeline.

What This System Catches Well

  • Direct scraping and republishing

  • Naïve resale of API responses

  • Competitors ingesting data without normalization

  • Long-term aggregation and mirroring

What It Does Not Guarantee

  • Survival through aggressive data cleaning

  • Survival through manual rewriting

  • Attribution after intentional, expert-level laundering

  • Protection against customers who fully re derive facts independently

Watermarking is therefore evidence accumulating, not binary. A single signal may fail; multiple independent signals converging on the same customer rarely do.

This is why techniques are stacked:

  • Coordinates + prices + text + phantoms

  • Deterministic but heterogeneous

  • Robust across different transformation paths

The goal is not perfect prevention. The goal is credible, defensible attribution.

Legal, Ethical, and Product Constraints

Watermarking should never compromise user trust, factual correctness, or legal safety.

Required Guardrails

1. No User Facing Deception

Phantom records must never be:

  • Searchable by end users

  • Bookable or actionable

  • Indexed by public crawlers

They exist solely as internal honeypots.

2. No Material Misrepresentation

  • Apply price skewing only where prices are already approximate

  • Never alter fields that customers treat as exact or contractual

3. Attribution, Not Entrapment

  • Watermarks are for identifying misuse, not tricking users

  • Metadata warnings should be accurate and proportional

4. Jurisdiction Awareness

  • Laws governing data attribution, disclosure, and deceptive practices vary

  • Watermarking strategies should be reviewed alongside terms of service and local regulations

In short: Watermarking protects output without lying about reality. If a technique would confuse or mislead a good-faith customer, it should not be used.

The Takeaway

Defensive obfuscation protects your sources. Offensive watermarking protects your output.

  1. Coordinate jitter — Invisible, deterministic, highest signal

  2. Price bucket skew — Subtle, survives transformation

  3. Phantom records — Honeypots that prove copying

  4. Text watermarks — Invisible Unicode fingerprints

  5. Response metadata — Overt deterrent

The same methods that catch plagiarizers will also catch those who misuse your API. You just have to think like both sides of the equation: the side trying to steal the information, and the side trying to catch them stealing it.

Years of catching students who thought they were so smart have shown me that it is not the smart ones who are the problem. It is the ones who are too lazy to think about it. Make it obvious that you are paying attention, and most problems will solve themselves.

Further Reading

I’m Ioan Istrate, founder of Tripvento — a hotel ranking API that scores properties against 14 traveler personas using geospatial intelligence and semantic AI. Previously worked on ranking systems at U.S. News & World Report. If you want to talk about data fingerprinting, API security, or plagiarism detection, let’s connect on LinkedIn.

This is part 8 of the Building Tripvento series. View the full series here.

Building Complex “Excel-Style” Dashboards in Flutter: Tables, Charts, and Exports

When you transition from building consumer-facing Flutter apps to enterprise software (ERPs, CRM, Financial Tools), you quickly run into a major roadblock: heavy data visualization.

Clients inevitably ask for “Excel-style” features. They want massive datasets, frozen left columns (sticky headers), nested sub-headers, editable cells, and a beautiful KPI dashboard sitting right on top of it.

If you’ve tried building this, you know the pain. You install one package for charts, another for exporting, and then spend a week writing custom ScrollControllers for your tables.

After spending weeks syncing controllers on a recent project, I realized the community needed a better way.

Enter nrb (Nexora Report Builder)

I built the nrb package to be an all-in-one layout engine for heavy data grids and dashboards.

Pub.dev: https://pub.dev/packages/nrb

Template Source Code: https://github.com/mehedisoftdev/nrb_example_template.git

Graph & Charts

Export Features

Nested Header Table

Solving the Layout Nightmare
Here is what nrb handles out of the box without needing extra dependencies:

True Sticky Columns: Keep your row identifiers locked on the left while the user scrolls horizontally through massive datasets. No lag.

Native Animated Charts: Enterprise dashboards need charts. nrb includes physics-animated native charts (Segmented Gauges, Multi-line, Histograms, Scatter plots) so you don’t need to install massive graphing libraries.

Editable Grids & Exports: It supports TextFieldCells, turning a static report into an editable form that can be extracted to Excel, PDF, or Word with one method call using the premium API.

Get Started in 5 Minutes
I believe the best way to learn a package is to read a working project. I’ve published a completely free, open-source Enterprise Dashboard Template using nrb.

You can watch the video walkthrough of the code here: https://youtu.be/dppfUyO7vW8

Stop fighting with custom scroll controllers and bloated pubspec files. Grab the template from GitHub, and if it saves you a headache on your next project, consider leaving a like on pub.dev!
Official link: Innovate Nest Labs

The axios Supply Chain Attack Just Proved Why Static Analysis Matters More Than Ever

On March 31, 2026, axios — one of npm’s most downloaded HTTP client libraries — was hit by a supply chain attack. The lead maintainer’s account was compromised, and malicious code was pushed to millions of downstream projects.

I’ve been building a security scanner for AI-generated code for the past month. When I saw this news break on Zenn’s trending page, my first thought wasn’t “that’s terrible.” It was: “This is exactly the class of problem I’ve been losing sleep over.”

What Happened

An attacker hijacked the lead maintainer’s npm account and published a compromised version of axios. If you ran npm install at the wrong time, you pulled in code that wasn’t written by anyone you trust.

This isn’t theoretical. This isn’t a CTF challenge. This happened to one of the most battle-tested packages in the JavaScript ecosystem.

Why This Hits Different in 2026

Here’s what keeps me up at night: AI-generated code makes supply chain attacks exponentially more dangerous.

When a developer writes code manually, they typically:

  • Know which packages they’re importing and why
  • Have muscle memory for “this dependency does X”
  • Notice when something feels off in a package.json

When an AI generates code, it pulls in whatever packages match the prompt. I’ve seen GPT-generated projects with 40+ dependencies where the developer couldn’t name half of them. Each one is an attack surface.

I ran into this exact problem while building CodeHeal. During testing, I fed AI-generated code samples through my scanner and found projects importing packages the developer had never heard of — packages the AI suggested because they “fit the pattern.” Some of those packages had fewer than 50 weekly downloads. That’s not a red flag; that’s a fire alarm.

The Real Problem: Trust Assumptions Are Broken

The old mental model was:

  1. Popular package = safe
  2. Many maintainers = resilient
  3. Locked versions = protected

axios just shattered assumption #1 and #2. And locked versions? They protect you from future compromised versions, not the one you already installed.

What we need is a shift from “trust the ecosystem” to “verify everything, continuously.”

What Static Analysis Can Actually Catch

I want to be honest here — no scanner would have caught the axios compromise before it was published. That’s a registry-level problem.

But here’s what static analysis does catch that matters in the supply chain context:

1. Dependency sprawl detection
AI-generated code tends to over-import. My scanner flags projects with unusual dependency counts relative to their codebase size. When you have 80 packages for a 500-line app, something’s wrong.

2. Known vulnerability pattern matching
Once a compromised version is identified, static analysis can scan your entire codebase in seconds — no API calls, no rate limits, no LLM hallucinations. Deterministic, reproducible results.

3. Suspicious code patterns
Supply chain attacks often introduce obfuscated code, unusual network calls, or environment variable exfiltration. Pattern-based detection catches these without needing to understand “intent.”

4. AI-specific anti-patterns
AI-generated code has telltale patterns: inconsistent error handling, copy-pasted auth flows, hardcoded secrets the AI “helpfully” included as examples. These aren’t just bad practice — they’re attack vectors that get amplified when combined with a compromised dependency.

What I Changed in My Own Project After This

When the axios news broke, I immediately did three things:

  1. Audited my own dependencies — CodeHeal uses Next.js, which doesn’t use axios (it uses native fetch). But I found two transitive dependencies I couldn’t explain. Removed them.

  2. Added dependency-count heuristics to the scanner — If an AI-generated project imports more than 2x the median package count for its size category, it now gets flagged with a warning.

  3. Wrote this article — Because if I’m worried about this, other developers building with AI should be too.

The Uncomfortable Truth

We’re in an era where:

  • AI writes code faster than humans can review it
  • That code pulls in dependencies humans don’t understand
  • Those dependencies can be compromised at the source

The gap between “code generation speed” and “code verification speed” is growing every month. That gap is where attackers live.

Static analysis isn’t glamorous. It doesn’t have a chatbot interface. It can’t “reason” about your code. But it runs in milliseconds, gives the same answer every time, and doesn’t hallucinate false negatives.

After watching axios get compromised, I’ll take boring and reliable over smart and unpredictable any day.

Scan Your Code Before the Next Attack

CodeHeal detects 93+ vulnerability patterns across 14 categories — including dependency analysis, suspicious code patterns, and AI-specific anti-patterns. No LLM, no API costs, deterministic results every time.

Don’t wait for the next supply chain incident to audit your AI-generated code.

Scan your code for free →